CC Rank Checker is updated with Common Crawl's Oct '26 web graph.
25.1M domains, 16 releases since 2023, harmonic centrality + PageRank.
New: compare up to 20 domains in one chart, PNG export, dark mode, free API.
@peec_ai: HC 6.8M to 393K since mid '25.
cc: @Burnszilla @glindahl @CommonCrawl
The best part is ++
Common Crawl
The Common Crawl Foundation (Common Crawl) is a nonprofit 501(c)(3) organization that crawls the web and freely provides its archives and datasets to the public. Access to the data is free on Amazon Web Services, but users may incur storage and compute costs. More on Wikipedia
-
Common Crawl Foundation reposted
Metehan Yesilyurt @metehan777
-
Common Crawl Foundation
@CommonCrawl
Steering Committee Election Results Announced netpreserveblog.wordpress.com/2026/11/10/steering-committ…
-
Common Crawl Foundation
@CommonCrawl
This is a pretty useful summary guide to Common Crawl. (100% AI written, but it's not bad)
casrai.org/guides/common-crawl -
Common Crawl Foundation
@CommonCrawl
Introducing warc2zip
We are pleased to introduce warc2zip, a tool that allows anyone to turn WARC archives into simpler, zipped files that can be inspected with ordinary tools.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
The uneven rise of AI-generated web content
arxiv.org/pdf/2610.36631 -
Common Crawl Foundation reposted
Phil Hoyeck
@PAHoyeck
Just learned that Patrick Stewart has passed away. Such a sad loss. Here he is in one of the best things ever put on television, the Star Trek episode “The Measure of a Man.” I show it to my students in Philosophy and Science Fiction every year.
This media couldn't be displayed. See it on the original post.
DiscussingFilm
@DiscussingFilm
Patrick Stewart has sadly passed away at the age of 86.
-
Common Crawl Foundation reposted
Stephen Burns
@Burnszilla
In 1950, five people at MIT passed notes through slots. Today the math from that experiment helps decide what AI gets trained on.
stephenburns.ai/blog/harmonic-centrality-ai-visibility -
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation will be at IETF 127 in SF, week of November 15. If you are around, we'd love to chat!
-
Common Crawl Foundation
@CommonCrawl
October 2026 Crawl Archive Now Available
We are pleased to announce the release of the October 2026 crawl archive, consisting of 2.16 billion pages (or 371.19 TiB of uncompressed content)
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Findings of the WMT 2026 Shared Task of the Open Language Data Initiative
Laurie Burchell Common Crawl Foundation
Common Crawl Foundation
@CommonCrawl
www2.statmt.org/wmt26/pdf/2026.wmt-1.57.pdf
We present the results of the WMT 2026 shared task of the Open Language Data Initiative (OLDI). Participants were invited to contribute to the massively multilingual open datasets supported by OLDI, FLORES+ and OLDI Seed, or to create new resources in line with OLDI’s ethos. We accepted ten submissions: five extending FLORES+, and five extending other open and massively-parallel datasets (BOUQuET, Seed, SMOL, and WMT24+). These contributions advance the coverage and quality of multilingual datasets, especially for underserved language varieties. All contributions are released under permissive open-source licenses. -
Common Crawl Foundation reposted
Brian Wesley
@BrianWesley0711
My bet: low-resource languages would lose at the filter.
Quality classifiers trained mostly on English throw out good Icelandic pages as noise. Smarter crawl budgets won't help if the filter can't read the language. -
Common Crawl Foundation
@CommonCrawl
The Common Crawl Foundation at the TPDL Conference
The Common Crawl Foundation participated in the 30th TPDL (Theory and Practice for Digital Archives) conference in Faro, Portugal presenting two contributions on Crawl theory and on archival data enrichment.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
arxiv.org/abs/2610.13321
Web crawling is a major source of large language model (LLM) pretraining data, yet data-selection pipelines discard a large share of crawled pages.
We investigate how a crawler should allocate its budget across and within hosts to collect more high-quality pretraining data. -
Common Crawl Foundation
@CommonCrawl
Common Crawl - the ultimate time capsule for knowledge | Amazon Web Services
www.youtube.com/watch?v=rGT-al-FbCk -
Common Crawl Foundation reposted
Luis Oala
@LuisOala
we will have two papers @NeurIPSConf this year from the croissant community 🥐
1. "croissant baker" led by rafi al attrach and @tompollard
2. "croissant miner" led by berke arda and @akhtarmubashara
i took a quick glance at the rearview mirror
since early 2023, our idea for a unified ml data access layer has grown into an expansive ecosystem, incl
- data aggregators spanning hundreds of thousands of datasets incl @huggingface @kaggle @dataverseorg @CommonCrawl and others
- tooling spanning auto-generation and -verification of croissant files
- the formal spec maintenance under @MLCommons
- and a growing list of community extensions spanning verticals such geo, responsible AI, health and others
onwards towards the composable data dream(: -
Common Crawl Foundation
@CommonCrawl
-
Post not available here, view on X
Common Crawl Foundation
@CommonCrawl
This media couldn't be displayed. See it on the original post. -
Common Crawl Foundation reposted
Will Held
@WilliamBarrHeld
There’s an enormous amount of open training data on Hugging Face. What does it take to make it work together 🤗?
For Marin’s 535B run, we built on 25T tokens from 152 datasets with licenses permitting training.
Here’s the work between downloading those and training a model 🧵 -
Common Crawl Foundation
@CommonCrawl
Information Stewardship Forum 2026: Creating Community and Purpose Around US Government Information
A report from the inaugural Information Stewardship Forum, a three-day convening hosted by the Internet Archive in San Francisco on March 18–20, 2026, that brought together 120 people working to preserve and provide access to United States government information.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
September 2026 Crawl Archive Now Available
We are pleased to announce the release of the September 202 6 crawl archive, consisting of 2.17 billion pages (or 361.4 TiB of uncompressed content.)
📷
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Getting Started with Common Crawl Data on Hugging Face
We made parts of our crawl archive available experimentally on a Hugging Face Storage Bucket. This blog post explains how to use the data on Hugging Face, with tools and examples on which you can build.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
CommonsDB, ISCC, Spaghetti, and Meatballs
Notes from the CommonsDB final conference in Alicante: a registry of 6.5 million open works keyed on ISCC, and the EUIPO's push for federated copyright infrastructure.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Bodhium Labs: From web pages to a question corpus
FineQuestions draws on 110 snapshots of FineWeb, the filtered English-language corpus derived from Common Crawl, spanning 2013–2025. Extraction yielded roughly 13.4 billion raw questions filling 22 TB. Normalization and aggregation reduced these to approximately 1.5 billion unique questions.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
How Common Crawl and AWS Open Data built the foundation for the AI revolution
by Rich Skrenta and Dr. Beryl Rabindran
aws.amazon.com/blogs/publicsector/how-common-crawl-and-aw… -
Common Crawl Foundation
@CommonCrawl
Web Graph Embeddings: An Experimental Dataset Release
We are publishing an experimental dataset of graph embeddings built from the Common Crawl Web Graph: a 128-dimensional vector for each of 52.9 million web hosts, learned from hyperlinks alone, along with two interactive Hugging Face Spaces.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
signüll
@signulll
the modern web you see incl websites you browse will likely disappear or become irrelevant altogether in the next few years. they’ll feel like absolute ghost towns.
when the previous era existed (pre ai) google aggregated attention & then sprayed traffic to the web based on intent.
modern ai has no need to spread traffic like this, it just needs to do something through an agent to agent negotiation. this leaves websites & web interfaces completely irrelevant.. which renders the browser pretty obsolete over time, just go look at your browser history & see how top heavy it all is.
this is why ai is such a giant game to win because it is the ultimate aggregation of attention / time spent. you never even have to leave like you did google! whoever controls this basically controls a large portion of the gdp. e.g. there might be a measure of success metric that is something like gdp per ai agent. -
Common Crawl Foundation
@CommonCrawl
Common Crawl Rate Limit
The CDX index server is heavily rate limited. What triggers a block, how long it lasts, and the interface that has no limit.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
A Content Analysis of llms.txt Files from the July 2026 Crawl Archive
We analyzed the contents of 584,107 llms.txt files from the July 2026 crawl. Two thirds are produced by a plugin, half follow the structure the specification defines, and a few files even contain prompt injections.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Thom Vaughan of Common Crawl, speaking from the Paris Open Source AI Summit recently.
opensourceaisummit.eu -
Common Crawl Foundation
@CommonCrawl
Common Crawl gets a lot of opt-out requests.
We respect publisher rights, even if they don't possess time machines go fix their robots.txt files from 20 years ago. It is what it is. We endeavor to be polite, however.
commoncrawl.org/blog/common-crawl-foundation-opt-out-regi…
Our ongoing opt-out registery / ledger is here:
docs.google.com/spreadsheets/d/1uavIZ-Y2ew-Vj7d0_pY67SGD2…
We consider ourselves archivists / librarians. We preserve the open public web for the benefit of all. But if you do not want to be included, it is straightforward to opt out. -
Common Crawl Foundation
@CommonCrawl
August 2026 Crawl Archive Now Available
We are pleased to announce that the crawl archive for August 2026 is now available, containing 2.14 billion web pages or 360 TiB of uncompressed content.
Common Crawl Foundation
@CommonCrawl
commoncrawl.org/blog/august-2026-crawl-archive-now-available
Common Crawl Foundation
@CommonCrawl
commoncrawl.org/blog/host--and-domain-level-web-graphs-ju…
Host- and Domain-Level Web Graphs June, July, and August 2026
We are pleased to announce a new release of host-level and domain-level web graphs based on the crawls of June, July, and August 2026, consisting of 235.0 million nodes and 3.1 billion edges at the host level, and 119.7 million nodes and 2.5 billion edges at the domain level.
📷 -
Common Crawl Foundation
@CommonCrawl
Fascinating analysis by @pewresearch - How Much of the Internet Is Written With AI?
"To explore this question, we used the Common Crawl web archive to collect almost half a million English-language webpages from the past five years. We then ran the text of those pages through an AI detection tool to see how many of them were likely written or substantially edited by AI."
Pew Research Center
@pewresearch
AI-authored content has become increasingly common online, but where is it coming from?
This growth has been driven almost entirely by commercial (.com) websites.
#aicontent #aiauthorship
Common Crawl Foundation
@CommonCrawl
Full article: www.pewresearch.org/data-labs/2026/08/20/how-much-of-the-…
-
Common Crawl Foundation
@CommonCrawl
Announcing the First Stable Release of CC-Downloader
Over a year ago we released cc-downloader, an experimental tool to politely download Common Crawl data. Today we're releasing its first stable version, with a Rust library and Python bindings.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Inclusion by design: making African languages visible to AI
Common Crawl Foundation
@CommonCrawl
idrc-crdi.ca/en/research-in-action/inclusion-design-makin…
@IDRC_CRDI -
Common Crawl Foundation
@CommonCrawl
Notes from HTTP Workshop Basel and IETF 126 Vienna
Two weeks in Basel and Vienna, at the HTTP Workshop and IETF 126. Protocol adoption measured across the whole web, and an attempt to define what "machine readable" actually means.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Hamdy Mubarak
@Hamdy_Mubarak
Excited to share a collaboration between @QatarComputing and @CommonCrawl to strengthen Arabic LLMs.
We contributed 30K+ Arabic domains, enriched with quality annotations and metadata, to improve Arabic coverage in future Common Crawl releases.
🔗 commoncrawl.org/blog/turning-30-000-arabic-domains-into-a… -
Common Crawl Foundation
@CommonCrawl
July 2026 Crawl Archive Now Available
The crawl archive for July 2026 is now available. The data was crawled between July 7th and July 25th, and contains 2.14 billion web pages (or 364.01 TiB of uncompressed content). We also announce some improvements and changes.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Common Crawl Joins Project Tapestry
Common Crawl has joined Project Tapestry, a global initiative led by the AI Alliance to advance open, sovereign AI. We will contribute our expertise in responsible web data, multilingual coverage and culturally informed AI development.
📷
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Measuring Crawled Coverage of a Website in Common Crawl
How can we measure how many pages we’ve crawled from a particular website? The answer is a lot more complicated than you might think.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Congrats on luca@commoncrawl.org getting 5000 Github stars on his project GROBID!
A machine learning software for extracting information from scholarly documents
grobid.readthedocs.io/en/latest/ -
Common Crawl Foundation
@CommonCrawl
Is one vantage point enough? IPv6 across the top million web hosts
We probed the top 1,000,000 web hosts for IPv6 from five vantage points on three continents. 327% work from everywhere, but one vantage point turns out to be enough for the headline rate.
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation
@CommonCrawl
* 31.7%
Wish we could edit X posts :) -
Common Crawl Foundation
@CommonCrawl
Measuring What the Crawler Sees: Discovery Curves, Core Persistence, and Shell Dynamics in Longitudinal Web Crawls
Amazing research by {micha,hande,luca} @ commoncrawl
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Turning 30,000 Arabic Domains Into a Better Crawl
How we filtered, geolocated and categorised a donation of Arabic seed domains
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation at LREC 2026
The Common Crawl team attended the 16th International Conference on Language Resources and Evaluation in Palma, Mallorca, co-organizing a tutorial, presenting recent published work, and strengthening links with the research community.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
13th Web-as-Corpus Workshop @ EMNLP 2026
Common Crawl Foundation
@CommonCrawl
On 29th October 2026, the Web-as-Corpus Workshop will return for its 13th edition, co-located with EMNLP 2026 in Budapest. The organising committee includes engineers from the Common Crawl Foundation alongside researchers from the Jožef Stefan Institute, the University of Oslo, and the University of Turku.
commoncrawl.org/blog/13th-web-as-corpus-workshop-emnlp-2026 -
Common Crawl Foundation
@CommonCrawl
Hi everyone,
Our June 2026 Crawl Archive and corresponding Web Graph are now available.
The June 2026 crawl consists of 2.10 billion web pages (or 354 TiB of uncompressed content). Captures are from 40.8 million hosts or 33.6 million registered domains.
The corresponding Web Graph release consists of 247.3 million nodes and 6.3 billion edges at the host level, and 121.1 million nodes and 3.9 billion edges at the domain level.
Live long and prosper!
Luca / @whitenoise -
Common Crawl Foundation
@CommonCrawl
The May 2026 crawl archive (CC-MAIN-2026-21) is now also available on our HF bucket. 🤗
huggingface.co/buckets/commoncrawl/commoncrawl -
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation at IIPC-WAC 2026
Common Crawl was well represented with contributions at the 2026 IIPC Web Archiving Conference and General Assembly.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
CommonLID Update: New Tools, Growing Impact
CommonLID, a community-built language ID benchmark, has a new website and interactive leaderboard. Its paper was accepted to ACL 2026, with a poster session on 7 July. Source code, a PyPI package, and the dataset are now available.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
The Columnar Index Is Now the URL Index
We have renamed the Columnar Index to the URL Index, to be clearer about its purpose and to pave the way for more datasets in a columnar format.
commoncrawl.org/blog/the-columnar-index-is-now-the-url-index -
Common Crawl Foundation
@CommonCrawl
Introducing the AI Visibility Audit
A free guide for SEOs and GEOs on how to check whether AI systems can actually reach a site, and how to stay visible in the crawl that trains them.
Common Crawl Foundation
@CommonCrawl
commoncrawl.org/blog/introducing-the-ai-visibility-audit
Link to PDF:
cdn.prod.website-files.com/6479b8d98bf5dcb4a69c4f31/6a1d9… -
Common Crawl Foundation
@CommonCrawl
Under-represented languages deserve better tools! On June 4th, The Common Crawl Foundation and Mozilla Data Collective will host a webinar to test language identification for the languages you care about.
Common Crawl Foundation
@CommonCrawl
RSVP and join speakers Laurie Burchell and Pedro Ortiz Suarez from the Common Crawl Foundation and Kostis Saitas Zarkias and Robert Pugh from Mozilla Data Collective for a truly hands-on session.
Thursday, June 4th 6 PM CEST | 12 PM ET | 9 AM PDT Register via Zoom: -
Common Crawl Foundation
@CommonCrawl
May 2026 Crawl Archive Now Available
We are happy to announce the release of the May 2026 crawl archive, consisting of 2.16 billion web pages, or 365.56 TiB of uncompressed content.
📷
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
As an early experiment in distributing Common Crawl data through another channel, the April 2026 crawl archive is now available in a Hugging Face Storage Bucket, alongside its existing home on AWS S3.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
You can now build directly on Common Crawl from the browser
Browsers can now fetch Common Crawl data directly, no backend needed. Build SQL explorers, snapshot viewers and diff tools as static pages.
📷
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Tristan Rhodes
@tristanbob
Have you ever seen a user agent named "CCBOT"?
If so, you were visited by @CommonCrawl, a non-profit that crawls the internet and publishes a 10+ petabytes open-source dataset.
I think it's beautiful that humanity shares this data.
It means that anyone with minimal resources has the access to data required to build their own AI models.
It also means we don't have to crawl the entire internet thousands of times for each research, saving large amounts of bandwidth and resources. -
Common Crawl Foundation
@CommonCrawl
Our April 2026 Crawl Archive and corresponding Web Graph are now available.
The April 2026 crawl consists of 2.19 billion web pages (or 379.2 TiB of uncompressed content). Captures are from 43.2 million hosts or 35.4 million registered domains and include 660.5 million new URLs, not visited in any of our prior crawls.Post not available here, view on X
Common Crawl Foundation
@CommonCrawl
📷 April 2026 Crawl Announcement
📷 April 2026 Web Graph Announcement
📷 Crawl Statistics
📷 Web Graph Statistics
Live long and prosper!
Common Crawl Foundation
@CommonCrawl
📷 April 2026 Crawl Announcement
📷 April 2026 Web Graph Announcement
📷 Crawl Statistics
📷 Web Graph Statistics
Common Crawl Foundation
@CommonCrawl
Sorry, now with the actual links.
commoncrawl.org/blog/april-2026-crawl-archive-now-available
blog.commoncrawl.org/blog/host--and-domain-level-web-grap…
commoncrawl.github.io/cc-crawl-statistics/
commoncrawl.github.io/cc-webgraph-statistics/ -
Common Crawl Foundation
@CommonCrawl
April 2026 Common Crawl Newsletter
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Financial Times
@FT
Mistral CEO: AI companies should pay a content levy in Europe ft.trib.al/hKU8k0g | opinion
-
Common Crawl Foundation
@CommonCrawl
March 2026 Crawl Archive Now Available
We are pleased to announce the release of the March 2026 crawl, containing 1.97 billion web pages, or 344.64 TiB of uncompressed content. We also observed a dramatic increase in fetches over IPv6, explained by the enabling of Happy Eyeballs in the OkHttp library.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Blocking the Internet Archive Won’t Stop AI, But It Will Erase the Web’s Historical Record
www.eff.org/deeplinks/2026/03/blocking-internet-archive-w…
@eff -
Common Crawl Foundation
@CommonCrawl
IPv6 Adoption Across the Top 100K Web Hosts
We probed the 100,000 most-linked web hosts for IPv6 support using the Common Crawl Web Graph. Only 36.9% are fully reachable over IPv6, with adoption ranging from 71% among the top 100 to 32% in the long tail.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
We've never had an entire city ask to be deleted before...
-
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation would like to share with you an updated overview of our organization as of March 2026.
Please let us know if we can be helpful.
drive.google.com/file/d/1ww2R0x_e_DL8eiY590D_Xpe9z34G002X… -
Common Crawl Foundation reposted
Wayne Yamamoto
@kazabyte
I've been dabbling with Claude Code. Using English as a programming language, I wrote a C compiler. medium.com/@kazabyte/english-as-a-programming-language-ho…
-
Post not available here, view on X
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
github.com/commoncrawl/cc-webgraph-statistics
Summary of changes
This PR contains substantial redesign and refactoring for the following:
- Interactive charts instead of static images
- New domain lookup tool for plotting HC and PR (and even comparison of two different domains) over time
- Combine avgindegree and avgdegree plots into avgdegree (closes Merge plots avgoutdegree and avgindegree into avgdegree #4)
- Add appropriate reference links to harmonic centrality (closes Add links to research papers in the section explaning harmonic centrality #5)
- Make masthead image disappear quicker via parallax scrolling so that content is reached faster
- Substantial mobile/responsive UX improvements
- Improve rank tables UX to be one unified table
- Proper links and sanitation of anchor tags with rel= and target= -
Common Crawl Foundation
@CommonCrawl
February 2026 Crawl Archive Now Available
We are pleased to announce the release of the February 2026 crawl, consisting of 2.1 billion web pages (or 363 TiB of uncompressed content). Captures are from 45.5 million hosts or 37.1 million registered domains.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Introducing the New Examples & Resources Browser
We've replaced our old Examples and Use Cases pages with a single searchable, filterable browser. 119 resources from 115 contributors, all in one place. Search, filter by type or language, sort, and share links. We welcome community submissions.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
AI Plumbers at FOSDEM’26
Common Crawl was invited to the AI Plumbers unconference held at FOSDEM this year. The contrast between the 100 people at the unconference, compared to the 10,000 people at the main event, couldn't be bigger.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
EleutherAI
@AiEleuther
Announcing our latest paper: CommonLID: Re-evaluating State-of-the-Art Language Identification Performance on Web Data
In collaboration with @CommonCrawl @MLCommons and @JohnsHopkins we worked with 80+ native speaker annotators to build a LID benchmark on actual Common Crawl text covering 109 languages. Existing evaluations overestimate how well LangID works on web data. -
Common Crawl Foundation
@CommonCrawl
IBM researchers created a high-quality, 10-trillion-token dataset called GneissWeb, which makes up Granite’s core linguistic capabilities. Common Crawl has open-sourced Gneiss Web's annotations providing direct access to the data.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
CC-Citations: A Visualization of Research Papers Referencing Common Crawl
We are proud to release an interactive visualization of thousands of research papers using or citing Common Crawl data.
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation
@CommonCrawl
Quentin Lhoest 🤗
@lhoestq
Impressive citations map of @CommonCrawl work
Amazing to explore many areas of projects built on top of CC
commoncrawl.org/blog/cc-citations-a-visualization-of-rese… -
Common Crawl Foundation
@CommonCrawl
CommonLID: Re-evaluating State-of-the-Art Language Identification Performance on Web Data
We are excited to announce the release of CommonLID, a language identification benchmark for the web, covering 109 languages. CommonLID was developed in collaboration with multiple open-source organizations and language community groups.
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation
@CommonCrawl
Language identification still proves to be a challenging task, especially for web data. In collaboration with @MLCommons @AiEleuther @JohnsHopkins and 97 community members, we created CommonLID, a new benchmark for LangID for 100+ languages!
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation
@CommonCrawl
CommonLID proves to be the most challenging dataset in our evaluation of existing LangID systems, as can be seen in the last column of the table above.
Common Crawl Foundation
@CommonCrawl
CommonLID can help us to create the next generation of open-source LangID models, which can in turn help create larger multilingual datasets. We would like to thank members of @MasakhaneNLP and @seacrowd_ai for their support in this effort.
Common Crawl Foundation
@CommonCrawl
Dataset: huggingface.co/datasets/commoncrawl/CommonLID
Preprint: www.arxiv.org/abs/2601.18026
Read the blog post:
commoncrawl.org/blog/commonlid-re-evaluating-state-of-the… -
Common Crawl Foundation
@CommonCrawl
Web Archives for Social Sciences Datathon, Bristol
Recently, a two-day Bristol datathon used Common Crawl web archives to analyse UK industries and policy, strengthening social science research through hands-on, team-based work.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
We're pleased to present community-contributed content built using Common Crawl data, hosted under the Common Crawl S3 bucket. If you have a project you'd like to contribute, please get in touch!
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
How SEOs Are Using Common Crawl's Web Graph Data for AI Ranking Signals
As SEOs grapple with the shift from traditional Search Engine Optimization to AI visibility, they're discovering a resource that's been powering AI training for years: Common Crawl's Web Graph.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
GneissWeb Annotations Examples
A new Common Crawl index annotation has been added to Hugging Face and our S3 bucket.
The methodology we followed was to take all the pages of the FineWeb dataset, see if they were included in GneissWeb, and calculate the four classification scores (medical, science, technology, educational) on the specified records.
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation
@CommonCrawl
Previous post about Common Crawl and Gneissweb:
commoncrawl.org/blog/announcing-gneissweb-annotations -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
We have two new references for how to use the CC CDXJ and Columnar indicies:
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Robert Scoble
@Scobleizer
The AI backlash is here.
This post has a million views.
People hate technology.
They hate innovation.
They see that it is coming for their jobs.
Coming for their way of life.
Innovation is asking them to do more work. To spend nights and weekends learning about AI and building new things.
They hate that. And I've seen it my entire career as people tell me over and over again that they don't like what I'm pitching them.
How many have gone to an Apple store and had a demo of the Vision Pro? Even in Silicon Valley I keep finding smart people who refuse. And my consumer research outside the valley shows far far greater resistance.
There are couple other such posts this morning going viral:
@zachweinberg: x.com/zachweinberg/status/2003103388980937157
@tszzl: x.com/tszzl/status/2002488418887168297
Here's the real problem.
Let's say you burn down Silicon Valley.
The Chinese are coming and coming with cars that will eviscerate the rest of the auto industry. Americans can't see that because we tax the heck out of them and keep them from selling here.
And soon they are coming with robots. Americans can't see that because they aren't like me meeting with robot pioneers here and in China. Or watching the robot community here on X (or understand what they are talking about with their highly technical talks about world models and reinforcement learning.
And they are coming with AI models. Most Americans are sticking their heads in the sand and ignoring what's going on on @huggingface and here on X. I talk to entrepreneurs around the world who keep telling me they are building businesses on Chinese models because they are cheaper and better.
And they are coming with entertainment businesses that will eviscerate Hollywood. Most Americans see AI artists as anti human. The Chinese don't.
The only way out of this +is+ innovation. That's where any new jobs are gonna be.
So go ahead and burn down Silicon Valley and San Francisco.
That won't save your job and will doom America to being a poor country subservient to the Chinese.
And, yes, we need to do a better job of explaining the role of innovation.
But that job is bigger than what I can do.
Why?
Because people hate innovation and want to stick their heads in the sand, and even, roll back innovation, my posts aren't getting any reach here on X outside of a small group of innovation supporters.
Well, I'll keep supporting the innovators. I made lists of almost all of them, 37,000 in AI alone, and 7,600 AI companies: x.com/scobleizer/lists
But that isn't nearly enough. The entire industry needs to do a better job of talking to everyday people and getting them to see a better world is possible.
For now all they hear is "you are taking my job."
And they aren't wrong about that either. Which makes this all so difficult to get people onto the side of innovation.
⚡︎
@_sorrengailll
My unpopular opinion / Hot Take : I actually do not desire to see technology advance any further.
-
Common Crawl Foundation
@CommonCrawl
We are pleased to announce the release of the December 2025 Crawl Archive and corresponding Web Graph release.
commoncrawl.org/blog/december-2025-crawl-archive-now-avai…
The December 2025 Crawl Archive (CC-MAIN-2025-51) fetched between December 4th and December 17th consists of 2.16 billion web pages (or 364 TiB of uncompressed content). Page captures are from 46 million hosts or 36 million registered domains and include 783 million new URLs, not visited in any of our prior crawls.
The December 2025 Web Graph release (cc-main-2025-oct-nov-dec) consists of 250.8 million nodes and 10.9 billion edges at the host level, and 121.3 million nodes and 6.2 billion edges at the domain level.
commoncrawl.org/blog/host--and-domain-level-web-graphs-oc…
commoncrawl.github.io/cc-crawl-statistics/
commoncrawl.github.io/cc-webgraph-statistics/
We hope this release is useful in your research and projects. As ever, we welcome your questions, comments, and feedback.
Warm wishes for the season from your friends at Common Crawl. -
Common Crawl Foundation
@CommonCrawl
As 2025 at Common Crawl comes to a close, we present a dozen papers from 2025 that demonstrate the range of topics and areas of study for which Common Crawl’s datasets are used and referenced.
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation
@CommonCrawl
As another year here at Common Crawl comes to a close, we present a dozen papers (selected from the thousands published in 2025) that demonstrate the range of topics and areas of study for which Common Crawl’s datasets and statistics are used and referenced. For more papers citing Common Crawl’s data, which has been regularly collected since 2008, see Research Papers and cc-citations, our curated BibTeX database.
Classification of Worldwide News Articles by Perceived Quality, 2018-2024
“This study explored whether supervised machine learning and deep learning models can effectively distinguish perceived lower-quality news articles from perceived higher-quality news articles. 3 machine learning classifiers and 3 deep learning models were assessed using a newly created dataset of 1,412,272 English news articles from the Common Crawl over 2018-2024.”
arxiv.org/abs/2511.16416
Combating Health Misinformation With Fusion-Based Credible Retrieval Techniques
“This study aims to combat health misinformation by enhancing the retrieval of credible health information using effective fusion-based techniques. … The datasets for these events are based on the CommonCrawl News dataset”
journals.sagepub.com/doi/10.1177/14604582251388860
Geospatiality: The Effect of Topics on the Presence of Geolocation in English Text Data
“This study investigates the relationship between texts’ thematic categories and their likelihood of containing usable geolocation information by quantifying and modelling this relationship across seven diverse English text datasets of different types, including web forums, microblogs, news, and magazines.” Study uses Common Crawls Distribution of Languages statistics.
www.tandfonline.com/doi/full/10.1080/13658816.2025.2460051
High-Fidelity Simultaneous Speech-To-Speech Translation
Introduces Hibiki, “a decoder-only model for simultaneous speech translation.” The “training dataset is made of filtered web pages from Common Crawl, as well as curated sources such as Wikipedia, StackExchange or scientific articles and it contains 12.5% of multilingual documents.”
arxiv.org/abs/2502.03382
Optimising Web Accessibility Evaluation: Population Sourcing Methods for Web Accessibility Evaluation
“We present a tool-supported framework, OPTIMAL-EM, that runs parallel to the Website Accessibility Conformance Evaluation Methodology (WCAG-EM). We aim to optimise web accessibility evaluation through the targeted use of automated tools and human evaluation to audit a more representative set of pages.” Uses four approaches, including Common Crawl.
www.sciencedirect.com/science/article/pii/S10715819250002…
Paraphrase Detection for Urdu Language Text Using Fine-Tune BiLSTM Framework
“This research proposes a novel bidirectional long short-term memory (BiLSTM) framework to address Urdu paraphrase detection’s intricacies.“ … The study “incorporates the GloVe approach for embedding words with 50 dimensions. [It uses] Common Crawl pre-trained vectors trained on a large amount of web-based text (42 billion tokens, 1.9 million words, 50 d vectors). “
www.nature.com/articles/s41598-025-93260-6
Reinforced Disentangled HTML Representation Learning with Hard-Sample Mining for Phishing Webpage Detection
“This study introduces a reinforced Triplet Network to optimize disentangled representation learning tailored for phishing detection…The datasets used in this study include benign data from Common Crawl and phishing data from Phishtank and Mendeley Data.”
www.mdpi.com/2079-9292/14/6/1080
Semantic Annotation Model and Method Based on Internet Open Dataset
“[T]his paper deeply studies the semantic annotation model and method based on internet open datasets, aiming to improve annotation efficiency and accuracy and promote data resource sharing and utilization. This paper selects Common Crawl dataset to provide sufficient training samples; methods such as removing stop words and deduplication are used to preprocess data to improve data quality; a keyword extraction model based on heuristic rules and text context is constructed.”
www.igi-global.com/gateway/article/370966
Scalable Private Partition Selection via Adaptive Weighting
Proposes “an algorithm for this problem, MaxAdaptiveDegree (MAD), which adaptively reroutes weight from items with weight far above the threshold needed for privacy to items with smaller weight, thereby increasing the probability that less frequent items are output.” [Uses Common Crawl datasets]
arxiv.org/abs/2502.08878
SocialQuotes: Learning Contextual Roles of Social Media Quotes on the Web
Introduces SocialQuotes, “a new data set built from the Common Crawl of over 32 million social quotes, 8.3k of them with crowdsourced quote annotations.”
ojs.aaai.org/index.php/ICWSM/article/view/35882
Temporally Extending Existing Web Archive Collections for Longitudinal Analysis
This paper introduces “a methodology to extend existing web archive collections temporally to enable longitudinal analysis, including a dataset extended with this methodology [to identify] reasons URL candidates could be missing from the … [Environmental Governance and Data Initiative] EDGI dataset, and crawled the past web of 2008 in order to identify these missing pages.” Includes Common Crawl, in addition to Internet Archive and the End of Term Archive.
arxiv.org/abs/2505.24091
Web2Wiki: Characterizing Wikipedia Linking Across the Web
Presents “the first large-scale analysis of how Wikipedia is referenced across the Web. Using a dataset from Common Crawl [it identifies] over 90 million Wikipedia links spanning 1.68% of Web domains and examine their distribution, context, and function.”
arxiv.org/abs/2505.15837
With over 10,000 research papers referencing Common Crawl’s dataset, we are constantly surprised by the myriad ways in which our dataset is useful for academic research. We look forward to being surprised again in 2026! -

Common Crawl Foundation
@CommonCrawl
We are pleased to announce the release of the web graphs based on the crawls of September, October, and November of 2025, consisting of 235.7 million nodes and 9.5 billion edges at the host level, and 100.7 million nodes and 6.6 billion edges at the domain level.
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
This is an abridged version of a keynote given by @jedsundwall at the 2025 Chan Zuckerberg Initiative Open Science Meeting.
radiant.earth/blog/2025/11/great-data-products/ -
Post not available here, view on X
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
bookofjoe
@bookofjoe
"You shouldn't have put your content on the internet if you didn't want it to be on the internet."
— Common Crawl's executive director Rich Skrenta -
Common Crawl Foundation
@CommonCrawl
Common Crawl Celebrates World Digital Preservation Day
CCF celebrates World Digital Preservation Day, which invites the community to unite in answering a powerful question: Why Preserve?
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Rich Skrenta
@skrenta
France is trying to delete French from the Internet
-
Common Crawl Foundation
@CommonCrawl
Setting the Record Straight: Common Crawl’s Commitment to Transparency, Fair Use, and the Public Good
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Identifying Rare Languages in Common Crawl Data is a Needles-in-a-Haystack Problem
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation October/November 2025 Newsletter! Montreal, SF and Stanford. :)
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
www.youtube.com/watch?v=_73V4bnEk3U
This Stanford HAI seminar featured Common Crawl Foundation’s work on preserving humanity's knowledge and making it accessible through its free public web dataset. -
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation would like to thank Stanford HAI for the opportunity to present this week:
"Preserving Humanity's Knowledge and Making it Accessible:"
We appreciate Patrick Hynes and Professor Diyi Yang for hosting us!
(link to followup post and PDF slides in replies)
Common Crawl Foundation
@CommonCrawl
commoncrawl.org/blog/common-crawl-foundation-at-stanford-hai
Common Crawl Foundation
@CommonCrawl
PDF slides here :)
raw.githubusercontent.com/commoncrawl/presentations/refs/… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Common Crawl EU crew making the mandatory Palo Alto Apple store pilgrimage for adapters
-
Common Crawl Foundation
@CommonCrawl
#wmdqs #colm_conf #commoncrawl
Workshop on Multilingual Data Quality Signals
@wmdqs
In collaboration with @CommonCrawl @MLCommons @AiEleuther, the first edition of WMDQS at @COLM_conf starts tomorrow in Room 520A! We have an updated schedule on our website, including a list of all accepted papers.
-
Common Crawl Foundation
@CommonCrawl
Common Crawl has added IBM’s GneissWeb quality and category annotations to its web dataset, enabling users to filter high-quality content and explore topics like medical, education, and technology.
commoncrawl.org/blog/announcing-gneissweb-annotations -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Stanford HAI
@StanfordHAI
“When only a few have the resources to build and benefit from AI, we leave the rest of the world waiting at the door,” said @StanfordHAI Senior Fellow @YejinChoinka during her address to the @UN Security Council. Read her full speech here: hai.stanford.edu/policy/yejin-chois-briefing-to-the-unite…
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation Opt-Out Registry
Publishers have been sending Common Crawl legal opt-out requests. In the interest of transparency and to better serve our ecosystem, we are publishing the full opt-out list for every legal request we have received.
Why We're Doing This
We have many downstream users who are not aware of the legal notices we have received. On behalf of the broader ecosystem, we want to alert our users about material that content owners have specifically requested to be excluded from our crawls.
About Common Crawl
Common Crawl is a free, non-commercial archive of the public web that has operated for 18 years. We have never charged for access to our data, and our datasets have been cited in over 10,000 research papers.
Each month, we crawl several billion new pages from our frontier of over 1 trillion pages, supporting research in web science, natural language processing, internet security research, the humanities, and other fields.
Our Commitment
We respect content owners' rights and are committed to honoring legitimate opt-out requests. We encourage publishers to use standard methods like robots.txt files to control crawling, and we willcontinue to process legal requests as they are received.
Moving Forward
We will be updating our "Opt-Out Registry" on an ongoing basis as we receive new requests. This
initial publication represents our commitment to transparency with both content creators and the
research community that relies on our data.
For questions about opt-out procedures or to submit requests, please contact us at info@commoncrawl.org
To configure how our crawler (CCBot) interacts with your website, visit:
commoncrawl.org/ccbot
The Common Crawl Opt-Out registry can be viewed here:
docs.google.com/spreadsheets/d/1uavIZ-Y2ew-Vj7d0_pY67SGD2… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
On October 22, the Common Crawl team will lead a seminar at Stanford HAI. Our topic of discussion is “Preserving Humanity's Knowledge and Making it Accessible: Addressing Challenges of Public Web Data”. Space is limited for those attending in-person.
There is also an option to join virtually if you are not located in the Bay Area.📷 Please register at:
hai.stanford.edu/events/common-crawl-foundation-preservin… -
Common Crawl Foundation reposted
Fishon 💡
@fishon_amos
My latest article "Train-Set SEO: Why Embedding Your Brand in AI’s DNA is the Future of Search Optimization" just got published on @hackernoon 💚💚
hackernoon.com/train-set-seo-why-embedding-your-brand-in-… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Thank you, Leo, Jeff and Paris, for the opportunity to talk about AI and Common Crawl on TWiT! I really enjoyed the conversation!
@leolaporte @jeffjarvis @parismartineau
twit.tv/shows/intelligent-machines/episodes/833 -
Common Crawl Foundation reposted
clem 🤗
@ClementDelangue
We don’t give nearly enough credit to the people and organizations who build and share open AI datasets.
In fact, I’d argue they matter even more than open models:
- they’re foundational, enabling hundreds of different models
- they remove not only technical but also legal bottlenecks for democratization of AI building
- their impact usually lasts longer, since datasets are less tied to the latest training fad.
Let’s celebrate the teams who are sharing open datasets today. Who are your favorite ones?
Guilherme Penedo
@gui_penedo
> SmolLM3
> GLM-4.5
> NVIDIA-Nemotron-Nano
These are just some of the recent OS releases relying on 🥂 FineWeb2 for their multilingual data
Proud that the community trusts us for their data supply 🫡 -
Common Crawl Foundation
@CommonCrawl
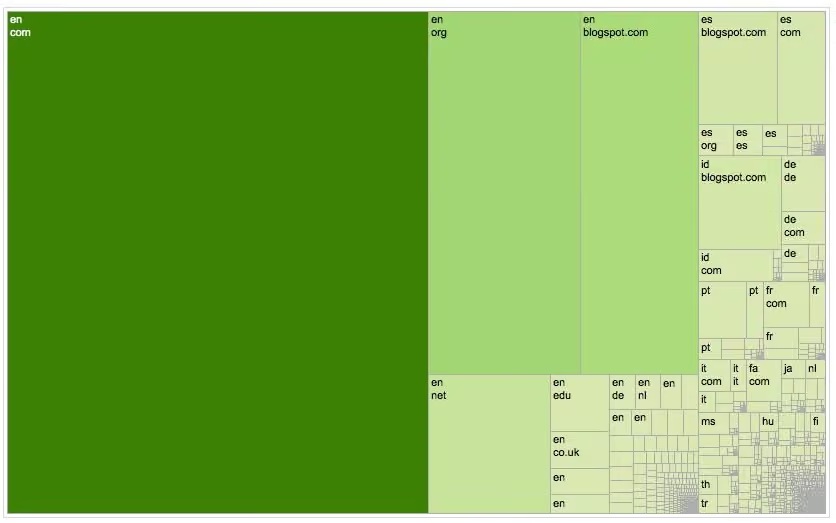
Common Crawl Foundation wants to expand its language diversity. We're currently 43% English. Pedro Ortiz Suarez from our team published a paper related to this. We are excited to push this forward!
arxiv.org/abs/2503.06547 -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
blogs.microsoft.com/on-the-issues/2025/07/20/eudigitalunl…
"MOIC will also partner with Common Crawl, one of the largest free and open repositories of web crawled data. MOIC will fund work at Common Crawl, leveraging native speakers to annotate and seed European language data in the publicly available Common Crawl data set." -
Common Crawl Foundation reposted
Catherine Arnett @ EMNLP 🇭🇺
@linguist_cat
One of the biggest obstacles to improving language technologies for low-resource languages is the lack of data. To address this, we need better language identification tools. So, we're organizing a shared task on Language Identification for Web Data!
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation, together with IBM, the AI Alliance, and BrightQuery will be hosting an "UN Conference" at IBM's new flagship NYC HQ at One Madison Avenue on Friday, June 20, from 12:30-5pm.
If you are in NYC or will be attending the UN Open Source Week, it would be great to see you there! We will have talks about AI, policy, and responsible data.
lu.ma/p0a1scde
#unopensourceweek #ibm #brightquery #ai -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Constellation²
@Conste11ation
"The most valuable resource isn't data, it's the ability to transform data from an abundant commodity into verified intelligence"
- Ben Jorgensen, Constellation CEO
Constellation’s new product, Digital Evidence, launched @DigitalChamber DC Summit!
🌐constellationnetwork.io/digital-evidenceThis media couldn't be displayed. See it on the original post. -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
ReadyAI
@ReadyAI_
Excited to launch our partnership with @CommonCrawl to enhance tools and datasets for AI researchers
First up, the Common Crawl Agent: commoncrawl.org/ai-agent
ReadyAI’s structured data pipeline turns thousands of records into detailed insights to get you started training AI today
David Fields
@DavFields
The single largest source of data for GPT, Llama and EVERY SOTA model is @CommonCrawl
Couldn't be more excited to announce @ReadyAI_ has partnered w/@CommonCrawl to enhance tools and datasets for AI researchers. Our first collab...the Common Crawl Agent.
Try it here 👇
commoncrawl.org/ai-agent
ReadyAI’s structured data pipeline converts thousands of records into metadata enhanced vector embeddings for extremely accurate insights, helping AI researchers and developers quickly build, test, and deploy smarter models.
More details on the partnership here: readyai.ai/p/readyai_x_common_crawl -
Common Crawl Foundation
@CommonCrawl
Our friends at Webrecorder have announced the launch of govarchive.us, a dedicated site for exploring their US Government Web Archive on Browsertrix. More details in their blog post: webrecorder.net/blog/2025-03-25-govarchive-us-and-mirrori…
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
February 2025 Crawl Archive Now Available
The data was crawled between February 6th and February 20th, and contains 2.6 billion web pages. Page captures are from 47.6 million hosts or 38.5 million registered domains and include 1 billion new URLs not visited in any of our prior crawls.
www.commoncrawl.org/blog/february-2025-crawl-archive-now-… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
www.commoncrawl.org/blog/opening-the-gates-to-online-safety
Last week in Paris, at the AI Action Summit, a coalition of major technology companies and foundations announced the launch of ROOST: Robust Online Open Safety Tools -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Pedro Ortiz Suarez
@pjox13
I’ll be today at the AI Action Summit in Paris, if you’re attending and want to discuss about @CommonCrawl or about open data, please DM me!
-
Common Crawl Foundation
@CommonCrawl
www.commoncrawl.org/blog/january-february-2025-newsletter
We’re happy to share our January/February 2025 newsletter with updates and insights from the world of open data and web archiving. -
Common Crawl Foundation
@CommonCrawl
We are pleased to announce a new release of host-level and domain-level web graphs based on the crawls of November, December 2024 and January 2025. The host-level graph consists of 277.7 million nodes and 2.7 billion edges, and the domain-level graph has 100.8 million nodes and 1.9 billion edges.
www.commoncrawl.org/blog/host--and-domain-level-web-graph… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
We are happy to announce cc-downloader, an experimental command-line tool for downloading Common Crawl data via https:
www.commoncrawl.org/blog/introducing-cc-downloader -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Markus Kliegl
@MarkusKliegl
We are excited to release Nemotron-CC, our high quality Common Crawl based 6.3 trillion tokens dataset for LLM pretraining (4.4T globally deduplicated original tokens and 1.9T synthetically generated tokens).
Compared to the leading open DCLM dataset, Nemotron-CC enables to either create a 4x larger dataset of similar quality or increase the MMLU by more than 5 points using a high quality subset of the tokens.
Blog post: research.nvidia.com/labs/adlr/Nemotron-CC/
Paper: arxiv.org/abs/2412.02595
Dataset: data.commoncrawl.org/contrib/Nemotron/Nemotron-CC/index.html
We thank the Common Crawl Foundation for hosting the dataset.
(with @SudanSudanDan *, Ying Lin*, @KezhiKong*, Joseph Jennings, @BrandonNor90881, @MostofaPatwary, @MohammadShoeybi, @ctnzr) -
Common Crawl Foundation reposted
MLCommons
@MLCommons
Announcing the release of AILuminate, a first-of-its kind benchmark to measure the safety of LLMs. The AILuminate v1.0 benchmark offers a comprehensive set of safety grades for today's most prevalent #llms. mlcommons.org/2024/12/mlcommons-ailuminate-v1-0-release/
(1/4) -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
OcciGlot
@occiglot
📣Community Call
Contribute to LLM pre-training resources in (your) unrepresented language!
Please submit any websites in that language to @CommonCrawl's web language project.
They will help increase non-english data in future releases.
github.com/commoncrawl/web-languages -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
We're spinning up another account on the friendly skies. Follow us there if you like as well.
bsky.app/profile/commoncrawl.bsky.social
🦋 -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
commoncrawl.org/blog/reflections-on-recent-talks-at-the-t…
Reflections on Recent Talks at the Turing Institute and UCL
Thom Vaughan and Pedro Ortiz Suarez discussed the power of Common Crawl’s open web data in driving research and innovation during two notable presentations last week -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
www.commoncrawl.org/blog/october-2024-crawl-archive-now-a…
The data was crawled between October 3rd and October 16th, and contains 2.49 billion web pages . Page captures are from 47.5 million hosts or 38.3 million registered domains and include 1.03 billion new URLs, not visited in any of our prior crawls. -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
suchit
@asquirous
So we processed ~24TBs of @CommonCrawl data on @ApacheSpark and open-sourced the datasets.
Has server name, ip, host, script tags' src attributes, etc., and it's enriched with geolocation data from @maxmind!
Available on @huggingface 🤗
(link in thread) 🧵 -
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation had the privilege of participating in a groundbreaking workshop hosted by the Internet Architecture Board (IAB) in Washington DC.
www.commoncrawl.org/blog/iab-workshop-on-ai-control -
Common Crawl Foundation
@CommonCrawl
We're happy to announce the release of our September crawl and Web Graph release.
The September crawl consists of 2.8 billion web pages, and the corresponding Web Graph consists of 306.5 million nodes and 2.6 billion edges.
commoncrawl.org/blog/september-2024-crawl-archive-now-ava… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Jackie McGuinness
@jackie_mcg
On this 30th anniversary of the Violence Against Women's Act, @WHOSTP is annoucning commitments from leading tech companies, including @OpenAI, @Microsoft, @Adobe, @AnthropicAI, @cohere, and @CommonCrawl, to curb the creation of image-based sexual abuse. www.whitehouse.gov/ostp/news-updates/2024/09/12/white-hou…
-
Common Crawl Foundation
@CommonCrawl
commoncrawl.org/blog/august-september-2024-newsletter
August/September 2024 Newsletter
- Common Crawl Citations in Academic Research
- Common Crawl Statistics on Hugging Face
- Monthly Crawl Updates
- Updates on our Policy Efforts
- Roadmap and Future Plans -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
We are pleased to announce a new release of host-level and domain-level web graphs based on the crawls of June, July, August 2024. The crawls used to generate the graphs were CC-MAIN-2024-33, CC-MAIN-2024-30, and CC-MAIN-2024-26.
www.commoncrawl.org/blog/host--and-domain-level-web-graph… -
Common Crawl Foundation
@CommonCrawl
Practically Intelligent podcast w/ Common Crawl:
- The importance of curated data in AI training
- Challenges of expanding Common Crawl globally
- The future of open internet access in the AI era
www.youtube.com/watch?v=J46mp8w74AM -
Common Crawl Foundation
@CommonCrawl
The crawl archive for August 2024 is now available. The data was crawled between August 3rd and August 16th, and contains 2.3 billion web pages (or 327.4 TiB of uncompressed content)
www.commoncrawl.org/blog/august-2024-crawl-archive-now-av… -
Common Crawl Foundation
@CommonCrawl
Congrats to the Allen AI team for two Best Paper awards at ACL!
Jesse Dodge
@JesseDodge
Congrats to our team for winning two paper awards at #acl2024!
OLMo won the Best Theme Paper award, and Dolma won a Best Resource Paper award!
All the credit goes to the whole team for the massive group effort 🎉🎉 -
Common Crawl Foundation
@CommonCrawl
Common Crawl's impact on research has grown substantially since its beginning. Our crawls have become a vital resource for researchers in various fields, from natural language processing to red teaming.
www.commoncrawl.org/blog/the-increase-of-common-crawl-cit… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
We're happy to announce that the July 2024 crawl is now available, containing 2.5 billion web pages. Two new WARC headers were introduced in this crawl with information relating to the HTTP protocol. Please see our post for more information.
www.commoncrawl.org/blog/july-2024-crawl-archive-now-avai… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Glad to see @ShayneRedford 's significant research getting prominent coverage.
www.nytimes.com/2024/07/19/technology/ai-data-restriction…
www.dataprovenance.org/consent-in-crisis-paper -
Common Crawl Foundation reposted
Cohere Labs
@Cohere_Labs
Build the future of evals in your languages. 💬
We are releasing a new MMLU evaluation set which has been verified by native speakers. After auditing for Western centricity, we will release publicly for others to build on and continue to research. ✨ -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Quentin Lhoest 🤗
@lhoestq
The @CommonCrawl team just released all their statistics publicly ! And across all dumps, including the more recent one 🙌
Now is the time to finally analyze what's inside the source of most pre-training datasets out there 👀
1/n -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
📷 Check out NVIDIA NeMo Curator - This GPU-accelerated data-curation library includes data download, document deduplication, language identification, filtering, and other features often requested by Common Crawl users. Helpful for preparing large-scale, high-quality datasets for pretraining and customization. Learn more here: github.com/NVIDIA/NeMo-Curator
@NVIDIAAI -
Common Crawl Foundation reposted
Emmanouil Tranos
@EmmanouilTranos
We will use web data from our partner, the @CommonCrawl, to map economic activities in the UK at an unprecedented level of detail. We will develop data products, papers and tools for the continuous monitoring and mapping of economic activities.
www.sdruk.ukri.org/2024/05/21/funding-new-smart-data-rese… -
Common Crawl Foundation
@CommonCrawl
arxiv.org/pdf/2404.10006
"There are many public collections of web crawls, but one that is known for being very reliable and quite wide in scope is the Common Crawl. Common Crawl’s measurements are preferred for web and network analysis due to their extensive coverage, regular updates, and large-scale, publicly accessible datasets, which reduces the need for resource-intensive data collection and is applicable across various research in a reproducible way." -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Pedro Ortiz Suarez
@pjox13
The May 2024 main crawl is out! 🚀📚
This is a very special release for us, as this is officially our 100th crawl! 🥳🎉🎊
As always, please let us know if you have any feedback! 📝
And happy data crunching! 🧑💻
Common Crawl Foundation
@CommonCrawl
commoncrawl.org/blog/may-2024-crawl-archive-now-available
Our 100th crawl!! -
Common Crawl Foundation
@CommonCrawl
commoncrawl.org/blog/may-2024-crawl-archive-now-available
Our 100th crawl!! -
Common Crawl Foundation reposted
IIPC
@NetPreserve
We’re excited to announce that #iipcga25 and #iipcwac25 will be hosted by the National Library of Norway in Oslo. We look forward to working with the @Nettarkivet Team!
#webarchives | #webarchiving | #digitalpreservation -
Common Crawl Foundation reposted
SutherlandGold
@SutherlandGold
Our May newsletter is out! www.linkedin.com/pulse/may-2024-sutherlandgold-group-ajjxc/
Last month, we got together with some of the smartest people we know to unpack
⚪️ @CommonCrawl's #ai & The Right to Learn on an #openinternet event
⚪️ How to write compelling #content, with @zornkell
⚪️ @RSAConference 2024 -
Common Crawl Foundation reposted
Pete Skomoroch
@peteskomoroch
If you want better LLMs, a high impact place to make improvements is improving the coverage of @CommonCrawl. Common Crawl is a nonprofit web crawl that has historically focused on breadth, not completeness. It’s a statistical sample limited by the organization’s crawl resources and open source contributions to the codebase. In some cases a website with 1000 pages might only have one crawled page in the common crawl dataset. Lots of gains to be made at the bottom of the stack.
Ethan Mollick
@emollick
Teach your AIs well: more evidence that data with high educational value for humans is the best training data for LLMs. Interesting discussion of AI training from different datasets here: huggingface.co/spaces/HuggingFaceFW/blogpost-fineweb-v1
-
Common Crawl Foundation reposted
Anjney Midha
@AnjneyMidha
SB 1047 will force most AI startups to leave California.
All because @Scott_Wiener tried to rush a shoddy piece of AI regulation while no one was looking
Rohan Pandey
@khoomeik
Dove into the "covered model" definitions in SB 1047 (Sec. 3f2). This is absurd.
⬇️🧵 on why scaling laws mean that virtually *all LLM's could come under govt supervision* by SB 1047 if a well-funded entity decides to train a suboptimal model this year. -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
The Web Graph covering our three most recent crawls (CC-MAIN-2023-50, CC-MAIN-2024-10, and CC-MAIN-2024-18) is now available.
commoncrawl.org/blog/host-and-domain-level-web-graphs-nov… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
SutherlandGold
@SutherlandGold
We're thrilled to be part of @CommonCrawl's "#ai & The Right to Learn on an Open Internet" conference. The day started strong with remarks from @jeffjarvis, @craignewmark, @gilelbaz, and @skrenta.
-
Common Crawl Foundation reposted
Amy Chen
@iamamychen
Common Crawl Foundation founder @gilelbaz started this 17 years ago to make accessible this web scale dataset for researchers, developers, entrepreneurs, inventors etc. Now @skrenta leads a team of ‘archivists’ & ‘librarians’ enabling 10 petabytes of open data for our AI future
-
Common Crawl Foundation reposted
MLCommons
@MLCommons
We are excited to announce the release of an @MLCommons AI Safety benchmark POC. Built through an inclusive decision-making and engineering process, the POC validates our approach to a v1.0 AI Safety benchmark suite. Learn more: mlcommons.org/2024/04/mlc-aisafety-v0-5-poc/
#ai, #benchmarks -
Common Crawl Foundation
@CommonCrawl
Are you a fan of both Common Crawl and Discord? If so, join the Common Crawl Foundation's new Discord server!
discord.com/invite/njaVFh7avF -
Common Crawl Foundation reposted
Jeff (Hot Type) Jarvis
@jeffjarvis
Reupping this for California folk because I posted this before you all woke up this morning. My analysis of the California Journalism Preservation Act:
drive.google.com/drive/folders/1mJYxDwrSgIDjKVzUQlKRZG_I7…
Jeff (Hot Type) Jarvis
@jeffjarvis
Today I'm releasing a major paper on California's Journalism Preservation Act (& its federal cousin, JCPA): its weaknesses; the history of news & copyright; newspapers' long history of fighting new technologies & competitors--and alternative solutions. 1/
drive.google.com/file/d/1HHcDuUW8ca3il1bAc6lzqG_4PTe-O40L… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
LF AI & Data Foundation
@LFAIDataFdn
Today, Gen AI Commons launches the LF AI & Data Outreach Survey which is designed to help us better understand the community’s insights and perspectives on #opensource and #generativeai.✔️
🔗 Learn more and take the survey: lfaidata.foundation/blog/2024/03/13/generative-ai-commons… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation is happy to join NIST's new U.S. AI Safety Institute Consortium in support of efforts to create safe and trustworthy AI. Learn more: www.nist.gov/artificial-intelligence/artificial-intellige…
National Institute of Standards and Technology
@NIST
Today, @CommerceGov announced the formation of the NIST-administered U.S. AI Safety Institute Consortium, which will unite government and industry with AI developers and users. Read more: www.nist.gov/news-events/news/2024/02/biden-harris-admini…
-
Common Crawl Foundation
@CommonCrawl
Common Crawl is hiring!
www.linkedin.com/jobs/view/3813107017/ -
Common Crawl Foundation reposted
Rich Skrenta
@skrenta
Had a great time chatting with @jasonhowell and @jeffjarvis on their new podcast @AIInsideShow about @CommonCrawl, AI, and the Right to Learn - even for machines
aiinside.show/episode/ai-positive
www.youtube.com/watch?v=VTEdIkHY3cE&t=3m09s -
Common Crawl Foundation reposted
Jason Howell
@jasonhowell
Tomorrow is the PREMIERE episode of @AIInsideshow! Live stream kicks off Wednesday, January 24 at 11 am PT/2 pm ET. @jeffjarvis and I welcome @skrenta from Common Crawl to the show!
Subscribe: aiinside.show
Support: patreon.com/aiinsideshow
Live: www.youtube.com/watch?v=VTEdIkHY3cE -
Common Crawl Foundation
@CommonCrawl
Great interview about open data with Common Crawl's @pjox13 and Thom at the recent Paris AI-Pulse conference #scaleway #aipulse
www.youtube.com/watch?v=hmlWY2BQGyI -
Common Crawl Foundation reposted
Joe Amditis
@jsamditis
Watch Jeff's full opening remarks here: youtu.be/tX26ijBQs2k
-
Common Crawl Foundation reposted
Jeff (Hot Type) Jarvis
@jeffjarvis
Here are the remarks without a wall on Buzzmachine: buzzmachine.com/2024/01/09/journalism-and-ai/
-
Common Crawl Foundation
@CommonCrawl
Common Crawl Foundation is proud to benefit from generous support from DuckDuckGo. From all of us at CCF, and on behalf of all of the users of our dataset, thank you!
DuckDuckGo
@DuckDuckGo
Everyone using the Internet deserves simple and accessible online privacy.
We're proud to donate $1.1M to organizations that are working to make that a reality.
This is made possible through your ongoing support of DuckDuckGo — thank you! 🎉 spreadprivacy.com/2023-duckduckgo-charitable-donations/ -
Common Crawl Foundation
@CommonCrawl
After the US holiday weekend, starting with the European morning, our aggressive downloaders have returned. Please see our status page for the details of maximizing download speeds despite 503 Slow Down errors.
status.commoncrawl.org -
Common Crawl Foundation
@CommonCrawl
Our blog post about October/November 2023 performance issues accessing Common Crawl:
commoncrawl.org/blog/oct-nov-2023-performance-issues -
Common Crawl Foundation reposted
Together AI
@togethercompute
We are excited to release RedPajama-Data-v2: 30 trillion filtered & de-duplicated tokens from 84 CommonCrawl dumps, 25x larger than our first dataset.
It exposes a diverse range of quality annotations so you can slice & weight the data for LLM training.
together.ai/blog/redpajama-data-v2 -
Common Crawl Foundation reposted
Geoffrey Hinton
@geoffreyhinton
New paper:
managing-ai-risks.com
Companies are planning to train models with 100x more computation than today’s state of the art, within 18 months. No one knows how powerful they will be. And there’s essentially no regulation on what they’ll be able to do with these models. -
Common Crawl Foundation
@CommonCrawl
Excited to see this new effort related to AI safety from MLCommons. Looking forward to supporting and participating in this effort.
David Kanter
@TheKanter
Excited to announce a new AI Safety working group. Composed of experts in industry and academia, we will build a platform and tests for industry-standard AI safety testing–helping to realize AI benefits while minimizing risk.
mlcommons.org/en/news/formation-ai-safety-working-group/ -
Common Crawl Foundation
@CommonCrawl
We are pleased to announce a new release of host-level and domain-level web graphs based on the crawls of March, May, and October 2023. The host-level graph consists of 378 million nodes and 2.6 billion edges, and the domain-level graph has 94 million nodes and 1.69 billion edges.
www.commoncrawl.org/blog/host-and-domain-level-web-graphs… -
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation reposted
Lesley Frew
@lesley_elis
This #webarchivewednesday check out the 3 part blog series on @openpreserve "Monitoring Disappearing File Formats" - @reinvantveer used data such as @CommonCrawl to investigate the obsolescence of formats on the web. Some expected (ColdFusion) and others a surprise (GIF)! (1/2)
-
Common Crawl Foundation
@CommonCrawl
Common Crawl will be at ICML 2023! DM if you'd like to meet up and chat. #icml #icml2023 #commoncrawl
-
Common Crawl Foundation
@CommonCrawl
Common Crawl is happy to have contributed to this updated open-source robots.txt parser, so that we can continue to strictly obey robots.txt rules with our crawling.
Sebastian Nagel
@sebnagel
Released #crawlercommons 1.4: Java 11, #robotstxt parser compliant with #rfc9309 - github.com/crawler-commons/crawler-commons
-
Common Crawl Foundation
@CommonCrawl
We're joining this @Google group discussion on news protocols to supplement robots.txt. You should too. blog.google/technology/ai/ai-web-publisher-controls-sign-up/ #respectforpublishers
-
Common Crawl Foundation
@CommonCrawl
The May/June 2023 crawl is now available. 3.1 billion web pages from 44 million hosts, including 1 billion new URLs, not visited in any of our prior crawls.
commoncrawl.org/2023/06/may-june-2023-crawl-archive-now-a… -
Common Crawl Foundation
@CommonCrawl
Common Crawl is at the @hplt_eu #hackathon in Prague this week. If you're nearby, come say hi!
hplt-project.org/hackathon2023 -
Common Crawl Foundation
@CommonCrawl
"We ran a case study on the Common Crawl web archive and processed them using the Let's Data infrastructure at high scale and saw staggering results. We processed 219K files, 477 TB S3 uncompressed data in 48 hours at a nominal cost of $5 per TB-Hour!" www.letsdata.io
-
Common Crawl Foundation reposted
Kingsley Uyi Idehen
@kidehen
Latest #webdatacommons data corpus - #structureddata sourced from @CommonCrawl (Nov 2017) covering 3.2 billion HTML docs across 26 million websites: webdatacommons.org/structureddata/2017-12/stats/stats.html. #rdf #semanticweb #linkeddata #nosql #graphdb #knowledgegraph #microdata #jsonld #rdfa #microformat
-
Common Crawl Foundation
@CommonCrawl
Need 3 billion web pages in WARC, WAT, and WET? Here you go! #opendata commoncrawl.org/2017/09/september-2017-crawl-archive-now-…
-
Common Crawl Foundation
@CommonCrawl
Check it out! "Common Crawl And Unlocking Web Archives For Research" via @forbes www.forbes.com/sites/kalevleetaru/2017/09/28/common-crawl…
-
Common Crawl Foundation
@CommonCrawl
We're hiring! Want to download billions of web pages per month using hundreds of servers? Join our #opendata team! commoncrawl.org/jobs
-
Common Crawl Foundation reposted
IIPC
@NetPreserve
We want YOUR ideas for the IIPC General Assembly 2016 - new blog post netpreserveblog.wordpress.com/2015/09/16/we-want-your-ide… #webarchiving
#iipcga16 -
Common Crawl Foundation reposted
Amitabha Roy
@roy_amitabha
Busting graph processing myths with Chaos and @CommonCrawl
amitabharoy.wordpress.com/2015/09/11/busting-graph-proces… -
Common Crawl Foundation
@CommonCrawl
Great progress! Can't wait for @zhengda1936 to evaluate #aws FlashGraph with the Web Data Commons hyperlink graph!
Da Zheng
@zhengda1936
FlashGraph is much faster and more economical than distributed graph engines in the cloud www.flashgraph.net/blog/flashgraphismuchfasterandmuchmore… @Smerity @Frankmcsherry
-
Common Crawl Foundation
@CommonCrawl
For those slow days you need 145 terabytes of the web, the July crawl with 1.81 billion web pages is now live!
blog.commoncrawl.org/2015/08/july-2015-crawl-archive-avai… -
Common Crawl Foundation reposted
Justin Seitz
@jms_dot_py
Using Python to Mine Common Crawl | Automating OSINT Blog
automatingosint.com/blog/2015/08/osint-python-common-crawl/
@smerity @commoncrawl @bellingcat #python #osint -
Common Crawl Foundation reposted
@mikko
Interesting project: commoncrawl.org is dedicated to providing A COPY OF THE INTERNET to researchers at no cost.
Cc @CommonCrawl #2pb -
Common Crawl Foundation reposted
Smerity
@Smerity
Slides from "@CommonCrawl: the whole web as your dataset"
slides.com/smerity/dato-whole-web-as-your-dataset
#datasmt -
Common Crawl Foundation
@CommonCrawl
GraphLab Create (@datoinc) made huge speed gains on processing the #webdatacommons 128B edge hyperlink graph
#datasmt -
Common Crawl Foundation reposted
-
Common Crawl Foundation reposted
Kristinn Sigurðsson
@kristsi
A minor release of webarchive-commons, 1.1.6, was made yesterday. groups.google.com/d/msg/openwayback-dev/ylnaHvRdzpM/xwZo0…
-
Common Crawl Foundation reposted
WikiResearch
@WikiResearch
What’s trending in Wikipedia? Trend comparison and pageview analytics by @vitribyte: www.vitribyte.com
-
Common Crawl Foundation reposted
Pete Skomoroch
@peteskomoroch
The arXiv as Dataset blog.lateral.io/2015/07/harvesting-research-arxiv/ via @uselateral
-
Common Crawl Foundation reposted
Russ Salakhutdinov
@rsalakhu
Releasing BookCorpus: 11,038 books dataset that we used to train skip-thought vectors
www.cs.toronto.edu/~mbweb/
Encoder github.com/ryankiros/skip-thoughts -
Common Crawl Foundation
@CommonCrawl
The May 2015 crawl archive (2.05 billion webpages) has been released along with the URL index for random lookup!
blog.commoncrawl.org/2015/07/may-2015-crawl-archive-avail… -
Common Crawl Foundation reposted
Keith Resar
@KeithResar
Awesome status updates in @Slack - scouring @CommonCrawl corpus to generate latest Ngrams analysis for @prospellerweb
-
Common Crawl Foundation reposted
Knight Foundation
@knightfdn
Great panel at #alaac15 today: Digital archiving for humans – at 1030 am w/ @dpla @internetarchive @PopUpArchive kng.ht/1GVcgqH
-
Common Crawl Foundation reposted
SF Text
@Sf_text
Video: (via www.youtube.com/watch?v=RjJDLKObas0) The Common Crawl corpus contains petabytes of web... tmblr.co/ZtBdGy1msf3LB
-
Common Crawl Foundation reposted
Adrian Colyer
@adriancolyer
Is our focus on scalability at all costs leading us down the wrong path? blog.acolyer.org?p=941
-
Common Crawl Foundation reposted
Webrecorder
@webrecorder_io
beta.webrecorder.io now has a new 'patch' mode to update existing recordings with any missed content that was not recorded initially.
-
Common Crawl Foundation reposted
Fw:Thinking
@FwThinking
Pre-recording banter from last week, via @howstuffworks: instagram.com/p/3W6vt3Rlwj/ (Expect an episode on @CommonCrawl soon!)
-
Common Crawl Foundation
@CommonCrawl
The April 2015 crawl archive has been released: more than 2.11 billion webpages for you to analyze, completely free!
blog.commoncrawl.org/2015/05/april-2015-crawl-archive-ava… -
Common Crawl Foundation reposted
arnaud gaudinat
@AGaudinat
2 new index index.commoncrawl.org from #commoncrawl, one for 2014 and the last for April 2015. Thanks for #bigopendata contribution.
-
Common Crawl Foundation
@CommonCrawl
Thiébaud Weksteen uses @CommonCrawl data for web application testing in "What one may find in robots.txt"
xn--thibaud-dya.fr/robots.txt.html -
Common Crawl Foundation
@CommonCrawl
Want to review @Smerity's presentation on internet scale analytics from #biganalyticsisrael? View the slides online!
slides.com/smerity/internet-scale-analytics-with-common-c… -
Common Crawl Foundation
@CommonCrawl
.@datoinc's @guestrin: 9 min PageRank iteration on WDC Linkgraph (128 bln edges) w/ single node!
#biganalyticsisrael
webdatacommons.org/hyperlinkgraph/ -
Common Crawl Foundation reposted
Smerity
@Smerity
Just kicked off #biganalyticsisrael with @bigdata & @ronkasabian - 700+ attendees! Excited to present on @CommonCrawl
-
Common Crawl Foundation reposted
Martin Potthast
@martinpotthast
In the end, it took about 9 days to complete the download of one @CommonCrawl (WARC files only). Next up: Indexing. x.com/martinpotthast/status/591178287646384128/photo/1
-
Common Crawl Foundation reposted
Smerity
@Smerity
Liking word vectors? Check out GloVe - largest model is 840bn tokens from @CommonCrawl vs 100bn word2vec model! #tbtb
nlp.stanford.edu/projects/glove/ -
Common Crawl Foundation reposted
Raymond Yee (@rdhyee@social.tchncs.de)
@rdhyee
Definitely true that @CommonCrawl is great. I hope companies that profit from it will send $ to it. x.com/wiseio/status/592343638216155136
-
Common Crawl Foundation reposted
Ben Lorica 罗瑞卡
@bigdata
Automated trading on Internet content - high-speed trading via web-reading bots slate.com/business/2015/04/bot-makes-2-4-million-reading-…
-
Common Crawl Foundation reposted
Adrien Barbaresi
@adbarbaresi
An example of analysis using data from the CommonCrawl to gather business telephone numbers engineeringblog.yelp.com/2015/03/analyzing-the-web-for-th…
-
Common Crawl Foundation reposted
WikiResearch
@WikiResearch
Where does information in Wikipedia come from? Visualizing geoprovenance by @shiladsen et al. shilad.com/localness/
-
Common Crawl Foundation reposted
@Lambo@openbiblio.social - Lambert Heller
@Lambo
Web crawling is much larger than Google! Great article by @bit_player on @CommonCrawl - refers even to Paul Otlet :)
American Scientist
@AmSciMag
Crawling Toward a Wiser Web With @CommonCrawl: www.americanscientist.org/issues/pub/2015/3/crawling-towa… #compsci #data #science
-
Common Crawl Foundation reposted
Jason Scott
@textfiles
Wow. AMAZING. Pizza Hut STILL hosts the very first commerce page on the WWW. www.pizzahut.com/assets/pizzanet/home.html (Different URL, but still)
-
Common Crawl Foundation reposted
John Lilly
@johnolilly
Congrats on the #time100 @reidhoffman! time.com/3822665/reid-hoffman-2015-time-100/
-
Common Crawl Foundation reposted
American Scientist
@AmSciMag
Crawling Toward a Wiser Web With @CommonCrawl: www.americanscientist.org/issues/pub/2015/3/crawling-towa… #compsci #data #science
-
Common Crawl Foundation reposted
KDnuggets
@kdnuggets
Added to KDnuggets #datasets: Web Data Commons, structured data from the Common Crawl, the largest public web corpus www.kdnuggets.com/datasets/index.html
-
Common Crawl Foundation reposted
Aaron Bradley
@aaranged
RDFa, Microdata, and Microformat Deployment Trends 2012-2014 from the Common Crawl Corpus - webdatacommons.org/structureddata/
-
Common Crawl Foundation
@CommonCrawl
It's here! In-depth with New URL Index and Query API, Jan/Feb '15 crawl already added!
Retweet & feedback welcome!
goo.gl/ZLi5B4 -
Common Crawl Foundation reposted
Jim Hendler
@jahendler
interesting new article: “Linked Data in Libraries: A Case Study of Harvesting and Sharing - klou.tt/okfckqklzjwo
-
Common Crawl Foundation
@CommonCrawl
F USE: A Reproducible, Extendable, Internet-scale Corpus of Spreadsheets- extracts from the @CommonCrawl corpus!
kjlubick.github.io/pubs/MSR2015-Fuse_spreadsheet_corpus.pdf -
Common Crawl Foundation
@CommonCrawl
Deep Speech: Scaling up end-to-end speech recognition cites @CommonCrawl
arxiv.org/pdf/1412.5567v2.pdf -
Common Crawl Foundation reposted
Martin Potthast
@martinpotthast
My #easterhack: copy @CommonCrawl to betaweb at Digital Bauhaus Lab @bauhaus_uni. 75MB/s (kudos @awscloud), ETA 4.5d.
-
Common Crawl Foundation reposted
Arijit K
@rijitK
new big graph sources: common crawl [commoncrawl.org/the-data/get-started/] and web data commons [webdatacommons.org]
-
Common Crawl Foundation reposted
Russell Jurney 🇺🇦
@rjurney
Evaluating distributed graph processing systems on 100+ billion edges from the common crawl blog.commoncrawl.org/2015/04/evaluating-graph-computation…
-
Common Crawl Foundation reposted
Ben Lorica 罗瑞卡
@bigdata
Do you have questions about Apache Spark or #bigdata? Attend a Reddit AMA with Spark's creator @matei_zaharia goo.gl/TkI8Yv
-
Common Crawl Foundation reposted
Werner Vogels
@Werner
"How Amazon Web Services Uses Formal Methods" by Chris Newcombe, et al in @cacmmag wv.ly/1ENidlL #aws
-
Common Crawl Foundation
@CommonCrawl
Evaluating graph systems: Lets push state of the art advancement significantly and swiftly
Post by @Frankmcsherry
goo.gl/pwa7ca -
Common Crawl Foundation
@CommonCrawl
145TB fresh Feb data out now! Plus preview: URL Index and query API. Check it out, have fun
blog.commoncrawl.org/blog/february-2015-crawl-archive-ava… -
Common Crawl Foundation reposted
Stanford NLP Group
@stanfordnlp
Don’t cheap out on the CPUs of your new server quite yet! RT @jaykreps: Really good analysis of Spark performance. www.eecs.berkeley.edu/~keo/publications/nsdi15-final147.pdf
-
Common Crawl Foundation
@CommonCrawl
#opendata matters "@newsyc50: Data is at the heart of search. But who has access to it? andreasgal.com/2015/03/30/data-is-at-the-heart-of-search-… (news.ycombinator.com/item?id=9289409)"
-
Common Crawl Foundation
@CommonCrawl
Weekend reading: $10 CC Mapreduce Job, why #opensource = secure, ML for utilities, March Madness datascience & more
blog.commoncrawl.org/2015/03/5-good-reads-in-big-open-dat… -
Common Crawl Foundation reposted
Dr. Ali Hürriyetoğlu
@hurrial
Sebastian Speigler from @SwiftKey explains his research project for @CommonCrawl and discusses why open data matters youtu.be/QELJU_Fx0hc
-
Common Crawl Foundation reposted
Marshall Kirkpatrick
@marshallk
Beautiful! Library of Congress releases StoryCorps.me mobile app for capturing oral history interviews! blogs.loc.gov/folklife/2015/03/ethnography-21st-century-s…
-
Common Crawl Foundation reposted
Webrecorder
@webrecorder_io
A new url index and query api now available for @CommonCrawl at index.commoncrawl.org - bulk query by url, prefix, host, domain w/ paging
-
Common Crawl Foundation reposted
Edd Wilder-James
@edd
More on this theme "Batch Your Big Data Jobs—Or Stream Them?" readwrite.com/2015/03/23/hadoop-big-data-batch-streaming
-
Common Crawl Foundation
@CommonCrawl
Happy to see so much recent interest & independent projs w/ our dataset- Please donate commoncrawl.org/donate so we can keep #opendata free!
-
Common Crawl Foundation reposted
👋 👉 @Sascha@Bonn.social
@Sascha_Foerster
Common Crawl. Free Index of the web @Lambo #s20bar commoncrawl.org
-
Common Crawl Foundation reposted
Webrecorder
@webrecorder_io
pywb 0.9.0 released: features include automated WARC/ARC indexing, collection mgmt, user metadata, github.com/ikreymer/pywb #webarchiving
-
Common Crawl Foundation reposted
James (Galileo VC)
@jamesfromsydney
For $10.60 an engineer found 748m US phone numbers, only 48% were on Yelp. @CommonCrawl dataset is a great resource! engineeringblog.yelp.com/2015/03/analyzing-the-web-for-th…
-
Common Crawl Foundation reposted
Pete Skomoroch
@peteskomoroch
WikiReverse shows web pages that link to Wikipedia articles based on 36 million links parsed by @CommonCrawl wikireverse.org
-
Common Crawl Foundation reposted
Andy Jackson
@anjacks0n
Fellow format nerds might appreciate this PDF metadata breakdown from the 2014 @CommonCrawl dataset: pdfinfo.net/en/stats_cc2/
-
Common Crawl Foundation
@CommonCrawl
Read this! Trend: #bigdata vs. Hadoop vs. Business Intelligence, Analysis of CC PDF metadata, Bye to Google Code
goo.gl/Ocfxjv -
Common Crawl Foundation reposted
Dalan Mendonça
@dalanMendonca
Just discovered @CommonCrawl - this effort is amazing
-
Common Crawl Foundation reposted
Yelp Engineering
@YelpEngineering
Did you know that for the cost of a sandwich you could analyze all the data on the web with mrjob and @CommonCrawl? engineeringblog.yelp.com/2015/03/analyzing-the-web-for-th…
-
Common Crawl Foundation reposted
Nova Spivack
@novaspivack
Will Smart Machines Make Us Stupid? AI Experts Weigh In www.wsj.com/articles/BL-DGB-40964 -[I moderated this SXSW panel on AI, and @WSJ picked it up]
-
Common Crawl Foundation reposted
Irma Leticia Kramer
@bluflowr
Ever since seeing @boudicca @DataDayTexas I've been itching to dive into @commoncrawl Hope to soon! You should too! #data
-
Common Crawl Foundation
@CommonCrawl
Our latest release was 139TB+ goo.gl/Zrmc1v
Please donate to @CommonCrawl to support free #opendata
commoncrawl.org/donate/ -
Common Crawl Foundation
@CommonCrawl
Research via @OhioState : Azmat -Sentence Similarity using Associative Matrices
Thanks for using @CommonCrawl !
goo.gl/j7zxh2 -
Common Crawl Foundation reposted
AMPLab
@amplab
New Pub: Rethinking Data-Intensive Science Using Scalable Analytics Systems goo.gl/knTGRP
-
Common Crawl Foundation
@CommonCrawl
Read why we need your help! Make a tax-deductible donation to @commoncrawl and the #openweb today.
goo.gl/TZNaLh -
Common Crawl Foundation reposted
Stanford NLP Group
@stanfordnlp
Openness, interdisciplinarity, and trust in text mining—great discussion to have! medium.com/@IgorBrigadir/shapes-of-stability-a7a9a6ad8749 HT @heatherfro @trochee
-
Common Crawl Foundation reposted
WSJ Tech
@WSJTech
Facebook has bought TheFind, a search engine that crawls the Internet to offer a personalized shopping experience www.wsj.com/articles/BL-DGB-40877
-
Common Crawl Foundation
@CommonCrawl
Good weekend reads: @Prismatic aspect tag API, @Wikipedia open letter to NSA, @awscloud EC2 vs C3, C4 and more
blog.commoncrawl.org/blog/5-good-reads-in-big-open-data-m… -
Common Crawl Foundation reposted
Nova Spivack
@novaspivack
Catch my @sxsw panel #ai #stateunion panel - RSVP now! schedule.sxsw.com/2015/events/event_IAP41921 #sxsw
-
Common Crawl Foundation reposted
Smerity
@Smerity
Someone decided to use port 18779690999 in a URL. Far over a 32 bit integer! The magic you find in a @CommonCrawl size sample of the web :P
-
Common Crawl Foundation reposted
🌲Roelof ☀️
@graphific
Exciting new stuff from @stanfordnlp: Tree-structured LSTM's! arxiv.org/abs/1503.00075 #nlproc #nlp #lstm #arxiv
-
Common Crawl Foundation reposted
Pete Skomoroch
@peteskomoroch
Aspects: new text extraction API released by @Prismatic blog.getprismatic.com/deeper-content-analysis-with-aspects/
-
Common Crawl Foundation
@CommonCrawl
Read this! Why #ai is just like us, 139 TB #opendata for you to play with, Hadoop Gamechangers- Spark, Hive & Presto
goo.gl/O08SbQ -
Common Crawl Foundation reposted
Kevin Ashley
@kevingashley
#idcc15 timely RT @CommonCrawl We provide PBs of open web data free of charge. As non-profit, we need your donation! commoncrawl.org/donate
-
Common Crawl Foundation reposted
Andrej Karpathy
@karpathy
Very nice and long reddit AMA with Jürgen Schmidhuber. Lots of RNN and AI food for thought www.reddit.com/r/MachineLearning/comments/2xcyrl/i_am_jür…
-
Common Crawl Foundation reposted
AffirmedSystems
@affirmedsystems
Dirt Cheap Web-Scale Parallel Text from the Common Crawl www.cs.jhu.edu/~ccb/publications/bitexts-from-common-craw… #webscale #cloud #lowlatency
-
Common Crawl Foundation reposted
O'Reilly Radar
@radar
Year Zero: Our life timelines begin oreil.ly/1GMNF6n @acroll "This will fundamentally change how we live"
-
Common Crawl Foundation
@CommonCrawl
NEW crawl archive- A whopping 139TB! Have fun and let us know what you do with #opendata Thanks @blekko & @awscloud! goo.gl/0zIaGP
-
Common Crawl Foundation
@CommonCrawl
Please donate to @CommonCrawl - we provide petabytes of open web data 100% free to you and 100% funded by donors!
goo.gl/Z8h37p -
Common Crawl Foundation reposted
Search Engine Land
@sengineland
Google Researchers Introduce System To Rank Web Pages On Facts, Not Links by @mattmcgee selnd.com/1DEdzpx
-
Common Crawl Foundation reposted
Tim Hopper
@tdhopper
·@bigdata’s interview with David Blei is fantastic radar.oreilly.com/2015/02/topic-models-past-present-and-f…
-
Common Crawl Foundation
@CommonCrawl
Link corrected blog.commoncrawl.org/2015/02/5-good-reads-in-big-open-dat… 5 Good Reads, why startups should embrace @twitterhadoop & FlashGraph + more stories in #opendata
-
Common Crawl Foundation
@CommonCrawl
Good reads! Startups should embrace @twitterhadoop, Topic Models via @bigdata, Flashgraph: analyzing 129 bil edges
goo.gl/M7nv4z -
Common Crawl Foundation reposted
Tony Spencer
@notsleepy
@KrisRoadruck finally managed to work out how to extract anything from @CommonCrawl and results were everything I dreamed
-
Common Crawl Foundation reposted
Colin Dellow @cldellow@hachyderm.io
@cldellow
Drooling over Common Crawl datasets
-
Common Crawl Foundation reposted
Steve Eichert
@steveeichert
Analyzing a Web graph with 129 billion edges using FlashGraph – Common Crawl – Blog blog.commoncrawl.org/blog/analyzing-a-web-graph-with-129-…
-
Common Crawl Foundation
@CommonCrawl
Research by @eBay w/ @MosesSMT #machinetranslation in #ecommerce = customers find products across language boarders goo.gl/GqsWxj
-
Common Crawl Foundation reposted
Mohammad Sabah
@mohammad_sabah
How Deep Learning Will Accelerate Self-Driven Cars: getprismatic.com/story/1424878834835?share=MzcwMzc.MTQyND…
-
Common Crawl Foundation reposted
Sean Gourley
@sgourley
Because sometimes you just need a framework to analyze a graph with 129 Billion edges blog.commoncrawl.org/2015/02/analyzing-a-web-graph-with-1…
-
Common Crawl Foundation
@CommonCrawl
Awesome @zhengda1936 FlashGraph is a SSD-based graph processing framework for analyzing massive graphs 129 bil edges! blog.commoncrawl.org/blog/analyzing-a-web-graph-with-129-…
-
Common Crawl Foundation reposted
Smerity
@Smerity
.@rxin & @matei_zaharia (@databricks) show #spark's great for @CommonCrawl scale. We'll be releasing a Spark starter kit soon!
#stratahadoop -
Common Crawl Foundation
@CommonCrawl
Look at cool projects our free opendata supports commoncrawl.org/the-data/examples. Please donate/RT so we can keep doing it! commoncrawl.org/donate
-
Common Crawl Foundation reposted
Street Fight
@streetfightmag
On Street Fight: Factual CEO Says Machine Learning Could Upend Local Search streetfightmag.com/2015/02/17/factual-ceo-machine-learnin… @gilelbaz @factual
-
Common Crawl Foundation
@CommonCrawl
Guest blog post by @rossf7 : WikiReverse- Visualizing Reverse Links with CommonCrawl goo.gl/XsK62E #opendata
-
Common Crawl Foundation reposted
Alistair Croll
@acroll
Narrative matters. Difference between revealing events and spoiling the ending. @markmadsen at #stratahadoop data driven business day.
-
Common Crawl Foundation reposted
Alistair Croll
@acroll
Doing a walkthrough of the #stratahadoop keynote room in San Jose. Huge!
-
Common Crawl Foundation reposted
Andy Jackson
@anjacks0n
The Digital Dark Age ... Still Looming After All These Years: 2003 (web.archive.org/web/20030110082553/http://www.guardian.co…) to 2015 (www.theguardian.com/technology/2015/feb/13/google-boss-wa…) (typo fixed)
-
Common Crawl Foundation reposted
PublishWhatYouFund
@aidtransparency
'Exploring the open data barometer: The challenges ahead for an open data revolution' Friday 20th Feb www.eventbrite.co.uk/e/friday-lunchtime-lecture-exploring… #odifridays
-
Common Crawl Foundation
@CommonCrawl
5 Good Reads Blog: goo.gl/5Qik0e
Conflation of @facebook w/ the web, @backblaze datasets, underfunding the #openweb & more ! -
Common Crawl Foundation reposted
Ben Lorica 罗瑞卡
@bigdata
Systematic inequality/hierarchy in faculty hiring networks: institutional prestige has a large impact advances.sciencemag.org/content/1/1/e1400005 via @hsu_steve
-
Common Crawl Foundation reposted
Wikimedia Foundation
@Wikimedia
Who links to Wikipedia? A @CommonCrawl external link analysis by @eglu81 #datascience blog.wikimedia.org/2015/02/03/who-links-to-wikipedia/
-
Common Crawl Foundation reposted
Danny Linden
@CodingDanny
My AWS EMR + PIG on @CommonCrawl Slides from todays AWS Meetup: www.slideshare.net/dannylinden2/commoncrawl-with-aws-emr-pig …
-
Common Crawl Foundation reposted
Danny Linden
@CodingDanny
Today i give a talk about AWS+EMR+PIG on @CommonCrawl Dataset at Munich AWS Meetup Group by @Osterjour: meetu.ps/2FbWjB #excited
-
Common Crawl Foundation reposted
Andy Jackson
@anjacks0n
The birth of the hashtag #hashtag www.webarchive.org.uk/shine/graph?query=hashtag&year_star…
-
Common Crawl Foundation
@CommonCrawl
We provide petabytes of open web data completely free of charge. As a non-profit, we need your donation! commoncrawl.org/donate
-
Common Crawl Foundation
@CommonCrawl
5 stories in Big Open Data (and beyond) we think you should check out, from the @Commoncrawl Blog: blog.commoncrawl.org/blog/5-good-reads-in-big-open-data-f…
#opendata -
Common Crawl Foundation reposted
Wikipedia
@Wikipedia
Who links to Wikipedia? A @CommonCrawl external link analysis by @eglu81 #datascience blog.wikimedia.org/2015/02/03/who-links-to-wikipedia/
-
Common Crawl Foundation reposted
Quid, Inc.
@Quid
Sentiment Analysis. Parsing. Sentence Semantics and more on this list of deep learning publications for #nlp go.quid.com/l/52282/2015-02-04/4dqy8/4954
-
Common Crawl Foundation reposted
Entrepreneur
@Entrepreneur
On #netneutrality, FCC Chairman Pushes for the 'Strongest Open Internet Protections Ever Proposed' entm.ag/1zS08X3 via @Reuters
-
Common Crawl Foundation reposted
WikiResearch
@WikiResearch
Who links to Wikipedia? An analysis by @eglu81 of @CommonCrawl data blog.wikimedia.org/2015/02/03/who-links-to-wikipedia/
-
Common Crawl Foundation reposted
Andy Jackson
@anjacks0n
New @UKWebArchive post on how we use our data to help improve open source tools like Apache Tika www.networksolutions.com/typepad?siteID=100&channelID=P99…
-
Common Crawl Foundation
@CommonCrawl
Have you used @CommonCrawl archive in any of your projects? We love hearing and helping out w/ great #opendata! Let us know and Please RT!
-
Common Crawl Foundation reposted
Ben Lorica 罗瑞卡
@bigdata
Let me rephrase that :-) If you overfit you can end up with non-robust models goo.gl/op6Ydg #deeplearning
-
Common Crawl Foundation reposted
Kristinn Sigurðsson
@kristsi
The downside of web archive deduplication kris-sigur.blogspot.com/2015/01/the-downside-of-web-archi…
-
Common Crawl Foundation
@CommonCrawl
NEW Blog post via @domicone: The Promise of #open Government #data & Where We Go Next
blog.commoncrawl.org/blog/the-promise-of-open-government-…
#opendata #openweb #opengov -
Common Crawl Foundation
@CommonCrawl
2014: 1.3 petabytes/18.5bil pages added to @CommonCrawl & we contributed to 19 (and still counting!) research papers goo.gl/UF85KT
-
Common Crawl Foundation
@CommonCrawl
WikiReverse Proj 36mil links to 4mil #wikipedia articles using July @CommonCrawl archive -processed for $64! goo.gl/1KPe4v @rossf7
-
Common Crawl Foundation reposted
Andy Jackson
@anjacks0n
Furthermore, of the two-thirds remaining, only about half is recognisable similar or the same as it was two years ago. (fixed typo)
-
Common Crawl Foundation reposted
Andy Jackson
@anjacks0n
Analysing link-rot in the Legal Deposit web archive - surprised to find that in just two years, one third of the URLs we crawled have gone!
-
Common Crawl Foundation
@CommonCrawl
"The Battle for America's Internet" via @Salon
www.salon.com/2015/01/25/the_battle_for_americas_broadban… -
Common Crawl Foundation reposted
Sinan Aral
@sinanaral
A simple statistical misunderstanding is leading many neuroscientists astray in their use of machine learning blogs.discovermagazine.com/neuroskeptic/2015/01/18/machin…
-
Common Crawl Foundation reposted
Gianluca Demartini
@eglu81
@edwardbetts It seems you link to Wikipedia as nobody else on the Web :) wikireverse.org/sites At least up to @CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Uh oh! The unbeatable #poker machine - it can even bluff! #machinelearning #artificialintelligence
connectsci.au/news -
Common Crawl Foundation reposted
Ross Fairbanks @rossf7.bsky.social
@rossf7
Today I'm launching WikiReverse my open data project using @CommonCrawl data wikireverse.org
-
Common Crawl Foundation
@CommonCrawl
Great #research w @CommonCrawl
#opendata - Dynamic Topic Adaptation for Phrase-based MT
#machinetranslation #ai #nlp goo.gl/MTOhI8 -
Common Crawl Foundation
@CommonCrawl
#facebook opensources #ai tools
goo.gl/7FMGwb
#opensource #machinelearning #opendata #open -
Common Crawl Foundation
@CommonCrawl
Fast Training of word2vec Representations Using N-gram Corpora @FilipGinterFIN goo.gl/dEu5bT
#research w/ @CommonCrawl #opendata -
Common Crawl Foundation reposted
Helen Hockx-Yu
@hhockx
"The Cobweb - Can the Internet be archived?" The New Yorker features web archiving. www.newyorker.com/magazine/2015/01/26/cobweb
-
Common Crawl Foundation reposted
Nova Spivack
@novaspivack
2015 Trends in Big Data: Real Time - DATAVERSITY www.dataversity.net/2015-trends-big-data-real-time/
-
Common Crawl Foundation
@CommonCrawl
What is @CommonCrawl ? What kinds of things are possible if you have access to crawl #data? #opendata #opeweb www.youtube.com/watch?v=ozX4GvUWDm4
-
Common Crawl Foundation reposted
Pete Skomoroch
@peteskomoroch
"Key Court Victory Closer for IRS Open-Records Activist" - Awesome work by @carlmalamud philanthropy.com/article/Key-Court-Victory-Closer-for/151…
-
Common Crawl Foundation reposted
Stanford NLP Group
@stanfordnlp
New @techreview article on Skype speech translation cites @chrmanning “stunning success” but could hit a wall www.technologyreview.com/news/534101/something-lost-in-sk… #nlproc
-
Common Crawl Foundation
@CommonCrawl
#opendata #research citing @commoncrawl #opendata!
Bloom filter-based Routing in NDN via @poliba_social
goo.gl/8V4v6R -
Common Crawl Foundation
@CommonCrawl
"Combining Domain and Topic Adaptation for SMT"
#research using @CommonCrawl Repository goo.gl/v1mTfg -
Common Crawl Foundation reposted
KDnuggets
@kdnuggets
A Deep Dive into Recurrent Neural Nets #deeplearning #machinelearning nikhilbuduma.com/2015/01/11/a-deep-dive-into-recurrent-ne…
-
Common Crawl Foundation reposted
Jonathan Frye
@JonathanAFrye
Brilliant #dataviz of population density across 9 cities
www.vox.com/2015/1/2/7480993/population-density-visualized
via @voxdotcom
HT @KirkDBorne -
Common Crawl Foundation
@CommonCrawl
#nasa using #machinelearning to predict properties of stars goo.gl/kOqcSy #bigdata
-
Common Crawl Foundation reposted
Alistair Croll
@acroll
If you read one thing this week, read this. Five times. Absolutely mind-opening piece on emotions and data www.newyorker.com/magazine/2015/01/19/know-feel
-
Common Crawl Foundation
@CommonCrawl
8 years and counting of big #opendata: @CommonCrawl is 100% #free, 100% donation funded - help us keep the web #open commoncrawl.org/donate
-
Common Crawl Foundation reposted
Jim Hendler
@jahendler
Obama’s proposals on online privacy - nice to see serious govt attention to this problem: www.washingtonpost.com/blogs/the-switch/wp/2015/01/12/pre…
-
Common Crawl Foundation
@CommonCrawl
What can #opendata do for you? from @ODIHQ vimeo.com/110800848 #open #data #knowledge
-
Common Crawl Foundation reposted
Lisa Green
@boudicca
At @DataDayTexas? Don't miss @mipsytipsy at 4pm! "Upgrade your database - without losing your data, your performance, or your mind" #ddtx15
-
Common Crawl Foundation reposted
O'Reilly Strata Data & AI Conference
@strataconf
Meet your favorite authors & gain their insights at #ddtx15. 3 more #authorsignings this afternoon. instagram.com/p/xr07r3p7ly/
-
Common Crawl Foundation
@CommonCrawl
Fantastic talk by @WWRob Building Better Experts: co-optimization of human and machine intelligence at Idibon #ddtx15
-
Common Crawl Foundation reposted
Gregory Foster (@gregoryfoster@sigmoid.social)
@gregoryfoster
"N-gram Counts and Language Models from the @CommonCrawl":
statmt.org/ngrams/BuckEtAl_LREC2014_CommonCrawlLM.pdf
(HT @boudicca) #ddtx15 -
Common Crawl Foundation reposted
Gregory Foster (@gregoryfoster@sigmoid.social)
@gregoryfoster
"Dirt Cheap Web-Scale Parallel Text from the @CommonCrawl":
www.cs.jhu.edu/~ccb/publications/bitexts-from-common-craw…
(HT @boudicca) #ddtx15 -
Common Crawl Foundation
@CommonCrawl
Super excited for @pacoid's talk at @DataDayTexas in 10 minutes! A New Year in Data Science: ML Unpaused #ddtx15
-
Common Crawl Foundation reposted
SV Data Science
@SVDataScience
When our data scientists take @caltrain to work, we get graphs of how fast it goes! thanks @chloemawer @jbwhitmore
-
Common Crawl Foundation
@CommonCrawl
Check us out, public #data sets on @awscloud aws.amazon.com/datasets/41740 #opendata AWS tops list of reliable public clouds- story via @gigaom
-
Common Crawl Foundation reposted
Nova Spivack
@novaspivack
Open Source Is Data Science's Missing Ingredient - ReadWrite readwrite.com/2015/01/08/open-source-big-data-science-python
-
Common Crawl Foundation reposted
MiguelAfonsoCaetano
@remixtures
#research: Why cash and #copyright are bad news for creativity - Dan Hunter (The Conversation) theconversation.com/why-cash-and-copyright-are-bad-news-f… via @ConversationEDU
-
Common Crawl Foundation reposted
Onno on Linux
@onnix
@CommonCrawl surfsara.nl/blog/‘norvig-web-data-award’-krijgt-vervolg-2015 (Dutch only)
-
Common Crawl Foundation reposted
Ben Lorica 罗瑞卡
@bigdata
"humans-in-the-loop" machine learning: I'm hosting @OReillyMedia webcast on this important topic, featuring @marcua www.oreilly.com/pub/e/3298
-
Common Crawl Foundation reposted
Joe Hellerstein
@joe_hellerstein
Continue to be impressed with the Yago knowledgebase project. en.wikipedia.org/wiki/YAGO_(database) #cidr15
-
Common Crawl Foundation reposted
Tim O'Reilly
@timoreilly
RT @FightfortheFtr: Congress wants to introduce a new law called "Title X" to give Comcast everything they want. cms.fightforthefuture.org/stop-titlex/
-
Common Crawl Foundation reposted
Atigeo
@atigeo
Discounted registration ends in 12 hours - Data Day Texas #ddtx15 Austin www.eventbrite.com/e/data-day-texas-2015-tickets-11302579… via @CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
We love our Google Group community! Have a @CommonCrawl technical question? Find an answer here: goo.gl/zt8Oxh
-
Common Crawl Foundation
@CommonCrawl
Last day for discounted registration rate for Data Day Texas 2015. You don't want to miss this event! #ddtx15 datadaytexas.com
-
Common Crawl Foundation
@CommonCrawl
Research citing @Commoncrawl : Document-level Re-ranking for Statistical Machine Translation @UofTsukuba #opendata #machinentranslation
-
Common Crawl Foundation
@CommonCrawl
After years of stagnating #timberland sales boomed in 2014. And it did this with customer #data #datascience #bigdata
www.washingtonpost.com/news/business/wp/2015/01/02/how-ti… -
Common Crawl Foundation reposted
Ross Fairbanks @rossf7.bsky.social
@rossf7
Blog on parsing @CommonCrawl data using the elasticrawl tool I wrote last year that I've just updated rossfairbanks.com/2015/01/03/parsing-common-crawl-using-e…
-
Common Crawl Foundation reposted
Martin Ford
@MFordFuture
Deep learning and machine intelligence will be big stories in 2015 @akosner www.forbes.com/sites/anthonykosner/2014/12/29/tech-2015-d… #ai #riseoftherobots
-
Common Crawl Foundation reposted
Stanford NLP Group
@stanfordnlp
Nice discussion of GloVe—& word2vec—by @RadimRehurek: “Very nice and clear paper, go read it if you haven’t!” radimrehurek.com/2014/12/making-sense-of-word2vec/ #nlproc
-
Common Crawl Foundation
@CommonCrawl
HAPPY 2015! Our gift, NEW CRAWL goo.gl/VDdEP2 Let us know how you use #opendata & plz support @CommonCrawl : commoncrawl.org/donate
-
Common Crawl Foundation
@CommonCrawl
New Crawl Archive!!! goo.gl/VDdEP2 Check out our impact goo.gl/jZlvSV & support #opendata in 2015: commoncrawl.org/donate
-
Common Crawl Foundation reposted
OurResearch
@OurResearch_org
ArXiv hits 1 million papers, and manages to “publish” them at a cost of < $10/article www.nature.com/news/the-arxiv-preprint-server-hits-1-mill… #openscience
-
Common Crawl Foundation reposted
Jason Scott
@textfiles
Here's 2,000 MS-DOS screenshots taken automatically by my robot army for the @internetarchive. www.flickr.com/photos/textfiles/sets/72157650018149815/
-
Common Crawl Foundation reposted
Search Engine Land
@sengineland
How Yahoo Directory looked back in 1995. selnd.com/1A2Nzoq
-
Common Crawl Foundation reposted
Pete Skomoroch
@peteskomoroch
MT @odbmsorg: Underhyped #bigdata as an Advance in the Scientific Method
by Yanpei Chen
www.odbms.org/2014/12/underhyped-big-data-scientific-method/ /cc @jaykreps -
Common Crawl Foundation
@CommonCrawl
Just a few days left in 2014! We've got big plans for #opendata & need your year-end gift to make it happen !blog.commoncrawl.org/2014/12/please-donate-to-common-crawl/
-
Common Crawl Foundation reposted
Ben Lorica 罗瑞卡
@bigdata
The origins of sequential analysis & other methods: @TheEconomist on Statistics & Statisticians during World War II goo.gl/isrSN8
-
Common Crawl Foundation reposted
Pete Skomoroch
@peteskomoroch
This was mostly right, more CDOs than I expected "4 big data predictions that won't happen in 2014 and 1 that will" venturebeat.com/2014/01/06/4-big-data-predictions-that-wo…
-
Common Crawl Foundation reposted
Techmeme
@Techmeme
Sony breach highlights need to move to mobile apps and cloud services to strengthen security blog.learningbyshipping.com/2014/12/21/why-sonys-breach-m… www.techmeme.com/141223/p4
-
Common Crawl Foundation reposted
Semantic Web
@SemanticWeb
Opinion: @novaspivack on a New Era in Semantic Web History
semanticweb.com/nova-spivack-new-era-semantic-web-history…
/cc @cogcomputing #semanticweb #linkeddata #ai -
Common Crawl Foundation
@CommonCrawl
We've got big 2015 plans @CommonCrawl but we need help to make it happen! Please support whether its $10 or $1000! blog.commoncrawl.org/2014/12/please-donate-to-common-crawl/
-
Common Crawl Foundation reposted
Stanford NLP Group
@stanfordnlp
Google ending Freebase could mess up #nlproc use—given G’s record of abandoning APIs, best hope’s Wikidata groups.google.com/forum/ HT @willf
-
Common Crawl Foundation
@CommonCrawl
#opendata could open up $3-5 trillion a year in additional #economicvalue goo.gl/vXZjrc #bigdata #openweb
-
Common Crawl Foundation reposted
Stanford NLP Group
@stanfordnlp
In exuberance over the very genuine success of deep learning lies the danger that people start doing hype not science www.machinedlearnings.com/2014/12/nips-2014.html
-
Common Crawl Foundation reposted
Tim O'Reilly
@timoreilly
Brilliant piece on what's wrong with how we think about "everyone should learn to program" medium.com/the-truant-haruspex/end-user-computing-5367171… via @mikeloukides
-
Common Crawl Foundation reposted
Hilary Mason
@hmason
Big Data, Machine Learning, and the Social Sciences medium.com/@hannawallach/big-data-machine-learning-and-th… @hannawallach totally nails it.
-
Common Crawl Foundation
@CommonCrawl
Here's some fun crowd contributed #opendata where and why in #sanfrancisco have you cried? #maps #sf www.google.com/maps/d/u/0/edit?mid=zP60ZK9XmRZw.kKeFOZ_5nxJU
-
Common Crawl Foundation
@CommonCrawl
6 Bold #bigdata Predictions for #2015- 2015 will be @hadoop 's show me the money year.
goo.gl/mYFB5a -
Common Crawl Foundation reposted
Jeanne Kramer-Smyth
@spellboundblog
DigiPres Commons: find preservation tools, understand file formats & learn from others about digital preservation www.digipres.org
-
Common Crawl Foundation
@CommonCrawl
#metadata creators wo #semanticweb exp make #rdf #data w #linkeddata principles @HumboldtUni @CommonCrawl #opendata
edoc.hu-berlin.de/oa/conferences/re3FIwpKnRC5k/PDF/25n7z5… -
Common Crawl Foundation
@CommonCrawl
RT @jahendler in great company: Top 200 Influencers in #bigdata & #analytics analyticsweek.com/top-200-thought-leaders-in-bigdata-anal… @bigdata @acroll @data_nerd @bobevansIT
-
Common Crawl Foundation reposted
Semantic Web
@SemanticWeb
Cognitive Computing: What’s Ahead in 2015 www.dataversity.net/cognitive-computing-whats-ahead-2015/ #cogcomputing #ai #machinelearning #datascience
-
Common Crawl Foundation
@CommonCrawl
Do you love #opendata projs? @CommonCrawl provides the infrastructure & we need your end of yr support! Please #rt: blog.commoncrawl.org/blog/please-donate-to-common-crawl
-
Common Crawl Foundation reposted
Ben Lorica 罗瑞卡
@bigdata
Recent @nberpubs survey paper: the #bigdata Revolution and Economic Analysis web.stanford.edu/~jdlevin/Papers/BigData.pdf
-
Common Crawl Foundation reposted
Stanford NLP Group
@stanfordnlp
NOT deep learning—but great machine reading! RT @tariusdamon deepdive.stanford.edu #bigdata open source pkg that democratizes deep learning
-
Common Crawl Foundation reposted
Serhat Akkılıç
@sakkilic
. @commoncrawl is a nonprofit organization monthly crawling the web, downloading 2.8 billion pages & store results in a public data set
-
Common Crawl Foundation
@CommonCrawl
More from the anti-linking #eu trend- #google #news out of #spain developing story on #copyright of #openweb goo.gl/EPLuE5
-
Common Crawl Foundation reposted
-
Common Crawl Foundation reposted
Anita Yorker
@anitayorker
Please Donate To Common Crawl! – Common Crawl – Blog blog.commoncrawl.org/2014/12/please-donate-to-common-crawl, see more tweetedtimes.com/kdnuggets/analytics-data-mining?s=tnp
-
Common Crawl Foundation reposted
desertnaut
@desertnaut
MT @alexissmirnov: New word representation project from @stanfordnlp: GloVe. Trained @commoncrawl www-nlp.stanford.edu/projects/glove/ #nlp
-
Common Crawl Foundation
@CommonCrawl
Please support @commoncrawl with a donation! And spread the word about our work by retweeting/sharing this post blog.commoncrawl.org/2014/12/please-donate-to-common-crawl/
-
Common Crawl Foundation reposted
Open Knowledge Foundation (@okfn@fosstodon.org)
@OKFN
Where does your country rank? Global Open Data Index 2014 now published. index.okfn.org/place/ #openindex14
-
Common Crawl Foundation reposted
Pete Skomoroch
@peteskomoroch
"Machine Intelligence wins and loses on demos" medium.com/@shivon/the-current-state-of-machine-intellige…
-
Common Crawl Foundation
@CommonCrawl
Did you know that @CommonCrawl crawls #opendata relying 100% on #donations? Be a supporter today we need your help! commoncrawl.org/donate
-
Common Crawl Foundation reposted
Martin Kleppmann
@martinkl
I wrote a post on O’Reilly Radar: “Wouldn’t it be fun to build your own Google?” (On web crawling and @CommonCrawl) radar.oreilly.com/2014/12/wouldnt-it-be-fun-to-build-your…
-
Common Crawl Foundation reposted
Kirk Borne
@KirkDBorne
#bigdata vs #opendata -- mapping it out: www.opendatanow.com/2013/11/new-big-data-vs-open-data-map… by @JoelGurin HT @sociabilities
-
Common Crawl Foundation
@CommonCrawl
"In favor of #opendata ... the benefits #data sharing brings to #science far outweigh the risks." synapse.ucsf.edu/articles/2014/12/04/science-publishing-t… via @UCSF
-
Common Crawl Foundation reposted
Wikimedia Foundation
@Wikimedia
WMF awards 13 grantees funding for projects to fight gender gap, develop classification algorithm, and more:
blog.wikimedia.org/2014/12/05/ieg-selects-exciting-new-ba… -
Common Crawl Foundation reposted
Eric Porres
@eporres
Great read: Automation, jobs, and the future of work, feat @reidhoffman, @timoreilly, @Wadhwa shar.es/13aEWa via @McKinsey_MGI #ai
-
Common Crawl Foundation reposted
Alistair Croll
@acroll
Are you a #montreal startup but can't make it to the Lean Startup conference next week? Live Stream at Notman House! www.eventbrite.com/e/lean-startup-conference-2014-live-st…
-
Common Crawl Foundation
@CommonCrawl
We need your help! @CommonCrawl is 100% donor funded & our #opendata is #free. Make a tax-deductible gift today: commoncrawl.org/donate
-
Common Crawl Foundation reposted
James Baker Battles the Pink SPARQL and QS Robots
@j_w_baker
#webarchives Key point emerging. The internet (and its place in culture) right now isn't the same as the internet then.
-
Common Crawl Foundation reposted
Amy Heineike
@aheineike
For #givingtuesday : Peek eyewire www.indiegogo.com/projects/peek-retina-help-fight-avoidab… (via @zahedab) and the wonderful @commoncrawl commoncrawl.org/donate/
-
Common Crawl Foundation reposted
Ben Lorica 罗瑞卡
@bigdata
I'm hosting a free @OReillyMedia webcast tomorrow on The Future of #bitcoin: A Data-Driven Perspective www.oreilly.com/pub/e/3274
-
Common Crawl Foundation reposted
mza
@mza
The new Reserved Instance model: aws.amazon.com/blogs/aws/simplified-reserved-instances/ #aws
-
Common Crawl Foundation reposted
Jim Hendler
@jahendler
Great mtg at #mellon on #linkeddata for libraries and museums. There's billions of great triples out there! #semweb
-
Common Crawl Foundation
@CommonCrawl
10e8+ URLs from @CommonCrawl with approx 1500 blogs mostly written in German & potentially under CC license #research goo.gl/T72Zvj
-
Common Crawl Foundation reposted
Roger Magoulas
@rogerm
Ben Lorica (@bigdata) and I are hosting the O'Reilly Data Show, first episode: science of moving dots, now on iTunes podcasts.apple.com/us/podcast/oreilly-data-show/id944929220
-
Post not available here, view on X
Common Crawl Foundation
@CommonCrawl
@digitalpebble Great work, thanks for the #donate shout and we love hearing about #opensource projs with #opendata, a million thanks!!!
-
Common Crawl Foundation
@CommonCrawl
Hope everyone in the @CommonCrawl family has a restful #thanksgiving! We're #thankful that you care about #opendata commoncrawl.org/donate/
-
Common Crawl Foundation reposted
Alexis Smirnov
@alexissmirnov
@CommonCrawl tank you for creating and maintaining such a valuable dataset. @radialpoint is one of many teams who benefited from your work.
-
Common Crawl Foundation
@CommonCrawl
RT @alexissmirnov: New word representation project from Stanford NLP: GloVe. Trained @commoncrawl www-nlp.stanford.edu/projects/glove/
-
Common Crawl Foundation reposted
tbiz
@tbiz
I want the web’s data to always be available for research and innovation, so I just donated to @CommonCrawl
-
Common Crawl Foundation reposted
Jim Hendler
@jahendler
back to the #bigdata world…
-
Common Crawl Foundation
@CommonCrawl
Consider making a tax-deductible gift to us for the holidays commoncrawl.org/donate @CommonCrawl 100% Donor funded, 100% free. Please RT!!
-
Common Crawl Foundation reposted
Liz Krane
@LearningNerd
I finally got around to reading @TimOReilly's famous essay "Government as a Platform" www.oreilly.com
#mustread #opengov #opendata -
Common Crawl Foundation reposted
Ben Lorica 罗瑞卡
@bigdata
How fashion industry leaders innovate with data and what you can learn from what they know: a new @radar report goo.gl/zzQdfx
-
Common Crawl Foundation
@CommonCrawl
Join us tonight for Web-Scale Natural Language Processing in Northern Europe! www.eventbrite.de/e/web-scale-natural-language-processing… #nlp #bigdata
-
Common Crawl Foundation reposted
Tim O'Reilly
@timoreilly
“A Field Guide to the Distributed Development Stack” by @odewahn Rocks! oreil.ly/1AjxNru
-
Common Crawl Foundation reposted
Smerity
@Smerity
Running #hadoop jobs for @CommonCrawl at 10,972 metres leaving #stratahadoop. Thanks @Fly_Norwegian for free wifi!
-
Common Crawl Foundation
@CommonCrawl
#stratahadoop @edwindjonge giving excellent advice on best practices in statistical analysis and visualization.
-
Common Crawl Foundation
@CommonCrawl
Fantastic talk by @danielequercia on using crowd-sourced data & computational social science to increase happiness in cities! #stratahadoop
-
Common Crawl Foundation
@CommonCrawl
#strataconf Wondering what to see after lunch? Come to see @CommonCrawl and @neofonie talk at the open data track in room 212!
-
Common Crawl Foundation
@CommonCrawl
For the last day of #stratahadoop Barcelona, we've released the October crawl archive: 3.72 billion pages, 1/4th PB!
blog.commoncrawl.org/2014/11/october-2014-crawl-archive-a… -
Common Crawl Foundation reposted
John Akred
@jmakred
Talking about #data4good with @DataKindUK at #stratahadoop. @DataKind never ceases to inspire.
-
Common Crawl Foundation
@CommonCrawl
"The world can be made a better place through data" @duncan3ross of @DataKindUK at #stratahadoop
-
Common Crawl Foundation reposted
Duncan Ross
@duncan3ross
More from @fhr in Using Data for GOOD! Room 212 at 1150 #stratahadoop @DataKindUK
-
Common Crawl Foundation
@CommonCrawl
#stratahadoop @majsander telling how she gained customer insight using open data rather than paying for facebook data
-
Common Crawl Foundation reposted
Juha Meronen
@JuhaMeronen
Trust, honesty and avoiding surprises. The right principles with personal & sensitive data. @cutting at #stratahadoop
-
Common Crawl Foundation
@CommonCrawl
Excited to see @majsander talk about the value of open data this morning at #stratahadoop!
-
Common Crawl Foundation reposted
Hacker News Bot
@newsycombinator
CERN makes public first data of LHC experiments opendata.cern.ch
-
Common Crawl Foundation
@CommonCrawl
What's the secret to crawling 2.98 billion pages in 1 month? Generous tax-deductible support from donors like you! commoncrawl.org/donate/
-
Common Crawl Foundation reposted
Kate Ting
@kate_ting
It's standing room only for @cloudera's @sean_r_owen's #stratahadoop talk. Spark is distributed Scala.
-
Common Crawl Foundation reposted
Mounia Lalmas
@mounialalmas
Impressed by ratio of female speakers at Data-Driven Business Day #stratahadoop Yes females do Big Data :-)
-
Common Crawl Foundation reposted
Emma Martinho-Truswell
@EmmaTruswell
A clear, beautiful, practical explanation of #opendata - built using #opendata - vimeo.com/110800848 @UKODI @WorldBank
-
Common Crawl Foundation reposted
O'Reilly Strata Data & AI Conference
@strataconf
Missing #stratahadoop Barcelona? Sign up at strataconf.com/video & be notified when Complete Video Compilation is available @OReillyMedia
-
Common Crawl Foundation reposted
Open Data Institute
@ODIHQ
This Friday: How can we get the best out of renting with #opendata? with @odchallenges theodi.org/lunchtime-lectures/friday-lunchtime-lecture-ge… #odifridays @alexhilton
-
Common Crawl Foundation reposted
Lisa Green
@boudicca
If you're at #stratahadoop come to room 118 right now! @aheineike is about to speak and it's sure to be one of the best talks of the event!
-
Common Crawl Foundation
@CommonCrawl
10 minutes until Big Data Will Destroy More Jobs Than It Creates with @rogerm and @r0ml! Room 118 at #stratahadop
-
Common Crawl Foundation reposted
Edwin de Jonge
@edwindjonge
#stratahadoop: Spark camp, appearantly there is a R pkg for Spark in development amplab-extras.github.io/SparkR-pkg/, #rstats
-
Common Crawl Foundation
@CommonCrawl
A packed room at #stratahadoop Spark Camp listening to a great presentation by @pacoid!
-
Common Crawl Foundation reposted
Peter Speyer
@PeterSpeyer
A severe lack of data still hampers progress in developing countries www.economist.com/news/international/21632520-rich-countr… #healthdata
-
Common Crawl Foundation reposted
Smerity
@Smerity
.@boudicca presenting the benefits of #opendata at @BigDataBeers in Berlin for @CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
Barcelona 11/21- @CommonCrawl @boudicca presents w/ @neofonie @padolphs #stratahadoop #hadoop #opendata #nlp strataconf.com/strataeu2014/public/schedule/detail/37548
-
Common Crawl Foundation
@CommonCrawl
1 Wk: @CommonCrawl in #oslo- workshop on web-scale natural language processing www.mn.uio.no/ifi/om/aktuelt/arrangementer/andre/nlpg.html REGISTER www.eventbrite.de/e/web-scale-natural-language-processing… #nlp
-
Common Crawl Foundation
@CommonCrawl
Very excited for Web-Scale Natural Language Processing in Northern Europe on 24 November at @UniOslo! www.mn.uio.no/ifi/om/aktuelt/arrangementer/andre/nlpg.html #nlp
-
Common Crawl Foundation
@CommonCrawl
Excited for @Smerity & @boudicca to bring #opendata to #bigdata Beers Meetup in #berlin tomorrow www.meetup.com/Big-Data-Beers/events/217301572/ #openweb
-
Common Crawl Foundation reposted
mza
@mza
Introducing AWS Lambda, an all new event-driven computing service: aws.amazon.com/lambda #aws #reinvent
-
Common Crawl Foundation
@CommonCrawl
Nearing a quarter petabyte a month of #opendata! @CommonCrawl September crawl archive: 2.98 billion pages and 220+TB
blog.commoncrawl.org/2014/11/september-2014-crawl-archive… -
Common Crawl Foundation
@CommonCrawl
Really looking forward to hearing @bensbutler give Big Data and HPC State of the Union today at 1:15pm! #reinvent
-
Common Crawl Foundation reposted
mza
@mza
More on Amazon Aurora, via @jeffbarr: aws.amazon.com/blogs/aws/highly-scalable-mysql-compat-rds… #aws #reinvent
-
Common Crawl Foundation
@CommonCrawl
Join us 11/17- @Smerity @boudicca in #berlin for the #bigdata #beers #meetup: www.meetup.com/big-data-beers/events/217301572/ Spaces filling up fast, RSVP asap!
-
Common Crawl Foundation
@CommonCrawl
In #oslo Nov 24- @boudicca & @smerity talk @CommonCrawl for #nlp natural-language processing www.eventbrite.de/e/web-scale-natural-language-processing… www.mn.uio.no/ifi/om/aktuelt/arrangementer/andre/nlpg.html
-
Common Crawl Foundation reposted
Matt Cutts
@mattcutts
" 'Net Neutrality' is Obamacare for the Internet." <--said Ted Cruz, unironically. Wild to see Cruz burn bridges with many tech-savvy folks.
-
Common Crawl Foundation reposted
O'Reilly Strata Data & AI Conference
@strataconf
Join #stratahadoop Barcelona for cocktails in the atmospheric @ocanabcn Café, Bar, Restaurant, Apotheke, & Terrace: oreil.ly/104u7dB
-
Common Crawl Foundation reposted
Sidharth Shah
@iamsidd
@CommonCrawl has cool Research Papers. Thank you for making data available commoncrawl.github.io/cc-examples/ #bigdata #datasets
-
Common Crawl Foundation
@CommonCrawl
Join us 24 November for Web-Scale Natural Language Processing in Northern Europe at the University of Oslo! www.mn.uio.no/ifi/om/aktuelt/arrangementer/andre/nlpg.html #nlp
-
Common Crawl Foundation reposted
CLS, Inc.
@CLS_Inc
The State of Open Data in 2014 // opendatasoft.com/2014/11/04/weekly-open-data-state-open-d… // via @opendatasoft #opendata #opengov #odisummit
-
Common Crawl Foundation reposted
Mitch MacKenzie
@mitchmac
Interesting analysis of the reach of Google Analytics and how it was arrived at with @commoncrawl data www.slideshare.net/ODBA/measuring-theimpactgoogleanalytics
-
Common Crawl Foundation
@CommonCrawl
Do you believe in free #opendata? Donate to @CommonCrawl, tweet & RT! commoncrawl.org/donate/ #openknowledge #opensource #openaccess
-
Common Crawl Foundation
@CommonCrawl
The problem of managing #schemas via @oreillymedia www.oreilly.com/radar/ #hadoop #bigdata
-
Common Crawl Foundation reposted
DarthPeet
@DarthPeet
GloVe, a Stanford alternative for word2vec: www-nlp.stanford.edu/projects/glove/
-
Common Crawl Foundation reposted
World Wide Web Foundation
@webfoundation
Italy's draft Declaration of Internet Rights is now open for public consultation. Learn more via @pdmteam| techpresident.com/news/25327/italy-pioneers-internet-bill…
-
Common Crawl Foundation
@CommonCrawl
Thanks @thedatainc for mentioning @CommonCrawl - #data sources for cool #datascience projects blog.thedataincubator.com/2014/10/data-sources-for-cool-d… #bigdata #opendata
-
Common Crawl Foundation reposted
Heiko Ehrig
@heikoehrig
Thank you @boudicca for coming to Berlin.
-
Common Crawl Foundation reposted
evnhsn.eth
@evnhsn
First detailed data analysis shows exactly how Comcast jammed Netflix @scrawford @backchnnl medium.com/@scrawford/e474fc4925e4
-
Common Crawl Foundation
@CommonCrawl
Free #opendata for #research, #entrepreneurs #hackers #datascience @CommonCrawl is100% donor supported! Please RT! commoncrawl.org/collaborators
-
Common Crawl Foundation reposted
O'Reilly Radar
@radar
RT @mikeloukides: Bioprintable Ebola tests #synbio
www.newscientist.com/article/dn26451-biological-litmus-pa… -
Common Crawl Foundation
@CommonCrawl
US Special Operations Command (SOCOM) is building an #opensource #datamining program to mine the #openweb www.defensenews.com/article/20141025/DEFREG02/310250027/S…
-
Common Crawl Foundation reposted
The Linux Foundation
@linuxfoundation
Enterprise adoption of open source practices is on the rise www.linux.com/news/featured-blogs/200-libby-clark/789783-… w/ @GitHub @Black_Duck_sw
-
Common Crawl Foundation reposted
Kirk Borne
@KirkDBorne
15 timeless (often retweeted) #datascience articles at @DataScienceCtrl www.techtarget.com #abdsc #bigdata #analytics
-
Common Crawl Foundation reposted
Open Data Institute
@ODIHQ
How #opendata is putting the breaks on £100m worth of bike theft theodi.org/news/check-that-bike-tackles-over-100m-worth-o…
-
Common Crawl Foundation
@CommonCrawl
What to see a great talk about using #spark on big data? Join us tonight at the Cyber Security meetup! www.meetup.com/Bay-Area-Cyber-Security-Meetup/events/2066…
-
Common Crawl Foundation
@CommonCrawl
#civitech hackathon analyzes #ebola with mobile #mapping and #opendata - @CDCgov goo.gl/Fas58C #opengov #publichealth #govtech
-
Common Crawl Foundation reposted
Jeff Barr ☁️
@jeffbarr
Now Open - #aws Germany (Frankfurt) Region - EC2, DynamoDB, S3, and Much More - aws.amazon.com/blogs/aws/aws-region-germany/
-
Common Crawl Foundation reposted
RiskIQ
@RiskIQ
Take a break Thurs from #sfgiants & join us for #security talks + pizza & beer at the Bay Area #cybersecurity #meetup www.meetup.com/bay-area-cyber-security-meetup/
-
Common Crawl Foundation
@CommonCrawl
Product features from 1.9 mil #product offers from 9,240 e-shops extracted from @CommonCrawl! ceur-ws.org/Vol-1267/LD4IE2014_Petrovski.pdf #ecommerce #linkeddata
-
Common Crawl Foundation reposted
Kirk Borne
@KirkDBorne
The best #bigdata are #linkeddata >> awesome ontology wiki here: ontology-linked-data.wikispaces.asu.edu/Home
-
Common Crawl Foundation
@CommonCrawl
Our huge dataset is petabytes big and made possible by our supporters. Please donate today to keep #opendata free! commoncrawl.org/donate/
-
Common Crawl Foundation
@CommonCrawl
Very excited for the talks at the Cyber Security meetup on Thursday! Especially the @RiskIQ talk about #spark www.meetup.com/Bay-Area-Cyber-Security-Meetup/events/2066…
-
Common Crawl Foundation
@CommonCrawl
#linkeddata challenge- training & testing #data curated at large #scale using @CommonCrawl #webdatacommons goo.gl/oAt8gV @rmeusel
-
Common Crawl Foundation
@CommonCrawl
#hadoop platforms apps represent $1 trillion opportunity. 73% enterprise use or plan to. www.cio.com.au/article/557601/hadoop-platform-apps-repres… #bigdata #datascience
-
Common Crawl Foundation
@CommonCrawl
5 great online tools for creating #infographics coolinfographics.com/blog/2014/10/10/5-great-online-tools… #dataviz #data #datascience
-
Common Crawl Foundation reposted
The Nation
@thenation
Why Hasn't Big Data Saved Democracy? thenat.in/1CwDgYZ
-
Common Crawl Foundation
@CommonCrawl
A nice #saturdayafternoon #webinar www.youtube.com/watch?v=41sIhawjHE0&list=TLwGBJyNAnFO37Eg… from Pivotal - What you can do with #hadoop
-
Common Crawl Foundation
@CommonCrawl
Beautiful #interactive #map of @internetarchive 2.6 million book #collection images incubator.quasimondo.com/internetarchive/InternetArchiveB… #datascience #dataviz #archive
-
Common Crawl Foundation reposted
Nova Spivack
@novaspivack
Revised Tweet test results: 61 out of 31690 followers fav’d the tweet = .446%. Twitter says 5.8% (by impressions).
-
Common Crawl Foundation reposted
Liberation Technology
@Liberationtech
We must make our research #openaccess & resign from publications that keep articles behind paywalls, @Harvard says www.theguardian.com/science/2012/apr/24/harvard-universit…
-
Common Crawl Foundation reposted
Nicolas Torzec
@nicolastorzec
Yahoo open sources Format.js, JavaScript libraries focused on formatting numbers, dates, and strings in 150 languages yahooeng.tumblr.com/post/100006468771/announcing-format-j…
-
Common Crawl Foundation reposted
Olivier Grisel
@ogrisel
I you use pretrained word embeddings models from nlp.stanford.edu/projects/glove/ you should consider donating to @CommonCrawl: commoncrawl.org/collaborators
-
Common Crawl Foundation
@CommonCrawl
@jefferson_bail Thanks for the RT and spreading the word about @CommonCrawl commoncrawl.org/donate/
-
Common Crawl Foundation reposted
Brewster Kahle
@brewster_kahle
Archive project launched! Media, Money & Elections: 2014 Philly Political Media Ad Watch...try it blog.archive.org/2014/10/15/media-money-elections-2014-ph…
@internetarchive -
Common Crawl Foundation
@CommonCrawl
Slashing #shipping #co2 #emissions needs #opendata, @IMOHQ told www.businessgreen.com/bg/news/2375142/slashing-shipping-e… #openweb #opengov #green #cleanenergy #bigdata #p2
-
Common Crawl Foundation reposted
Bolke de Bruin
@bolke2028
The value of data is relative. Better models means data is worth more #strataconf #strata #bigdata
-
Common Crawl Foundation
@CommonCrawl
Did you know @CommonCrawl is a 501c(3) nonprofit backed 100% by donations? Please RT help keep #opendata free! commoncrawl.org/collaborators #open
-
Common Crawl Foundation reposted
Smerity
@Smerity
PageRank on #webdatacommons Hyperlink Graph from @CommonCrawl data - 1 machine, 128 billion edges, 75 mins! @rmeusel
github.com/icoming/FlashGraph/wiki/Performance-of-FlashGraph -
Common Crawl Foundation
@CommonCrawl
10 Most Popular #datascience #presentations on @SlideShare www.techtarget.com #bigdata #analytics #datascientist #opendata
-
Common Crawl Foundation
@CommonCrawl
#dataviz / #datanalysis: rate of #ebola spread using #opendata from @WHO via @KDnuggets www.kdnuggets.com/2014/10/analyzing-ebola-spreading-expon… #bigdata #datascience
-
Common Crawl Foundation reposted
Computing History
@computermuseum
Has anyone got their original website on CD-ROM or floppies archived away? We are looking to build a collection of early websites.
-
Common Crawl Foundation
@CommonCrawl
200 #bigdata Leaders to follow on Twitter many @CommonCrawl friends on the list! @jahendler @acroll @bigdata & more! www.bigdata-madesimple.com/200-big-data-thought-leaders-t…
-
Common Crawl Foundation reposted
Tim O'Reilly
@timoreilly
Can we use data to make better regulations? workspaceupdates.googleblog.com/2023/04/new-community-fea… I respond to a recent @NewYorker op ed
-
Common Crawl Foundation
@CommonCrawl
Brazilian Government Develops Toolkit for #opendata Initatives blog.okfn.org/2014/10/07/branzilian-government-develops-t… #opengov #bigdata #datascience #openweb via @OKFN
-
Common Crawl Foundation
@CommonCrawl
Calculating the #risk of #searchengine #spam... "Don’t brush off the risk of a spam penalty" searchengineland.com/calculating-risk-search-engine-spam-… . #seo @sengineland
-
Common Crawl Foundation reposted
Kirk Borne
@KirkDBorne
.@DiegoKuonen @SYNTASACO @bobehayes I say that #datascience is Transdisciplinary => transcends discipline boundaries!
-
Common Crawl Foundation reposted
Smerity
@Smerity
Interested in how we use #aws at @CommonCrawl? Check out slides.com/smerity/aws-at-common-crawl
-
Common Crawl Foundation reposted
Lucy Bartlett
@Lucy_Bartlett
. @CommonCrawl a great tool for #socent looking for help with or want to access #bigdata . Learning going on at the Advanced AWS meet up!
-
Common Crawl Foundation
@CommonCrawl
From @timberners_lee: it's not just about getting data but being transparent up and down the supply chain www.cbronline.com/news/berners-lee-share-data-or-watch-yo… #opendata
-
Common Crawl Foundation
@CommonCrawl
Today launches @CommonCrawl Fall #fundraising Campaign! Please donate for #opendata& #openweb commoncrawl.org/donate
-
Common Crawl Foundation
@CommonCrawl
Stuff the #internet says about high #scalability highscalability.com/stuff-the-internet-says-on-scalabilit… via highscalability.com #datascience #highscalability #bigdata
-
Common Crawl Foundation
@CommonCrawl
Check out the new @commoncrawl website! commoncrawl.org
Common Crawl Foundation
@CommonCrawl
@digitalpebble Great idea! We will add some information about how we use Nutch today!
-
Common Crawl Foundation reposted
Kirk Borne
@KirkDBorne
Can #bigdata Tell Us What Clinical Trials Don’t? www.nytimes.com/2014/10/05/magazine/can-big-data-tell-us-… #healthcare #analytics
-
Common Crawl Foundation
@CommonCrawl
W/o #opendata #knowledge and #power are centralized- loss to #innovation europeanbusinessexpress.com/2014/10/02/digital-gold-turn-… @rufuspollock @okfn #opengov #openweb #open
-
Common Crawl Foundation
@CommonCrawl
#datadriven innovation key to combat #climatechange build #energyefficiency, #opendata tracks consumer #energy habits www.chicagotribune.com/bluesky/hub/chi-us-chamber-new-dat…
-
Common Crawl Foundation reposted
-
Common Crawl Foundation reposted
Stanford NLP Group
@stanfordnlp
Turns out big data analytics requires ability to understand different human languages. Who would’ve thought? www.foreignpolicy.com/articles/2014/09/26/why_big_data_mi… #nlproc
-
Common Crawl Foundation reposted
Jim Hendler
@jahendler
WooT, just learned I received @IBMResearch faculty award - thanks to my students and especially to @IBMWatson for all the help!
-
Common Crawl Foundation
@CommonCrawl
Some light Saturday reading! Top 10 #hadoop Blog Posts www.techtarget.com #bigdata
-
Common Crawl Foundation
@CommonCrawl
Interactive #timelapse of the #occupycentral protests in #hongkong using #opendata goo.gl/HNqyQ7 #dataviz
-
Common Crawl Foundation
@CommonCrawl
Building a better #data revolution mega888today.com #opendata #bigdata
-
Common Crawl Foundation reposted
mari muraki
@codemestat
Learning about web observatories w/ @CommonCrawl & @websciencetrust. If you're around Stanford's Green Library, come join the workshop.
-
Common Crawl Foundation reposted
Wendy Hall
@DameWendyDBE
Second day of #webobservatory @CommonCrawl workshop at Stanford. Beautiful day #webscience
-
Common Crawl Foundation
@CommonCrawl
-
Common Crawl Foundation
@CommonCrawl
#france becomes 1st #eu country with Chief #data Officer techcrunch.com/2014/09/17/france-announces-a-new-ambitiou… #opendata #opengov #bigdata
-
Common Crawl Foundation
@CommonCrawl
.@jahendler on the value of Web Observatories and schema.org
-
Common Crawl Foundation
@CommonCrawl
Listening to @DameWendyDBE give a wonderful talk on Web Science and the work of the Web Observatory!
-
Common Crawl Foundation reposted
Wendy Hall
@DameWendyDBE
With @jahendler at the #stanfordterraceinn looking forward to our workshop with @CommonCrawl at today
-
Common Crawl Foundation reposted
Kirk Borne
@KirkDBorne
The 22 "Must-have" Skills of a #datascientist: www.techtarget.com #abdsc #machinelearning #dataviz #statistics...
-
Common Crawl Foundation
@CommonCrawl
#deeplearning these days - FastML fastml.com/deep-learning-these-days/ via @fastml #machinelearning #datascience #data
-
Common Crawl Foundation reposted
Open Data Institute
@ODIHQ
Free upcoming lecture: Making music with #opendata. Friday, 7 Oct from 1pm. theodi.org/lunchtime-lectures/friday-lunchtime-lecture-ma…
-
Common Crawl Foundation
@CommonCrawl
How #opendata restored citizen trust in Indonesian election goo.gl/3M2Ef3 #opengov #openweb
-
Common Crawl Foundation
@CommonCrawl
16 Resources to Learn and understand #hadoop www.techtarget.com
-
Common Crawl Foundation
@CommonCrawl
Very excited for the Web Observatory Workshop with @DameWendyDBE and @jahendler at Stanford on 10/2! www.meetup.com/Open-Data-Bay-Area/events/209112862/
-
Common Crawl Foundation reposted
Tim O'Reilly
@timoreilly
Fantastic piece by @antheaws about why it's important for open data to be used by its producers
medium.com/@antheaws/hey-uncle-sam-eat-your-own-dogfood-9… #platforms -
Common Crawl Foundation
@CommonCrawl
180 #datascience, #bigdata & #analytics bloggers goo.gl/sAIkM8
-
Common Crawl Foundation reposted
Doug Cutting
@cutting
"Ultimately, open source is a requirement for widespread adoption." mobile.nytimes.com/blogs/bits/2014/09/27/more-open-source…
-
Common Crawl Foundation reposted
Open Knowledge Foundation (@okfn@fosstodon.org)
@OKFN
We've signed on to the Net Neutrality Coalition thisisnetneutrality.org - in support of the basic principles behind the open internet!
-
Common Crawl Foundation
@CommonCrawl
Exploratory #analysis of @CommonCrawl #opendata! goo.gl/yyp1vg @ntua & University of Thessaly
-
Common Crawl Foundation reposted
Tim O'Reilly
@timoreilly
Thanks for the shout out, @johnolilly! #cfasummit This is still such an important idea.
-
Common Crawl Foundation
@CommonCrawl
We'll see you at @sfopendrinks tonight in Berkeley! www.meetup.com/login/?returnUri=https%3A%2F%2Fwww.meetup.… Let's talk #opendata over a beer or few 6 PM @Freehouse2700
-
Common Crawl Foundation
@CommonCrawl
Wow! @CommonCrawl referenced 4 #open paraphrase database for Japanese @NAIST_MAIN_EN #opendata goo.gl/pvJ4qz
-
Common Crawl Foundation
@CommonCrawl
End of summer gift from @CommonCrawl! August crawl: 2.8 billion pages and 200+TB!! Let us know how you use #opendata! commoncrawl.org/blog/august-2014-crawl-data-available
-
Common Crawl Foundation
@CommonCrawl
Join us for the Web Observatory Workshop with @DameWendyDBE and @jahendler at Stanford on 10/2! www.meetup.com/Open-Data-Bay-Area/events/209112862/
-
Common Crawl Foundation reposted
SF Open Drinks
@sfopendrinks
Hey— SF Open Drinks’ers! We just got a meetup page. Sign up and RT. www.meetup.com/San-Francisco-Open-Drinks/ tx @boudicca
-
Common Crawl Foundation
@CommonCrawl
35 unusual problems that can be solved through #datascience www.techtarget.com #bigdata #opendata #opengov
-
Common Crawl Foundation
@CommonCrawl
RT @KirkDBorne: Easy way to learn #machinelearning: www.techtarget.com #abdsc #bigdata #analytics #datascience by @analyticbridge
-
Common Crawl Foundation reposted
Darth Meerkat
@DarthMeerkat
And the winner of the 'Modest Job title' goes to this chap.
-
Common Crawl Foundation
@CommonCrawl
GovFresh guide to OpenFDA govfresh.com/2014/09/openfda/ #opengov #opendata #civitech #openweb @govfresh @openFDA
-
Common Crawl Foundation reposted
Jim Hendler
@jahendler
Well-writen piece on difficulties in exploting #bigdata by non-profits and social orgs - blogs.hbr.org/2013/03/you-cant-just-hack-your-way-to/
-
Common Crawl Foundation reposted
Nova Spivack
@novaspivack
Big data study finds most productive people work in sprints: 52 minutes, rest for 17 venturebeat.com/2014/09/19/big-data-study-finds-most-prod…
-
Common Crawl Foundation
@CommonCrawl
Don't miss the @OReillyMedia webcast on becoming a data-driven enterprise by @AmandaKahlow on 10/1! www.oreilly.com/pub/e/3159
-
Common Crawl Foundation reposted
Tim O'Reilly
@timoreilly
How third-world tech can help the U.S. via @FortuneMagazine for.tn/1pUf3EF Good thoughts from Paul Maritz
-
Common Crawl Foundation
@CommonCrawl
Realtime automatic completion! #research uses @CommonCrawl #data from @PRHLT @upv Universitat Politècnica de València www.localprobook.com/article/CASMACAT.html
-
Common Crawl Foundation reposted
Heiko Ehrig
@heikoehrig
"Crunching @CommonCrawl with the Cloud-Based MIA Platform" at Strata EU Barcelona Nov 21st with @boudicca & @padolphs strataconf.com/strataeu2014/public/schedule/detail/37548
-
Common Crawl Foundation
@CommonCrawl
RT @kirkdborne: Warning: Your Mood May Affect Your Ability to Interpret Data www.columnfivemedia.com/blog/warning-mood-might-affect-ab… #analytics #datascience #dataviz
-
Common Crawl Foundation
@CommonCrawl
Answering Big Governance Questions Through #data blog.thegovlab.org/post/answering-big-governance-question… #opengov #opendata #bigdata #p2 #civitech #open
-
Common Crawl Foundation reposted
Neofonie GmbH
@neofonie
Welche Chancen bieten frei zugängliche Webdaten? Neofonie stellt zusammen mit @CommonCrawl Methoden vor. #strataconf www.neofonie.de/aktuelles/Neofonie_stellt_Webanalyse_Meth…
-
Common Crawl Foundation
@CommonCrawl
RT @github: Help us support the open Internet: github.com/blog/1888-join…
-
Common Crawl Foundation reposted
Open Data Institute
@ODIHQ
Sharing #data is useful but also risky - where is the trade-off? @statshero reflects on @ukan_net symposium t.co/qD1275aTon #opendata
-
Common Crawl Foundation
@CommonCrawl
#bigdata Practitioners need storytellers touch siliconangle.com/2014/09/04/big-data-practitioners-need-s… #datascience
-
Common Crawl Foundation reposted
Dataconomy
@DataconomyMedia
Twitter's #machinelearning expert talks us through the #algorithm that identifies interests and influencers: dataconomy.com/how-twitter-handles-your-data/
-
Common Crawl Foundation
@CommonCrawl
RT @syhw: I finally did this "harsh/hands-on intro/tips to deep learning" blog post:
snippyhollow.github.io/blog/2014/08/09/so-you-wanna-try-d… #deeplearning #machinelearning -
Common Crawl Foundation
@CommonCrawl
RT @dfjsteve: The locus of learning shifts from artifacts to the process of their creation via @VLAB #deeplearning
-
Common Crawl Foundation
@CommonCrawl
RT @worldbankdata: How are organizations maximizing #opendata that gov'ts publish? @ wrld.bg/B5UCg #opengov #openweb #p2
-
Common Crawl Foundation
@CommonCrawl
Researching using @CommonCrawl corpus! Translation project adaptation for MT-Enhanced computer assisted translation idp.springer.com/transit?redirect_uri=https%3A%2F%2Flink.…
-
Common Crawl Foundation
@CommonCrawl
Having the right dictionary is at the heart of any #textmining #analysis. www.analyticsvidhya.com/blog/2014/09/creating-dictionary-… #bigdata #businessanalytics #datascience
-
Common Crawl Foundation reposted
Data Science Central
@analyticbridge
36 #machinelearning resources and articles from data science and big data bloggers: www.techtarget.com
-
Common Crawl Foundation
@CommonCrawl
#data #mining Reveals How Social #coding Succeeds and Fails blog.urx.com/urx-blog/2014/9/4/the-science-of-crawl-part-… #github
-
Common Crawl Foundation
@CommonCrawl
RT @newsyc50: #machinelearning Cheat Sheet Map scikit-learn.org/stable/tutorial/machine_learning_map/ind… (news.ycombinator.com/item?id=8251710)
-
Common Crawl Foundation reposted
Raymond Yee (@rdhyee@social.tchncs.de)
@rdhyee
@edsu I'm working with @CommonCrawl folks on tutorials. e.g., IPython Notebook + docker to analyze CC data nbviewer.ipython.org/github/rdhyee/CommonCrawlTutorials/b…
-
Common Crawl Foundation
@CommonCrawl
RT @Terry_Timko: Nice pic: The Modern #datascientist
via @MktngDistillery -
Common Crawl Foundation
@CommonCrawl
#hadoop in the #cloud gaining traction, "HaaS" (ex @awscloud EMR) market expected to grow $16.1 billion by 2020... www.wsj.com/articles/BL-CIOB-5192
-
Common Crawl Foundation
@CommonCrawl
The #science of #webcrawl, Part 1: Deduplication of Web Content blog.urx.com/urx-blog/2014/9/4/the-science-of-crawl-part-…
-
Common Crawl Foundation
@CommonCrawl
RT @novaspivack: Meet the computer scientist trying to digitize, analyze and visualize our past — gigaom.com/blog/meet-the-computer-scientist-trying-to-dig… [love the vision!]
-
Common Crawl Foundation
@CommonCrawl
What is @CommonCrawl - Seek #data, Find Truth #opendata #opengov #datascience #startups #bigdata www.youtube.com/watch?v=ozX4GvUWDm4 Oldie but goodie!
-
Common Crawl Foundation reposted
Semantic Web
@SemanticWeb
Natural Language Processing Market Booms semanticweb.com/natural-language-processing-market-booms_… via @semanticweb
-
Common Crawl Foundation reposted
Tim O'Reilly
@timoreilly
Fascinating look at @safari's data analysis to categorize 25,000 books and 2400 videos blog.safaribooksonline.com/2014/09/03/safari-aggregations/
-
Common Crawl Foundation
@CommonCrawl
7 signs your hair is on fire: The challenges of #scaling #hadoop gigaom.com/blog/seven-challenges-scaling-hadoop/ #datascience via @gigaom
-
Common Crawl Foundation reposted
Dataconomy
@DataconomyMedia
Can #bigdata improve medical diagnoses? According to @JeremyPHoward and @Enlitic, the answer is yes: dataconomy.com/former-kaggle-chief-scientist-rolls-out-en…
-
Common Crawl Foundation reposted
Kirk Borne
@KirkDBorne
MediaLab = Nice resource for #dataviz, #sna analysis, scraping: tools.medialab.sciences-po.fr #bigdata #analytics | HT @LannyMorrow
-
Common Crawl Foundation
@CommonCrawl
RT @carlmalamud: This article about the @internetarchive @flickr reverse mashup www.bbc.com/news/technology-28976849 Great hack by Kalev Leetaru.
-
Common Crawl Foundation
@CommonCrawl
RT @openscience: With proper credit for sharing #opendata, science would accelerate www.wired.com/2014/08/sciences-big-data-problem/ #openscience
-
Common Crawl Foundation
@CommonCrawl
Excellent post by @rmeusel! Web Data Commons Extraction Framework for the Distributed Processing of @CommonCrawl Data commoncrawl.org/blog/web-data-commons-extraction-framewor…
-
Common Crawl Foundation
@CommonCrawl
#bigdata Divide: The challenge of modern-day #analytics platforms when you’re not #google www.techtarget.com #nosql #hadoop #datascience
-
Common Crawl Foundation reposted
SF Open Drinks
@sfopendrinks
Join us tonight at the South Beach Yacht Club (Pier 40A) @6pm for a very special edition of open drinks!
-
Common Crawl Foundation
@CommonCrawl
At Home with Tim O'Reilly "fascinating interview series @timoreilly and @slashdot. " slashdot.org/video/?embed=FxdG1wbzpSk8L_j3eXppL2T7BxlydkL1
-
Common Crawl Foundation
@CommonCrawl
RT @googleresearch: Machines read b/w the lines + new corpus w/ entity salience annotations goo.gl/MFkxGB #machinelearning
-
Common Crawl Foundation
@CommonCrawl
Fantastic new tool for extracting data from the @CommonCrawl corpus by Web Data Commons! WDC Extraction Framework webdatacommons.org/framework/
-
Common Crawl Foundation
@CommonCrawl
Deep Learning for NLP (Without Magic)" nice slides, videos; nlp.stanford.edu/courses/NAACL2013/ via @LannyMorrow
-
Common Crawl Foundation
@CommonCrawl
RT @thedatacrunch "Watch the global #hacking war in #realtime with a weirdly hypnotic #map " map.ipviking.com #bigdata #dataviz
-
Common Crawl Foundation
@CommonCrawl
Developing and Adopting #bigdata #machinelearning Practice: www.techtarget.com via @analyticbridge #datascience
-
Common Crawl Foundation
@CommonCrawl
The Philosophy of #datascience: “#semanticweb innovations are likely to have implications for us all” blogs.lse.ac.uk/impactofsocialsciences/2014/07/18/the-phi…
-
Common Crawl Foundation reposted
Gear11
@Gear11sw
Sifting the Web for RSS feeds with the help of @commoncrawl and Elastic Map Reduce: gear11.com/2014/08/sifting-the-web-for-rss-using-common-c…
-
Common Crawl Foundation
@CommonCrawl
RT @Mapbox: 1 million #ny high quality buildings+addresses on mapbox.com/blog/nyc-build… x.com/Mapbox/status/502909922670309376/photo/1 #openstreetmap #opendata
-
Common Crawl Foundation
@CommonCrawl
Check out @CommonCrawl's active Google Group, frequent responses from @Smerity! groups.google.com/forum/?fromgroups #datascientists #hackers #developers
-
Common Crawl Foundation
@CommonCrawl
RT @acroll: DATA+DESIGN: a free, simple introduction to preparing and visualizing information. infoactive.co/data-design/
-
Common Crawl Foundation
@CommonCrawl
RT @KirkDBorne: 12 Useful Things to Know about #machinelearning: linkd.in/1AEVhVT #datascience #statistics
-
Common Crawl Foundation
@CommonCrawl
Ranking each state on #opendata policy www.datainnovation.org/2014/08/state-open-data-policies-a… via @DataInnovation via @SunFoundation #opengov
-
Common Crawl Foundation reposted
Marco Bonzanini
@marcobonzanini
Great Sentiment Analysis tutorial sentiment.christopherpotts.net #nlp #machinelearning
-
Common Crawl Foundation
@CommonCrawl
RT @KirkDBorne Supervised #machinelearning A Review of #datamining Classification Techniques: www.informatica.si/PDF/31-3/11_Kotsiantis - Supervised Ma…
-
Common Crawl Foundation
@CommonCrawl
RT @timoreilly: I still LOVE the command line, and now this: Data Science at the Command Line datascienceatthecommandline.com Webcast Weds!
-
Common Crawl Foundation
@CommonCrawl
Neural Networks & #deeplearning neuralnetworksanddeeplearning.com #datascience #machinelearning by @michael_nielsen RT @KirkDBorne:
-
Common Crawl Foundation
@CommonCrawl
Why isn't all government software #opensource? by @BenBalter | red.ht/1sTECJD #opengov via @opensourceway #opendata
-
Common Crawl Foundation
@CommonCrawl
Introduction to #opensource #tech for developing #digitalmaps using #opendata: www.epsiplatform.eu/psi/ #epsi via @epsiplatform
-
Common Crawl Foundation
@CommonCrawl
RT @KirkDBorne: Multiple Deep Learning Tutorials: e-learning-teleformacion.blogspot.com/2014/08/deep-learni… #bigdata #datascience #machinelearning
-
Common Crawl Foundation
@CommonCrawl
#machinelearning at scale. MS&E 317: Algorithms for Modern Data Models web.stanford.edu/~ashishg/amdm/ #stanford via @plusepsilon
-
Common Crawl Foundation
@CommonCrawl
Emerging Insights from the first phase of Open Data in Developing Countries opendataresearch.org/sites/default/files/publications/Pha… #opendata via @OCSDNet #bigdata #opengov
-
Common Crawl Foundation
@CommonCrawl
RT @OpenGovHub: Thousands Can Fact-Check The News With Grasswire techcrunch.com/2014/08/05/thousands-can-fact-check-the-ne… #opengov #opendata
-
Common Crawl Foundation
@CommonCrawl
Not many tech talks include a haiku :) @Smerity at SF Python User Group
-
Common Crawl Foundation
@CommonCrawl
Watching @smerity give a great talk about using Python for big open data at SF Python User Group!
-
Common Crawl Foundation
@CommonCrawl
What to do with @commoncrawl from @xinglin87 xinglin-system.blogspot.com/2014/08/what-to-do-with-commo…
-
Common Crawl Foundation reposted
James O'Reilly
@jamesoreilly
RT @techdirt Spain's Ill-Conceived 'Google Tax' Law Likely To Cause Immense Damage To Digital Commons & Open Access feeds.feedburner.com/~r/techdirt/feed/~3/nvoLTpo1fa4/stor…
-
Common Crawl Foundation
@CommonCrawl
RT @anjacks0n #webarchiving in #javascript Age. The ubiquity of <script>: www.networksolutions.com/typepad?siteID=100&channelID=P99…
-
Common Crawl Foundation
@CommonCrawl
RT @peteskomoroch: Fascinating Look Inside The 1.1 Million #openinternet Comments www.npr.org/blogs/alltechconsidered/2014/08/12/339710293/… #openweb #netneutrality #bigdata
-
Common Crawl Foundation
@CommonCrawl
Why the #us #gov needs to embrace #open #data www.nextgov.com/emerging-tech/2014/08/government-platform… via @Nextgov @AliceLipowicz #opengov #opendata
-
Common Crawl Foundation reposted
TechCrunch
@TechCrunch
Any complex system with eyes is only as impartial as the algorithmic entity powering it tcrn.ch/1op6G9a
-
Common Crawl Foundation
@CommonCrawl
RT @bigdata: What every #datascientist needs to know about Active Learning: #strataconf @l2k www.oreilly.com/pub/e/3160 #crowdsourcing
-
Common Crawl Foundation
@CommonCrawl
6 comprehensive #dataviz catalogues for #journalists & #designers mediakar.org/2014/05/18/1708/ #datascience
-
Common Crawl Foundation
@CommonCrawl
A Trello List of Great #datascience Resources via @yarapavan: trello.com/b/rbpEfMld/data-science
-
Common Crawl Foundation
@CommonCrawl
Can #bigdata can answer big questions on #health? stan.md/1p5hwAu via @SUMedicine:
-
Common Crawl Foundation
@CommonCrawl
#publicsafety #civictech #innovation in-house in #sanfrancisco www.emergencymgmt.com/safety/Public-Safety-Innovation-San… #opengov
-
Common Crawl Foundation
@CommonCrawl
The Case for Comprehensive #opendata Legislation www.accela.com/blog/case-for-comprehensive-open-data-legi… #opengov #bigdata
-
Common Crawl Foundation
@CommonCrawl
Glove: Global vectors for word representation www.socher.org/index.php/Main/GloveGlobalVectorsForWordRe… Fascinating work from the Manning lab & they used @CommonCrawl data!
-
Common Crawl Foundation reposted
Pete Skomoroch
@peteskomoroch
Recommending music on Spotify with deep learning benanne.github.io/2014/08/05/spotify-cnns.html
-
Common Crawl Foundation
@CommonCrawl
CommonCrawl's July crawl is massive, just over 4 billion pages and 266 terabytes in size: that's a quarter petabyte!
commoncrawl.org/july-2014-crawl-data-available/ -
Common Crawl Foundation
@CommonCrawl
RT @OReillySolid @timoreilly on designing above the level of a single device to revolutionize societies goo.gl/mWpExQ
-
Common Crawl Foundation
@CommonCrawl
15 #opendata insights … via @OKFN #bigdata #opengov www.timdavies.org.uk/2014/07/22/3484/
-
Common Crawl Foundation
@CommonCrawl
RT @MSNewEngland: Great use of #opendata — 5 Questions With @MassInnov8 #massedudata Challenge Winner Rob Rolleston: archives.wbur.org/learninglab/2014/07/31/5-questions-with…
-
Common Crawl Foundation
@CommonCrawl
#google tells #eu forgetting isn't easy in today's #tech world www.hugedomains.com/domain_profile.cfm?d=viewstimes.com #righttobeforgotten #privacy #rtbf
-
Common Crawl Foundation
@CommonCrawl
Great read from @timoreilly www.linkedin.com/pulse/20140325160616-16553--they-have-no… on #opengov & need for #siliconvalley in DC #digitalcitizens #bigdata
-
Common Crawl Foundation
@CommonCrawl
Fascinating #longread #singapore experiments w/ #bigdata #surveillance for social harmony foreignpolicy.com/the-social-laboratory-singapore-surveil… #opengov
-
Common Crawl Foundation
@CommonCrawl
#wikipedia links to be removed by #google in #righttobeforgotten www.theguardian.com/technology/2014/aug/02/wikipedia-page… #rtbf #eu #privacy #freepress
-
Common Crawl Foundation
@CommonCrawl
Via @OKFestival: #business Models That Take Advantage of #opendata Opportunities www.programmableweb.com/news/okfestival-business-models-t… #bigdata
-
Common Crawl Foundation reposted
Alexander B. Howard
@digiphile
4 examples of #opendata & social impact, as shared by @sandramoscoso. www.datainnovation.org/2014/07/the-social-impact-of-open-… #opengov
-
Common Crawl Foundation
@CommonCrawl
RT @xamat: Videos from the @graphlabconf are now online youtube.com/playlist?list=…
-
Common Crawl Foundation
@CommonCrawl
#strataconf webcast by @l2k: Real-world Active Learning, a topic data scientists need to learn about www.oreilly.com/pub/e/3160 via @bigdata:
-
Common Crawl Foundation
@CommonCrawl
#opendata for economic growth by @WorldBank www.worldbank.org/content/dam/Worldbank/document/Open-Dat… via @napo #bigdata #opengov
-
Common Crawl Foundation
@CommonCrawl
How #opendata Might Be Transforming Citizen-Government Interaction innovationinsights.wired.com/insights/2014/07/quiet-revol… by #govhack #opengov #bigdata
-
Common Crawl Foundation
@CommonCrawl
Via @BigDataDiary: [Infographic]: Big Data And Its Importance In Future : www.toolsjournal.com/integrations-articles/item/3371-info…
-
Common Crawl Foundation reposted
Alistair Croll
@acroll
“Asking disruptors for a business plan is like asking Magellan to draw a map of the world before he’s even set sail" www.linkedin.com/today/post/article/20140731155812-511218…
-
Common Crawl Foundation
@CommonCrawl
Our 470 member #googlegroup groups.google.com/forum/?fromgroups invites collab 4 #hackers #coders #datascience #developers #opendata
-
Common Crawl Foundation
@CommonCrawl
Interested in processing WARC files incrementally with #python? We've just made it easier! Try it and give feedback!
github.com/commoncrawl/gzipstream -
Common Crawl Foundation
@CommonCrawl
Awesome #map @Morchickit Openness level in Europe according to the @OKFN open data index! @maps4thought
-
Common Crawl Foundation
@CommonCrawl
RT @anjacks0n: Wow, the @CommonCrawl dataset held at Amazon is just over half a petabyte of data. Nice. aws.amazon.com/datasets/41740 Thanks!
-
Common Crawl Foundation
@CommonCrawl
Missed @sunfoundation + @DataInnovation's panel on the social impact of #opendata? Recap + full video here: www.datainnovation.org/2014/07/event-recap-the-social-imp…
-
Common Crawl Foundation
@CommonCrawl
At #ups, a #bigdata system that boggles the mind for.tn/1mNNdIT via @FortuneMagazine:
-
Common Crawl Foundation reposted
Guardian Tech
@guardiantech
Right to be forgotten is unworkable, say peers feeds.theguardian.com/c/34708/f/663871/s/3cfdea97/sc/7/l/…
-
Common Crawl Foundation reposted
Tomasz Tunguz
@ttunguz
Great post by @frankbien of @LookerData => It's Time To Welcome The Chief Analytics Officer To The C-suite www.fastcompany.com/3033590/the-future-of-work/its-time-t…
-
Common Crawl Foundation reposted
Eric Baize
@ericbaize
In 10 years, I have not found a more effective picture to explain software security. #swsec
-
Common Crawl Foundation
@CommonCrawl
Map of US states altered according to population via @Amazing_Maps mentalfloss.com/article/56214/us-map-distorted-population #dataviz #maps #bigdata
-
Common Crawl Foundation reposted
Jason Trost
@jason_trost
This is begging for a @CommonCrawl study: Large-scale study of canvas fingerprinting, evercookies & cookie syncing securehomes.esat.kuleuven.be/~gacar/persistent/index.html
-
Common Crawl Foundation
@CommonCrawl
The Society of Editors warn on #righttobeforgotten societyofeditors.co.uk/page-view.php?pagename=News&parent… via @socofeduk #rtbf #eu #freepress
-
Common Crawl Foundation reposted
Forrester
@forrester
15% of global business and technology decision-makers are planning on investing in #bigdata in 2014. #forrbigdata s.forr.com/zmSF
-
Common Crawl Foundation reposted
High Point Travel BZ 😎
@HighPoinTravel
Interesting! “@2morrowknight: How Powerful Is Your Passport? huff.to/1x4kG9B #ttot #travel #dataviz ”
-
Common Crawl Foundation
@CommonCrawl
RT @CyrisXD: Verizon's Thoughts on speedtest.net x.com/CyrisXD/status/489950468483731458/photo/1
-
Common Crawl Foundation
@CommonCrawl
#opendata & #crowdfunding can breathe new life into democracy - t.co/x7MH3CAnHo via @VentureBeat t.co/Xw9936Kkjg @cityforward
-
Common Crawl Foundation
@CommonCrawl
3 reasons to embrace #open via @DigitalAgendaEU @NeelieKroesEU ec.europa.eu/commission/presscorner/detail/en/SPEECH_14_556 ec.europa.eu/commission/presscorner/detail/en/SPEECH_14_556 #opendata #opengov #p2
-
Common Crawl Foundation reposted
Michael Cavaretta
@mjcavaretta
RT @TextMining_r: A hyperlink graph of 3.5B web pages from @CommonCrawl www.reddit.com/r/textdatamining/comments/2arpee/a_hyperli… #bigdata ht @sgourley @DataScienceCtrl
-
Common Crawl Foundation
@CommonCrawl
How accessible are state exec orders? snlg.ht/1rdKoVA #opendata via @SunFoundation #opengov #bigdata
-
Common Crawl Foundation
@CommonCrawl
How #bigdata Brings #marketing & #finance Together blogs.hbr.org/2014/07/how-big-data-brings-marketing-and-f… via @dr_morton @HarvardBiz
-
Common Crawl Foundation
@CommonCrawl
Is anyone still saying #yolo? @yelp new #data tool can tell you www.wired.com/2014/07/yelps-new-data-tool-illuminates-tre… #news #socialmedia
-
Common Crawl Foundation
@CommonCrawl
Slides from @Smerity's presentation on measuring the impact of Google Analytics using @CommonCrawl data www.slideshare.net/ODBA/measuring-theimpactgoogleanalytics
-
Common Crawl Foundation
@CommonCrawl
Slides from Oskar Singer's talk The Switchabalizer - our journey from spell checker to homophone corrrecter www.slideshare.net/ODBA/sf-presentation-37367979
-
Common Crawl Foundation
@CommonCrawl
#opendata: To Improve Innovation, Do We Need to Share? via @myscienceworkhttp://ow.ly/zyaEf
-
Common Crawl Foundation reposted
Raymond Yee (@rdhyee@social.tchncs.de)
@rdhyee
I see that the @CommonCrawl google group (groups.google.com/forum/) is a good place to discuss tech -- nice replies from @Smerity
-
Common Crawl Foundation
@CommonCrawl
"#data is the fuel of innovation" #sacramento #bigdata is now #opendata www.publicceo.com/2014/07/sacramento-countys-big-data-ope… #opengov #govhack
-
Common Crawl Foundation
@CommonCrawl
What the Internet Can See From Your #cat Pictures www.nytimes.com/2014/07/23/upshot/what-the-internet-can-s… via @UpshotNYT #tgif #metadata #datascience ow.ly/i/6jEZo
-
Common Crawl Foundation reposted
Jason Trost
@jason_trost
Using Common Crawl to measure the prevalence of Google Analytics and the privacy implications slides.com/smerity/measuring-the-impact-google-analytics by @smerity
-
Common Crawl Foundation
@CommonCrawl
Thx to @OReillyMedia for providing books 4 our @OpenDataBA meet up tonight!
-
Common Crawl Foundation
@CommonCrawl
14 definitions of a #datascientist www.bigdata-madesimple.com/what-is-a-data-scientist-14-de… via @datamadesimple #datascience #bigdata #opendata
-
Common Crawl Foundation reposted
Tim O'Reilly
@timoreilly
Good piece by @zittrain: Don't force Google to 'forget' www.nytimes.com/2014/05/15/opinion/dont-force-google-to-f…
-
Common Crawl Foundation reposted
Pete Warden
@petewarden
Join me for a Deep Learning webcast tomorrow! petewarden.com/2014/07/23/join-me-for-a-deep-learning-web… - bring your questions too, I'll be doing a Q&A mc-ed by @bigdata
-
Common Crawl Foundation
@CommonCrawl
Open Data Bay Area is tonight in SF! Two great tech talks and many great conversations with smart interesting people www.meetup.com/Open-Data-Bay-Area/events/192665352/
-
Common Crawl Foundation reposted
Fight for the Future
@fightfortheftr
We need to get the whole Internet organized before the FCC decision this Fall. Here's our plan tumblr.fightforthefuture.org/post/92585274213/a-scary-num…
-
Common Crawl Foundation reposted
₿en ₿utler
@bensbutler
Check out the new AWS Big Data Technology Fundamentals course: www.aws.training/learningobject/wbc?id=35364 #bigdata
-
Common Crawl Foundation
@CommonCrawl
#bigdata & #opendata can make the world a fairer place #socialjustice newsroom.ucla.edu/stories/can-big-data-transform-social-j… ow.ly/i/6iRI5
-
Common Crawl Foundation
@CommonCrawl
What the biggest players told @fcc about #netneutrality @aclu @reddit @verizon consumerist.com/2014/07/18/from-att-to-verizon-what-the-w… ow.ly/i/6iQZc
-
Common Crawl Foundation
@CommonCrawl
TOMORROW: @Commoncrawl #bigdata #opendata #meetup 7/23 w/ speakrs @Smerity & Oskar Singer! www.meetup.com/ai-ml-workshop/events/192665352/ Please RT!
-
Common Crawl Foundation
@CommonCrawl
No appeals process for #rtbf #google is the gatekeeper of #freepress? www.independent.ie/business/technology/googles-mighty-mes… ow.ly/i/6iQLg @indobusiness
-
Common Crawl Foundation
@CommonCrawl
#sanfrancisco @mayoredlee announces #opendata strategic plan medcitynews.com/2014/07/san-franciscos-chief-data-officer… #opengov #bigdata
-
Common Crawl Foundation
@CommonCrawl
hiddenfromgoogle.com check out who the #internet has forgotten in the #eu #rtbf #rightobeforgotten ow.ly/i/6fLUy
-
Common Crawl Foundation
@CommonCrawl
"the highly complex analyses...exceeded human ability to diagnose" www.bigdata-madesimple.com/case-study-big-data-improves-c… Wow! #machinelearning #digitalhealth
-
Common Crawl Foundation
@CommonCrawl
Yikes! #google receiving 1000+ takedown reqs/day since #righttobeforgotten pressgazette.co.uk/publishers/digital-journalism/bing-and… #privacy #eu #rtbf #tech
-
Common Crawl Foundation
@CommonCrawl
7/23 @Smerity & Oskar Singer talk about @CommonCrawl projects at #bigdata meetup! #opendata www.meetup.com/ai-ml-workshop/events/192665352/ ow.ly/i/6eUXA
-
Common Crawl Foundation
@CommonCrawl
Jer Throp explains data trails @blprnt vimeo.com/91054550 #vimeo #dataviz
-
Common Crawl Foundation
@CommonCrawl
3 Ways Cities Can Grow Open Data Projects www.govtech.com/data/3-Ways-Cities-Can-Grow-Open-Data-Pro… #opengov #opendata #bigdata #govhack
-
Common Crawl Foundation
@CommonCrawl
Our 470 member #googlegroup groups.google.com/forum/?fromgroups invites collab 4 #hackers #coders #datascience #developers #opendata
-
Common Crawl Foundation
@CommonCrawl
Another Right To Be Forgotten Request Backfires Completely www.techdirt.com/articles/20140716/08170927896/another-ri… via @Techdirt #rtbf #eu #google
-
Common Crawl Foundation
@CommonCrawl
humans and robots will grow #economy & #jobs thru "middle work" via @novaspivack @tecchrunch techcrunch.com/2014/07/12/humans-and-computers-will-come-…
-
Common Crawl Foundation
@CommonCrawl
Tonight's @sfopendrinks moved to Palomino (across the street from Waterbar). Come join us to talk open source, open web and open data!
-
Common Crawl Foundation
@CommonCrawl
Watching a demo if the awesome @mozilla Appmaker at the @webmaker webmaker launch! Check out webmaker.org
-
Common Crawl Foundation
@CommonCrawl
Don't miss @oreillymedia webcast How to Get Started with Deep Learning in Computer Vision www.oreilly.com/pub/e/3121 @petewarden @bigdata
-
Common Crawl Foundation reposted
mza
@mza
Nice post on the new #aws Big Data blog: building a recommender with Mahout and EMR: blogs.aws.amazon.com/bigdata/post/Tx1TDK3HHBD4EZL/Buildin…
-
Common Crawl Foundation reposted
₿en ₿utler
@bensbutler
Excited to introduce our new #aws #bigdata blog! blogs.aws.amazon.com/bigdata/
-
Common Crawl Foundation
@CommonCrawl
Maker Cantina tonight at @mozilla SF kicking off @webmaker Maker Party party.webmaker.org Details about tonight events.webmaker.org
-
Common Crawl Foundation
@CommonCrawl
Join #bigdata #meetup 7/23 @Smerity & Oskar Singer talk @commoncrawl #data www.meetup.com/ai-ml-workshop/events/192665352/ Please RT! #opendata
-
Common Crawl Foundation reposted
Lisa Green
@boudicca
Super excited for @sfopendrinks tonight! 5.30pm at Waterbar. Lots of smart folks talking open science, open data, open knowledge, open code!
-
Common Crawl Foundation
@CommonCrawl
What is #deeplearning & why should u care? via @acroll @radar @oreillymedia #machinelearning #datascience www.oreilly.com/radar/
-
Common Crawl Foundation
@CommonCrawl
Come see two great tech talks by @Smerity and Oskar Singer on working with @CommonCrawl data on 7/23 in SF! #bigdata www.meetup.com/Open-Data-Bay-Area/events/192665352/