Jerry Liu
@jerryjliu0

You shouldn’t blindly trust benchmarks - you should be able to encode your preferences relative to your use cases and design eval metrics around that.
We’re excited to release ParseBench-2 as not only a comprehensive document parsing benchmark, but also a framework for parsing benchmark design. Where you can articulate a set of human preferences of what “good parsing” looks like and “hillclimb” evaluation metrics against that.
The important part is not hand-crafting a deterministic parsing metric. Metric design can be automated by coding agents; what’s important is an open framework + datasets for encoding human preferences and optimizing metrics.
📋 For instance, if you’re dealing with mostly backoffice data, you may care about accurate form parsing, bounding boxes, and scans!
📊 On the other hand, if you’re dealing with investor research reports, you may care more about tables and charts, but less around handwriting.
We let you encode a severity policy that encodes the impact of every negative parsing error, and forces the metric to fit against it - think of fitting a linear regression in high-dimensional space.
A baseline approach for encoding human preferences is LLM as a judge. But the result of this approach vs. a “simple” LLM as a judge call is that you get much more granular, repeatable, quantifiable breakdowns of each dimension that are efficiently run at scale.
For instance, one OCR tool might be better at linearizing text, but worse at preserving formatting. Another OCR tool might be better at preserving empty rows in tables but struggle with merged cells.
The scores reflected on our website do reflect a “default” preference, but it is explicitly and transparently articulated both in our Github and technical report. The important part is that you can change and customize it for your needs.
ParseBench-2 is our most ambitious, comprehensive open benchmark to date. It is not simply a set of deterministic metrics, but a framework for designing parse evals.
We’re rapidly working on improvements and expansions (e.g. fixing minor annotation issues and tuning metrics). If you have thoughts please chime in! Everything is fully OSS.
ParseBench-2 Repo: github.com/run-llama/parsebench
ParseBench-2 Blog: www.llamaindex.ai/blog
Technical Report: www.llamaindex.ai/files/parsebench-v2-severity-aware-eval…
Jerry Liu
@jerryjliu0
Today we’re introducing ParseBench-2 - our most ambitious document parsing benchmark to date.
It is the only benchmark that provides both extreme granularity into every single type of production parsing error, while also making sure that metric scores are highly aligned with human judgment. We do this by painstakingly assigning severity scores to 330+ error types, and tuning each metric to match the severity scores.
Existing benchmarks either use brittle deterministic metrics (e.g. OmniDocBench) or LLM-as-a-judge (ParseArena), which can help recognize equivalent representations but are coarse/stochastic/subject to bias by the prompt+model.
ParseBench-2 also contains:
✅ 4.3k+ document pages (double from ParseBench-1).
✅ An extra dimension (forms)
✅ Much better ground-truth across all dimensions compared to ParseBench-1.
This is the next evolution of ParseBench, our hugely popular benchmark that has 50k+ monthly downloads, over 150+ OCR solutions benchmarked, and has been adopted by companies like NVIDIA, Cohere, Aleph Alpha, Perplexity, and others.
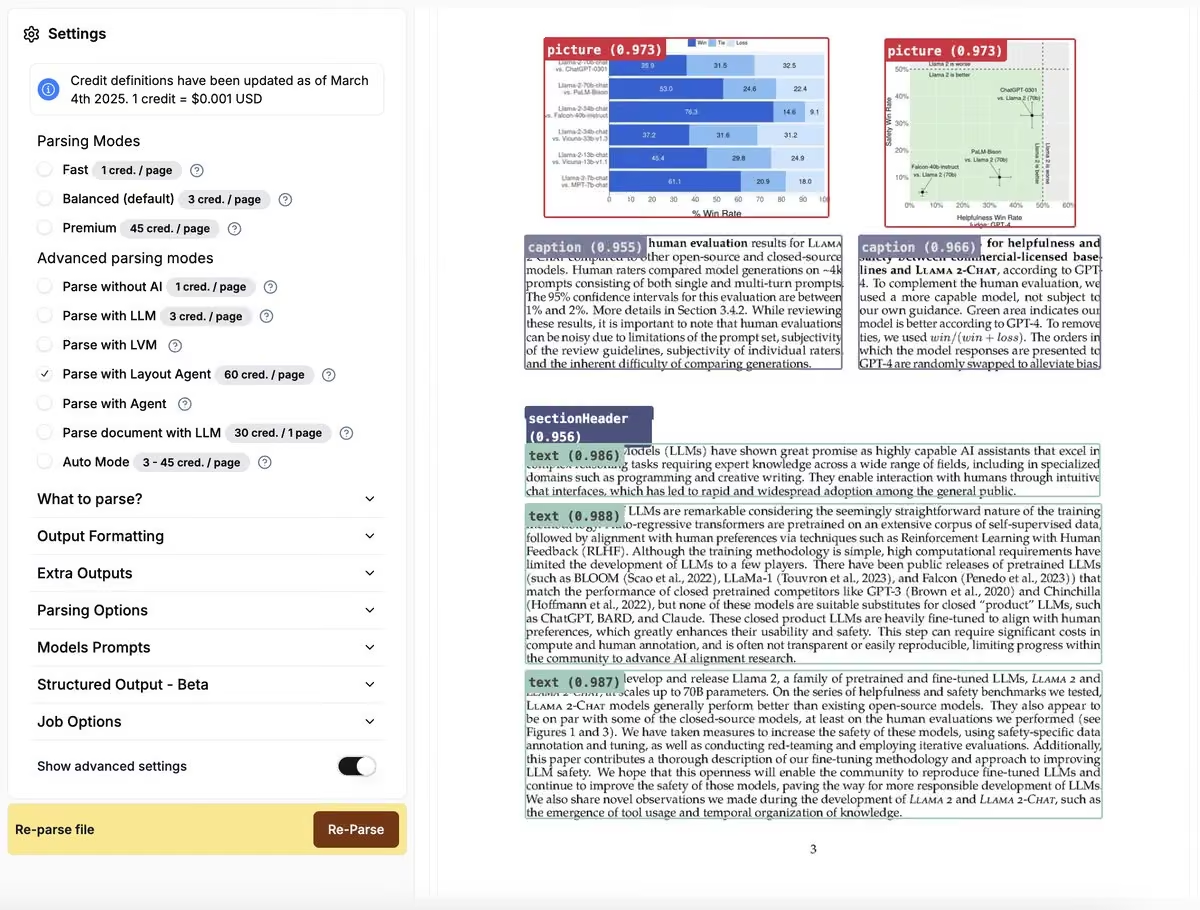
Alongside ParseBench-2, we are also releasing OCRia-1.5 - a new family of document parsing models that powers all our modes in LlamaParse. They represent a massive step up in capabilities from our latest release, and are state of the art in parsing complex tables, forms, charts, formatting, and assigning bounding boxes to complex layouts.
Come check out our blog post, technical report, and website.
Blog: www.llamaindex.ai/blog/introducing-parsebench-v2
Technical Report: www.llamaindex.ai/files/parsebench-v2-severity-aware-eval…
Website: www.parsebench.ai
If you’re interested in trying out our OCRia-1.5 capabilities, come sign up for LlamaParse: cloud.llamaindex.ai


 Imaan Sultan 🇵🇰🇸🇦




 Logan Markewich


 KERNEL


 Daytona


 Julia Fedorin


 GMI Cloud


 Claude


 Murtaza Khomusi






 Google AI Developers




 andrew pignanelli


 Wing VC


 Simon Willison


 Clelia Bertelli🧑🚀


 Auth0


 Shubham Saboo

 Tuana


 Bearly AI


 Peter Yang


 Cursor




 jason
 Taqi Jaffri


 Saroop Bharwani
 Dragonfly








 Marcus Schiesser




 harpreet


 Noah Hein




 DataCamp


 Robert Schwentker


 AI.Engineer 🔜 CODE


 Gradio


 Y Combinator



 OpenAI Developers





 Ofer Mendelevitch


 Karan Vaidya


 Akshay 🚀


 Barr Yaron

 Logan Kilpatrick


 yenkel


 Avi Chawla


 Qdrant


 Corinne Marie Riley


 Luke Tucker


 MLflow