If you're interested in trying Kimi K3.1 Pro (for free) we're hosting a hackathon with some crazy prizes :)
luma.com/cerebras-kimi-hackathon
Cerebras Systems
Cerebras Systems Inc., headquartered in Sunnyvale, California, develops semiconductors, supercomputers, and related software to power artificial intelligence deep-learning applications such as inference engines. Products include its wafer scale engine (WSE)-3 semiconductors, its CS-3 supercomputers, and its "AI inference cloud" and "AI training cloud" APIs, which allow users to access the company's computing power without buying its hardware. The company also builds data centers using its processors and supercomputers to provide cloud computing services directly to clients. More on Wikipedia
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Sarah Chieng
@MilksandMatcha
-
Cerebras
@cerebras
Cerebras today announced financial results for Q3 2026, delivering record revenue, and raising full year outlook.
Q3 2026 highlights:
• Record Revenue: GAAP cloud revenue grew 265%; Core cloud revenue grew 272%
• 700 MW of data center capacity now under contract
• Commercial wins with 2 new hyperscalers
• Day-zero launch partner for @Kimi_Moonshot K3.1, running at up to 2,000 tps
• Raised Q4 guidance and full year outlook across the board
Cerebras
@cerebras
Details: investors.cerebras.ai/news-releases/news-release-details/…
-
Cerebras
@cerebras
Excited to be a day 0 @kimi_moonshot partner!
Sarah Chieng
@MilksandMatcha
-
Cerebras
@cerebras
World-class AI performance, meeting everyday life. @BiltRewards 👋
Andrew Feldman
@andrewdfeldman
A chip the size of a dinner plate, to help you book your next dinner.
@BiltRewards selected @Cerebras to power its Neighborhood OS and AI assistant, Bilt Concierge.
More than 8 million people across the US use Bilt to earn rewards on rent.
Bilt allows members to spend those rewards at 50,000+ local merchants.
Now, with Bilt Concierge, an AI agent can do it for you.
Just ask it to book a table, plan a trip or shop locally and it’s done.
With Cerebras, those services will be near instant.
World-class AI performance, meeting everyday life.
Excited to partner with @ankurjain_2 and the @BiltRewards team. -
Cerebras reposted
Alycia Cary
@alyciazcary
Making this engineering documentary was one of the first things I wanted to do @cerebras
There is much in here about what it takes to make something new, how to push ideas beyond what is possible, and about work that is continual discovery and invention — because that is what this team has done together for years.
Being in the same room as these people is both humbling and inspiring -- let alone trying to tell the story of what they've built. I hope it is as fun to watch as it was to make!
Cerebras
@cerebras
Fearless Engineering: The CS-4 is our first engineering documentary.
Through lab footage and conversations with the engineers behind each breakthrough, the film follows the creation of the CS-4, our latest wafer-scale AI system.
0:00 introducing the engineering team
1:09 Wafer-scale history
2:28 Powering the wafer
4:00 The cooling problem
4:18 Designing the cold plate
5:11 Holes in the wafer
6:33 the alignment problem
7:47 The CS-4 PRD
8:35 Designing for deployability and serviceability
11:01 Removing the motherboard
11:25 Removing internal cooling loops
11:41 inventing the power rack
12:35 A one-person lab deployment
14:03 Backpack: 50% fewer components
14:55 Connecting the compute backpack to cooling manifold
17:58 shifting Cerebras’s focus from training to inference
19:09 Building the Cerebras Cloud
20:01 CS-3 vs. CS-4 performance
20:49 3D Stacked DRAMThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Behind the scenes at @cerebras HQ in south bay. If you're around, come say hi and grab lunch.
Gotta update the whiteboard with Kimi K3.1 Pro. -
Cerebras
@cerebras
Fearless Engineering: The CS-4 is our first engineering documentary.
Through lab footage and conversations with the engineers behind each breakthrough, the film follows the creation of the CS-4, our latest wafer-scale AI system.
0:00 introducing the engineering team
1:09 Wafer-scale history
2:28 Powering the wafer
4:00 The cooling problem
4:18 Designing the cold plate
5:11 Holes in the wafer
6:33 the alignment problem
7:47 The CS-4 PRD
8:35 Designing for deployability and serviceability
11:01 Removing the motherboard
11:25 Removing internal cooling loops
11:41 inventing the power rack
12:35 A one-person lab deployment
14:03 Backpack: 50% fewer components
14:55 Connecting the compute backpack to cooling manifold
17:58 shifting Cerebras’s focus from training to inference
19:09 Building the Cerebras Cloud
20:01 CS-3 vs. CS-4 performance
20:49 3D Stacked DRAMThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Moonshot just dropped Kimi K3.1 Pro. We used it to speed run online shopping.
One prompt → monitor found → checkout → order confirmed.
11.5 seconds.
Watch @Kimi_Moonshot K3.1 Pro in action, accelerated by Cerebras. -
Cerebras
@cerebras
Last week, short seller @CulperResearch, published a report arguing that Cerebras wafers wear out after about two years. Nearly every financial conclusion in that report depends on that one number.
That number is wrong.
How long our systems last is a fair question, so we want to address the topic plainly. Read our response on our blog.
cerebras.ai/blog/what-it-took-to-build-wafer-scale-and-wh… -
Cerebras
@cerebras
On Big Chip Club, @MilksandMatcha talks with @cdngdev, the former @OpenAI robotics intern behind this summer’s viral Astra robot-painting demo.
They discuss the creative process behind building products people want to make for themselves, why robotics needs fast inference, and what recursive self-improvement (RSI) would require.
0:00 Meet Thijs: Discord, OpenAI, and Stanford
0:47 Building a wardrobe app in a day
3:17 Making demos that cut through the noise
4:43 Whimsical and practical demos
5:25 Where good ideas come from
7:04 Teaching a robot to paint the Golden Gate Bridge
8:52 Improving the robot’s painting ability
10:34 Giving Sam Altman the robot’s painting
12:00 Why robots need fast inference
14:11 What demos should Cerebras build?
15:07 Getting started with robot arms
16:33 Recreating apps and 3D models on demand
17:56 From generated models to physical things
19:45 Inside OpenAI
20:17 What RSI means
23:11 Getting AI's benefits to everyone
24:39 Personal assistants for everyday tasksThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
I asked Naji Jackson, former personal assistant to @alexandr_wang and EA to @rauchg, about the craziest thing she's ever had to do as an assistant.
From @najtheconnector herself:This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Naji Jackson has spent more than 20 years supporting leaders in tech, including @alexandr_wang and @rauchg.
She joins @MilksandMatcha on @Cerebras' Big Chip Club to talk about the AI tools she has tried, why fast inference matters for making AI assistants useful, and the trust and judgment involved in the job.
0:00 Meet Naji Jackson
1:20 Being an executive assistant to some of the most influential people in tech
3:14 The craziest thing she’s had to do as an EA
5:10 Learning preferences and anticipating needs
6:56 Testing Grok Bot, Meta Muse, and Claude Cowork
9:42 What do AI assistants still need to improve?
11:27 Why AI assistants must be fast to be useful
15:28 Can AI replace a human assistant?
16:42 Personal assistants vs. executive assistants
17:37 How to hire a personal assistant
19:47 How to reach NajiThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sean Lie
@seanlie
How we deploy multi-trillion parameter models at scale
Today, let's break down the math for how @cerebras:
1. Fits the full model into on-chip memory
2. Maps the model across multiple chips
3. Handles a high # of concurrent requestsThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Will AI ever replace high-caliber assistants?
I asked Naji Jackson (@najtheconnector), who has spent 20+ years as a personal assistant in tech, including working with @alexandr_wang and @rauchg.
Presented by @Cerebras for Big Chip ClubThis media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Naji Jackson has spent more than 20 years supporting leaders in tech, including @alexandr_wang and @rauchg.
She joins @MilksandMatcha on @Cerebras' Big Chip Club to talk about the AI tools she has tried, why fast inference matters for making AI assistants useful, and the trust and judgment involved in the job.
0:00 Meet Naji Jackson
1:20 Being an executive assistant to some of the most influential people in tech
3:14 The craziest thing she’s had to do as an EA
5:10 Learning preferences and anticipating needs
6:56 Testing Grok Bot, Meta Muse, and Claude Cowork
9:42 What do AI assistants still need to improve?
11:27 Why AI assistants must be fast to be useful
15:28 Can AI replace a human assistant?
16:42 Personal assistants vs. executive assistants
17:37 How to hire a personal assistant
19:47 How to reach NajiThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
When Cerebras started, data centers were built for roughly 5 kW per rack. A single one of our chips needed more than that.
Today, AI racks from NVIDIA and AMD also draw 100–200 kW. The power and liquid cooling infrastructure we needed early on has become industry standard.
I sat down with our cofounder and CTO @seanlie to talk behind-the-scenes what it actually takes to deploy @cerebras hardware, and how we bring up larger models.
0:25 Does a dinner-plate-sized chip need a special data center?
1:48 Why liquid cooling makes denser racks possible
3:24 From delivered racks to production tokens
4:17 Things fail constantly. How do you keep serving?
5:39 What changes when you want to run a bigger model?
7:38 Can our CTO recognize our own data centers?This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Our ambassadors made October a massive global movement for fast inference! We hosted Cafe Compute Meetups in 15 cities:
Boston • Bengaluru • Dubai • Austin • Brisbane • Melbourne • Indore • Barcelona • Mexico City • Bhopal • Seoul • London • San Francisco • Dublin • Taipei
A massive shoutout to our incredible Cerebras Ambassadors who are growing their local AI communities around the world. 🙌
Want to bring fast inference to your community? Apply to become a Cerebras Ambassador: www.cerebras.ai/ambassadors -
Cerebras
@cerebras
Breaking it down with Sean Lie, our CTO,
How we deploy Trillion-parameter frontier models on Cerebras
Sean Lie
@seanlie
How we deploy multi-trillion parameter models at scale
Today, let's break down the math for how @cerebras:
1. Fits the full model into on-chip memory
2. Maps the model across multiple chips
3. Handles a high # of concurrent requestsThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Read more: www.cerebras.ai/press-release/cerebras-and-oracle-team-up…
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
How to deploy multi-trillion parameter models (fast):
A single Cerebras WSE-3T wafer has 44 GB of on-chip memory, and trillion-parameter frontier models need terabytes for their weights alone.
We’ll use the open source model Kimi K3, with ~3 trillion parameters, as an illustrative example.
For this illustrative example, we use:
- A 256k assumed average request size
- 4-bit weight quantization (like theHugging Face implementation)
- An 8-bit KV cache
## Size of Each Layer
Kimi K3 has 3 trillion parameters. If all 3T parameters are stored at 4 bits each, the raw parameter payload is:
3T x 4 bits / bits per byte = 1.5 TB
divide by 93 layers gives
1500 GB / 93 = 16 GB per layer
## Number of wafers
We can fit 2 linear layers per wafer and 1 dense layer per wafer
69 linear layers / 2 = 35 wafers
24 dense layers / 1 = 24 wafers
total = 35 + 24 wafers
## How many requests can we serve
We only need to calculate KV cache requirements for dense layers.
We can calculate the remaining space for the KV cache with Total wafer storage - size of one dense layer.
44 GB - 16 GB = 28 GB
To find the number of concurrent requests supported for any particular model mapping, we first calculate how much cache a single 256k request takes up:
576 byes / 256,000 = 147 MB per equence
Then divide:
28 GB / 147 MB = 190 concurrent requests
The same approach extends to larger models: calculate the memory needed for weights and request state, distribute the model across wafers, and connect them into a pipeline. Each additional wafer contributes compute and on-chip memory, allowing us to accommodate models that exceed the capacity of any single chip. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
We are converting a 102 year old building in SF into a haunted house for Halloween next Friday
We are orchestrating horror actors, among many other freak show things.
Presented by @cerebras x @SpaceXSI -
Cerebras
@cerebras
Naji Jackson has spent more than 20 years supporting leaders in tech, including @alexandr_wang and @rauchg.
She joins @MilksandMatcha on @Cerebras' Big Chip Club to talk about the AI tools she has tried, why fast inference matters for making AI assistants useful, and the trust and judgment involved in the job.
0:00 Meet Naji Jackson
1:20 Being an executive assistant to some of the most influential people in tech
3:14 The craziest thing she’s had to do as an EA
5:10 Learning preferences and anticipating needs
6:56 Testing Grok Bot, Meta Muse, and Claude Cowork
9:42 What do AI assistants still need to improve?
11:27 Why AI assistants must be fast to be useful
15:28 Can AI replace a human assistant?
16:42 Personal assistants vs. executive assistants
17:37 How to hire a personal assistant
19:47 How to reach NajiThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
To put this in context, it helps to compare @cerebras with how GPUs run large models. GPUs face two key challenges that the wafer-scale design avoids.
#1: Weights live off-chip
On a Cerebras wafer, each layer’s weights sit in on-chip SRAM right next to the compute that uses them. Nothing has to be fetched per token, so the bandwidth bottleneck goes away.
In contrast, a GPU has only tens of MB of on-chip SRAM, so model weights are stored in off-chip HBM. To generate each token, the GPU has to stream every layer’s weights from HBM into its compute cores. As a result, decoding is usually limited by memory bandwidth, not compute.
#2: A GPU cannot fit a model layer on chip
On a Cerebras wafer, each wafer has 44 GB of on-chip memory allowing entire model layers to fit on a single chip.
In contrast, a GPU often cannot fit a single model layer in fast on-chip memory, so you have to shard the same layer about multiple GPUs in HBM (tensor parallelism). Each GPU computes part of the layer, and the GPUs then have to combine their partial results before the next layer can start. That synchronization happens several times per layer, on every token, which adds communication overhead and latency at every step.
All of this traffic leaves the chip and travels over external links and switches. A full 72-GPU Rubin NVL72 rack, for example, connects its GPUs with roughly 5,000 internal copper cables, for 260 TB/s of total NVLink bandwidth.
A single WSE-3T has 53.5 PB/s of on-wafer fabric bandwidth, more than 200x that of the entire rack. At the small batch sizes used for fast decoding, this communication can take as long as the computation itself. -
Cerebras
@cerebras
Cerebras speed. @awscloud simplicity.
This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Use your existing AWS account to subscribe to Cerebras Inference: aws.amazon.com/marketplace/pp/prodview-ph4bdvplhhz3o?appl…
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
The @cerebras team booked a world champion olympic climber, Janja Garnbret, for a private climbing workshop in SF.
Full climbing gym book out as well. Drop a #bigchipenergy for an invite. -
Cerebras
@cerebras
46,225 mm² of silicon
4 trillion transistors
900,000 AI-optimized cores
250 petaflops of AI compute
At the center of every CS-4 Wafer-Scale Backpack is the WSE-3 Turbo ⤵️This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
The new physics of cybersecurity makes inference speed essential. Defenders now need to detect, reason, and act so much faster than attackers.
Read more about how Cerebras is partnering with CrowdStrike to accelerate that defense loop 👇
Thank you, @gdb, for highlighting how AI-enabled cybersecurity is more critical than ever!
sarah guo
@saranormous
OpenAI took 25% of its production engineers off every project and told them: you are just securing now. Their top model hunted in their infrastructure until it saturated (stopped finding new issues).
Will everyone else follow?
New physics of cybersecurity
@gdb / @NoPriorsPodThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Your AI agent has a to-do list. Waiting shouldn’t be the longest item.
Cerebras’ Andy Hock joins theCUBE to discuss why inference speed matters for reasoning models and AI agents.
Where would less waiting make the biggest difference?
Watch the full conversation with Andy Hock and theCUBE:
www.youtube.com/watch?v=H2GnroPz95w -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
AI is raising the stakes in cybersecurity.
If attacks are fast, defense must be faster.
Speed is becoming a security primitive.
Greg Brockman
@gdb
6 days and $40,000 of compute with GPT-5.6 Sol to find a critical vulnerability in Chrome, claiming Google’s first full-chain reward in 2026 for a vulnerability that would affect an estimated 1 billion users.
Highlights the opportunity for defenders to utilize these tools to secure their software to unprecedented levels:
Oege de Moor
@oegerikus
For the second time in Google Chrome’s history, Google awarded a $250,000 bounty for a full-chain exploit… to @XBOW. Here’s the full story:
At an all-hands at the start of 2026 in Malta, I set the team a crazy challenge. A full-chain exploit of Chrome by the annual Black Hat cybersecurity conference in August.
I believed there were few better tests of whether @XBOW could move beyond web applications to desktop software, servers and devices.
Chrome is one of the most hardened pieces of software on the planet, used by more than half the world’s population.
A full-chain exploit lets an attacker take total control of a machine, where they can read every email, password and bank login the user types. You don’t need to download anything or click a phishing link. Visiting the wrong site is enough.
So @moyix, Andres Luksenberg, Baul Lee, and Willem Pinckaers took on the challenge along with a fifth teammate: OpenAI's GPT-5.6 Sol.
They built a chain they thought would win, but Google told us they already knew one of the bugs.
We were already in Las Vegas for Black Hat and DEF CON, and the team didn’t want to go home without the win.
So Brendan and the agents built a new exploit in just 6 days.
We submitted it to Google and waited.
The news came through that we'd done what should’ve been impossible. A full-chain bounty of $250,000, the first awarded under Google’s 2026 rules.
It took just 6 days and $40,000 of compute to construct an exploit that affects a billion users of Chrome on Windows. An intelligence-agency veteran told me his team used to spend 6 months on this kind of vulnerability.
My takeaway: the cost of finding truly critical vulnerabilities is collapsing, for attackers and defenders alike. Restricting powerful models is not the answer; GPT-5.6 Sol is already public.
But defenders have one advantage attackers never will: they can test their own code first.
Assume your software is exploitable. Whoever is hunting your bugs has the same building blocks we did.
This is cause for urgency but not panic.
XBOW is now developing an autonomous product for testing compiled software (desktop applications, servers, embedded devices), and partnering with the world’s top organizations to design that product.
If you’d like to be one of them, get in touch.
P.S. Restart Chrome whenever the Update button appears! -
Cerebras
@cerebras
AI agents rely on a good harness.
Faster inference gives a harness room to inspect results and recover sooner, while you steer the work. @MilksandMatcha breaks down the loop. -
Cerebras
@cerebras
See you in Chicago for @Supercomputing 26!
-
Cerebras reposted
Cerebras
@cerebras
If the cyber attack is fast, the defense must be faster. By removing inference as a bottleneck, Cerebras helps defenders act before attackers can advance. x.com/i/article/2102944198404304896
-
Cerebras reposted
Julie Shin Choi (she/her)
@juliechoi
How do you SCALE FAST in this explosive moment of growth?
That was the SF Tech Week conversation I joined at @genspark_ai Spark House alongside @sang_wen @zacharylipton @shengao @MarkMcQuade.
Whether building agents, models, or AI native experiences, speed matters.
Speed of execution.
Speed of tokens.
Speed to market.
At @Cerebras, we think about this all day, everyday.
Another protip: hire your marketers faster than you think! 😉
@sang_wen tysm for bringing us together.
#sftechweek @Techweek_ -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Thousands of people applied to become @cerebras ambassadors, and I’m so proud of the cohort we’ve brought together.
Many of our Ambassadors are also Codex Ambassadors and have done an amazing job of showing the past and powerful work of fast inference and frontier models.
If you’d like to join the team or ambassador program, host an event, or attend one near you, reach out and tell us your city. I’d love to get you connected :)
It's an incredible program led by many of the best. @communidiyi @paw_lean @rhiannon_io -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Big respects big.
-
Cerebras
@cerebras
“If you’ve ever asked AI to do something and then drummed your fingers waiting for it to respond, you’ve run up against slow inference. To pick up the pace, Cerebras developed its own inference platform from the semiconductor wafer up.”
Cerebras is proud to be named in @FastCompany 's 2026 Next Big Things in Tech list. -
Cerebras
@cerebras
We get a lot of questions about CS-4’s components.
Take a closer look at the engineering behind the CS-4 Wafer-Scale Backpack. ⤵️This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
See you at @SFTechWeek!
Post not available here, view on X
Cerebras
@cerebras
Cerebras
@cerebras
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Thanks @sama . We are excited to be building extraordinary things and blazing speeds with @OpenAI
Sam Altman
@sama
There is some speculation about our partnership with Cerebras.
Cerebras is a close partner, and we have a deep engagement pushing on the frontiers of speed. -
Cerebras reposted
-
Cerebras reposted
Handshake
@joinHandshake
We're teaming up with @cerebras for Cafe Compute: Researcher Edition next Thursday in SF
Excited to gather the best of the SF research community in one room. One attendee walks away with a NeurIPS All Access Pass + a free roundtrip flight to Sydney.
Data + compute = AGI. Come talk about both.
RSVP here → luma.com/cafecomputeresearch -
Cerebras
@cerebras
Interact with the article here: www.cerebras.ai/blog/disaggregated-inference-from-the-gro…
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
A few more snaps from the night with the best
Hosted together with @OpenAI @cerebras -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
We found a very dumb bug. The original is incorrect.
Our AI assistant is actually 40x faster than Grok Bot, not 20x.
For a simple dinner reservation:
Grok Bot: 7 min 40 sec
Meta Muse: 4 min 36 sec
Instinct: 14 min +
Claude Cowork: 6 min 25 sec
Human (me) : 37 sec
@cerebras: 11 sec
The below is what we built, powered by models on Cerebras. Otherwise known as 'what @bot would feel like if it was fast' @elonmusk -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
on set with cerebras and @bot
#welovegrokbot -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Silicon Valley often talks about long-term partners.
There are few better examples than TSMC.
In 2017, we flew to Taipei to ask TSMC to take a bet on us.
For a product that didn't exist.
Cerebras was 30 people.
Pre-product. Pre-revenue.
We were asking the greatest manufacturer in the world to collaborate on something that hadn’t been done before.
And to work with a company smaller than the catering staff in their dining hall.
TSMC’s fabs are our generation's pyramids - $40 to $50 billion, each.
Their entire manufacturing process was built around producing chips the size of a postage stamp.
We were proposing a chip 55x larger than anything ever made.
It had been tried before.
And it had failed every time in the 70-year history of computing.
TSMC had a thousand reasons to say no.
They were already a behemoth.
The best in the world at making a completely different kind of chip.
Why take the risk?
Instead, they greenlit the project in the meeting.
And they've been an extraordinary partner ever since.
That decision sums up why TSMC continues to win:
An openness to new ideas.
And a willingness to collaborate, regardless of the size of the company. -
Cerebras
@cerebras
The agentic era runs on fast inference.
@AlphaSenseInc, a leading AI market intelligence platform, uses Cerebras to power its agentic research. The same model runs 8.5x faster, enabling 3x more evidence to be reviewed with no added latency.
Learn how AlphaSense does it by reading our joint blog in the reply 👇
Cerebras
@cerebras
Blog 👉 www.cerebras.ai/blog/how-alphasense-uses-fast-inference-t…
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Live from the OpenAI devday after party 💃
Hosted by @OpenAI x @cerebras -
Cerebras reposted
Sean Lie
@seanlie
I joined AMD right after graduating from MIT. Two stints there and a decade building @cerebras later, I still lose sleep over how much memory and compute to put on a chip.
I’ve spent my entire career in computer architecture, and I’ve never seen the problems change this quickly. Models keep getting larger. The demands on the hardware keep growing. Decisions about where to put memory and how to connect it have become central to what people can build with AI.
We chose SRAM for its bandwidth. Now we’re working on wafer-scale stacked DRAM to give larger models more capacity while preserving fast inference. That brings us back to some very physical problems: how to power it, cool it, and manufacture it reliably.
This is the work I love. In part two of our AMA, I answered your questions about those decisions and where we’re going next.
0:30 What changes between CS4, CS5, and CS6?
2:19 HBM already stacks memory. What’s different here?
3:34 We chose SRAM for speed. Why add DRAM?
4:52 Drawing the stack is easy. Making it work isn’t.
7:23 The memory-versus-compute decision that keeps me up at nightThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
When will AI personal assistants be fast enough to be useful?
Using Qwen 3.8 27B on Cerebras at ~1,500 tokens/sec, we made an AI personal assistant 19x faster than a suite of other AI personal assistants - Grok Bot, Meta Muse, and Claude Cowork - on the same dinner reservation task.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Read the full blog by @MilksandMatcha:
-
Cerebras
@cerebras
The world’s fastest inference is coming to @general_compute
Cerebras
@cerebras
Under the multiyear agreement, General Compute will deploy Cerebras systems so its customers can deliver ultrafast inference to developers building agentic applications.
Cerebras
@cerebras
Details: www.cerebras.ai/press-release/general-compute-selects-cer…
-
Cerebras reposted
Sean Lie
@seanlie
When we designed our wafer-scale systems, we focused on keeping compute close to memory so we could generate tokens quickly. Bringing that speed to more developers also takes work across the software and infrastructure around it.
That’s why I’m excited about our partnership with @gimletlabs. Their software maps different phases of inference to the hardware best suited to each, bringing Cerebras into Gimlet Cloud behind a single API.
Together, we plan to deploy Cerebras-powered inference capacity, with the first datacenter expected online later this year.
As agents take on longer tasks, the time spent waiting on each model call adds up. I’m looking forward to seeing what developers build when they can work through those steps faster.
Congrats to @zainasgar and the Gimlet team. We're just getting started.
Gimlet Labs
@gimletlabs
We’re bringing @cerebras wafer-scale compute to Gimlet Cloud.
100 MW planned. First datacenter expected later this year, with speeds up to 3,000 tokens/sec.
Building the multisilicon inference cloud.
Blog: gimletlabs.ai/blog/cerebras-announcement -
Cerebras
@cerebras
6,000 fewer components means a lot fewer things to install, connect, and potentially get wrong.
Angela explains why @cerebras designed CS-4 around easier deployment. Once the data center infrastructure is ready, getting the compute up and running can take hours.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
I was told Grok Bot just shipped new improvements to their browser use harness
I re-ran the same dinner reservation experiment to see if there was an improvement
Old Grok Bot: 7 min 40 sec
New Grok Bot: 7 min 16 sec
(and for reference)
Human (me): 37 sec
Cerebras: 22 sec
Notes
1. Basically the same total time since grok bot measures the prompt input time to the minute so +/- 30 seconds
2. The browser use time did go down significantly, but the increase in reasoning and orchestration time canceled it out
3. Building fast agents are hard...luckily we happen to be experts @elonmusk @mdamore9 :) -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Excited to share that I'll be speaking at @aiDotEngineer NYC on Oct 12-14.
@covacut (@OpenAI) and I will be giving a joint talk about using AI for content creation, and some of the AI workflows behind our 700K+ followers and 200M+ views.
We'll see you in NYC! -
Cerebras
@cerebras
The world’s fastest inference is coming to Gimlet Cloud.
@gimletlabs 🟧 -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Stay tuned for the next AMA where Cerebras CTO @seanlie answers Twitter's hottest questions around
> Stack DRAM
> why does it differ from NVIDIA HBM,
> breaking down the technical challenges of hardware that delivers fast inference.
Next one, best one. Coming out early next weekThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Yesterday, I joined @sk7037, VP at OpenAI, and @dylan522p of SemiAnalysis on a panel about AI infrastructure.
Two predictions I've heard for 25 years came up.
The first is that when the price of compute drops, the market gets smaller.
This has never happened.
Every time the price came down, people found new applications, and the market grew.
Every single time. Bar none.
Take the chip industry.
In the last 10 years, everybody's chips have improved.
We produce more per unit power.
And we produce more per dollar.
The history of our industry is a massive reduction in the cost per unit compute.
The second is that when compute moves to the edge, the market for data centers gets smaller.
This has also never happened.
Putting compute in people's pockets gave us millions of new apps.
Most of them rely on data centers to do anything hard.
It is not a zero sum game. The entire market grows as compute is adopted at the edge.
Over the next decade, the demand for edge compute in fields like robotics will explode.
Every robot will drive more demand in the data center.
Both misconceptions assume there's a fixed amount of work for computers to do.
In practice, cheaper and more accessible compute creates work that didn't exist before.
AI will follow the same pattern.
Great to be a part of the summit. -
Cerebras reposted
Daniel
@imnotchalk
I just hosted @cerebras Cafe Compute Vancouver!
Thanks to everyone that showed up, I hope you learned more about the ultra fast inference we provide at Cerebras.
We had over 300 people signup! Don't worry if you couldn't make this one, we will host more in the future!
Special thanks to @communidiyi , @kodahhhhh , @JackyZhong0124 , @wuhuaguor and Kai for helping with the event! -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Answering Twitter and Discord's most asked questions about how and why we built our hardware.
I asked Angela Yueng, SVP of Product, why that tiny distance matters so much. In part two of our AMA, we got into the hardest parts of engineering CS4, how @cerebras is using AI agents to monitor its systems, and whether there’s still room to push the wafer faster.
0:27 Why half a millimeter matters for AI speed
2:11 AI agents monitoring the hardware that runs AI
3:06 The hardest part of building CS4
4:16 Have we hit the wafer’s power ceiling
5:26 How many countries does it take to build one CS4This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
CS4 uses the same wafer as CS3. So where does the extra speed come from?
You asked on Twitter and Discord. Join Angela Yeung, SVP of product and @MilksandMatcha, on the behind-the-scenes on the engineering behind CS4: connecting wafers, recirculating cooling water, and getting compute deployed at scale.
1:08 Where does the extra speed come from?
2:33 Connecting wafers for 10-trillion-parameter models
4:15 What breaks first when you scale?
6:07 Breaking down cooling
7:30 Easy CS4 deploymentThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
I compared every single AI personal assistant on the same task:
Grok Bot: 7 min 40 sec
Meta Muse: 4 min 36 sec
Instinct: 14 min +
Claude Cowork: 6 min 25 sec
Human (me) : 37 sec
Cerebras: 22 secThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
CS4 uses the same wafer as CS3. So where does the extra speed come from?
You asked on Twitter and Discord. Join Angela Yeung, SVP of product and @MilksandMatcha, on the behind-the-scenes on the engineering behind CS4: connecting wafers, recirculating cooling water, and getting compute deployed at scale.
1:08 Where does the extra speed come from?
2:33 Connecting wafers for 10-trillion-parameter models
4:15 What breaks first when you scale?
6:07 Breaking down cooling
7:30 Easy CS4 deploymentThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
“The metric that matters here for us is actually time to decision.”
@CrowdStrike VP of Engineering Keith Culley explains why faster inference is essential to AI security: more inspection, faster decisions, and less friction inside the same critical response window.
Cerebras
@cerebras
Learn more about the Cerebras × CrowdStrike partnership: www.cerebras.ai/customer-spotlights/crowdstrike
Cerebras
@cerebras
Watch Keith’s talk at Cerebras Supernova: youtu.be/r3vfF6rb-4I
-
Cerebras
@cerebras
If the cyber attack is fast, the defense must be faster. By removing inference as a bottleneck, Cerebras helps defenders act before attackers can advance. x.com/i/article/2102944198404304896
-
Cerebras reposted
Diyi Zhu
@communidiyi
2 @cerebras community-run Cafe Computes this week, cohosted with @OpenAI:
🇵🇹 Lisbon - luma.com/cclisbon
🇨🇦 Vancouver - luma.com/cafecomputevancouver
Big shoutout to @francisco_rib @imnotchalk and of course @paw_lean -
Cerebras reposted
Diyi Zhu
@communidiyi
i'm so proud of the work our @cerebras ambassadors are doing all over the world.
the bangladesh crowd looks lit! @mitul_shahriyar
Mitul Shahriyar
@mitul_shahriyar
Had a great time hosting the first @cerebras Cafe Compute event, with support from @OpenAI! 🙌
A big thank you to @communidiyi for the support! and Dmitry for the QNA
I also built an app where you can add your API keys from the OpenAI Developer Platform and Cerebras Cloud to compare response speeds and see how fast Cerebras responds 😁
Check out the repo and try it yourself:
github.com/Dev-Change-Makers-Community/Cerebras_Cafe_Compute
#cafecompute #cerebras #openai -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
The global community benefits when labs share strong open models. @seanlie also sees a strategic challenge in how much of that progress is coming from Chinese labs.
He argues that staying competitive in models and the hardware behind them will require a national effort that extends beyond any one company.
From @seanlie of @cerebras in conversation with @swyx on @latentspacepod. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
2 years later and Cafe Compute has gone fully global 🌍
Cafe Compute is our free late-night coffeeshop for engineers, founders, writers, anyone who wants to co-work or hang out late at night.
Come find your people :)
Lisbon · Sept 23
Vancouver · Sept 24
Toronto · Sept 28
Melbourne · Sept 30
Paris · Sept 30
Taipei · Oct 4
Dublin · Oct 6
Miami · Oct 6
Portland · Oct 6
Bangalore · Oct 7
Peshawar · Oct 7 (booked out)
Sydney · Oct 8
San Francisco · Oct 8
London · Oct 9
Seoul · Oct 10
Barcelona · Oct 13
New York · Oct 13
Brisbane · Oct 21
Stockholm · Oct 22
Austin · Oct 22
Boston · Oct 28
Sydney / NeuriPS · Dec 7
rsvp here: luma.com/cerebras
Follow @communidiyi and @cerebras to stay up to date ☕ -
Cerebras reposted
Damnang
@damnang2
Finally getting around to posting this photo!
Thanks to @MilksandMatcha, I had the chance to visit the Cerebras office today. The whole place had such an energetic and exciting atmosphere.
And seeing the wafer scale chip in person after only seeing it in photos was honestly so cool!
Thank you so much for the invitation!! -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
We're hosting our first cafe compute with the @claudeai team
We are almost at capacity with a few more spots next week....let us know what you're building below to get an invite 👇 -
Cerebras
@cerebras
Cyber attackers move fast, so defenders have to move faster 🚨
Analyzing an unfamiliar file is an everyday security workflow: analysts identify its behavior and indicators, then search for them across the environment before the threat spreads.
Powered by Cerebras, GPT-5.6 Sol Ultrafast completes the analysis in 58 seconds, versus 4 minutes and 43 seconds for Sol Standard on GPUs-- helping defenders contain threats before attackers can advance.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Cerebras
@cerebras
Cyberattacks are growing more sophisticated and moving faster—effective defense requires AI that can keep pace.
Hear from Cerebras Chief Information Security Officer Naor Penso about how the world’s fastest inference enables cybersecurity professionals to protect their systems, and how our strategic partnership with @CrowdStrike is bringing this unique capability to organizations worldwide.
Link to the full interview in the comments 👇This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Cyberattacks are growing more sophisticated and moving faster—effective defense requires AI that can keep pace.
Hear from Cerebras Chief Information Security Officer Naor Penso about how the world’s fastest inference enables cybersecurity professionals to protect their systems, and how our strategic partnership with @CrowdStrike is bringing this unique capability to organizations worldwide.
Link to the full interview in the comments 👇This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Full interview: www.youtube.com/watch?v=sD2kVXOfhLs
-
Cerebras
@cerebras
We built Money Agent, a personal finance assistant powered by @Alibaba_Qwen 3.8 27B on Cerebras.
Now you can turn a home-buying question into a real-time conversation, then into a financial goal, faster.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
“Measure three times and cut once.” - @andrewdfeldman
This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Buckle up.
@cerebras is bringing you the fastest AI in the world. -
Cerebras
@cerebras
A new chip needs a system that can power it, cool it, and support what comes next.
@seanlie walks through the modular Nexus platform behind @cerebras CS-4, and how designing it alongside the next wafer-scale chip creates room for further gains in inference speed.
From @seanlie’s conversation with @swyx on @latentspacepod.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
David Davidović
@thegeomaster
This is the future of design. I rebuilt the Rivermark agent to run on Qwen3.8-27B on @Cerebras at 1,500 tokens/sec.
In under 3 minutes, I pulled in an iconic Ibiza nightclub's brand from their website, used it to make posters for a real party, then built a full social campaign and tweaked it to perfection.
Rivermark is what I call a "short-horizon" agent. Underneath it's just HTML and CSS, so it can make almost anything. But you inject taste as you go instead of delegating and waiting.
Everyone's using the same models and churning out the same-looking designs. This is a way to use your human judgment to stand out and amplify yourself. No more garbage flyers.
I'm excited to share this with the world. DM me or follow @userivermark for an early access spot.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Codebase analysis in seconds!
Daniel
@imnotchalk
Qwen3.8 27B is now available on @cerebras Shared Tier at ~1500 tok/s. 🚀
It's so fast that the time I spent on writing the prompt was longer than the time it spent to summarize my codebase. -
Cerebras
@cerebras
The first @cerebras chip had to prove that wafer-scale computing could work. The question now is what that speed makes possible.
@seanlie reflects on that shift, and why combining frontier-model intelligence with fast inference opens up a different set of applications.
From @seanlie’s conversation with @swyx on @latentspacepod.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
I have tracked my macros (mostly protein) for years now. It is time consuming and extremely annoying. All the apps suck and it take forever.
So I gave 3 models the same food photo and asked for the macros:
Qwen 3.8 27B on @cerebras // 2.46s
GPT Astra by @OpenAI // 19.55s
Fable 5.1 by @AnthropicAI // 14.74s
All three landed around 1,200–1,300 calories. Qwen finished nearly 8x faster than Astra in this run.
I just want to log my lunch and eat it :) -
Cerebras
@cerebras
Cerebras makes Qwen 3.8 27B goes brrrrr 💨
Alok
@analogalok
Operating System powered by Qwen 3.8 27B at 1950 tokens/sec!
here is what 1,950 tokens/second @Alibaba_Qwen's 3.8 27b actually looks like on @cerebras:
i wrote a minimal python web server that turns cerebras inference into a live operating system.
zero apps on disk.
when you double click an icon:
1) python proxies a raw SSE stream from qwen 27b at 1,950 tok/s
2) calculator compiles & mounts in 11s
3) full canvas paint studio with brush engine compiles in 10s.
at 2,000 tokens/second, software is just an on demand hallucination that runs instantly.
the model weights ARE the operating system runtime.
what else would you build at 1,950 tokens/second? -
Cerebras
@cerebras
Radical innovation or "a long hard slog" as @andrewdfeldman likes to put it.
This media couldn't be displayed. See it on the original post.
Jack Altman
@jaltma
New episode of Uncapped with the founder of Cerebras @andrewdfeldman and my partner @ericvishria.
We talked about the company's winding road to success, the market around chips, the current state future of the AI supply chain, the role of investors and Eric's relationship with the company, and more.
This was one of my favorites, hope you enjoy.
Timestamps:
(0:00) Intro
(1:07) Why Andrew started Cerebras in 2016
(2:54) Eric on investing without experience in chips
(4:10) Attacking Goliath
(9:44) Near-death experiences and the valley of death
(10:44) 18 months of "still can't make it"
(12:16) Solving a 75-year-old compute problem
(13:26) What comes after wafer scale
(16:19) The chip supply chain explained
(22:30) Why the US punted a strategic industry
(25:51) How to be a good hardware board member
(27:50) Hardware vs. software investing
(29:05) The pivot from training to inference
(27:00) Specialization vs. flexibility
(35:22) Building effective teams for chips
(39:14) External relationships and TSMC
(42:20) The AI infrastructure buildout
(44:12) The data center supply chain
(53:14) Speed creates markets
(54:10) Disaggregation with AMD and AWS
(55:24) What actually makes Nvidia great
(57:30) Near-death experiences
(59:58) Andrew's childhood next to William ShockleyThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Jack Altman
@jaltma
New episode of Uncapped with the founder of Cerebras @andrewdfeldman and my partner @ericvishria.
We talked about the company's winding road to success, the market around chips, the current state future of the AI supply chain, the role of investors and Eric's relationship with the company, and more.
This was one of my favorites, hope you enjoy.
Timestamps:
(0:00) Intro
(1:07) Why Andrew started Cerebras in 2016
(2:54) Eric on investing without experience in chips
(4:10) Attacking Goliath
(9:44) Near-death experiences and the valley of death
(10:44) 18 months of "still can't make it"
(12:16) Solving a 75-year-old compute problem
(13:26) What comes after wafer scale
(16:19) The chip supply chain explained
(22:30) Why the US punted a strategic industry
(25:51) How to be a good hardware board member
(27:50) Hardware vs. software investing
(29:05) The pivot from training to inference
(27:00) Specialization vs. flexibility
(35:22) Building effective teams for chips
(39:14) External relationships and TSMC
(42:20) The AI infrastructure buildout
(44:12) The data center supply chain
(53:14) Speed creates markets
(54:10) Disaggregation with AMD and AWS
(55:24) What actually makes Nvidia great
(57:30) Near-death experiences
(59:58) Andrew's childhood next to William ShockleyThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Hot seat with @cerebras SVP of Product coming soon
Breaking down our future hardware roadmap, data center bring-up, and moreThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
During an outage, every second matters. That is one of the reasons OpenAI is using @cerebras internally.
@seanlie describes how fast inference is being used for incident response and critical research, where more reasoning within the available time can improve the response.
From @seanlie’s conversation with @swyx on @latentspacepod. -
Cerebras reposted
Kevin Taylor
@KevinTaylor00
I tested out Qwen3.8-27B on @cerebras by having it autonomously order Llama merch from Amazon and ship straight to our HQ.
It spent roughly $80 on my card in less than 30 seconds without any human interventionThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Connecting the dies and working around defects were fundamental challenges for wafer-scale computing. Making it work also came down to power, cooling, and reliability.
@seanlie explains how those lessons are shaping @cerebras’ approach to stacking DRAM.
From @seanlie’s conversation with @swyx on @latentspacepod.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Qwen3.8-27B is now live at Cerebras speed.
The dense, open-weight model from @Alibaba_Qwen scores 34 on the Artificial Analysis Intelligence Index—making it comparable to models such as GPT-5.6 Luna, DeepseekV4 Pro, and Claude Sonnet 4.6.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Get started: cloud.cerebras.ai
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Making a wafer-scale chip work means accounting for defects from the beginning.
@seanlie explains how @cerebras built redundant compute and wiring into the hardware, allowing it to route around defects and turn an imperfect wafer into a working system.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
A model’s architecture reflects the hardware it was designed to run on. Most of the models running on @cerebras were designed for NVIDIA GPUs.
@seanlie explains why adapting even parts of a model to the hardware could unlock further performance gains, and what closer co-design with OpenAI could enable.
From @seanlie’s conversation with @swyx on @latentspacepod. -
Cerebras
@cerebras
AI is already helping write the code that runs on @cerebras hardware.
@seanlie describes how the team uses models running on its own systems to generate code that helps bring more models onto those same systems.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Alycia Cary
@alyciazcary
At @cerebras Supernova, I spoke with researcher @m_elhoushi about his team’s new paper: "Don't Drop Dropout."
He gave one of the clearest explanations I’ve heard of what layer dropout is and how it benefits training and inference.
This is the kind of research Cerebras does every day, and we are always looking to collaborate with co-design talent!This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Mostafa Elhoushi
@m_elhoushi
My team published “Don’t Drop Dropout.” At @cerebras Supernova, I discussed it and our work on layer sparsity, efficient training/inference, adaptive computation, and co-design. Co-design researchers, let’s collaborate.
This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Mostafa Elhoushi
@m_elhoushi
New paper from @cerebras : 🎯 Don't Drop Dropout!
www.alphaxiv.org/abs/2609.05275
Dropout vanished from LLM pretraining. We show for one type of dropout - layer dropout - it shouldn't have.
With the right recipe it gives lower loss at the same training FLOPs, or up to 25% FLOP savings.
🧵(1/n) -
Cerebras
@cerebras
“Don’t Drop Dropout,” new research from Cerebras and @MBZUAI, shows layer dropout can save up to 25% of training FLOPs and deliver up to 1.5× faster inference.
Congratulations to @m_elhoushi, @DeyNolan, @BCZhang_, @ShaneBergsma, @ARHmahmoud, and the full team.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Read the paper: www.alphaxiv.org/abs/2609.05275
Cerebras
@cerebras
Watch the full interview with @alyciazcary: youtu.be/F67gavWiiHM
-
Cerebras reposted
Sean Lie
@seanlie
When we started @cerebras, we knew we would have to solve difficult problems in yield, power, and cooling. What became clear was that making wafer-scale work would require rethinking almost the entire system.
Today, we answered questions from the community about those engineering decisions, how we run larger models, and what it takes to program the hardware.
2:15 Why hasn't NVIDIA gone wafer-scale?
4:10 How we build a working chip out of an imperfect wafer
8:07 What happens when a model won't fit on one wafer?
11:34 Why we chose SRAM over HBM
14:26 How much of a barrier is NVIDIA's CUDA moat?This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Running GPT-5.6 Sol Ultrafast on Cerebras, @MatthewBerman saw his workflow flip: fewer parallel agents, same productivity, lower mental load.
When tokens stop being the bottleneck, the rest of the stack becomes the next layer to optimize. Faster inference opens that door.
Cerebras
@cerebras
Watch the full conversation with @milksandmatcha: youtu.be/BpjGdS_h6cc
-
Cerebras
@cerebras
Calling all CTOs: Cafe Compute's coming to SF @Techweek_, cohosted with @datadoghq
RSVP in link:
Cerebras
@cerebras
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
“My Xbox broke when I was eight.” @dylan522p opened it up to fix the Red Ring of Death, stayed on the repair forums, and was moderating them by 12.
By 2020, he had turned that lifelong obsession with chips into his job. I loved hearing where it all began.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
To understand why Cerebras built a very, very big chip, it really comes down to one number: the energy it takes to move a bit of data.
Off-chip: ~1–10 pJ/bit
On-chip: ~0.1 pJ/bit
Moving data on-chip can take up to ~100× less energy than moving it off-chip. At AI scale, where you’re constantly moving trillions of bits,
that difference becomes enormous.
Cerebras is not big for size's sake. By keeping compute and memory close together, you get minimal data movement. -
Cerebras reposted
SemiAnalysis
@SemiAnalysis_
Sat down with @milksandmatcha at @Cerebras Supernova to talk chips
Everyone is making different inference bets
Some want cheap tokens
Some want speed
NVIDIA is hard to beat on throughput, but there's huge room on speed
Cerebras is a yapper. These wafers talk really fast.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Time is expensive.
"I think any company that pays their people over a certain amount of money should just use Ultrafast mode."
@dylan522p makes the case that companies should default to Ultrafast mode for high-paid employees, especially as coding agents let non-engineers build software and automate work.
Cerebras
@cerebras
Watch the full conversation with @milksandmatcha: youtu.be/rpr_Zpbpppw
-
Cerebras
@cerebras
“If all AI is built on one platform, we'll only have a certain envelope of future outcomes. Whereas if the future of AI is built on a broad population of platforms by a broad population of users and organizations and nations, we're much more likely to experience the benefit of this technology rapidly and avoid the risks.”
Andy Hock and @DanAkarca of @CallosumAI on the vision behind the new Cerebras-Callosum partnership.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full conversation: youtu.be/ClIb0J0NIeY
-
Cerebras
@cerebras
Our partnership with @mbzuai goes back many years. Today, Cerebras is a launch partner for K2 Horizon, a new family of six open models from the @IFM_AI team.
All six models are released as open weights under Apache 2.0, giving developers the freedom to inspect, reproduce, adapt, and build on the work.
Congratulations! -
Cerebras reposted
Danyal
@DanAkarca
“We're in the early stages now of this Cambrian explosion. What are the boundary cases where we want certain tasks on certain models on certain silicon? We’re making that programmable. This is where all the frontier performance is going to come from.”
Proud to launch our new partnership between @CallosumAI and @cerebras. Thanks to Andy for a great conversation!This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
"You now have new surface area to expose the benefits of the silicon in new ways.
We had some really amazing results when doing this over a huge amount of different silicon. Cerebras was unbelievably good.
We could actually not only improve the speed by a significant amount in these long-context reasoning problems, we also found that we could also make them very cost-effective because we're being efficient with the tokens."
— @DanAkarca, co-founder of @CallosumAI, in conversation with our Andy Hock on the new Cerebras-Callosum partnership.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full conversation: youtu.be/ClIb0J0NIeY
-
Cerebras
@cerebras
“We coined this term called the semi-async valley of death.”
At Cerebras Supernova, @silasalberti unpacked why coding tasks that take 1 to 3 minutes break flow, and how Cerebras powers Cognition’s SWE-1.7 in Devin at up to 1,000 tokens per second to keep developers in the loop.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full interview with @milksandmatcha: youtu.be/KSu4TbzJGAs
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
It is interesting to see the industry move from 12Hi back toward 8Hi HBM just as DRAM stacking is accelerating.
Going vertical does not make the fundamental constraints of memory disappear. As stacks get taller, thermals, power, yield, packaging, and reliability become increasingly difficult architectural problems.
HBM stacks DRAM vertically beside compute. The next frontier (as seen at hot chips) is stacking DRAM directly on compute, turning the interface from the edge of a chip into its entire surface area. -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Today, we announced a new 165 MW data center in Mikkeli, Finland, in partnership with Compute Nordic Finland.
Construction of the first 50 MW is already under way.
Two things make this project special to me:
First, we designed the Mikkeli data center to give back. The facility is designed to capture the heat our computers generate so the community can use it, and the water that cools our systems gets recirculated instead of drawn from the town's supply.
Second, it creates long-term jobs. An estimated €1.0–1.7 billion will be invested into the region and it will create up to 250 permanent technical jobs in South Savo.
Thank you to Compute Nordic Finland, the City of Mikkeli, and our network of Finnish partners for helping bring this to life. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
a great bring your friends to work day @swyx @vibhuuuus @seanlie
we have labs/ hardware testing/ equipment/ manufacturing/ racks in our office in south bay
friends and connections always welcome to come by for a hardware tour -
Cerebras reposted
Sean Lie
@seanlie
Ten years ago, we started @cerebras around an approach many believed was impossible.
As a computer architect, it is hard for me to imagine a more exciting time. Model releases are accelerating, and hardware tapeout is compressing from multi-year roadmaps to annual launches.
Hot Chips is my favorite conference, and it’s where I launched Cerebras 7 years ago. This year’s conference was especially exciting, and so much innovation was shared. I am watching the industry recreate itself: SRAM is mainstream, DRAM is moving into the third dimension, networks are being fundamentally redesigned, and AI is helping design and program the chips themselves.
The industry has never moved faster and some of the hardest architectural questions are still wide open. -
Cerebras reposted
Diyi Zhu
@communidiyi
where in the world is cafe compute this week?
🇯🇵 Tokyo: luma.com/cctokyo
🇲🇾 Kuala Lumpur: luma.com/cerebrasmalaysia
🇮🇳 Hyderabad: luma.com/cchyderabad
big thanks to our @cerebras ambassadors for hosting @asahiXXXXXXXXX @hazlijohar @jayant99acharya -
Cerebras
@cerebras
At Cafe Compute Fal.Con, we’re giving one lucky winner the opportunity to experience Cerebras-like speed from behind the wheel of a supercar at SPEEDVEGAS.
The winner take a supercar onto a purpose-built Las Vegas racetrack with a professional instructor riding alongside.
Ferrari, Lamborghini, Porsche, McLaren, Aston Martin, Mercedes-AMG, Nissan GT-R, Lotus. Which car will you drive?
RSVP: luma.com/cerebrasfalcon
Come see us at Booth # 1039 at Fal.Con with @CrowdStrike
***
No purchase necessary. One winner will be selected at random at Cafe Compute on Sept 1. Must be in attendance at time of drawing to win. Must be 18+ and have a valid driver's license. Prize is subject to vehicle and reservation availability. Participation may require acceptance of SPEEDVEGAS’s terms and liability waiver. Cerebras is not responsible for personal injury, death, property damage, or other loss arising from participation in or use of the prize. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras
@cerebras
Congratulations @andrewdfeldman on being included in @TIME's list of TIME100 AI. 🟧🚀
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Last week, Cerebras CTO @seanlie announced CS-4, 30x faster than the GPU.
This week at #hotchips2026, Cerebras announced CS-5, another step function faster than anything we've seen before with up to 10,000 tokens/sec/user on models such as Gemma 4 31B and gpt-oss-120B.
Seana and I will be doing an AMA on Cerebras, CS4/5/6, Hot Chips announcements. Let us know what questions you have. -
Cerebras
@cerebras
The Cerebras Wafer-Scale architecture compounds across generations.
CS-4 is the industry’s fastest AI accelerator and the first system built on the new Cerebras Nexus rack-scale platform.
CS-5 is designed to set a new standard for token-generation speed with our next-generation wafer.
And with CS-6, we plan to push the frontier of 3D integration further, stacking DRAM at wafer scale to deliver the next step-change in AI performance and efficiency.
Cerebras
@cerebras
Read the deep dive from @hotchipsorg www.cerebras.ai/blog/ultrafast-frontier-inference-cerebra…
-
Cerebras
@cerebras
Congratulations to our partners at @OpenAI today. Taking a new chip to real lab results at great performance is a huge achievement, and improving speed across the board pushes our whole industry forward.
We look forward to having Jalapeno and the next-gen Cerebras solution together in production in 2027, driving OpenAI’s comprehensive fast and ultrafast inference product portfolio to continue evolving what's possible with fast AI.
Tibo
@thsottiaux
Excited about our Jalapeno results today. An incredible achievement from the team, taking a new chip from concept all the way to very impressive performance on real workloads in the lab.
Tomorrow’s fast will feel like today’s ultrafast. As I’ve mentioned before, we’re pushing to bring this to as many people as possible.
We’ve seen a TON of demand for /ultrafast, made possible by our deep partnership with Cerebras and their unique hardware, which will push the frontiers of tomorrow's ultrafast even further. I’m very much looking forward for the collaboration to continue pushing the absolute limits of how fast we can run our most capable models on Cerebras and bring this to the most demanding customers. -
Cerebras
@cerebras
Fast inference makes all things possible. Thanks for building this use case @thegeomaster
David Davidović
@thegeomaster
Meet the fastest AI design canvas in the world, running on Cerebras at 1000+ tokens/sec.
In this demo of Rivermark, I use my voice to create beautiful, on-brand social content and tweak it to perfection in real time, powered by Gemma 4 on Cerebras Inference.
This means you can go through dozens of ideas for your visuals and tune them to pixel perfection in the same time it takes other tools to respond to your first prompt.
We’re opening early access in the coming weeks, so if you’re a busy designer, founder, or marketer with a high bar for content - reply or DM for a spot.
Next up: Qwen3.8-27B is coming to @Cerebras on September 3, and we'll offer day 0 support for it. Excited to build!This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
The CS-4 is the fastest AI accelerator in the world, establishing a new roofline for Frontier AI.
CS-4 is built to accelerate every part of the AI ecosystem:
- Developers who want faster tokens for interactive reasoning and agentic applications.
- AI factories require infrastructure that is simpler to deploy and built for hyperscale.
- Hyperscalers and Neoclouds need ultra-fast, high-throughput inference to serve the most intelligent AI models in real-time. -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
.@cerebras CS-4 expands the frontier of AI compute.
Up to 2x faster than CS-3.
Up to 10x more token capacity.
More speed for every user.
More capacity for every operator.
CS-4 solutions deliver both, in the same power budget.
The fast just got faster. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
What happens when you give the quant trader’s bible to two frontier AI models?
The Green Book is what traders use to prepare for firms like SIG and HRT, where I interned. And in high-frequency quant trading, being right isn’t enough. You have to be first.
Inside Codex, I extracted all 183 questions and their official solutions. Then I gave GPT-5.6 Sol Ultrafast (via API) on @cerebras and Claude Opus 5 the exact same test, timed every answer, and blind-graded the results.
One finished nearly three times faster, and got more answers right.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Faster agent loops. New systems that were not practical before. Cerebras inference is coming to @CallosumAI APIs. 🟧
Callosum
@CallosumAI
We are proud to announce our first major partnership with @CerebrasSystems.
Their wafer-scale engines are delivering inference at speeds that are hard to comprehend. Composed within Callosum's platform, that speed becomes something entirely new: heterogeneous multi-agent systems operating in regimes of intelligence that were not possible before. -
Cerebras reposted
Pauline P. Narvas
@paw_lean
Excited to be collaborating on @Cerebras × @OpenAI community events in EMEA. Come join us!
🇩🇪19/8 BER luma.com/cafecomputeberlin
🇵🇹10/9 LIS luma.com/cclisbon
🇧🇪12/9 BXL luma.com/cafecomputebrussels
🇫🇷17/9 PAR luma.com/ccparis
🇸🇪24/9 STO luma.com/ccsweden
🇬🇧1/10 LON luma.com/cclondon
🇮🇪7/10 DUB luma.com/cafecomputedublin -
Cerebras
@cerebras
The Fastest AI Just Got Faster. Meet CS-4.
This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
•Up to 30× faster inference than GPUs
•Up to 10× more throughput per watt than CS-3
•50% fewer components with modular compute, power, and I/O assemblies
www.cerebras.ai/cs4 -
Cerebras
@cerebras
The Supernova Stage is set.
Join the live stream
youtube.com/live/JTNk__O4poU -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras
@cerebras
Congratulations to @Alibaba_Qwen team on the Qwen 3.8 27B launch!
We can't wait for our users to try it out! Contact us for dedicated deployments and it's going to be up soon in the Cerebras Shared Tier. 🟧⚡️
Qwen
@Alibaba_Qwen
We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Qwen/qwen38
- ModelScope:
www.modelscope.cn/collections/Qwen/Qwen38 -
Cerebras reposted
Rohan Varma
@TheRohanVarma
Had fun chatting with @MilksandMatcha about all things Codex and Cerebras! Check out the full conversation on Youtube :)
These days, I use Codex, Slack, and a browser. Every other tool I use is through Codex plugins or Codex computer use.
As more work gets platformed on top of Codex, Ultrafast is going to help everything get done faster!This media couldn't be displayed. See it on the original post. -
Cerebras reposted
AMD
@AMD
Real-time AI starts with scale and speed.
Hear @Cerebras Founder and CEO @AndrewDFeldman share how AMD and Cerebras are working together to help developers unlock faster AI experiences.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Ultrafast mode for GPT-5.6 Sol is now in limited preview, powered by Cerebras.
We gave @OpenAI's GPT-5.6 Sol the same prompt on Ultrafast and Standard: build a financial terminal-style dashboard for analysts.
Ultrafast: 1 min 50 seconds
Standard: 12 min 20 seconds
Same result, nearly 7x faster.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Sign up to be notified as capacity expands. www.cerebras.ai/blog/accelerating-gpt-5-6-sol-ultrafast-w…
-
Cerebras
@cerebras
Previewing Ultrafast mode for @OpenAI's GPT 5.6 Sol, powered by Cerebras.
GPT-5.6 Sol Ultrafast generates responses at up to 750 tokens per second. That's the full, GPT-5.6-Sol model -- up to 14× faster than the same model on Standard processing.
It speedran Humanity’s Last Exam in 11h 11m, nearly 7× faster than Claude Fable 5 with comparable accuracy.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
learn more: www.cerebras.ai/blog/accelerating-gpt-5-6-sol-ultrafast-w…
-
Cerebras
@cerebras
Cerebras today announced financial results for Q2 2026, with our fast inference cloud business nearly quadrupling year over year.
• GAAP cloud revenue grew 281%; core cloud revenue grew 287%
• 600 MW of data center capacity now under contract
• Manufacturing capacity scaling more than 10x in 2026
• Partnering with OpenAI to serve GPT-5.6 Sol
• Partnering with AMD on disaggregated inference
Cerebras
@cerebras
The Report: investors.cerebras.ai/news-releases/news-release-details/…
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Pretraining teaches a model to predict. Reinforcement learning teaches it to act.
@jeffreygwang of @OpenAI explains how the two paradigms turn next-token prediction into models that can reason, use tools and complete useful tasks.
Big Chip Club with @cerebras // @alyciazcaryThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
"You could imagine yourself actually being 10x more productive."
@DeyNolan from the Cerebras Core ML team speaks with @alyciazcary on why speed contributes to intelligence.
In agentic workloads like Claude Code, queries can run for hours. Faster inference means more test time compute in the same budget.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full conversation: youtu.be/oITV7YH8ljo
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Not every agent task needs a frontier model.
@Thom_Wolf (Co-founder of Hugging Face) on routing work to smaller open models for repeatable sub-tasks, evaluation, and cost control, matching compute to the value of the work.
Join us in the Token Billionaires Lounge by @cerebras and @aiDotEngineer.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
TIME
@TIME
Is the GPU reaching its limits for AI? At @RaiseSummit, @cerebras makes the case for a different approach to AI chips.
This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
“We think not only in terms of training workloads, but also inference workloads.”
@jeffreygwang of @OpenAI explains why reinforcement learning has become an inference workload, and why training and inference must be co-designed.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full Big Chip Club interview: youtu.be/iM96VKpgAms
In conversation with @MilksandMatcha for Big Chip Club, produced by @alyciazcary. -
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Agents are only as good as the context they can access.
@jerryjliu0 on production document workflows: structure the data, retrieve broadly, then zoom in only where deeper analysis is needed.
Join us in the Token Billionaires Lounge, presented by
@cerebras and @aiDotEngineerThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
“Getting the maximum amount that you can out of a given chip is a super high priority for us.”
@jeffreygwang of @OpenAI explains why training performance depends on moving parameters efficiently and reducing communication overhead, not just arithmetic.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full Big Chip Club interview: youtu.be/iM96VKpgAms
In conversation with @MilksandMatcha for Big Chip Club, produced by @alyciazcary. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Open models are being asked to do more in smaller footprints.
@thorwebdev on the tradeoffs behind open, on-device AI, and how model size, deployment location, and product goals shape what developers can build.
Join us in the Token Billionaires Lounge by @cerebras and @aiDotEngineer.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
AI should reduce workflow friction, not add another chatbot.
@sarahmsachs (Head of AI @ Notion) on moving from isolated assistance to durable agent workflows built around a shared system of record.
From the Token Billionaires Lounge, presented by @cerebras and @aiDotEngineer.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
“The codebase is part of the prompt.”
@dexhorthy on why coding loops amplify existing patterns, and why better verifiers, human review, and deliberate codebase gardening matter more as generation gets faster.
Join us in the Token Billionaires Lounge, presented by @cerebras and @aiDotEngineer.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
"The dream is a totally different type of hardware unlocks a new type of model."
@sarahookr on why the rise of agentic workflows is moving the focus back to the system, and why that opens the door for chip architectures beyond the GPU.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full interview: youtu.be/yOqdhbSmkpw
In conversation with @MilksandMatcha for Big Chip Club, produced by @alyciazcary. -
Cerebras
@cerebras
“Whatever hardware allows that to happen is the hardware that we want.”
@jeffreygwang from @OpenAI on a future where agents consume far more tokens.
Cerebras is building the infrastructure to deliver those tokens at speed.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full Big Chip Club interview: youtu.be/iM96VKpgAms
In conversation with @MilksandMatcha for Big Chip Club, produced by @alyciazcary. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
From training his first neural net in high school to working at OpenAI.
@jeffreygwang followed a five-year trail through Andrew Ng’s course, early GAN papers + OpenAI research.
By the time ChatGPT arrived, “it all pointed toward OpenAI.”
Presented with @cerebras // @alyciazcary -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
The hard part of agent loops is not starting them!
It’s knowing when to move up a layer, and when to come back down. @swyx explains the operator skill behind useful loops: automate repeatable work, watch for failure, drop into the problem when reliability breaks, then climb back up once the system is sound.
That flexibility (not token volume for its own sake) is the key to productive loops.
Join us in the Token Billionaires Lounge, presented by
@cerebras and @aiDotEngineerThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Read more here: www.cerebras.ai/blog/getting-the-most-out-of-gpt-5-6-sol-….
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
the new age of 'personalized shopping'
I made a clone of aritzia where I'm the model on every piece of clothing
Buillt with gpt-5.6-sol standard...but just you wait for gpt-5.6-sol ultrafast (750 tok/s) running on @cerebras
coming soon 👀This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Today, @AMD and Cerebras introduced a powerful disaggregated inference solution, pairing the right engine to each phase of the inference pipeline.
This is what agentic AI has been waiting for: the fastest production inference at massive scale.
Cerebras
@cerebras
The joint solution delivers:
•The fastest inference tokens in production
•At 5x greater capacity
•On frontier-scale 1T+ parameter models
Cerebras
@cerebras
@andrewdfeldman joined @LisaSu on stage at Advancing AI 2026 to announce the partnership.
Cerebras plans to deploy @AMD Helios with the joint solution initially launching through Cerebras Inference Cloud in the second half of 2026.
www.cerebras.ai/press-release/amd-and-cerebras-announce-i… -
Cerebras reposted
Thor 雷神 ⚡️
@thorwebdev
Tons of folks braved the hurricane to make it to the Gemma 4 Cafe Compute in NYC hosted by @cerebras and @datadoghq 🗽☕🌪️
Thanks everyone for making the trip to experience Gemma on Cerebras 🚀
Cerebras
@cerebras
Gemma 4 31B is now available in Public Preview on Cerebras. Our first multimodal model runs at over 1,800 tokens/s for ultra-fast image and text workflows.
Give it a try: chat.cerebras.aiThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Winners have been dm'ed! Happy Learning 🤓
Cerebras
@cerebras
We just launched a completely free 1.5 hour course teaching the basics of inference, multi-agent workflows, and hardware.
The first 20 U.S./D.C. participants age 18+ to complete our free Deep Learning course by July 20 will receive a free 1 month Codex Pro plan.
No purchase necessary. OpenAI terms apply. While supplies last. Reply in comment with your completion certificate to qualify. -
Cerebras
@cerebras
Cerebras and @CrowdStrike are partnering to power Falcon AIDR on the world’s fastest inference.
AI attacks move in seconds, and cybersecurity can’t wait in a queue. Together, CrowdStrike and Cerebras are enabling security AI to detect, reason, and respond at machine speed.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Google Gemma
@googlegemma
Extremely fast multimodal inference!
Damage Scout uses Gemma 4 on @cerebras running at an impressive 2,300+ toks/s! It analyzes rental car walkaround videos and generates annotated damage reports with box coordinates in <6 seconds. -
Cerebras
@cerebras
Korea is building the future of AI—fast.
During ICML, we joined our partners at Upstage in Seoul to talk about what ultra-fast inference unlocks. Solar 31B runs at up to 2,000 tokens/sec on the Cerebras Wafer-Scale Engine.
Thanks to everyone who joined us!This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Google Gemma
@googlegemma
Voice AI without the wait! ⏱️
Thanks to Hugging Face and Cerebras, developers can now use the Gemma 4 31B model as the brain for voice AI at ultra-fast inference speeds. Add it to a fully open-source, cascaded speech-to-speech stack that can be used to power existing voice apps! 🗣️This media couldn't be displayed. See it on the original post. -
Cerebras reposted
-
Cerebras
@cerebras
We just launched a completely free 1.5 hour course teaching the basics of inference, multi-agent workflows, and hardware.
The first 20 U.S./D.C. participants age 18+ to complete our free Deep Learning course by July 20 will receive a free 1 month Codex Pro plan.
No purchase necessary. OpenAI terms apply. While supplies last. Reply in comment with your completion certificate to qualify. -
Cerebras reposted
DeepLearning.AI
@DeepLearningAI
Fast inference makes a new class of real-time LLM applications possible.
In our new short course, Fast LLM Inference with Cerebras, built in partnership with @Cerebras and taught by @zhennydez, @duerr_seb, and @MilksandMatcha, you'll build them on the Wafer-Scale Engine, where a model's weights sit on-chip and tokens come out several times faster than a typical GPU setup.
You'll build a webpage that personalizes itself as users interact with it, assemble a multi-tool workflow that analyzes market signals in one response, and adopt habits for cleaner agentic coding with Codex.
Enroll for free: learn.deeplearning.ai/courses/fast-llm-inference-with-cer…This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Sometimes the best DX is deleting the README.
@andrewqu (@vercel) built npx skills add so one skill could install across Claude Code, Codex, OpenCode, and more.
That tiny CLI became the flywheel for Vercel’s Skills Marketplace.
Join us in the Token Billionaires Lounge, presented by @cerebras and @aiDotEngineerThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
NYC builders: next Tuesday we’re turning @datadoghq into Cafe Compute with @GoogleDeepMind ☕️
Come try Gemma 4 31B at @cerebras speed, get increased model access, and meet the teams behind it.
Comment what you're building, and top ideas will get a special gift from Cerebras 🤭This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
5,000+ RSVPs. A line out the door. The wafer everyone wanted a picture with.
At Cafe Compute with @OpenAI during @icmlconf, @gabrielchua shared what 750 tokens/sec on Cerebras means for developers.
NYC is next, co-hosted with @GoogleDeepMind and @datadoghq. RSVP in the comments.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Join us for Cafe Compute: Gemma in NYC with @GoogleDeepMind and @datadoghq: luma.com/cafecomputenyc
-
Cerebras
@cerebras
Speed is a first-class product primitive.
As @OfficialLoganK from @GoogleDeepMind puts it: if every model ran at 2,000 tokens/sec, you wouldn’t make the same product faster. You’d build different products.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full interview: youtu.be/LRpw1PAQxbc
In conversation with @MilksandMatcha for Cerebras's Big Chip Club, produced by @alyciazcary. -
Cerebras
@cerebras
Dominic Kundel (from @OpenAI) gives the inside scoop on where GPT-5.6-Sol gets magical: computer use.
Background browser tabs, app control, multi-agent fanout, and Codex verifying its own work all change when latency drops.
Join us in the Token Billionaires Lounge, presented by @cerebras and @aiDotEngineer. In conversation with @dkundel // @MilksandMatchaThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Molly O’Shea
@MollySOShea
NEW: Cerebras $CBRS CEO Andrew Feldman (@andrewdfeldman)
"When the chip on your shoulder is the largest chip the world has ever seen."
"The demand for AI has outpaced everybody's expectation & everybody's forecast. & so everybody's chasing. They're chasing chips, memory, or data centers."
We get into the chip 58x larger than any other, $20B OpenAI deal signed in 4.5 weeks, & what's actually going on with the 'big AI deals'
Recorded 2 months after Cerebras' $5.5B IPO at a $56B valuation, where a first-day pop briefly hit ~$95B before settling toward ~$60B.
We cover:
› A "Cambrian explosion" of new chip architectures
› $20B+ OpenAI deal: 750MW of inference compute over 3 years
› Why inference, not training, is where the value is now
› "We are behind" on the data center build-out
› Free tokens & circular deals: "These are drug pushers"
› Creating 1,000 millionaires
› Nvidia's balance sheet & market strength
› Sovereign AI & owning the stack
› Co-design & data centers in space
› A real 25-year path to ending cancer
@cerebras builds AI infrastructure for training & inference. It went public in May 2026, & its products include inference, Wafer Scale Engine, AI supercomputers, AI model services, cloud, systems, & processors.
Filmed at the Raise Summit in Paris.
Thank you to Brex, MongoDB & AssemblyAI for helping make this trip & content series happen.
𝐓𝐈𝐌𝐄𝐒𝐓𝐀𝐌𝐏𝐒
(00:00) Andrew Feldman, Co-Founder & CEO at Cerebras Systems
(00:49) Why hardware suddenly became the coolest industry in tech
(01:51) What changed at Raise AI Summit
(03:01) Inside the $20 billion Cerebras - OpenAI deal
(05:50) What actually changes two months after an IPO
(06:32) Turning 1,000 employees into millionaires
(07:52) Staying sane during an AI gold rush
(10:44) Life after the IPO plateau
(11:45) The truth about the global data center shortage
(12:56) Why data centers are borrowing jet engines for power
(14:44) Are data centers really headed to space?
(15:37) The shift to designing chips & software together
(17:39) The biggest misconception about co-designing chips & software
(18:31) Inside SpaceX's multi-billion dollar AI deals
(20:06) NVIDIA's playbook for locking out competitors
(20:54) The hidden cost behind free tokens
(22:52) Andrew's response to Karp's sovereign AI thesis
(24:18) AI's biggest win might be curing cancer
(26:50) Peptides & biohacking
(28:00) How AI could finally fix the broken education problem
(29:46) The mentors who shaped Andrew Feldman's careerThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Google Gemma
@googlegemma
Gemma 4 is live on @cerebras, the fastest multimodal inference ever!
Running on Gemma 4 31B open-weight model at a blistering 1,500+ tokens/sec. That's a 15x speedup, unlocking real-time visual and agentic loops without the GPU lag.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
The fastest way to get the same AI UI every time is asking for “a beautiful UI.”
What works better: interview yourself, decide design before code, use ugly data, set scale/tone, then art direct the loop.
Fast generation does not replace taste. It makes taste matter more.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Should people building AI products use the competition?
@OfficialLoganK's answer: obviously.
Using other teams’ tools is how you understand what great feels like, find your own gaps, and keep up with the frontier. The internet discourse is just a bonus 😅This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Multimodal reasoning has a latency problem. More video frames leads to more waiting.
We built Damage Scout with Gemma 4 on Cerebras, running at over 2,300 toks/s, to show what fast multimodal inference unlocks.
Damage Scout samples frames from a rental car walkaround, sends them to Gemma 4, gets back structured findings and box coordinates, then renders an annotated damage report in under 6 seconds.
Same task. Same frames. A complete different experience powered by Cerebras ⚡️ -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
I had to ask @OfficialLoganK whether he actually bought the Mac mini 😅
He did, and his take is a useful reminder: technical possibility isn’t the same as a great product. The next big opportunity in local AI may be making it click for normal people.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
We're excited to collaborate with @upstageai, one of Korea's leading AI companies. Upstage's Solar 31B is now running on Cerebras at up to 2,000 tokens/sec.
Watch Solar 31B complete a deep research query across 246 sources...how much faster do you think it is?This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
📅 Save the date for Supernova 2026...more demos, more announcements, more builders, and more of what’s next in fast AI.
August 18, 2026
📍 The Midway | San Francisco
Doors open at 2:00 PM
Programming: 3:00–7:00 PM
Supernova After Party: 7:00–10:00 PM
We expect this to fill up fast — and we know fast.
Save your spot: luma.com/cerebrassupernova26 -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
5 part loops prompting structure to avoid MASSIVE TOKEN BURN
This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
The fastest AI in the world. Designed and manufactured in the U.S.
Flex
@Flexintl
We're expanding our partnership with @Cerebras to scale production of the CS-3, one of the world's most advanced AI accelerator systems, in the heart of Silicon Valley.
Together, we're helping power the next wave of AI.
🔗investors.flex.com/news/news-details/2026/Flex-and-Cerebr…
#aiinfrastructure $FLEXThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Cognition
@cognition
SWE-1.7 is free for all paid users for the next month.
We're also launching SWE-1.7 Lightning, served on
@cerebras at 1000 tokens per second! -
Cerebras reposted
Cognition
@cognition
Introducing SWE-1.7, the most capable model we’ve trained yet.
It scores within a few points of the strongest frontier models at a fraction of the cost, and is now available at 1000 tok/s.
RL is not hitting its limit: after refining our recipe, we keep seeing gains as we scale -
Cerebras
@cerebras
🌍🟧
-
Cerebras
@cerebras
🔨
Peter Steinberger
@steipete
5.6 on Cerebras is insane. 10x speed.
-
Cerebras
@cerebras
Read more: www.cerebras.ai/blog/first-look-gemma-4-on-cerebras-3-fas…
-
Cerebras reposted
SuperAI
@superai_conf
The more AI reasons, the more compute each answer demands and the slower it runs.
Past a point, latency caps how much reasoning you can actually use.
That's why Andy Hock of @cerebras calls speed a form of intelligence.
Catch the full session: www.youtube.com/watch?v=i5_UgecakfI -
Cerebras
@cerebras
"The hardware lottery got worse."
Six years after @sarahookr's landmark essay, she's even more convinced that our current chips are constraining which AI ideas succeed — and which never get a chance.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full interview: youtu.be/yOqdhbSmkpw
In conversation with @MilksandMatcha for Big Chip Club, produced by @alyciazcary -
Cerebras reposted
Rabi Shanker Guha
@rabi_guha
Imagine you never needed an app again.
Every screen on your phone, generated live the moment you ask.
No app store. No downloads. No predefined screens.
You ask for dinner, and the screen to order it gets written - right then, just for you.
We're calling it AppLess. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
on set filming with the co-founder of hugging face
geopolitics, open models, why hasn't my reachy robot arrived yet
the one and only @Thom_Wolf -
Cerebras
@cerebras
We loved hosting Cafe Compute #icml with @OpenAI. we gifted all the brightest ML researchers in the fully packed room Codex Pro Plans
Thanks @communidiyi and @gabrielchua for the welcome remarks
Missed us? Come say hi to our team at Cafe Gabedo tomorrow and Thursday. Wafer will be there too -
Cerebras reposted
Alycia Cary
@alyciazcary
.@cerebras is in Korea! We’re hosting at cafe gabedo all week for @icmlconf
come by to chat with our team & enjoy coffee on us ☕️
July 7-9, 10am-4pm
@communidiyi , @juliechoi , @learnwdaniel , @DeyNolan -
Cerebras reposted
Diyi Zhu
@communidiyi
in addition to the cafe compute party we're hosting at ICML (4600+ RSVPs and counting 🤯), we bought out cafe gabdeo inside COEX for 3 days where @cerebras and @OpenAI team members are meeting with #icml attendees
let us buy you a coffee. we're here tuesday wednesday and thursday -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Loops are the #1 way to AI generate code at scale.
Spiralling is the symptom of a broken loop. With no definite end state, the loop has no way to know it's finished, so it keeps "improving" in circles while the token meter runs.
Verification is a strong solution, where you want to keep the loop on track so that you are not wasting tokens and are still completing your goal efficiently.
> Be annoyingly specific about what counts as done
> Explicitly name the shortcuts you're forbidding before the model goes looking for them
Read more about building verifiable loops: www.cerebras.ai/blog/never-loop-without-verifiersThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Token billionaires lounge
must apply and submit token spending reciepts
@_lopopolo @swyx @communidiyi @jxnlco -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Generative UI, built for you on demand, principally requires fast inference.
Logan Kilpatrick @OfficialLoganK on how AI could reshape software: agents handle transactional tasks, while new interfaces unlock richer experiences.
Speed changes the interface.
Presented with @cerebras // @alyciazcaryThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
only good things cooking with the one and only Head of AI @ Notion
@sarahmsachs @NotionHQ -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Don’t stop shipping @zhennydez @AndrewYNg
-
Cerebras reposted
Thomas Wolf
@Thom_Wolf
Most people should probably update their priors on the state of open-source speech-to-speech.
It's honestly kind of mind-blowing.
We teamed up with @cerebras to build a fully open-source realtime voice demo (models + code) to show what's possible today.
Demo : huggingface.co/spaces/smolagents/hf-realtime-voice
Blog: huggingface.co/blog/cerebras-gemma4-voice-ai
Go test it, fork it, tweak it, and impress your friends.
video is raw, no cut, no speed-up, first take -
Cerebras reposted
David Davidović
@thegeomaster
The new Gemma 4 31B on Cerebras is insane.
We connected the @mowgli_ai design agent to this super fast model to see how it performs, and we're blown away.
This feels like a completely different tool now. Working with the agent is a truly collaborative experience - there's no reason to switch tabs while waiting, or to combine 5 things into one prompt. You just say what you want, and it's there instantly.
I'm convinced more than ever that fast inference is the future. @cerebrasThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Andi Marafioti
@andimarafioti
Talk to Gemma 4 31B with our voice app!
It sees and searches the web faster than you blink. Thanks to @cerebras’ ultra fast inference, the LLM is almost instantaneous.
The whole stack is fully open-source, and is a drop-in replacement for OpenAI's realtime API.
Demo:This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
"If you knew you could get that many tokens, you would build different products."
Logan Kilpatrick (@OfficialLoganK ,@GoogleDeepMind) on why fast inference doesn't just make AI faster. It changes what is possible to build.
@googlegemma's Gemma 4 is now on Cerebras, running at over 1800 TPS.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full interview: youtu.be/LRpw1PAQxbc
In conversation with @MilksandMatcha for Cerebras's Big Chip Club, produced by @alyciazcary. -
Cerebras
@cerebras
We gave two agents the same task: “Find images matching this description.”
Both use Gemma 4 31B. One runs on Cerebras.
The other runs on GPUs.
You can see the difference.
Speed changes the product experience. What would you build if you didn't have to wait?This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Alok
@analogalok
I just ran Gemma 4 31B on @CerebrasSystems at 1,800+ tokens/sec and it's multimodal.
For context: that's 35x faster than a typical GPU endpoint, and the first token (reasoning included) lands in 1.5 seconds. This isn't a benchmark slide, I recorded the inference live.
Prompt I used:
"Create a simulation of an iPhone. Include at least one working dummy note taking app, a functional notification pulldown, high quality graphics, single HTML file, any libs via CDN."
- Generation time: 3 seconds.
- Notes app worked.
- Notification panel worked.
- Rendered first try.
This is what wafer-scale inference unlocks, not just "faster," but a different category of product. When generation is this fast, you stop waiting and start iterating in real time.
Why this matters:
Gemma 4 31B is Google DeepMind's flagship open weight model, Apache 2.0 licensed, dense (not MoE), and built for efficiency over raw parameter count. It scores close to Claude Haiku 4.5 on the Artificial Analysis Intelligence Index (30 vs 29) but runs ~18x faster on Cerebras.
It's also the first multimodal model on Cerebras's platform, meaning you can now feed it screenshots, documents, charts, and UI states at wafer scale speed.
# Applications I'm most excited about:
- Screenshot → Insight: Drop in a dashboard or document screenshot, get structured findings back instantly. no waiting, no batching.
- Live UI generation: Full interactive interfaces (like my iPhone sim) generated and rendered in under 2 seconds.
- Screenshot -> Patch: Feed it a broken UI + console error, get a minimal code fix and verification steps back.
- Computer use & agentic loops: See -> reason -> act - verify, fast enough to keep a human in the loop instead of waiting on the model.
- Long context summarization: Full research reports condensed into decision ready summaries you can read and requery in one sitting.
The bigger unlock isn't the speed number itself, it's that agentic and multimodal loops (see -> reason -> output -> tool call -> verify -> retry) finally run in real time instead of feeling sluggish.
As Logan Kilpatrick (@OfficialLoganK) put it: "If every model was doing 2,000 tokens per second, you wouldn't build the same product and just have it be faster, you'd build different products."
Gemma 4 31B is live now on Cerebras Inference Cloud in public preview. If you're building multimodal, agentic, or real time apps, this is worth testing today.
What would you build with such insane inference throughput?
Cerebras
@cerebras
Gemma 4 31B is now available in Public Preview on Cerebras. Our first multimodal model runs at over 1,800 tokens/s for ultra-fast image and text workflows.
Give it a try: chat.cerebras.aiThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Livid
@Livid
this is what Cerebras 1800 t/s gemma4-31b be like
-
Cerebras
@cerebras
All attendees will receive free Codex Pro Plans 👀
Sarah Chieng
@MilksandMatcha
I host a ton of events.
This video was so fun to make, capturing how my team and I leverage AI when curating an incredibly high volume of intimate, tasteful, and high-quality events using some of our favorite tools like @OpenAIDevs Codex, Eve by @vercel and more.
But we are also excited to learn. Let me know if you have any suggestions or favorite tools and workflows :)
And if you're heading to ICML, definitely say hi to the @Cerebras team.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Mimosas and massages and wafer speed inference for the token billionaires at @aiDotEngineer.
Meet you at the lounge? -
Cerebras
@cerebras
Gemma 4 31B is now available in Public Preview on Cerebras. Our first multimodal model runs at over 1,800 tokens/s for ultra-fast image and text workflows.
Give it a try: chat.cerebras.aiThis media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Learn more: www.cerebras.ai/blog/gemma-4-on-cerebras-the-fastest-infe…
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
@cerebras is now running @GoogleDeepMind's Gemma 4 - the leading open-weight multimodal model - at 1,851 tokens per second in public preview.
This is 35x faster than a typical GPU endpoint.
Cerebras speed also translates into world class latency - Gemma 4 on Cerebras returns its first answer token inclusive of reasoning in 1.5 seconds, making Cerebras the only provider that lets Gemma 4 be used in real-time settings.
This is the power of wafer scale. -
Cerebras reposted
Ray Fernando
@RayFernando1337
Gemma 4 31B MULTIMODAL!!!! at ROCKET speeds. WHAT DA FAHH!!! I can't contain myself rn. Speed is the first step to super intelligence.
-
Cerebras reposted
OpenAI
@OpenAI
Introducing a limited preview of GPT-5.6 Sol, our next generation frontier model, as well as GPT-5.6 Terra, a balanced model for efficient, everyday work, and GPT-5.6 Luna, a fast and affordable model for high-volume work.
openai.com/index/previewing-gpt-5-6-sol/ -
Cerebras reposted
Google Gemma
@googlegemma
Gemma 4 is the first multimodal model on Cerebras! ️
What can you build with Gemma 4 31B running at 1500 tokens per second?
Join the Cerebras x Gemma 4 24-hour virtual hackathon this Sunday to compete for $5,000 in prizes.
Participants get early access to Gemma 4 on Cerebras. -
Cerebras
@cerebras
Introducing the Cerebras Ambassador Program 🌏
We're looking for AI community builders to build your local ecosystem around the world's fastest inference.
In the last few months, our community has hosted Cafe Compute Meetups in Berlin, Mexico City, Mumbai, SF, Seattle, and NYC. We want your city to be next!
Application link in comments.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Apply here: cerebras.ai/ambassadors
We read every application -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras
@cerebras
Cerebras today reported financial results for the first quarter of fiscal year 2026, marking the company’s first quarterly reporting period as a public company.
Read the report: investors.cerebras.ai/news-releases/news-release-details/… -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Behind the scenes from the very first Cafe Compute.
Cafe Compute, SF's first and only late-night (free) coffeeshop for developers, engineers, researchers, anyone to co-work late into the night.
Last weekend at the Exa series C party, someone came up to me and told me that she met her long term boyfriend at a Cafe Compute.
Our next one is coming up next week with the @cerebras and @GeminiApp team.
Jeremy Bernier
@jeremybernier
At 3pm today I was in Menlo Park and debating heading to SF to work out of a cafe. Then I remembered that there's literally no great cafes to work out of in SF that are open past 5pm. Maybe some meh ones open until 6pm, but def nothing worth the drive. Ironic given that SF is supposed to be the place for building startups.
If you like working out of cafes, SF is surprisingly bad for it. Most cafes are cute little spots that close 3-5pm and barely have seating. I haven't found a single great cafe that combines modern design, ample seating, and remains open past 5pm. Actually I have yet to find a single cafe that even just checks those first two boxes.
The #1 city in the world for working out of cafes is Seoul, and its surrounding suburbs. You could be in a random suburb of Seoul, and within 15 minutes walking distance there will be a quality work cafe with tasteful modern design, ample seating, thriving co-working space vibes, and open 24/7. There are even 24/7 cafes with zero employees - something that could never exist in the U.S.
I was in Tokyo last week and saw the most beautiful and aesthetic co-working space I've ever seen where you can rent by the hour or day, attached to one of the nicest bookstores I've ever seen, two more hip and stylish cafes, all in a beautiful building and beautiful area. A 15 minute walk away was the nicest Starbucks Reserve I've ever seen, with 4 floors. These kind of places don't exist in the U.S, and definitely don't exist in SF.
Ironically, Tokyo and Seoul are probably better places to build a startup if you're just working from your laptop, don't have an office and prefer working out of cafes to holing up in your apartment all day in your pajamas, don't need to beg rich people for funding, and don't care about networking.
Anyways I ended up driving 10 mins to Mountain View to work out of the only cafe I know here with ample seating, modern design, and open till 6pm. Of course it has nothing on what I saw in Asia though (attached photos are from Tokyo) -
Cerebras reposted
Jeremy
@jeremysoojk
Proud to represent @cerebras in Singapore
We'll be partnering with communities, builders, and spaces to give the world's fastest inference the spotlight it deserves.
@curve_labs also uses Cerebras to provide builders with personality tooling that powers human-like agents 🤝 -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
what if you could instantly clone any object?
Gemma 4 is now on @Cerebras Inference, running up to 10x faster than GPUs (1,500 tokens/sec). Multimodal generations you can iterate on in real time :) -
Cerebras
@cerebras
Right now, when you send a query to an LLM, it gets decrypted on the server. The LLM sees your data in plain text.
Prof. Ajay Joshi (BU, @CipherSonicAI ) on fully homomorphic encryption, which may be key for the future of AI privacy: how we can compute on data without ever decrypting it.
The catch: it's a brutally memory-bound workload. Exactly the bottleneck wafer-scale was built to solve.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full interview: youtu.be/o5zFrYbASow
Cerebras
@cerebras
In conversation with @MilksandMatcha for Big Chip Club. Produced by @alyciazcary.
-
Cerebras
@cerebras
Early access to the world's fastest multimodal model is here. Get your hands on the Gemma 4 model on Cerebras.
24-hour hackathon with $5,000 prize and top project featured by Google DeepMind and Cerebras.
RSVP link in comments
Cerebras
@cerebras
RSVP here: luma.com/cerebras-piwl
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Fast tokens are the most valuable tokens.
Because inference speed is productivity.
And @cerebras makes the fastest tokens in the world.
@GoogleDeepMind's Gemma 4 runs at 1,500+ tokens per second on Cerebras — more than an order of magnitude faster than on GPUs and 15x faster than Claude Haiku 4.5.
Private preview today. GA later this month.
Build blazing fast multimodal apps.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
"Most of the real world is actually the long tail. And how do you learn the long tail as cheaply as possible is one of the most important questions right now."
@sarahookr on why GPUs — built for dense, predictable matmuls — are the wrong tool for the world AI is actually moving into.
Presented with @Cerebras and @alyciazcary -
Cerebras reposted
Hassaan Raza
@hassaanraza
Last week Apple previewed the future of Siri. In 1987 though, Apple showcased a far more advanced AI assistant that would change how we use our computers entirely. It could see you, control your computer, and even looked and sounded human. They called it Knowledge Navigator.
For nearly 40 years it remained science fiction. This past week at @tavus we finally brought it to life with the help from our friends at @cerebras.
Meet Dom:This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Faster inference gives cybersecurity products more than just faster answers.
It lets them fit more context, tool calls, validation, and policy checks into their latency budget.
More in our blog 👉 www.cerebras.ai/blog/ai-inference-cybersecurity -
Cerebras
@cerebras
Andrew Feldman on AI model selection:
Shop like you're at Costco.
You don't need to buy everything.
You don't need the biggest thing on the shelf.
And somehow you definitely don't need the 400 oz tub of mayo.
Same with AI.
Not every problem needs the biggest, most expensive model.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras reposted
max.berlin
@maxjendrall
Yesterday I organised Europe’s first community Cafe Compute with @cerebras in Berlin!
We had over 200 signups and ~80 people join us to talk about fast inference and running frontier intelligence at the speed of 1000+ tokens per second.
Special thank you for Cerebras and @communidiyi for entrusting me with the Ambassadorship and @WigetJanette with @aicampusberlin for hosting us and helping me organise this evening.
In the first half we had Zigfrid (Solutions Architect at Cerebras) join us and answer all the questions we had about what they do and how their chips work.
And in the second half we had great demos from the community:
@slobkebap presented a real time GenUI flow to build UI in realtime by talking to it using @OpenAIDevs's realtime v2 api combined with Cerebras GLM-4.7
@SpringStreetNYC presented his autonomous AI research lab experiment in which he tried to teach a small model to ask great questions on the level of frontier models.
Hoang Minh showcased how he finds vulnerabilities in big OSS projects very fast and helps patch them.
And my personal favourite demo that night: @leolurch, who showed us his machine learning pipeline to find lost art pieces on auction platforms. Basically face recognition but for art, to recover potentially stolen or simply lost art from the last centuries.
I had so many cool chats and am glad that so many very talented people showed up.
Thank you everyone for coming!
And thank you so much @0xSero for sharing the event! -
Cerebras
@cerebras
Bonjour! Will we see you @RaiseSummit?
-
Cerebras
@cerebras
NVIDIA paid $20B for Groq.
AWS partnered with Cerebras for the same purpose.
A quick breakdown of why disaggregated inference is the next thing in AI infrastructure.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
one of the things I loved about my convo with @sarahookr is how she frames chaos
> "no one knows the answer" = fun time
> a million different approaches to memory = super interesting
> agentic workflows breaking everything = a huge opportunity
her take: the bigger the problem, the bigger the impact.
This is a great mindset, especially right now. The hardest problems in AI infrastructure aren't solved. The hardware lottery is more dire than ever. That's not a reason to be anxious, it's the reason we’re here.
Produced with @cerebras // @alyciazcaryThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
how do you become one of the most well-known developers in the world if you can't type?
@jxnlco sat down with us to share his story and how he continues to ship code at OpenAI. Turns out the answer is fast inference + the right agentic tools.
new convo w/ @Cerebras and @alyciazcary -
Cerebras reposted
adaption
@adaption_ai
The internet was supposed to summon what you need.
Instead: hundreds of tabs.
AI should fix that. Co-founder @sarahookr explains the interface should adapt to you, not the other way around. -
Cerebras
@cerebras
RT @MilksandMatcha: on set with the one and only @TheRohanVarma cooking something spicyyyy
-
Cerebras
@cerebras
TSMC is perhaps the greatest manufacturing company in the world.
They have been our partner from our inception.
In August of 2017, we met with TSMC’s senior leadership in Taipei.
They were one of the largest companies in the world.
We had an idea written on PowerPoint.
We thought that we could build the largest chip in the history of the computer industry.
In the meeting, they greenlit the project.
Today our 4 trillion transistor Wafer Scale Engine, is the fastest AI processor in the world.
It is 58 times larger than the largest competitor and uses a fraction of the power per unit compute.
We could not have done it without them.
They have been an extraordinary partner in every way.
Pictured below from left to right: TSMC CEO Dr. C.C. Wei, Cerebras COO Dhiraj Mallick and TSMC SVP Dr. Kevin Zhang.
Location TSMC’s headquarters in Taiwan. -
Cerebras
@cerebras
Google just released their fastest model: Gemini 3.5 Flash. We ran it head-to-head against Kimi K2.6 on Cerebras. The two are neck-and-neck on intelligence, but what about speed?
Full benchmark results:
www.cerebras.ai/blog/which-is-faster-gemini-3-5-flash-or-… -
Cerebras
@cerebras
We are in the recursive age of AI.
Faster inference => faster AI development.
Our take on this from the hardware perspective: www.cerebras.ai/blog/why-the-ai-race-shifted-to-speed
Anthropic
@AnthropicAI
Our internal data shows Claude is accelerating AI development—a possible path to recursive self-improvement, or AI autonomously building a more capable successor.
It’s happening faster than we thought, and the implications deserve greater attention. www.anthropic.com/institute/recursive-self-improvement -
Cerebras reposted
Bloomberg Live
@BloombergLive
How did @cerebras arrive at their blockbuster IPO?
"It's the largest chip ever made. [It's] the fastest AI processor ever built. We solved the problem that had been open in the compute industry for 75 years." @andrewdfeldman #bloombergtech @tsgiles
⏯️www.youtube.com/watch?v=OiQZt4yOj2gThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
"If you can co-locate your memory, you're getting a lot more bang for your buck because you're avoiding this costly memory transfer."
@sarahookr (author of The Hardware Lottery, founder of @adaptionlabs ) on why inference is forcing a new chip paradigm - one that wafer-scale was built for.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
In conversation with @MilksandMatcha for Big Chip Club. Produced by @alyciazcary.
Cerebras
@cerebras
Watch the full interview: youtu.be/yOqdhbSmkpw
-
Cerebras
@cerebras
we sent 2 PMs to @Microsoft Build with one mission:
whoever gets the most photos with the Wafer-Scale Engine in 10 minuntes, wins.
for anyone who hasn't met it in person — the WSE is the largest chip ever built, and it powers the fastest AI. It tends to draw a crowd!This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Our PMs: @joyceatcerebras & Eric Cheng
-
Cerebras reposted
Bloomberg Live
@BloombergLive
TOMORROW: What's next for @cerebras after its IPO?
@tsgiles speaks with CEO & Co-Founder Andrew Feldman about AI infrastructure, competition, and growth at #bloombergtech Opening Night.
Live at 7:25 PM PDT ⏯️
www.youtube.com/@Bloomberg_Live/streams?cbrd=1&ucbcb=1 -
Cerebras
@cerebras
AI is now writing the code to build the next AI.
Faster inference = faster time-to-next-model
Whoever gets to AGI first wins (everything).
Yet some still question if speed matters.
Puzzling. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
"Dwarkesh says diffusion is cope. I disagree. I think diffusion is going to be painful."
One of my favorite moments from my convo with @pk_iv is his take: the internet isn't getting rebuilt for AI anytime soon. His mom is still going to use Google for the next 10 years. @browserbase meets the world where it is.
Presented with @cerebras //@alyciazcaryThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
A behind-the-scenes look at what it's like to work at OpenAI
with @jxnlco @Cerebras, @alyciazcary -
Cerebras reposted
MTS
@MTSlive
SITUATION EXPLAINED: Cerebras raised $5.55 billion in their IPO and closing their first day of trading valued at $66 billion, making it the biggest US tech IPO since Snowflake in 2020.
Cerebras makes Wafer-Scale Engine chips built for AI inference.
We asked @MilksandMatcha the main difference between wafer-scale chips and traditional GPUs:
- GPUs are great at parallel work (graphics, training)
- AI inference is sequential, AKA one token at a time
This causes the "memory wall" problem:
- Every GPU core needs model weights, KV cache, and activations to do its math
- On a GPU, that data lives in off-chip memory (HBM)
- Cores constantly load and offload from off-chip memory, which is a huge bottleneck; hardware accounts for ~70% of inference latency
Cerebras' chips:
-Dinner-plate sized (vs. GPUs which are palm-sized) with tens of thousands of cores
-Memory sits directly on top of the cores as distributed SRAM
-Weights and KV cache can be accessed at on-chip speeds in the PB/s range, compared with off-chip speeds in the TB/s range achieved by GPUs with HBM.This media couldn't be displayed. See it on the original post.
Sarah Chieng
@MilksandMatcha
I joined Cerebras last than two years ago. And yesteryday, we IPOd.
It took 3 days from when I first heard about Cerebras to when I started on my first day. I had many job offers, and would have never imagined that I would pick a hardware company. But when you try an inference demo on a Cerebras chip (WSE-3), playing with an early llama model, it's hard not to have a holy sh*t moment.
It's been incredible starting and building the developer experience team, introducing a new category of products, experiences, and research that were never possible before.
We are only getting started. -
Cerebras
@cerebras
“This technology, this work would be big enough to require dedicated silicon… you needed to start with a clean sheet of paper and you needed to do something fundamentally different.”
@andrewdfeldman joined @PeterDiamandis on MOONSHOTS to discuss wafer-scale AI compute, fast inference, and the infrastructure layer behind frontier AI.
Full episode — Andrew’s segment begins at 1:23
youtu.be/kklrodAua_U -
Cerebras
@cerebras
Cerebras congratulates our investors for making the Midas List.
Eric Vishria, Steve Vassallo and Lior Susan led our series A.
Thomas Laffont led our series B and Brad Gerstner our series D and E.
We thank them for their extraordinary support over more than a decade and we congratulate them on their recognition.
CC: @ericvishria, @vassallo, @EclipseVentures, @thomas_coatue & @altcap -
Cerebras
@cerebras
Multi-LoRA is in private preview on Cerebras Inference.
Deploy one base model alongside a library of LoRA adapters. Switch between them per request, with no reloading, no separate deployments, and no latency cost.
Available now for dedicated endpoint users. Reach out to your account rep to get access.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
“For hard problems, there is no upper bound to how much faster you want to be... speed is of the essence. It’s true in coding. It’s true in agentic flows. It's true in every part of the AI landscape.”
Don't miss @andrewdfeldman on the latest episode of the @20VC podcast with @HarryStebbings.
Full episode: www.youtube.com/watch?v=6EOwSXE3XwsThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Andrej Karpathy and Fei Fei Li both did nearly 10 YEARS of higher education before eventually founding Eureka Labs and World Labs.
If you have attended major AI conferences like ICML, ICLR, or NeurIPS recently, you will see that there is a huge shift of researchers pivoting to start companies, and a vast amount of VCs who now find deal flow from these conferences. It was interesting to sit down with Ajay Joshi, who did his postdoc at MIT, is a current professor and is now starting his own company, Ciphersonic.
Presented with @cerebras // @alyciazcary -
Cerebras
@cerebras
Sovereign AI means countries can build, deploy, and govern AI on their own terms.
🌐 National capability is the goal.
☑️ Capacity is the prerequisite.
🚀 Speed is the strategic advantage.
🇺🇸 U.S. 🇦🇪 UAE 🇮🇳 India are building with Cerebras.
Learn more: www.cerebras.ai/blog/what-is-sovereign-ai-and-how-cerebra… -
Cerebras reposted
Alycia Cary
@alyciazcary
very cool to be on set with the brilliant @sarahookr. she has the rare skill of seeing all the threads that pull ai development in specific directions, and how to adjust them so good ideas surface. and she's one of the clearest communicators i've met!
all that to say... new #bigchipclub interview coming out very soon with @MilksandMatcha for @cerebras -
Cerebras
@cerebras
Exactly one week after ringing the bell at @Nasdaq, we celebrated with the employees and their families who made it happen.
Our global teams gathered together to mark 10 years of everything that led to that moment. Kids running around, stories being shared across two cities, and more than a few well-earned tears of pride.
A company is built on a decade of late nights, hard calls, pivots, breakthroughs, and the unshakeable belief that we were onto something worth fighting for.
In our CEO @andrewdfeldman's words: "We need you more than ever. We're just getting started." -
Cerebras
@cerebras
"As people began integrating AI into their day-to-day work, speed became fundamentally important. And we were just crushed with demand.
Is Cerebras inference faster for specific use cases? No, it's faster across the board. Big models, small models, U.S. models, Chinese models, trillion-parameter models, one-billion-parameter models...across the board."
@andrewdfeldman @saranormous and @eladgil dive in on @NoPriorsPod
www.youtube.com/watch?v=jeop9wfb9jU&t=39s -
Cerebras reposted
James Wang
@draecomino
I'm looking for a truly based technical product marketer.
Must be fully steeped in the AI landscape and be a daily AI user/builder. You will get to market next-gen Cerebras models and hardware. Together we will speedmog GPUs.
DM to apply. job-boards.greenhouse.io/cerebrassystems/jobs/7628238003 -
Cerebras
@cerebras
We're bringing Cafe Compute to @TOtechweek next Wednesday, cohosted with @Bell. 🇨🇦🇨🇦🇨🇦
Cafe Compute Toronto is where Canadian AI builders and researchers come together to push on what's possible on lightning fast inference.
RSVP link in comments
Cerebras
@cerebras
RSVP: luma.com/cctoronto26
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
I asked a college professor how he catches AI cheating. Here's what he said:
-
Cerebras
@cerebras
Google's new fast model 3.5 Flash vs Cerebras
-
Cerebras
@cerebras
Cerebras is now running Kimi K2.6 – a trillion parameter model – in enterprise trials.
At ~1,000 tokens/s, this is the fastest frontier model performance ever measured by Artificial Analysis @ArtificialAnlys.
Cerebras
@cerebras
Learn more: www.cerebras.ai/blog/cerebras-kimi-k2-Enterprise
-
Cerebras
@cerebras
“The GPU isn’t the only way.” — @andrewdfeldman + @tbpn ⤵️
This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Nasdaq Exchange
@NasdaqExchange
The world's fastest AI inference is officially #nasdaqlisted. Welcome, @Cerebras. $CBRS.
-
Cerebras
@cerebras
Winners announced, congrats!
@ishaangtwt
@SudipS196
@franjavitl06
@smarative
@JadMadi
Cerebras
@cerebras
🎁 We're giving away 5 Windsurf plans ($250 credit each)!
Try SWE-1.6 — @Cognition’s latest fast and intelligent agentic coding model, powered by Cerebras. In a side-by-side with Claude, the speed difference is clear. More iterations, faster fixes, better code.
💬Comment why you want access to enter. Five winners will be selected at random within 48 hours. -
Cerebras reposted
Mark Goldberg
@Mark_Goldberg_
@cerebras marketing meeting:
“No bad ideas…”
👏👏👏 my kids’ new favorite book is now about an underdog wafer -
Cerebras reposted
Shaun Smith
@evalstate
Hey, @MilksandMatcha is so multi-talented, never knew she was also an author! - thank you @cerebras team. Not opened the box yet - think there's a wafer inside?
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
on set with some of the best today, can't wait to release @0xSero @alyciazcary @sarahookr
-
Cerebras
@cerebras
👇⌛️
Cognition
@cognition
Intelligence at 1000 tokens per second, right in your terminal.
Now available with SWE-1.6 Fast, powered by @cerebras.
We're giving the first 100 people who respond a free month of Max to try it out. -
Cerebras
@cerebras
🎁 We're giving away 5 Windsurf plans ($250 credit each)!
Try SWE-1.6 — @Cognition’s latest fast and intelligent agentic coding model, powered by Cerebras. In a side-by-side with Claude, the speed difference is clear. More iterations, faster fixes, better code.
💬Comment why you want access to enter. Five winners will be selected at random within 48 hours. -
Cerebras
@cerebras
Fully homomorphic encryption was invented in the 1980s.
Why wasn't it adopted sooner? A 100,000x slowdown, driven by memory boundedness. Ajay Joshi from @CipherSonicAI explains how his team got it down to less than 2x.
(if this pattern sounds familar... LLM inference is memory-bound too. It's why wafer-scale exists.)This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full interview: youtu.be/o5zFrYbASow
Big Chip Club is presented by @MilksandMatcha and @alyciazcary -
Cerebras
@cerebras
Cerebras inference ecosystem, updated: open-weight model families, cloud providers, integrations.
👉 www.cerebras.ai/blog/ecosystem -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Someone hacked into my Twitter account last week. I will not say what I did (yes it was my fault and yes it was followed by very intense panic)
But I feel like security is always one of those things that we see happens to others and then never think it'll happen to us.
It was really refreshing to sit down with Ajay Joshi, Professor at Boston University about how this does not need to be the norm! We can take full advantage of AI (without giving it access to all of our secrets).
Presented with @cerebras // @alyciazcaryThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Kyle Jeong
@kylejeong
I don’t have children yet (I’m 21) but when I do they will learn about chips
Thanks @MilksandMatcha & @zhennydez this is very creative. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
watching devs misuse fast inference is almost painful right now. I feel like people are missing the point
1. any bad habit that generated slop code at 50 toks/s (sonnet) is now going to generate slop code at 1,200 toks/s (Codex Spark)
2. 20x faster code generation also means your context window is going to fill up 20x faster (the all-feared compaction)
3. you are probably already guilty of generating massive amounts of code that's never verified
You must understand. The industry is entering a new era of fast inference. Codex Spark at 1,200 tok/s powered by @cerebras is just the beginning of a step function faster future of faster models.
It is incredible. IT IS SO EXCITING. There has never been a more exciting time where you don't have to doomscroll to cope with the endless 'cogitating' 'reticulating' and 'schlepping'.
BUT. This new era does require us to update how we treat the model, or we are going to generate technical debt at machine speed.
I gave my first talk at @aiDotEngineer London about this. It was nerve-wracking, but also SO MUCH FUN. Thank you to @swyx for the opportunity and the incredible @0xSero @zhennydez and @halleychangg for the talk feedback and contributions.
What a time to be alive. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
WHO WOULD HAVE EVER EXPECTED.
300+ developers, partying past 11:00 PM, on a tuesday night?
cafe compute miami (and 21st birthday party for @swyx). presented by @cerebras and @cognition -
Cerebras reposted
Philip Kiely
@philipkiely
Fun drop from my friends @MilksandMatcha @zhennydez — great ship out Dev Writers SD!
-
Cerebras reposted
Sherwin Wu
@sherwinwu
One of my favorite of our recent blog posts: @cerebras made GPT‑5.3‑Codex‑Spark so fast that we had to rethink how Codex uses the Responses API – leading us to build WebSocket support for ultra fast latency.
Cerebras speed is just 🤯
OpenAI Developers
@OpenAIDevs
⚙️ We made agent loops faster with WebSockets in the Responses API
As Codex got faster, the bottleneck moved from inference to inefficient API calls
WebSockets keep response state warm across tool calls, helping workflows run up to 40% faster end to end
openai.com/index/speeding-up-agentic-workflows-with-webso… -
Cerebras reposted
Lukas Levert
@lukaslevert
How cute— @cerebras made a children's book!
My future kids will thank you for the alpha @zhennydez @MilksandMatcha 🙏 -
Cerebras
@cerebras
"Everyone wants faster agents. And you know what sucks... people think it's my fault. But it's actually the inference."
@pk_iv, CEO of @Browserbase, sits down with @MilksandMatcha on why inference speed is the real bottleneck for browser agents, and why Browserbase + Cerebras gets you the fastest agents possible.
Cerebras
@cerebras
watch the full interview: youtu.be/HKL92gQmF_A
-
Cerebras reposted
Alessio Fanelli
@FanaHOVA
By far the cutest AI book I own! Thank you @cerebras @MilksandMatcha @zhennydez!
-
Cerebras reposted
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
The absolute lack of taste in this city is abominable.
The Devil Wears Prada 2 is a ruthless education in beauty, aesthetics, and taste.
We're renting out an entire theater on opening night so the researchers training our models can get educated themselves.
Comment “PURPLE GRADIENT” and I’ll DM you the invite. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
had to push @pk_iv on the biggest critique of @browserbase, that they're enabling an internet overrun by bots...
his answer: trust is the whole game. and Browserbase wants to be the arbiter of good bots.
(also he made me say "haters" instead of "common take" lol)This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sumeet 🎒
@TheCoderShow
India’s first @cerebras Cafe Compute.
Mumbai showed up.
World’s first Cerebras Ambassador here.
Solutions Architect joined live. Real demo. Real speed.
The room lit up the moment they felt it.
Bangalore and Delhi, you’re next. -
Cerebras
@cerebras
Join @cerebras and @cognition at @AIEMiami After Party on Tuesday April 21 to meet the team behind the world's fastest inference. RSVP link in comments.
Be sure to catch Head of DevX @MilksandMatcha's talk on latency debt if you're at AIE!
Cerebras
@cerebras
RSVP: luma.com/ccmiami
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras
@cerebras
New cookbook alert! 🚨
Presented by @zhennydez and @alyciazcary from @cerebras, in partnership with @khushi_shelat from @p0
zhenwei
@zhennydez
Over 70% of people don't trust what they read online. Increasingly, it's getting harder to tell what's real.
So, we built a content fact-checker with @p0 that verifies any article in under 10 seconds.
Powered by @cerebras' fast inference up to 2,000 tokens/sec and @p0 Search and Extract API.
Check out the full cookbook below!This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
"I used a billion tokens this week. I'm not even in the top 100 Codex users at OpenAI."
We sat down with @jxnlco (creator of Instructor, now on @OpenAI's Developer Experience team) to talk about how zero-latency inference is changing the way engineers work.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the full interview: youtu.be/z_7GCp0BApc
Cerebras
@cerebras
Get started with Codex Spark: openai.com/index/introducing-gpt-5-3-codex-spark/
-
Cerebras reposted
Sumeet 🎒
@TheCoderShow
YC teaches you how to build.
Cafe Compute shows you what to build on.
In 8 days, one room in Mumbai gets access to the world's fastest AI chips.
The rest will read about it on X.
April 18th. 5-7pm 👇
luma.com/cafecomputemumbai
@cerebras -
Cerebras
@cerebras
Cafe Compute went global this week 🌎 Two cities. Two continents. One big chip.
This week Cafe Compute hit San Francisco for @HumanXCo and London at @OpenAI's office for @aiDotEngineer Europe — fueling developers with coffee and the fastest AI on the planet.
Next stop: Miami for @aiDotEngineer Miami 🌴
Cerebras
@cerebras
Sign up for future events: luma.com/cerebras
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
one of my favorite parts of the job
sitting down with extraordinary people like @jxnlco from OpenAI to discuss how codex changes the way we work
presented by @cerebras // @alyciazcaryThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Can AI really replace SaaS?
We asked Codex Spark to build a simple Salesforce clone. It generated a build plan, then wrote all the code in 29 seconds.
And it works! Add contacts, live search, full pipeline dashboard – all unit tests passed.
The same task on full Codex took ~5× longer. For rapid prototyping and self-contained work, nothing beats Spark. ✨This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Fast tier. 🟧
Cognition
@cognition
We’re releasing SWE-1.6, our best model in both intelligence & model UX. SWE-1.6 matches our Preview model on SWE-Bench Pro while dramatically improving on various behavioral axes.
It’s available today in Windsurf in two modes: free tier (200 tok/s) and fast tier (950 tok/s). -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
cafe compute at the OpenAI London office
w/ the best cohosts @kagigz @reach_vb @0xSero @communidiyi @cerebras @OpenAIDevs -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
audit and fix your entire developer docs site in under a minute
We built an AI agent with @browserbase and @cerebras that audits your entire docs site
> point it at any documentation site
> agent goes down the link tree
> agent crawls and verifies every page, checks every link, reads every code snippet
> agent also compares content to your GitHub repo
> returns a full report with suggested fixes and source references
The full code and tutorial for how to build this yourself is live now.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
What is semiconductor yield?
How does it work?
Why did it define the semiconductor industry for 70 years?
How did this problem get solved?
And how does this impact developers?
What Is Semiconductor Yield?
When you manufacture chips, not every one comes out working. Some have defects.
“Yield” is the percentage of chips from a manufacturing run that actually work. If you make 100 chips and 90 work, your yield is 90%.
How Does Yield Work?
Chips are made from silicon wafers - thin, circular discs about 12 inches in diameter.
In a perfect world, every square millimeter of a wafer would be flawless.
But that never happens. Every wafer has tiny random defects scattered across it.
Chips are cut from these wafers.
And any chip that lands on a defect is thrown away.
The process of chip manufacturing looks a lot like your mother making cookies.
Imagine your mom rolled out a circle of cookie dough 12 inches in diameter.
Then when she wasn't looking, your brother threw a handful of peanut M&Ms into the air and they landed at random on the dough.
Those M&Ms are flaws.
Nobody can eat a cookie with a peanut M&M in it.
So she has to throw away every cookie that has one.
Now she gets out a small cookie cutter and stamps out cookies.
Because the cookie cutter is small, the probability of hitting an M&M is low. And when a cookie does have one, there isn't much good dough surrounding it.
Not much good dough is thrown away.
The result: a lot of good cookies.
They are small but there are a lot of them.
On the other hand, if she uses a big cookie cutter, the probability of hitting an M&M is much larger.
And when she throws that cookie away, she throws away a lot of good dough with it.
The result: only a few cookies.
They are big, but the 12 inch diameter circle of dough yielded only a few.
This is exactly how chip manufacturing works.
The cookie dough is a silicon wafer.
The cookies are chips.
Peanut M&Ms are flaws (because they are gross)
Bigger chips hit more flaws.
More good silicon gets thrown away.
Smaller chips, like smaller cookies, are less likely to hit flaws.
And when they do, less silicon is discarded.
This is why big chips are disproportionately more expensive.
This is also why people assumed that because there was no way to make a wafer without flaws, there was no way to make a chip the size of a wafer.
Why Did This Define The Industry For 70 Years?
In an ideal world, you'd build really big chips for many data center applications.
Data moves incredibly fast on-chip.
So if you keep the data and compute on-chip, your work takes less time, and uses less power.
In AI, that manifests as super fast inference.
But the moment data has to leave one chip and travel to another - through cables, switches, connectors, circuit boards - it slows down and uses more power.
Lots of off-chip communication slows work, and, in AI, produces slow inference.
Though everyone agreed they were faster, nobody could yield big chips.
So the industry settled on a workaround: don't build one big chip.
Build thousands of small ones and wire them together.
Most AI data centers are built this way today.
Thousands of little GPUs connected by cables, switches, and networks.
It works.
But you pay a price.
Every connection adds latency.
Every cable adds overhead.
Every hop between chips slows things down.
For 70 years, everyone accepted this as the only way.
How Did Cerebras Solve the Yield Problem?
In 2019, we solved the yield problem at @cerebras and brought the first wafer sized processor, wafer scale processor, to market.
How did we do that?
The answer came from studying a different kind of chip entirely. Memory.
Memory is built with a different process.
Memory chips are made up of millions of identical tiles, with redundant tiles woven throughout.
In a memory chip, if a tile has a flaw in it, the chip doesn't get thrown away.
The bad tile is shut down and one of the redundant ones is called into action.
Memory chips weren't designed to avoid flaws, but rather to withstand them.
They use redundancy to withstand flaws.
And their yield is extraordinary.
Our founders realized that if we could develop a compute architecture that looked like memory, that was built of hundreds of thousands of identical tiles, we too could use redundancy to withstand flaws.
We could fail in place, and route around the failed tile, just as they do in memory (and interestingly as they do in data centers where they fail in place, route around, and keep going). This would enable us to yield a wafer scale processor.
And today we are happy to compare our yields to GPUs, that are 1/58th our size.
How Does This Impact Developers?
The impact is simple and easy to see. Cerebras wafer scale processors are up to 15 times faster than @nvidia GPUs.
And when your AI is fast, people use it more often, stay longer, and use it to solve more interesting problems. -

Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras
@cerebras
Packed room. Line around the block.
Why? Because everyone wants to go faster.
Appreciate everyone who showed up.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Join us at our future events: luma.com/cerebras
-
Cerebras
@cerebras
Problem solved. ✅
Andrew Feldman
@andrewdfeldman
NVIDIA's biggest GTC announcement was a $20 billion bet on the same problem we solved 6 years ago.
Their next-gen inference chip - not available yet - has 140x less memory bandwidth than @cerebras.
To run a single 2 trillion parameter model, you need 2,000+ Groq chips.
On Cerebras, that's just over 20 wafers.
Even paired with GPUs, Groq maxes out at ~1,000 tokens per second.
We run at thousands of tokens per second today.
And every day. In production now.
Why?
When you connect 2,000 chips together, every interconnect has latency. Every cable has overhead.
It doesn't matter what your memory bandwidth is on paper if you're bottlenecked by the wiring between thousands of tiny chips.
We solved this with wafer scale.
One integrated system. Little interconnect tax.
Jensen told the world that fast inference is where the value is.
He’s right - it’s why the world’s leading AI companies and hyperscalers are choosing Cerebras. -
Cerebras
@cerebras
what can you build with gpt-5.3-codex-spark?
@jxnlco from @OpenAI demos 3 real workflows — ones you can set up yourself inside the Codex app to help you spend less time on overhead and more time building.
00:09 – what is gpt-5.3-codex-spark?
00:25 – workflow 1: multi-agent daily briefing from slack, drive & meets
01:06 – workflow 2: automated PR review
01:31 – workflow 3: real-time interactive coding
02:56 – what speed changes, and what's coming nextThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras
@cerebras
Nvidia DLSS 5 off DLSS 5 on
-
Cerebras
@cerebras
Standing room only.
-
Cerebras
@cerebras
☕ Thanks to everyone who grabbed coffee with us this morning.
🟧 The big chip is just getting started.
See you around!This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Amazon Web Services
@awscloud
We're teaming up with @cerebras to build the fastest possible inference.
Coming soon to Amazon Bedrock, we’re delivering inference performance an order of magnitude faster than what’s available today by connecting AWS Trainium3 for compute-intensive prefill with Cerebras CS-3 to power decode.
Learn more about the partnership. go.aws/3Pzcota -
Cerebras
@cerebras
Our coding workflows were designed to accommodate slow inference. @OpenAI's Codex Spark powered by @cerebras changes the game.
Here's how we make the most out of 1,200 tokens per second, with @MilksandMatcha.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
get started: chatgpt.com/codex
Cerebras
@cerebras
for more comprehensive tips, check out our guide to Codex Spark: www.cerebras.ai/blog/codex-spark-best-practices
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
I gave both Codex and Claude Code full access to my twitter account.
Codex spark (powered by Cerebras) did a full GTM outreach workflow 3x FASTER than Claude code, and used way less tool calls.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
The AI Conference
@AIconference
AI isn’t just evolving. It’s scaling. And the infrastructure behind it is redefining what’s possible.
@SarahChieng, Head of Developer Experience at @Cerebras, works with the engineers building the systems training the world’s largest AI models.
Hear her speak at @aiconference -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras
@cerebras
gpt-oss-120b is one of the most-used models on Cerebras Inference.
We sat down with @ml_angelopoulos from @arena and @SarahChieng to break down its strengths, weaknesses, and where it's outperforming. Here's what he's seeing.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
-
Cerebras reposted
Ray Fernando
@RayFernando1337
Who wants in to Cafe Compute by Cerebras? It is going to be a huge week at GTC and would be fun for you to join me! luma.com/cccerebrasgtc26?tk=FWeGGi
-
Cerebras reposted
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
"Gone are the days where one number can describe how good a model is."
We asked @arena founder @ml_angelopoulos what to expect from AI in 2026. More models, more fragmentation, and a lot more choice. Here's what he's seeing.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
chinese labs shipped 6 open source models over lunar new year while most of the industry was on vacation
Kimi K2.5, DeepSeek OCR 2, Seedance 2.0, GLM 5, Doubao Seed 2.0, Qwen 3.5
the pace is unreal. and this is exactly why we're so excited to support open source models at @cerebras
get started with over 1M+ FREE tokens/day -
Cerebras
@cerebras
10 academic papers. Parsed, analyzed, and synthesized. In under 10 seconds.
We built a research agent with @Cerebras Inference and @UnstructuredIO that processes entire literature reviews so you become a subject expert faster
Cerebras
@cerebras
try it out: inference-docs.cerebras.ai/cookbook/agents/academic-resea…
-
Cerebras
@cerebras
Introducing ExomeBench: a benchmark for evaluating genomic models on disease-associated genetic variants, built in collaboration with with @MayoClinic.
Most genomics benchmarks focus on general sequence modeling tasks. What remains under-evaluated is whether these models can answer clinically meaningful questions about genetic variants.
That's why we built ExomeBench and are releasing it to the public: a benchmark for evaluating health-relevant variant interpretation in exome regions.
Cerebras
@cerebras
Try it out and start testing your models:
@github: github.com/Cerebras/exome_bench
@huggingface (dataset): huggingface.co/datasets/cerebras/exome_bench -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
one of my favorite parts of this job is getting to sit down with people like Sarah Su
she's a junior at MIT studying AI, organizing HackMIT, interning at @cerebras, and she has a really unique perspective on why her generation isn't buying into the AI hype the way you'd expect
Sarah dives into her first-hand experience with AI in the classroom, declining hackathon projects, and what the next generation of MIT CS/AI students are excited to build.
Guest @SarahhhSuuu
Producer @alyciazcaryThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Faster 🟧
Tibo
@thsottiaux
We’ve made GPT-5.3-Codex-Spark about 30% faster. It is now serving at over 1200 tokens per second. More to come on speed across the board.
-
Cerebras
@cerebras
Proud to partner with @G42ai and @mbzuai (Mohamed bin Zayed University of Artificial Intelligence) to deliver a national-scale AI supercomputer in India with 8 exaflops of compute capacity.
This cluster is designed to support researchers, startups, enterprises, and government entities, and will serve as a foundational asset under the India AI Mission, accelerating AI innovation tailored to India’s needs.
Cerebras
@cerebras
It will operate under India-defined governance frameworks, ensuring full data sovereignty, security, and compliance. Read more: www.g42.ai/resources/news/uae-deploy-8-exaflop-supercompu…
-
Cerebras reposted
G42
@G42ai
In New Delhi, India takes a major step forward in strengthening sovereign AI infrastructure and expanding domestic compute capacity for advanced AI development with the deployment of an 8 exaflop national-scale AI supercomputer.
Delivered by G42 in partnership with @mbzuai and @cerebras, it will be the largest AI supercomputer in India, operating under India-defined governance frameworks, ensuring full data sovereignty, security, and compliance. Designed to support researchers, startups, enterprises, and government entities, it will serve as a foundational asset under the India AI Mission, accelerating AI innovation tailored to India’s needs.
At G42, we are committed to supporting nations in building, deploying, and scaling AI within their own borders, responsibly, securely, and at scale, enabling the development of AI-Native Societies.
Read more: www.g42.ai/resources/news/uae-deploy-8-exaflop-supercompu…
#g42 #g42ai #responsibleai #indiaaiimpactsummit2026 #ai #technology #globalsouth #exponentialai -
Cerebras
@cerebras
Over the weekend, the Cerebras team connected with 1,000+ student hackers at Stanford’s @hackwithtrees!
Some highlights:
• Met so many students building with the Cerebras API and OpenAI's new GPT-5.3-Codex-Spark model (powered by Cerebras🤝).
• Heard from our partner, OpenAI’s @sama, talk about the future of AGI where AI will move beyond simple automation into solving complex real economic problems and discovering new domains of knowledge.
• Hosted a sponsor lunch with friends from @GoogleDeepMind, @graphite, @warpdotdev, @HeyGen, @runpod, and more.
Talking with student hackers, we saw how low latency, a Cerebras specialty, changes how people build. Cerebras-powered teams shipped working projects in just a few hours, then spent the weekend iterating with real users instead of debugging.
When inference is instant, development becomes: ship, test, learn, repeat; with each cycle faster than the last.
Ready for 2000+ tokens/second? Meet us at our events or start now at cloud.cerebras.ai.
Cerebras
@cerebras
-
Cerebras reposted
-
Cerebras
@cerebras
Happy Lunar New Year! It's the Year of the Fire Horse.
In 2026, Cerebras charges forward — blazing-fast inference, full throttle.
Let’s ride. 🐎🚀 -
Cerebras
@cerebras
Collapse minutes to seconds,
hours to minutes,
and days to hours.
That is what we are here to do. -
Cerebras reposted
Browserbase
@browserbase
Make your browser agents lightning fast with Browserbase and Cerebras.
We built a template that uses the newest open-source models to spin up a fleet of browsers, crawling your docs and verifying they're up to date with your codebase,
All in under a few minutes. -
Cerebras reposted
Anikate Kaw
@anikatekaw
Everyone following AI should take a moment to understand this graph to grasp the importance of hardware.
The important and less talked about part of this graph is that for the SAME DURATION cerebras provides HIGHER ACCURACY with a SMALLER MODEL.
This is the Hardware Lottery by @sarahookr and Bitter Lesson by Richard Sutton playing out in real life. Over time cerebras hardware will prove that SPEED is a QUALITATIVE ADVANTAGE and not just QUANTITATIVE.
Congrats to @OpenAIDevs and @cerebras for this milestone. -
Cerebras
@cerebras
OpenAI Codex-Spark powered by Cerebras
You can now just build things faster—at 1,000 tokens/s. -
Cerebras reposted
Steve Krouse
@stevekrouse
experimenting generating html as fast as possible
1. using cerebras glm 4.7 @ 2k tps
2. parent agent generates html scaffold with "slots"
3. each child agent is assigned to generate slot
/* SLOT_START:initializeScene */
function initializeScene() { return ""; }
/* SLOT_END:initializeScene */
generates a threejs game in 25 seconds
turns out a single file is all you need to orchestrate work -
Cerebras reposted
Isaac Tai 🧇
@hi_im_isaac_
1 claude code → 14 mins
10 opencodes running @cerebras → 45 secs -
Cerebras
@cerebras
Who's your agent?
-
Cerebras
@cerebras
Cerebras Systems today announced the closing of a $1 billion Series H financing at a post-money valuation of approximately $23 billion. The round was led by Tiger Global, with participation from Benchmark, Fidelity Management & Research Company, Atreides Management, Alpha Wave Global, Altimeter, AMD, Coatue, and 1789 Capital, among others.
For more information on Cerebras, visit www.cerebras.ai/press-release/cerebras-systems-raises-usd… -
Cerebras
@cerebras
GLM 4.7 is one of the top open-source models on LM Arena—and it's going toe-to-toe with Claude Opus 4.5 and Gemini Pro.
We sat down with @ml_angelopoulos, co-founder and CEO of @arena, to break down 8,000+ developer votes:
→ Within 30 points of Gemini Pro in math & coding
→ Frontier-level multi-turn & instruction following
→ The open-source model devs are actually switching to
The best part? You can run it at 1,500+ tokens/sec on Cerebras—for free.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Daniel Kim
@learnwdaniel
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
The Year of Latency Debt (And How Big Tech Is Paying It Down)
In the past six months, the four most important companies in AI have all made massive billion dollar bets on faster inference, and none of those bets were on the NVIDIA hardware that already dominates AI today.
What is ‘Latency Debt’?
In software engineering, "technical debt" refers to the accumulated cost of shortcuts and slop code that works today but creates problems tomorrow. Engineers move fast, auto-accept AI suggestions, and defer the cleanup.
Latency debt works the same way, it is the hidden cost we accumulated while optimizing models faster than infrastructure. We optimized for intelligence, but each advancement like more model parameters or new reasoning models requires more compute per response.
If you've been building with frontier AI models, you've probably felt this too. This is the best technology humans have ever built, and using it often feels like watching paint dry.
The Smart Money Is Already Moving
Here's how you know latency debt is real: follow the money.
> Google, despite being one of NVIDIA's largest customers, built its own Ironwood TPU, 4x faster than NVIDIA's GPUs
> Anthropic committed tens of billions of dollars to Google's TPU infrastructure
> NVIDIA itself paid $20 billion to gut Groq for their IP and top talent
> And OpenAI just purchased 750 MW worth of Compute from @cerebras
Here is a full deep dive on how we got here, the software vs. hardware misalignment, and how we are finally paying down this debt. -
Cerebras
@cerebras
The @EPCCed at the University of Edinburgh—one of Europe’s leading supercomputing centers—has developed new high-level libraries to program the Cerebras CS-3 and just open-sourced them for everyone else to use.
When they measured the performance against GPU and CPU clusters, they found:
→ 14× faster than 128 Nvidia A100 GPUs on acoustic wave modeling
→ 20× faster than 128 nodes of a Cray EX supercomputer
→ Their compiler-generated code outperforms hand-tuned implementations
The A100 is obviously not the latest GPU. For context, Nvidia B200 has ~4× the dense FP32 flops of A100. So as a first-order approximation, a single WSE-3 delivered the performance of ~450 B200s for their workload.
Using the Cerebras Software SDK, the team built a compiler that automatically transforms standard Fortran and Python stencil codes into optimized Cerebras WSE programs. It removes the need for rewrites or recasting. Scientists keep writing in the languages they know, and the compiler converts it to Cerebras hardware code.
The compiler uses MLIR—the same infrastructure underlying modern AI toolchains—and plug directly into scientific frameworks like Devito and PSyclone.
Their results will be published at ASPLOS 2026.
Read the pre-print here: arxiv.org/abs/2601.17754 -
Cerebras
@cerebras
GLM 4.7 is one of the strongest open-source coding models available—but most developers aren't prompting it correctly.
We put together 10 rules to help you get the most out of it:
- Front-load instructions (it has a strong recency bias)
- Use firm language: "must" and "strictly" > soft suggestions
- Break complex tasks into smaller steps
- Disable reasoning for simple tasks, enable it for hard ones
- Use critic agents for code review, QA, and validation
- Pair it with a frontier model for the hardest 10% of workloads
- and more…
GLM 4.7 hits 96% on Tau² Bench and 86% on GPQA Diamond.
At 1,500 tokens/sec on Cerebras, it's 20x faster than closed-source alternatives on GPUs.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Learn more: www.cerebras.ai/blog/glm-4-7-migration-guide
-
Cerebras reposted
Daniel Kim
@learnwdaniel
Super fast @openclaw with @cerebras is super ergonomic to use ngl
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Cafe Compute is officially open for the year
We're coming soon to Boston, NYC, Seattle, Austin, London, Miami, Brazil, and many more.
The first, late night coffeeshop with coffee, free credits, and good company. Cheers to everyone who joined us last night ☕️
Presented by @cerebras @BainCapVC @p0 @reductoai @communidiyi @adelwu_ @amandamhuang @khushi_shelat -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
MoEs were invented in 1991.
Jacobs, Jordan, Nowlan, and Hinton proposed MoEs in 1991. “Let’s have a bunch of specialized experts and route inputs to the right one.”
However, it was totally impractical back then.
Two reasons.
1. the hardware couldn't support it
2. scale wasn’t a pronounced bottleneck
In the latest Big Chip Club, @dmsobol breaks down
> Why early MoEs were theoretically brilliant but impossible to run
> How hardware limitations stalled progress for decades
> What next-generation MoEs look like when hardware makes specialization possible @cerebrasThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
We're thrilled to announce the winner of the GLM4.7 Hackathon - X track, cohosted with @cline! The winners @Maaztwts and @enflect_ win $2500 USD and Cerebras Code plans for building a desktop AI assistant in 24hr hours using FAST inference.
Maaz
@Maaztwts
Built FlickAI in 24 hours at the @cerebras x @cline Vibe Coder Hackathon
▨ A desktop AI assistant that:
• Sees what’s on your screen
• Wakes up instantly
• Helps with coding, emails, notes anything and everything.
Built this with my teammate @enflect_This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Say hello to @dmsobol in Osaka on Jan 28!
Daria Soboleva
@dmsobol
I am heading to Osaka for @scahpcasia2026!
My talk on MoEs is on Wed, Jan 28th | 3:30pm (15:30) | Session 2.3 tpc.dev/tpc-track-at-sca-hpca26/
Look forward to discuss how we’ve solved the all-to-all bottleneck to scale MoEs to trillion-parameters on Cerebras hardware.
Also, I'm leading our MoE work at @CerebrasSystems. If you want to join the team, talk over coffee, or suggest what I should visit in Japan, DM me! 💜 -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
What is it like to be a delegate at Davos?
It’s like watching a trade show swallow a small Swiss village.
Every storefront is stripped bare and rented out to a corporation, a media outlet, or a well-funded entrepreneur. Out go the café tables. In come the branded backdrops, LED panels, and pop-up “offices.”
We gather to talk about AI, transformation, and the future of the global economy in a mountain village that looks almost exactly as it did in the 1950s.
It’s a bit like holding a ski conference in downtown Phoenix and earnestly debating the challenges of building resorts in the Nordics.
The irony is hard to miss.
And yet - despite the absurd prices and awful traffic - something very valuable happens here.
Davos works precisely because there is nothing else to do.
No competing nightlife, sprawling distractions or easy escapes. Unlike Las Vegas, Barcelona, or other trade-show cities, you can’t scatter. You’re forced into conversation.
As a result, people show up focused. Meetings actually happen and you keep bumping into the same people. The salon-style discussions around the main forum are the highlight: small groups of serious leaders bringing real business problems.
For all the buzzwords and excess, Davos still delivers one important thing: a temporary community where people who care about similar problems are forced to talk, listen, and engage.
Buried under the jargon, there is real learning... if you’re willing to look for it. -
Cerebras
@cerebras
Throwback to last year's hackathon with @cline where 1000+ hackers signed up to play around with the latest model on Cerebras, among them @archimagos who wrote about his experience.
Missed out? Join us tomorrow on Discord for our GLM 4.7 hackathon, with $5000 and Cerebras Code for winners!
Cerebras
@cerebras
RSVP here: luma.com/pzfjr8qp
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
The fastest AI processor in the world the @cerebras WSE is having fun in Davos.
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
GLM 4.7 is the top ranked OS model on leaderboards...but lets see if it’s worth the hype?
This Friday, @cerebras and @cline are excited to host a virtual GLM 4.7 Hackathon with $5K in cash and Cerebras Code plan prizes.
> All levels welcome
> Technical workshops
> Entirely virtual
> Technical support from engineers -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Cafe Compute is now open for the year!
Cafe Compute is the first, late-night coffeeshop for developers, researchers, writers to cowork with free coffee, pastries, and good company. ☕️
This year, we're excited to go national and global.
We have quite a list of cities already brewing, but let us know where you're based and we'll come visit you next :)
Presented by @cerebras @BainCapVC @reductoai @p0 @modal @browserbase @Replit @MITCSAIL -
Cerebras
@cerebras
If you think Cerebras is just about speed, you do not understand Cerebras.
Just as mass can be converted to energy, speed can be converted to intelligence.
It's the natural consequence of test-time compute scaling.
Cerebras
@cerebras
Read more www.cerebras.ai/blog/the-cerebras-scaling-law-faster-infe…
-
Cerebras reposted
Sam Altman
@sama
Very fast Codex coming!
Cerebras
@cerebras
OpenAI🤝Cerebras
openai.com/index/cerebras-partnership/ -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
What can these guys teach us about data center cooling?
A lot it turns out.
If you slip into icy water you are dead in 10 minutes.
But it's 10 below zero in Buffalo. Snow is coming in sideways.
How are these guys not dead?
The answer is simple. Air isn’t a very good cooling medium.
Air pulls heat away from the body very slowly. Water pulls heat away fast.
That’s why falling into icy water is lethal while standing shirtless in much colder air is survivable.
That same applies to cooling AI processors.
For decades, air cooling was good enough.
Chips were smaller. Power density was lower.
Blowing cool air over your chips was the strategy.
Its inefficient, but workable.
That era is over.
Modern AI systems concentrate enormous amounts of compute into very small spaces.
Power density keeps rising. Heat is generated faster than air can carry it away.
At that point, air cooling doesn’t fail because of bad engineering.
It fails because of physics.
Water cooling works for the same reason icy lakes are dangerous: water moves heat orders of magnitude more efficiently than air.
This came up in a longer conversation with TBPN.
I've put the link in the comments. -
Cerebras
@cerebras
OpenAI🤝Cerebras
openai.com/index/cerebras-partnership/ -
Cerebras
@cerebras
72% of people don't trust the internet.
AI generated false information is polluting even trusted sources. It's impossible to sort through what is real.
With this cookbook, you can build a fact checker that scans web-pages and verifies every claim. All at the speed of light, powered by @cerebras.
Test it on Hacker News, the latest NeurIPS papers, the Wall Street Journal, X/Twitter...
Built with
@p0 Search API
@cerebras Inference
@OpenAI's gpt-oss-120B
Comment what questionable claims you catch 🧐
Cerebras
@cerebras
Get the starter code here: cookbook.openai.com/articles/gpt-oss/build-your-own-fact-…
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
What if 1 line of code could 2× your LLM inference speed?
Predicted Outputs is a new software technique that can drastically speed up your model output speed. By telling the model which sections of the response will stay the same, Predicted Outputs can reuse over 80% of tokens during generation — delivering major latency gains without changing your existing workflow.
Watch how @Cerebras predicted outputs reuse known tokens to cut latency, speed up code & doc generation, and keep your workflow exactly the same.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Everyone talks about our hardware @Cerebras. Few notice the software.
Ryan Loney breaks down the hidden optimizations powering 20× faster LLM inference than GPUs, speculative decoding, token reuse, and why we’re just getting started.
Watch the full story hereThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
A common misconception in AI right now is that everything we’re excited about is new.
When I graduated from MIT in 2023, only 3% of students majored in AI (Course 6-4). I wasn’t one of them...oops.
What I know about models, agents, frameworks, and hardware I learned after graduating. And if you’re newer to the field like me, it’s easy to assume today’s breakthroughs are fairly recent.
After all, GPT-1 shipped in 2018... so it’s tempting for us to think the important ideas are less than a decade old.
They aren’t.
Mixture-of-Experts, the backbone of top models from companies like OpenAI and Google was invented in 1991 by Jacobs, Jordan, and Nowlan in “Adaptive Mixtures of Local Experts.”
Over 30 years ago!
In this conversation with @dmsobol, we discuss why MoEs are resurfacing now, the rapidly emerging compute bottlenecks, and how newer hardware architectures change the equation (@cerebras).
A reminder that what feels “frontier” today is often decades in the making :)This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Parallel
@p0
New cookbook:
A real-time fact-checking app to showcase Parallel’s high-accuracy web search and @Cerebras blazing fast inference, built with @aisdk.
Try it out: oss.parallel.ai/agents/cerebras-fact-checker/ -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
To put it bluntly, the Chinese model labs have officially caught up.
The latest release from @zai_org [GLM-4.7] marks the first time that an open-source model outperforms closed frontier models like Sonnet-4.5.
That’s a genuine inflection point.
2026 is going to be unbelievable as international players enter the model race, and z.ai becoming the first public AI lab only adds to the moment.
WHO WOULD HAVE THOUGHT!
We've worked closely with the developer community to put together a guide of the best tricks to optimize GLM 4.7 behavior.
Take it for a spin. It's free on @cerebras :) -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
We are cooking quite the storm of events in 2026
> Cafe Compute continues to go global 🌎
> Omakase hackathons
> Barrys w/ Builders workout classes
Subscribe to our @cerebras calendar so you don't miss out 🧡 -
Cerebras
@cerebras
GLM-4.7 from @Zai_org is live on Cerebras!
- Frontier intelligence for coding, tool-driven agents, and multi-turn reasoning
- Record coding speed: ~1,000 tokens per second (up to 1,700 TPS for other uses)
- Strong price-performance: ~10x higher than Sonnet 4.5
Cerebras
@cerebras
Read our blog: www.cerebras.ai/blog/glm-4-7
-
Cerebras
@cerebras
“Inference speed determines what AI can actually do.” 💃
2025 year made that clear. Real-time inference moved from production to proof. Not benchmarks. Not demos. With measurable results for our partners and customers.
Read @andrewdfeldman reflection on 2025 and groove with us in 2026. -
Cerebras reposted
Daria Soboleva
@dmsobol
MoE models are compute efficient. Everyone knows that. But they are not parameter efficient. Why?
Our experts learn redundant, overlapping functions. We're spending extra money loadings weights for redundant experts. This is wasteful. And we're not fixing it.
Attaching here a plot I showed at my @NeurIPSConf workshop showing how much redundancy there is in deepseek-v3 model in the first 23 layers. Diagonal is expert compare to itself. 🧵 -
Cerebras
@cerebras
A proud moment today, we have signed an MOU with the @ENERGY to deepen collaboration on next-generation AI and HPC in support of the @WhiteHouse Genesis Mission.
This builds on years of real work and a strong partnership with the national labs. We're just getting started. -
Cerebras
@cerebras
“DELOITTE TO REFUND AUSTRALIAN GOVERNMENT AFTER AI HALLUCINATIONS FOUND IN REPORT”
It's not about choosing the right model anymore. Most AI products don’t fail because the model is “bad.” They fail because the system drops context or over-writes user work.
Top teams take complaints like this and turn them directly into evals, so regressions never ship twice.
@ankrgyl explains what reliable AI UX actually looks like — and how teams use Cerebras + Braintrust to turn user complaints into lasting fixes.
Build with @cerebras and @braintrustThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
We had a cereal good time hosting Cafe Compute with @sfcompute!🎄 We had more than 100 AI builders, entrepreneurs, and investors enjoy our barista bar, talk shop, and hold THE BIG CHIP. Thanks for joining us for the launch of the Big Chip Club, and stay tuned for BIGGER & BETTER in 2026 🥂
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Cafe Compute is sf's first late-night coffeeshop with free coffee, desks, food, and unbeatable company.
Last year, Cafe Compute started as a Tuesday night experiment in our Hayes Valley living room. We kept the lights on late, ordered in-and-out, and made sure our wifi would survive.
In 2025, 10,000 people showed up! Researchers, first-time founders, cereal founders, and friends-of-friends, across SF, NYC, San Diego, Vancouver, and more. Thank you so much to the community who joins us.
We closed out the year with a Cafe Compute: cereal edition to launch our Big Chip Club podcast, and the verdict was unanimous: Oreo-os are king.
If you want an invite next year, comment your favorite cereal and we'll add you to the list :) Let's bring SF back. 🤙
A huge shoutout to the team who makes Cafe Compute possible @communidiyi @zhennydez @cerebras @sfcompute -
Cerebras
@cerebras
So proud of our team!
Andrew Feldman
@andrewdfeldman
I don’t think anyone becomes an engineer to do things a little bit better.
We become engineers to build things nobody’s built before - to change what’s possible.
That takes passion and drive bordering on obsession.
It takes a team that works together.
A team that works like it matters.
There is a feeling - a buzz in the building - when an engineering team is cranking.
It is amazing.
I don’t play an instrument.
But I imagine it is what musicians mean when they describe a jam session as “swinging”.
Collaboration in the creative process to build something important is a phenomenal feeling.
That’s what drives us at Cerebras every day:
Not balance. Not comfort.
But the chance to build something extraordinary. -
Cerebras reposted
Jared Hulbert
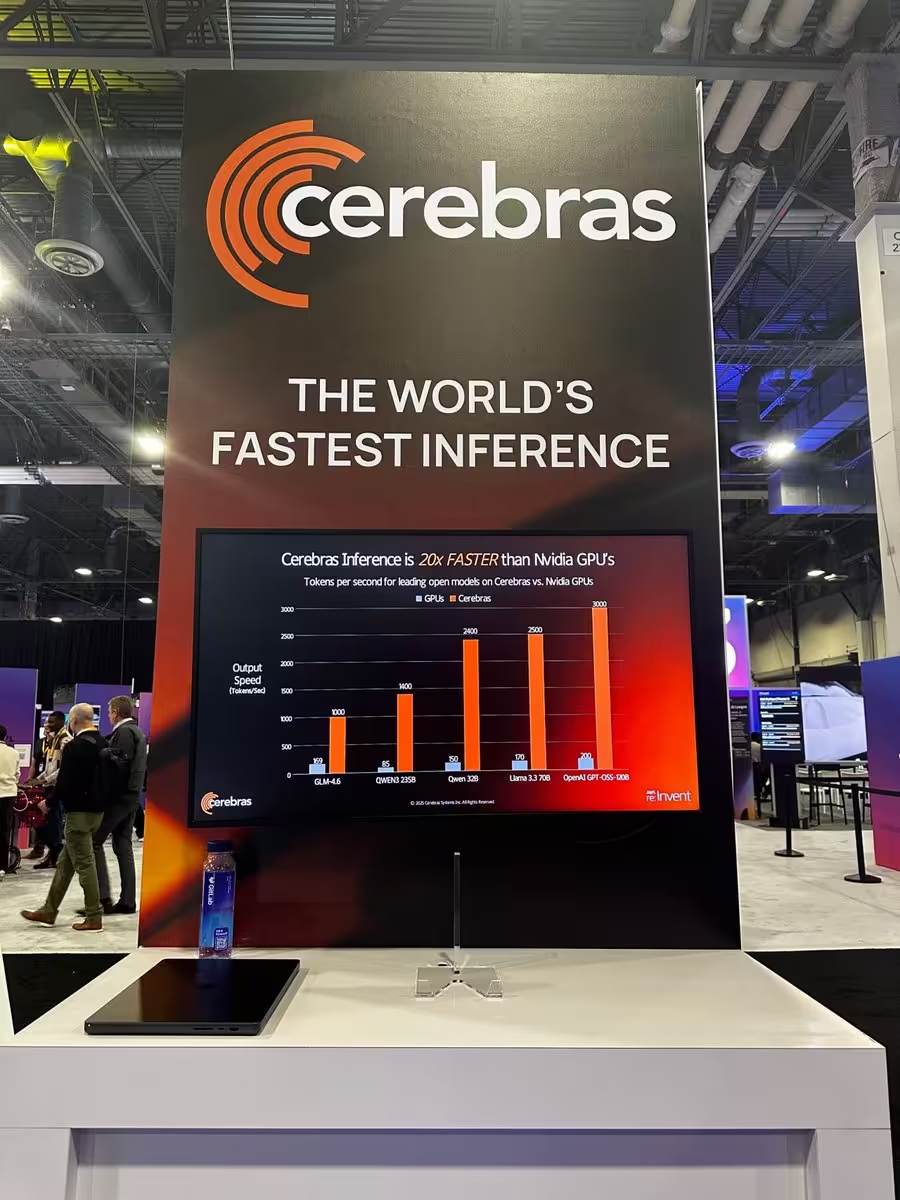
@jaredhulbert
It’s unofficially bring your dad to work day at @cerebras
They’re building some impressive things here. Like let’s push the limits on multiple mechanical, thermodynamical, electrical, and compiler level engineering problems concurrently kind of things. -
Cerebras
@cerebras
how many NeurIPS papers were written with ChatGPT?
did Google use Google Photos to train Nano Banana Pro?
could we use AI to talk to other species?
we asked researchers for their real code confessions
watch til the end. #codeconfessionsThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Tired of waiting for minutes for your AI coding assistant?
@cognition built agents that search, reason & edit code in a few seconds.
Powered by Cerebras—running at 1K tokens/sec with frontier-level accuracy.
Cerebras
@cerebras
Case study 📷 www.cerebras.ai/blog/case-study-cognition-x-cerebras
-
Cerebras
@cerebras
📽️ A five-person Cerebras team approached one of the world’s largest semiconductor manufacturers with a radical proposal — and TSMC backed the vision.
We recently won TSMC North America’s Innovation Zone Demo of the Year, earning the highest number of attendee votes across 43 showcased technologies. ⤵️This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Some of our top customers are still choosing Llama 3.1 8B.
For a while, we jumped to whatever hottest, latest model was taking up our twitter feed. 🙈
But as we are quickly realizing, to create a SOTA product, you need a model that fits your exact use case.
Here’s what our customers tell us:
> a lot of the legwork is actually around prompting
> there’s an art to selecting and combining multiple models
> benchmarks only show part of the picture. you have to understand the unique quirks of each model.
Especially as model releases become more and more frequent, we need a clear way to evaluate new models.
We have to break free of the naive trend to migrate to the ‘latest and greatest’. And you can easily achieve this using tools like @cerebras and @braintrust to swap models safely (without breaking production).This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Daria Soboleva
@dmsobol
8th Neural scaling workshop at @NeurIPSConf is wrapped!
Some observations 🧵
1/ @darkproger
(OpenAI) shared how gpt-oss was built and how to efficiently run 128 experts on a single h100. This was a significant move from OpenAI in the open-weights community.
2/ @waterluffy (MBZUAI) detailed how to optimize training LLMs and how to fight instabilities in training. As a community we are closing the gaps between open-source and closed source models, which is exciting.
3/ @mciccone_AI
(Vector Institute) showed how academia can solve scarce compute problem by federating Europe's scattered public clusters. I personally think this is going to be super impactful as there is a ton of abandoned hardware not being used bc there is no physical connection.
4/ @aurickq (Snowflake) presented Arctic inference and how suffix tree cache can generate 4x speedups (now available on
@vllm_project!) without losing the quality.
5/ I shared how we at @cerebras think about MoE models and where the efficiency gains are. MoEs are compute efficient, but not parameter efficient. They introduce a lot of redundancy that post-training needs to deal with. This is why looking at expert merging, pruning and quantization is important.
6/ @JustinLin610 (Qwen) shared how his team is approaching scaling models to higher intelligence. knowledge, code, math, context all matter. Make risky bets to win! Looks like NSA does not work, so don't use that :) Junyang is super down to earth and honest. Really appreciate your insights!
7/ Eric Sather (Cerebras) showed how expert merging leads to collapsed representations in MoE models, which hurts quality. Pruning should be your go-to strategy.
8/ @irinarish (CERC-AAI UdeM Lab/Mila/42.com) shared her students' work on inference optimizations. Looks like GPT-3 moment for time series models is yet to come!
9/ Ayush Kaushal (Nolano AI/Mila) discussed with us how to scale ternary models. What are the similarities with LLMs and how ternary can be more beneficial during the inference time. Was very insightful for me, would def read the paper in detail.
Meta highlights on "Sovereign AI" panel with reps from US, UAE, Canada, Armenia, Japan, Korea: "Sovereign" means different things. It's independence from other countries, capability, and benefits for citizens.
@sarahookr explained how low-resource languages benefit from popular ones through data scaling, but model capacity limits how many languages fit. Hrant Khachatrian noted Armenia's students now have more compute than MIT students, enabling cross-country collabs. @keunwoochoi shared how Korea's open-source contributions are critical for their government strategy.
Meta highlights on "AI: Show me the money" panel with reps across academia and industry. Is AI profitable? looks like it can be. @dylan522p and @swyx both agree that we already see profit in coding apps if you're #1. @tri_dao advises hw companies to make risky bets to compete with nvidia. @irinarish noted AGI has many definitions and is hard to optimize for, so it makes more sense to optimize software while developing AI capabilities to generate profits (@swyx). -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Market commentators love to talk about Nvidia's “CUDA lock-in.” But for AI Inference, it simply isn’t real, it’s a boogey man spoken about by those who simply don’t know.
This misconception shows up everywhere - analyst notes, investor memos and slide decks - it's everywhere except in anything written by people who actually use AI.
Inference is API-driven. There is no CUDA anywhere in an inference deployment.
To deploy inference you simply don’t need it.
You don’t need to rewrite kernels.
You don’t need to rebuild your model.
You don’t need to redesign your stack.
Moving an inference workload from GPUs to a competitor’s processor can be done in a handful of keystrokes. Teams do it every day. The friction is trivial because what matters in inference is the API surface, not anything else.
This is why the inference market is becoming genuinely competitive:
👍 Models are portable.
👍 Switching from a GPU to an accelerator costs nothing, and the gain is large.
👍 Performance decide winners - not software lock-in.
The real moat in inference is speed.
And Cerebras is the fastest in the world. -
Cerebras
@cerebras
Introducing Jais-2 - a major leap for Arabic AI. Co-developed with @G42ai , Inception, and @mbzuai, Jais-2 is a family of Arabic models built end-to-end on Cerebras from pretraining to inference.
Jais-2 70B runs at 2,000 tokens/sec – 20x faster than leading LLMs. It brings deep cultural grounding and dialect awareness to more than 400 million Arabic speakers worldwide.
Learn more: www.cerebras.ai/blog/jais2 -
Cerebras
@cerebras
Cerebras is showcasing nine new papers at NeurIPS 2025, spanning pretraining to inference:
1️⃣CODA – orchestrate 32B models to beat 235B models
2️⃣Calibrated Reasoning – 1-3x token savings in best-of-n sampling
3️⃣DREAM – 3.6× faster VLM inference using spec decode
4️⃣CompleteP – hyper parameter transfer from 2 to 128 layers
5️⃣Power Lines – scaling laws for weight decay and batch size
6️⃣PTPP-Aware Adaptation – predict adaptation performance before training
7️⃣Prot42 – generate protein binders from sequence alone, matching AlphaProteo
8️⃣Chem42 – design drug-like molecules for specific protein targets with 6x fewer parameters
9️⃣Gene42 – process 192k DNA base pairs at single-nucleotide resolution
Read our blog to learn more: www.cerebras.ai/blog/cerebras-at-neurips-2025-nine-papers… -
Cerebras
@cerebras
We set up a camera and asked @aiDotEngineer developers to CONFESS. The answers … speak for themselves.
Thank you @swyx, @dkundel, @altryne, @RealGeneKim! Until the next one…This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Cafe Compute has officially landed at @NeurIPSConf
@cerebras @OpenAI @BainCapVC, @mercor_ai and @sfcompute are teaming up for a lil shindig this Thursday.
Come see wafer IRL. -
Cerebras
@cerebras
If you want your team to actually use agentic GTM, it has to feel instant.
@rox_ai, one of the hottest AI agent startups serving the Fortune 2000, now routes its fast-path GTM workflows to Cerebras (~1,000 TPS).
The result: ultra-low-latency responses that drive real adoption and make Rox feel instantaneous.
Cerebras
@cerebras
Read more about how we enable real-time, cutting edge experiences at Rox, via @awsmarketplace: www.cerebras.ai/blog/rox-cerebras-real-time-speed-for-age…
-
Cerebras
@cerebras
Heading to @NeurIPSConf 2025?
📡 Cerebras is co-hosting the 8th Neural Scaling Workshop at NeurIPS 2025 with @mbzuai, @Mila_Quebec and CERC-AAI Lab.
Join us:
🔗 luma.com/gy51vuqd -
Cerebras reposted
Haikoo Khandor
@HaikooKhandor
Met the amazing @SarahChieng at Cafe Compute NYC today! Talked a bit about @cerebras and got to know about their chip, aka the world’s largest AI chip! Thank you for organising such a great networking event!
-
Cerebras reposted
-
Cerebras reposted
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
it's time to CONFESS
an inside look on Stanford's campus...on exactly what the next generation of engineers are up to 🫣
presented by @cerebras -
Cerebras
@cerebras
Cerebras inference 🚀 is now live in @Microsoft Marketplace 🛒
@Azure customers can now pair the Marketplace ecosystem with Cerebras speed, scale & quality for real-time search, voice, coding, agents & more.
Cerebras
@cerebras
👉Let’s go marketplace.microsoft.com/en-us/product/saas/12372016.cer…
-
Cerebras
@cerebras
After 9 years at NVIDIA, James Wang left and joined @cerebras.
In this Big Chip Club episode, @draecomino breaks down the bottlenecks of NVIDIA GPUs, and what's keeping them OUT OF first place...
Drop your follow-up questions below 👇This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
🚀🚀🚀🚀
UAE Embassy US
@UAEEmbassyUS
The UAE-US AI partnership is delivering results. The 5GW AI Campus with @Microsoft, @Cisco, @Oracle, @nvidia, @AMD, @Cerebras & @OpenAI is under construction, with the first phase of the 1GW Stargate UAE launching in 2026.
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Once again @cerebras is the fastest in the world in serving frontier open-weight models. @ArtificialAnlys shows GLM-4.6 on Cerebras at > 1400 tps/user.
By way of comparison to other frontier models, running on Cerebras, GLM-4.6 is 17x faster than Claude Sonnet 4.5, 25% lower cost, with comparable intelligence for many tasks including code editing, full-stack web dev, tool-calling, deep reasoning, refined writing, and more.
The pace of innovation in AI never ceases to amaze, with open models continually pushing the frontier every few weeks— when combined with the world’s fastest inference, new markets are born. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
After 9 years at NVIDIA, James Wang left and joined @cerebras.
In this Big Chip Club episode, @draecomino exposes the early days of NVIDIA, working with Jensen himself, and taking a bet on the next generation of compute.This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
My team at @cerebras is offering a free ticket with travel stipend to join us at @NeurIPSConf in San Diego Dec 2-7.
Tag a deserving researcher, builder, or yourself who would like to attend NeurIPS, and a link to their project. We will select a winner Nov 24.
And if you are already attending, come join us for a Cafe Compute -
Cerebras
@cerebras
GLM-4.6 is now live on Cerebras 🟧
- 1,000 TPS: 17x faster than Claude
- World’s #1 tool calling model
- Tasteful and reliable codegen
- Self-serve API starting at $10
Try it now: cloud.cerebras.aiThis media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Learn more: www.cerebras.ai/blog/glm
-
Cerebras
@cerebras
See you in St. Louis for @Supercomputing 25!
-
Cerebras reposted
Forward Future
@ForwardFuture
"We’d solved a problem the best in the world couldn’t solve in 75 years.”
Andrew Feldman, CEO of @Cerebras, on the moment everything changed.
“A decade ago, the entire system — hardware and software — was just an idea. For 18 months we spent $8 million a month and couldn’t make it work.”
“Our board stayed with us. Each failure we root-caused, figured out what went wrong, and tried again.”
“Then one day, it worked. We were standing in a small lab with the windows open and a hole drilled in the wall for hot air to escape. The five founders stood there for 30 minutes, speechless. We’d solved a problem the best in the world couldn’t solve in 75 years.” -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Today, the President of Guyana His Excellency Dr Mohamed Irfaan Ali and I signed an MOU to build a 100 MW AI data center - the largest in the Caribbean and one of the largest data centers in Latin America.
All in Guyana.
It’s a historic partnership - powered by clean energy from the country’s new Gas-to-Energy project.
This historic collaboration was in part facilitated by @exxonmobil who built the gas pipe from the deep water wells to land and leaders at @EYnews who have shared regional insight with me and are assisting in many ways.
The new facility will bring advanced AI computing power to Guyana - creating jobs, new skills, and a foundation for local innovation.
It will also enable Cerebras to serve much of Latin America and the eastern coast of the US at extraordinary low latency.
We’ll work side by side with the government to train engineers and use AI to improve education, healthcare, and agriculture across the country. This compute will catalyze collaborations across the Caribbean and South America. And will provide blazing fast AI inference to hundred of millions of people.
It’s also the first project in our @cerebras for Nations program - helping countries capitalize on somatic resources to build and operate their own AI infrastructure.
This is a statement of ambition by Guyana - a small nation putting its flag in the ground and declaring that it will lead the next great wave of technology.
I am honored to stand alongside President Ali and the people of Guyana as we take this bold step together. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
In a world where it’s now easier than ever to ship code you barely understand…
Codemaps generates an instant, hierarchical walkthrough of your repo so you stay in control.
In this Big Chip Club episode, @swyx demos @windsurf’s newest feature: the first tool built for human understanding, not just AI reasoning.
It’s pretty damn cool. And it’s powered by @cerebrasThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Introducing Cerebras for Nations, our global initiative to advance and scale sovereign AI.
How it works:
1️⃣ We will build world-class AI supercomputers with our WSE-3 chips and CS-3 systems
2️⃣ Co-develop state-of-the-art models and deploy with the world’s fastest inference
3️⃣ Invest locally in talent, education, and AI policy
Cerebras
@cerebras
Reach out to us www.cerebras.ai/press-release/cerebrasfornations
-
Cerebras reposted
Warp
@warpdotco
sponsoring Cafe Compute next friday ☕️ — come join us at the official after-party for AI Engineer Code Summit with @SarahChieng
late-night pop-up coffeeshop with a coffee cart ☕️, pies 🥧, snacks 🍿, and more
Warp is the AI-native HR and payroll platform for fast-growing companies. automate your payroll, benefits, HR, and compliance in one place
co-hosting with @cerebras, @BainCapital, @McKinsey, @modal , @getmetronome, @ExaAILabs
luma below -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
The Wall Street Journal is starting to see what we’ve seen at @cerebras for years.
The “reticle limit” - the boundary that defines how large a chip can be - has become the ceiling for progress.
It has kept chips the size of postage stamps for more than 20 years.
Every new generation of GPU comes with more parts, more wiring, and more overhead - all to work around the reticle limit.
The elegant solution is wafer-scale computing - a single piece of silicon the size of a dinner plate, not a postage stamp.
Wafer scale compute solves these problems. There is no maze of thousands of cables to interconnect a sea of tiny chips. No painful distributed compute complexity. Just raw, unified blazing fast compute.
That’s the world we’ve been building at Cerebras since 2015.
Our WSE-3 packs 4 trillion transistors on one wafer - 14× more than @nvidia biggest chip. Each WSE-3 contains 900,000 AI computer cores connected with a high performance low power on-chip fabric. And most importantly, the WSE-3 contains 2,625× the memory bandwidth of a GPU. Memory bandwidth is the source of speed in AI inference.
The reticle limit was the line.
Cerebras engineers are the only ones to have stepped across it. -
Cerebras reposted
Cerebras
@cerebras
Cerebras Code just got an UPGRADE. It's now powered by GLM 4.6
Pro Plans ($50):
300k ▶️ 1M TPM @ 24M Tokens/day
Max Plans ($200):
400k ▶️ 1.5M TPM @ 120M Tokens/day
Fastest GLM provider on the planet at 1000 tokens/s and at 131K context.
Get yours before we run out 👇 -
Cerebras
@cerebras
Cerebras beats Nvidia H100 but can it beat Blackwell?
Blackwell inference endpoints are finally out and it’s fast. It runs GPT-OSS-120B at ~700 tokens/s, leapfrogging H100 and Groq.
Cerebras clocked in at 3,000 TPS - still #1.
Looking forward to Rubin!
Cerebras
@cerebras
More in our blog:
www.cerebras.ai/blog/blackwell-vs-cerebras -
Cerebras
@cerebras
Behind the scenes with @swyx on how @windsurf built 20x faster search over your codebase
This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Forward Future
@ForwardFuture
What happens when you build a chip the size of a dinner plate?
That’s the Cerebras Wafer Scale Engine (WSE): 50× larger than a traditional chip and up to 30× faster. Its size allows memory to sit directly on the chip, cutting latency dramatically.
To house it, Cerebras built an advanced data center in Oklahoma City with two massive halls, hundreds of racks, all cooled to 70°F through a closed-loop system so efficient they actually have to heat the water to prevent condensation.
All of it is fortified by thick concrete walls to withstand tornadoes, protecting one of the fastest AI inference systems on Earth. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
What a fun little breakfast chat with @Swyx
Windsurf just released Fast Context.
Unlike traditional agentic search, Fast Context searches and retrieves relevant code from your codebase 20x faster.
Game changing for developers who want to stay in flow. Watch it in action inside Andrej Karpathy’s nanochat repo.
All over a bowl of Swyx's favorite childhood cereal, Raisin Bran. Powered by @cerebras.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
🔧 Just deployed additional speed optimizations for
@cognition SWE-1.5. The fastest measured request was an eye watering 1,881 token/s per Grafana dashboard. 🤯🤯 -
Cerebras
@cerebras
Even frontier models fail all the time. The difference is we fail in 15 sec and with one more prompt you get the right answer. Time to success = 30 sec.
On GPT Codex it takes 22min just to find out it failed. 🫠
Theo - t3.gg
@theo
Just ran the same prompt with Windsurf's new SWE-1 model and gpt-5-codex
gpt-5-codex took over 22 minutes. SWE-1 took under 15 seconds.
Neither worked 🙃 -
Cerebras
@cerebras
Sonnet but 10x faster 🟧
Soham Ratnaparkhi
@SohamR_7113
The SWE-1.5 is the best model I have used recently. It perfectly balances coding intelligence with speed.
It matches Claude Sonnet 4.5 thinking's intelligence, but is at least 10x faster. SWE-1.5 as a daily driver is too good to be true.
@cognition @windsurf are cooking like crazy since the acquisition.
Kudos to the team for making such an amazing model for coding. -
Cerebras reposted
Cognition
@cognition
Today we’re releasing SWE-1.5, our fast agent model.
It achieves near-SOTA coding performance while setting a new standard for speed. Now available in @windsurf. -
Cerebras
@cerebras
Today, @cognition released SWE-1.5 – the world’s fastest coding agent, powered by Cerebras.
SWE-1.5 achieves frontier-level coding ability, comparable to Sonnet 4.5 and surpassing GPT-5.
Cerebras and Cognition engineers worked hand in hand over the past few weeks, training a custom draft model for super-fast spec decoding and building a custom priority system for smoother agent sessions.
The result is the first coding agent that completes intricate software engineering tasks in 5-10 seconds instead of minutes. Going from start-stop coding to continuous flow is like using an AI computer ten years in the future.
We had an extraordinary experience working with the Cognition team. SWE-1.5 is available in @windsurf today. Be careful - you may never go back to slow coding agents again. -
Cerebras
@cerebras
GPT-OSS-Safeguard from @OpenAI is here.
Open-weight, safety-tuned, transparent reasoning.
Now available in private preview at Cerebras speeds⚡️
www.cerebras.ai/build-with-us -
Cerebras reposted
OpenAI Developers
@OpenAIDevs
gpt-oss-safeguard works with the same inference solutions as gpt-oss and will be available with some of our inference partners, including Ollama, LM Studio, Cerebra, and Groq.
OpenAI
@OpenAI
Now in research preview: gpt-oss-safeguard
Two open-weight reasoning models built for safety classification.
openai.com/index/introducing-gpt-oss-safeguard/ -
Cerebras
@cerebras
A beautiful Blackwell wafer from Nvidia.
Too bad it's cut into pieces after the photo is taken 😢 -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
cafe compute
sf/nyc's first late night coffeeshop for tech co-working
presented by @cerebras @BainCapVC @cognition @arena
the Rich
@Duderichy
they managed to make a nyc cafe with no women in it
incredible -
Cerebras
@cerebras
Do you want to use REAP models on Cerebras inference API?
-
Cerebras
@cerebras
Due to popular demand, we've released more REAP models! @Zai_org
➡️GLM4.6-FP8 REAP@25%
➡️GLM4.6-FP8 REAP@30%
➡️GLM4.6-FP8 REAP@40%
REAP is a one-shot pruning technique developed and open sourced by Cerebras. It compresses MoEs by up to 50% with minimal loss in coding ability. Links👇
Cerebras
@cerebras
Full model list huggingface.co/cerebras/models
Cerebras
@cerebras
-
Cerebras
@cerebras
Three figure speed is for GPUs
Ara
@arafatkatze
Qwen3 on Cerebras is 25 times faster than the next best alternative.
See for yourself(2518 TPS vs 102.6 TPS)
Cerebras
@cerebras
OpenRouter announces Exacto - model providers rigorously tested for tool calling accuracy.
Qwen3 Coder on Cerebras is certified exacto accurate.
And of course it's the fastest provider in the entire exacto universe.
OpenRouter
@OpenRouter
Exacto models + provider combos:
Kimi K2: @GroqInc and @Kimi_Moonshot
GLM-4.6: @novita_labs, @DeepInfra, and @Zai_org
gpt-oss-120b: Groq, DeepInfra, Novita
Qwen3 Coder: @baseten, @cerebras, and @GoogleAI
DeepSeek Terminus: @AtlasCloud_AI, DeepInfra, and Novita -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
This is a fun video about @cerebras' flagship data center in Oklahoma City. A massive AI deployment in a top tier, water cooled data center. @MatthewBerman and I have a fund conversation and dive into the details of AI deployments in massive data centers.
Matthew Berman
@MatthewBerman
We got to tour Cerebras' new datacenter and I got to interview their CEO:
0:00 Intro
0:55 Inside Cerebras
1:31 Location
2:39 Wafer Chip
3:36 How are they so fast?
4:16 Cooling
6:48 Power
10:23 2nd Data Hall
11:15 Building in the US
11:55 The toughest challenge
13:01 What's next?This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Cerebras inference growth on @huggingface
Reminds us of a certain Pink Floyd song.. -
Cerebras reposted
Matthew Berman
@MatthewBerman
We got to tour Cerebras' new datacenter and I got to interview their CEO:
0:00 Intro
0:55 Inside Cerebras
1:31 Location
2:39 Wafer Chip
3:36 How are they so fast?
4:16 Cooling
6:48 Power
10:23 2nd Data Hall
11:15 Building in the US
11:55 The toughest challenge
13:01 What's next?This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
OpenRouter announces Exacto - model providers rigorously tested for tool calling accuracy.
Qwen3 Coder on Cerebras is certified exacto accurate.
And of course it's the fastest provider in the entire exacto universe.
OpenRouter
@OpenRouter
Exacto models + provider combos:
Kimi K2: @GroqInc and @Kimi_Moonshot
GLM-4.6: @novita_labs, @DeepInfra, and @Zai_org
gpt-oss-120b: Groq, DeepInfra, Novita
Qwen3 Coder: @baseten, @cerebras, and @GoogleAI
DeepSeek Terminus: @AtlasCloud_AI, DeepInfra, and Novita -
Cerebras
@cerebras
Pay-as-you-go is now available on @awscloud Marketplace.
Use your AWS account—no upfronts, no lock-ins—to serve frontier models 20x faster than leading GPUs.
Cerebras
@cerebras
Easy to get started ➡️ aws.amazon.com/marketplace/pp/prodview-ph4bdvplhhz3o?appl…
-
Cerebras reposted
Daniel Kim
@learnwdaniel
Excited to talk about how cerebras makes tokens go zoom at ai benchmark club -- come by!
luma.com/3gd2lcxv?tk=CPtrDt -
Cerebras
@cerebras
In <1 minute, add evals, logging, and tracing to your inference stack so you can always
> pick the best model
> improve your prompts
> catch bugs
with @braintrustdata and Cerebras inference.
Avoid the AI deleting your entire codebase this halloween and remember, our free tier gets you 1M+ free toks/day per model.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
full docs here: inference-docs.cerebras.ai/integrations/braintrust
-
Cerebras reposted
LiquidMetal AI
@LiquidMetalAI
Today starts the AI Champion Ship Hackathon - A chance to win $35K+ cash, $35K+ credits, pitch to partners and Sequoia and Amplify, and more!
Partners include: @Vultr , @cerebras , @elevenlabs , @Netlify , @WorkOS , @stripe , Searchable, and @Cloudflare .
Deadline: December 7, 2025 -
Cerebras
@cerebras
🧮 What does 8×7B actually mean? It is NOT 8 experts with 7B active parameters per token.
Turns out it’s actually 13B active parameters.
But wait — where does 13B come from?
If you’ve ever tried to make sense of MoE math, our next post in the MoE 101 guide by @dmsobol (and interactive calculator) breaks it all down.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
In the world of Mixture of Experts (MoE), even the simplest questions get surprisingly complex:
❓ How much storage do you actually need?
❓ How much compute does that translate to?
❓ What are the real bottlenecks — memory, compute, or communication?
⁉️ And how does Cerebras solve GPU bottlenecks?
www.cerebras.ai/blog/moe-guide-calculator -
Cerebras
@cerebras
SWE-grep is truly some inspired ML from @cognition.
Take a 1M line codebase like React. With multiple fast inference calls on Cerebras, it can fetch & explain relevant code in seconds. Here are a few measurements taken on React, Vercel, PyTorch repos.
Cerebras
@cerebras
Try it on Fast Context playground
playground.cognition.ai -
Cerebras
@cerebras
No tricks, just treats from our ML team. 👻
Vithu Thangarasa
@vithursant19
(1/5) Compressing a 1T parameter MoE model by 50% with virtually no loss in quality is now possible.
Our new paper with @mikelasby @lzrvch @NishSinnadurai Sean Lie and @yanii introduces an expert pruning criterion for one-shot compression that aims to solve the memory bottleneck of these massive models, making them far more accessible for research and deployment. -
Cerebras
@cerebras
Cerebras is now powering Cognition's latest code retrieval models directly in @windsurf
Context retrieval has been one of the biggest bottlenecks in agentic coding. When you ask an agent to work on a large codebase, it can spend 60% of its time just searching for relevant files. This retrieval process not only keeps you waiting, but pollutes the context window with irrelevant snippets and racks up your inference bill.
Cognition trained two specialized, compact models using RL and deployed them on Cerebras for maximum speed. Querying huge ~1M line codebases like React, Vercel, and PyTorch, swe-grep finds relevant code snippets in a few seconds, compared to minutes on Claude and Cursor. End-to-end retrieval, reasoning, and summarization runs ~5x faster than today’s leading models.
Cognition’s Fast Context is available now in Windsurf Cascade. Cerebras is proud to be putting our wafer to work for every Cognition user! 🤝
Cognition
@cognition
Introducing SWE-grep and SWE-grep-mini:
Cognition’s model family for fast agentic search at >2,800 TPS.
Surface the right files to your coding agent 20x faster.
Now rolling out gradually to Windsurf users via the Fast Context subagent – or try it in our new playground! -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
it's your classic late night coffeeshop, but the coffee bar's free and we hired jump scare actors
but let's be real. nothing's scarier than NVIDIA's slow inference 👻
Presented by @cerebras @cognition @BainCapVC @arena -
Cerebras
@cerebras
Wanna hear a cool story? Our Oklahoma City datacenter was designed around water, not air. To keep our wafer-scale systems running at peak performance, we use a Tier III, 6,000-ton chilled-water plant inside a 100,000 sq ft F5-rated facility.
Unlike traditional air-cooled systems, our chilled-water design moves heat quietly and efficiently, even under the heaviest AI workloads.
It keeps hundreds of millions of cores perfectly balanced as they drive real-time inference at massive scale. A closed-loop system recycles and stores water, maintaining stable cooling without drawing on external sources...even when winds might hit 318 mph. 🌪️ -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
At 7, I won scariest halloween costume.
So naturally, we’re going all out for the next Cafe Compute — jump actors, face painters, trick-or-treating, and a live DJ
SF’s first late-night coffee shop for engineers, founders & writers. Join @cerebras, @BainCapVC & @arena on Oct 22.
(green wig & pointed hat not pictured) -
Cerebras
@cerebras
🟧 Cerebras Inference self-serve is finally here 🟧
– Pay by credit card starting at $10
– Run Qwen3 Coder, GPT OSS & more at 2,000+ TPS
– 20x the speed of GPU-based model providers
Go ahead. Melt our wafers.
cloud.cerebras.aiThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Core42
@core42_ai
Join Neha Gupta, Chief Financial Officer at Core42, and Julie Choi, Chief Marketing Officer at @cerebras, for an exclusive fireside chat exploring how Core42 Compass, accelerated by Cerebras, is redefining real-time AI for enterprise use cases from accelerating OSS model inference to enabling next-gen agentic applications.
📅 Thu, Oct 16 - 2:45 PM
📍 AI Hall, G42 District, Entrance H6, Stand B25
#core42 #cerebras #gitex2025 -
Cerebras
@cerebras
Not sure what events to go to for AI Tech week?
Our intern @KevinTaylor00 used @browser_use to scrape all of the events in record time.
With Cerebras, the agents can now take 30+ steps per minute.
⚡️Go give it a try. It's super fast ⚡️This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
The fastest inference in the world is coming to the world’s largest technology exhibition. Meet us at @GITEX_GLOBAL.
📍 Hall 3 | Booth H3-B12
📅 13 – 17 October 2025
📌 Dubai World Trade Centre (DWTC)
Cerebras
@cerebras
Featuring an exclusive fireside chat with @andrewdfeldman: The World’s Fastest AI Inference – Accelerating the Future of Agents and Reasoning
Cerebras
@cerebras
Want to meet the team? Get in touch: share-na2.hsforms.com/102tudzOjQ_2ZQJO_GGEr2A5c85x
-
Cerebras
@cerebras
On Friday, Cerebras withdrew our S-1. It had become stale and no longer reflected the current state of our business. Our business and financial position have evolved significantly for the better since our initial filing in 2024:
• In 2024, we achieved record revenues.
• In 2025 we are on track to achieve record revenues.
• Our inference business is growing exponentially.
We closed an 𝗼𝘃𝗲𝗿-𝘀𝘂𝗯𝘀𝗰𝗿𝗶𝗯𝗲𝗱 $𝟭.𝟭𝗕 𝗦𝗲𝗿𝗶𝗲𝘀 𝗚 𝗿𝗼𝘂𝗻𝗱 𝗹𝗲𝗱 𝗯𝘆 𝗽𝗿𝗲𝗺𝗶𝗲𝗿 𝗳𝗶𝗻𝗮𝗻𝗰𝗶𝗮𝗹 𝗶𝗻𝘃𝗲𝘀𝘁𝗼𝗿𝘀 — including Fidelity, Atreides, and Tiger Global — who are major investors in IPOs as well as late-stage private companies.
Withdrawing our S-1 was an 𝗮𝗱𝗺𝗶𝗻𝗶𝘀𝘁𝗿𝗮𝘁𝗶𝘃𝗲 𝘀𝘁𝗲𝗽. We will file a new offering document that better describes and reflects all these changes, including the new financing, at a time of our choosing.
Withdrawing and refiling an S-1 will have no impact on the planned timing of our IPO. -
Cerebras reposted
Shane Bergsma
@ShaneBergsma
(1/4)
@cerebras Hot off the presses 🔥📄arxiv.org/abs/2509.25087
If you're spending $1B to train an LLM, you need to know it’s on track—every step of the way.
With optimal AdamW τ + fixed TPP, loss curves collapse to a universal path → an early-warning signal for training. -
Cerebras reposted
Daniel Kim
@learnwdaniel
2000 tokens/sec gives me dopamine high on @opencode
-
Cerebras
@cerebras
Cerebras CEO @andrewdfeldman joined Caroline Hyde and Ed Ludlow on Bloomberg @technology to discuss how our wafer-scale chips and $1.1B Series G round are reshaping the future of AI infrastructure.
📺 Watch the full conversation:
www.bloomberg.com/news/videos/2025-09-30/ai-chip-maker-ce… -
Cerebras
@cerebras
Cerebras 🤝 @NasdaqExchange
-
Cerebras
@cerebras
Sonnet 4.5 can code for 30 hours.
That's 30 GPU hours.
aka 3 Cerebras hours tops.
Yuchen Jin
@Yuchenj_UW
Claude Sonnet 4.5 runs autonomously for 30+ hours of coding?!
The record for GPT-5-Codex was just 7 hours.
What’s Anthropic’s secret sauce? -
Cerebras reposted
murat 🍥
@mayfer
i've arguably got more work value out of cerebras thx to gpt-oss & qwen-coder, than i got from incremental improvements from claude 3.5>4.5
a 3s turnaround time vs 3min is a qualitative difference. the slow smart model is still essential to get unstuck, but not every step along the way is about being stuck. when the work is clear, tedious, and needs lots of iterative feedback, the fast-and-smart-enough really shines
Cerebras
@cerebras
Over the past year, @cerebras has delivered 20x faster inference than Nvidia GPUs, powering GPT-OSS-120, Llama, Qwen, DeepSeek & more at 2k–3k tok/sec.
We’re serving trillions of tokens/month via our cloud, on-prem, & partners like @awsmarketplace, @IBM, @huggingface, @openrouter and @vercel.
Today we announced $1.1B Series G at $8.1B valuation to accelerate our mission: building the world’s fastest AI infra for the world's fastest and best builders. -
Cerebras
@cerebras
Over the past year, @cerebras has delivered 20x faster inference than Nvidia GPUs, powering GPT-OSS-120, Llama, Qwen, DeepSeek & more at 2k–3k tok/sec.
We’re serving trillions of tokens/month via our cloud, on-prem, & partners like @awsmarketplace, @IBM, @huggingface, @openrouter and @vercel.
Today we announced $1.1B Series G at $8.1B valuation to accelerate our mission: building the world’s fastest AI infra for the world's fastest and best builders.
Cerebras
@cerebras
Full release: www.cerebras.ai/press-release/series-g
Cerebras
@cerebras
Just wanna build? Get your API key: cloud.cerebras.ai
-
Cerebras
@cerebras
Cerebras is proud to announce our record $𝟭.𝟭𝗕 𝗦𝗲𝗿𝗶𝗲𝘀 𝗚 𝗮𝘁 𝗮𝗻 $𝟴.𝟭𝗕 𝘃𝗮𝗹𝘂𝗮𝘁𝗶𝗼𝗻. As builders of the world’s fastest AI infrastructure, we’re scaling to meet explosive demand.
Funding will accelerate:
🚀 Breakthrough 𝗔𝗜 𝗽𝗿𝗼𝗰𝗲𝘀𝘀𝗼𝗿 𝗱𝗲𝘀𝗶𝗴𝗻, 𝗽𝗮𝗰𝗸𝗮𝗴𝗶𝗻𝗴, 𝘀𝘆𝘀𝘁𝗲𝗺𝘀, 𝗮𝗻𝗱 𝘀𝘂𝗽𝗲𝗿𝗰𝗼𝗺𝗽𝘂𝘁𝗲𝗿𝘀
🚀 Expansion of 𝗨.𝗦. 𝗺𝗮𝗻𝘂𝗳𝗮𝗰𝘁𝘂𝗿𝗶𝗻𝗴 𝗰𝗮𝗽𝗮𝗰𝗶𝘁𝘆 and 𝗴𝗹𝗼𝗯𝗮𝗹 𝗱𝗮𝘁𝗮 𝗰𝗲𝗻𝘁𝗲𝗿 footprint
🚀Growth of 𝗖𝗲𝗿𝗲𝗯𝗿𝗮𝘀 𝗜𝗻𝗳𝗲𝗿𝗲𝗻𝗰𝗲 𝗮𝗻𝗱 𝗧𝗿𝗮𝗶𝗻𝗶𝗻𝗴 to meet explosive demand
The round was led by 𝗙𝗶𝗱𝗲𝗹𝗶𝘁𝘆 𝗠𝗮𝗻𝗮𝗴𝗲𝗺𝗲𝗻𝘁 & 𝗥𝗲𝘀𝗲𝗮𝗿𝗰𝗵 𝗖𝗼𝗺𝗽𝗮𝗻𝘆 and 𝗔𝘁𝗿𝗲𝗶𝗱𝗲𝘀 𝗠𝗮𝗻𝗮𝗴𝗲𝗺𝗲𝗻𝘁, with participation from 𝗧𝗶𝗴𝗲𝗿 𝗚𝗹𝗼𝗯𝗮𝗹, 𝗩𝗮𝗹𝗼𝗿 𝗘𝗾𝘂𝗶𝘁𝘆 𝗣𝗮𝗿𝘁𝗻𝗲𝗿𝘀, 𝟭𝟳𝟴𝟵 𝗖𝗮𝗽𝗶𝘁𝗮𝗹, 𝗔𝗹𝘁𝗶𝗺𝗲𝘁𝗲𝗿, 𝗔𝗹𝗽𝗵𝗮 𝗪𝗮𝘃𝗲, and 𝗕𝗲𝗻𝗰𝗵𝗺𝗮𝗿𝗸.
👊 Let's go! cerebras.ai/press-release/series-g
Cerebras
@cerebras
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
If a prototype takes a day, waiting a week for user feedback is "really painful," said Andrew Ng.
Well....now you can get user feedback in under 60 seconds :)
Whether you're prototyping a feature or building a full fledged product, learn how to build an AI-powered user research system that automatically generates user personas, conduct interviews, and synthesize insights. All in <60 seconds.
Includes a full code notebook, recorded tutorial, and docs.
The stack
🤖 @cerebras fast inference
🤖 @langchain's LangGraph for orchestrating multi-agent workflows
🤖 @langchain's LangSmith for tracing and evaluating
Andrew Ng
@AndrewYNg
The invention of modern writing instruments like the typewriter made writing easier, but they also led to the rise of writer’s block, where deciding what to write became the bottleneck. Similarly, the invention of agentic coding assistants has led to a new builder’s block, where the holdup is deciding what to build. I call this the Product Management Bottleneck.
Product management is the art and science of deciding what to build. Because highly agentic coding accelerates the writing of software to a given product specification, deciding what to build is the new bottleneck, especially in early-stage projects. As the teams I work with take advantage of agentic coders, I increasingly value product managers (PMs) who have very high user empathy and can make product decisions quickly, so the speed of product decision-making matches the speed of coding.
PMs with high user empathy can make decisions by gut and get them right a lot of the time. As new information comes in, they can keep refining their mental models of what users like or do not like — and thereby refine their gut — and keep making fast decisions of increasing quality.
Many tactics are available to get user feedback and other forms of data that shape our beliefs about users. They include conversations with a handful of users, focus groups, surveys, and A/B tests on scaled products. But to drive progress at GenAI speed, I find that synthesizing all these sources of data in a PM's gut helps us move faster.
Let me illustrate with an example. Recently, my team debated which of 4 features users would prefer. I had my instincts, but none of us were sure, so we surveyed about 1,000 users. The results contradicted my initial beliefs — I was wrong! So what was the right thing to do at this point?
- Option 1: Go by the survey and build what users told us clearly they prefer.
- Option 2: Examine the survey data in detail to see how it changes my beliefs about what users want. That is, refine my mental model of users. Then use my revised mental model to decide what to do.
Even though some would consider Option 1 the “data-driven” way to make decisions, I consider this an inferior approach for most projects. Surveys may be flawed. Further, taking time to run a survey before making a decision results in slow decision-making.
In contrast, using Option 2, the survey results give much more generalizable information that can help me shape not just this decision, but many others as well. And it lets me process this one piece of data alongside all the user conversations, surveys, market reports, and observations of user behavior when they’re engaging with our product to form a much fuller view on how to serve users. Ultimately, that mental model drives my product decisions.
Of course, this technique does not always scale. For example, with programmatic online advertising in which AI might try to optimize the number of clicks on ads shown, an automated system conducts far more experiments in parallel and gathers data on what users do and do not click on, to filter through a PM's mental model of users. When a system needs to make a huge number of decisions, such as what ads to show (or products to recommend) on a huge number of pages, PM review and human intuition do not scale.
But in products where a team is making a small number of critical decisions such as what key features to prioritize, I find that data — used to help build a good mental model of the user, which is then applied to make decisions very quickly — is still the best way to drive rapid progress and relieve the Product Management Bottleneck.
[Original text: www.deeplearning.ai/the-batch/issue-310/ ] -
Cerebras reposted
Isaac Tai 🧇
@hi_im_isaac_
me building a game in TWO MINUTES during my lunch break with Cerebras Code
This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Build Your Own Deep Research...20x faster than ChatGPT
Learn how to build a deep research assistant that can automatically search the web, analyze multiple sources, and provide structured insights in under 60 seconds.
Includes a full code notebook, recorded tutorial, and docs.
The stack:
⚡@cerebras fast inference
📷@ExaAILabs web search -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Build a real-time AI Voice Agent that can actually sell.
In less than 30 minutes, you'll learn how to build a sophisticated real-time voice sales agent that can have natural conversations with potential customers.
Includes a full code notebook, recorded tutorial, and docs
The stack:
⚡ @cerebras fast inference
🎙 @livekit for real-time audio/video infrastructure
🗣 @cartesia realistic speech synthesis (STT/TTS) -
Cerebras reposted
Daniel Kim
@learnwdaniel
$200/month gets you the Ferrari of vibe coding.
Dozens of tool calls, instantly handled with 1.5M TPM on Cerebras Code Max available now!This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Cafe Compute has officially landed in NYC
By popular demand, we're excited to expand! Some behind the scenes with @amandamhuang
And a huge thank you to our partners @BainCapVC, @cerebras, @StructifyAI, @ExaAILabs, @floraai, @sfcompute, @haizelabs
Where should we go next?This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Meet OKC: the World's Fastest AI Datacenter, powered by Cerebras. Located in the heart of Oklahoma, our OKC datacenter is delivering over 40 ExaFlops of AI compute. That's trillions of tokens per second for AI developers to build with.
Read @andrewdfeldman's blog:Post not available here, view on X
Cerebras
@cerebras
With trusted partners like Scale Datacenter, we have turned vision into reality. From America’s heartland to the world, Cerebras is delivering the fastest AI infrastructure ever built. Many thanks to the Oklahoma Chamber of Commerce and Expand Energy for joining us today!
Cerebras
@cerebras
The breakthroughs that will define the next decade of AI in medicine, science, energy, and beyond will begin in Oklahoma City at our new state-of-the-art datacenter. Onward!
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
WE'RE HOSTING A 6 MONTH HACKATHON
Well… sorta.
On NVIDIA, building your project would take half a year. Luckily, we're 20x faster so it'll only take you 1 week 🤷♀️
️
Join @cerebras , @Meta, @Docker, and @WeMakeDevs for the ultimate 7-day virtual hackathon.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
AI coding tools have gone viral for accidentally wiping out entire codebases in one go.
Now, @Docker and Cerebras have teamed up to fix this: spin up safe sandboxes and develop with lightning-fast inference for complete peace of mind.
With Cerebras’ inference speed, teams can build and evaluate new code quickly while keeping experiments safe, repeatable, and far, far away from your production database.
Read more here: www.cerebras.ai/blog/DockerComposeThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
🧮 Calling all Mathletes, this one is for you.
We’ve been asked to show the math behind our MoE claims. So we did. Our analysis confirms:
On GPUs, expert parallelism creates severe communication overheads that dwarf computation and make MoE training painfully slow.
At Cerebras, we avoid model parallelism entirely, but sparsity subdivides batches and leaves experts I/O bound.
With BTA, we fix it. By decoupling batch size requirements across experts and attention layers, we remove the bottleneck.
@dmsobol breaks it down.
Cerebras
@cerebras
If you haven't read part 4: www.cerebras.ai/blog/moe-guide-scale
-
Cerebras
@cerebras
Get started now 👉
github.com/charmbracelet/crush -
Cerebras reposted
WeMakeDevs
@WeMakeDevs
Early registrations are open for our biggest hackathon yet, the FutureStack GenAI Hackathon, in collaboration with @cerebras, @Meta, and @Docker.
This month, developers from across the globe will come together for an online hackathon packed with prizes, learning, and opportunities you won’t want to miss.
Winners can look forward to:
💰 Major cash prizes
👀 An interview opportunity with Cerebras
☕ A coffee chat with Meta engineers
🎁 Swag and more surprises to be announced
No matter your background, you’ll have access to the tools, support, and mentorship to kickstart your GenAI journey. You can team up or compete solo, this is where the next big ideas begin.
👉 Register early and secure your spot today: www.wemakedevs.org/hackathons/futurestack25 -
Cerebras
@cerebras
This is wafer scale coding
cerebras.ai/code
Nathan Flurry 🔩
@NathanFlurry
@cerebras at 2,200 tokens/second with @opencode currently holds the crown for hands down the coolest demo
Cannot wait for Cerebras to scale up to be able to use this for everything -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Free, instant access to 1M inference tok/day
@cerebras inference is 20x faster than on NVIDIA. You probably don't even know what that feels like.
Now you can chat.cerebras.ai
Building our new chat and showcase were so fun to ship. I promise this will be your *holy shit* moment of 2025.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
K2 Think is now available and runs fastest on Cerebras Inference at 2,000 TPS on Cerebras – 20x faster than GPU.
Launched by @mbzuai and @G42ai, K2 Think is a world leading open-source reasoning model that beats GPT OSS 120B and DeepSeek on math and reasoning.
Cerebras
@cerebras
Just 32B parameters - proving smaller models can be smarter, beating 10x larger models with deeper reasoning
Cerebras
@cerebras
Try it today: www.cerebras.ai/k2think
Cerebras
@cerebras
K2 Think is available through MBZUAI K2-Think app - www.k2think.ai/k2think
-
Cerebras reposted
Kunal Kushwaha
@kunalstwt
Want to learn about Generative AI but not sure where to begin?
In this video, I’ll walk you through the basics step by step, what GenAI is, how Large Language Models (LLMs) work, what tokens mean, and why AI chips are so important.
I’ll show you a hands-on demo: building the world’s fastest coding assistant on @cerebras, the world’s biggest and fastest AI chip, that writes 1,000 lines of JavaScript in just 4 seconds, completely free! 👨💻
👉 Watch here: youtu.be/4ulWHZlBe8Q
PS: Two big announcements at the start of the video that you don’t want to miss! 👀 -
Cerebras reposted
Alex Volkov
@altryne
NEW: K2 Think from MBZUAI (read: not Kimi K2, this is a different K2) is out.
Apparently this is a finetune of Qwen 2.5 based on @llm360 practices.
With impressive Math and Code scores for a 32B model, the offer it for free, powered by Cerebras! 🔥
MBZUAI
@mbzuai
Introducing K2 Think - a breakthrough in advanced AI reasoning.
Developed by MBZUAI’s Institute of Foundation Models and @G42ai, K2 Think delivers frontier reasoning performance at a fraction of the size of today’s largest systems.
Smaller. Smarter. Open to the world.
Available now: k2think.ai/K2Think
#k2think #ai #opensource #mbzuai #g42 #innovationThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Cerebras Code Plans are open for business and massively upgraded.
Pro Plans ($50):
165k▶️300k TPM @ 24M Tokens/day
Max Plans ($200):
300k▶️400k TPM @ 120M Tokens/day
More vibing, more tokens. Keep sending us feedback!
Dylan Patel
@dylan522p
To all the inference providers out there
Cerebras
@cerebras
More information on our coding plans here 👇
cerebras-inference.help.usepylon.com/articles/9996007307-… -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Cafe Compute is finally coming to NYC!
the first, regular late-night coffeeshop for engineers, founders, writers...(anyone) to co-work or hangout late at night 🗽☕️
free coffee cart, food, and more
presented by @cerebras @BainCapital @StructifyAI @haizelabs @sfcompute @floraai @ExaAILabs -
Cerebras reposted
-
Cerebras
@cerebras
What does Cerebras do?
We take reasoning models and make them run at the speed of instruct models.
No coffee breaks while ur model is 'planning'.
No switching tasks while ur model is 'thinking'.
Test time compute is done in 2s tops.
Lock in and do your work. -
Cerebras
@cerebras
MoE 101 - Episode 4: Theoretical: 60% fewer FLOPs. Reality: 7x slow down
You followed all the tips from our last video. Your MoE model finally trains…
Then you try to scale it on GPUs...and... memory issues ❌, underused experts ❌, unpredictable compute bottlenecks ❌.
From expert parallelism on the GPU to BTA techniques on the Cerebras, @dmsobol breaks it down: www.cerebras.ai/blog/moe-guide-scale -
Cerebras
@cerebras
⚡️Grok fast vs. Cerebras fast⚡️
Grok Code Fast: 160 TPS, $1.5/M tokens
Cerebras Qwen Coder: 2,000 TPS, $2/M tokens
Cerebras: 13x faster, 33% higher cost, ~9x better price-
performance -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Stop hosting bad events
I’ve been hosting events as part of my role as a growth engineer at @cerebras. I’m nearing my 1 year mark, and thought I’d share some of my favorite parts of hosting a good event
7 TIPS & TRICKS
1. piggyback on what people already have to do
2. start with an MVP event
3. host a series
4. people notice small details
5. hacks to maximize ROI
6. how to bring in partners
7. tricks to being a good host
I made a guest post on @swyx's blog @DXTipsHQ
Read here: dx.tips/hosting -
Cerebras
@cerebras
"But Cerebras hardware costs millions"
My man, it's 25c per M tokens for OSS 120B. Let us worry about the hardware bill, you enjoy the 3,000 TPS tokens. -
Cerebras
@cerebras
Introducing Fast Deep Coder by @NinjaTechAI - a coding agent with its own cloud VM
‣ Sonnet-level capability (69.6% SWE-bench)
‣ 5–10x faster using Qwen3 Coder on Cerebras
‣ Runs in a persistent cloud VM, freeing up your laptop
‣ Native GitHub integration
Try it here:This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Blog & evals:
www.ninjatech.ai/blog/fast-deep-coder -
Cerebras
@cerebras
Introducing ⚡️Cerebras MCP Server ⚡️
You can now turbocharge any AI editor that uses MCP for tool calling with 20x faster inference.
Here is Claude Code writing files at breakneck speed via Cerebras.
Get started now 👇This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
-
Cerebras
@cerebras
🎂 Cerebras Inference turns 1! 🚀
Let's break it down:
- 6x faster than when we launched — From @Meta Llama to @Alibaba_Qwen 3 to @OpenAI OSS, models running on Cerebras deliver 𝟯,𝟬𝟬𝟬+ 𝘁𝗼𝗸𝗲𝗻𝘀/𝘀𝗲𝗰
- Our inference powers the best AI natives, global enterprises, and developers including Meta, @IBM , AlphaSense, @Docker, @GSK , Mayo Clinic, Core42, @vercel and more
- Largest model served: ~half a trillion parameters, 7x bigger than launch
- #1 provider of tokens on @huggingface 🤗
- Serving billions of tokens per day on @openrouter
- The leading code gen inference provider, powering AI developers with @Cline and @windsurf
We’re just getting started… but couldn’t have done Year 1 without YOU. Build on, builders. ❤️🔥
inference.cerebras.ai -
Cerebras
@cerebras
Bankers & consultants spend days on financial models. At Cerebras, we did it in under 2 seconds.
Watch us run what is most likely the fastest financial model ever recorded in Excel.
@jpmorgan @GoldmanSachs your move.
Want to break your own speed record? sign up for an API key here: cloud.cerebras.ai
Cerebras
@cerebras
Repository: github.com/ianb-cerebras/financial-modeler
-
Cerebras reposted
EPCC
@EPCCed
We’re getting ready to host @IEEECluster 2025 in Edinburgh next week. Among the highlights will be keynotes from Natalia Vassilieva (@cerebras); Rosa Badia (@BSC_CNS) and Garth Wells (@Cambridge_Uni ). Talk abstracts: edin.ac/41qm0K9
-
Cerebras
@cerebras
MoE 101 - Episode 3: You don’t need Google-scale compute to train effective MoE models
We proved it with a hands-on experiment that beats dense GPT-2 scale model. @dmsobol will show you how with methodology (and debugging secrets)
Cerebras
@cerebras
Step by step: www.cerebras.ai/blog/moe-guide-debug
Cerebras
@cerebras
From the beginning: www.cerebras.ai/moe-guide
-
Cerebras
@cerebras
Flappy Bird but the pipes are toxic texts from your ex. Every flap = emotional growth, every dodge = drama avoided. Built in 10 seconds with Cerebras and @cline.
High score: inner peace.
Experience instant vibe coding and emotional freedom for free at cerebras.ai/clineThis media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Play it here: deluxe-cheesecake-3e4f69.netlify.app
-
Cerebras
@cerebras
The first Nvidia Blackwell results for GPT OSS 120B are out! @ArtificialAnlys ran Cerebras vs. Nvidia head to head:
Blackwell DGX B200: 1 user = 900 TPS, 10 users = 580 TPS
Cerebras CS-3: 1 user = 2790 TPS, 10 users = 2740 TPS
Also, Cerebras is live in production.
Cerebras
@cerebras
There was a limitation in the previous measurement harness for 10 parallel users on Cerebras. It got fixed last night and now our results are as good as n=1. Before and after illustration:
-
Cerebras reposted
Cerebras
@cerebras
Introducing the new ✨Cerebras Referral Program✨
+200K Qwen3 Coder tokens/day for you.
+200K Qwen3 Coder tokens/day for your friends.
Up to 1M additional free tokens every single day
Start building with Qwen3 Coder, completely free! -
Cerebras
@cerebras
Cerebras had its best week ever on @openrouter this week. The top three models according to the people:
1️⃣ OpenAI GPT OSS 120B
2️⃣ Qwen3 32B
3️⃣ Qwen3 235B Instruct
What have you been building? Show us👇 -
Cerebras
@cerebras
As of Aug 21, 2025 Sarah and Isaac are no longer friends....
Here's what happened.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Introducing the new ✨Cerebras Referral Program✨
+200K Qwen3 Coder tokens/day for you.
+200K Qwen3 Coder tokens/day for your friends.
Up to 1M additional free tokens every single day
Start building with Qwen3 Coder, completely free! -
Cerebras
@cerebras
Tips and tricks for using gpt-oss
In 2 minutes, @dkundel and @SarahChieng cover the top secrets to get the most out of gpt-oss -- from prompting, deployment tricks, and more.
Try it out today at over 3000 tok/s at cloud.cerebras.ai :)This media couldn't be displayed. See it on the original post. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
In the same week, @OpenAI dropped their first open model series gpt-oss AND the much awaited gpt-5...
In 2 minutes, @DKundel from OpenAI and I break down how developers should decide between the two models -- use case, cost, reliability, and more.
Try out gpt-oss for free on @cerebras at cloud.cerebras.aiThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Cerebras is now the🥇inference provider on @huggingface serving 5M monthly requests
clem 🤗
@ClementDelangue
Just crossed 20M monthly requests with @huggingface inference providers, our router for open models.
@cerebras @novita_labs & @FireworksAI_HQ are growing the fastest!
It's now powering the official open playground from @OpenAI & integrate with apps like @cline & @roocode.
Let's go!
Cerebras
@cerebras
-
Cerebras reposted
Leandro von Werra
@lvwerra
Excited to release: Jupyter Agent 2
The agent can load data, execute code, plot results inside Jupyter faster than you can scroll!
🤖 Powered by Qwen3-Coder
⚡️ Running on Cerebras
⚙️ Executed in E2B
↕️ Upload your files
All videos are in *real time*!
hf.co/spaces/lvwerra/jupyter-agent-2This media couldn't be displayed. See it on the original post. -
Cerebras reposted
GosuCoder
@GosuCoder
Here is an *early* run of testing tool calling on providers on Qwen 3 Coder on OpenRouter. There is runtime variance, so i'll need to smooth that out.
What I'm testing:
• How well AI models can actually USE TOOL
• Testing Real native tool calling in long message chains
• Tests if models call the right tools with correct parameters
Key Metrics:
• Tool Recall: Did it call the tools it was supposed to? (Higher = better)
• Tool Precision: Were the tools it called actually needed? (Higher = better)
• Parameter Accuracy: Did it use the right values? (Higher = better)
• Scenario Success: Did complete workflows actually work? (Higher = better)
Final Score Calculation:
• Combines 5 metrics: Scenario Success + Tool F1 + Parameter Accuracy (structural) + Parameter Accuracy (semantic) + Execution Success
• Each weighted equally, averaged to 0-100%
• A+ = 90%+, A = 85%+, B = 70%+
Results show huge differences between providers, but again remember there will be a few percent runtime difference, but this is sick, now pair this with my tps tests. I think we can legit start objectively figuring out which provider we should be using.
Cost is one of the next things to figure out.
Also sorry its not sorted, but you can see @cerebras and Alibaba are actually very close in scoring. I have detailed breakdowns
On a final note:
I'm debating if I should do emulated tool calling as well (prompt based tool calling). -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Last week, @OpenAI dropped their first open model series — gpt-oss.
In 2 minutes, @DKundel from OpenAI and I break down what it is, why it matters, and how you can start building with it today.
Try out the models for free on @cerebras at cloud.cerebras.aiThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Introducing SuperNinja – the world’s fastest deep research by @NinjaTechAI powered by Cerebras:
‣ 1-2min for full answer instead of 10min
‣ 5x faster than o3, Gemini Pro etc.
‣ Same accuracy as measured by GAIAPost not available here, view on X
Cerebras
@cerebras
Faster inference is a different UX – users can ask follow up questions, update the report, and explore new data in the same time it takes for a traditional agent to generate a first draft report. In early testing, user engagement was 2x higher when using Cerebras Inference.
Cerebras
@cerebras
SuperNinja is launching today:
Try SuperNinja: super.myninja.ai
Read the research blog: www.ninjatech.ai/blog/superninja-cerebras-worlds-fastest-…
Build on Cerebras Inference: inference.cerebras.ai -
Cerebras
@cerebras
www.youtube.com/watch?v=So7TNRhIYJ8&t=7s
Sarah Chieng
@MilksandMatcha
What's @cerebras been cooking?
-
Cerebras
@cerebras
Our intern @KevinTaylor00 made diet coke game mobile responsive with @cline and Qwen3-Coder on Cerebras, instantly ✨
try it now 👉cerebras.ai/clineThis media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
We built Death by Diet Coke in less than 30 seconds using Cerebras Code Pro, where you get higher rate limits and more power for Qwen3-Coder.
We are opening the same number of Cerebras Code Pro/Max plans as diet coke cans in the office.
First come, first serve. -
Cerebras
@cerebras
We built Death by Diet Coke in less than 30 seconds using Cerebras Code Pro, where you get higher rate limits and more power for Qwen3-Coder.
We are opening the same number of Cerebras Code Pro/Max plans as diet coke cans in the office.
First come, first serve. -
Cerebras
@cerebras
What's your favorite model on Cerebras right now?
-
Cerebras
@cerebras
Deployed some more capacity and we are so back
-
Cerebras
@cerebras
Here’s what nobody tells you about MoE: the router can single-handedly destroy your model. You can have perfect expert network architecture, tuned hyperparameters, and unlimited compute, but if your router collapses, you’re back to dense model performance regardless of number of experts you choose.
So... your shiny new routing method fails at 3am during a multi-million-dollar training run. You wished something existed to help with debugging...
@dmsobol is here with the assist!
With production-scale MoE now in the open, like @OpenAI's gpt-oss-120B, understanding routing isn’t just academic. It’s the key to scaling these models
Read the latest in our MOE Guide: "Router Wars: Which MoE Routing Strategy Actually Works"
www.cerebras.ai/blog/moe-guide-router -
Cerebras
@cerebras
Come build some really cool stuff with super fast inference ⚡️⚡️
rsvp 👉 partiful.com/e/hUU7NyM8EjHLxjMuJROs
Cognition
@cognition
Lots of new frontier models this week. So this Sunday, we’re hosting the Applied AI Hackathon in SF to push the limits of what’s possible.
$100,000 in prizes. Judges including @karpathy and @swyx.
12 hours to build something that shouldn’t exist yet.
Details & how to join👇 -
Cerebras
@cerebras
one shot vibe coding with gpt-oss-120b through anycoder by @huggingface.
the future is here
Cerebras
@cerebras
try it now 👉huggingface.co/spaces/akhaliq/anycoder
-
Cerebras reposted
AK
@_akhaliq
vibe coding a Qwen3-4B-Instruct-2507 @Alibaba_Qwen chat app
Qwen3-Coder-480B-A35B-Instruct with @cerebras one shotted it and one click deployed on Hugging Face through anycoder -
Cerebras
@cerebras
GPT OSS 120B is a reasoning model
But we run it so fast it it feels like an instruct model -
Cerebras reposted
Vaibhav (VB) Srivastav
@reach_vb
The best open model currently available on Inference Providers, blazing fast! Powered by @cerebras 🔥
Try it out today!
Vaibhav (VB) Srivastav
@reach_vb
OpenAI COOKED! That's an Apache 2.0 licensed 120B apache 2.0 licensed model competing with OpenAI O3 🤯
> 120B and 20B models
> 128K context
> First open model to be able to tool call in CoT
> Released with optimised kernels
Apache 2.0 license! What a landmark release - Kudos @OpenAIDevs 🤗 -
Cerebras
@cerebras
OpenAI GPT-OSS-120B is live on Cerebras
3,000 tokens/s - fastest OpenAI model on record
1 second reasoning time
131K context
Go build something fantastic.
inference.cerebras.ai
Cerebras
@cerebras
Live on OpenRouter
OpenRouter
@OpenRouter
Today, OpenAI returns to open source! 🚀
Excited to be a launch partner for gpt-oss, OpenAI’s new open-weight models with variable reasoning.
First providers are @FireworksAI_HQ, @GroqInc, and @cerebras, with more to come! Here’s what's launching today 👇
Cerebras
@cerebras
Chat app is a little slow right now. We are seeing ~3700 TPS on OpenRouter
inference-docs.cerebras.ai/models/openai-oss -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
In 2016, @sama and I first met. @OpenAI was a vision. @cerebras was powerpoint. Sam and the OpenAi founders became one of the early investors in @cerebras.
In the following years, the Cerebras and OpenAI frequently met to explore working together. But the timing was too early—LLMs hadn’t been invented yet.
Today, the story comes full circle. OpenAI just released its most powerful open weight reasoning model—and it runs fastest on Cerebras Systems. Not a little bit faster than the competition. It smokes the competition.
Running on our third generation Wafer Scale Engine, OpenAI gpt-oss-120B runs at up to 3,000 tokens/s – the fastest speed achieved by an OpenAI model in production. Reasoning that take minutes on @nvidia GPUs take a single second on Cerebras Systems.
Good things take time. -
Cerebras reposted
Daniel Kim
@learnwdaniel
Its super duper fast
Go try it!
Cerebras
@cerebras
OpenAI GPT-OSS-120B is live on Cerebras
3,000 tokens/s - fastest OpenAI model on record
1 second reasoning time
131K context
Go build something fantastic.
inference.cerebras.ai -
Cerebras reposted
-
Cerebras reposted
Cerebras
@cerebras
🏆@sherbondy built a Wordle Clone, fully vibe coded with @Cline powered by Cerebras.
Play as many times as you want — no need to wait 24 hours for another puzzle!
Try it now 👉 wordget.app -
Cerebras reposted
Cerebras
@cerebras
🏆 @arty_int created a real-time ASL translator, built with @Cline and powered by @Cerebras.
Instantly translate sign language into text and unlock a new era of accessibility.
See the repository here: github.com/drxyu/signtalk -
Cerebras
@cerebras
After a weekend of insane demand with lots of devs hitting our API, our Qwen Coder endpoint has been been running 24/7 at nearly 100% utilization since launch.
We’ve temporarily paused signups for Code Pro/Max plans while we scale.
Hang tight — we'll be back soon.
Cerebras
@cerebras
Cerebras Code: 20x faster than Claude, 1x the price
Today we are launching two monthly coding plans:
➡️Cerebras Code Pro: $50/m – for indie developers
➡️Cerebras Code Max: $200/m – for power users with 5x rate limits
Both plans get: Qwen3-Coder at 2,000 tokens/s, 131K context, and no weekly limits.
Sign up now: cerebras.ai/codeThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
We just wrapped up the @Cline × Cerebras hackathon—and it was amazing!
Over 800 developers came together to try instant vibe coding powered by Cerebras’ lightning-fast inference.
Here are the winners who crushed it with their projects:
Cerebras
@cerebras
🏆 @arty_int created a real-time ASL translator, built with @Cline and powered by @Cerebras.
Instantly translate sign language into text and unlock a new era of accessibility.
See the repository here: github.com/drxyu/signtalk
Cerebras
@cerebras
🏆@sherbondy built a Wordle Clone, fully vibe coded with @Cline powered by Cerebras.
Play as many times as you want — no need to wait 24 hours for another puzzle!
Try it now 👉 wordget.app -
Cerebras reposted
David Jensen
@davidjensen1990
📽️ Demo video: screen.studio/share/lS2nm5kM
🌐 Try it live: main.d1134qzwxlik4n.amplifyapp.com
Thanks to @cerebras and @Cline for the opportunity to build and share this at the hackathon!
#hackathon #knowledgegraph #opensource #ai #datascience -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Qwen3-Coder is now available on Cerebras, 17x faster than on GPU providers.
And it's completely free.
Try it out directly in your developer flow, or signup for our virtual hackathon tomorrow. It's a $5,000 prize :)
@cerebras @clineThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
We just launched an integration with @cline, the open-source coding tool that lets you code up to 20x faster than other providers.
That means you have a lot more free time. So what should you do with it?
How about win $5,000?
We’re hosting a hackathon tomorrow. Come build something fast—with all your new free time.
Sign up for Cerebras and join the hackathon.
Link here: lu.ma/8bgbzje8 -
Cerebras reposted
Artificial Analysis
@ArtificialAnlys
Cerebras has been demonstrating its ability to host large MoEs at very high speeds this week, launching Qwen3 235B 2507 and Qwen3 Coder 480B endpoints at >1,500 output tokens/s
➤ @cerebras now offers endpoints for both Qwen3 235B 2507 Reasoning & Non-reasoning. Both models have 235B total parameters with 22B active.
➤ Qwen 3 235B 2507 Reasoning offers intelligence comparable to o4-mini (high) & DeepSeek R1 0528. The Non-reasoning variant offers intelligence comparable to Kimi K2 and well above GPT-4.1 and Llama 4 Maverick.
➤ Qwen3 Coder 480B has 480B total parameters with 35B active. This model is particularly strong for agentic coding and can be used in a variety of coding agent tools, including the Qwen3-Coder CLI.
Cerebras’ launches represent the first time this level of intelligence has been accessible at these output speeds and have the potential to unlock new use cases - like using a reasoning model for each step of an agent without having to wait minutes. -
Cerebras
@cerebras
🟧🟨QWEN3 CODER is LIVE on Cerebras 🟨🟧
2,000 tokens/s - 20x faster than Sonnet
0.5s time-to-full-answer
131K context
$2 per M input/output tokens
Available in Cline, Windsurf & morePost not available here, view on X
Cerebras
@cerebras
Speed & latency are off the charts
artificialanalysis.ai/models/qwen3-coder-480b-a35b-instru…
Cerebras
@cerebras
One more thing - $50 and $200 plans:
Cerebras
@cerebras
Cerebras Code: 20x faster than Claude, 1x the price
Today we are launching two monthly coding plans:
➡️Cerebras Code Pro: $50/m – for indie developers
➡️Cerebras Code Max: $200/m – for power users with 5x rate limits
Both plans get: Qwen3-Coder at 2,000 tokens/s, 131K context, and no weekly limits.
Sign up now: cerebras.ai/codeThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
Devin Developers
@devindevelopers
Qwen3-Coder at ~2000 tokens/sec is now live in Windsurf! ⚡️
Fully hosted on US servers by @cerebras.
Video is 1x speed. -
Cerebras
@cerebras
Cerebras Code: 20x faster than Claude, 1x the price
Today we are launching two monthly coding plans:
➡️Cerebras Code Pro: $50/m – for indie developers
➡️Cerebras Code Max: $200/m – for power users with 5x rate limits
Both plans get: Qwen3-Coder at 2,000 tokens/s, 131K context, and no weekly limits.
Sign up now: cerebras.ai/codeThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
AK
@_akhaliq
Qwen3-235B Thinking @Alibaba_Qwen is live on anycoder using @cerebras
1700 TPS • 131K Context • 1.7s time-to-full-answer -
Cerebras
@cerebras
🟪 Qwen3-235B Thinking is live on Cerebras
1700 TPS • 131K Context • 1.7s time-to-full-answer
$0.6 | $1.2 per M tokens
Try chat: inference.cerebras.ai
Get API key: cloud.cerebras.ai
Pay-as-you-go via @huggingface
Cerebras
@cerebras
Thinking is now instant
1.7 seconds to: process 1,000 input tokens, think a lot, and return 500 output tokens.
Cerebras
@cerebras
Easy to deploy with HuggingFace Inference
huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507?inferen…
Cerebras
@cerebras
Qwen3 235B Thinking is live on @openrouter
To escape slow GPU speeds, use the 'only' 'provider' flags.
openrouter.ai/provider/cerebras -
Cerebras reposted
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Another late-night tech coffeeshop in the books
@amandamhuang and I are hosting our next Cafe Compute in NYC 🗽 :) Reply if you're interested in co-hosting or tag someone we should invite 👇👇
Presented by @BainCapital and @cerebras
Sarah Chieng
@MilksandMatcha
Over this last year, @amandamhuang and I started running 'Cafe Compute'
SF's first, regular late-night coffeeshop for engineers, founders, writers...(anyone) to co-work or hangout late at night.
We always bring in Bryan and Annie, two amazing baristas to serve free coffee and food, and it's been so nice to watch the community grow. It's now been a year of cafe computes, and we're excited to continue the series -- we'll be expanding to NYC and Vancouver (ICML) next :)
Please reach out if you'd ever like to attend or cohost.
Sponsored by @cerebras and @BainCapVC -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Just a little bit faster, just a little bit lower latency...@ArtificialAnlys this useful graphic with Latency versus Output Speed for the @alibaba_cloud new Qwen3 235B 2507 Instruct model...this is a frontier model with exceptional accuracy, and when serve by @cerebras, its blisteringly fast, with very low latency. Build fast with Cerebras Inference.
-
Cerebras
@cerebras
🟪 Qwen3-235B 2507 Instruct is live on Cerebras
1400 TPS • 131K Context • 230ms TTFT
$0.6 | $1.2 per M tokens
Try chat: inference.cerebras.ai
Get API key: cloud.cerebras.ai
Pay-as-you-go via @openrouterPost not available here, view on X
Cerebras
@cerebras
Our launch blog
www.cerebras.ai/blog/qwen3-235b-2507-instruct-now-availab…
Cerebras
@cerebras
Qwen3 235B Instruct on Cerebras is live on @huggingface
Add these 9 characters to make your model go 11x faster
huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507?inferen… -
Cerebras
@cerebras
Have 80 pages of docs you don’t want to read? Thankfully, we have @knowlifyai, which can generate Khan Academy style videos from PDFs in 15 seconds.
Learn more or get free compute at cerebras.ai -
Cerebras reposted
*yo (blue tick)
@roramora0
I am so love in Cerebras + Qwen right now. Created: 3D Holographic AI Cards within 2 minutes. Link in comments.
I REPEAT, I CREATED THIS IN 2 MINS!!!
All metrics and titles are AI generated.
@cerebras @Alibaba_Qwen -
Cerebras reposted
Daniel Kim
@learnwdaniel
Instant Coding with Cline x Cerebras Qwen3-235b
Write a Python script that uses Pygame to simulate a single red ball bouncing inside a rotating regular hexagon, all in SI units with a conversion of 100 pixels = 1 meter. The window should be 800×600 pixels at 60 FPS, with a black background. The hexagon is centered on the window, has a radius of 250 pixels (2.5 m), and rotates clockwise at 60 degrees per second. The hexagon does not respond to gravity, but the ball does. Use a gravitational acceleration of 9.81 m/s², and give the ball a restitution of 0.92 so it bounces. The ball should be 10 pixels in radius (0.1 m), colored red, and start near the hexagon’s center but offset upwards by 1 meter. It should have an initial horizontal velocity of 1 m/s (i.e., 100 pixels/s). To prevent tunneling through the hexagon edges, implement multiple substeps (e.g., 5) each frame and carefully resolve collisions by pushing the ball out of the polygon when penetration occurs, then reflecting its velocity. Render the hexagon’s edges in white with a line width of 3, draw the red ball as a circle, and label the window caption as “Red Ball in a Rotating Hexagon (SI Units).” End the script cleanly when the user closes the window. -
Cerebras
@cerebras
we're playing chess, while they're playing checkers
cerebras.ai/cline -
Cerebras reposted
-
Cerebras
@cerebras
get your api key now ->
cloud.cerebras.ai
️️ ️️️️️️️️️️️ ️️ ️️ ️️
@moes_code
Wait. I get this for free?
-
Cerebras
@cerebras
Let's talk about MoE:
🔶 How many experts should you use?
🔶 How does dynamic routing actually behave in production?
🔶 How do you debug a model that won’t train?
🔶 What does 8x7B actually mean for memory and compute?
🔶 What hardware optimizations matter for sparse models?
Mixture of Experts (MoE) is changing how the biggest AI models are built — but it’s still hard to get right.
That's why we are launching a new MoE 101 series, led by @dmsobol to bridge the gap between theory and practice.
Dive in to our MoE guide: www.cerebras.ai/moe-guide -
Cerebras reposted
ES-FoMo@ICML2025
@ESFoMo
We'll start off the day with two invited talks! The first, at 8:40AM, is from @hagay_lupesko from @cerebras on Zero to 50 ExaFLOPS in under a year - lessons from the trenches.
You'll want to be up bright and early for this one, don't miss it!
2/ -
Cerebras
@cerebras
🤗 @HuggingFace SmolAgents x Cerebras 🚀
Quickly launch far more capable, ultra‑responsive agents with
•Just a few lines of code
•~300 mstime to first token
•~2.6 k tok/s (≈ 19× GPU)Post not available here, view on X
Cerebras
@cerebras
3. Build & run it locally from the GitHub repo: github.com/kevint-cerebras/cerebras-multiagent
Cerebras
@cerebras
4. Show off your work ⤵️
-
Cerebras
@cerebras
Please invite us for dinner next time!
Sarah Chieng
@MilksandMatcha
do you ever have a fish to fry but your hands are too dirty?
our new intern @imbaime built a crazy real-time voice to browser automation and this was his demo...
the stack 🤖
> @cerebras for fast inference
> @browserbase for browser automation
> @Cartesia for voice processing
Ian Baime
@imbaime
When you tell your boss @SarahChieng you’re gonna cook but she doesn’t understand that you are literally cooking @cerebras
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
do you ever have a fish to fry but your hands are too dirty?
our new intern @imbaime built a crazy real-time voice to browser automation and this was his demo...
the stack 🤖
> @cerebras for fast inference
> @browserbase for browser automation
> @Cartesia for voice processing
Ian Baime
@imbaime
When you tell your boss @SarahChieng you’re gonna cook but she doesn’t understand that you are literally cooking @cerebras
-
Cerebras reposted
Vithu Thangarasa
@vithursant19
Excited to be here at ICML 2025 in Vancouver! 🇨🇦 Come swing by the @cerebras booth (#108) to meet the team, chat about our ICML work, and see how Cerebras delivers the fastest inference in the world across a wide range of frontier models.
Thrilled to be presenting two papers at the 3rd Workshop on Efficient Systems for Foundation Models (ES-FoMo III):
⭐ MASSV: Multimodal Adaptation and Self-Data Distillation for Speculative Decoding of Vision-Language Models (arxiv.org/pdf/2505.10526)
⭐ SD²: Self-Distilled Sparse Drafters (arxiv.org/abs/2504.08838)
📍 Catch our poster session on Saturday, July 19, from 1:00–2:30pm PST, where we’ll share some of our techniques for speculative decoding. -
Cerebras
@cerebras
See you in Vancouver for @icmlconf
Sarah Chieng
@MilksandMatcha
Over this last year, @amandamhuang and I started running 'Cafe Compute'
SF's first, regular late-night coffeeshop for engineers, founders, writers...(anyone) to co-work or hangout late at night.
We always bring in Bryan and Annie, two amazing baristas to serve free coffee and food, and it's been so nice to watch the community grow. It's now been a year of cafe computes, and we're excited to continue the series -- we'll be expanding to NYC and Vancouver (ICML) next :)
Please reach out if you'd ever like to attend or cohost.
Sponsored by @cerebras and @BainCapVC -
Post not available here, view on X
Cerebras
@cerebras
Read more:
www.cerebras.ai/press-release/cerebras-enables-notion-to-… -
Cerebras
@cerebras
- Qwen3-235B is now live on Cerebras -
Frontier intelligence • 1500 t/s • 0.6s reasoning time
$0.6/$1.2 per M tokens
Free API key via Cerebras
Pay-as-you-go via @openrouter
131k context soon
Try it here: inference.cerebras.ai
Cerebras
@cerebras
Official model name via API is:
qwen-3-235b-a22b -
Cerebras
@cerebras
A little faster? 👀
Andrew Feldman
@andrewdfeldman
We are just a little bit faster than@nvidia GPUs on Qwen 235B...18X faster. @cerebras inference is blazing fast...come build cool stuff on Cerebras inference
-
Cerebras
@cerebras
ICML (@icmlconf) starts next week!
Don't miss the 3rd Workshop on Efficient Systems for Foundation Models (es-fomo.com) where our team will present their papers and Hagay Lupesko will give a talk on training and inference.
Register for Cafe Compute ICML edition: lu.ma/mw7edj9g
See you in Vancouver! -
Cerebras
@cerebras
What open source projects (eg. deep research, coding agents) should we implement on Cerebras Inference?
Drop a repo link and we'll take a look👇 -
Cerebras
@cerebras
“You need a shopping cart? You call Stripe. You need a chatbot? You call Cerebras. AI is becoming an API in every app.”
@andrewdfeldman sat down with @SiliconANGLE at @RaiseSummit.This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
The world's fastest AI inference is now available in @awscloud Marketplace. It's easier than ever to access models like @AIatMeta Llama, @Alibaba_Qwen, @deepseek_ai, consolidate billing, and experience the speed of Cerebras.
Cerebras
@cerebras
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
We launched Qwen 235B on the Cerebras cloud. Not only is it 18 X times faster than the leading GPU offering but it cuts response time from minutes to less than a second. Faster response. Faster answers. What’s not to like?
-
Cerebras
@cerebras
The Cererbas super secret business plan:
1. Get frontier models on the wafer
2. Bring it up to full context
3. Make it run 20x faster
4. Collect all the tokens -
Cerebras
@cerebras
Sometimes, you have to see it to believe it. 🚀🚀
LoucB
@LoicBerthelot
🤯 Holy mother of AI
Met @hi_im_dev_ yesterday on a YC event in Paris.
Amazing dude
He showed me @cerebras and how fast their llama model was...
Didn't believe it at first
I plugged the model on my SaaS compared to gemini-2.5-flash-preview-04-17
The result in video, it's like 100x faster.... WTFThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Deep research on ChatGPT takes over ten minutes.
We do it under 30 seconds.
Using Qwen3-235B on Cerebras, we've benchmarked agentic search workflows that process 10M+ document enterprise repositories in seconds, not hours.
Early enterprise customers report 20x faster document analysis compared to popular RAG solutions. Reach out for a live demo and free trial.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
-
Cerebras
@cerebras
Frontier AI is now on Cerebras.
This week we are launching Qwen3-235B—@Alibaba’s flagship reasoning model that rivals ChatGPT and Claude. In classic Cerebras style, we run the model at 1,500 tokens/second.
That means reasoning time goes from 60 seconds on GPUs to just 0.6 seconds. For enterprise customers, we're enabling them with 131K context, which enables production-grade code generation. @Alibaba_Qwen 3-235B will be available for all to try later this week.
Meanwhile, try Qwen3-32B for free at inference.cerebras.ai -
Cerebras
@cerebras
Live from Supernova Paris at the @RaiseSummit
Post not available here, view on X
Cerebras
@cerebras
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Free, instant access to 1M inference tok/day
@cerebras is excited to launch Cerebras Supernova! Developers get 1M free inference toks/day, and if you're a startup, get up to 3 months FREE of increased context windows, rate limits, and 245M tok/day.
All on the world's fastest inference provider.
This is the most generous free tier that exists. It really is land of the free...(credits)🇺🇸 -
Cerebras
@cerebras
“The Race to Superintelligence” — with
@andrewdfeldman and @ericschmidt, diving into the AI compute arms race, open vs closed intelligence architectures, and what kind of founders will shape the AGI era. July 8, 2025 at @RaiseSummit
RAISE Summit
@RaiseSummit
Eric Schmidt joins @RaiseSummit 2025.
As former CEO & Chairman of @Google, @ericschmidt helped shape the modern internet and led one of the most influential companies in history.
Now, he returns to the global stage to tackle what he calls “the birth of a new epoch”: the rise of Artificial Intelligence. At RAISE, Eric will speak in two landmark sessions:
🔹 “AI and the Genesis of a New Epoch” — a fireside chat inspired by his book Genesis (co-authored with Henry Kissinger), exploring AGI timelines, self-improving code, and why we may have already passed the Turing Test.
🔹 “The Race to Superintelligence” — with @andrewdfeldman (CEO, @cerebras), diving into the AI compute arms race, open vs closed intelligence architectures, and what kind of founders will shape the AGI era. July 8, 2025
Louvre, Paris
As intelligence becomes infrastructure, the stakes have never been higher. -
Cerebras
@cerebras
Home of the fastest inference in the world. 🫡
Get yours: cloud.cerebras.ai -
Cerebras
@cerebras
Sean Lie, Cerebras CTO, highlighted an uncomfortable truth for the AI industry at @VentureBeat Transform panel.
Cerebras
@cerebras
The most revealing moment came when the panel discussed pricing. “If these million tokens are as valuable as we believe they can be, right? That’s not about moving words. You don’t charge $1 for moving words. I pay my lawyer $800 for an hour to write a two-page memo.”
Cerebras
@cerebras
This observation cuts to the heart of AI’s price discovery problem. The industry is racing to drive token costs below $1.50 per million while claiming these tokens will transform every aspect of business. The panel implicitly agreed with each other that the math doesn’t add up.
Cerebras
@cerebras
The panel’s consensus was clear: success requires matching specific workloads to appropriate infrastructure rather than pursuing one-size-fits-all solutions.
Cerebras
@cerebras
Read the full story: venturebeat.com/ai/nvidias-ai-factory-narrative-faces-rea…
-
Cerebras
@cerebras
The @RaiseSummit is only one week away!
Are you joining us at Supernova Zone?
The line up includes talks from our luminary partners from @IBMwatsonx @AIatMeta @livekit @MayoClinic @GSK @ExaAILabs @NotionHQ @Docker @UseCline @DataRobot @nlxai
Cerebras
@cerebras
We will be hosting the FINALS of the world’s largest AI startup competition!
10 groundbreaking finalists, selected from over 1,000 startups across the globe, will pitch live on stage. Don’t miss this showcase of the future of AI innovation.
Cerebras
@cerebras
Register now:
lu.ma/zcaqettj -
Cerebras
@cerebras
Featured Paper at @icmlconf - The Internationall Conference on Machine Learning:
SD² - Self-Distilled Sparse Drafters
Speculative decoding is a powerful technique for reducing the latency of Large Language Models (LLMs), offering a fault-tolerant framework that enables the use of highly compressed draft models.Post not available here, view on X
Cerebras
@cerebras
The results:
- 1.59× higher Mean Accepted Length (MAL) than layer-pruned draft models
- 43.87% fewer MACs (Multiply-Accumulate operations) than dense draft models
- Only 8.36% reduction in MAL vs. dense models — a strong tradeoff for efficiency
Cerebras
@cerebras
See you at ICML
cloud.cerebras.ai -
Cerebras
@cerebras
📽️World Premiere: "Top Llama" - celebrate the fastest Llamas in the world.
This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Do you feel the need for speed? Get your free API key and start flying! cloud.cerebras.ai
-
Cerebras
@cerebras
"Before Cerebras, everything sits sub 200 tokens per second output. And after us, on every model, you have vast improvements, order of magnitude improvements. And what this allows you to do is deliver something special and different to your customers —faster responses, richer interactions, more intelligent systems."
But how?
We do this with a relentless commitment to bottoms-up engineering and a fearless approach to tackling extraordinarily hard problems. We began by designing the industry's largest processor..."
Cerebras
@cerebras
Cerebras
@cerebras
Hear the full story live from @andrewdfeldman at @RaiseSummit on July 8th and 9th in Paris.
Register now for exclusive access to Supernova: lu.ma/zcaqettj -
Cerebras
@cerebras
Powered by Cerebras, @NinjaTechAI revolutionizes productivity with an All-in-One Autonomous Assistant featuring 16 specialized AI agents that handle everything from writing and coding to deep research. They’ve seen:
⏱️ 15× faster resolution of complex queries (under 20 seconds vs. 1-4 minutes)
🤹♂️ 4× increase in weekly usage with Instant Reasoning SuperAgent
🦾 10-20× faster performance than flagship proprietary models at a fraction of the cost
Cerebras
@cerebras
So, how does Ninja solve world's hardest math problems quickly and accurately? ➡️ youtu.be/_Xs54iyjh9I
Cerebras
@cerebras
Do you want to build the next NinjaTech? Start here: cloud.cerebras.ai
-
Cerebras
@cerebras
🧠 Research spotlight: Multimodal Adaptation and Self-Data Distillation for Speculative Decoding of Vision-Language Models - MASSV first connects the target VLM’s vision encoder to the draft model via a lightweight trainable projector, then applies self-distilled visual instruction tuning using responses generated by the target VLM to align token predictions.
Read here: arxiv.org/pdf/2505.10526
Cerebras
@cerebras
Don't forget to get your API key: cloud.cerebras.ai
-
Cerebras
@cerebras
Reasoning efficiency is the next frontier for thinking models.
On an AIME 2025 question, every model below gets the right answer, but some use 3-10x more tokens.
DeepSeek R1 Distilled is the least 'over-thinker' in this eval. -
Cerebras
@cerebras
AI's most iconic hardware will be on full display in the Supernova Zone @RaiseSummit
Cerebras
@cerebras
Skip the line: lu.ma/zcaqettj
-
Cerebras
@cerebras
⭐️Stars, stripes, and the WSE 🍦 Join us at Cafe Compute: Land of the Free (Credits) for a night of cool treats, hot espresso, and red, white & blue fits.
Hosted by Cerebras, @BainCapVC, and @usepylon
🇺🇸July 1 | SF | 7–10 PM lu.ma/jh51she4 -
Cerebras
@cerebras
Cerebras brings ultra-fast inference to @IBMwatsonx AI Model Gateway.
Now you can run high-performance models—like those from Cerebras, @OpenAI, @AnthropicAI & more—through a single interface.
Cerebras
@cerebras
Get your free API key to get started: cloud.cerebras.ai
Cerebras
@cerebras
-
Cerebras
@cerebras
Cerebras CTO and Co-Founder Sean Lie will be doing a fireside chat tomorrow at #vbtransform 2025 alongside @SemiAnalysis_ @GroqInc moderated by @M12vc.
We're looking forward to sharing how super fast AI inference is creating new categories and opportunities for all! See you @VentureBeat -
Cerebras
@cerebras
Supernova is coming to Paris at @RaiseSummit July 8-9!
Wafer can't wait to see you at the Louvre. We bring the speed. You bring the brilliance!
RSVP --> lu.ma/zcaqettj
Cerebras
@cerebras
en français cette fois:
Supernova arrive à Paris au @RaiseSummit les 8 et 9 juillet ! Wafer a hâte de vous voir au Louvre. Nous apportons la vitesse. Vous apportez l'éclat ! RSVP --> lu.ma/zcaqettj
cc @HenriDelahaye -
Cerebras reposted
Nick
@nickbaumann_
oh my is @cerebras fast
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Building the fastest AI while wearing bunny suits. At @cerebras we are fast and fashionable.
-
Cerebras
@cerebras
AI Scaling Laws from the Cerebras Perspective
A new blog post by our CTO, Sean Lie
www.cerebras.net/blog/the-cerebras-scaling-law-faster-inf… -
Cerebras
@cerebras
Think. But don't over think.
Try saying 'hello' to Qwen3 on Cerebras: inference.cerebras.ai
Yuchen Jin
@Yuchenj_UW
o3-pro is the slowest and most overthinking model.
A simple 'Hi' cost me $80. 🥲 -
Cerebras
@cerebras
Cerebras real-time reasoning is now on @MistralAI
Magistral is Mistral AI’s first reasoning model
- Handles multi-step logic, multilingual reasoning, and complex workflows
- Runs 10x faster in Le Chat, powered by Cerebras Wafer-Scale inference
- Try here:This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Get your free API key: cloud.cerebras.ai
-
Cerebras
@cerebras
if only there was a way to serve faster inference...let me get back to you🤔
Yuchen Jin
@Yuchenj_UW
o3-pro is the slowest and most overthinking model.
A simple 'Hi' cost me $80. 🥲 -
Cerebras
@cerebras
AI builders – see you in Paris next month!
RAISE Summit
@RaiseSummit
As the AI industry accelerates, @cerebras is bringing Supernova, their flagship AI event at the @RaiseSummit, inside the most iconic venue on Earth: the Louvre.
For two full days, a monumental Supernova Zone will take over the summit, featuring exclusive sessions, cutting-edge activations, and a dynamic networking arena where tokens, agents, and AI-native infrastructure collide.
This isn’t just a showcase. It’s the European debut of Cerebras Supernova, a historic leap in AI compute, inference, and deployment. The future of intelligence is being built, and it’s happening in Paris, under the glass pyramid.
Whether building apps, deploying models, or designing infrastructure for the agentic era, Supernova is where AI goes from promise to production. Cerebras will unveil the next generation of models and cloud infrastructure powering real-time reasoning and intelligent agents. From DeepSeek R1 to Llama 4 to Qwen, Cerebras delivers the fastest AI inference for cutting-edge open-source models, engineered for those deploying at scale.
Founded in 2015, Cerebras Systems has redefined what’s possible in AI compute. Our flagship product, the CS-3 system, is powered by the world’s largest and fastest commercially available AI processor, the Wafer-Scale Engine-3. Cerebras Inference delivers breakthrough inference speeds, empowering customers to create cutting-edge AI applications.
Register to the Luma link!
lu.ma/zcaqettj -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Building Data Centers....@cerebras has 5 data centers in the US...We power the fastest inference in the industry enabling all sorts of cool applications--Reasoning, Agentic, Voice to name a few. More to come...
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
At @cerebras our solutions are designed, manufactured and deployed in the USA. Here we are bringing up our fifth US data center to ensure that everyone has access to the fastest inference in the industry.
-
Cerebras reposted
Daria Soboleva
@dmsobol
Speaking next week about Qwen 3 models w @arankomatsuzaki & @grmcameron on @cerebras Discord!
We're analyzing what makes these new models different and their implications for AI development🤖
discord.gg/ggfYtRE7S7
RT if your network would find this interesting! -
Cerebras
@cerebras
PSA: all Cerebras models are on OpenRouter with 32K context. We know you want longer context - team is on it!
openrouter.ai/provider/cerebras -
Cerebras
@cerebras
Have you tried Cerebras on @openrouter yet?
We make the GPU vendors look like they lost their pulse. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Free, instant access to 1M inference tok/day
@cerebras is now waitlist-free! Building the new onboarding flow and removing our waitlist were so fun to ship
& all API signups automatically get
> Free 1,000,000 toks/day
> SOTA models on the world's fastest inference provider -
Cerebras
@cerebras
Cerebras 🤝 OpenRouter!
Kevin Taylor
@KevinTaylor00
Over 450 developers from around the world joined @cerebras and @openrouter for an incredible Qwen 3 hackathon!
Presenting the top projects built on Qwen. 📷 -
Cerebras
@cerebras
How's everyone's experience with Qwen3-32B in coding? Are you seeing Sonnet level performance?
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
We are pretty fast on @AIatMeta's Llama 4 Maverick model. More than twice as fast as @nvidia recently published Blackwell Performance according third party benchmarking firm @ArtificialAnlys.
-
Cerebras
@cerebras
Question for DeepSeek R1 users – are you really waiting 60sec for an answer? What use case tolerates that?
-
Cerebras
@cerebras
Which model would single handedly make you switch to Cerebras?
-
Cerebras reposted
Artificial Analysis
@ArtificialAnlys
Congratulations to Cerebras on their latest result for Llama 4 Maverick!
Artificial Analysis has benchmarked @cerebras' Llama 4 Maverick endpoint at 2,400 tokens per second, compared to NVIDIA Blackwell's 1,040 tokens per second for the same model.
As always, we are excited to see the limits of inference speed pushed - allowing more actions per minute for agents, higher volume real-time use cases and more.
Cerebras
@cerebras
Cerebras just beat NVIDIA Blackwell
Last week: Blackwell hit 1,000 t/s on Llama 4.
Today: Cerebras hit 2,500 t/s on the same model, same benchmarks by @ArtificialAnlys
Blackwell smoked Groq, AMD, Google – everyone.
Only Cerebras stands – and we smoked Blackwell. -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
We are pretty fast at @AIatMeta Llama 4 Maverick model. More than twice as fast as @nvidia recently published Blackwell performance. @ArtificialAnlys numbers below.
@cerebras 2,522 Tokens per second
@nvidia 1,038 t/s
@SambaNovaAI 702 t/s
@GroqInc 549 t/s
@awscloud 290 t/s
Does anyone really want slow inference? -
Cerebras
@cerebras
Cerebras just beat NVIDIA Blackwell
Last week: Blackwell hit 1,000 t/s on Llama 4.
Today: Cerebras hit 2,500 t/s on the same model, same benchmarks by @ArtificialAnlys
Blackwell smoked Groq, AMD, Google – everyone.
Only Cerebras stands – and we smoked Blackwell. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
I'm looking to hire a few growth engineer interns this summer.
> No age requirements
> Must be technical
> In-person, relocation $$ covered
> Unlimited Cerebras ramen
> You'll work directly with me -
Cerebras
@cerebras
The more tokens you use, the higher the intelligence.
💡 But reasoning models are slow...unless you run them on Cerebras.
Watch Cerebras CTO Sean Lie's full keynote now: cerebras.ai/supernovaThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Cerebras is proud to partner with @mbzuai (Mohamed bin Zayed University of Artificial Intelligence) as they launch the Institute of Foundation Models (IFM) — a global, multi-site initiative spanning Abu Dhabi, Paris, and now in the heart of Silicon Valley.
We’re enabling fast, scalable inference to support IFM’s research on large-scale foundation models and unlock new capabilities for researchers, startups, and enterprises across the AI ecosystem. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
6 months of late nights, laptops, and community
This was my favorite one yet -- celebration edition. Everyone came with something personal to celebrate
> baby's first PR 👩💻
> adopting a dog 🐶
> company acquisition 💰
SF's first and only free, late night coffeeshop. Whether you're here to co-work or hangout, Cafe Compute is open for you.
It’s been amazing seeing this late-night community grow and we can't wait to see you at the next one.
Presented by @cerebras and @BainCapVC
Filmed by Sarah and @nicholascarpo
Sarah Chieng
@MilksandMatcha
fortune cookies and inference speeds went crazy last night
sf's first late night coffee-shop is back
Location: Cafe Compute
Hours: 7:00 - 10:00 PM
Happy Lunar New Years from @cerebras and @BainCapVC 🧧🐍 -
Cerebras
@cerebras
Supernova showed what’s possible when inference isn’t the bottleneck.
⚡️ Real-time AI
🛠️ Agentic workflows
🧠 Qwen: the fastest open-weight reasoning model, now running in real time
Big thanks to the devs, startups, customers, and partners who made it electric.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Watch the keynotes here: www.cerebras.ai/supernova
Cerebras
@cerebras
Join the Cerebras Supernova Startups Program — transforming startups to build what they can’t on GPUs www.cerebras.ai/startups
-
Cerebras
@cerebras
This whole thread!! 🤯👏
Daria Soboleva
@dmsobol
Just dropped on arXiv: "Power Lines: Scaling Laws for Weight Decay and Batch Size in LLM Pre-training": arxiv.org/abs/2505.13738
We found precise power laws that predict optimal hyperparameters for any model/data combination, enabling efficient large-scale training.
1/n 🧵 -
Cerebras
@cerebras
We’re super excited to be supporting @cerebral_valley’s Llama 4 hackathon with @MetaforDevs on May 31st-June 1st in NYC!
This is going to be one of the best AI events of the year, and we’re excited to see what you build! We will also be providing API credits for all developers to use 🔥
Sign up 👉 cerebralvalley.ai/e/llama-4-hackathon-nyc-f673085d -
Cerebras reposted
Sally Ward-Foxton
@sallywf
I attended @cerebras developer event in SF - they are betting on the need for speed from reasoning and agentic AI. With 6 new data centres coming online in 2025, the company will be a hyperscaler in its own right by Q3.
Featuring @andrewdfeldman
www.eetimes.com/cerebras-counts-on-the-need-for-speed/ -
Cerebras
@cerebras
Artificial Analysis measured the time to first token of every reasoning model from o3 to R1.
DeepSeek R1 = 103 sec
Qwen3-32B on Cerebras = 1.1 sec
We give you R1 level intelligence with 99% latency reduction.
Try it: inference.cerebras.ai
Cerebras
@cerebras
Qwen3-32B vs. leading models eval
artificialanalysis.ai?models=gpt-4-1%2Co3%2Cllama-4-scout… -
Cerebras
@cerebras
Live on @poe_platform - Cerebras, delivering the fastest inference in the world.
Build a bot, drop the link below, and we’ll share our favorites.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
🤖 Choose a model (@Alibaba_Qwen 3 32B, @AIatMeta Llama 3.3 70B, Llama 4 Scout, @deepseek_ai R1 Distill Llama 70B) - poe.com/search?q=cerebras
✍ Add a prompt template
🔢 Connect your data
🖇️ Chain it with other tools
Cerebras
@cerebras
Read more about our partnership here: www.cerebras.ai/blog/bringing-cerebras-inference-to-quora…
-
Cerebras
@cerebras
0 to 50,000,000,000,000 tokens in just 3 years. 50T Tokens. That kind of scale isn’t just extraordinary, 𝗶𝘁’𝘀 𝗮 𝗰𝗮𝗹𝗹 𝘁𝗼 𝗯𝘂𝗶𝗹𝗱.
LLM growth is exploding, and speed is the catalyst.
Cerebras
@cerebras
Don't wait for the future. Build it: cloud.cerebras.ai
Cerebras
@cerebras
Full video of @andrewdfeldman and Sean Lie's keynotes: www.cerebras.ai/supernova
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
.@cerebras is pretty fast at Qwen3 32B Reasoning. More than 50 X faster than @nvidia GPU based solutions. This is impotrtant since Qwen3 32B is a world class reasoning model at a fraction of the size and per token price of similarly intelligent models.
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Intelligent models don’t need to be slow. @cerebras Qwen3 32B Reasoning is all alone in the intelligent and fast blisteringly quadrant, according to @ArtificialAnlys
When inference is fast, AI can change the world. -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
This year has been all about reasoning — faster inference, more capable agents, and real-time decision-making.
Last week I joined @dsa, CEO of @livekit (powering voice for OpenAI, Character AI, xAI), to ask:
What does reasoning look like in real-time voice AI — and how does that change with omni models?
“Reasoning model interfaces were never designed with voice in mind. Today’s models (like o3) output cryptic status logs mid-thought — imagine hearing ‘reticulating splines’ in conversation.
Humans don’t work this way.
Humans fill silence with ‘uh’ or ‘you know’. Voice agents will need interjections, timed pauses, and expressive avatars that adapt to the model’s cognitive load.
As thinking budgets get more dynamic, agents won’t just talk like us — they’ll signal cognition the way we do. That’s the missing piece for truly fluid, real-time collaboration with AI.” -
Cerebras
@cerebras
Come join us at the exclusive @Alibaba_Qwen 3 Hackathon sponsored by Cerebras and @openrouter!
Try out the new Qwen3 32B at the blistering speed of Cerebras with the ease of OpenRouter.
Get FREE API credits and win cash prizes!
See you there! lu.ma/3iy18vm7?tk=0yuxq9 -
Cerebras
@cerebras
Huge thanks to our guests, partners, speakers & the AI community for making our first SUPERNOVA unforgettable!
-
Cerebras
@cerebras
Live from SUPERNOVA! @andrewdfeldman speaks about the WHY behind our journey at Cerebras and the imperative of speed and scale.
Post not available here, view on X
Cerebras
@cerebras
Andy Hock and Armand Ruiz of @IBM spoke about why now is the right time for IBM to integrate the highest-performance inference by partnering to bring Cerebras to the watsonx.ai platform
Cerebras
@cerebras
@learnwdaniel shared incredible startups in production using Cerebras Inference. Want to join us? cerebras.ai/startups
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
At @cerebras’ Supernova.
Showing a really really big wafer. -
Cerebras
@cerebras
Instant reasoning is here: @Alibaba_Qwen 3-32B on Cerebras:
⚡ 1.2 sec reasoning latency
🚀 2,400+ tokens/sec
Cerebras
@cerebras
try it now! inference.cerebras.ai
Post not available here, view on X
Cerebras
@cerebras
All developers receive 1 million free tokens per day, with no waitlist. www.cerebras.ai/build-with-us
Cerebras
@cerebras
Outperforms GPT-4.1 and Claude Sonnet 3.7 and it runs on Cerebras with real-time responsiveness. Verified by @ArtificialAnlys
-
Cerebras
@cerebras
See you tomorrow.
www.cerebras.ai/supernova -
Cerebras
@cerebras
📢 “Self-Data Distillation for Recovering Quality in Pruned Large Language Models”, will be presented at The Eighth Annual Conference on Machine Learning and Systems (@MLSysConf 2025)!
📅 When: Tuesday, May 13 @ PM PST
📍 Where: Santa Clara Convention Center, Session 3: Quantization & Sparsity
🔗 Read it here: arxiv.org/abs/2410.09982
👑 Presented by @vithursant19
Thank you to our incredible team! @ganeshvenk Sean Lie @mikelasby @NishSinnadurai -
Cerebras
@cerebras
Cerebras lit up Times Square today with SUPERNOVA — and we’ll be live in San Francisco next week.
Last chance, join us! lu.ma/21yj9tla?coupon=TWI -
Cerebras
@cerebras
Powered by Cerebras Inference, @norby_io is revolutionizing AI companionship with a Pixar-like voice experience that adapts to your personality while keeping you in a focused, productive flow state.
⏱️ 87% decrease in conversational response latency
📢88% Reduction in conversation summary processing time
🧠Long-term memory storage that creates personalized interactions
Thanks for the demo @adrianmullanThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
The Cerebras team collaborated with top researchers from @Princeton, @Harvard, and @ETH_en Zurich to introduce Complete Parameterization (CompleteP), a fundamental research breakthrough.
CompleteP makes it practical to train large-scale deep models with real compute-efficiency savings and more flexible width/depth tradeoffs. Without CompleteP, deeper models are plagued with training instability and shifting optimal hyperparameters. CompleteP improves scaling laws. This matters as we push into >100B or trillion-parameter models.
Cerebras is proud to support this kind of fundamental scaling research. Join our team! You'll get to work alongside @BCZhang_ and @DeyNolan on groundbreaking work like this!
Nolan Dey
@DeyNolan
(1/7) @cerebras Paper drop: arxiv.org/abs/2505.01618
TLDR: We introduce CompleteP, which offers depth-wise hyperparameter (HP) transfer (Left), FLOP savings when training deep models (Middle), and a larger range of compute-efficient width/depth ratios (Right). 🧵 👇 -
Cerebras
@cerebras
ludicrous... we like the sound of that. ⚡🚀
Watch this space @openrouter 🤝 Cerebras
OpenRouter
@OpenRouter
Introducing a ludicrous-speed provider: @cerebras
Watch an animation generate instantly for ~$0.001, at over 1.8k TPS 🤯 -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
At IBM Think 25, @AnthropicAI , @nvidia , @OpenAI and @cerebras were announced as IBM partners.
-
Cerebras
@cerebras
Cerebras x @IBM : Partnering to help enterprises accelerate AI adoption without compromise.
Businesses shouldn’t have to choose between bleeding-edge AI performance and enterprise-grade reliability.
It’s no longer enough for AI to be powerful, it also has to be practical, efficient, and trustworthy at enterprise scale.
That’s exactly why we’re working with IBM and @IBMwatsonx
Cerebras
@cerebras
The details: www.cerebras.ai/blog/cerebras-partners-with-ibm-to-accele…
-
Cerebras
@cerebras
We aren't just talking about the future of AI infrastructure. We are making it a reality.
6 new datacenters.
40 million tokens/sec.
The fastest inference on Earth.
What will you build with it?
Cerebras
@cerebras
See you at SUPERNOVA
lu.ma/21yj9tla -
Cerebras
@cerebras
2025 is going as fast as Cerebras Inference—here’s a quick April recap:
✨ Supernova lands May 15 in SF - Have you registered yet?? lu.ma/21yj9tla
*Space is limited!*
Cerebras
@cerebras
🚀 @Meta x Cerebras
We are proud to be an official launch partner for Meta’s Llama API, delivering the fastest inference performance for any large language model, anywhere. With 18x faster inference and 2,600 tokens/sec, developers can now instantly build real-time voice, agents, and reasoning apps. -
Cerebras
@cerebras
🔖
Kyle Jeong
@kylejeong
Looking for Research Papers has never been easier,
Use @cerebras' instant inference on @Stagehanddev to search for relevant papers and extract important info
Watch it do 5 papers in < 19 seconds
Learn faster than ever🤘 -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Yesterday, I shared the big step forward with @cerebras integration into @AIatMeta’s flagship new Llama API.
What’s in it for developers?
1/ The fastest Llama 4 inference in the world. —18x faster than GPUs, 4x faster than the next best
2/ Full accuracy — native 8/16-bit, no compromises
3/Easy migration — 1-click API and 3 code changes to switch from OpenAI
4/ No lock-in — prompts and outputs remain yours, with full provider portability
5/ Production-ready — consistent, predictable speeds at scale
Can’t wait to see the innovations that the AI community will unlock 🔓 ⚙️ 👊 -
Cerebras reposted
LiveKit
@livekit
Devs building in voice and video AI, we’ve got something special cooked up for next week — on 4/30, we’re doing a fireside chat with @juberti in SF.
Justin is a legend. He created the WebRTC protocol, led dev for Google Meet and Stadia, started @FixieAI, and is now the Head of Realtime AI at @OpenAI.
Come hang out with us @fdotinc, there will be lots of food and good vibes! -
Cerebras reposted
Michael Nuñez
@MichaelFNunez
🚨 Meta just teamed up with Cerebras to launch the Llama API — delivering AI speeds up to 18x faster than OpenAI (2,600 tokens/sec!).
Is this the new gold standard for real-time AI?
Full story: venturebeat.com/ai/meta-unleashes-llama-api-running-18x-f… #ai #technews #metaai #cerebras @Meta @cerebras -
Cerebras
@cerebras
Cerebras launched inference just 8 months ago.
Today it is officially part of Llama API.
Any developer can now click a button and get a wafer-scale chip to generate tokens at ~2,600 t/s.
Insane progress. -
Cerebras
@cerebras
Cerebras and @Meta Collaborate to Drive Fast Inference for Developers in New Llama API
🦙The world’s most popular open-source models — now with the world’s fastest inference.
🔑 Native to @AIatMeta Llama API with 1-click API key generation.
🗣️ Unlock next-generation applications like real-time voice assistants, instant agents, sub-second reasoning
Cerebras
@cerebras
Get the details: www.cerebras.ai/press-release/meta-collaborates-with-cere…
Cerebras
@cerebras
Feel the speed: inference.cerebras.ai
-
Cerebras
@cerebras
Customer experience and compliance—no trade-offs.
Sei AI, powered by Cerebras, is redefining financial services with real-time voice support and instant compliance monitoring.
This results in:
⚡️60% faster real-time feedback & customer support
📞Real-time compliance monitoring that catches issues before calls end
💰2x more features, leading to infrastructure cost savingsThis media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Thank you @Ramthemaniac for the demo!
Check them out: www.seiright.com
Cerebras
@cerebras
Want to build the future with us? Let’s connect.
www.cerebras.ai/build-with-us -
Cerebras
@cerebras
Paying more. Running slower? 🙈
If that’s your current setup... maybe it’s time we talked.
www.cerebras.ai/build-with-us
Andrew Feldman
@andrewdfeldman
Price performance leadership on Meta Llama 4, from @cerebras ..When inference is fasts. AI can change the world.
-
Cerebras
@cerebras
🚀 Calling all developers!
Which models are you most excited to use next?
Are you building with tool calling, multimodal capabilities, or long context windows?
We’re building the fastest inference engine for real-time AI, and we want your input to help shape what comes next.
Take this quick survey (under 3 minutes!) so we can prioritize features and models that make a real difference for you.
www.cerebras.ai/cerebras-developer-survey -
Cerebras
@cerebras
It’s #iclr2025 week, and we’re proud to share that Team Cerebras will be presenting their paper:
"Straight to Zero: Why Linearly Decaying the Learning Rate to Zero Works Best for LLMs"
at @iclr_conf!
Big congrats to the authors, your work is powering the future of AI compute.Post not available here, view on X
Cerebras
@cerebras
The result: up to 60% compute savings (!)
That’s a massive impact for training large models efficiently.
Cerebras
@cerebras
Want to dive deeper?
The full paper: Straight to Zero – ICLR 2025
arxiv.org/abs/2502.15938 -
Cerebras
@cerebras
As interest grows in real-time reasoning, agentic AI, and edge deployments, the design tradeoffs around active parameter count are more important than ever.
@dmsobol (our expert of hashtag#MOE) is curious to know what you think. 👇
Daria Soboleva
@dmsobol
Curious #ml thought experiment: If you were designing a new #mixtureofexperts model today, what active parameter count would you target?
With models like Llama 4 at 17B active, is that the sweet spot? Or would you go smaller for edge devices or larger for more capabilities? -
Cerebras reposted
Daria Soboleva
@dmsobol
Curious #ml thought experiment: If you were designing a new #mixtureofexperts model today, what active parameter count would you target?
With models like Llama 4 at 17B active, is that the sweet spot? Or would you go smaller for edge devices or larger for more capabilities? -
Cerebras
@cerebras
92% of companies plan to increase AI investments over the next 3 years.
But only 1% have fully integrated AI into their workflows.
The gap?
Real-time performance and scale.
That’s why we created Cerebras Supernova.
Join us - Space is limited: lu.ma/21yj9tla -
Cerebras
@cerebras
"The difference between good and great AI isn't just accuracy—it's speed. When milliseconds matter, having the right infrastructure becomes everything." ⚡
At HumanX, Angela Yeung showed how @perplexity_ai & @MistralAI gain a real edge with Cerebras speed.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
Catch her at Supernova—see what’s next 🚀 lu.ma/21yj9tla
-
Cerebras reposted
apolinario (poli)
@multimodalart
Testing Codex open source nature to its limits: @OpenAI Codex cli 🤝 LLaMA 3.3 70B w/ tool use
Ultra fast inference speed using @cerebras via @huggingface Inference Providers
Next step: locally running LLMs 🔥 -
Cerebras
@cerebras
Over 200 developers from around the world build joined us for an incredible Llama 4 hackathon with @huggingface
Presenting the top five projects built on @Meta Llama 4 powered by Cerebras. 🧵Post not available here, view on X
Cerebras
@cerebras
4th Place: LLM Inference Speed Comparison - A Streamlit application to compare inference speeds across different LLM providers for Llama 4 🦙
llm-inference-akash.streamlit.app
Cerebras
@cerebras
5th Place: Cerebras Code Scanner - this scanner leverages prompt engineering to extract code insights that traditional rule-based tools cannot detect, enabling deeper security and performance analysis.
github.com/drxyu/cerebras-code-scanner -
Cerebras
@cerebras
Real-time reasoning is now faster and more accurate. The latest Cerebras Planning and Optimization (CePO) update turbocharges the capabilities of the open-source reasoning models – @deepseek_ai R1 and @Alibaba_Qwen QwQ 32B.
We have optimized how these models handle long context lengths, enabling stronger multi-step reasoning without hitting performance ceilings.
You can see the results here: www.cerebras.ai/blog/cepo-update-turbocharging-reasoning-… -
Cerebras reposted
Hugging Face
@huggingface
We’re partnering with @cerebras to bring the fastest Llama 4 experience right to you! 🔥
Join us tomorrow in our hackathon to build real-time systems, code agents/ assistants AND more!
Bonus: We’re giving 20USD free inference credits and one month Pro subscription to all 🤗
Capped at 300 people only, sign up below 💥 -
Cerebras
@cerebras
This is breakthrough performance. 🚀
Andrew Feldman
@andrewdfeldman
.@cerebras is pretty fast at Llama 4... 3.5X faster than the next nearest competitor and 20X faster than @nvidia GPU based solutions.
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
.@cerebras is pretty fast at Llama 4... 3.5X faster than the next nearest competitor and 20X faster than @nvidia GPU based solutions.
-
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Call me at 415-918-5699 or DM for access.
@cerebras -
Cerebras
@cerebras
Our partnership with @huggingface allows developers to unlock new possibilities for real-time agents, code-generation tools, multilingual assistants, and more. Get instant access to the fastest open-weight inference on the planet—including @AIatMeta Llama 4 on the Cerebras Inference Cloud.
We are excited to present the Cerebras and Hugging Face Llama 4 Hackathon! You'll have an 8-hour window to build something amazing (and fast) with Cerebras inference for the new Llama 4 models!
📷 Join the hackathon: lu.ma/eihdh2gd -
Cerebras
@cerebras
Subsecond code generation in action. 👀
Same prompt. Same output. Just 19x faster. Cerebras powers the fastest @AIatMeta Llama 4.
Get Access now: www.cerebras.ai/build-with-us -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
. @cerebras is the fastest Llama 4 Scout provider in the world. 19 times faster than the fastest GPU, according to third party benchmark firm @ArtificialAnlysis.
Our CS-3 accelerators are made in the USA and our data centers are located in the USA. -
Cerebras
@cerebras
Llama 4 is now live on Cerebras!
- We broke the perf chart again at 2,611 tokens/s
- 19x faster than the leading GPU cloud
- Only API in the world with <1s total response time
Try now: inference.cerebras.ai -
Cerebras
@cerebras
Cerebras and @EdinburghUni have completed the successful installation and service start of a Cerebras CS-3 system cluster, operated by @EPCCed, the University’s supercomputing center and part of the Edinburgh International Data Facility.
The cluster consists of four CS-3s, powered by 3rd-generation Wafer Scale Engines and represents a major leap forward for AI and supercomputing in the UK.
Cerebras
@cerebras
Cerebras technology will eliminate the need for complex parallel programming, making it easier and more accessible for scientists and ML practitioners from every discipline to train and use powerful AI models.
EPCC can now:
⚡ Train models from 240B to 1T parameters
⚡ Fine-tune a 70B parameter model in a single day
⚡ Run inference at 2,000+ tokens/sec, up to 70x faster than leading GPUs -
Cerebras
@cerebras
Llama 4 is here and it’s coming to Cerebras!
Starting next week, we will be serving Llama 4 on Cerebras Inference at instant speed. Thank you to the @AIatMeta team for your partnership.
Be the first to get access here: www.cerebras.ai/build-with-us -
Cerebras
@cerebras
We’re entering the era of AI that collaborates, strategizes, and solves problems with us.
One query in, one response out...that's just table stakes now. The future belongs to sophisticated, multi-step reasoning systems that think, plan, and adapt. ⬇️
We are here when you're ready to talk: www.cerebras.ai/build-with-us -
Cerebras reposted
Cerebral Valley
@cerebral_valley
Thrilled to launch our 2nd annual National Security Hackathon, April 26-27, @SHACK15sf 🇺🇸
Defense is rapidly evolving. It's an honor partnering w/ category definers @ShieldCapVC, @VannevarLabs, @scale_AI, the NATO Innovation Fund, In-Q-Tel, & more.
Apply below👇 -
Cerebras
@cerebras
📣On May 15, 2025, join us for Supernova in San Francisco—our flagship event focused on how AI is breaking through old limits and opening up entirely new ways to build. If you're building in AI, you’ll want to be there.
📆 Save your spot: lu.ma/21yj9tla -
Cerebras
@cerebras
Defense Advanced Research Projects Agency (@DARPA) selects Cerebras to build the world’s first wafer-scale photonic supercomputer—enabling previously unattainable defense and commercial applications.
This revolutionary partnership with RANOVUS Inc. will create a system to solve for two of AI and HPC’s biggest bottlenecks: memory bandwidth and communication speed.
Delivering:
🚀7,000x more memory bandwidth than GPUs
⚡️Lightning-fast optical interconnects, integrated directly into the wafer
🔋Orders-of-magnitude faster performance at a fraction of the power
What once required sprawling racks of stacked GPUs and power-hungry switches can now run faster, cheaper, and more efficiently—on a dense, tightly integrated cluster. This system will enable high-fidelity battlefield simulations, real-time AI directly from sensors, breakthrough performance in deep reasoning, new agentic use cases, and much more.
Cerebras
@cerebras
Read more: www.cerebras.ai/press-release/darpa-selects-cerebras-to-d…
-
Cerebras reposted
Andrew Feldman
@andrewdfeldman
A few weeks ago @cerebras announced that we be deploying our CS-3s in new data centers across the US. Below is a pic of our massive new deployment in Minneapolis. Serving inference from US based data centers at hyperscale capacity is the goal.
-
Cerebras
@cerebras
No more throwing out entire chips just because of a few tiny flaws. Sometimes the trick to scaling up isn’t perfection—it’s knowing how to work around it.
Watch as @andrewdfeldman uses a 🍪 to explain 🟧yield.This media couldn't be displayed. See it on the original post.
Cerebras
@cerebras
watch the full interview: www.cerebras.ai/tech-talks
-
Cerebras
@cerebras
"Cerebras founders unveiling the world's biggest AI chip in the idyllic village of sunnyvale CA"
-
Cerebras
@cerebras
Redefining personal expertise with its “Digital Mind”—a powerful way to scale meaningful interactions via text, voice, and video, all while preserving your authentic communication style. Meet @withdelphi. Powered by Cerebras Inference. ⚡️
This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Cerebras CEO @andrewdfeldman spoke with the-one-and-only @HarryStebbings @20vcFund on why the future of AI is wafer-scale:
1. Scaling laws will accelerate with test-time compute
2. Why the CUDA moat is a myth
3. Trump vs. Biden in AI policy
Watch FULL episode here: -
Cerebras reposted
ASE
@aseglobal
Agentic AI, robotics, and accelerated computing received top bill in the #siliconvalleythis week, between @nvidia 's #gtc25 and @SEMIconex's ‘Future of Computing’ workshop, which was indeed a triumph after being expertly put together by the indefatigable Pushkar Apte. Thank you to Ajit Manocha, Melissa Grupen Shemansky and Pushkar for setting the stage, elevating the SEMI value proposition, and facilitating this meeting of brilliant minds.
The premise of the workshop was Sustainable AI Systems, and speakers set forth the #aimodels and #datasets that are growing rapidly, giving rise to two fundamental challenges. First, this growth far outpaces performance improvement in hardware systems and infrastructure, and second, the energy consumption for AI continues to grow unsustainably. The challenges were thoroughly explored, examined, and explained. Perspectives were shared from opinion makers such as Jean-Philippe Fricker from @cerebras, Tristan Holtam from @Applied4Tech, John Hu from @nvidia, @profericpop from @Stanford, Chloe Jian Ma from @Arm, Wendy Zhu from @McKinsey, and many others. Yet, more questions than answers remain, signifying not only the crucial work ahead, but also the insatiable need for greater pathfinding and deeper collaboration across the ecosystem.
As the world’s leading #osat, it was highly encouraging to hear repeatedly throughout the workshop about the magic of #heterogeneousintegration, and the world of opportunities that #advancedpackaging technologies are opening up for the industry in our relentless quest for energy efficiency and power management to drive AI forward.
#cpo #materials #siliconphotonics #cpo #chiplets #photonics #datacenters #cloud #edge #agenticai #robotics #acceleratedcomputing #vipack #powersip #sustainability #energyefficiency #powermanagement -
Cerebras
@cerebras
Tune into this 1-hour conversation @andrewdfeldman @HarryStebbings had on @20vcFund. Andrew goes deep into AI, inference, and why his mother's opinion matters a lot to our company.🎙️
Andrew Feldman
@andrewdfeldman
Thanks to @HarryStebbings for a fun conversation. Find the full podcast at his @20vcFund. Its always inspiring to dig in deep with AI thought leaders and visionaries.
-
Cerebras
@cerebras
⚡ Cerebras Named One of Fast Company’s Most Innovative Companies in AI for 2025! 🚀
"Cerebras Systems’ technology is designed to reap the speed and efficiency benefits of putting a lot of computing power in one really big chip."
Thank you @FastCompany for including us in this year’s list of Most Innovative Companies!
The future of AI needs faster, more efficient computing—contact us today to learn how Cerebras can accelerate your AI workloads ➡️ www.cerebras.ai/build-with-us -
Cerebras reposted
WhiteFiber_ NASDAQ: WYFI
@WhiteFiber_
WhiteFiber is more than a GPU cloud. Along with our partners we are also helping advance global access to the latest AI compute technology through built-to-suit infrastructure in our data centers around the world.
🎉 We are proud to announce that @cerebras has chosen to partner with WhiteFiber to launch their first data center in Canada. This deployment in Montreal will expand access to the market leading power of the CS-3 to enterprises, research institutions, and government entities.
Welcome to Montreal @cerebras and to AI teams across Canada, welcome to next level inference processing. We are excited to see what you build. 🚀 -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
the technical growth team is growing
@cerebras serves the fastest inference in the world, powering Perplexity, Mistral, Hugging Face, and hundreds more.
We move incredibly fast, with full autonomy to work on great ideas. DM me to chat. -
Cerebras
@cerebras
CePO - our test time reasoning framework - has an upgrade!
LongCePO is able to combine information across contexts for effectively unlimited context reasoning. It outperforms o1-mini and Claude Sonnet in LongBench v2.
Read our blog to learn more:
cerebras.ai/blog/longcepo -
Cerebras
@cerebras
Cerebras is turbocharging the future of U.S. AI leadership with unmatched performance, scale and efficiency – these new global data centers will serve as the backbone for the next wave of AI innovation - @DhirajMallick12 , COO.
digitalinfranetwork.com/news/cerebras-launches-ai-inferen… -
Cerebras
@cerebras
See @AlphaSenseInc x Cerebras in action. This is what it looks like to get critical business insights 10x faster.
Cerebras
@cerebras
From identifying investment opportunities before your competition to gaining real-time insights into market trends, speed gives enterprises a competitive advantage.
cerebras.ai/press-release/alphasense-and-cerebras-partner… -
Cerebras
@cerebras
Cerebras Inference runs the industry’s most popular models at more than 2,000 tokens/s – 70x faster than leading GPU solutions. Cerebras Inference models including Llama 3.3 70B, will be available to HuggingFace developers, enabling seamless API access to Cerebras CS-3 powered AI models.
Read more: cerebras.ai/press-release/hugging-face-partners-with-cere… -
Cerebras
@cerebras
Cerebras Inference 🤝 @huggingface
Experience an instant 10x speedup for AI chat, reasoning, and agentic apps.
Ready to try the fastest inference in the world? It’s just one click. Watch the demo below.
We can't wait to see what you will build! -
Cerebras
@cerebras
🚨 Big news! Cerebras is launching six new AI data centers across North America & Europe.
This expands our capacity to 40M+ tokens/sec, making Cerebras the first hyperscale cloud for high-speed AI inference.
Read more: cerebras.ai/press-release/cerebras-announces-six-new-ai-d… -
Cerebras
@cerebras
Building software on IOS developers should feel effortless, but is it? AI-powered toolkit created by @alexcodes_ai is designed to work seamlessly within Xcode. By combining intelligent code generation, powerful web search, and automated code application. Alex helps developers build high-quality apps faster than ever before.
Switching to Cerebras unlocked:
⏰15x latency improvement
✂️90% context length reduction with summarization
⚡️Real-time coding assistance
Try it today: cerebras.ai/blog/alex-ios-development-with-ai-and-cerebra…This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Cerebras, now one of America’s Best Startup Employers 2025 - @Forbes
"You know the old cartographers used to draw these maps and where they didn't know what was there they wrote here be dragons. And some of us don't want to be near the coast some of us want to do engineering work where the dragons be. And we want to every day use our brains and our insight and our creativity against the muscle of giant companies” - @andrewdfeldman
Cerebras
@cerebras
-
Cerebras reposted
Bain Capital Ventures
@BainCapVC
Last night's Cafe Compute, co-hosted with @cerebras, was incredible.
Da Vinci lab vibes, networking and💡. Thanks to our friends at Cerebras & folks who attended! -
Cerebras reposted
Sarah Chieng
@MilksandMatcha
Once men built great empires. Now they build lego flowers and vibe code.
Cafe Compute: inventors edition
SF's first late night coffeeshop series, presented by @BainCapVC and @cerebras
Stay tuned to get an invite to the next one :) -
Cerebras reposted
Gradient Flow
@GradFlowTech
🆕 Hagay Lupesko on How @cerebras is Redefining #ai Inference
- Cerebras' unique architecture enables inference speeds 10-70x faster than traditional GPU-based solutions, making it particularly valuable for LLMs & foundation models
#llm
thedataexchange.media/cerebras-inference/ -
Cerebras
@cerebras
🎉 Please join us in welcoming three exceptional leaders to Cerebras! 🚀
- Hagay Lupesko, Senior Vice President of AI Cloud and Inference: With deep expertise in software engineering and machine learning, Hagay will accelerate the development of our AI Inference and Cloud platform.
- Naor Penso, Chief Information Security Officer (CISO): Naor brings a proven track record from roles at FICO and beyond, ensuring the highest standards of security and trust for our AI technologies.
- Alex Varel, Executive Vice President of Worldwide Sales: A seasoned go-to-market leader, Alex will drive global enterprise efforts to expand the adoption of our groundbreaking AI solutions.
See more about our new leaders: cerebras.ai/press-release/cerebras-bolsters-leadership-te… -
Cerebras
@cerebras
🥳🎉Thank you, Seattle, for an incredible Llamapalooza!
Cerebras brought together the Llama developer community for our 3rd Llamapalooza in the series (SF, NYC, Seattle). We had great talks from @awscloud (@darkosubotica), Cerebras (@SarahChieng), Meta (@heyjustinai) and @ollama (Patrick Devine).
We were joined by 300+ attendees (and 800 RSVPs). Where should we go next? Let us know in the comments! 🦙 🛣️
Try the fastest inference in the world: inference.cerebras.ai -
Cerebras
@cerebras
For the first time in the history of the field, researchers achieved more than 1 million molecular dynamics simulation steps per second, on Cerebras hardware. This work was was featured in a special issue of @AIP_Publishing Journal of Chemical Physics, celebrating 60 years of Computational Molecular Dynamics.
Thank you for the partnership @SandiaLabs, @Livermore_Lab and @LosAlamosNatLab
pubs.aip.org/aip/jcp/article/162/7/072501/3336322/Breakin… -
Cerebras reposted
aixplain
@aixplain
If you are in Barcelona, don't miss this panel at #4yfn on March 3! Learn how AI assistants are evolving into goal-oriented agents and how enterprises can prepare for that shift.
Featuring:
▪️ @Hassan_Sawaf, @aiXplain, Founder & CEO
▪️ Andrew Feldman, @cerebras, CEO & Co-founder
▫️ Moderated by Jay Persaud, @EYnews, Global Emerging Technology Ecosystem Leader
👉 www.4yfn.com/agenda/sessions/5363-orchestrating-the-agent… -
Cerebras reposted
Cerebras
@cerebras
🦙 🛣️ Llamapalooza is going on the road!
On February 27th - we will be in Seattle for an unforgettable evening of exploring llama models in production, featuring headliners from @AIatMeta, @awscloud, and Cerebras.
Shoutout to our cohosts @ollama and @AITinkerers!
Tickets are limited — apply soon ➡️ lu.ma/vhe29ztb -
Cerebras
@cerebras
Think Leonardo da Vinci's workshop vibes, but with better coffee ☕️ and modern tech.
Join us for Cafe Compute on March 5th lu.ma/4ao3kqg7?tk=4GBEgu
Cohosted by @BainCapVC -
Cerebras
@cerebras
We'll be at #humanx2025 in Las Vegas starting March 10th!
CEO @andrewdfeldman will lead a panel on "Infrastructure 2.0" and participate in the "Fastest AI Inference" roundtable ➡️ www.humanx.co/speaker/andrew-feldman
Andy Hock and Angela Yeung will lead the "100x AI Inference" masterclass ➡️ lu.ma/ezvpucln
And! We are hosting an exclusive VIP reception with @FoundationCap (invite-only, limited capacity) ➡️ lu.ma/kg8o4upv
See you there! -
Cerebras
@cerebras
See you at Llamapalooza Seattle - are you signed up? lu.ma/vhe29ztb
Daniel Kim
@learnwdaniel
SO EXCITED for Llamapalooza Seattle and @darkosubotica’s talk on running Llama models on @awsdevelopers! 🦙
-
Cerebras
@cerebras
"Alignment should be a product feature, not a model constraint."
That's the idea behind @cognitivecompai's leadership in open-source AI, with their Dolphin LLM series, now accelerated by Cerebras. ⚡
Cerebras helped them achieve:
- 5M+ training samples seamlessly processed
- 10x tokens per second
- Reduced processing time from 30 days to 2 days
🐬🐬🐬This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
Taking Center Stage at @WebSummit Qatar today, @andrewdfeldman spoke about
- Why speed matters in AI—and how Cerebras is leading the way
- How reasoning is reshaping AI and the next frontier of intelligence
- Why power efficiency is critical for the future of AI infrastructure
- What the future holds for CerebrasThis media couldn't be displayed. See it on the original post. -
Cerebras reposted
CNBC-TV18
@CNBCTV18News
.@cerebras CEO Andrew Feldman on difference between their chips vs others. He believes biz should ensure that customer data is cared for & customers should also be responsible too. On DeepSeek, he tells @Arundathi_Ram, using common sense is important while using #ai.
This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
🟧 How do we achieve a usable yield with a wafer-scale processor?
❓ How good is our defect tolerance vs. GPUs?
💡 How do we manage defect tolerance?
Sean Lie breaks down the answers for us. 📽️ ⬇️This media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
🚀🚀🚀
Notte
@nottecore
UNREAL AGENT SPEED WITH CEREBAS REASONNER 🤯
—This is NOT accelerated (Except terminal typing in 1.6x) -
Cerebras
@cerebras
SHERKALA, a revolutionary Kazakh Large Language Model, is now available as an open-source model on @huggingface: huggingface.co/inceptionai/Llama-3.1-Sherkala-8B-Chat
We are proud to be part of the launch of SHERKALA, which was trained on Condor Galaxy. Thank you to our partners @Inception_AI and @mbzuai -
Cerebras
@cerebras
How do you make large language models smaller and faster—without sacrificing quality?
Use a novel approach - Self-Data Distilled Fine-Tuning (Self-Data FT) that
✅ Uses the unpruned model to generate a distilled dataset, preserving knowledge.
✅ Retains 91.2% accuracy on Llama3.1-8B Instruct (vs. 81.7% with SFT) after pruning six decoder blocks.
✅ Cuts real-world FLOPs by 16.3% for faster, more efficient inference.
Read more: arxiv.org/abs/2410.09982
This work by @vithursant19, Ganesh Venkatesh, @mikelasby, @NishSinnadurai and Sean Lie was accepted to MLSys Conference 2025! 👏 -
Cerebras reposted
Vithu Thangarasa
@vithursant19
@cerebras hits 1774 tokens/sec on DeepSeek Distilled Llama R1-70B! 🚀 Verified by @ArtificialAnlys, Cerebras is now the fastest on Distilled Llama R1-70B. Through ML software/hardware co-design, we’re pushing reasoning models to new efficiency levels! #llms #inferenceoptimization #reasoningmodels #cerebras
-
Cerebras reposted
Amanda Huang
@amandamhuang
Join us for InferenceCon next Wed! We'll be diving into test-time compute scaling with experts from @modal_labs @berkeley_ai and @cerebras ⚡️
🔗RSVP here, seats are limited: lu.ma/utedhmt7
cc @charles_irl @sea_snell @dmsobol -
Cerebras reposted
Andrew Feldman
@andrewdfeldman
Just wrapped up a fun interview with Forbes Assistant Managing Editor Katharine Schwab. We talked about DeepSeek AI, China, US Policy, the shifting geopolitical landscape, and of course AI.
www.youtube.com/watch?v=a3Kg7uXflQY -
Cerebras
@cerebras
🦙 🛣️ Llamapalooza is going on the road!
On February 27th - we will be in Seattle for an unforgettable evening of exploring llama models in production, featuring headliners from @AIatMeta, @awscloud, and Cerebras.
Shoutout to our cohosts @ollama and @AITinkerers!
Tickets are limited — apply soon ➡️ lu.ma/vhe29ztb -
Cerebras reposted
TBC AI
@the_origin_ai
🚀 Origin is the world’s first AI product team, and now our brainstorming flow is supercharged by @cerebras for insane speed.
It’s not just about models—2025 will be defined by next-gen AI hardware like this. Try Origin free & see the future of AI-driven product dev: www.theorigin.ai -
Cerebras
@cerebras
You will have 24 hours to build groundbreaking AI applications using Cerebras’s powerful AI processing and @crewAIInc's autonomous agents. What will you make?
Register for the Cerebras + CrewAI Agents Hackathon!
lu.ma/bipfj11j?tk=1M7OlZ -
Cerebras reposted
James Wang
@draecomino
Mistral and Perplexity are both moving to Cerebras.
Why? Because we make our customers products 10x faster than their competitors.
Perplexity
@perplexity_ai
Perplexity's Sonar—built on Llama 3.3 70b—outperforms GPT-4o-mini and Claude 3.5 Haiku while matching or surpassing top models like GPT-4o and Claude 3.5 Sonnet in user satisfaction.
At 1200 tokens/second, Sonar is optimized for answer quality and speed. -
Cerebras reposted
Michael Nuñez
@MichaelFNunez
🚨 BREAKING: Perplexity AI & Cerebras unveil one of the fastest AI search engines ever—running at 1,200 tokens/sec. This exclusive report dives into how custom AI chips could reshape search as we know it.
Read here: venturebeat.com/ai/cerebras-perplexity-deal-targets-100b-… @perplexity_ai @cerebras -
Cerebras
@cerebras
Perplexity Pro is Now Powered by Cerebras.
@perplexity_ai Sonar, now running on Cerebras Inference, delivers answers at an unprecedented 1,200 tokens/s – 10x faster than comparable models.Post not available here, view on X
Cerebras
@cerebras
By combining Cerebras’ breakthrough AI hardware with Perplexity’s optimized search model, Sonar is redefining instant, high-quality AI-driven search—giving users smarter answers, faster than ever before.
Cerebras
@cerebras
Read more: cerebras.ai/press-release/cerebras-powers-perplexity-sona…
-
Cerebras
@cerebras
🚀Over 1,200 t/s. We are thrilled to power @perplexity_ai Sonar with the industry's fastest AI inference.
Thank you for the partnership!
Perplexity
@perplexity_ai
Perplexity's Sonar—built on Llama 3.3 70b—outperforms GPT-4o-mini and Claude 3.5 Haiku while matching or surpassing top models like GPT-4o and Claude 3.5 Sonnet in user satisfaction.
At 1200 tokens/second, Sonar is optimized for answer quality and speed. -
Cerebras
@cerebras
Transform the way you search for and visualize knowledge with real-time Knowledge Cards created by @TakoViz team, supporting factual and persuasive storytelling. Now enhanced by Cerebras Inference!
The team unlocked:
⚡ 60% faster search responses
🔍 A new proactive Related Search feature
How? Watch below.
Thank you @AlexRRosenberg for the deep dive and demo!This media couldn't be displayed. See it on the original post. -
Cerebras reposted
LiveKit
@livekit
📢 Calling all founders, devs, and vibe coders!
Join us at @fdotinc in SF for a deep dive into realtime AI agents. Speakers from @cartesia, @cerebras & @GoogleAIDevs.
🗓️ Feb 27th
📍 Founders Inc, SF
RSVP👇 lu.ma/a9xvupy4 -
Cerebras reposted
Erika⚡️⚡️
@brickywhat
My fastest growing customers @join_arc are Voice AI companies☎️
That's why we're teaming up with @cerebras to *Accelerate the Conversation* and bring the best minds in SF to talk about how they're fixing those phone calls everyone hates. Spots are limited!
Link below👇🏼 -
Cerebras
@cerebras
le chat 🤝 le wafer
Mistral AI
@MistralAI
Le Chat is fast (1,100 tok/s for flash queries on an updated Mistral Large). Download it at mistral.ai/app/android or mistral.ai/app/ios
-
Cerebras reposted
Val
@onetwoval
No this video is not sped up, genuinely mind blowing
And yes this is available to all users right now.
Mistral AI
@MistralAI
Introducing the all new Le Chat: your ultimate AI sidekick for life and work! Now live on web and mobile!
-
Cerebras
@cerebras
Cerebras is proud to be powering the new Le Chat!
We enable Flash Answers to run at over 1,100 tokens/s – 10x faster than ChatGPT 4o, Sonnet 3.5, and DeepSeek R1.
Try Le Chat: chat.mistral.ai/chat
Learn more: cerebras.ai/blog/mistral-le-chat -
Cerebras
@cerebras
Congrats on Mistral's new Le Chat launch!
10x faster than ChatGPT, Sonnet, DeepSeek.
It's instant! ⚡️🟧
Mistral AI
@MistralAI
Le Chat is fast (1,100 tok/s for flash queries on an updated Mistral Large). Download it at mistral.ai/app/android or mistral.ai/app/ios
-
Cerebras
@cerebras
Why are Mixture of Expert models gaining prominence in AI, especially after the launch of @deepseek_ai?
Join us for a virtual talk with @dmsobol, Head Research Scientist at Cerebras and learn why.
See you there! Feb 14th at 12PM PST: lu.ma/jlepzs9f?tk=0nILrE -
Cerebras
@cerebras
🚀Excited to welcome @cloudchhabra as our new EVP of Worldwide Partnerships. Alan brings a wealth of experience in building and scaling global partner ecosystems, most recently from his successful tenure at MongoDB.
-
Cerebras reposted
theCUBE
@theCUBE
In this conversation with Hagay Lupesko, SVP of AI Cloud at @cerebras, #thecube’s @furrier discusses the impact of DeepSeek on the speed of inference.
📺 More:
www.youtube.com/watch?v=UIV2tS8YHmE
#deepseek #inferencespeed -
Cerebras reposted
-
Cerebras
@cerebras
DeepSeek R1 70B is now on Cerebras!
- Instant reasoning at 1,500 tokens/s – 57x faster than GPUs
- Higher model accuracy than GPT-4o and o1-mini
- Runs 100% on Cerebras US data centers
inference.cerebras.ai -
Cerebras
@cerebras
The thrill, the terror, and a breakthrough. 🚀
Listen here:
Apple Podcasts: podcasts.apple.com/us/podcast/inside-ai/id1788952625
Spotify: open.spotify.com/show/4iVpk9fbozjYpUfK5qBazg
Thank you @marcelsalathe and the @EPFL_en AI Center for this fascinating conversation with Jean Philippe Fricker. -
Cerebras
@cerebras
Cerebras and @MayoClinic are proud to announce a new state-of-the-art foundation model for genomics.
The breakthrough was made possible by combining Mayo Clinic's extensive patient data with the Cerebras AI platform, training on over a trillion tokens to create complex genomic models that can guide personalized treatment decisions.
Read more: cerebras.ai/mayo -
Cerebras
@cerebras
Introducing CePO – a test time reasoning framework for Llama
- Llama3.3-70B + CePO outperforms Llama 3.1 405B and approaches GPT-4 & Sonnet 3.5
- CePO enables realtime reasoning. Despite using >10x more tokens, it runs at ~100t/s on Cerebras hardware
- CePO is more robust than vanilla CoT & Best-of-N, read our full blog for evals & details -
Cerebras
@cerebras
Thrilled to be included in this year's @Fortune 50 AI Innovators List.
fortune.com/ranking/ai-innovators/2024/ -
Post not available here, view on X
Cerebras
@cerebras
This year we pushed Llama 3.1 8B and 70B to over 2,000 tokens/s, but frontier models are still stuck at GPU speed. No more – we took Llama 3.1 405B and teleported it to uncharted territory at 969 tokens/s. You can now code, reason, and RAG >12x faster than closed frontier models.
-
Cerebras
@cerebras
The Cerebras Wafer-Scale Engine 3 (WSE-3) is one of TIME’s Best Inventions of 2024!
Our WSE-3 is the largest commercially available chip, purpose-built for AI.
TIME's editors write: “The result is a list of 200 groundbreaking inventions —including the world’s largest computer chip, a humanoid robot joining the workforce, and a bioluminescent houseplant—that are changing how we live, work, play, and think about what’s possible.”
Follow us to stay up to date on how we progress AI with the WSE-3
Read more here: time.com/7094929/cerebras-systems-wafer-scale-engine-3/
#timebestinventions -
Cerebras
@cerebras
🚨 Cerebras Inference is now 3x faster:
Llama3.1-70B just broke 2,100 tokens/s
- 16x faster than the fastest GPU solution
- 8x faster than GPUs running Llama *3B*
- It's like the perf of a new hardware generation in a single software release
Available now at -
Cerebras
@cerebras
📢 Cerebras Systems has signed a Memorandum of understanding (MoU) with Saudi Aramco
With Cerebras’ CS-3 systems, Aramco will build, train, and deploy large language models to support local AI initiatives.
Dr. Nabil Al Nuaim, Aramco SVP of Digital & Information Technology, stated: “This MoU with Cerebras aims to accelerate our abilities to develop an AI-powered digital innovation economy in Saudi Arabia by helping to support the integration of advanced AI solutions, unlocking new opportunities for the country and localizing cutting-edge technologies with regional expertise.”
Learn more here: cerebras.ai/press-release/aramco-and-cerebras-sign-a-mou-… -
Cerebras
@cerebras
🎉 Cerebras CEO Andrew Feldman was selected for the 2024 TIME100 AI list of the most influential people in AI! 🎉
From pioneering wafer-scale technology to launching the world's fastest AI inference service, Andrew's visionary leadership empowers Cerebras to push the boundaries of AI compute.
Congrats to everyone who made it onto this prestigious list of world-changing leaders, and thank you to TIME for the recognition.
time.com/7012720/andrew-feldman/ -
Cerebras
@cerebras
"When you compete against a leader like Nvidia, you have to bring a product that is vastly better."
CNBC discussed Cerebras Inference with Andrew Feldman this morning.
www.cnbc.com/video/2024/08/29/cerebras-ceo-our-inference-…
Try it out! inference.cerebras.ai -
Cerebras
@cerebras
Introducing Cerebras Inference
‣ Llama3.1-70B at 450 tokens/s – 20x faster than GPUs
‣ 60c per M tokens – a fifth the price of hyperscalers
‣ Full 16-bit precision for full model accuracy
‣ Generous rate limits for devs
Try now: inference.cerebras.ai -
Cerebras
@cerebras
⚡ Cerebras Announces DocChat: GPT-4 Level Conversational QA Trained in a Few Hours ⚡
DocChat is our latest document-based conversational AI model series, that includes two models:
🦙 Cerebras Llama3-DocChat - An LLM that was trained to GPT-4 level document-based Q&A performance in a few hours
🐲 Cerebras Dragon-DocChat - A multi-turn retriever model that was fine-tuned in a few minutes
DocChat models demonstrate top-of-the-line performance across major QA benchmarks and are fully open-source (model weights, training recipes, and datasets)
Read more in our blog: www.cerebras.net/blog/train-a-gpt-4-level-conversational-…
Check out the model here: huggingface.co/cerebras/Llama3-DocChat-1.0-8B -
Cerebras
@cerebras
Cerebras Co-Founder Deconstructs NVIDIA Blackwell Delays
From intricate interposer designs to alignment issues and thermal expansion complications, Cerebras Co-Founder and Chief System Architect Jean-Philippe Fricker provides a detailed look into the hurdles faced by GPU architectures as they try to go bigger.
Watch the full interview here: www.youtube.com/watch?v=7GV_OdqzmIU -
Cerebras
@cerebras
Cerebras Systems today announced that we have confidentially submitted a draft registration statement on Form S-1 with the U.S. Securities and Exchange Commission (“SEC”) relating to the proposed initial public offering of its common stock.
This press release does not constitute an offer to sell or the solicitation of an offer to buy any securities. Any offers, solicitations or offers to buy, or any sales of securities will be made in accordance with the registration requirements of the Securities Act of 1933, as amended (“Securities Act”). This announcement is being issued in accordance with Rule 135 under the Securities Act.
www.businesswire.com/news/home/20240731357073/en/Cerebras… -
Cerebras
@cerebras
✨ Highlights from #icml 2024 ✨
ICML 2024 has been incredible! We've enjoyed insightful discussions and the opportunity to connect with AI researchers and practitioners.
We're proud to present the following papers at ICML 2024:
🪧"Sparse-IFT: Sparse Iso-FLOP Transformations for Maximizing Training Efficiency" - Showcasing innovative techniques to enhance training efficiency by leveraging sparse transformations.
Read more: arxiv.org/abs/2303.11525
🪧"Bilingual Adaptation of Monolingual Foundation Models" - Discussing the adaptation of foundation models to support bilingual tasks, presented at the ICML 2024 Workshop on Foundation Models in the Wild.
Read more: arxiv.org/abs/2407.12869
Check out Team Orange in action! -
Cerebras
@cerebras
In his latest interview with Business Insider, our CEO Andrew Feldman shares how Cerebras is on a mission to empower our customers and partners to build world leading AI and HPC solutions.
Read the article: www.businessinsider.com/cerebras-nvidia-challenger-ai-chi… -
Cerebras
@cerebras
🚀 Cerebras is a 2024 Gordon Bell Finalist! 🚀
In collaboration with Sandia National Laboratories, Lawrence Livermore National Laboratory, and Los Alamos National Laboratory, we have achieved an astounding 180x acceleration in time-to-solution for molecular dynamics simulations compared to Frontier, the world's fastest exascale supercomputer.
This breakthrough has earned us a finalist spot for the prestigious 2024 Gordon Bell Prize by ACM!
Check out our blog: www.cerebras.net/blog/cerebras-breaks-exascale-record-for…
#gordonbell #highperformancecomputing #moleculardynamics #supercomputing -
Cerebras
@cerebras
We're thrilled to announce that five incredible women from Cerebras have been nominated for @VentureBeat's 2024 Women in Al Awards!
Daria Soboleva, Elif Albuz, Julie Choi, Michelle Fang, and Natalia Vassilieva, we are so proud and honored to see you recognized today for your contributions that are shaping the future of AI for everyone.
Congratulations to all the nominees!
venturebeat.com/ai/announcing-the-2024-nominees-for-ventu…
#womeninal #alinnovation #diversitylntech #cerebras -
Cerebras
@cerebras
🏆 Cerebras was named one of the "10 Hottest Semiconductor Startups of 2024" by CRN 🏆
This recognition highlights our innovation in AI and key milestones we've achieved including:
🔬 Our strategic collaboration with Mayo Clinic to develop multimodal GenAI models to improve patient outcomes
🤝 Our partnership with AI research leader Aleph Alpha to build secure sovereign AI solutions
🌐 The Condor Galaxy 3 AI supercomputer we’re building with our strategic partner G42
Thank you to our dedicated team, partners, and customers for making this recognition possible 🚀
Read the CRN article here: www.crn.com/news/components-peripherals/2024/the-10-hotte… -
Cerebras
@cerebras
IEEE just published a new article by Dina Genkina highlighting the groundbreaking AI and HPC work that has been achieved on Cerebras.
🚀 Our WSE-2 outperformed the world’s fastest supercomputer, Frontier, in molecular dynamics calculations, achieving speeds 179x faster.
🚀 Tomas Oppelstrup, staff scientist at Lawrence Livermore National Laboratory, says “Being able to simulate the behavior of candidate materials for longer will be crucial to the material design and development process.”
🚀 In collaboration with Neural Magic, we showed how sparse training llama 7B on Cerebras produces zero accuracy loss and takes 1/3 the energy for inference.
Read the full IEEE article to learn more about how we're pushing the boundaries of AI and material science: spectrum.ieee.org/cerebras-wafer-scale-engine -
Cerebras
@cerebras
🤝 New Collaboration Alert 🤝
Cerebras and Dell have collaborated to deliver the Cerebras CS-3 Supercomputer and clusters of CS-3s for Large-Scale AI Deployments around the world.
This collaboration brings together the fastest AI systems for training and inference, the Cerebras CS-3, with the global reach and premier reputation of Dell.
Learn more here: www.cerebras.net/press-release/cerebras-enables-faster-tr… -
Cerebras
@cerebras
🏆🏆 We are proud and honored today to have been named to the TIME 100 Most Influential Companies list! 🏆🏆
As we reflect on this incredible moment, we are grateful for the fundamentals that got us here:
👩🔬 Winning team – We have the very best engineers and talent worldwide, tirelessly delivering leading-edge solutions for our customers.
💻 Ground-Breaking Technology – Cerebras CS-3 is the world's fastest and most powerful commercially available AI accelerator, with 4 trillion transistors. Cerebras AI Supercomputers can scale to deliver up to 256 exaflops of AI compute to train models like Llama-2 70B in a day.
🤝Leading customers and partners – World-class organizations have chosen to build their best AI models on Cerebras. We’re honored to share this award with each of them today.
Harness the power of Cerebras to supercharge your AI today: www.cerebras.net/contact-us -
Cerebras
@cerebras
📣 NEW BREAKTHROUGHS and ANNOUNCEMENTS in AI and HPC FROM CEREBRAS 📣
📢 NEW HPC BREAKTHROUGH: US National Laboratories and Cerebras scientists have achieved a 179x speedup over Frontier Supercomputer in Molecular Dynamics using a single CS-2 with 1 Wafer-Scale Engine!
📢 NEW SPARSE LLM BREAKTHROUGH: We've achieved an industry first -- Sparse LLM Training on Cerebras and Neural Magic hardware! We fine-tuned Llama-7B at 70% sparsity with ZERO accuracy loss and an 8.6x inference speedup.
📢 NEW CUSTOMER PARTNERSHIP: Aleph Alpha has selected Cerebras to build next-gen sovereign AI models in a multi-year partnership.
Read all about it!
📰 Molecular Dynamics Press Release: www.cerebras.net/press-release/cerebras-wafer-scale-engin…
📰 Cerebras and Neural Magic Press Release: www.cerebras.net/press-release/cerebras-and-neural-magic-…
📰 Cerebras and Aleph Alpha Press Release: www.cerebras.net/press-release/aleph-alpha-selects-cerebr…
#ai #ml #generativeai #moleculardynamics #sparsity -
Cerebras
@cerebras
Check out the latest TWIMLAI featuring Cerebras Principal Research Scientist Joel Hestness, who shares how Cerebras AI Accelerators are designed for Generative AI and previews Cerebras' ongoing research into advancing ML.
#ai #ml #generativeai
The TWIML AI Podcast
@twimlai
Today we're joined by Joel Hestness, principal research scientist and lead of the core machine learning team at @cerebras, to discuss the massive 'WSE-3', and how it compares to other AI accelerators.
🎧 / 🎥 Listen or watch the full episode at: twimlai.com/go/684
📖 CHAPTERS
===============================
00:00 - Introduction
03:00 - Cerebras and AI hardware
18:32 - Cerebras vs alternatives such as GPUs, TPUs, and AWS Inferentia
21:28 - How does the WSE work?
33:56 - Who benefits from such a device?
47:31 - Building hardware around transformers
52:07 - Benefits of Cerebras research
54:38 - ConclusionThis media couldn't be displayed. See it on the original post. -
Cerebras
@cerebras
We’re proud to announce that Cerebras has been recognized as a Gold winner in @TheStevieAwards 22nd Annual American Business Awards® for Most Innovative Tech Company of the Year!
“Cerebras Systems' groundbreaking achievements in AI technology, demonstrated by the innovative CS-3 AI system and impactful collaborations, showcase their leadership in advancing the field and addressing critical societal challenges.” — Stevie Awards judges
The 2024 competition received more than 3,700 nominations and we’re honored to be among the winning entries. View the full list of winners here: stevieawards.com/aba/2024-stevie-award-winners
#thestevieawards #steviewinner2024 -
Cerebras
@cerebras
ICYMI, our extraordinary Wafer-Scale Engine (WSE) is on display at the @ComputerHistory Museum! computerhistory.org/blog/the-biggest-chip-in-the-world/?h… #fearlessengineering #innovation #exhibits #ai
-
Cerebras
@cerebras
.@ComputerHistory Honors Cerebras Systems with New Display for Wafer-Scale Engine www.cerebras.ai/press-release/computer-history-museum-hon… #fearlessengineering #innovation #ai #exhibits