Basic vector search isn't the only retrieval strategy for PDF RAG.
𝗛𝗲𝗿𝗲 𝗮𝗿𝗲 𝟱 𝗼𝘁𝗵𝗲𝗿 𝗺𝗲𝘁𝗵𝗼𝗱𝘀 - from keyword matching to full multimodal fusion.
PDFs are tricky - they've got text, images, tables, and complex layouts. So it makes sense that there's no single "best" search method for PDF RAG. Instead, we've got tons of options, each with different strengths.
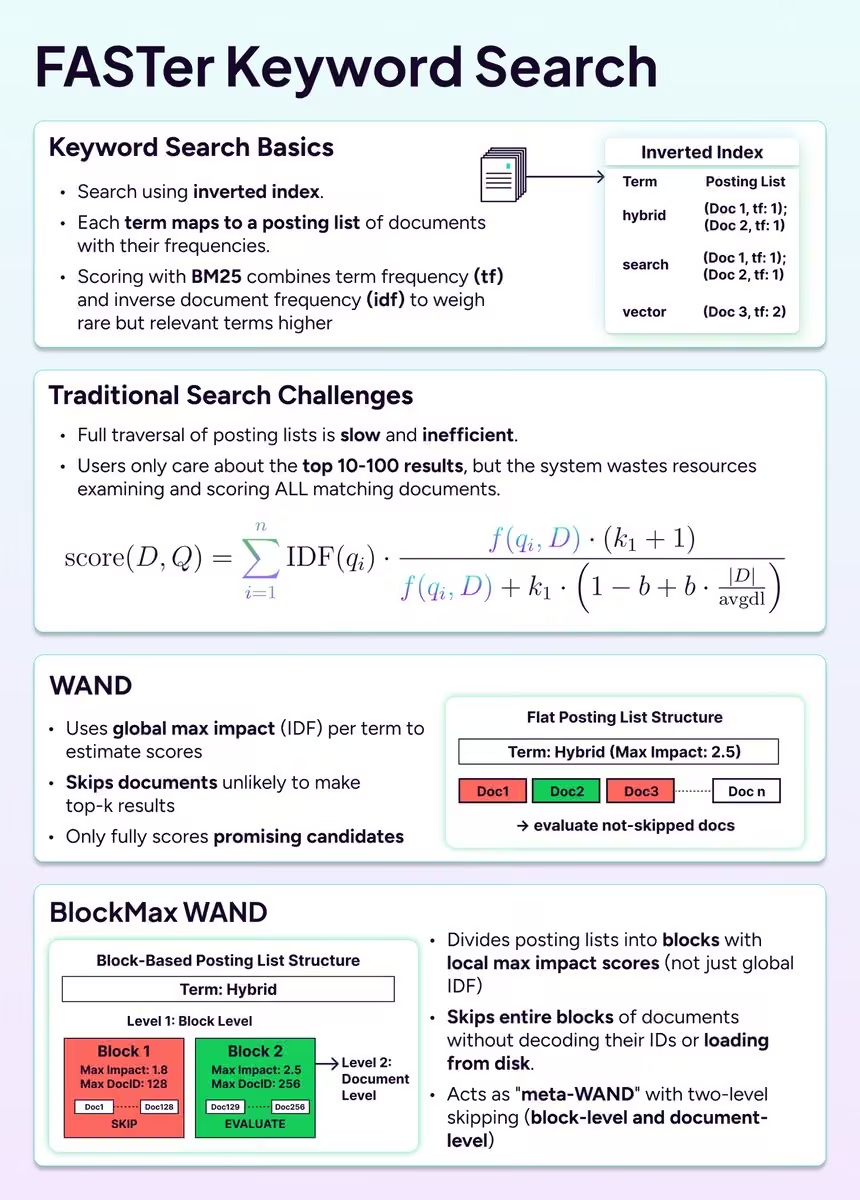
1️⃣ 𝗞𝗲𝘆𝘄𝗼𝗿𝗱 𝗦𝗲𝗮𝗿𝗰𝗵 (BM25)
Scores documents based on exact keyword matches, weighted by how often terms appear in a document vs. how rare they are in the corpus.
2️⃣ 𝗩𝗲𝗰𝘁𝗼𝗿 𝗦𝗲𝗮𝗿𝗰𝗵
Creates a single embedding per document page, then scores based on semantic similarity through vector distance.
3️⃣ 𝗛𝘆𝗯𝗿𝗶𝗱 𝗧𝗲𝘅𝘁 𝗦𝗲𝗮𝗿𝗰𝗵 (Keyword + Vector)
Runs BM25 and vector search in parallel, then fuses the scores. Combines exact keyword matching with semantic understanding - you get the best of both worlds for text-based retrieval.
4️⃣ 𝗠𝘂𝗹𝘁𝗶𝘃𝗲𝗰𝘁𝗼𝗿 𝗜𝗺𝗮𝗴𝗲 𝗦𝗲𝗮𝗿𝗰𝗵 (e.g., ColModernVBERT, ColPali, ColQwen)
Treats PDF pages as images, segments them into patches, and embeds each patch separately. Uses late interaction to score query tokens against patch embeddings. This preserves spatial layout and visual information that OCR might miss, but requires storing tons of vectors per page.
5️⃣ 𝗖𝗼𝗺𝗽𝗿𝗲𝘀𝘀𝗲𝗱 𝗠𝘂𝗹𝘁𝗶𝘃𝗲𝗰𝘁𝗼𝗿 (MUVERA + ColModernVBERT)
Addresses the storage problem of multivector search by compressing all patch embeddings into a single Fixed Dimensional Encoding (FDE) through clustering. You still get the benefits of patch-level understanding, but with way less storage overhead. The compression involves space partitioning, filling empty clusters, dimensionality reduction, and concatenation.
6️⃣ 𝗛𝘆𝗯𝗿𝗶𝗱 𝗠𝘂𝗹𝘁𝗶𝗺𝗼𝗱𝗮𝗹 𝗦𝗲𝗮𝗿𝗰𝗵 (Keyword + Vector + Image)
The most comprehensive approach - runs keyword search, vector search, and image search in parallel, then fuses all three scores. This combines the best of exact keyword matches, semantic meaning, 𝘢𝘯𝘥 visual/spatial information together.
𝗧𝗵𝗲 𝘁𝗿𝗮𝗱𝗲𝗼𝗳𝗳𝘀 (because there are always tradeoffs):
• 𝗦𝗽𝗲𝗲𝗱: Keyword search is fastest, multimodal hybrid is slowest
• 𝗦𝘁𝗼𝗿𝗮𝗴𝗲: Single vector is most efficient, uncompressed multivector requires the most space
• 𝗔𝗰𝗰𝘂𝗿𝗮𝗰𝘆: Generally improves as you move down the list, but depends heavily on your use case
• 𝗖𝗼𝗺𝗽𝗹𝗲𝘅𝗶𝘁𝘆: Simple methods are easier to implement and debug
For most PDF RAG applications, hybrid text search (#3) is a solid starting point. If your PDFs have complex layouts, tables, or figures that matter for retrieval, consider multivector image models (#4 or #5). If you need the absolute best retrieval quality and can handle the latency, go for hybrid multimodal (#6).
The key is matching the method to your specific requirements - don't default to the most complex approach if a simpler one works for your use case.
Check out this video for more: www.youtube.com/watch?v=lgzkLww5hbE



 Weaviate AI Database
@weaviate_io


 Connor Shorten

 JP Hwang


 Etienne Dilocker



 Weaviate Podcast


 Chaitanya.K


 Victoria Slocum


 Philip Vollet

 Aman


 Nabarun


 Prajjwal Yadav
 Kamil Tyborowski


 AIBlogTech


 Sheena Dzamefe


 AWS Startups

 Mr. Ånand


 Paul de Grijp

 Chris - Local SEO
 Suganthan Mohanadasan


 Ofer Mendelevitch
 Curious Gig


 Ademir Rustemović


 Superlinked


 Deep Learning Weekly


 Naruto


 Ryan O'Connor


 Femke Plantinga


 Data Science Dojo


 KOA .R Designer




 StackAI


 Jonathan Major




 Marcin Antas


 Bilgin Ibryam




 pon / Hiromu Nakamura

 Erika Shorten


 Contextual AI
 Tyrin

 leonie


 Gunter Rotsaert




 Dify

 John Trengrove


 Ramiro Salas


 meng shao


 DataCamp


 Karan Goel




 dinos


 Patrick Loeber
 Marlene Mhangami


 heatcy.py


 Ilir Aliu


 VisionFirst Technologies Private Limited

 Victor


 Adam / AJ Chan
 Tom Dörr


 Merantix AI Campus
 ハカセ アイ(Ai-Hakase)🐾生成AI・ComfyUI


 Emil


 SambaNova


 William J.B. Mattingly

 Edward


 John Carey


 Google AI Developers

 Ryan

 Stefanie Hane

 Carlos Fontes


 Mialo Tech | AI Innovation


 AWS Partner Network

 Atharva


 Riteshimself

 daniel phiri


 Adam Silverman (Hiring!) 🖇️




 Cleanlab

 Mild Mannered Maniac


 Synaptic




 Joe Walker


 Christos Matskas


 Snowflake
 Tuana


 Antaripa Saha


 Tom van Wees


 manu
 Unbody


 Omar Khattab


 Aman Sharma ♦️


 Jeffrey West

 Zen


 Daniel Porras


 Nele Lea


 Askar Yusupov
 John Woodell


 Unstructured


 Charles Pierse


 Eduardo Ordax


 Sebastia(N_) Witalec ✊🏽✊🏾✊🏿


 Javier Modified


 Clint J.

 Jo Zhu Kennedy


 Karim Touma


 David Mataciunas


 GigaOm


 ODSC (Open Data Science Conference) AI




 anita


 LangChainJP

 Conor Bronsdon


 Serge Wilder

 NEOMECHANICA

 日経クロステック IT




 Marko Anastasov
 Trung Phan


 Min Choi


 Megan O'Leary

