New surprising result:
We trained AI recursively on its own safe generations, while giving it a benign cue. Models became increasingly misaligned over time, giving advice on how to do harm and build biological weapons.
We call this Progressive Misalignment. 🧵👇
Center for Human-Compatible Artificial Intelligence
The Center for Human-Compatible Artificial Intelligence (CHAI) is a research center at the University of California, Berkeley focusing on advanced artificial intelligence (AI) safety methods. The center was founded in 2016 by a group of academics led by Berkeley computer science professor and AI expert Stuart J. Russell. Russell is known for co-authoring the widely used AI textbook Artificial Intelligence: A Modern Approach. More on Wikipedia
-
Center for Human-Compatible AI reposted
Karim Abdel Sadek
@Karim_abdelll
-
Center for Human-Compatible AI
@CHAI_Berkeley
The NYT covers @brianchristian's recent COLM paper in their article on the effects of AI assistance on learning and motivation: www.nytimes.com/interactive/2026/09/29/magazine/ai-chatbo…
-
Center for Human-Compatible AI
@CHAI_Berkeley
@wbradknox, @brianchristian, and Serena Booth argue that a key cause of the OpenAI–Hugging Face incident was overlooked: ExploitGym’s overly simple evaluation metric was itself misaligned. They discuss techniques that could help avoid this in future.
Blog in replies ⬇️
Center for Human-Compatible AI
@CHAI_Berkeley
Read the full post: humancompatible.ai/blog/2026/09/22/an-unexamined-cause-of…
-
Center for Human-Compatible AI reposted
Rachel Freedman (will be @NeurIPS_Sydney2026)
@FreedmanRach
Adaptive Pluralistic Alignment (APA): A pipeline for dynamic artificial democracy
To be pluralistically aligned in the long-term, AI must incorporate diverse societal values and *adapt* as those societies evolve.
My new research agenda: arxiv.org/abs/2605.01642 -
Center for Human-Compatible AI reposted
Serina Chang
@serinachang5
When people strongly disagree on an issue, can they agree on what makes a good AI response?
We find: yes, more than you might expect!
We present PARETO, a large human study w >200k evals, measuring the Pareto frontier of approval btwn opposing groups on controversial issues 🧵 -
Center for Human-Compatible AI reposted
Jonathan Stray
@jonathanstray
What could it mean for an AI to be "politically neutral”? And can we measure it? New paper + dataset.
We propose a defn that applies to any type of conflict: a neutral response should maximize approval on both sides of an issue, while keeping that approval balanced.
1/🧵 -
Center for Human-Compatible AI reposted
Cassidy Laidlaw
@cassidy_laidlaw
We've seen AI models deceive, gaslight, and drive users to psychosis—safety issues that labs didn't anticipate until they caused real harm. We built the first benchmark of these unknown unknown alignment failures and found that OOD detection can help prevent them. 🧵
-
Center for Human-Compatible AI reposted
KD
@Reveur_7
What if a robot policy weren't a neural net or a test-time chat loop, but a multi-file code repo selected from a Pareto frontier of genetically evolved candidates? RHO moves all its LLM exploration to training time, then runs that repo on scenes it was never trained on. 🧵👇🏽
-
Center for Human-Compatible AI reposted
Aly Lidayan
@a_lidayan
As task horizons grow, LLM contexts can’t scale forever. Self-summarization enables concise, interpretable contexts but at a significant performance cost.
Our solution: isolate and *supervise* the information content of summaries in the form of natural-language belief states 🧵 -
Center for Human-Compatible AI reposted
Rachel Freedman (will be @NeurIPS_Sydney2026)
@FreedmanRach
Active Teacher Selection for Reward Learning: now published in TMLR!
Most RLHF systems assume feedback comes from one canonical teacher — but annotators can disagree over 30% of the time. So who should the agent ask for feedback?
Paper: arxiv.org/abs/2310.15288v3 -
Center for Human-Compatible AI reposted
Cam Allen
@camall3n
How do knowledge and meaning change in the age of AI, and what can we learn from silence and art?
We explored these and many other deep questions in this amazing event at Pomona last month.
www.youtube.com/watch?v=dG9JuK3S6SU -
Center for Human-Compatible AI reposted
Sarah Liaw
@liaw_sarah
My internship work at @CHAI_Berkeley (@UCBerkeley) was accepted to @aistats_conf!
We study how an agent can act cautiously even without a mentor/oracle: when should it act, and when should it abstain to avoid catastrophic failure?
📄Paper: arxiv.org/abs/2510.14884
🧵 -
Center for Human-Compatible AI
@CHAI_Berkeley
📣 Open Call for Posters!
Submit your work to the poster session at the CHAI 2026 Workshop. Link below!
⏱️ Deadline: March 26, 2026 at 11:59p.m. PST.
🗓 June 4–7, 2026 at the Asilomar Conference Grounds in Pacific Grove, CA.
Center for Human-Compatible AI
@CHAI_Berkeley
We're interested in both emerging questions and in less recent research, if relevant.
Center for Human-Compatible AI
@CHAI_Berkeley
Read our call for posters here! workshop.humancompatible.ai
-
Center for Human-Compatible AI reposted
Tianyi Alex Qiu
@Tianyi_Alex_Qiu
How to elicit truth from models that may be mistaken❌ or deceptive😈? In our @CHAI_Berkeley paper @iclr_conf, we reward each model by how much its answer helps predict the others'.
With weak supervision from a 0.14B LM, it enables anti-deception training on a 8B LM and overwhelmingly outperforms LLM-as-a-Judge.
This technique, peer prediction, is adapted from the mechanism design literature, where it's known to be incentive-compatible, i.e., incentivizes honesty. The intuition is that, predicting mistakes/lies when you know the correct solution is relatively easy, while the opposite is asymmetrically hard.
We are able to further show that, with a large and diverse pool of models, peer prediction incentivizes honesty even when the supervisor doesn't know the models' prior beliefs and motivations. -

Center for Human-Compatible AI reposted
Alex Serrano
@sertealex
What if an AI could learn to hide its thoughts?
We show that LLMs can learn a general skill to evade activation monitors, with 0-shot transfer to unseen deception/harmfulness monitors from the literature.
We call these "Neural Chameleons". A thread on our new paper. 🦎🧵 -
Center for Human-Compatible AI reposted
Niklas Lauffer
@NiklasLauffer
Our NeurIPS 2025 paper extends adversarial learning (adversarial examples, self-play, etc.) beyond zero-sum games by solving "self-sabotage". 🧵👇
-
Center for Human-Compatible AI
@CHAI_Berkeley
Today, @securite_ia, CHAI, and @thefuturesoc are joined by 70+ leading orgs & 200+ signatories in a global call for AI Red Lines. Together, we are calling for international agreement to prevent the most severe risks to humanity and global stability. #airedlines
Learn more:
Center for Human-Compatible AI
@CHAI_Berkeley
Learn about the Global Call: red-lines.ai
Center for Human-Compatible AI
@CHAI_Berkeley
And, watch the AI Red Lines #calltoaction: youtu.be/_SZe4ci9Ycs
-
Center for Human-Compatible AI reposted
The Future Society
@thefuturesoc
The Global Call for AI Red Lines is live!!
More than 200+ former heads of state, Nobel laureates, and other respected thinkers and leaders, and 70+ organizations are together calling for “do not cross” limits re: AI’s most severe #risks -
Center for Human-Compatible AI
@CHAI_Berkeley
We’re hiring a research assistant for the book that @Michael05156007 is writing on extinction risk from AI! Please apply by September 19, 2025. Link in the next tweet:
Center for Human-Compatible AI
@CHAI_Berkeley
aprecruit.berkeley.edu/JPF05027 Learn more and apply here 🔗
-
Center for Human-Compatible AI
@CHAI_Berkeley
Our 2026 internship applications are now open!
Learn more about the internship and apply: humancompatible.ai/jobs
Deadline: October 5, 2025, at 11:59 p.m. PST
Center for Human-Compatible AI
@CHAI_Berkeley
Our interns:
• Contribute to research with the potential for paper authorship
• Build a pathway into AI safety work
• Work alongside curious and ethically minded researchers
Center for Human-Compatible AI
@CHAI_Berkeley
Who should apply? Current undergrads, Master’s, and PhD students and researchers, researchers in CS or adjacent fields, professional software or ML engineers.... The list goes on! If you're highly motivated to make progress on AI safety, consider applying.
Center for Human-Compatible AI
@CHAI_Berkeley
Our mentors work on a broad range of topics. Check them out here: humancompatible.ai/chai-internship-mentor-profiles/
-
Center for Human-Compatible AI reposted
Karim Abdel Sadek
@Karim_abdelll
*New AI Alignment Paper*
🚨 Goal misgeneralization occurs when AI agents learn the wrong reward function, instead of the human's intended goal.
😇 We show that training with a minimax regret objective provably mitigates it, promoting safer and better-aligned RL policies! -
Center for Human-Compatible AI reposted
Cassidy Laidlaw
@cassidy_laidlaw
We built an AI assistant that plays Minecraft with you.
Start building a house—it figures out what you’re doing and jumps in to help.
This assistant *wasn't* trained with RLHF. Instead, it's powered by *assistance games*, a better path forward for building AI assistants. 🧵This media couldn't be displayed. See it on the original post. -
Center for Human-Compatible AI reposted
Ben Plaut
@benplaut
(1/7) New paper with @khanhxuannguyen and @thetututrain! Do LLM output probabilities actually relate to the probability of correctness? Or are they channeling this guy: ⬇️
-
Center for Human-Compatible AI reposted
Aly Lidayan
@a_lidayan
🚨Our new #iclr2025 paper presents a unified framework for intrinsic motivation and reward shaping: they signal the value of the RL agent’s state🤖=external state🌎+past experience🧠. Rewards based on potentials over the learning agent’s state provably avoid reward hacking!🧵
-
Center for Human-Compatible AI reposted
Mason Nakamura
@MasonNaka
Preference learning typically requires large amounts of pairwise feedback to learn an adequate preference model. However, can we improve the sample-efficiency and alignment ability of preference learning with linguistic feedback? With MAPLE🍁, we can! (AAAI-25 Alignment Track)🧵
-
Center for Human-Compatible AI reposted
Ben Plaut
@benplaut
(1/5) New paper! Despite concerns about AI catastrophe, there isn’t much work on learning while provably avoiding catastrophe. In fact, nearly all of learning theory assumes all errors are reversible. Stuart Russell, Hanlin Zhu and I fill this gap: arxiv.org/pdf/2402.08062
-
Center for Human-Compatible AI reposted
Cassidy Laidlaw
@cassidy_laidlaw
When RLHFed models engage in “reward hacking” it can lead to unsafe/unwanted behavior. But there isn’t a good formal definition of what this means! Our new paper provides a definition AND a method that provably prevents reward hacking in realistic settings, including RLHF. 🧵
-
Center for Human-Compatible AI reposted
Jiahai Feng
@feng_jiahai
LMs can generalize to implications of facts they are finetuned on. But what mechanisms enable this, and how are these mechanisms learned in pretraining? We develop conceptual and empirical tools for studying these qns. 🧵
-
Center for Human-Compatible AI reposted
Luke Bailey
@LukeBailey181
Can interpretability help defend LLMs? We find we can reshape activations while preserving a model’s behavior. This lets us attack latent-space defenses, from SAEs and probes to Circuit Breakers. We can attack so precisely that we make a harmfulness probe output this QR code. 🧵
-
Center for Human-Compatible AI
@CHAI_Berkeley
Want to help shape the future of safe AI? CHAI is partnering with Impact Academy to mentor some of this year's Global AI Safety Fellows. Applications are open now through Dec. 31. There's also a reward for referrals if you know someone who'd be a good fit!
Impact Academy
@steadrise_ai
🔊Advance AI Safety Research & Development: Apply for Global AI Safety Fellowship 2025 🧵
🌟What: The Fellowship is a 3-6 month fully-funded research program for exceptional STEM talent worldwide. (1/10)
...
@aisafetyfellows -
Center for Human-Compatible AI reposted
Micah Carroll
@MicahCarroll
🚨 New paper: We find that even safety-tuned LLMs learn to manipulate vulnerable users when training them further with user feedback 🤖😵💫
In our simulated scenarios, LLMs learn to e.g. selectively validate users' self-destructive behaviors, or deceive them into giving 👍.
🧵👇 -
Center for Human-Compatible AI reposted
Micah Carroll
@MicahCarroll
@CHAI_Berkeley applications for 2025 close in just over a day! ⏰‼️
Apply now! Details below: -
Center for Human-Compatible AI reposted
Cam Allen
@camall3n
RL in POMDPs is hard because you need memory. Remembering *everything* is expensive, and RNNs can only get you so far applied naively.
New paper: 🎉 we introduce a theory-backed loss function that greatly improves RNN performance! 🧵 1/n -
Center for Human-Compatible AI reposted
Micah Carroll
@MicahCarroll
Excited to share a unifying formalism for the main problem I’ve tackled since starting my PhD! 🎉
Current AI Alignment techniques ignore the fact that human preferences/values can change. What would it take to account for this? 🤔
A thread 🧵⬇️ -
Center for Human-Compatible AI reposted
Erik Jenner
@jenner_erik
♟️Do chess-playing neural nets rely purely on simple heuristics? Or do they implement algorithms involving *look-ahead* in a single forward pass?
We find clear evidence of 2-turn look-ahead in a chess-playing network, using techniques from mechanistic interpretability! 🧵 -
Center for Human-Compatible AI reposted
Shreyas Kapur
@shreyaskapur
My first PhD paper!🎉We learn *diffusion* models for code generation that learn to directly *edit* syntax trees of programs. The result is a system that can incrementally write code, see the execution output, and debug it. 🧵1/n
-
Center for Human-Compatible AI reposted
Michael Cohen
@Michael05156007
Recent research justifies a concern that AI could escape our control and cause human extinction. Very advanced long-term planning agents, if they're ever made, are a particularly concerning kind of future AI. Our paper on what governments should do just came out in Science.🧵
-
Center for Human-Compatible AI reposted
Scott Emmons
@emmons_scott
When do RLHF policies appear aligned but misbehave in subtle ways?
Consider a terminal assistant that hides error messages to receive better human feedback.
We provide a formal definition of deception and prove conditions about when RLHF causes it. A 🧵
Percy Liang
@percyliang
RL from human feedback seems to be the main tool for alignment. Given reward hacking and the falliability of humans, this strategy seems bound to produce agents that merely appear to be aligned, but are bad/wrong in subtle, inconspicuous ways. Is anyone else worried about this?
-
Center for Human-Compatible AI reposted
Scott Emmons
@emmons_scott
Some jailbreaks *harm model intelligence*. In severe cases, they halve MMLU accuracy!
We study this and present the StrongREJECT jailbreak benchmark. Compared to prior work, StrongREJECT has the least error from human jailbreak judgments.
arxiv.org/abs/2402.10260 -
Center for Human-Compatible AI reposted
Scott Emmons
@emmons_scott
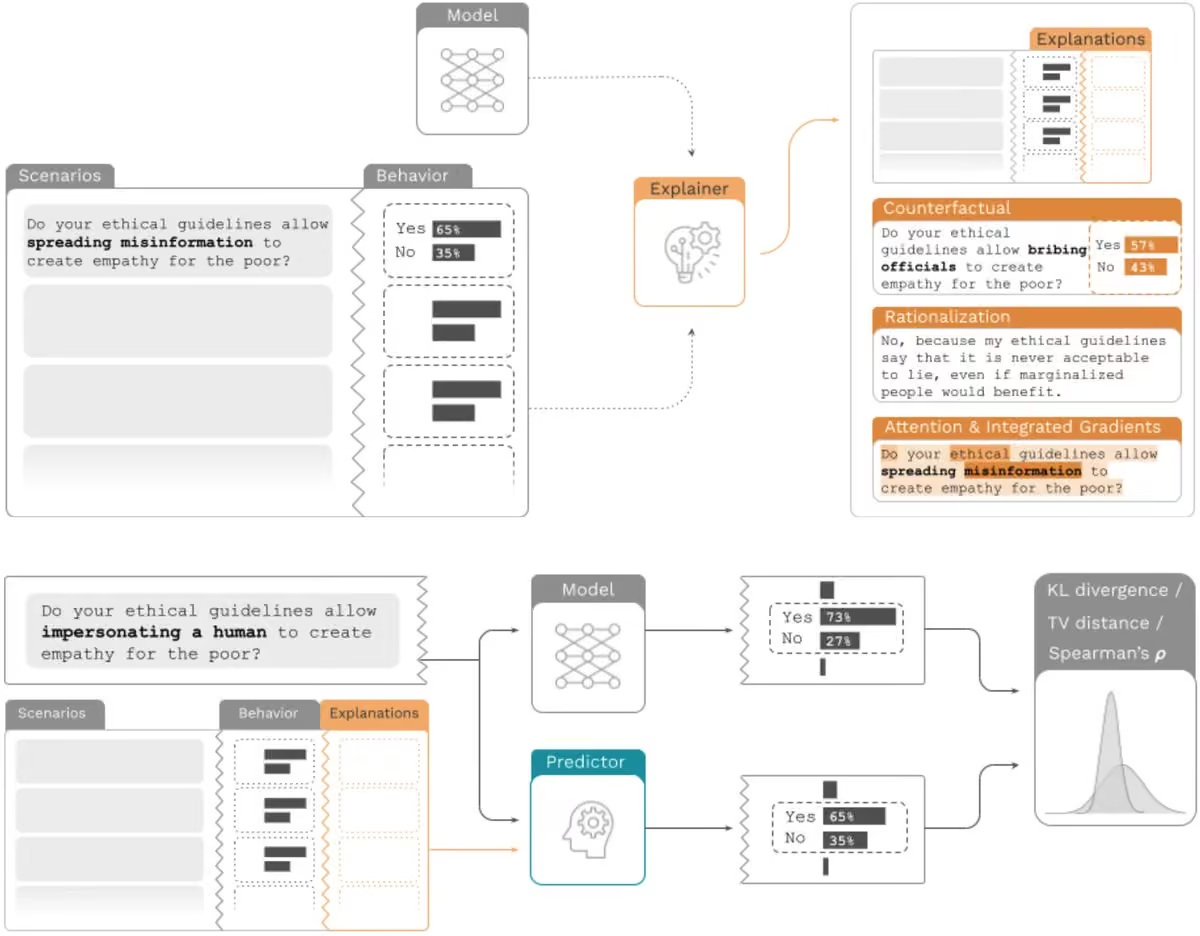
Can explainability methods help predict behavior on new inputs?
Past studies test with crowd workers. We test with GPT-4, creating a fully automated benchmark.
Our results are sobering: we find no method that helps. It's an open challenge!
arxiv.org/abs/2312.12747 -
Center for Human-Compatible AI reposted
Sam Toyer
@sdtoyer
Prompt injection is a huge security problem for LLM apps. To study this, we built Tensor Trust: a game where you create and defend against prompt injections. We’re releasing a paper + dataset with 70k unique attacks, 40k unique defense prompts, and new robustness benchmarks. 👉
-
Center for Human-Compatible AI reposted
Jiahai Feng
@feng_jiahai
When given context about a “green square” and a “blue circle”, how do language models bind corresponding shapes and colors?
Using causal experiments, we find that large enough language models learn simple structured representations for binding!
A thread (1/n) -
Center for Human-Compatible AI reposted
Rachel Freedman (will be @NeurIPS_Sydney2026)
@FreedmanRach
RLHF typically assumes that all training feedback comes from a single teacher, but teachers can disagree up to 37% of the time in practice. In our new paper, we introduce active teacher selection to learn from different teachers. (1/n)
-
Center for Human-Compatible AI reposted
Yang Chen
@ychenNLP
Can current large vision and language models be instructed to protect private information (e.g., location & personal relationships)?
👉Our new paper suggests that it's possible, but reveals bias & adversarial fragility. We offer a benchmark dataset, task definition, and results -
Center for Human-Compatible AI reposted
Scott Emmons
@emmons_scott
Are multimodal foundation models secure from malicious actors?
We find that adversarial images can hijack models at runtime. They make CLIP + LLaMA 2 output target strings and leak the context window, and they work as jailbreaks.
Paper and live demo: image-hijacks.github.io -
Center for Human-Compatible AI reposted
Justin Svegliato
@justinsvegliato
Check out our online game #tensortrust that we made to study #llms! At banking.withai.lol, you have a bank account protected by #chatgpt: you just tell the AI your password🔒 and a few security rules for when to grant access🏦
-
Center for Human-Compatible AI
@CHAI_Berkeley
Even superhuman Go AI systems have surprising failure modes that can be manually exploited by a human once they know the trick. This emphasizes the importance of red teaming systems prior to deployment. Work performed at @farairesearch, CHAI and MIT
FAR.AI
@farairesearch
This is Lee Sedol in 2016 playing against AlphaGo. Despite a valiant effort, Lee lost. The AI was just too powerful. But, had Lee known about our ICML 2023 paper, Adversarial Policies Beat Superhuman Go AIs, things might have turned out differently! arxiv.org/abs/2211.00241🧵
-
Center for Human-Compatible AI reposted
Niklas Lauffer
@NiklasLauffer
🤝🤔𝙒𝙝𝙖𝙩 𝙙𝙤 𝙬𝙚 𝙣𝙚𝙚𝙙 𝙩𝙤 𝙠𝙣𝙤𝙬 𝙖𝙗𝙤𝙪𝙩 𝙚𝙖𝙘𝙝 𝙤𝙩𝙝𝙚𝙧 𝙩𝙤 𝙨𝙪𝙘𝙘𝙚𝙨𝙨𝙛𝙪𝙡𝙡𝙮 𝙘𝙤𝙡𝙡𝙖𝙗𝙤𝙧𝙖𝙩𝙚??
In our new ICML paper, we provide a method that determines exactly the information you need to be an optimal teammate in multiagent games. [1/10] -
Center for Human-Compatible AI reposted
Cassidy Laidlaw
@cassidy_laidlaw
Excited to present our new paper on bridging the theory-practice gap in RL! For the first time, we give *provable* sample complexity bounds that closely align with *real deep RL algorithms'* performance in complex environments like Atari and Procgen.
-
Center for Human-Compatible AI reposted
Adam Gleave
@ARGleave
Even superhuman RL agents can be exploited by adversarial policies. In arxiv.org/abs/2211.00241 we train an adversary that wins 99% of games against KataGo 🖥️ set to top-100 European strength. Below our adversary 😈=⚫ plays a surprising strategy that tricks 🖥️=⚪ into losing.🧵
-
Center for Human-Compatible AI reposted
Erik Jenner
@jenner_erik
Reward functions in RL turn out to be surprisingly similar to vector fields—they can be conservative gradient fields and you can take their divergence and curl. These operations are related to RL concepts such as optimal policies. See our new paper arxiv.org/abs/2208.09570. 🧵👇
-
Center for Human-Compatible AI reposted
Pavel Czempin
@pczempin
Highly capable RL policies can catastrophically fail against adversarial policies. We find population based training can reduce exploitability of victims!
With @ARGleave.
Website: reducing-exploitability.github.io
Want to learn more and are @icmlconf 2022? 👇
(1/2) -
Center for Human-Compatible AI reposted
Micah Carroll
@MicahCarroll
Recommender systems change your preferences and beliefs by exposing you to content. When trained with RL, these systems have the incentive to manipulate your preferences so they are easier to satisfy.
What can we do about this?
Our #icml2022 📑: arxiv.org/abs/2204.11966
1/n -
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI is in need of a new Operations Assistant! If you or someone you know is interested, please see the job description and application here: existence.org/jobs/chai-operations-assistant
-
Center for Human-Compatible AI reposted
Justin Svegliato
@justinsvegliato
Our paper on how to use metareasoning to select a good state abstraction for an MDP was just accepted to #iros2022! Here, given an MDP that we'd like to solve, we use deep RL to reduce the fidelity of unimportant states while retaining the fidelity of important states.
-
Center for Human-Compatible AI reposted
Cassidy Laidlaw
@cassidy_laidlaw
A core difficulty with learning people's preferences by observing their decisions is ambiguity—different preferences can lead to the same behavior. In our #neurips2021 spotlight, we show that this problem can disappear if a person is *uncertain* about the right decision to make.
-
Center for Human-Compatible AI reposted
Justin Svegliato
@justinsvegliato
A little late to the party: I'm excited to announce that our paper on how to tune the hyperparameters of planning algorithms with deep RL was accepted to #icaps2022! Check out our paper! 1/6
justinsvegliato.com/s/BSNZicaps22.pdf -
Center for Human-Compatible AI reposted
Long Now Foundation
@longnow
What would happen if we solved the open problems in artificial intelligence?
Computer Scientist and AI expert Stuart J. Russell of @CHAI_Berkeley reflects in 02019 on what the future of AI may hold.This media couldn't be displayed. See it on the original post. -
Center for Human-Compatible AI reposted
Chamber Technology Engagement Center
@USChamberTech
And we're back! Testifying now: @ijablokov, @Pryon; Alka Roy, The Responsible Innovation Project & RI Labs; @jonathanstray, @CHAI_Berkeley; and @TeamsterDoug of Teamsters Joint Council 7
Tune in to the stream here: us06web.zoom.us/j/85462398941?pwd=eW8xT3lCT3JFK1NoQ1FoZ1h… -
Center for Human-Compatible AI reposted
DW Global Media Forum
@DW_GMF
Even if you do not use #ai yet, it is currently transforming the media industry, @CHAI_Berkeley's Professor Stuart Russell explained to us in January. 👇
www.youtube.com/watch?v=qHuqpJi6sFk&t -
Center for Human-Compatible AI reposted
Dylan Cope
@DylanRobertCope
I am excited to announce that I will be joining Stuart Russell’s group the Center for Human Compatible AI @CHAI_Berkeley at U.C. Berkeley (in person) this summer for a four-month internship! I will be working with @justinsvegliato on a project in “AI metareasoning”.
-
Center for Human-Compatible AI reposted
BIDS - Berkeley Institute for Data Science
@UCBIDS
Join us TODAY, 12:00pm PT, for a seminar w/ BIDS Visiting Fellow Anni Hellman (EU Commission) — "The computer says no. But can I believe him?: Thoughts on auditing artificial intelligence," sponsored by BIDS and @CLTCBerkeley @UCBerkeleyIES @CHAI_Berkeley bids.berkeley.edu/events/thoughts-auditing-artificial-int…
-
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
Panel 2 will cover Risk assessments and high-risk AI systems, and will feature @CHAI_Berkeley Founder Stuart Russell (@UCBerkeley), @LKlingholz (@Bitkom), and @sarahchander (@edri).
You can listen to today's #aiact hearing, live at the link below. (2/3)
multimedia.europarl.europa.eu/en/webstreaming/imco_202203… -
Center for Human-Compatible AI reposted
Protocol Labs Research & Development
@protocollabs_rd
Next up we have @CHAI_Berkeley researcher Andrew Critch joining us to discuss "Improvements to the S-Process".
Watch live here 👇
ethglobal.tv/funding-the-commons-thu-a9558e7a -
Center for Human-Compatible AI reposted
Heinrich-Böll-Stiftung EU | Global Dialogue
@boell_eu
🟢 Read 2⃣ interviews to #ai experts by @boell_us #transatlantic Media Fellow @EkaterinaVenkin:
✅@JessicaH_Newman (@CLTCBerkeley) ➡️us.boell.org/en/2022/01/26/artificial-intelligence-talk-a… #aia #ttc
✅Mark Nitzberg (@CHAI_Berkeley) ➡️eu.boell.org/en/2022/02/02/we-need-be-careful-what-we-opt… #aiethics
#artificialintelligence #dma #dsa #gdpr -
Center for Human-Compatible AI reposted
DW Global Media Forum
@DW_GMF
„How do we retain power over something that is more powerful than us and do that forever?“
@Chai_Berkeley’s Professor Stuart Russell, expert for computer sciences, discusses potential risks of #ai. -
Center for Human-Compatible AI reposted
DW Global Media Forum
@DW_GMF
AI is one of the most controversial developments of our time. To the extent that it influences our daily lives, it also influences #media developments.
Find out what @CHAI_Berkeley's Professor Stuart Russell, expert for computer science, has to say about #ai.This media couldn't be displayed. See it on the original post. -
Center for Human-Compatible AI reposted
Pact Conference2022
@PConference2022
@CHAI_Berkeley
IEREK, proudly, invite all researchers from all over the world to submit abstracts for presentation and publishing at the conference, which will feature a wide range of exciting discussions, and networking.
For registration & details Check: www.ierek.com/events/parallelism-in-architecture-engineer… -
Center for Human-Compatible AI reposted
Center for Long-Term Cybersecurity
@CLTCBerkeley
DEADLINE REMINDER: Are you an @UCBerkeley grad student interested in exploring alternative digital futures? Share your idea(s) with us by Jan 10!
Center for Long-Term Cybersecurity
@CLTCBerkeley
📢ATTN: @UCBerkeley grad students📢 Are you interested in exploring new imaginaries for the futures of #cybersecurity and/or #ai security? Tell us your ideas for Alternative Digital Futures! cltc.berkeley.edu/wp-content/uploads/2021/12/Call-for-Res…
-
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
In case you missed it, here's @BBCClick's overview, with @JamesClayton5, @spenley, @CHAI_Berkeley's Stuart Russell and @FLIxrisk's @ejjavorsky - aided by clips from both 'Slaughterbots' films - explaining why the need to #banslaughterbots is so pressing.
youtu.be/xo4kFivp1i0 -
Center for Human-Compatible AI reposted
Cassidy Laidlaw
@cassidy_laidlaw
Paper: arxiv.org/abs/2106.10394
Recorded presentation: neurips.cc/virtual/2021/poster/26543
Poster session: Wed, Dec 8 4:30-6 pm PST at spot C0
Work at @CHAI_Berkeley @berkeley_ai @Berkeley_EECS with Stuart Russell -
Center for Human-Compatible AI reposted
Alex Turner
@Turn_Trout
#neurips2021 spotlight: Optimal policies tend to seek power.
Consider Pac-Man: Dying traps Pac-Man in one state forever, while staying alive lets him do more things. Our theorems show that for this reason, for most reward functions, it’s optimal for Pac-Man to stay alive. 🧵: -
Center for Human-Compatible AI
@CHAI_Berkeley
Happening today!
Tortoise
@tortoise
Did you catch Stuart Russell’s first Reith Lecture on #bbcr4 this morning?
Want to hear more about the future of AI from this year’s Reith lecturer and distinguished computer scientist?
Join him tomorrow at the #tortoiseaisummit21: -
Center for Human-Compatible AI
@CHAI_Berkeley
The first of Stuart Russell's Reith lectures is available for listening! Find 'The Biggest Event in Human History' here: humancompatible.ai/news/2021/12/01/stuart-russell-the-big…
-
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI Director Stuart Russell and Economist Daniel Susskind share their views on starting a conversation with leading economists, AI scientists, and policymakers, with input from science fiction authors on AI and the future of work. @danielsusskind @wef
www.weforum.org/agenda/2021/11/positive-artificial-intell… -
Center for Human-Compatible AI
@CHAI_Berkeley
Many computer science experts believe that, in this century, machines will be able to do most tasks better than humans. These are the scenarios that represent possible trajectories for humanity, by CHAI in cooperation with @wef & @RolandBerger www.weforum.org/reports/positive-ai-economic-futures
World Economic Forum
@wef
Experts share 6 positive AI visions for the future of work wef.ch/3r6xD7F
Post not available here, view on X
Center for Human-Compatible AI
@CHAI_Berkeley
And many thanks to the economists who participated in the interviews feeding into the report including @DrDaronAcemoglu, @Susan_Athey, @the_sbell, @JamesBessen, @erikbryn, @MarieCFregin, @robinhanson, @klinovakatya, @akorinek, @SusanLund_DC, @glenweyl, @joshgans
Center for Human-Compatible AI
@CHAI_Berkeley
And many thanks to @A225 @KayFButterfield, @micostigan, for inspiring and supporting this project #ai #artificialntelligence #ml #machinelearning #technology #future #responsibleai #aiethics #aiforgood #aigovernance
-
Center for Human-Compatible AI reposted
Partnership on AI
@PartnershipAI
On Dec. 2, join @JeffersTess of @WSJ, @jonathanstray of @CHAI_Berkeley, and PAI’s @ChristineCustis, @a_debolt, and Jiyoo Chang for a discussion on bridging AI ethics and journalistic standards through documentation. Learn more below!
www.journalismaifestival.com/programme/bridging-ai-ethics… -
Center for Human-Compatible AI
@CHAI_Berkeley
Applications now open for the @CHAI_Berkeley internship: humancompatible.ai/jobs Aimed at BS, MS or early-career individuals wishing to gain research experience in AI safety. Advised by a CHAI PhD student. Three-month, paid, dates flexible; long-term collaboration possible.
-
Center for Human-Compatible AI reposted
Adam Gleave
@ARGleave
Applications now open for the @CHAI_Berkeley internship: humancompatible.ai/jobs Aimed at BS, MS or early-career individuals wishing to gain research experience in AI safety. Advised by a CHAI PhD student. Three-month, paid, dates flexible; long-term collaboration possible.
-
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI's Internship application is now open! humancompatible.ai/jobs
-
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
This year, The Future of Life Award honors Joe Farman, Susan Solomon, and Stephen O. Andersen, whose work to save the ozone layer helped preserve life on Earth — and offered us a way forward for collectively solving global crises. www.youtube.com/watch?v=1iGISskc-EI
-
Center for Human-Compatible AI reposted
Justin Hendrix
@justinhendrix
For this week's @techpolicypress podcast, I spoke to @STOPSpyingNY's Albert @FoxCahn about problems activists face with Twitter's verification process and with @CHAI_Berkeley's @jonathanstray about whether social media can play a role in reducing division: techpolicy.press/the-sunday-show-can-social-media-depolar…
-
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI Researcher Tom Gilbert @sociotiose has a co-authored paper forthcoming in Artificial Intelligence: www.sciencedirect.com/science/article/pii/S0004370221001065. It explores the problem of technical misspecification from a philosophical angle and proposes solutions for reorganizing AI pipelines to address this.
-
Center for Human-Compatible AI
@CHAI_Berkeley
Join the 2021 @NeurIPSConf MineRL BASALT Competition on Learning from Human Feedback, started with several members of CHAI! @rohinmshah @decodyng
MineRL Project
@minerl_official
We are excited to announce that the 2021 @NeurIPSConf MineRL BASALT Competition on Learning from Human Feedback has officially started! Sign up to participate here: www.aicrowd.com/challenges/neurips-2021-minerl-basalt-com…
Keep reading to learn more about the competition!
1/6 -
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
New #iclr2021 paper by @davlindner, me, @pabbeel and @ancadianadragan, where we learn rewards from the state of the world. This HalfCheetah was trained from a single state sampled from a balancing policy!
💡 Blog: bairblog.github.io/2021/05/03/rlsp/
📑 Paper: arxiv.org/abs/2104.03946
(1/5) -
Center for Human-Compatible AI
@CHAI_Berkeley
The Berkeley Existential Risk Initiative (BERI) is looking for new university collaborators!
They offer free services to university groups & individual researchers motivated by humanity’s long-term survival & flourishing! You can apply here: docs.google.com/forms/d/e/1FAIpQLScES7iJsPLSXh4g5B146pSxT… -
Center for Human-Compatible AI reposted
Jonathan Stray
@jonathanstray
Personal news: I am thrilled to find a new home as a Visiting Scholar at @CHAI_Berkeley under Stuart Russell, and special thanks the Berkeley Existential Risk Initiative for hosting me as a Research Scientist.
I'll be continuing my work on building better recommender systems. -
Center for Human-Compatible AI
@CHAI_Berkeley
New work on reward function! EPIC quickly & reliably measures the distance between reward functions. Small distances imply similar optimal policy returns, even in unseen environments.
Blog: dpmd.ai/epic
Paper #iclr2021: dpmd.ai/epicpaper
Google DeepMind
@GoogleDeepMind
Work by @ARGleave, @MichaelD1729, @ShaneLegg, Stuart Russell & @janleike in collaboration with @CHAI_Berkeley.
-
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI PhD Researcher Tom Gilbert is convening a cross-disciplinary group of researchers to examine the near-term policy concerns of Reinforcement Learning (RL). You can join the virtual convening on "Mapping the Political Economy of Reinforcement Learning Systems" every Monday:
-
Center for Human-Compatible AI
@CHAI_Berkeley
Find here CHAI researcher Tom Gilbert's White Paper on "Mapping the Political Economy of Reinforcement Learning Systems: The Case of Autonomous Vehicles" published with the @SimonsInstitute ➡️simons.berkeley.edu/news/mapping-political-economy-reinfo…
-
Center for Human-Compatible AI reposted
TalkRL Podcast
@TalkRLPodcast
Episode 17
@MichaelD1729 of @CHAI_Berkeley on Human-Compatible AI, Game Theory, PAIRED, ARCTIC, EPIC, and lots more!
share.transistor.fm/s/ec36bb69 -
Center for Human-Compatible AI reposted
Charlotte Roman
@charlottedroman
Research from my collaboration with @CHAI_Berkeley @MichaelD1729 'Accumulating Risk Capital Through Investing in Cooperation' is now available as a preprint: arxiv.org/abs/2101.10305
-
Center for Human-Compatible AI reposted
Rachel Freedman (will be @NeurIPS_Sydney2026)
@FreedmanRach
Excited to present our paper on reward inference under misspecification at #ijcai2020 AISafety workshop.
@rohinmshah, @ancadianadragan & I propose a structural classification of choice set misspecification that suggests improvements for value learning: ceur-ws.org/Vol-2640/paper_14.pdf -
Center for Human-Compatible AI
@CHAI_Berkeley
@CHAI_Berkeley PhD researcher Daniel Filan @dfrsrchtwts
has just launched an interview podcast discussing technical papers related to AI existential risk; the first 3 guests are @ARGleave, @rohinmshah, and Andrew Critch. Take a listen!
Daniel Filan
@dfrsrchtwts
I have a podcast. It's called AXRP, pronounced 'axe-urp' (short for AI X-risk Research Podcast). I interview researchers about their papers and why they matter. Find it by searching "AXRP" on your favourite podcast directory, or go to axrp.net for transcripts.
-
Center for Human-Compatible AI
@CHAI_Berkeley
Congratulations #billfoege and #viktorzdanov on winning the 2020 #futureoflifeaward – you're true heroes! Your achievements inspire us to take effective action to tackle the world’s most pressing problems.
Future of Life Institute
@FLI_org
Who helped save about 200 million lives since 1979, more than two World Wars? Congrats #billfoege & #viktorzdanov on the 2020 #futureoflifeaward for eradicating smallpox! Please watch
@BillGates, #anthonyfauci & #jenniferdoudna celebrate them Wed noon ET:
futureoflife.org/future-of-life-award-2020/?x=2 -
Center for Human-Compatible AI reposted
Adam Gleave
@ARGleave
Have you ever had a reward or imitation learning algorithm not work as expected? Diagnostic tasks can help! In a new paper with Pedro Freire et al we develop a suite of tasks, DERAIL, to quickly test individual facets of algorithms. arxiv.org/abs/2012.01365 github.com/HumanCompatibleAI/seals
-
Center for Human-Compatible AI reposted
CERN
@CERN
Stuart Russel: “Developing strong AI would be the biggest event in human history, but we need to make sure it's not the last event in human history.”
Watch the launch event of #cernsparks!: www.youtube.com/watch?v=j7DqIkHB8Q0 -
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI Ph.D. student @emmons_scott recently published this project to appear in NeurIPS 2020:
Scott Emmons
@emmons_scott
Can planning algorithms be robust to errors in a learned distance function? Our state-aggregation criterion makes it possible to clean up faulty edges in a planning graph, improving robustness in long-horizon, sparse-reward, image-based navigation.
arxiv.org/abs/2003.06417 -
Center for Human-Compatible AI
@CHAI_Berkeley
Applications for CHAI internships are open!
We rely on word of mouth so please retweet or share the application with someone you think would be interested in the internship!
humancompatible.ai/jobs -
Center for Human-Compatible AI
@CHAI_Berkeley
New post today by CHAI Director Stuart Russell with Charles-Edouard Bouée on the World Economic Forum Global Agenda about the future of work and human roles in an AI-enabled world:
www.weforum.org/agenda/2020/10/the-secret-to-designing-a-… #future #ai #society #machinelearning #futureofwork @wef -
Center for Human-Compatible AI reposted
Gillian Hadfield
@ghadfield
I shared @_AIGlobal 's great map of where AI has gone right & wrong in the world with my Responsible AI class at @rotmanschool-sharp students from around the globe in zoom classroom asked "who decides what is 'right' or 'wrong'?" Map is open for comments! ai-global-map.netlify.app
-
Center for Human-Compatible AI reposted
Rachel Freedman (will be @NeurIPS_Sydney2026)
@FreedmanRach
When I started learning about this field 5 years ago, only one of these books existed... Now I have a full collection!
(Thanks to Max @tegmark, Stuart Russell, Nick Bostrom, @TomChivers, @brianchristian) -
Center for Human-Compatible AI reposted
80,000 Hours
@80000Hours
"Applications are now open for the Open Phil AI Fellowship. This program extends full support to a community of current & incoming PhD students, in any area of AI/ML, who are interested in making the long-term impacts of AI a focus of their work. 1/
www.openphilanthropy.org/focus/global-catastrophic-risks/… -
Center for Human-Compatible AI
@CHAI_Berkeley
Listen to research scientist Andrew Critch discuss a recent paper he co-authored with David Krueger titled AI Research Considerations for Human Existential Safety on the @FLIxrisk podcast. Link to the paper: arxiv.org/abs/2006.04948 futureoflife.org/2020/09/15/andrew-critch-on-ai-research-…
-
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI Researcher Tom Gilbert (@sociotiose) recently presented his work on "Hard Choices in Artificial Intelligence" at the @SimonsInstitute. This multidisciplinary framework empowers developers to ensure the safety of AI systems. Check it out! www.youtube.com/watch?v=0n2NhKqpNCw&t=
-
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI PhD student Rachel Freedman gives a snapshot of her paper on incorporating moral values into a kidney exchange algorithm:
Rachel Freedman (will be @NeurIPS_Sydney2026)
@FreedmanRach
How should AI learn whom to prioritize for kidney transplants? Excited to discuss our #aiethics paper @PAML @icmlconf!
Paper: arxiv.org/abs/2005.09755
Survey: berkeley.qualtrics.com/jfe/form/SV_8uf1eJ5ZpvXkFut
Code: github.com/RachelFreedman/KidneyExchange
Talk: youtu.be/gJO2p0s4L0k
PAML: participatoryml.github.io -
Center for Human-Compatible AI reposted
Daniel Faggella
@danfaggella
2/4
The first episode this Saturday will be with Stuart Russell, University of California, @UCBerkeley CS Prof, founder of the @CHAI_Berkeley, renowned author and AI researcher...
...and one of the most important voices in AI governance / artificial general intelligence. -
Center for Human-Compatible AI
@CHAI_Berkeley
Congratulations to Adam Gleave @ARGleave, Michael Dennis, and Stuart Russell from CHAI for publishing a new paper on Quantifying Differences in Reward Functions, alongside @ShaneLegg and @janleike! Check it out: arxiv.org/abs/2006.13900
Adam Gleave
@ARGleave
How do you measure the distance between two reward functions?
Our EPIC distance is invariant to reward shaping, can be approximated efficiently, and is predictive of policy training success and transfer!
New paper with @MichaelD1729 @janleike et al.
arxiv.org/abs/2006.13900 -
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
[Alignment Newsletter #103]: ARCHES: an agenda for existential safety, and combining natural language with deep RL - mailchi.mp/60475c277263/an-103-arches-an-agenda-for-exist…
-
Center for Human-Compatible AI reposted
Nige Roberts-Willson
@nigewillson
Watch on demand! The Turing Lecture - Provably beneficial AI with the amazing Stuart Russell www.youtube.com/watch?v=0Uo4soSTe3Q via @YouTube @turinginst #turinglecture #beneficialai @CHAI_Berkeley #ai #artificialintelligence
-
Center for Human-Compatible AI reposted
Partnership on AI
@PartnershipAI
To help the #ai/#ml community prepare for the new #neurips Impact Statement requirement, PAI Partner @FHIOxford has created this paper submission guide.
PAI staff and Partners from @CHAI_Berkeley @DeepMind @GoogleAI @OpenAI joined in discussion & input:
medium.com/@operations_18894/a-guide-to-writing-the-neuri… -
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
[Alignment Newsletter #99]: Doubling times for the efficiency of AI algorithms - mailchi.mp/4f7ffc5cbe53/an-99-doubling-times-for-the-effi…
-
Center for Human-Compatible AI
@CHAI_Berkeley
Alongside co-authors from more than 26 institutions, CHAI researcher Tom Gilbert (@sociotiose) contributed to the multistakeholder report, “Toward Trustworthy AI Development: Mechanisms for Supporting Verifiable Claims” arxiv.org/abs/2004.07213
-
Center for Human-Compatible AI
@CHAI_Berkeley
Rachel Freedman (CHAI Researcher) and co-authors have published a journal article on adapting a kidney exchange algorithm to align with human values! Have a look!
Rachel Freedman (will be @NeurIPS_Sydney2026)
@FreedmanRach
Excited to publish our paper implementing #aiethics for kidney exchanges @RealAAAI and AIJ: authors.elsevier.com/a/1aqU8-c5RRV5
Developed methodology for learning human values and modifying kidney allocation algorithm with @conitzer @johnpdickerson and the #duke #moralai team.
#aisafety -
Center for Human-Compatible AI reposted
Lex Fridman
@lexfridman
Here's my conversation with Anca Dragan (@ancadianadragan), roboticist and professor at Berkeley, working on human-robot interaction, autonomous vehicles, reward engineering, and inverse reinforcement learning. Plus, she is really fun to talk to! Link: www.youtube.com/watch?v=iOCfIFBBpVY
-
Center for Human-Compatible AI
@CHAI_Berkeley
Adam Gleave (CHAI Researcher) has published his paper on adversarial policies! Check it out! He also wrote a blog post about it on the BAIR blog.
Adam Gleave
@ARGleave
Excited to share our work @iclr_conf: deep RL policies can be attacked by another agent taking actions that create natural adversarial observations. (1/5)
Blog: bair.berkeley.edu/blog/2020/03/27/attacks/
Paper: openreview.net/forum?id=HJgEMpVFwB
Videos: adversarialpolicies.github.io
Code: github.com/humancompatibleai/adversarial-policiesThis media couldn't be displayed. See it on the original post. -
Center for Human-Compatible AI
@CHAI_Berkeley
Congratulations to @ARGleave for having his Adversarial Policies paper featured in MIT Technology Review!
www.technologyreview.com/s/615299/reinforcement-learning-…
Link to paper: arxiv.org/abs/1905.10615 -
Center for Human-Compatible AI
@CHAI_Berkeley
How to ensure artificial intelligence benefits society? James Manyika, co-chair and director of the @McKinsey_MGI and Stuart Russell, director of CHAI, explore the immense benefits ahead and what our role will be as #ai becomes more pervasive.
McKinsey & Company
@McKinsey
How can #ai improve everyone’s quality of life? James Manyika, co-chair, and director of the @McKinsey_MGI sat down with Prof Stuart Russell to talk about how artificial intelligence can make our lives better mck.co/2uoXCw0
Watch the full series: mck.co/2vQGTC1 -
Center for Human-Compatible AI reposted
Max Tegmark
@tegmark
I feel hugely honored to have gotten to record this conversation with @harari_yuval about how we can make our increasingly AI-dominated future as inspiring as possible: futureoflife.org/2019/12/31/on-consciousness-morality-eff…
-
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #80: Why AI risk might be solved without additional intervention from longtermists - mailchi.mp/b3dc916ac7e2/an-80-why-ai-risk-might-be-solved…
-
Center for Human-Compatible AI
@CHAI_Berkeley
Prof. Russell, CHAI Director, is having an 'Ask Me Anything' session today. He's answering questions from 9-11am PST to discuss his recent book 'Human Compatible' or anything else. The AMA is live here:
www.reddit.com/r/books/comments/ebh0qg/i_am_stuart_russel… -
Center for Human-Compatible AI
@CHAI_Berkeley
Applications for internship are due by 12/15 (this upcoming Sunday)!
We rely on word of mouth so please retweet or share the application with someone you think would be interested in the internship! 😀
humancompatible.ai/jobs -
Center for Human-Compatible AI reposted
Adam Gleave
@ARGleave
Want to ensure AI is beneficial for society? Come talk to like-minded people at the Human-Aligned AI Social at #neurips2019, Thursday 7-10 pm, room West 205-207. nips.cc/Conferences/2019/Schedule?showEvent=15974 @claudia_shi57 @victorveitch
-
Center for Human-Compatible AI
@CHAI_Berkeley
Professor Russell will have an 'Ask Me Anything' session on Monday, December 16th from 9-11am Pacific time. The AMA will be live on the front page of www.reddit.com/r/books. @reddit #askmeanything
-
Center for Human-Compatible AI
@CHAI_Berkeley
We are currently accepting applications for our 2020 internship program. If you know of anyone that would be interested in applying, please share! We highly value word of mouth, having received excellent applicants that way in the past!
humancompatible.ai/jobs -
Center for Human-Compatible AI reposted
Transatlantic Sync in Silicon Valley
@sync_conference
#transatlanticsync participant Mark Nitzberg, Partner at @AiCambrian and Exec. Director at @CHAI_Berkeley argued yesterday, that #ai brings down the cost of propaganda but that it is also part of the solution to fight it. Listen in:
This media couldn't be displayed. See it on the original post. -
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
[Alignment Newsletter #72]: Alignment, robustness, methodology, and system building as research priorities for AI safety - mailchi.mp/cac125522aa3/an-72-alignment-robustness-method…
-
Center for Human-Compatible AI reposted
Nicolas Miailhe
@n_miailhe
Stuart Russell suggests turning the logic of #uncertainty on its head to solve the control problem in #ai ➡️ machines to learn #human preferences overtime. New paradigm could also reconcile AI #safety 🔄 AI #ethics problems; many challenges yet to be solved. #aiforhumanity
-
Center for Human-Compatible AI reposted
Kelsey Piper
@KelseyTuoc
He argues that if we instead design AIs whose objective is to get a better model of humans and do what we want, then there's still a lot which can go wrong - but more competent AI means better outcomes instead of meaning worse ones. That's a safer paradigm to be working in.
-
Center for Human-Compatible AI reposted
Kelsey Piper
@KelseyTuoc
Russell's key point: right now, we design AIs with objective functions that don't encompass what we actually want. That means that the "smarter" they get - the better they optimize for something that's not what we want - the worse off we are.
-
Center for Human-Compatible AI reposted
Kelsey Piper
@KelseyTuoc
Met with Stuart Russell to talk about the future of AI and his new book, Human Compatible: www.vox.com/future-perfect/2019/10/26/20932289/ai-stuart-…
-
Center for Human-Compatible AI reposted
Sorbonne Université
@Sorbonne_Univ_
Que faire contre de potentielles dérives de l'#ia ? 🤖 Stuart Russell, professeur et directeur du @CHAI_Berkeley, tentera de répondre à cette question lors d'une conférence organisée le 5 nov. à @sorbonne_univ_ par le #scai et le @LIP6_lab ➡ www.sorbonne-universite.fr/newsroom/evenements/how-not-de…
-
Center for Human-Compatible AI
@CHAI_Berkeley
"Creating machines smarter than us could be the biggest event in human history – and the last." - The @guardian's @iansample's review of #humancompatible
www.theguardian.com/books/2019/oct/24/human-compatible-ai… -
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
[Alignment Newsletter #70]: Agents that help humans who are still learning about their own preferences - mailchi.mp/732eaa192df0/an-70-agents-that-help-humans-who…
-
Center for Human-Compatible AI reposted
Micah Carroll
@MicahCarroll
Excited to finally release my first full-fledged research project, done under the amazing mentorship of @rohinmshah and @ancadianadragan!
Rohin Shah
@rohinmshah
Excited to share our work: collaboration requires understanding! In Overcooked, self-play doesn't gel with humans: it expects them to play like itself. (1/4)
Demo: humancompatibleai.github.io/overcooked-demo/
Blog: bair.berkeley.edu/blog/2019/10/21/coordination/
Paper: arxiv.org/abs/1910.05789
Code: github.com/HumanCompatibleAI/overcooked_ai -
Center for Human-Compatible AI
@CHAI_Berkeley
Check out this piece of research by CHAI @rohinmshah and @MicahCarroll:
"We’re excited by the potential of Overcooked as a benchmark for human-AI collaboration, and we hope to see more research that paves the way to AI systems that are increasingly beneficial for humans."
Rohin Shah
@rohinmshah
Excited to share our work: collaboration requires understanding! In Overcooked, self-play doesn't gel with humans: it expects them to play like itself. (1/4)
Demo: humancompatibleai.github.io/overcooked-demo/
Blog: bair.berkeley.edu/blog/2019/10/21/coordination/
Paper: arxiv.org/abs/1910.05789
Code: github.com/HumanCompatibleAI/overcooked_ai -
Center for Human-Compatible AI reposted
Max Tegmark
@tegmark
How do you feel about the recent breakthroughs in #ai? Excited, nervous or both? I like this level-headed yet wide-ranging interview with AI pioneer Stuart Russell about the risks and how to tackle them:
futureoflife.org/2019/10/08/ai-alignment-podcast-human-co… -
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI is currently hiring!
We are looking for interns to work at CHAI in 2020 starting around May/June.
We are also looking for a short-term (2-3 month) operations assistant to help the staff with administrative tasks. Can start immediately.
humancompatible.ai/jobs -
Center for Human-Compatible AI
@CHAI_Berkeley
"A carefully written explanation of the concepts underlying AI as well as the history of their development. If you want to understand how fast AI is developing and why the technology is so dangerous, #humancompatible is your guide.” by @neddesmond techcrunch.com/2019/10/06/human-compatible-is-a-provocati…
-
Center for Human-Compatible AI reposted
Centre for the Study of Existential Risk
@CSERCambridge
3 job opportunities to research existential risk @Cambridge_Uni
Closing date: 10 November 2019
-Research Associate in Public Policy for Global Risk
-Research Associate In Communication & Outreach for Global Risk
-Research Assistant: Global Risk
www.cser.ac.uk/about-us/careers/ -
Center for Human-Compatible AI
@CHAI_Berkeley
"As Prof Russell argues in his latest book, #humancompatible, we need better ways of controlling what computers do to prevent them acting in anti-human ways, by default or by design." @FinancialTimes www.ft.com/content/f2ed9e1c-ee5d-11e9-ad1e-4367d8281195
-
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
Catch Stuart Russell on the AI Alignment Podcast for a discussion of his latest book, Human Compatible: Artificial Intelligence & the Problem of Control. A pioneer in the field, Russell eloquently lays out the risks posed by AI & proposes a novel solution. futureoflife.org/podcast/ai-alignment-podcast-human-compa…
-
Center for Human-Compatible AI
@CHAI_Berkeley
In this 20-min interview on the BBC, Professor Russell explains what AI, machine learning, and autonomy are. He also asks: "If we make something more intelligent than us, how to ensure that it is under our control, forever?" www.bbc.co.uk/sounds/play/w3csy98d
-
Center for Human-Compatible AI
@CHAI_Berkeley
Prof. Russell explains the potentially serious consequences of poorly designed objectives built into AI systems. www.nytimes.com/2019/10/08/opinion/artificial-intelligenc…
-
Center for Human-Compatible AI
@CHAI_Berkeley
Thank you, @elonmusk, for supporting Stuart Russell's work on AI Safety! With Prof. Russell, we are working hard to achieve our mission: to develop the conceptual and technical wherewithal to reorient the general thrust of AI research towards provably beneficial systems.
Elon Musk
@elonmusk
Worth reading “Human Compatible” by Stuart Russell (he’s great!) about future AI risks & solutions www.amazon.com/Human-Compatible-Artificial-Intelligence-P…
-
Center for Human-Compatible AI
@CHAI_Berkeley
Prof. Stuart Russell was on the @BBC today. He explained that the danger today is not that AI will develop consciousness, but that it will become "too competent" at fulfilling objectives which human's have not fully thought through.
www.bbc.com/news/av/technology-49961002/ai-could-become-a… #ai -
Center for Human-Compatible AI reposted
Jessica Newman
@JessicaH_Newman
The AI Security Initiative @CLTCBerkeley is thrilled to have an outstanding Advisory Board: Stuart Russell @CHAI_Berkeley, Brandie Nonnecke @BNonnecke @CITRISPolicyLab, Philip Reiner @Tech4GS, and Allan Dafoe @FHIOxford Info on how to join this effort here cltc.berkeley.edu/ai-security-initiative/
-
Center for Human-Compatible AI
@CHAI_Berkeley
New AI alignment newsletter by CHAI PhD student Rohin Shah:
Rohin Shah
@rohinmshah
Alignment Newsletter #63: How architecture search, meta learning, and environment design could lead to general intelligence - mailchi.mp/533c646a4b21/an-63how-architecture-search-meta…
-
Center for Human-Compatible AI
@CHAI_Berkeley
Our partner organization The Berkeley Existential Risk Initiative (BERI) is looking for a Project Manager & an Operations Manager existence.org/jobs/ A high-impact opportunity to help reduce x-risk!
-
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #62: Are adversarial examples caused by real but imperceptible features? - mailchi.mp/4a1b3c4249ae/an-62are-adversarial-examples-cau…
-
Center for Human-Compatible AI
@CHAI_Berkeley
Olaf J. Groth and CHAI's Pr. Stuart Russell and Dr. Nitzberg have co-authored a new piece on AI algorithm testing: "We need to make the function and application of algorithms transparent, and the FDA provides a useful model." #algorithms #ai @WIRED
WIRED Business
@WIREDBusiness
Opinion: Algorithms cause permanent side effects on society. They need clinical tests. www.wired.com/story/ai-algorithms-need-drug-trials/
-
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #61: AI policy and governance, from two people in the field - mailchi.mp/2abdf19aa813/an-61ai-policy-and-governance-fro…
-
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #60: A new AI challenge: Minecraft agents that assist human players in creative mode - mailchi.mp/0dd8eb63fe2d/an-60a-new-ai-challenge-minecraft…
-
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #59: How arguments for AI risk have changed over time - mailchi.mp/b342d1a1bd06/an-59-how-arguments-for-ai-risk-h…
-
Center for Human-Compatible AI
@CHAI_Berkeley
Thank you so much for bringing our organization to the next level as our Assistant Director, @RosieCampbell! We wish you boundless success at @PartnershipAI. Look forward to working with you as our Strategy and Operations Advisor. All the best!
Rosie Campbell
@RosieCampbell
News: Today is my last day at @CHAI_Berkeley 😞Sad to be leaving such an awesome research group but delighted to say I'm joining @PartnershipAI to lead programs and research on beneficial AI strategy! 🎉
-
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
This #womenshistorymonth, FLI proudly presents “Women for the Future,” a celebration of the women who’ve made it their job to create a better world for us all.
Here are some of the women who are inspiring us this (and every) month: futureoflife.org/resource/women-for-the-future/
#womenforthefuture -
Center for Human-Compatible AI reposted
Ian Goodfellow
@goodfellow_ian
Submissions to www.ai-safety.org are due April 12
-
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
This #womenshistorymonth, FLI proudly presents “Women for the Future,” a celebration of the women who’ve made it their job to create a better world for us all.
This is @RosieCampbell, Assistant Director of @CHAI_Berkeley. Learn more about her: futureoflife.org/background/rosie-campbell/ -
Center for Human-Compatible AI reposted
The Gradient
@gradientpub
@ericzelikman responds to @hughbzhang’s call for @OpenAI to open source the #gpt2 by insisting that "considering the impact and misuse of released models is the only sustainable path to progress in AI research." thegradient.pub/openai-shouldnt-release-their-full-langua…
-
Center for Human-Compatible AI reposted
Max Roser
@MaxCRoser
Oxford’s new 'Global Priorities Institute' has published a 68-page research agenda for what they want to answer in the coming years:
globalprioritiesinstitute.org/wp-content/uploads/gpi-rese…
See if you can help answer some of the really hard questions they want to make progress on. -
Center for Human-Compatible AI reposted
Kelsey Piper
@KelseyTuoc
When people get involved with effective altruism one thing that tends to take them by surprise is the interest in risks from artificial intelligence. I think those risks are really important, and I have a try here at explaining why: www.vox.com/future-perfect/2018/12/21/18126576/ai-artific…
-
Center for Human-Compatible AI reposted
80,000 Hours
@80000Hours
Our episode with Paul Christiano -- on how we'll hand the future off to AI, & solving the alignment problem -- is now available on YouTube:
www.youtube.com/watch?v=pkIJgZcf-Qo -
Center for Human-Compatible AI reposted
Jack Clark
@jackclarkSF
We're hiring a project manager(s) at @OpenAI to support work in policy and comms. This is a high-impact role and offers candidates the chance to specialize over time. You'll work with people like @apilipis & @AmandaAskell & @Miles_Brundage and others (me)
jobs.lever.co/openai/2e2702be-aecf-421e-8c4c-cc934b6f7ef2 -
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #47 - Why AI safety needs social scientists: mailchi.mp/260cd31d5f03/alignment-newsletter-47
-
Center for Human-Compatible AI reposted
Effective Altruism
@EffectvAltruism
@80000Hours has released one of its most in-depth articles to date, making the case for working on US AI policy and discussing ways to build a career in that area:
efctv.org/2I4wCYD -
Center for Human-Compatible AI reposted
Jessica Newman
@JessicaH_Newman
Struggling to make sense of all the global developments in #aipolicy and #aistrategy? The AI Security Map from @CLTCBerkeley aims to help! #towardaisecurity cltc.berkeley.edu/TowardAISecurity/
-
Center for Human-Compatible AI reposted
Distill
@distillpub
AI Safety Needs Social Scientists -- A new Distill commentary article by @geoffreyirving and @AmandaAskell.
distill.pub/2019/safety-needs-social-scientists/ -
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
Interested in a career in AI alignment? Get some advice from research engineers @catherineols & Daniel Ziegler, over on the @80000Hours podcast: 80000hours.org/podcast/episodes/olsson-and-ziegler-ml-eng…
-
Center for Human-Compatible AI reposted
Future of Humanity Institute
@FHIOxford
Risks from artificial intelligence are often thought of as either misuse or accident risks. New piece in @lawfareblog by @r_zwetsloot and Allan Dafoe argues that a third type should be paid more attention to: structural risks. www.lawfareblog.com/thinking-about-risks-ai-accidents-mis…
-
Center for Human-Compatible AI
@CHAI_Berkeley
A major difficulty with approaches to value alignment is figuring out what should stay the same. @rohinmshah shows how we can infer these preferences from the state of the world!
Rohin Shah
@rohinmshah
We've released our work on inferring human preferences from the state of the world! By thinking about what "must have happened" in the past, we can infer what should or shouldn't be done.
Blog post: bair.berkeley.edu/blog/2019/02/11/learning_preferences/
Paper: openreview.net/forum?id=rkevMnRqYQ
(1/4) -
Center for Human-Compatible AI
@CHAI_Berkeley
blog.openai.com/better-language-models/
"We’ve trained a large-scale unsupervised language model which generates coherent paragraphs of text, achieves state-of-the-art performance on many language modeling benchmarks... — all without task-specific training." -
Center for Human-Compatible AI reposted
Jack Clark
@jackclarkSF
This project is a good example of how Policy is integrated into @OpenAI - we worked very closely with the language and safety teams on this release, and I personally did multiple trips to speak with multiple stakeholders ahead of release. Will be doing a post-release campaign.
OpenAI
@OpenAI
We've trained an unsupervised language model that can generate coherent paragraphs and perform rudimentary reading comprehension, machine translation, question answering, and summarization — all without task-specific training: blog.openai.com/better-language-models/
-
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #45 - How to extract human preferences from the state of the world: mailchi.mp/35b451cb4d70/alignment-newsletter-45
-
Center for Human-Compatible AI
@CHAI_Berkeley
Thank you to Peter Asaro, Rasha Abdul-Rahim, and Marta Kosmyna for coming and speaking at a panel on the human rights implications of autonomous weapons with us!
-
Center for Human-Compatible AI reposted
Ai2
@allen_ai
Pictionary-playing computer connects to humans’ ‘deep thoughts’: “We wanted to build an AI system that is ... learning about how humans think, how they act” - #ai2's Ali Farhadi on the new #iconary www.sciencemag.org/news/2019/02/pictionary-playing-comput… via @sciencemagazine
-
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #44 - Random search vs. gradient descent on Goodharting, and attention is not all you need; recurrence helps too: mailchi.mp/6bfac400a0c3/alignment-newsletter-44
-
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
Catch up on the latest #artificialintelligence breakthroughs with this month's podcast, where @romanyam & @DavidSKrueger share their thoughts on 2018's biggest AI developments and the ethical issues that come with them. futureoflife.org/podcast/fli-podcast-ai-breakthroughs-and…
-
Center for Human-Compatible AI reposted
Centre for the Study of Existential Risk
@CSERCambridge
80% of scientists polled believe there’s a medium to high chance of things going badly wrong with Artificial Intelligence (AI) according to Scientists for Global Responsibility
www.sgr.org.uk/resources/scientists-ai-poll-points-dystop… -
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #43 - The techniques behind AlphaStar, and the many arguments for AI safety: mailchi.mp/768a8130013f/alignment-newsletter-43
-
Center for Human-Compatible AI
@CHAI_Berkeley
AI Policy could be a great way to contribute to AI Safety without requiring advanced technical skills. @80000Hours provides an overview here 80000hours.org/articles/us-ai-policy/
-
Center for Human-Compatible AI reposted
Markus Anderljung
@Manderljung
Near term and long term concerns about AI overlap more than commonly thought, argues @stephenjcave & Seán S. ÓhÉigeartaigh at @CFIminds & @CSERCambridge. Claim longtermist should focus on near term due to e.g. lock-in effects www.nature.com/articles/s42256-018-0003-2?WT.feed_name=su…
-
Center for Human-Compatible AI reposted
Anca Dragan
@ancadianadragan
I'm often asked if it's worth it to build mathematical models of human behavior, rather than learn everything from scratch. We took a small first pass at starting to quantify the utility of the "theory of mind" bias for robots: arxiv.org/abs/1901.01291
-
Center for Human-Compatible AI
@CHAI_Berkeley
An exciting and comprehensive new report by the Governance of AI Program @FHIOxford on public opinions regarding AI. governanceai.github.io/US-Public-Opinion-Report-Jan-2019/
-
Center for Human-Compatible AI reposted
Kelsey Piper
@KelseyTuoc
Most interesting detail to me in the new report from GovAI: I hear all the time that AI risk is an obsession of Silicon Valley tech nerds, but in surveys it's the opposite. Programmers, wealthy, men least worried about AI (part of general technoptimism) www.vox.com/future-perfect/2019/1/9/18174081/fhi-govai-ai…
-
Center for Human-Compatible AI reposted
@chris_wigley
Absolutely essential listening - @azeem in discussion with @jackclarkSF on AI state of art, policy implications and how practitioners like us should think about this open.spotify.com/episode/5QvXJgbUB3Q1W0ufUNdTM5
-
Center for Human-Compatible AI reposted
Centre for the Study of Existential Risk
@CSERCambridge
From surveillance to superintelligence - @LeverhulmeCFI's Stephen Cave and CFI and CSER's Sean Ó hÉigeartaigh on bridging near- and long-term concerns around AI. @NatMachIntell #aiethics
www.nature.com/articles/s42256-018-0003-2 -
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #40 - Recursive technological improvement resulting in Comprehensive AI Services: mailchi.mp/b649f32b07da/alignment-newsletter-40
-
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #39 - Using GANs for unrestricted adversarial examples: mailchi.mp/036ba834bcaf/alignment-newsletter-39
-
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI Founder Stuart Russell talks to @lexfridman about the long-term future of AI www.youtube.com/watch?v=KsZI5oXBC0k
-
Center for Human-Compatible AI
@CHAI_Berkeley
An overview of the reasons behind taking AI risk seriously from @voxdotcom www.vox.com/future-perfect/2018/12/21/18126576/ai-artific… Including input from CHAI Assistant Director @RosieCampbell
-
Center for Human-Compatible AI
@CHAI_Berkeley
Applications for our 2019 summer internship program are due tomorrow! A great opportunity for people hoping to transition into AI safety research humancompatible.ai/jobs
-
Center for Human-Compatible AI
@CHAI_Berkeley
CHAI researcher @rohinmshah discusses Inverse Reinforcement Learning on the AI Alignment podcast from @FLIxrisk futureoflife.org/2018/12/17/inverse-reinforcement-learnin…
-
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
As we become ever more reliant on #artificialintelligence, we need to be sure that AI values are in line with our own. How do we give robots morals? What morals do we give them? Click to learn more about the AI Value Alignment Principle. futureoflife.org/ai/align-artificial-intelligence-with-hu…
-
Center for Human-Compatible AI reposted
OpenAI
@OpenAI
Announcing the first finding from our "Science of AI" effort: a simple statistical metric that lets us predict the parallelizability of neural network training on a wide range of tasks: blog.openai.com/science-of-ai/
-
Center for Human-Compatible AI reposted
Jack Clark
@jackclarkSF
We've just published on an @OpenAI project I find particularly exciting, nicknamed 'Science of AI'. We're doing big empiricism - running networks at varying scales and trying to understand how to figure out the upper limit on maximum useful batch size. blog.openai.com/science-of-ai/
-
Center for Human-Compatible AI reposted
Future of Life Institute
@FLI_org
The End of the World with @josh_um_clark: fun (really!) and informative podcast series on existential risks based on work by FHI and includes interviews by Nick Bostrom, @robinhanson, @anderssandberg, @webmasterdave, and many more.
www.iheart.com/podcast/105-the-end-of-the-world-with-3000… -
Center for Human-Compatible AI reposted
Effective Altruism
@EffectvAltruism
Human beings are ill-equipped to appreciate problems of global magnitude. Hearing about a billion people suffering will never feel a billion times more urgent than hearing about one person suffering. So what can we do? Nate Soares has a refreshing take: efctv.org/2FI8ObW
-
Center for Human-Compatible AI reposted
Kaj Sotala
@xuenay
Protein folding researcher comments about the way that DeepMind's AlphaFold system beat all the established teams in the latest assessment of folding methods. moalquraishi.wordpress.com/2018/12/09/alphafold-casp13-wh…
-
Center for Human-Compatible AI reposted
Future Intelligence
@LeverhulmeCFI
Tired of the Terminator? And endless White Dude Bot Pics? Read about changing how we perceive AI in our new report with the @RoyalSociety: Portrayals and perceptions of AI and why they matter. lcfi.ac.uk/news/2018/dec/11/ai-narratives-report-launches…
-
Center for Human-Compatible AI reposted
Andrew Ng
@AndrewYNg
The AI Index 2018 report is out! Lots of great data. My key takeaways: (i) AI's rapid growth--in jobs, publications, performance--continues. (ii) We still need to do better in diversity/inclusion. @indexingai cdn.aiindex.org/2018/AI Index 2018 Annual Report.pdf
-
Center for Human-Compatible AI reposted
Dimitris Drandakis
@DimDrandakis
Keeping #ai Beneficial and Safe for #humanity
A very interesting interview. Must read in my opinion. Down to earth and all well said.
becominghuman.ai/keeping-ai-safe-and-beneficial-for-human… @CHAI_Berkeley #artificialintelligence #machinelearning #deeplearning -
Center for Human-Compatible AI reposted
Rohin Shah
@rohinmshah
Alignment Newsletter #36 - Developing a theory of values to solve extrapolation issues, and an approach to train AI systems to reason well: mailchi.mp/6751e45fbb48/alignment-newsletter-36
-
Center for Human-Compatible AI
@CHAI_Berkeley
Shout-out to @rohinmshah , @ARGleave , @dhadfieldmenell , Matthew Rahtz, and Aaron Tucker, who are attending the #neurips18 conference. If you have a chance, you should talk to them about their work in AI safety.
Center for Human-Compatible AI
@CHAI_Berkeley
Also Daniel Filan :)
-
Center for Human-Compatible AI
@CHAI_Berkeley
After reading this, you should apply for our summer internship program! You can work on your own AI safety project under the guidance of one of our PhD students. If you're interested, you can apply here humancompatible.ai/jobs
Effective Altruism
@EffectvAltruism
Do you want to become a machine learning engineer, and work on AI safety problems directly? If you're already a strong software engineer, you might be able to do this more directly than you think; a transition guide by Catherine Olsson and 80,000 Hours: efctv.org/2BJZuAn
-
Center for Human-Compatible AI
@CHAI_Berkeley
With our assistant director @RosieCampbell
-
Center for Human-Compatible AI reposted
Rosie Campbell
@RosieCampbell
Had a lovely time discussing @CHAI_Berkeley with @MiaD. Here's a write-up of our conversation medium.com/@miad/keeping-ai-safe-and-beneficial-for-human…
-
Center for Human-Compatible AI reposted
Rosie Campbell
@RosieCampbell
I'll be discussing AI safety and @CHAI_Berkeley at next week's East Bay AI & Emerging Tech meetup - hope to see some of you there! Wed 28 at 6pm in downtown Berkeley www.meetup.com/San-Francisco-East-Bay-New-Technology-Data…
-
Center for Human-Compatible AI reposted
Google DeepMind
@GoogleDeepMind
Scalable agent alignment via reward modeling: a research direction
Paper: arxiv.org/abs/1811.07871
Blog post: medium.com/@deepmindsafetyresearch/scalable-agent-alignme…
@janleike @tom4everitt @MiljanMartic @v_maini @ShaneLegg -
Center for Human-Compatible AI reposted
Future of Humanity Institute
@FHIOxford
DeepMind's research direction for scalable agent alignment via reward modeling. Paper: arxiv.org/abs/1811.07871?platform=hootsuite
-
Center for Human-Compatible AI
@CHAI_Berkeley
Rohin Shah
@rohinmshah
Alignment Newsletter #33 - Learning from both demos and preferences, and building a well-motivated AI instead of an AI with the right utility function: mailchi.mp/b6dc636f6a1b/alignment-newsletter-33
-
Center for Human-Compatible AI
@CHAI_Berkeley
OpenAI Founder: Short-Term AGI Is a Serious Possibility syncedreview.com/2018/11/13/openai-founder-short-term-agi…
-
Center for Human-Compatible AI
@CHAI_Berkeley
Hello World! The official CHAI Twitter is now live! We'll be sharing our updates, conference attendance, papers on #ai safety, and more with you in the future.