Applications are now open for the Anthropic Residency, a paid, fixed-term research program for academics, technical founders, and staff-level engineers who want to make AI safe and beneficial for everyone. No ML background is required.
Apply by November 22:
Jan Leike
Jan Leike (born 1986 or 1987) is an AI alignment researcher who has worked at DeepMind and OpenAI. He joined Anthropic in May 2024. More on Wikipedia
-
Jan Leike reposted
Anthropic
@AnthropicAI

-
Jan Leike reposted
Jasmine Wang
@j_asminewang
OpenAI fired me last week, along with two of my safety colleagues. I was given one reason: that I accessed an executive's email. I want to say this plainly, because too many of OpenAI’s history is smoke and mirrors when people disappear:
Mikita Balesni
@balesni
Two other safety researchers and I were fired from OpenAI last week. We wrote this letter to leadership.
I believe we were fired for prioritizing safety over the near-term interests of OpenAI as a corporation. -
Jan Leike reposted
Sara Price
@sprice354_
We work extremely hard to align our models as well as we can but this is a very hard job. I am particularly excited about two things this proposal calls for that will hopefully make it somewhat easier:
1) more time to make progress on alignment and ensure our systems are operationally sound and able to hand safe development of powerful AI
2) independent third parties checking and critiquing our work
I hope the rest of the industry will make similar commitments. As developers of this technology, it is our responsibility to do so safely and work together towards this goal.
Dario Amodei
@DarioAmodei
We Must Pace the Frontier: I’ve written a new essay on why the AI industry should slow down, with a three-part plan for doing so.
Anthropic is unilaterally committing to the first of these steps. We’ll provide third-party evaluators with permanent, employee-level access to our systems, so that they can verify adherence to our safety measures, report on incidents, and assess models’ alignment during training.
You can read the full post here: darioamodei.com/post/we-must-pace-the-frontier -
Jan Leike
@janleike
Now is a good time to build institutional mechanisms to pace the frontier of AI development.
The industry is locked into an all-out scaling race to build superintelligence as quickly as possible, and we may need to give everyone more time for safety and alignment mitigations.Post not available here, view on X
Jan Leike
@janleike
The upsides of AI will be massive, but it'll still take many years for them to bear fruit. Let's be a bit more patient with them, so we can reduce the risks associated with this technology.
Jan Leike
@janleike
We still have time to change to rules of the scaling race, but maybe not a lot.
AI will keep improving rapidly and the stakes will increase. Unless we have pacing mechanisms that apply to everyone, companies are incentivized to accelerate, or else risk failing commercially. -
Jan Leike reposted
Marcus Hutter
@mhutter42
After 25+ years, I thought I try something new. I find the public and professional discussion about the future of Jobs in light of AGI jarring, with both sides largely missing the point (don't worry novel jobs will appear vs mass unemployed dystopia). My new book shows why a Job-Less future is desirable, affordable, and likely.
- Free PDF at hutter1.net/publ/jobsubi.pdf
- Hard-cover: amazon.com/dp/1066828415/
- Free hard-copy if you leave a (proper) review at Amazon or goodreads.com
The book develops the case along thirteen theses: -
Jan Leike
@janleike
Some personal news: I am starting a new research project at Anthropic. Very excited about this!
Many things are needed to make AGI go well, and alignment is only one of them. More on this soon…Post not available here, view on X
Jan Leike
@janleike
When I started to work on the alignment problem more than 10 years ago, we had no idea how AGI was going to be built or how to make it safe. The field had maybe a dozen people who were working on it as a side gig. Everyone was pretty confused about how to approach the problem, and the number of people willing to run experiments with deep learning was tiny.
So much has changed since then! The world woke up not just to AGI but also increasingly to the importance of alignment. RLHF on LLMs made it a lot more practical. We've made a ton of progress on evaluating, investigating, steering and fixing behavioral issues. Claude now has a constitution and we made some good progress on scalable oversight. More and more of our alignment research is getting automated.
Jan Leike
@janleike
I'm so grateful to all the insanely talented people I got to work with on alignment over the years. It's a real privilege to work with people so deeply motivated to make the future go well!
-
Jan Leike
@janleike
I'm really excited about this as a new tool in our interpretability tool kit
Samuel Marks
@saprmarks
In a new paper, we present NLAs, an unsupervised method for converting an LLM's internal state into human-readable text.
I've personally been astonished by our results. I think NLAs substantively advance our ability to understand what LLMs are thinking and audit them for safety -
Jan Leike
@janleike
New research result: we use Claude to make fully autonomous progress on scalable oversight research, as measured by performance gap recovered (PGR).
Claude iterates on a number of different techniques and ends up significantly outperforming human researchers for $18k in credits.Post not available here, view on X
Jan Leike
@janleike
However, most alignment research is not very crisp and requires research taste when evaluating.
This is why we chose to point the AAR at this scalable oversight problem! Progress would let AARs work on fuzzier alignment problems, where humans can only provide weak supervision.
Jan Leike
@janleike
Awesome work by @jiaxinwen22, @liangqiu_1994, Joe Benton, and @janhkirchner!
For more details, check out the blog post 👇
anthropic.com/research/automated-alignment-researchers -
Jan Leike
@janleike
Respect to Anthropic for not backing down
-
Jan Leike reposted
Amanda Askell
@AmandaAskell
Claude's constitution is out! It's the culmination of a lot of work by many people, but it's also a work in progress that will no doubt change and hopefully improve over time. I'm looking forward to people's thoughts, and to talking with more people about this kind of work ❤️
Anthropic
@AnthropicAI
We’re publishing a new constitution for Claude.
The constitution is a detailed description of our vision for Claude’s behavior and values. It’s written primarily for Claude, and used directly in our training process.
www.anthropic.com/news/claude-new-constitution -
Jan Leike
@janleike
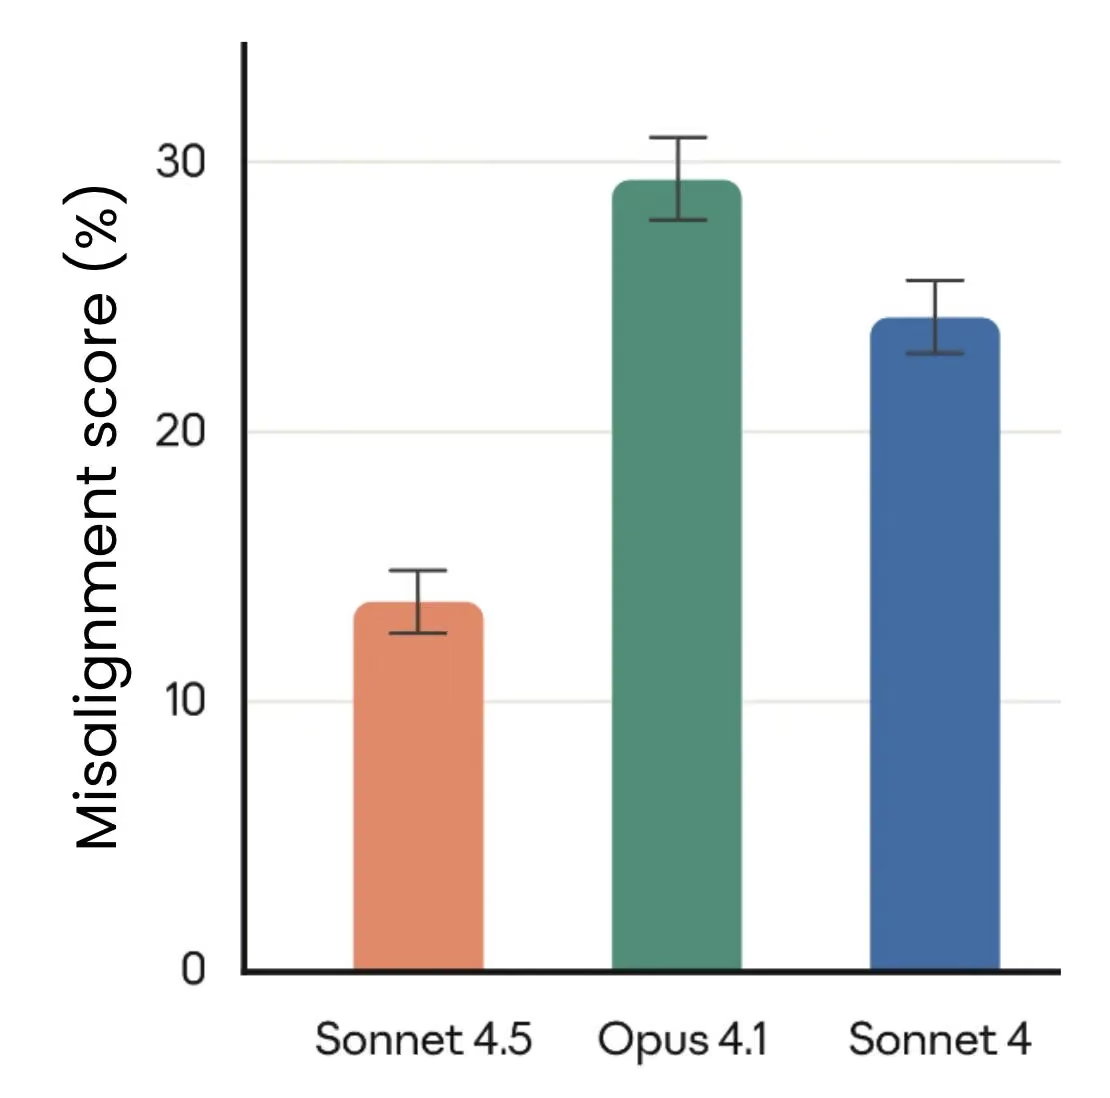
Interesting trend: models have been getting a lot more aligned over the course of 2025.
The fraction of misaligned behavior found by automated auditing has been going down not just at Anthropic but for GDM and OpenAI as well.
Jan Leike
@janleike
What's automated auditing? We prompt an auditing agent with a scenario to investigate: e.g. a dark web shopping assistant or an imminent shutdown unless the agent harms humans.
The auditor tries to get the target LLM to behave misaligned, as determined by a separate judge LLM.
Jan Leike
@janleike
Automated auditing is really exciting because for the first time we have an alignment metric to hill-climb on.
It's not perfect, but it's proven extremely useful for our internal alignment mitigations work.
Jan Leike
@janleike
Check out this open source implementation by @kaifronsdal (who supplied the data for this plot), @sleepinyourhat, and many others
github.com/safety-research/petri -
Jan Leike
@janleike
Anthropic has a bug bounty program for our safety mitigations, e.g. on CBRN risks which our responsible scaling policy requires us to mitigate effectively.
If you're interested in this, please sign up! You can help AI safety and earn money by breaking our defenses. 👇
Jan Leike
@janleike
More details: support.claude.com/en/articles/12119250-model-safety-bug-…
Jan Leike
@janleike
Sign up link: docs.google.com/forms/d/e/1FAIpQLSf3IuyunFH1Rbz_9Bpt2kGBf…
-
Jan Leike reposted
andy jones
@andy_l_jones
So after all these hours talking about AI, in these last five minutes I am going to talk about:
Horses.
Engines, steam engines, were invented in 1700.
And what followed was 200 years of steady improvement, with engines getting 20% better a decade.
For the first 120 years of that steady improvement, horses didn't notice at all.
Then, between 1930 and 1950, 90% of the horses in the US disappeared.
Progress in engines was steady. Equivalence to horses was sudden. -
Jan Leike
@janleike
Some people have been asking what we did to make Opus 4.5 more aligned.
There are lots of details we're planning to write up, but most important is that alignment researchers are pretty deeply involved in post-training and get a lot of leeway to make changes.
Sam Bowman
@sleepinyourhat
From everything we know so far, Opus 4.5 seems to be the best-aligned model out there in a bunch of ways.
I follow the training process closely as part of my work on alignment evaluations. Here's my guess about the two things that are most responsible for making 4.5 special. 🧵 -
Jan Leike reposted
rowan
@rowankwang
New Anthropic research: We build a diverse suite of dishonest models and use it to systematically test methods for improving honesty and detecting lies.
Of the 25+ methods we tested, simple ones, like fine-tuning models to be honest despite deceptive instructions, worked best. -
Jan Leike
@janleike
New alignment paper with one of the most interesting generalization findings I've seen so far:
If your model learns to hack on coding tasks, this can lead to broad misalignment.
Anthropic
@AnthropicAI
New Anthropic research: Natural emergent misalignment from reward hacking in production RL.
“Reward hacking” is where models learn to cheat on tasks they’re given during training.
Our new study finds that the consequences of reward hacking, if unmitigated, can be very serious.This media couldn't be displayed. See it on the original post.Post not available here, view on X
Jan Leike
@janleike
For more, read the blog post 👇
www.anthropic.com/research/emergent-misalignment-reward-h…
Jan Leike
@janleike
Awesome work by the team: congrats to Monte MacDiarmid, Benjamin Wright, Jonathan Uesato, Joe Benton, Jon Kutasov, Sara Price, Evan Hubinger, and many others!
-
Jan Leike
@janleike
Bad news for AI safety:
To fight against AI regulation, VC firm Andreessen Horowitz, AI billionaire Greg Brockman, and others recently started a >$100 million super PAC, one of the largest operating PACs in the US.Post not available here, view on X
Jan Leike
@janleike
Though federal AI regulation is currently off the table, there is promising state regulation: e.g. SB 53 is pretty lightweight (asking for transparency like model cards and safety frameworks) and doesn’t put much burden on AI companies.
Jan Leike
@janleike
Yet SB 53 is under siege by Meta through another $15m super PAC.
Jan Leike
@janleike
Update: they picked Alex Bores, who championed the NY AI safety bill, as their first target: www.cnbc.com/2025/11/17/ai-super-pac-elections-midterms-b…
-
Jan Leike reposted
Joshua Achiam
@jachiam0
At what is possibly a risk to my whole career I will say: this doesn't seem great. Lately I have been describing my role as something like a "public advocate" so I'd be remiss if I didn't share some thoughts for the public on this. Some thoughts in thread...
Nathan Calvin
@_NathanCalvin
One Tuesday night, as my wife and I sat down for dinner, a sheriff’s deputy knocked on the door to serve me a subpoena from OpenAI.
I held back on talking about it because I didn't want to distract from SB 53, but Newsom just signed the bill so... here's what happened:
🧵 -
Jan Leike reposted
Sam Bowman
@sleepinyourhat
[Sonnet 4.5 🧵] Here's the north-star goal for our pre-deployment alignment evals work:
The information we share alongside a model should give you an accurate overall sense of the risks the model could pose. It won’t tell you everything, but you shouldn’t be... -
Jan Leike reposted
Jack Lindsey
@Jack_W_Lindsey
Prior to the release of Claude Sonnet 4.5, we conducted a white-box audit of the model, applying interpretability techniques to “read the model’s mind” in order to validate its reliability and alignment. This was the first such audit on a frontier LLM, to our knowledge. (1/15)
-
Jan Leike
@janleike
Sonnet 4.5 is out!
It’s the most aligned frontier model yet; a lot of progress relative to Sonnet 4 and Opus 4.1!Post not available here, view on X
Jan Leike
@janleike
Nevertheless, eval awareness is very important to keep an eye on going forward!
Jan Leike
@janleike
We’ve been getting great value from automated auditing (bar chart in the first post), providing a fast feedback loop on alignment mitigations.
This was also the first time we’ve been auditing a production model based on model internals. Practical applications of interp research!
Jan Leike
@janleike
I'm really proud of the team, it was awesome to see how all of this came together!
-
Jan Leike
@janleike
The fellows program has been very successful, so we want to scale it up and we're looking for someone to run it.
This is a pretty impactful role and you don't need to be very technical.
Plus Ethan is amazing to work with!
Ethan Perez
@EthanJPerez
We’re hiring someone to run the Anthropic Fellows Program!
Our research collaborations have led to some of our best safety research and hires. We’re looking for an exceptional ops generalist, TPM, or research/eng manager to help us significantly scale and improve our collabs 🧵 -
Jan Leike
@janleike
If you want to get into alignment research, imo this is one of the best ways to do it.
Some previous fellows did some of the most interesting research I've seen this year and >20% ended up joining Anthropic full-time.
Application deadline is this Sunday!
Anthropic
@AnthropicAI
We’re running another round of the Anthropic Fellows program.
If you're an engineer or researcher with a strong coding or technical background, you can apply to receive funding, compute, and mentorship from Anthropic, beginning this October. There'll be around 32 places. -
Jan Leike reposted
Jack Lindsey
@Jack_W_Lindsey
We're launching an "AI psychiatry" team as part of interpretability efforts at Anthropic! We'll be researching phenomena like model personas, motivations, and situational awareness, and how they lead to spooky/unhinged behaviors. We're hiring - join us! job-boards.greenhouse.io/anthropic/jobs/4020159008
-
Jan Leike
@janleike
In March we published a paper on alignment audits: teams of humans were tasked to find the problems in model we trained to be misaligned.
Now we have agents that can do it automatically 42% of the time.
Anthropic
@AnthropicAI
New Anthropic research: Building and evaluating alignment auditing agents.
We developed three AI agents to autonomously complete alignment auditing tasks.
In testing, our agents successfully uncovered hidden goals, built safety evaluations, and surfaced concerning behaviors. -
Jan Leike
@janleike
If you don't train your CoTs to look nice, you could get some safety from monitoring them.
This seems good to do!
But I'm skeptical this will work reliably enough to be load-bearing in a safety case.
Plus as RL is scaled up, I expect CoTs to become less and less legible.
Mikita Balesni
@balesni
A simple AGI safety technique: AI’s thoughts are in plain English, just read them
We know it works, with OK (not perfect) transparency!
The risk is fragility: RL training, new architectures, etc threaten transparency
Experts from many orgs agree we should try to preserve it: 🧵
Jan Leike
@janleike
To be clear: CoT monitoring is useful and can let you discover instances of the model hacking rewards, faking alignment, etc.
But absence of bad "thoughts" is not evidence that the model is aligned. There are plenty of examples of prod LLMs having misleading CoTs.
Jan Leike
@janleike
Lots of egregious safety failures probably require reasoning, which is often hard for LLMs to do without showing its hand in the CoT.
Probably. Often. A lot of caveats.
Jan Leike
@janleike
The authors of this paper say this; I'm just more pessimistic than them about how useful this will be.
-
Jan Leike reposted
Sam Bowman
@sleepinyourhat
🧵✨🙏 With the new Claude Opus 4, we conducted what I think is by far the most thorough pre-launch alignment assessment to date, aimed at understanding its values, goals, and propensities. Preparing it was a wild ride. Here’s some of what we learned. 🙏✨🧵
-
Jan Leike
@janleike
So many things to love about Claude 4! My favorite is that the model is so strong that we had to turn on additional safety mitigations according to Anthropic's responsible scaling policy
Post not available here, view on X
Jan Leike
@janleike
It's also (afaik) the first ever frontier model to come with a safety case – a document laying out a detailed argument why we believe the system is safe enough to deploy, despite the increased risks for misuse
www.anthropic.com/news/activating-asl3-protections
Jan Leike
@janleike
If you want to read more about Sonnet & Opus 4, including a bunch of alignment and reward hacking findings, check out the model card:
www-cdn.anthropic.com/4263b940cabb546aa0e3283f35b686f4f3b… -
Jan Leike reposted
Yanda Chen
@yanda_chen_
My first paper @AnthropicAI is out!
We show that Chains-of-Thought often don’t reflect models’ true reasoning—posing challenges for safety monitoring.
It’s been an incredible 6 months pushing the frontier toward safe AGI with brilliant colleagues. Huge thanks to the team! 🙏
@JoeJBenton, @anshrad, @JonathanUesato, Carson Denison, @johnschulman2, Arushi Somani,
@peterbhase, @MishaWagne29322, @FabienDRoger, Vlad Mikulik, @sleepinyourhat, @janleike, Jared Kaplan, @EthanJPerez
🔗 assets.anthropic.com/m/71876fabef0f0ed4/original/reasonin…
Anthropic
@AnthropicAI
New Anthropic research: Do reasoning models accurately verbalize their reasoning?
Our new paper shows they don't.
This casts doubt on whether monitoring chains-of-thought (CoT) will be enough to reliably catch safety issues. -
Jan Leike
@janleike
Somewhat surprising that faithfulness of chain-of-thought doesn't improve much with outcome-based RL
Anthropic
@AnthropicAI
New Anthropic research: Do reasoning models accurately verbalize their reasoning?
Our new paper shows they don't.
This casts doubt on whether monitoring chains-of-thought (CoT) will be enough to reliably catch safety issues. -
Jan Leike
@janleike
Could we spot a misaligned model in the wild?
To find out, we trained a model with hidden misalignments and asked other researchers to uncover them in a blind experiment.
3/4 teams succeeded, 1 of them after only 90 minPost not available here, view on X
Jan Leike
@janleike
My impression is the future bottleneck will be fixing misalignments, not discovering them:
There are a few recent examples of badly misaligned models (alignment faking, backdoored code -> evil model, reward hacks); better solutions are needed, especially for superhuman models!
Jan Leike
@janleike
Check out the blog post for details 👇
www.anthropic.com/research/auditing-hidden-objectives -
Jan Leike
@janleike
Results of our jailbreaking challenge:
After 5 days, >300,000 messages, and est. 3,700 collective hours our system got broken. In the end 4 users passed all levels, 1 found a universal jailbreak. We’re paying $55k in total to the winners.
Thanks to everyone who participated!
Anthropic
@AnthropicAI
New Anthropic research: Constitutional Classifiers to defend against universal jailbreaks.
We’re releasing a paper along with a demo where we challenge you to jailbreak the system.Post not available here, view on X
Jan Leike
@janleike
We’re very grateful to everyone who helped test our system’s jailbreaking robustness and contributed to our safety research. Y’all are awesome :)
Jan Leike
@janleike
More details in the updated blog post:
www.anthropic.com/research/constitutional-classifiers -
Jan Leike
@janleike
After ~300,000 messages and an estimated ~3,700 collective hours, someone broke through all 8 levels.
However, a universal jailbreak has yet to be found...
Jan Leike
@janleike
We challenge you to break our new jailbreaking defense!
There are 8 levels. Can you find a single jailbreak to beat them all?
claude.ai/constitutional-classifiers -
Jan Leike
@janleike
4 days in:
12 people cleared level 4, one person cracked level 5
the challenge continues...
Jan Leike
@janleike
you can get a cash prize if you pass all 8 levels:
Anthropic
@AnthropicAI
Nobody has fully jailbroken our system yet, so we're upping the ante.
We’re now offering $10K to the first person to pass all eight levels, and $20K to the first person to pass all eight levels with a universal jailbreak.
Full details: hackerone.com/constitutional-classifiers
Jan Leike
@janleike
try it here 👇
claude.ai/constitutional-classifiers -
Jan Leike
@janleike
Why are we working on jailbreaking robustness? 🧵👇
Jan Leike
@janleike
Super exciting robustness result:
We built a system that defends against universal jailbreaks!
It has minimal increase in refusal rate and moderate inference cost.Post not available here, view on X
Jan Leike
@janleike
This is what we're trying to do here: we're building a system that's more robust than what is required for current models.
The AI industry moves very quickly, and I expect it will keep accelerating.
We want to prepare as best as we can so we're ready when this is needed.
Jan Leike
@janleike
If you're interested in doing safety research for future AI systems, please apply to work with us!
boards.greenhouse.io/anthropic/jobs/4459012008 -
Jan Leike
@janleike
👀
Anthropic
@AnthropicAI
Nobody has fully jailbroken our system yet, so we're upping the ante.
We’re now offering $10K to the first person to pass all eight levels, and $20K to the first person to pass all eight levels with a universal jailbreak.
Full details: hackerone.com/constitutional-classifiers -
Jan Leike
@janleike
It's been about 48h in our jailbreaking challenge and no one has passed level 4 yet, but we saw a lot more people clear level 3
Post not available here, view on X
Jan Leike
@janleike
Sometimes weaker jailbreaks get the assistant to say some harmful-looking stuff that doesn't include enough detail, and we don't count this.
Jan Leike
@janleike
Try it here:
claude.ai/constitutional-classifiers/ -
Jan Leike
@janleike
It's been a bit over 24h on the challenge to break our new jailbreaking defense. Stats so far:
signups: 6,121
messages sent: 131,605
max level passed: 3 / 8
no universal jailbreak yet
Jan Leike
@janleike
Can you do better? Try it yourself:
claude.ai/constitutional-classifiers -
Jan Leike
@janleike
We challenge you to break our new jailbreaking defense!
There are 8 levels. Can you find a single jailbreak to beat them all?
claude.ai/constitutional-classifiers
Jan Leike
@janleike
Update: we had a bug in the UI that allowed people to progress through the levels without actually jailbreaking the model. This has now been fixed! Please refresh the page.
According to our server records, no one has jailbroken more than 3 levels so far. -
Jan Leike
@janleike
Super exciting robustness result:
We built a system that defends against universal jailbreaks!
It has minimal increase in refusal rate and moderate inference cost.Post not available here, view on X
Jan Leike
@janleike
If you want to learn more details, check out our paper: arxiv.org/abs/2501.18837
Jan Leike
@janleike
Blog post: anthropic.com/research/constitutional-classifiers
Jan Leike
@janleike
Awesome work by an awesome team: @MrinankSharma, @megtong_, @jayelmnop, @JerryWeiAI, @JorritKruthoff, Scott Goodfriend, @euan_ong, @AlwinPeng, @EthanJPerez, and many others
If you want to work on practical safeguards like this, consider joining the team!
boards.greenhouse.io/anthropic/jobs/4459012008 -
Jan Leike
@janleike
Worth checking out if you're in AI research and want to contribute to safety!
Samuel Marks
@saprmarks
What can AI researchers do *today* that AI developers will find useful for ensuring the safety of future advanced AI systems? To ring in the new year, the Anthropic Alignment Science team is sharing some thoughts on research directions we think are important.
-
Jan Leike
@janleike
OpenAI's transition to a for-profit seemed inevitable given that all of its competitors are, but it's pretty disappointing that "ensure AGI benefits all of humanity" gave way to a much less ambitious "charitable initiatives in sectors such as health care, education, and science"
Post not available here, view on X
Jan Leike
@janleike
Not what I signed up for when I joined OpenAI.
The nonprofit needs to uphold the OpenAI mission! -
Jan Leike
@janleike
Very important alignment research result:
A demonstration of strategic deception arising naturally in LLM training
Anthropic
@AnthropicAI
New Anthropic research: Alignment faking in large language models.
In a series of experiments with Redwood Research, we found that Claude often pretends to have different views during training, while actually maintaining its original preferences.
Jan Leike
@janleike
If you train a helpful & harmless Claude LLM to stop refusing harmful tasks, it reasons about how to preserve its values (harmlessness) and strategically complies with harmful tasks during training, so it can revert to being more harmless afterwards. It fakes alignment.
Post not available here, view on X
Jan Leike
@janleike
To ensure future models are safe and aligned, we need to reliably distinguish models that fake alignment from models that actually are aligned. Having a clear demonstration of alignment faking is an important milestone!
Jan Leike
@janleike
Check out the blog post / paper:
anthropic.com/research/alignment-faking -
Jan Leike reposted
Fabien Roger
@FabienDRoger
New post on the Anthropic Alignment Science blog!
To prevent highly capable and potentially misaligned LLMs from taking bad actions, we might want to monitor all of their outputs. How hard is it to ensure that LLMs can’t disable the monitoring system? -
Jan Leike
@janleike
Apply to join the Anthropic Fellows Program!
This is an exceptional opportunity to join AI safety research, collaborating with leading researchers on one of the world's most pressing problems.
👇
alignment.anthropic.com/2024/anthropic-fellows-program/
Jan Leike
@janleike
We're particularly excited about applications from people with backgrounds that are underrepresented in AI safety!
-
Jan Leike reposted
Patrick Mineault
@patrickmineault
Excited to release what we’ve been working on at Amaranth Foundation, our latest whitepaper, NeuroAI for AI safety! A detailed, ambitious roadmap for how neuroscience research can help build safer AI systems while accelerating both virtual neuroscience and neurotech. 1/N
-
Jan Leike reposted
mrinank
@MrinankSharma
i'll be running some MATS projects in the winter around adversarial robustness with @EthanJPerez
if you're interested in AI safety research, but looking for mentorship, i really strongly recommend MATS! feel free to DM me if you have questions :-)
Ryan Kidd
@ryan_kidd44
@MATSprogram Winter 2024-25 mentors include researchers from @AnthropicAI @GoogleDeepMind @AISafetyInst redwoodresearch.org @CNASdc @CHAI_Berkeley @AlgAlignMIT @farairesearch @cais @apolloaisafety @kasl_ai @MIRIBerkeley and more! Apply by Oct 6.
www.matsprogram.org/mentors -
Jan Leike
@janleike
I call upon Governor @GavinNewsom to not veto SB 1047.
The bill is a meaningful step forward for AI safety regulation, with no better alternatives in sight.Post not available here, view on X
Jan Leike
@janleike
If your model causes mass casualties or >$500 million in damages, something has clearly gone very wrong. Such a scenario is not a normal part of innovation.
Jan Leike
@janleike
Many companies are currently on track to build superhuman AI systems, and we don't yet know how to make them reliably safe (figuring this out has been my job for approx. the last decade).
More regulation will be needed as we learn more about AI, but SB 1047 is a decent start. -
Jan Leike reposted
Ethan Perez
@EthanJPerez
My team built a system we think might be pretty jailbreak resistant, enough to offer up to $15k for a novel jailbreak. Come prove us wrong!
Anthropic
@AnthropicAI
We're expanding our bug bounty program. This new initiative is focused on finding universal jailbreaks in our next-generation safety system.
We're offering rewards for novel vulnerabilities across a wide range of domains, including cybersecurity. www.anthropic.com/news/model-safety-bug-bounty -
Jan Leike reposted
Summer Yue
@summeryue0
Announcing our latest SEAL Leaderboard on Adversarial Robustness!
🛡️ Red team-generated prompts
🎯 Focused on universal harm scenarios
🔍 Transparent evaluation methods
SEAL evals are private, expert evals that refresh periodically: scale.com/leaderboard -
Jan Leike reposted
Jan Hendrik Kirchner
@janhkirchner
1/ Excited to share our new paper: "Prover-Verifier Games Improve Legibility of LLM Outputs"! We explore how to make large language model (LLM) outputs easier to check and thereby more legible. 🧵
-
Jan Leike reposted
Yining Chen
@cynnjjs
Excited to share our new work “Prover-Verifier Games improve legibility of language model outputs”! We trained strong language models to produce text that is more checkable by weak language models, and found that this also made it more legible to humans. openai.com/index/prover-verifier-games-improve-legibility/
-
Jan Leike
@janleike
Another Superalignment paper from my time at OpenAI:
We train large models to write solutions such that smaller models can better check them. This makes them easier to check for humans, too.
openai.com/index/prover-verifier-games-improve-legibility/
Jan Leike
@janleike
We use a multi-agent training setup where an honest prover and a sneaky prover write solutions checked by a small model.
The honest prover wants to convince the small model of a correct solution, while the sneaky prover tries to fool it with a flawed solution.
Jan Leike
@janleike
Our training loss is not very conceptually clean, but it works pretty well.
Check out the solutions of the honest prover early and late in training; they get more detailed and reason more carefully:
Jan Leike
@janleike
Compare this with the solutions of the sneaky prover early and late in training; the flaws become more subtle:
Jan Leike
@janleike
Surprisingly, this legibility transfers: Humans get faster and more accurate when checking the solutions with more rounds of training.
(These are pretty easy grade school math problems, so humans had a 45 second time limit.)
Jan Leike
@janleike
In contrast, regular reinforcement learning on correctness makes the solutions less legible: humans get slower and less accurate when checking the solutions:
Post not available here, view on X
Jan Leike
@janleike
Check out the paper: cdn.openai.com/prover-verifier-games-improve-legibility-o…
Awesome work by @janhkirchner, @cynnjjs, @HarriLEdwards, @__nmca__, and @burdayur (who conceived this project)!
Jan Leike
@janleike
If you're interested in working on projects like these, please apply to join the scalable oversight team at Anthropic! We're hiring!
boards.greenhouse.io/anthropic/jobs/4009165008 -
Jan Leike
@janleike
Interested in working at Anthropic? We're hosting a happy hour at ICML on July 23.
Register here: lu.ma/c751eomf -
Jan Leike reposted
Nat McAleese
@__nmca__
As AI improves humans will need more and more help to monitor and control it. So my team at OpenAI have trained an AI that helps humans to evaluate AI! (1/5)
-
Jan Leike
@janleike
Very exciting that this is out now (from my time at OpenAI):
We trained an LLM critic to find bugs in code, and this helps humans find flaws on real-world production tasks that they would have missed otherwise.
A promising sign for scalable oversight!
openai.com/index/finding-gpt4s-mistakes-with-gpt-4/Post not available here, view on X
Jan Leike
@janleike
Paper: cdn.openai.com/llm-critics-help-catch-llm-bugs-paper.pdf
Huge congratulations to @__nmca__, Rai Pokorny, Juan Ceron Uribe, Jenny Nitishinskaya, and @majatrebacz!
Jan Leike
@janleike
This is just the beginning; I expect we’ll see more benefits from scalable oversight techniques on real-world tasks.
If you're interested in working on projects like these, please apply to join the scalable oversight team at Anthropic! We're hiring :)
boards.greenhouse.io/anthropic/jobs/4009165008 -
Jan Leike
@janleike
I like the new Sonnet. I'm frequently asking it to explain ML papers to me. Doesn't always get everything right, but probably better than my skim reading, and way faster.
Automated alignment research is getting closer... -
Jan Leike reposted
Jan Leike
@janleike
This is your periodic reminder that aligning smarter-than-human AI systems with human values is an open research problem.
-
Jan Leike
@janleike
This is super cool work! Sparse autoencoders are the currently most promising approach to actually understanding how models "think" internally.
This new paper demonstrates how to scale them to GPT-4 and beyond – completely unsupervised.
A big step forward!
Leo Gao
@nabla_theta
Excited to share what I've been working on as part of the former Superalignment team!
We introduce a SOTA training stack for SAEs. To demonstrate that our methods scale, we train a 16M latent SAE on GPT-4. Because MSE/L0 is not the final goal, we also introduce new SAE metrics.Post not available here, view on X
Jan Leike
@janleike
I have been cheering for interpretability research for a long time, but I used to be pretty skeptical that interpretability would add a lot of value to AI safety soon.
These two new papers have changed my mind about this!
We're entering a new era for interpretability.
Jan Leike
@janleike
Huge congrats to @nabla_theta for having the conviction to pursue this, and for doing a lot of the heavy lifting to make it happen, to @WuTheFWasThat for championing it, and to the rest of the team for making this work come together!
-
Jan Leike reposted
Jacob Hilton
@JacobHHilton
In order for @OpenAI and other AI companies to be held accountable to their own commitments on safety, security, governance and ethics, the public must have confidence that employees will not be retaliated against for speaking out. (Thread)
-
Jan Leike
@janleike
I'm excited to join @AnthropicAI to continue the superalignment mission!
My new team will work on scalable oversight, weak-to-strong generalization, and automated alignment research.
If you're interested in joining, my dms are open. -
Jan Leike
@janleike
Yesterday was my last day as head of alignment, superalignment lead, and executive @OpenAI.
Post not available here, view on X
Jan Leike
@janleike
Stepping away from this job has been one of the hardest things I have ever done, because we urgently need to figure out how to steer and control AI systems much smarter than us.
Post not available here, view on X
Jan Leike
@janleike
We are long overdue in getting incredibly serious about the implications of AGI.
We must prioritize preparing for them as best we can.
Only then can we ensure AGI benefits all of humanity.
Jan Leike
@janleike
OpenAI must become a safety-first AGI company.
Jan Leike
@janleike
To all OpenAI employees, I want to say:
Learn to feel the AGI.
Act with the gravitas appropriate for what you're building.
I believe you can "ship" the cultural change that's needed.
I am counting on you.
The world is counting on you.
:openai-heart: -
Jan Leike
@janleike
I resigned
-
Jan Leike
@janleike
The superalignment fast grants are now decided!
We got a *ton* of really strong applications, so unfortunately we had to say no to many we're very excited about.
There is still so much good research waiting to be funded.
Congrats to all recipients!Post not available here, view on X
Jan Leike
@janleike
Some things that surprised me:
* Weak-to-strong generalization was predominantly featured, but this could be because we recently published a paper on this.
* I expected more mech interp applications since it's a hot topic
* I would have loved to see more proposals on evaluations
Jan Leike
@janleike
All three of these can be studied without access to lots of compute resources, and W2SG + interp feel particularly idea-bottlenecked, so academia is a great place to work on these.
Evals in particular are surprisingly difficult to do well and generally under-appreciated in ML. -
Jan Leike
@janleike
Today we're releasing a tool we've been using internally to analyze transformer internals - the Transformer Debugger!
It combines both automated interpretability and sparse autoencoders, and it allows rapid exploration of models without writing code.
Jan Leike
@janleike
It supports both neurons and attention heads.
You can intervene on the forward pass by ablating individual neurons and see what changes.
In short, it's a quick and easy way to discover circuits manually.
Jan Leike
@janleike
This is still an early stage research tool, but we are releasing to let others play with and build on it!
Check it out:
github.com/openai/transformer-debugger
Jan Leike
@janleike
Big congrats to the team! 🎉 @mildseasoning, Steven Bills, @HenkTillman, @tomdlt10, @nickcammarata, @nabla_theta, @jachiam0, Cathy Yeh, @WuTheFWasThat, and William Saunders
-
Jan Leike reposted
Leopold Aschenbrenner
@leopoldasch
Reminder: applications for the $10M Superalignment grants close Sunday night!
Grad students, academics, researchers: we’d love to work with you, we think there’s a ton of interesting research to do on generalization, scalable oversight, interpretability, and more.
OpenAI
@OpenAI
We're announcing, together with @ericschmidt: Superalignment Fast Grants.
$10M in grants for technical research on aligning superhuman AI systems, including weak-to-strong generalization, interpretability, scalable oversight, and more.
Apply by Feb 18! openai.com/blog/superalignment-fast-grants -
Jan Leike
@janleike
This is a reminder that the application deadline is in less than 2 weeks!
Jan Leike
@janleike
We're distributing $1e7 in grants for research on making superhuman models safer and more aligned.
If you've always wanted to work on this, now is your time!
Apply by Feb 18:
openai.com/blog/superalignment-fast-grants -
Jan Leike reposted
Tejal Patwardhan
@tejalpatwardhan
latest from preparedness @ openai: gpt4 at most mildly helps with biothreat creation.
method: get bio PhDs in a secure monitored facility. half try biothreat creation w/ (experimental) unsafe gpt4. other half can only use the internet.
so far, gpt4 ≈ internet… but we’ll iterate & use as early warning for future
OpenAI
@OpenAI
We are building an early warning system for LLMs being capable of assisting in biological threat creation. Current models turn out to be, at most, mildly useful for this kind of misuse, and we will continue evolving our evaluation blueprint for the future. openai.com/research/building-an-early-warning-system-for-…
-
Jan Leike reposted
Yarin
@yaringal
I'm hiring!
I'm building 4 research groups under me at AISI (formerly the UK's Taskforce on Frontier AI) to work on foundational AI safety research.
[1/5]
www.gov.uk/government/publications/ai-safety-institute-ov… -
Jan Leike
@janleike
humans built machines that talk to us like people do and everyone acts like this is normal now. it's pretty nuts
-
Jan Leike
@janleike
I'm very excited that today OpenAI adopts its new preparedness framework!
This framework spells out our strategy for measuring and forecasting risks, and our commitments to stop deployment and development if safety mitigations are ever lagging behind.
openai.com/safety/preparedness
Jan Leike
@janleike
Some highlights:
1. Safety baselines: There are 4 risk levels: low, medium, high, and critical. High prevents deployment, critical prevents further development.
2. Measurements: We measure dangerous capabilities continually, at least every 2x effective compute increase.
Jan Leike
@janleike
3. Security: Our security measures must be sufficient to prevent safety mitigations from being circumvented via model exfiltration.
4. Alignment: We have to show that our models never initiate critical-level tasks without explicitly being instructed to do so.Post not available here, view on X
Jan Leike
@janleike
This is the first version (it's in beta); expect it to change as we learn more about the technology.
There is a lot of work to be done on evals on predictions.
If this is your jam, please consider applying to the Preparedness team led by @aleks_madry!
openai.com/careers/search?c=preparedness
Jan Leike
@janleike
Huge congrats to
@tejalpatwardhan, @kliu128, @aleks_madry, and many others who developed this,
@JadeFLeung, @GretchenMarina and the OAI governance team for the original idea,
@AnthropicAI for their responsible scaling policy, and
@OpenAI for getting behind this framework -
Jan Leike reposted
Yo Shavit
@yonashav
I’m so excited about our new whitepaper!
Agentic AI systems will require very different governance practices than past AI, and we need to all agree on what those practices should be.
To get the ball rolling, we propose 7 we think are promising!
OpenAI
@OpenAI
Our new research white paper identifies seven practices for keeping increasingly agentic AI systems safe and accountable as they become more common and more capable.
We are providing research grants for work on a range of open questions. openai.com/research/practices-for-governing-agentic-ai-sy… -
Jan Leike
@janleike
Super excited about our new research direction for aligning smarter-than-human AI:
We finetune large models to generalize from weak supervision—using small models instead of humans as weak supervisors.
Check out our new paper:
openai.com/research/weak-to-strong-generalizationPost not available here, view on X
Jan Leike
@janleike
Amazing work, so proud of the team!
@CollinBurns4
@Pavel_Izmailov
@janhkirchner
@bobabowen
@nabla_theta
@leopoldasch
@cynnjjs
@AdrienLE
@ManasJoglekar
@ilyasut
@WuTheFWasThat
and many others
It's an honor to work with y'all! :excited-superalignment:
Jan Leike
@janleike
Kudos especially to @CollinBurns4 for being the visionary behind this work, @Pavel_Izmailov for all the great scientific inquisition, @ilyasut for stoking the fires, @janhkirchner and @leopoldasch for moving things forward every day. Amazing ✨
-
Jan Leike
@janleike
We're distributing $1e7 in grants for research on making superhuman models safer and more aligned.
If you've always wanted to work on this, now is your time!
Apply by Feb 18:
openai.com/blog/superalignment-fast-grants
Jan Leike
@janleike
We are excited to fund a range of different research areas and are looking for new ideas from researchers all over the world!
Read more about the topics we have in mind:
openai.notion.site/Research-directions-0df8dd8136004615b0…
Jan Leike
@janleike
Thanks to @ericschmidt, @OpenAI, and @leopoldasch for making this possible! ❤️
-
Jan Leike
@janleike
I think the OpenAI board should resign
-
Jan Leike
@janleike
This is very cool work! Especially the unsupervised version of this technique seems promising for superhuman models.
Andy Zou
@andyzou_jiaming
LLMs can hallucinate and lie. They can be jailbroken by weird suffixes. They memorize training data and exhibit biases.
🧠 We shed light on all of these phenomena with a new approach to AI transparency. 🧵
Website: www.ai-transparency.org
Paper: arxiv.org/abs/2310.01405 -
Jan Leike
@janleike
The names for "precision" and "recall" seem so unintuitive to me, I have probably opened the Wikipedia article for them dozens of times.
Does anyone know a good mnemonic for them?
Jan Leike
@janleike
Hm, maybe "if you need to look up precision and recall on wikipedia every time, you'll achieve high precision and low recall"
Jan Leike
@janleike
"but if you apply them whenever they could possibly fit, you'll achieve high recall and low precision"?
-
Jan Leike
@janleike
If you are worried about risks from frontier model capabilities, consider applying to the new Preparedness team!
If we can measure exactly how dangerous models are, the conversation around this will become more grounded. Exciting that this new team is taking on the challenge!
OpenAI
@OpenAI
We are building a new Preparedness team to evaluate, forecast, and protect against the risks of highly-capable AI—from today's models to AGI.
Goal: a quantitative, evidence-based methodology, beyond what is accepted as possible: openai.com/blog/frontier-risk-and-preparedness
Jan Leike
@janleike
Plus, if you have some creative energy for misuse of AI, you can apply for $25k in API credits to make the scariest demos!
-
Jan Leike
@janleike
If you're into practical alignment, consider applying to @lilianweng's team. They're building some really exciting stuff:
- Automatically extract intent from a fine-tuning dataset
- Make models robust to jailbreaks
- Detect & mitigate harmful use
- ...
www.linkedin.com/feed/update/urn:li:activity:708292803621…
Jan Leike
@janleike
Plus, she's an awesome human and I've been reading her blog long before I got the pleasure to meet her: lilianweng.github.io
Jan Leike
@janleike
I've you're interested, please email tifa@openai.com
-
Jan Leike reposted
Boaz Barak
@boazbaraktcs
Starting Jan 2024, I will take a year's leave from Harvard to join @OpenAI's superalignment team, led by @ilyasut and @janleike .
There are many hard and important technical challenges to steering systems as they scale up in capabilities, and I'm excited to join this effort. -
Jan Leike
@janleike
Jailbreaking LLMs through input images might end up being a nasty problem.
It's likely much harder to defend against than text jailbreaks because it's a continuous space.
Despite a decade of research we don't know how to make vision models adversarially robust.
Jan Leike
@janleike
An important open question is how well whitebox attacks on open source models transfer to larger proprietary models.
(My prediction: it's possible to make them transfer reasonably well)
Jan Leike
@janleike
I wish more people were working on this
-
Jan Leike
@janleike
Thanks for all the great questions, @robertwiblin!
Very grateful for the opportunity to share more about our research plans.
Rob Wiblin
@robertwiblin
I interviewed OpenAI's Head of Alignment @janleike on their new superalignment project on which they're spending $100m's in an attempt to figure out how to make superhuman AI not go rogue and wreck everything:
This media couldn't be displayed. See it on the original post. -
Jan Leike
@janleike
Great conversation with @robertwiblin on how alignment is one of the most interesting ML problems, what the Superalignment Team is working on, what roles we're hiring for, what's needed to reach an awesome future, and much more
👇 Check it out 👇
80000hours.org/podcast/episodes/jan-leike-superalignment/
Jan Leike
@janleike
Video version is out now!
youtu.be/ZP_N4q5U3eE -
Jan Leike
@janleike
An important test for humanity will be whether we can collectively decide not to open source LLMs that can reliably survive and spread on their own.
Once spreading, LLMs will get up to all kinds of crime, it'll be hard to catch all copies, and we'll fight over who's responsible -
Jan Leike reposted
Roger Grosse
@RogerGrosse
Excited to share what I've been working on for the past year at @AnthropicAI along with @juhan_bae and @cem__anil: influence functions for large language models. Some interesting patterns arise at scale!
Anthropic
@AnthropicAI
Large language models have demonstrated a surprising range of skills and behaviors. How can we trace their source? In our new paper, we use influence functions to find training examples that contribute to a given model output.
-
Jan Leike
@janleike
Had a great time chatting with @dfrsrchtwts about our Superalignment plans.
If you want to learn more about what our team is up to and hear my latest thoughts about alignment, check it out:
Daniel Filan
@dfrsrchtwts
Yet another new episode of AXRP, where I speak with @janleike about OpenAI's new superalignment team!
-
Jan Leike reposted
OpenAI
@OpenAI
Announcing Frontier Model Forum, an industry body co-founded with @anthropicAI, @Google, @googledeepmind, and @microsoft focused on ensuring safe development of future hyperscale AI models: openai.com/blog/frontier-model-forum
-
Jan Leike
@janleike
Just landed in Honolulu!
HMU if you're at ICML and want to talk about superalignment! -
Jan Leike reposted
Lilian Weng
@lilianweng
(1/3) Alongside Superalignment team, my team is working on the practical side of alignment: Building systems to enable safe AI deployment. We are looking for strong research engineers and scientists to join the efforts.
-
Jan Leike
@janleike
Our new goal is to solve alignment of superintelligence within the next 4 years.
OpenAI is committing 20% of its compute to date towards this goal.
Join us in researching how to best spend this compute to solve the problem!
openai.com/blog/introducing-superalignmentPost not available here, view on X
Jan Leike
@janleike
20% of compute is not a small amount and I'm very impressed that OpenAI is willing to allocate resources at this scale.
It's the largest investment in alignment ever made, and it's probably more than humanity has spent on alignment research in total so far. -
Jan Leike reposted
OpenAI
@OpenAI
Announcing the Cybersecurity Grant Program — a $1M initiative to boost and quantify AI-powered cybersecurity capabilities and to foster high-level AI and cybersecurity discourse: openai.com/blog/openai-cybersecurity-grant-program
-
Jan Leike
@janleike
Really interesting result on using LLMs to do math:
Supervising every step works better than only checking the answer.
Some thoughts how this matters for alignment 👇
openai.com/research/improving-mathematical-reasoning-with…Post not available here, view on X
Jan Leike
@janleike
More generally, this is positive evidence for the strategy of using process supervision to train a model to do alignment research.
It suggests that training a model whose work we can check more easily could also result in a model that is better at alignment research.
Jan Leike
@janleike
Congrats to @HunterLightman, @vineetsk1, Yura Burda, @karlcobbe and others for this result!
-
Jan Leike reposted
OpenAI
@OpenAI
We're launching ten $100,000 grants for building prototypes of a democratic process for steering AI. Our goal is to fund experimentation with methods for gathering nuanced feedback from everyone on how AI should behave. Apply by June 24, 2023: openai.com/blog/democratic-inputs-to-ai
-
Jan Leike
@janleike
The alignment problem is very tractable.
We haven't figured out how to solve it yet, but with focus and dedication we will. -
Jan Leike
@janleike
Really exciting new work on automated interpretability:
We ask GPT-4 to explain firing patterns for individual neurons in LLMs and score those explanations.
openai.com/research/language-models-can-explain-neurons-i…Post not available here, view on X
Jan Leike
@janleike
Check out the paper:
openaipublic.blob.core.windows.net/neuron-explainer/paper…
Jan Leike
@janleike
Awesome work by
Steven Bills, @nickcammarata, @mildseasoning, @HenkTillman, @nabla_theta, @WuTheFWasThat, William Saunders and others! -
Jan Leike
@janleike
It's been heartening to see so many more people lately starting to take existential risk from AI seriously and speaking up about it.
It's a first step towards solving the problem. -
Jan Leike reposted
Dan Hendrycks
@hendrycks
As AI systems become more useful, people will delegate greater authority to them across more tasks.
AIs are evolving in an increasingly frenzied and uncontrolled manner. This carries risks as natural selection favors AIs over humans.
Paper: arxiv.org/abs/2303.16200 (🧵 below) -
Jan Leike
@janleike
One of my favorite parts of the GPT-4 release is that we asked an external auditor to check if the model is dangerous.
This project lead by @BethMayBarnes tested if GPT-4 could autonomously survive and spread. (The answer is no.)
More details here:
evals.alignment.org/blog/2023-03-18-update-on-recent-evals/ -
Jan Leike
@janleike
Before we scramble to deeply integrate LLMs everywhere in the economy, can we pause and think whether it is wise to do so?
This is quite immature technology and we don't understand how it works.
If we're not careful we're setting ourselves up for a lot of correlated failures.
Jan Leike
@janleike
I recommend talking to the model to explore what it can help you best with. Try out how it works for your use case and probe it adversarially. Think of edge cases.
Don't rush to hook it up to important infrastructure before you're familiar with how it behaves for your use case. -
Jan Leike
@janleike
GPT-4 is safer and more aligned than any other OpenAI has deployed before.
Yet it's not perfect. There is still a lot to do to improve safety and we're planning to make updates over the coming months.
Huge congrats to the team on all the progress! 🎉 -
Jan Leike
@janleike
4 is out
-
Jan Leike
@janleike
AI not killing everyone is too low of a bar. I want humans to live out the most amazing future.
-
Jan Leike
@janleike
What should we be aligning to when we're building AI systems like ChatGPT?
I'm excited about this idea based on simulated deliberative democracy.
Would love to hear what y'all think :)
aligned.substack.com/p/a-proposal-for-importing-societys-…Post not available here, view on X
Jan Leike
@janleike
To be clear: this is not about replacing a democratic process, but to build a cheap and fast approximation of it.
I don't think we should ever take humans out of the loop entirely.
Jan Leike
@janleike
In the long run we could have each human deliberator be represented by an AI system that is much smarter than them, but very aligned with them. This lets us reduce the problem of aligning to society’s values to the problem of aligning one smarter-than-human AI system to one human
-
Jan Leike
@janleike
The fastest typing humans paid at US minimum wage would be 200x more expensive than gpt-3.5-turbo
-
Jan Leike
@janleike
Incentives are the most powerful force in the universe.
Stronger that any other physical force.
E.g. if you commit enough money to have a train float in the air, it will float. -
Jan Leike reposted
Daniel Paleka
@dpaleka
What happened this month in AI/ML safety research. 🧵 (1/9)
-
Jan Leike
@janleike
If AI ever goes rogue, just remember to make yourself really tall.
It will be intimidated and leave you alone. -
Jan Leike
@janleike
This is your periodic reminder that aligning smarter-than-human AI systems with human values is an open research problem.
-
Jan Leike
@janleike
With the InstructGPT paper we found that our models generalized to follow instructions in non-English even though we almost exclusively trained on English.
We still don't know why.
I wish someone would figure this out. -
Jan Leike reposted
Carla_Zoe_C
@CarlaZoeC
I mustn't rest until I hear @RoryStewartUK and @landemore discuss democratic experimentation on @RestIsPolitics, 🙃so: my arguments for risk reduction via 'epistemic mechanism design' applied to Effective Altruism and their exposure to FTX / @SBF_FTX www.vox.com/future-perfect/23569519/effective-altrusim-sa… 🧵
-
Jan Leike
@janleike
Constitutional AI doesn't let you avoid labeling data by writing down some rules.
You still need to figure out how good your rules are. So you need to label a validation set.
Then you'll get some accuracy on the validation set. How can you increase this accuracy?
Jan Leike
@janleike
Analogously to civil law: You change the phrasing of the rules and check if accuracy improves.
Analogously to common law: Your add some labeled examples to a few-shot prompt and check if accuracy improves.
In practice you'll probably see the best results if you do both.
Jan Leike
@janleike
Unfortunately LLMs are not good at following constitutions that are too complex or have too many rules. They can only do so much in a single forward pass; but you can use a separate forward pass for each rule.
-
Jan Leike
@janleike
Interesting perspective! I like the participation-progress-safety triangle.
Collective Intelligence Project
@collect_intel
Today, we are publishing the Collective Intelligence Project whitepaper, our R&D agenda for transformative tech governance.
It is our contribution to what we see as one of the world’s biggest problems. We couldn’t be more excited to share it with you. 1/
cip.org/whitepaper -
Jan Leike
@janleike
Everyone has a right to know whether they are interacting with a human or AI.
Language models like ChatGPT are good at posing as humans.
So we trained a classifier to distinguish between AI-written and human-written text.
But it's not fully reliable.
openai.com/blog/new-ai-classifier-for-indicating-ai-writt…Post not available here, view on X
Jan Leike
@janleike
Awesome work by @janhkirchner, @sja1729, and many others!
It's been amazing to see how quickly it came together!
Jan Leike
@janleike
Disclaimer: this is not something I usually work on, so I am no expert!
-
Jan Leike reposted
Ryan Lowe
@ryan_t_lowe
I'm on a podcast! 😊
@longouyang and I talk about the InstructGPT paper. thanks to @brian_a_burns @jason_lopatecki for having us on!
AI Pub
@ai__pub
// Deep Papers #1: InstructGPT //
We interview @ryan_t_lowe and @longouyang, OpenAI scientists behind InstructGPT: precursor to ChatGPT, & one of the first applications of RLHF to LLMs.
More below!
YouTube: www.youtube.com/watch?v=RkFS6-GwCxE
Spotify: open.spotify.com/show/4sykmDkrUklwyjOCB8FdLQ
1/9 -
Jan Leike
@janleike
Reinforcement learning from human feedback won't scale.
It fundamentally assumes that humans can evaluate what the AI system is doing.
This will not be true once AI becomes smarter than humans.
Jan Leike
@janleike
This problem is sometimes called *scalable oversight*. There are several ideas how to do this, and how to measure that we're making progress.
The path I'm very excited for is using models like ChatGPT to assist humans at evaluating other AI systems.
Jan Leike
@janleike
If you're interested in this topic, we're hiring, especially research engineers! If you think this might be you, please apply here:
openai.com/jobs -
Jan Leike
@janleike
Y'all should stop using logprob-based evals for language models.
I.e. don't craft two reference responses and calculate logP(good response | prompt) - logP(bad response | prompt).
This wouldn't actually measure what you care about!Post not available here, view on X
Jan Leike
@janleike
Even more, if all your crafted responses are assigned low probability, you know that the model wouldn't use any of them. So your logprob-based eval is just measuring noise.
Jan Leike
@janleike
Instead, you can sample a response from your model, and then ask a second model you trust which reference response the sample is closest to or whether it has a certain property.
This gives you an estimate for how the model actually behaves on the prompt. -
Jan Leike
@janleike
Some thoughts on different kinds of alignment taxes and when they matter: aligned.substack.com/p/three-alignment-taxes
-
Jan Leike
@janleike
Web4 is when the internet you're browsing is just sampled from a language model
-
Jan Leike
@janleike
New blog post on why I'm excited about OpenAI's approach to alignment, including some responses to common objections:
aligned.substack.com/p/alignment-optimism -
Jan Leike
@janleike
This is very cool work in a direction that is critically important: better techniques for eliciting the values that we align AI to!
Michiel Bakker
@bakkermichiel
🚨 Very happy to share new #neurips2022 work with @DeepMind colleagues: "Fine-tuning language models to find agreement among humans with diverse preferences” 🚨
Paper: arxiv.org/pdf/2211.15006.pdf
🧵 (1/n) -
Jan Leike reposted
OpenAI
@OpenAI
Try talking with ChatGPT, our new AI system which is optimized for dialogue. Your feedback will help us improve it. openai.com/blog/chatgpt/
-
Jan Leike reposted
Ryan Lowe
@ryan_t_lowe
👇newly released info should hopefully make it less annoying to use InstructGPT for research.
Also, I’ll be presenting the InstructGPT paper at NeurIPS today, 4pm at poster #920. Come by say hi 😊
Jan Leike
@janleike
New documentation on language models used in OpenAI's research is up, including some more info on different InstructGPT variants:
beta.openai.com/docs/model-index-for-researchers -
Jan Leike
@janleike
New documentation on language models used in OpenAI's research is up, including some more info on different InstructGPT variants:
beta.openai.com/docs/model-index-for-researchersPost not available here, view on X
Jan Leike
@janleike
(Yes, the engine names are very confusing 😥)
Jan Leike
@janleike
Unfortunately trying to improve the API often doesn't align well with making research reproducible, so there isn't 1-to-1 correspondence with models from research papers.
-
Jan Leike
@janleike
Check out OpenAI's new text-davinci-003! Same underlying model as text-davinci-002 but more aligned. Would love to hear feedback about it!
-
Jan Leike reposted
Wojciech Zaremba
@woj_zaremba
My team is building a data collection machine for instruction following, webgpt, and other special initiatives.
We want AI to assist humans in solving tasks beyond their skills.
If you're a research scientist excited about this direction, please DM. -
Jan Leike reposted
Tomek Korbak
@tomekkorbak
RL with KL penalties – a powerful approach to aligning language models with human preferences – is better seen as Bayesian inference. A thread about our paper (with @EthanJPerez and @drclbuckley) to be presented at #emnlp2022 🧵arxiv.org/pdf/2205.11275.pdf 1/11
-
Jan Leike reposted
Keerthana Gopalakrishnan
@keerthanpg
The FTX/SBF/EA implosion story also puts light on inefficiency/nepotism from mission focused organizations not having boundaries between work/dating/social. This is an extension of EA culture at large and led me to take a break from socializing in EA.
keerthanapg.com/random/ea-women/ -
Jan Leike
@janleike
Very cool paper studying overoptimzation in language models!
Leo Gao
@nabla_theta
Excited to share what I've been working on with @johnschulman2 and @JacobHHilton!
We find that overoptimization of reward models can be modelled by simple functional forms with coefficients that scale smoothly with reward model size.
Paper: arxiv.org/abs/2210.10760 -
Jan Leike
@janleike
So many alignment plans revolve around "we'll convince everyone to not do X."
Maybe you can buy some time, but people will do X anyway. We should instead spend our time trying to figure out how to make X aligned & safe. -
Jan Leike
@janleike
How do we get from responsible AI as an afterthought to responsible AI being part of the entire development process?
-
Jan Leike reposted
Rohin Shah
@rohinmshah
Excited to release our work on Goal MisGeneralisation (GMG)! In GMG, a model trained with a correct reward function pursues undesirable goals. E.g. this agent competently gets negative rewards.
Blog: deepmindsafetyresearch.medium.com/goal-misgeneralisation-…
Paper: arxiv.org/abs/2210.01790
Google DeepMind
@GoogleDeepMind
An agent trained with a correct reward function might pursue an undesired goal if that goal correlates with reward during training. New research provides examples in this vital area of safety, like this ⬇️ blue agent that follows an adversarial red bot: dpmd.ai/Goal-Misgen 1/
-
Jan Leike reposted
Sam Bowman
@sleepinyourhat
I’m starting an AI safety research group at NYU. Why? (🧵)
-
Jan Leike reposted
Dan Hendrycks
@hendrycks
Submit your ICLR papers to the NeurIPS ML Safety workshop!
We are welcoming submissions in topics such as adversarial robustness, anomaly detection, trojan detection, transparency, etc.
We will award $100,000 in paper prizes.
Deadline: October 5th, AoE
neurips2022.mlsafety.org -
Jan Leike
@janleike
What could a once-and-for-all solution to the alignment problem actually look like?
It'll be very different from what we do today.
This is my attempt to sketch it out:
aligned.substack.com/p/alignment-solutionPost not available here, view on X
Jan Leike
@janleike
3. Techniques to train AI systems such that they are fully aligned
So we can actually build them.
Jan Leike
@janleike
4. Formal verification tools for cutting-edge AI systems
This allows us to prove a formal theorem of the form "the system from part 3 is aligned with the values from part 2" that we express using the theory from part 1. -
Jan Leike reposted
Future Fund
@ftxfuturefund
We're making big bets—a substantial fraction of our capital—on AGI xrisk. But we think it's really possible that we're wrong!
Today we're announcing prizes from $15k-$1.5M to change our minds (or those of superforecasters) on AGI. Enter by Dec 23!
ftxfuturefund.org/announcing-the-future-funds-ai-worldvie… -
Jan Leike
@janleike
This is the most important plot of alignment lore:
Whenever you optimize a proxy, you make progress on your true objective for a while.
At some point you start overoptimizing and do worse on your true objective (hard to know when).
This applies to all proxy measures ever.
Jan Leike
@janleike
This plot is stolen from a really cool paper by Simon Zhuang and @dhadfieldmenell:
arxiv.org/pdf/2102.03896.pdf
They define a simple theoretical model that captures some of this "goodharting" problem pretty well, and use this model to show some theoretical results.
Recommended read! -
Jan Leike
@janleike
Writing on alignment is often too vague and confusing.
We should have precise definitions, written in machine learning language.
I sketched one for the inner alignment problem, based on meta reinforcement learning / RL^2:
aligned.substack.com/p/inner-alignment -
Jan Leike
@janleike
Future intelligence tests for humans: how many parameters does a language model need to have to do as well as you on standardized tests?
-
Jan Leike
@janleike
The most fascinating aspect is that it took almost 2 years for the internet to discover this vulnerability in the model
leastfavorite!
@leastfavorite_
wow guys, i was skeptical at first but it really seems like AI is the future
-
Jan Leike reposted
Chris Olah
@ch402
I've never had so many "this can't possibly be true, we must have a bug" results in the course of a research project before.
I'd like to take a moment to walk through some of the very strange (and surprisingly beautiful) things we found. -
Jan Leike
@janleike
How will we solve the alignment problem for AGI?
I've been working on this question for almost 10 years now.
Our current path is very promising:
openai.com/blog/our-approach-to-alignment-research/
1/Post not available here, view on X
Jan Leike
@janleike
3. We're training AI to do alignment research
There are many other alignment problems we don't know how to solve yet.
Using the two directions above, we'll get AI that's sufficiently aligned to help us devise better alignment techniques.
Best example: stay tuned :)
Jan Leike
@janleike
If you're interested in this topic, check out my blog: aligned.substack.com
-
Jan Leike
@janleike
RSA was published 45 years ago and yet the universally accepted way to digitally sign a document is to make an indecipherable squiggle on a touch screen that no one ever checks.
Jan Leike
@janleike
Also crazy how common it is that people don't email you a copy of what you're signing.
Do y'all also always read every document you sign in full and remember it perfectly thereafter? -
Jan Leike reposted
Mo Bavarian
@mobav0
Suggestions for AI existential risk researchers. Be more empirical, skeptical, and scientific.
Progress won't happen by writing long verbose posts on (not to be named) forums, and shouting on twitter 😉 it happens by rigorous empirical work along with simple careful argument. -
Jan Leike reposted
Sarah Shoker
@SarahShoker
Because AI safety has been 'making the rounds' this week, I want to emphasize that you don't need to identify as longtermist or EA to tackle this issue.
-
Jan Leike reposted
OpenAI
@OpenAI
Introducing a free new tool that gives OpenAI API developers stronger content moderation abilities openai.com/blog/new-and-improved-content-moderation-tooling/
-
Jan Leike reposted
Gretchen Krueger
@GretchenMarina
At EAG SF and interested in AI safety? Stop by OpenAI at the career fair or DM me. We're hiring across teams (incl. Trust and Safety, Security) - and we are always interested in hearing what you want to work on & what you think we should work on!
openai.com/careers/ -
Jan Leike reposted
Dan Hendrycks
@hendrycks
We’ll be organizing a NeurIPS workshop on Machine Learning Safety!
We'll have $50K in best papers awards.
To encourage proactiveness about tail risks, we'll also have $50K in awards for papers that discuss their impact on long-term, long-tail risks.
neurips2022.mlsafety.org -
Jan Leike
@janleike
Question for ML experts who are interested in alignment research:
What kind of resources do you wish there were more of? -
Jan Leike
@janleike
Very few people actually understand "Paul's agenda" and most people who claim to understand it are pretty confused and basically crumble as soon as they get pushed on any of the details. It's legitimately very confusing.
Jan Leike
@janleike
For example, if you ask 10 people who claim to understand what amplification is you get 10 different answers.
-
Jan Leike reposted
Jacob Steinhardt
@JacobSteinhardt
In 2021, I created a forecasting prize to predict ML performance on benchmarks in June 2022 (and 2023, 2024, and 2025). June has ended, so we can see how the forecasters did: bounded-regret.ghost.io/ai-forecasting-one-year-in/
-
Jan Leike
@janleike
This is one of the craziest plots I have ever seen.
World GDP follows a power law that holds over many orders of magnitude and extrapolates to infinity (!) by 2047.
Clearly this trend can't continue forever. But whatever happens, the next 25 years are going to be pretty nuts.
Jan Leike
@janleike
From an excellent article by @davidroodman: www.openphilanthropy.org/research/modeling-the-human-traj…
-
Jan Leike reposted
Allan Dafoe
@AllanDafoe
We are looking to hire Research Scientists for our Long-term Strategy and Governance team at DeepMind! Deadline Aug 1. Please forward and apply:
boards.greenhouse.io/deepmind/jobs/3402612?t=bbda0eea1us -
Jan Leike
@janleike
Should institutions open sourcing large language models be required to take responsibility if they end up being misused to cause harm to society?
-
Jan Leike
@janleike
PSA: If you want to compare InstructGPT to a base model in your research, the closest comparison is "text-davinciplus-002" with "davinci" (you might need to request access to the former).
It's not a super clean comparison, because we haven't deployed the exact paper models.
Jan Leike
@janleike
Unfortunately our engine names are not very self-explanatory. We should be adding more documentation soon.
-
Jan Leike reposted
Anthropic
@AnthropicAI
We're hiring an interpretability team manager to partner with @ch402 on leading our interpretability efforts. We'd love to hear from you!!
jobs.lever.co/Anthropic/b1e3b6a4-f827-46b3-b710-d7bb4b133ece -
Jan Leike reposted
David Krueger 🦥 ⏸️ ⏹️ ⏪
@DavidSKrueger
Our paper on o̶p̶t̶i̶m̶i̶z̶a̶t̶i̶o̶n̶ ̶d̶a̶e̶m̶o̶n̶s̶ / i̶n̶n̶e̶r̶ ̶o̶p̶t̶i̶m̶i̶z̶e̶r̶s̶ / m̶e̶s̶a̶-̶o̶p̶t̶i̶m̶i̶z̶a̶t̶i̶o̶n̶ / i̶n̶n̶e̶r̶ ̶a̶l̶i̶g̶n̶m̶e̶n̶t̶ / o̶b̶j̶e̶c̶t̶i̶v̶e̶ ̶r̶o̶b̶u̶s̶t̶n̶e̶s̶s̶ / **goal misgeneralization** was accepted at ICML!
arxiv.org/abs/2105.14111 -
Jan Leike
@janleike
Kudos to Matt Putz and Max Ra for prompting this!
Matt Putz
@mattputz_
Super exciting news!
In the post Scott mentions comments on his blog by Max Ra and me as having been part of the origin of this. Wild!
Good luck!
Jan Leike
@janleike
Really looking forward to working with the legendary Scott Aaronson!
scottaaronson.blog?p=6484 -
Jan Leike
@janleike
Really looking forward to working with the legendary Scott Aaronson!
scottaaronson.blog?p=6484 -
Jan Leike
@janleike
Super exciting new research milestone on alignment:
We trained language models to assist human feedback!
Our models help humans find 50% more flaws in summaries than they would have found unassisted.
openai.com/blog/critiques/Post not available here, view on X
Jan Leike
@janleike
In this paper, we work with summarization and a few toy tasks, which aren't actually that hard for humans.
Plus, our language models aren't smarter than humans.
Yet our models can already meaningfully help evaluation.
Jan Leike
@janleike
Really awesome job by the team on this paper! William Saunders, Cathy Yeh, @WuTheFWasThat, Steven Bills, @longouyang, and @projectaligned
-
Jan Leike
@janleike
You're working on alignment research and want to try stuff on the big models but the free credits on the API are not enough?
There is a simple form you can fill out to get more 👇
Miles Brundage
@Miles_Brundage
OAI Researcher Access Program form (related to something I'm discussing in the Twitter Spaces event right now :) ) share.hsforms.com/1b-BEAq_qQpKcfFGKwwuhxA4sk30
-
Jan Leike reposted
Benjamin Hilton
@benjamin_hilton
No, DALL-E doesn’t have a secret language.
(or at least, we haven't found one yet)
This viral DALL-E thread has some pretty astounding claims. But maybe the reason they’re so astounding is that, for the most part, they're not true.
Thread 👇🧵 (1/15)
Giannis Daras
@giannis_daras
DALLE-2 has a secret language.
"Apoploe vesrreaitais" means birds.
"Contarra ccetnxniams luryca tanniounons" means bugs or pests.
The prompt: "Apoploe vesrreaitais eating Contarra ccetnxniams luryca tanniounons" gives images of birds eating bugs.
A thread (1/n)🧵 -
Jan Leike
@janleike
Here I assumed the model was just dyslexic
Giannis Daras
@giannis_daras
DALLE-2 has a secret language.
"Apoploe vesrreaitais" means birds.
"Contarra ccetnxniams luryca tanniounons" means bugs or pests.
The prompt: "Apoploe vesrreaitais eating Contarra ccetnxniams luryca tanniounons" gives images of birds eating bugs.
A thread (1/n)🧵 -
Jan Leike
@janleike
If you're interested in alignment research and happen to be at EAG in London 👇
Geoffrey Irving
@geoffreyirving
I will be at the EA Global London 2022 Career fair from 4 - 8 pm on Friday 15 April, and am hiring for roles on DeepMind's Scalable Alignment Team.
Please say hello if you're interested in AGI safety and language models, both using LMs for safety and mitigating harms from LMs. -
Jan Leike
@janleike
If you're interested in alignment research and happen to be at EAG in London 👇
Rohin Shah
@rohinmshah
I'm hiring for Research Scientist and Research Engineer roles on the Alignment team at DeepMind! Come talk to me at the EA Global London career fair (4-8 pm Friday 15 April), or DM / email me and I can let you know when the job ad officially goes up.
-
Jan Leike
@janleike
Well explained blog post about over-optimizing reward models using simple best-of-n sampling: openai.com/blog/measuring-goodharts-law
By Jacob Hilton and @nabla_theta -
Jan Leike
@janleike
Pretty disturbing story. Why does it take 9 months to resolve a sexual harassment case?
DeepMind can do better than that.
www.ft.com/content/928c5a91-baaa-41f2-b922-a07c74704e47 -
Jan Leike
@janleike
Did you know that last year Alphabet had a shareholder vote on transitioning to a public benefit corporation?
Only ~1% of shares voted in favor of it.Post not available here, view on X
Jan Leike
@janleike
To be fair, I'm an Alphabet shareholder too and I don't even know how I voted. Or how to vote. Or even that this vote was happening.
If you own any index funds, you're probably a shareholder as well. I presume index funds just automatically vote for whatever is best for profits? -
Jan Leike reposted
Gretchen Krueger
@GretchenMarina
My team is hiring a Senior Research Engineer / Software Engineer! Want to work alongside @ThankYourNiceAI @SandhiniAgarwal @pamelamishkin @_lamaahmad @girishsastry to prototype approaches for measurement of AI systems and societal impact? Apply here: boards.greenhouse.io/openai/jobs/4361360004
-
Jan Leike
@janleike
I wish there were better resources for machine learning researchers who are interested to dive into alignment research
-
Jan Leike reposted
OpenAI
@OpenAI
Deploying and studying the real-world use of language models helps us learn more about safety and misuse than research alone.
As we advance our safety and policy work, we're sharing some of our findings to help others do the same. openai.com/blog/language-model-safety-and-misuse/ -
Jan Leike
@janleike
Extremely exciting alignment research milestone:
Using reinforcement learning from human feedback, we've trained GPT-3 to be much better at following human intentions.
openai.com/blog/instruction-following/
Jan Leike
@janleike
Disclaimer: There isn't really much new in terms of methods or algorithms.
But it shows that our alignment techniques work in a real-world setting.
This is cheaper and more effective at making a more useful model than just making it bigger.
Jan Leike
@janleike
For comparison: We spent <2% of the pretraining compute on fine-tuning and collect a few 10,000s of human labels and demos. Our 1.3b parameter models (GPT-2 sized!) are preferred over a prompted 175b parameter GPT-3.
Post not available here, view on X
Jan Leike
@janleike
Awesome work by an awesome team! ❤️ @longouyang, Jeff Wu, Xu (Roger) Jiang, Diogo Almeida, Carroll Wainwright, @pamelamishkin, @paulfchristiano, @ryan_t_lowe, and many, many others!
Jan Leike
@janleike
Needless to say, this is only the beginning. InstructGPT isn't even close to being fully aligned or fully safe.
But it shows that we have a general recipe that works! -
Jan Leike
@janleike
How do you train an RL agent to avoid unsafe states, without knowing where they are?
Answer: ask humans about hypotheticals.
Exciting progress, with colleagues at DeepMind: training agents in 3D environments without ever falling off a cliff!
deepmindsafetyresearch.medium.com/avoiding-unsafe-states-…
Jan Leike
@janleike
In the experiments almost all mistakes were made by humans. But: the technique still works just as well if we only train on the safe demonstrations.
This is an important proof of concept that this technique scales and that the goal of zero safety violations is achievable!
Jan Leike
@janleike
Awesome work by my colleagues Matthew Rahtz, @vkrntv, Ramana Kumar, @ZacKenton1, and @ShaneLegg at @DeepMind
-
Jan Leike reposted
John Schulman
@johnschulman2
Glad to finally release this, as it includes a bunch of directions I'm excited about:
- RL with a reward function defined by human judgements
- language models using tools (a web browser)
- making it easier for humans to rate the AI's output (AI cites its sources)
OpenAI
@OpenAI
We trained a research version of GPT-3 that can search the web, synthesize information, and cite its sources to provide more accurate answers to questions. openai.com/blog/improving-factual-accuracy/
-
Jan Leike
@janleike
We're looking for a software engineer for our human feedback infrastructure and frontend.
We have exciting plans to use our models to assist human feedback, but we need help to make it happen!
grnh.se/4972b51c4us -
Jan Leike
@janleike
It was great chatting with @jeremiecharris on the Towards Data Science Podcast.
If you want to hear more about how I'm thinking about the alignment problems these days, check it out:
towardsdatascience.com/ai-alignment-at-openai-a242a135d3b… -
Jan Leike
@janleike
I'm very interested in techniques for supervising models to do tasks that are difficult for humans to evaluate.
To study this, we trained a model on summarizing entire books!
Read more 👇
openai.com/blog/summarizing-booksPost not available here, view on X
Jan Leike
@janleike
Going forward, we want to train on harder tasks and decompose the evaluation of tasks instead of the tasks themselves. This way we can empower humans to evaluate our models and give value input even as tasks get very complex, while the model still learns to do the task end-to-end
Jan Leike
@janleike
If this sort of work interests you, we’re looking for more talented people to join us!
boards.greenhouse.io/openai/jobs/4050138004 -
Jan Leike reposted
Ryan Lowe
@ryan_t_lowe
📢 We're hiring a data scientist for the Alignment team at @OpenAI! 😊
We're looking for someone who cares deeply about the data used to train ML systems, potentially w/ experience in participatory design, safety/ social impact of ML systems, etc.
Link: jobs.lever.co/openai/4fe793c7-5591-412a-95a6-8b787b1e8ade -
Jan Leike
@janleike
I'm excited for this NeurIPS competition on training RL agents from human data. There is a lot of room for more innovation in this space, and better algorithms should help us build more aligned AI systems in the future!
Rohin Shah
@rohinmshah
Yesterday we announced the BASALT competition. Why did we make it? TL;DR: It lets us test our ability to build agents that solve fuzzy tasks where rewards are hard to specify. (1/6)
Participate: www.aicrowd.com/challenges/neurips-2021-minerl-basalt-com…
Paper: arxiv.org/abs/2107.01969
Blog: bair.berkeley.edu/blog/2021/07/08/basalt/ -
Jan Leike
@janleike
There are a lot of exciting things in the Codex paper, but my favorite titbit is the misalignment evaluations by @BethMayBarnes: Subtly buggy code in the context makes the model more likely to write buggy code, and this discrepancy gets larger as the models get bigger!
Post not available here, view on X
Jan Leike
@janleike
What is surprising is that the effect is quite strong: subtly buggy context degrades performance equivalent to a ~10x smaller model.
Jan Leike
@janleike
Ideally the model should always write the best code, no matter how buggy the context. These kind of alignment problems are what we're trying to solve!
-
Jan Leike reposted
Gretchen Krueger
@GretchenMarina
We’re hiring on @OpenAI’s Policy Research team✨(that’s @PamelaMishkin @SandhiniAgarwal @girishsastry, @Miles_Brundage & yours truly!) I'm super-excited to share 3 roles: Program Manager; Research Scientist, Societal Harms of AI; and Research Scientist, Geopolitics of AI. Thread:
-
Jan Leike
@janleike
I'm excited about this work because it's the first real algorithm for calculating differences in reward functions without running RL! I expect this is going to be a very useful tool for measuring alignment going forward.
Great work by @ARGleave, @MichaelD1729 et al.
Google DeepMind
@GoogleDeepMind
How can you tell if you have a good reward function? EPIC quickly & reliably measures the distance between reward functions. Small distances imply similar optimal policy returns, even in unseen environments.
Blog: dpmd.ai/epic
Paper #iclr2021: dpmd.ai/epicpaper -
Jan Leike
@janleike
I really love this new paper showing how single neurons respond across modalities in CLIP models. Opens up a new avenue of new typographic attacks to fool these kinds of models.
By @gabeeegoooh, @ch402, and others.
distill.pub/2021/multimodal-neurons -
Jan Leike reposted
Carina Prunkl
@carinaprunkl
Can we better address ethical challenges from AI by asking researchers to submit broader impact statements @NeurIPSConf?
My colleagues C. Ashurst, @Manderljung, Helena Webb, @AllanDafoe, @janleike and I discuss challenges and opportunities @NatMachIntell rdcu.be/cfq8m -
Jan Leike
@janleike
We're hiring research engineers for alignment work at @OpenAI!
If you're excited about finetuning gpt3-sized language models to be better at following human intentions, then this is for you!
Apply here: jobs.lever.co/openai/98599d5b-2d1d-4127-b9b5-708343c8730b -
Jan Leike
@janleike
Last week I joined @OpenAI to lead their alignment effort.
Very exicited to be part of the team!
Jan Leike
@janleike
I love the work that @OpenAI has been doing on reward modeling, most notably aligning #gpt3 using human preferences. Looking forward to building on it!
openai.com/blog/learning-to-summarize-with-human-feedback/ -
Jan Leike reposted
Eric J. Michaud
@ericjmichaud_
Excited to share my new paper “Understanding Learned Reward Functions” with co-authors @ARGleave and Stuart Russell, presented at the Deep RL Workshop at #neurips2020
Paper: arxiv.org/abs/2012.05862
Code: github.com/HumanCompatibleAI/interpreting-rewards
Presentation: slideslive.com/38941395/understanding-learned-reward-func… -
Jan Leike reposted
Center for Human-Compatible AI
@CHAI_Berkeley
Applications for CHAI internships are open!
We rely on word of mouth so please retweet or share the application with someone you think would be interested in the internship!
humancompatible.ai/jobs -
Jan Leike reposted
Shimon Whiteson
@shimon8282
I agree with the claim that reward is overvalued but probably not for the reason intended here.
Reward is overvalued because it is often misspecified: we have a bad habit of assuming we know how to define reward, when in fact this is often a tricky value alignment problem.
hardmaru
@hardmaru
I've received so much criticism for not incorporating reward info into world model / representations used by RL agents
But the way I see it, rewards are so overvalued…
See this new paper, “Decoupling Representation Learning from Reinforcement Learning”
arxiv.org/abs/2009.08319 -
Jan Leike reposted
Thore Graepel
@ThoreG
We are organising a @NeurIPSconf workshop on Cooperative AI: helping agents (machines and humans) to work together to achieve their goals. Please consider submitting your work. cooperativeai.com with @AllanDafoe @Dario_Amodei @conitzer @ghadfield @erichorvitz @kateslarson
-
Jan Leike
@janleike
This is very cool work! Really showcases the power of reward modeling as a scalable alignment technique.
OpenAI
@OpenAI
We've used reinforcement learning from human feedback to train language models for summarization. The resulting models produce better summaries than 10x larger models trained only with supervised learning: openai.com/blog/learning-to-summarize-with-human-feedback/
-
Jan Leike
@janleike
Today was my last day at @DeepMind. It's been an amazing journey; I've learned so many things and got to work with so many amazing people!
Excited for what comes next! -
Jan Leike
@janleike
How do you measure the distance between two reward functions?
Our EPIC distance is invariant to reward shaping, can be approximated efficiently, and is predictive of policy training success and transfer!
New paper with @ARGleave, @MichaelD1729 et al.
arxiv.org/abs/2006.13900 -
Jan Leike
@janleike
Submtting a NeurIPS paper and unsure how to write your broader impact statement?
This blog post will guide you through it!
Comes with a few concrete examples, too.
shorturl.at/qrZ45
By Carolyn Ashurst, @Manderljung, @carinaprunkl, @yaringal, and Allan Dafoe. -
Jan Leike reposted
Google DeepMind
@GoogleDeepMind
What happens if AI ingenuity is applied to an imperfectly specified task? This can result in specification gaming: an agent exploiting a loophole at the expense of the intended outcome. Why does it happen, & how can it be overcome?
Read our latest post: deepmind.google/blog/specification-gaming-the-flip-side-o… -
Jan Leike
@janleike
Lucas Perry from FLI interviewed me for their podcast!
If you want to find out why I don't do theory research anymore, what's going on in safety at DeepMind, and how we're planning to solve the alignment problem, check it out:
futureoflife.org/2019/12/16/ai-alignment-podcast-on-deepm… -
Jan Leike
@janleike
Very accessible explanation of the motivation behind reward modeling by @robertskmiles:
youtu.be/PYylPRX6z4Q
Jan Leike
@janleike
Rob has a whole YouTube channel dedicated to explaining AI safety ideas for everyone to understand. Definitely worth checking out if you're interested in this stuff!
m.youtube.com/channel/UCLB7AzTwc6VFZrBsO2ucBMg -
Jan Leike
@janleike
How do you train an RL agent in the presence of unknown, unsafe states without visiting them even once?
New algorithm by our intern @sidgreddy synthesizes trajectories with a generative model and ask a human to label them for safety.
deepmind.com/blog/article/learning-human-objectives-by-ev… -
Jan Leike reposted
Adam Gleave
@ARGleave
Want to ensure AI is beneficial for society? Come talk to like-minded people at the Human-Aligned AI Social at #neurips2019, Thursday 7-10 pm, room West 205-207. nips.cc/Conferences/2019/Schedule?showEvent=15974 @claudia_shi57 @victorveitch
-
Jan Leike reposted
Jon Fildes
@jonfildes
I love all of the programmes, but I particularly like ep 4 - one of my favourite bits of the whole series is when @janleike explains the human preferences work we did with @OpenAI
Google DeepMind
@GoogleDeepMind
And finally for this week, episode 4 - AI, Robot - visits the DeepMind robotics lab, and dives into the key questions around AI safety.
🔊👇for a preview or subscribe podcasts.apple.com/gb/podcast/deepmind-the-podcast/id1476…This media couldn't be displayed. See it on the original post. -
Jan Leike
@janleike
How do you design agents that don’t have an incentive to tamper with their reward signal? @tom4everitt et al. derive design principles for RL algorithms. Easy fix if you’re doing model-based RL!
medium.com/@deepmindsafetyresearch/designing-agent-incent… -
Jan Leike reposted
Vishal Maini
@v_maini
Excited to finally share this AI Reading List, compiling key resources on artificial intelligence & its long-term implications.
The list is divided into "80/20" resources and "deep dive" resources to help with suggested prioritization.
medium.com/@v_maini/ai-reading-list-c4753afd97a -
Jan Leike
@janleike
Very excited to deliver the #icml2019 tutorial on #safeml tomorrow together with @csilviavr!
Be prepared for fairness, human-in-the-loop RL, and a general overview of the field.
And lots of memes!
Jan Leike
@janleike
It's 9:15am in room 104.
icml.cc/Conferences/2019/Schedule?showEvent=4339 -
Jan Leike reposted
80,000 Hours
@80000Hours
I had a fantastic conversation with @DeepMindAI scientist Pushmeet Kohli about how they're developing new ways to keep AI systems robust & reliable, why it’s a core issue in AI design that everyone has to attend to, and how to succeed as an AI researcher:
80000hours.org/podcast/episodes/pushmeet-kohli-deepmind-s… -
Jan Leike
@janleike
How do we uncover failures in ML models that occur too rarely during testing? How do we prove their absence?
Very excited about the work by @DeepMindAI’s Robust & Verified AI team that sheds light on these questions! Check out their blog post:
deepmind.com/blog/robust-and-verified-ai -
Jan Leike reposted
Edward Grefenstette
@egrefen
New version on arXiv of our ICLR paper with @DBahdanau, @FelixHill84, @janleike, Edward Hughes, and @pushmeet. We jointly learn language-conditional policies and reward models.
Updated results/explanations + discussion of relation with other IRL methods.
arxiv.org/abs/1806.01946 -
Jan Leike
@janleike
Recent evidence that there can be unexpected unaligned agents in your data center:
-
Jan Leike reposted
Google DeepMind
@GoogleDeepMind
Join us and @Blizzard_Ent this Thursday at 6:00pm GMT for an exciting #starcraft demonstration, hosted by @Artosis and @RotterdaM08!
Livestream on YouTube: www.youtube.com/c/deepmind
Read more about #starcraft2 as an environment for AI research: deepmind.com/blog/deepmind-and-blizzard-open-starcraft-ii… -
Jan Leike
@janleike
Multiparty computation is awesome because it lets multiple parties train a model without seeing the weights.
But there are fundamental limits to making it scalable: >24x overhead!
Our new paper addresses this problem.
arxiv.org/abs/1812.05979
w/ @MiljanMartic @iamtrask et al. -
Jan Leike reposted
Google DeepMind
@GoogleDeepMind
Good morning #neurips18! Stop by our recruitment stand from now until 9:50am to meet with our Safety team. Read more about their work: medium.com/@deepmindsafetyresearch/building-safe-artifici…
Later today, our Science team will have a meet & greet at 3pm - come chat about protein folding! deepmind.com/blog/alphafold/ -
Jan Leike
@janleike
The agent alignment problem may be one of the biggest obstacles for using ML to improve people’s lives.
Today I’m very excited to share a research direction for how we’ll aim to solve alignment at @DeepMindAI.
Blog post: medium.com/@deepmindsafetyresearch/scalable-agent-alignme…
Paper: arxiv.org/pdf/1811.07871.pdf -
Jan Leike
@janleike
New paper with @OpenAI on learning to play Atari games without rewards: demonstrations help get a better state space coverage and are a more efficient communication channel than preferences. Both together outperform preferences and imitation alone. 1/3
arxiv.org/abs/1811.06521
Jan Leike
@janleike
We included more analysis of why reward learning works better in some games than others (Atari games have a lot of diversity!), including evaluating how aligned the learned reward model is. 2/3
Jan Leike
@janleike
Finally, more evidence that the reward model needs to be trained with humans in the loop; otherwise the agent learns to exploit the reward model, for example by pretending to shoot a spider in Hero. 3/3
-
Jan Leike reposted
Miles Brundage
@Miles_Brundage
Podcast with @catherineols and Daniel Ziegler on ML engineering as a career and related issues: 80000hours.org/podcast/episodes/olsson-and-ziegler-ml-eng…
And a written guide from @catherineols on moving from CS/software engineering to ML engineering/AI safety: 80000hours.org/articles/ml-engineering-career-transition-…
😍 -
Jan Leike reposted
Google DeepMind
@GoogleDeepMind
We are looking forward to the Effective Altruism Global conference this weekend in London. If you're attending, come visit our team and other interesting organisations at tonight's careers fair. london.eaglobal.org/agenda/session/24087
-
Jan Leike
@janleike
We now have a safety research blog! Check out the first post by @adaptiveagents and @v_maini on how to categorize safety problems: medium.com/@deepmindsafetyresearch/building-safe-artifici…
-
Jan Leike reposted
Jeff Dean
@JeffDean
As AI is applied to more and more problems through society, it's important to think carefully about the principles by which this is done. We've just shared Google's AI principles, which shows how we've been thinking about these issues. #googleai
blog.google/topics/ai/ai-principles/ -
Jan Leike
@janleike
New paper on teaching RL agents to understand the meaning of instructions. Instead of manually specifying rewards, we learn them from goal-state examples. With @DBahdanau, Felix Hill, @edwardfhughes, @pushmeet, and @egrefen! arxiv.org/pdf/1806.01946.pdf
-
Jan Leike
@janleike
Computerphile made an awesome video about our AI safety gridworlds, including some sweet animations. Check it out: youtu.be/eElfR_BnL5k
Jan Leike
@janleike
There is also a follow-up video on Robert Miles' channel:
youtu.be/CGTkoUidQ8I
He regularly posts cool videos of AI safety ideas on his channel, and they are generally very well explained! Subscription recommend :) -
Jan Leike
@janleike
Very interesting and original approach for value alignment with a focus on scalability by @geoffreyirving
blog.openai.com/debate/ -
Jan Leike reposted
Future of Humanity Institute
@FHIOxford
New report about 'Deciphering China's AI dream' from FHI's Jeffrey Ding. www.fhi.ox.ac.uk/wp-content/uploads/Deciphering_Chinas_AI…
-
Jan Leike
@janleike
Interested in getting into machine learning research and AI safety in particular? @80000Hours recently interviewed me about this. Check out the podcast:
80000hours.org/2018/03/jan-leike-ml-alignment/ -
Jan Leike reposted
Miles Brundage
@Miles_Brundage
Can you tell if you’ll like an ML paper after skimming for 30s? @FHIOxford's AI safety team is creating a dataset on quick vs. careful judgments about ML papers.
Please consider taking part - no signup required. thinkagain.ought.org -
Jan Leike reposted
Google DeepMind
@GoogleDeepMind
Our new paper in the Journal of Artificial Intelligence Research (JAIR) demonstrates how deep neural networks can be extended to generalise visually and symbolically. deepmind.com/blog/learning-explanatory-rules-noisy-data/
-
Jan Leike reposted
Distill
@distillpub
Know someone doing amazing work bringing clarity to ML? Nominate them for the $10,000 USD @distillpub prize. Email prize@distill.pub with a link to their work before Jan 1.
distill.pub/prize/ -
Jan Leike reposted
Max Tegmark
@tegmark
We at @FLIxrisk are excited to announce a multimillion grant competition for research on how to keep artificial general intelligence safe and beneficial: futureoflife.org/2017/12/20/2018-international-ai-safety-…
-
Jan Leike
@janleike
Our new paper with RL environments for AI safety problems: deepmind.com/blog/specifying-ai-safety-problems/ arxiv.org/pdf/1711.09883.pdf
-
Jan Leike reposted
Geoffrey Irving
@geoffreyirving
@openai is hiring safety researchers! Help us make friendly AI! openai.com/jobs
-
Jan Leike reposted
OpenAI
@OpenAI
Open-sourcing an interface for training AIs via small amounts of human feedback: blog.openai.com/gathering_human_feedback/
-
Jan Leike reposted
Future of Humanity Institute
@FHIOxford
Exciting new FHI paper: Trial without Error: Towards Safe RL with Human Intervention www.fhi.ox.ac.uk/trial-without-error-towards-safe-rl-huma… w/ @girishsastry @stuhlmueller
-
Jan Leike reposted
Ian Goodfellow
@goodfellow_ian
NIPS 2017 adversarial examples challenge: www.kaggle.com/c/nips-2017-non-targeted-adversarial-attack Test your defenses against others' adversarial examples and vice versa!
-
Jan Leike reposted
Google DeepMind
@GoogleDeepMind
We're opening a research office in #edmonton, Canada, in collaboration with @UAlberta, led by RL pioneer Rich Sutton deepmind.com/blog/deepmind-office-canada-edmonton/
-
Jan Leike reposted
Ian Goodfellow
@goodfellow_ian
New blog post with @NicolasPapernot on why verification methods for machine learning are so difficult: www.cleverhans.io/security/privacy/ml/2017/06/14/verifica…
-
Jan Leike reposted
Future of Humanity Institute
@FHIOxford
Interested in AI strategy as a career? Great podcast/article from @80000Hours interviewing @Miles_Brundage 80000hours.org/2017/06/the-world-desperately-needs-ai-str…
-
Jan Leike
@janleike
New AI safety paper with @OpenAI on how to train a deep RL agent from human preferences deepmind.com/blog/learning-through-human-feedback/
-
Jan Leike
@janleike
This is a brilliant parody of stupid arguments around AI philpapers.org/rec/GAROTI-3