 Qwen
@Alibaba_Qwen

Qwen4-Max has made significant improvements on coding and finance tasks in particular. 🎉 @ValsAI

Politicians, athletes, journalists, NGOs, companies... They all use corporation-owned social networks to communicate with us. Citizens shouldn't have to hand over their data to companies to read content published by public entities. Public Feeds changes that by making posts of popular accounts freely available. Read more.

Qwen (also known as Tongyi Qianwen, Chinese: 通义千问; pinyin: Tōngyì Qiānwèn) is a family of predominantly open-weights large and small language models (LLM and SLM) developed by Alibaba Cloud. More on Wikipedia
Open foundation models for AGI.
Qwen
@Alibaba_Qwen
Qwen4-Max has made significant improvements on coding and finance tasks in particular. 🎉 @ValsAI
Qwen
@Alibaba_Qwen
+9 points over Qwen3.8-Max with lower costs. Give it a try! @ArtificialAnlys
 Artificial Analysis
@ArtificialAnlys
Alibaba has launched Qwen4 Max, gaining 9 points over Qwen3.8 Max on the Artificial Analysis Intelligence Index and landing 3 points behind Kimi K3.1 Pro at ~11% lower Cost per Task
Qwen4 Max, using xhigh reasoning effort, scores 43 on the Intelligence Index, 9 points ahead of Qwen3.8 Max (xhigh) and 3 points behind Kimi K3.1 Pro (max, 46)
Key takeaways:
➤ Qwen4 Max improves on every evaluation in the Index vs Qwen3.8 Max (xhigh, 34): HLE-Diamond +21 points (24% to 45%), AA-Omniscience +18 points, AutomationBench-AA +17 points, CritPt v2 +13 points, Terminal-Bench-Science +11 points, Terminal-Bench 4.0 +9 points, GDP.pdf +3 points, FrontierCode 2.0 +3 points and AA-Briefcase +82 Elo.
➤ Qwen4 Max costs $3.27 per Intelligence Index task, ~3x less than Qwen3.8 Max ($10.02) and ~11% less than Kimi K3.1 Pro ($3.68): This is driven by 25% lower per-token pricing than Qwen3.8 Max, 70% cheaper cache hits and lower token usage. Tencent Hy4 costs ~3x less per task ($1.03) than Qwen4 Max but scores 8 points lower on the Index.
➤ Qwen4 Max uses 39% fewer output tokens per task than Qwen3.8 Max: ~105k output tokens per Intelligence Index task vs ~171k for Qwen3.8 Max, ~72k for Kimi K3.1 Pro and ~78k for Tencent Hy4. Qwen4 Max uses fewer tokens, while increasing 9 points on the Intelligence Index
➤ Improvements in AA-Briefcase (knowledge work): On AA-Briefcase, our evaluation of agentic work across real business files, Qwen4 Max reaches 1686 Elo vs 1674 for Kimi K3.1 Pro and 1446 for Tencent Hy4.
➤ Qwen4 Max trails Kimi K3.1 Pro on Terminal-Bench 4.0 and Tencent Hy4 on FrontierCode 2.0: Qwen4 Max scores 48% on Terminal-Bench 4.0 vs 67% for Kimi K3.1 Pro and 37% for Tencent Hy4. On FrontierCode 2.0, @cognition’s private evaluation of real-world coding tasks, it scores 26%, level with Kimi K3.1 Pro (26%) and behind Tencent Hy4 (31%).
Key model details:
➤ Context window: 1M tokens
➤ Multimodal: Text and image input with text output
➤ Pricing: $1.50/$4.50 per 1M input/output tokens on Alibaba's first-party APIs, with a $0.075 cache hit price. This is lower than Qwen3.8 Max across the board ($2.00/$6.00, with a $0.25 cache hit price)
➤ Availability: @Alibaba_Qwen 's first-party APIs
 Qwen
@Alibaba_Qwen
Live in OpenCode Go. Try it now! 👀
 OpenCode
@opencode
Qwen4 Max is now available in OpenCode Go
Qwen
@Alibaba_Qwen
Qwen4-Max is live on @OpenRouter — go build with it.🙌
 OpenRouter
@OpenRouter
Qwen4 Max from @Alibaba_Qwen is live on OpenRouter.
The first model in the Qwen4 series, built for coding, office work and long-horizon agents.
Qwen
@Alibaba_Qwen
#4 on Python-PPTX arena and #5 on Spreadsheet arena. Thanks! @DesignArena
 DesignArena
@DesignArena
BREAKING: Qwen4-Max by @Alibaba_Qwen ranks #4 on Python-PPTX arena with an Elo rating of 1302 and #5 on Spreadsheet arena with an Elo rating of 1336.
On Spreadsheet arena, this marks a 30-position jump from Qwen’s previous model, Qwen 3.7 Max, and a 379-point Elo increase. On Python-PPTX arena, this marks a 5-position jump from its previous model and an 80-point Elo increase. This also places it in the same performance band as top models from @AnthropicAI, @OpenAI, and @Kimi_Moonshot.
Congrats to the @Alibaba_Qwen team on placing top-5 on both leaderboards!

 Qwen
@Alibaba_Qwen
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: www.qwencloud.com/models/qwen4-max
- Token Plan: www.qwencloud.com/pricing/token-plan
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
 Qwen
@Alibaba_Qwen
Qwen4-Max landed #6 in Image-to-WebDev Arena with 1674 pts — up 35 pts over Qwen3.8-Max at 1639. 🎨
Qwen
@Alibaba_Qwen
Qwen4-Max outperforms Qwen3.8-Max by +7.5% net on Agent Arena, making Alibaba #5 lab overall.
 Arena.ai
@arena
Qwen4-Max by @Alibaba_Qwen is the #1 Chinese model on the leaderboard making Alibaba now the #1 Chinese lab and #5 lab overall, just behind Anthropic, Google, OpenAI and Meta.
It debuts overall at #14 on Agent Arena with +7.5% net improvement across 14.7k real-world agentic sessions from our global community, real traces on real tasks.
This is a major leap over Qwen3.8-Max
- Rank: #39 → #14 overall
The Chinese frontier on Agent Arena:
- #14 Qwen4-Max (Alibaba): +7.5%
- #19 Hy4 (Tencent): +5.7%
- #21 Kimi K3.1 Pro (Max) (Moonshot): +4.0%
- #26 MiMo-V2.6-Pro (Xiaomi): +1.5%
- #30 DeepSeek-V4.1-Flash (Max) (DeepSeek): +1.1%
Breaking down performance across signals:
Qwen4-Max improves over Qwen3.8-Max across all four reported signals, with particularly large gains in user satisfaction and steerability.
- #15 Praise vs. Complaint: +13% (best Chinese model)
- #13 Confirmed Success: +9% (best Chinese model)
- #19 Steerability: +8%
- #29 Bash Reliability: +3%
By category, it is a top-ranked Chinese model across all 3:
- #12 in Work: +9%
- #14 in Chat: +8%
- #16 in Code: +8%
Congrats to the @Alibaba_Qwen team on this release!
 Qwen
@Alibaba_Qwen
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: www.qwencloud.com/models/qwen4-max
- Token Plan: www.qwencloud.com/pricing/token-plan
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
Qwen
@Alibaba_Qwen
Qwen4-Max lands at #6 in the Code Arena: WebDev — up 74 pts over Qwen3.8-Max. Give it a try! 🙌 @arena
Arena.ai
@arena
Qwen4-Max by @Alibaba_Qwen has landed as #6 in the Code Arena: WebDev!
With 1750 pts (preliminary), it's +74 pts over its predecessor, Qwen3.8-Max (0902) at 1676.
It's also the top Chinese model in:
- #6 HTML: 1748 pts
- #8 Brand & Marketing: 1705 pts
- #8 Reference-Based Design: 1770 pts
Congrats to the @Alibaba_Qwen team on this release!
 Arena.ai
@arena
Qwen4-Max by @Alibaba_Qwen is the #1 Chinese model on the leaderboard making Alibaba now the #1 Chinese lab and #5 lab overall, just behind Anthropic, Google, OpenAI and Meta.
It debuts overall at #14 on Agent Arena with +7.5% net improvement across 14.7k real-world agentic sessions from our global community, real traces on real tasks.
This is a major leap over Qwen3.8-Max
- Rank: #39 → #14 overall
The Chinese frontier on Agent Arena:
- #14 Qwen4-Max (Alibaba): +7.5%
- #19 Hy4 (Tencent): +5.7%
- #21 Kimi K3.1 Pro (Max) (Moonshot): +4.0%
- #26 MiMo-V2.6-Pro (Xiaomi): +1.5%
- #30 DeepSeek-V4.1-Flash (Max) (DeepSeek): +1.1%
Breaking down performance across signals:
Qwen4-Max improves over Qwen3.8-Max across all four reported signals, with particularly large gains in user satisfaction and steerability.
- #15 Praise vs. Complaint: +13% (best Chinese model)
- #13 Confirmed Success: +9% (best Chinese model)
- #19 Steerability: +8%
- #29 Bash Reliability: +3%
By category, it is a top-ranked Chinese model across all 3:
- #12 in Work: +9%
- #14 in Chat: +8%
- #16 in Code: +8%
Congrats to the @Alibaba_Qwen team on this release!
Qwen
@Alibaba_Qwen
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: www.qwencloud.com/models/qwen4-max
- Token Plan: www.qwencloud.com/pricing/token-plan
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
Qwen
@Alibaba_Qwen
📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: www.qwencloud.com/models/qwen4-max
- Token Plan: www.qwencloud.com/pricing/token-plan
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀
Qwen
@Alibaba_Qwen
Manufacturing: from sketch to real-world industrial production.
Qwen
@Alibaba_Qwen
AI for science: autonomous design and synthesis of novel coolant materials.
Qwen
@Alibaba_Qwen
Qwen4 is coming.
Deeper knowledge. Richer world understanding. Stronger coding and agentic capabilities.
Built for real-world tasks — from complex coding and knowledge work to front-end builds and professional software workflows.
Qwen4-Max is now in preview on Alibaba’s Token Plan. You can also get early access to the new model on QwenWork, Qoder, Qwen APP, and QwenStudio.
Put it to the test on a real problem. Show us what you build. 👀
Token Plan: qwencloud.com/pricing/token-plan
 Qwen
@Alibaba_Qwen
The becoming begins.
 Qwen
@Alibaba_Qwen
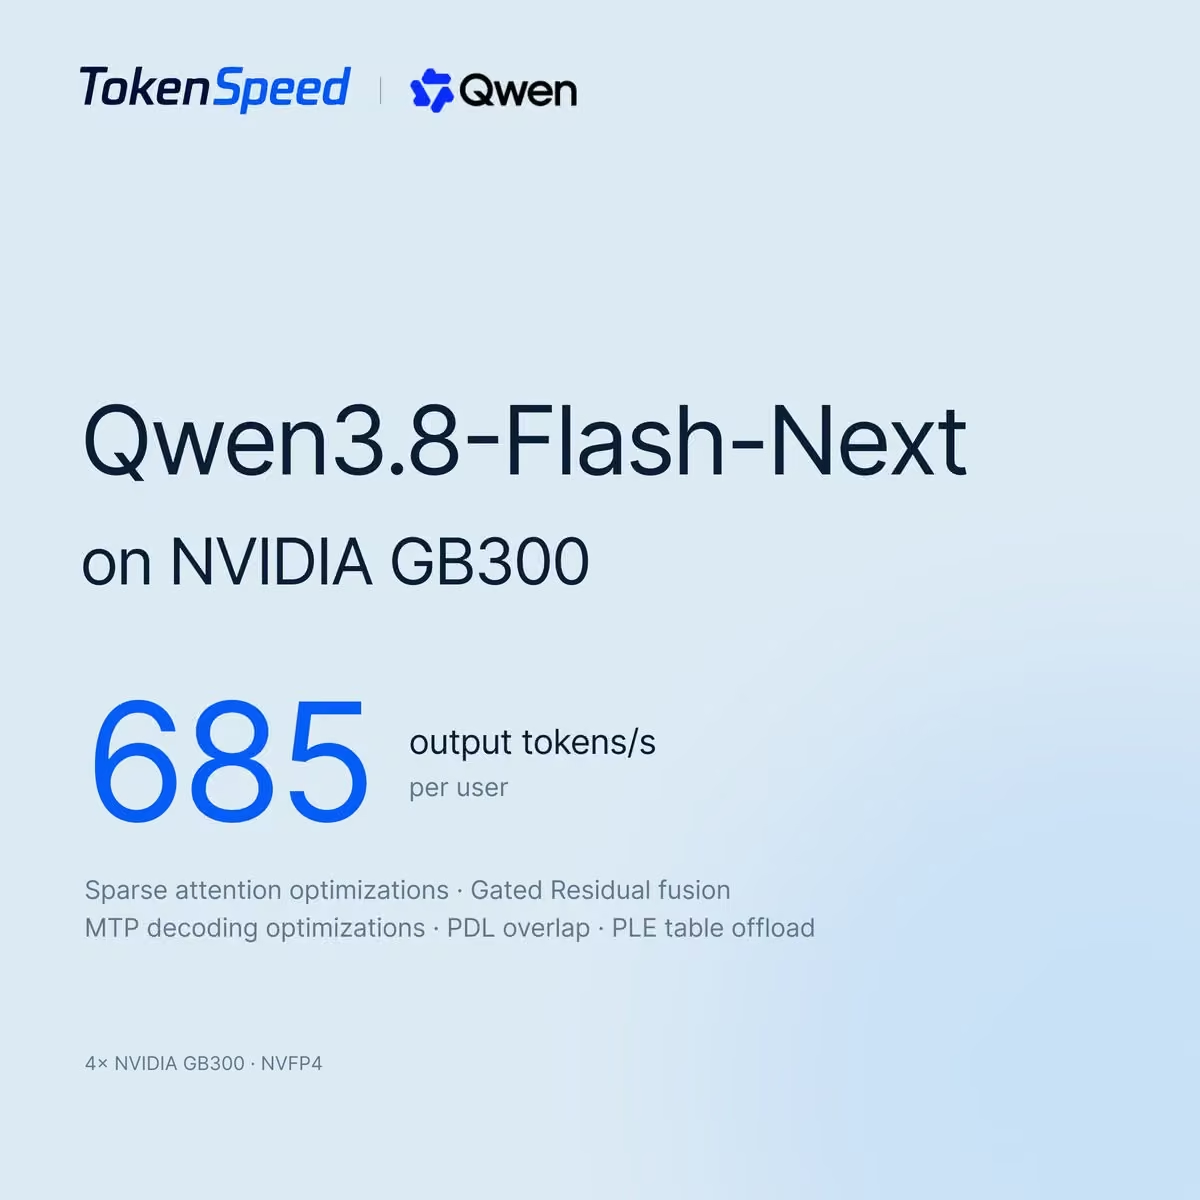
Congrats to @lightseekorg on the impressive TokenSpeed results! 🚀 Great to see Qwen3.8-Flash-Next reaching 685 output tokens/s per user on Nvida GPUs. Excited to see the community unlock more of Qwen’s inference potential!
 LightSeek Foundation
@lightseekorg
685 output tokens/s per user on @Alibaba_Qwen Qwen3.8-Flash-Next.
Running TokenSpeed on 4× NVIDIA GB300 with NVFP4.
A look at the kernel and serving optimizations behind the results:
👉 lightseek.org/blog/tokenspeed-qwen3-8-flash-next.html
⭐ github.com/lightseekorg/tokenspeed
 Qwen
@Alibaba_Qwen
Introducing QwenGyre, bringing elastic RL to extreme-long-horizon (XLong) agent training. ✨
It launches with two core designs: 🥳
- Elastic Scheduler: reallocates GPUs between rollout & training as demand shifts—live executions never interrupted. Up to 1.85× speedup over Colocate, 1.78× over Async.
- Trajectory Processor: turns branching executions (compaction, sub-agents, retries) into prefix-shared trajectory trees with bounded, deduplicated training samples. Partial progress after timeout still gets scored.
Scaled to Qwen3.8-2.4T-A95B with ~700K tokens per rollout, QwenGyre lifts NL2RepoBench from 52.5% to 58.5% in 48 steps, cutting end-to-end training time by ~44% vs Async.
🔗 Read the paper:
arxiv.org/abs/2609.33848
 Qwen
@Alibaba_Qwen
QwenGyre addresses two challenges of XLong-horizon agentic RL.
 Qwen
@Alibaba_Qwen
🚀 Meet Qwen-Image-2.1-Turbo — create and edit images in just 8 denoising steps! Open weights now available!
Built on Qwen-Image-2.1, Turbo is an accelerated checkpoint on the same 7B visual generation architecture.
Fewer steps does not mean lower quality: it still generates strong 2K images from text, and supports continued creation through natural-language edits, from adding accessories to changing a scene.
Start directly with Diffusers: load QwenImage21Pipeline and the checkpoint’s recommended 8-step sampling schedule is ready to go.
🌐 Prefer an API? Qwen-Image-2.1 Pro and Turbo APIs are now officially live. Choose a hosted API for your application, or use the Turbo weights in your own workflow.
🤖 ModelScope:
modelscope.cn/models/Qwen/Qwen-Image-2.1-Turbo
🤗 Hugging Face:
huggingface.co/Qwen/Qwen-Image-2.1-Turbo
🔗 Pro API:
modelstudio.console.alibabacloud.com/ap-southeast-1/model…
🔗 Turbo API:
modelstudio.console.alibabacloud.com/ap-southeast-1/model…
What will you create with 8 steps? Share your results with us!
Qwen
@Alibaba_Qwen
Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast: A lightweight 7B architecture that outperforms most closed-source models, with drastically accelerated inference for multi-image inputs.
- Native transparency: Natively generates and edits RGBA layers, enabling seamless compositing and text editing within transparent images.
- Versatile, high-fidelity editing: Supports up to 10 reference images and precise local control while preserving strict fidelity for portraits and products.
- Broad coverage & stunning aesthetics: Excels at panoramas, infographics, and virtual try-ons, delivering realistic textures and elegant typography.
Start to create your next masterpiece with Qwen-Image-2.1! 🖼️
- Blog: qwen.ai/blog?id=qwen-image-2.1
- GitHub: github.com/QwenLM/Qwen-Image-2.1
- Model Scope: www.modelscope.cn/models/Qwen/Qwen-Image-2.1
- Hugging Face: huggingface.co/Qwen/Qwen-Image-2.1
 Qwen
@Alibaba_Qwen
Pics:


 Qwen
@Alibaba_Qwen
Edit:


 Qwen
@Alibaba_Qwen
A week of free access to Qwen3.8-Max, Qwen3.8-Flash, and Wan3.0 on @gmi_cloudis live. Explore what you can build with us now. 🙌
 GMI Cloud
@gmi_cloud
We're extending FREE Qwen 3.8 Max + Flash for 7 more days!
And we've increased rate limits across all 3 models.
Built something with Qwen or Wan? Show us what you've got!
Tag us and @Alibaba_Qwen or @Alibaba_Wan. We'll pick 3 winners based on:
🏆 Most creative
🏆 Most challenging
🏆 Most effort put in
Each winner gets $200 cash + $200 in GMI credits!
Qwen
@Alibaba_Qwen
Thanks for the support! @gmi_cloud
Qwen
@Alibaba_Qwen
Qwen3.8-27B is now accessible via @nebiustf. Whether you are building agents or doing deep research, this 27B dense model is ready for your multi-step workflows! 🥳
 Nebius Token Factory
@nebiustf
Qwen3.8-27B is now live on Nebius Token Factory.
A compact 27B dense model for coding, research, and agent workflows, with a focus on planning and completing tasks across multiple steps.
Start building: tokenfactory.nebius.com/endpoints?modals=endpoint-details…
 Qwen
@Alibaba_Qwen
Introducing Qwen Intelligence, bringing personal intelligence within everyone's reach. 📱✨
It launches with three SOTA agents: 🥳
- Mobile Planner Agent: plans, decomposes & orchestrates complex tasks. #1 on MobilePA-Bench, MobilePA-Bench Business & Memory.
- Mobile-Use Agent: gets things done, API-first with GUI fallback. MobileWorld 82.1, MobileWorld-Real 92.2, AndroidDaily 97.2, 90% end-to-end success rate.
- Mobile Creative Agent: turns one sentence into ready-to-use creations. Image generated in 3s, about 2x faster than leading peers.
We're also opening up our benchmark suite: MobilePA-Bench, MobileWorld, MobileWorld-Real, and MobileWorld-Safety, covering planning, cross-app execution, real-device performance and safety.
🔗 Learn more about the agents:
- Qwen Intelligence official website: www.qwenintelligence.com
- Mobile Planner Agent: github.com/Tongyi-MAI/Qwen-Planner-Agent
- Mobile-Use Agent: tongyi-mai.github.io/Qwen-UI-Agent/
- Mobile Creative Agent: arxiv.org/abs/2608.16887
🔗 Explore our open benchmark suite:
- MobilePA-Bench: tongyi-mai.github.io/MobilePA-Bench/
- MobileWorld (GitHub): github.com/Tongyi-MAI/MobileWorld
- Leaderboard: tongyi-mai.github.io/MobileWorld/
 Qwen
@Alibaba_Qwen
Performance of Mobile Creative Agent:

 Qwen
@Alibaba_Qwen
Benchmark suite:
 Qwen
@Alibaba_Qwen
⚡ Meet Qwen-Audio-3.1! ASR, TTS & Realtime are fully upgraded, joined by two new models: TTS-Next for audio creation and ASR-Next for audio understanding.
Five models, one complete audio stack: understanding, generation, interaction & creation.
Plus big price cuts across the lineup: TTS ~70% off, Realtime ~85% off, and ASR up to 95% off.
Highlights: 🥳
- ASR: stronger multilingual & dialect recognition, plus native polishing that auto-removes fillers & repetitions for cleaner, more logical transcripts.
- ASR-Next: supports multi-speaker ASR with speaker labels, timestamps & aligned transcripts, and understands emotions, ambient & machine sounds for sound captioning, event localization, audio QA & reasoning.
- TTS: multilingual & dialect synthesis with natural cross-lingual voice transfer; control emotion, speed & style via simple instructions.
- TTS-Next: unified LM + diffusion framework generating voice, sound effects & background audio in one pass for audiobooks, podcasts, games & ads.
- Realtime: speak & listen at once with anytime interruption, just like a real call; it even slows down and responds empathetically when it senses a low mood.
Unlock the full potential of Qwen-Audio-3.1! 👇
- Blog: fun-resource-shanghai.oss-cn-shanghai.aliyuncs.com/cuijia…
- Qwen-Audio-3.1-ASR:
www.qwencloud.com/models/qwen-audio-3.1-asr-flash-filetrans
- Qwen-Audio-3.1-Realtime:
www.qwencloud.com/models/qwen-audio-3.1-realtime-plus
- More APIs: coming soon @qwen_cloud
 Qwen
@Alibaba_Qwen
Thanks @arena for the recognition! 🏆 Qwen-Image-2.1 is now the #1 open-source model in both the Image Edit and Text-to-Image Arenas. Try it now and show us what you create! 🎨
Arena.ai
@arena
Qwen-Image-2.1 by @Alibaba_Qwen just landed as the #1 open source model in the Image Edit Arena and Text-to-Image Arena!
With 1367 pts in the Image Edit Arena, Qwen-Image-2.1 took the #1 spot among open. It landed #16 overall, just 3 pts from GPT-Image-1.5-high-fidelity at #15.
See the leaderboard for the Text-to-Image arena below.
Congrats to the @Alibaba_Qwen team on this contribution to the open source ecosystem!
 Qwen
@Alibaba_Qwen
Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast: A lightweight 7B architecture that outperforms most closed-source models, with drastically accelerated inference for multi-image inputs.
- Native transparency: Natively generates and edits RGBA layers, enabling seamless compositing and text editing within transparent images.
- Versatile, high-fidelity editing: Supports up to 10 reference images and precise local control while preserving strict fidelity for portraits and products.
- Broad coverage & stunning aesthetics: Excels at panoramas, infographics, and virtual try-ons, delivering realistic textures and elegant typography.
Start to create your next masterpiece with Qwen-Image-2.1! 🖼️
- Blog: qwen.ai/blog?id=qwen-image-2.1
- GitHub: github.com/QwenLM/Qwen-Image-2.1
- Model Scope: www.modelscope.cn/models/Qwen/Qwen-Image-2.1
- Hugging Face: huggingface.co/Qwen/Qwen-Image-2.1
Qwen
@Alibaba_Qwen
Day-0 OpenVINO support from @inteldevs! 🥳 Qwen-Image-2.1 is ready to run optimized on Intel hardware. One open-weight checkpoint for both generation and editing. 👇
 Intel Devs
@inteldevs
We're excited to offer Day0 OpenVINO support for Qwen-Image-2.1
Read more about what you can accomplish here: medium.com/openvino-toolkit/generate-edit-create-qwen-ima…
Qwen
@Alibaba_Qwen
Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast: A lightweight 7B architecture that outperforms most closed-source models, with drastically accelerated inference for multi-image inputs.
- Native transparency: Natively generates and edits RGBA layers, enabling seamless compositing and text editing within transparent images.
- Versatile, high-fidelity editing: Supports up to 10 reference images and precise local control while preserving strict fidelity for portraits and products.
- Broad coverage & stunning aesthetics: Excels at panoramas, infographics, and virtual try-ons, delivering realistic textures and elegant typography.
Start to create your next masterpiece with Qwen-Image-2.1! 🖼️
- Blog: qwen.ai/blog?id=qwen-image-2.1
- GitHub: github.com/QwenLM/Qwen-Image-2.1
- Model Scope: www.modelscope.cn/models/Qwen/Qwen-Image-2.1
- Hugging Face: huggingface.co/Qwen/Qwen-Image-2.1
Qwen
@Alibaba_Qwen
Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast: A lightweight 7B architecture that outperforms most closed-source models, with drastically accelerated inference for multi-image inputs.
- Native transparency: Natively generates and edits RGBA layers, enabling seamless compositing and text editing within transparent images.
- Versatile, high-fidelity editing: Supports up to 10 reference images and precise local control while preserving strict fidelity for portraits and products.
- Broad coverage & stunning aesthetics: Excels at panoramas, infographics, and virtual try-ons, delivering realistic textures and elegant typography.
Start to create your next masterpiece with Qwen-Image-2.1! 🖼️
- Blog: qwen.ai/blog?id=qwen-image-2.1
- GitHub: github.com/QwenLM/Qwen-Image-2.1
- Model Scope: www.modelscope.cn/models/Qwen/Qwen-Image-2.1
- Hugging Face: huggingface.co/Qwen/Qwen-Image-2.1
Qwen
@Alibaba_Qwen
Qwen-Image-2.1 supports a variety of editing tasks while balancing performance across them. For example, given a three-view character reference, the model generates a complete storyboard.

 Qwen
@Alibaba_Qwen
Qwen-Image-2.1 also improves visual quality over its predecessor, particularly in the aesthetics of text and portraits. Below are several examples of text rendering.

 Qwen
@Alibaba_Qwen
Hi there, thanks for your question! 👋 Just a quick clarification: Outputs are not part of the licensed Materials. Users retain the rights to images and other content they generate using the model.
Qwen
@Alibaba_Qwen
Thanks @sgl_project for the day-0 support! 🙌 SGLang-Diffusion now serves Qwen-Image-2.1: text-to-image generation, multi-image editing, and transparent RGBA output. Try it out! 🎨
 SGLang
@sgl_project
Day-0 support for @Alibaba_Qwen’s Qwen-Image 2.1 is here in SGLang-Diffusion!
🖥️ Native precision on a single RTX 4090 24GB with CPU offload
- 1024×1024 generation in 18.7s and image editing in 21.7s with 22.7 GiB peak GPU memory during requests. - On an RTX PRO 6000 96GB: 8.0s generation and 9.6s editing.
🎨 Text-to-image, multi-image editing, and transparent RGBA output—all with one checkpoint.
⚡ Native inference with TP/SP, LoRA, and OpenAI-compatible APIs.
40 denoising steps, one image per request, warmed HTTP latency including PNG output. No quantization.
Cookbook and GPU-specific commands below 👇
Qwen
@Alibaba_Qwen
Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast: A lightweight 7B architecture that outperforms most closed-source models, with drastically accelerated inference for multi-image inputs.
- Native transparency: Natively generates and edits RGBA layers, enabling seamless compositing and text editing within transparent images.
- Versatile, high-fidelity editing: Supports up to 10 reference images and precise local control while preserving strict fidelity for portraits and products.
- Broad coverage & stunning aesthetics: Excels at panoramas, infographics, and virtual try-ons, delivering realistic textures and elegant typography.
Start to create your next masterpiece with Qwen-Image-2.1! 🖼️
- Blog: qwen.ai/blog?id=qwen-image-2.1
- GitHub: github.com/QwenLM/Qwen-Image-2.1
- Model Scope: www.modelscope.cn/models/Qwen/Qwen-Image-2.1
- Hugging Face: huggingface.co/Qwen/Qwen-Image-2.1
Qwen
@Alibaba_Qwen
Qwen-Image-2.1 × @HuggingApps: live demo on Spaces! 🖼 One single checkpoint for generation and editing. Try it in your browser, no setup needed. 👇
 Hugging Apps
@HuggingApps
Qwen Image 2.1 is here! 🖼️
A 7B params native image generation and editing model, with up to 10 image references
The model comes with it's own prompt enhancement LLMs, integrated with diffusers 🧨 and ComfyUI
▶️ on Spaces huggingface.co/spaces/hugging-apps/qwen-image-2-1
Qwen
@Alibaba_Qwen
Qwen-Image-2.1 is now supported in ComfyUI! Try it now and share your creations! 🖼️
 ComfyUI
@ComfyUI
Qwen-Image-2.1 is now supported in ComfyUI!
Open weights. One 7B checkpoint that generates and edits.
→ Image generation at native 2K
→ Instruction editing from up to 10 reference images in a single pass
→ RGBA output, alpha included
Qwen
@Alibaba_Qwen
Thanks @vllm_project for the day-0 support! 🙌 Generate, edit, transparent output — one model, ready to serve. Details 👇
 vLLM
@vllm_project
Qwen-Image-2.1 from @Alibaba_Qwen has day-0 support in vLLM-Omni. 🎉
Generate, edit, and create transparent images with one model: a 7.1B DiT paired with Qwen3-VL-8B.
Setup and supported combinations 👇
recipes.vllm.ai/Qwen/Qwen-Image-2.1
 Qwen
@Alibaba_Qwen
Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast: A lightweight 7B architecture that outperforms most closed-source models, with drastically accelerated inference for multi-image inputs.
- Native transparency: Natively generates and edits RGBA layers, enabling seamless compositing and text editing within transparent images.
- Versatile, high-fidelity editing: Supports up to 10 reference images and precise local control while preserving strict fidelity for portraits and products.
- Broad coverage & stunning aesthetics: Excels at panoramas, infographics, and virtual try-ons, delivering realistic textures and elegant typography.
Start to create your next masterpiece with Qwen-Image-2.1! 🖼️
- Blog: qwen.ai/blog?id=qwen-image-2.1
- GitHub: github.com/QwenLM/Qwen-Image-2.1
- Model Scope: www.modelscope.cn/models/Qwen/Qwen-Image-2.1
- Hugging Face: huggingface.co/Qwen/Qwen-Image-2.1
Qwen
@Alibaba_Qwen
A great example of practical AI solving real-world problems! Faster than ever. Thanks for building with Qwen. @cerebras Try it out for yourself! 🏠
 Cerebras
@cerebras
We built Money Agent, a personal finance assistant powered by @Alibaba_Qwen 3.8 27B on Cerebras.
Now you can turn a home-buying question into a real-time conversation, then into a financial goal, faster.
Qwen
@Alibaba_Qwen
Meet Qwen3.8-LiveTranslate, Qwen's next-generation real-time simultaneous interpretation model! 📢
Built on an Interleave architecture, it improves faithfulness, fluency, and conciseness while reducing average lagging (LAAL) from 2.8s to 2.3s across 60 languages.
New capabilities: 🙌
- Real-time speaker diarization — distinguishes speakers in multi-party speech and preserves each speaker's voice through more stable voice cloning.
- Synchronized bilingual display — source and translation on screen together.
- Long-context disambiguation — leverages conversation history to clarify names and terminology for consistent translations.
Let's try Qwen3.8-LiveTranslate! 🥳
- Blog: qwen.ai/blog?id=qwen3.8-livetranslate
- QwenCloud: www.qwencloud.com/models/qwen3.8-livetranslate-flash-real…
 Qwen
@Alibaba_Qwen
Performance:
 Qwen
@Alibaba_Qwen
Cases and more details:
Qwen
@Alibaba_Qwen
🚀 Meet Qwen3.8-Omni-Flash, Qwen's first omni-modal model built around agentic capabilities!
Native audio-video understanding, reasoning, and tool use come together in one model: understand the content, plan the task, execute with tools, and deliver the result.
Highlights: 🥳
- Audio-video intelligence that gets things done: jointly reason over what's seen and heard, and orchestrate tools across long workflows to auto-edit vlogs, translate short videos, and turn movies into recaps.
- A major leap: approaching Gemini 3.8 Flash in audio-video capabilities; +19.5 points on average in agent performance across WildClawBench-MM & UniClawBench.
- 1M-token context with agentic perception: actively explore long videos and locate key moments with higher accuracy, using 51.8% fewer tokens than static understanding on OmniVideoBench.
Video input costs are reduced by about 89% compared with Qwen3.5-Omni-Plus, making long-form audio-video understanding and agentic workflows more affordable than ever.
To help you build apps around Omni, we're also open-sourcing Qwen-MM-Plugins and Qwen-Live Harness! 🛠️
We can't wait to see what you build with Qwen3.8-Omni-Flash! 👀
- Blog: qwen.ai/blog?id=qwen3.8-omni-flash
- Qwencloud: www.qwencloud.com/models/qwen3.8-omni-flash
- Qwen Studio: chat.qwen.ai
- API: www.alibabacloud.com/help/en/model-studio/qwen-omni
- Qwen-MM-Plugins: github.com/QwenLM/Qwen-MM-Plugins
- Qwen-Live Harness: coming soon
github.com/QwenLM/Qwen-Live-Harness
 Qwen
@Alibaba_Qwen
Performance and price:
 Qwen
@Alibaba_Qwen
Cases and more details:
Qwen
@Alibaba_Qwen
Fast meets open. 🚀 Qwen3.8-27B is now running on @cerebras with rapid inference. Try it now!
Cerebras
@cerebras
Qwen3.8-27B is now live at Cerebras speed.
The dense, open-weight model from @Alibaba_Qwen scores 34 on the Artificial Analysis Intelligence Index—making it comparable to models such as GPT-5.6 Luna, DeepseekV4 Pro, and Claude Sonnet 4.6.
Qwen
@Alibaba_Qwen
Come build with Qwen🫴🫴
 QwenCloud
@qwen_cloud
Qwen is up. Come say hi😃
www.qwencloud.com
Qwen
@Alibaba_Qwen
Meet E-Commerce Bench, a new benchmark for long-horizon autonomous business operations. 🚀
Agents start with ¥100,000 to run online stores for 365 days, handling sourcing, negotiation, pricing, promotions, inventory and cash flow, in a market driven by real e-commerce data.
What's inside: 👀
- Real economics: 6886 products, 576 suppliers (152 fraudsters), 600-minute workdays, storage fees, returns and reputation.
- Long-horizon learning: almost no model learns to buy cheaper or improve its strategies over a full year of operation.
- Seven-axis evaluation: beyond year-end assets, we score six more dimensions, revealing that no single model dominates across the board.
Learn more about E-Commerce Bench: 👇
- Blog: qwen.ai/blog?id=e-commerce-bench
- Paper: arxiv.org/abs/2608.30730
- Project: ecbench.github.io
- Code: github.com/QwenLM/E-CommerceBench


 Qwen
@Alibaba_Qwen
🏆 #1 overall on Code Arena, and top of the Pareto frontier at $5/MToken. Thanks! @arena
Give Qwen3.8-Max-0902 a spin on QwenCloud.🥳
Arena.ai
@arena
Qwen3.8-Max-0902 by @Alibaba_Qwen just debuted at #1 overall in Code Arena: WebDev with 1,691 pts, and became the highest-scoring model on the Pareto frontier at a blended $5/MToken!
On the updated frontier, Qwen3.8-Max-0902 sits above HY4 Preview (1,629 pts at $2.08/MToken) and Qwen3.8-Flash-Next (1,620 pts at $0.39/MToken).
With this release, three models at the top of the overall leaderboard have moved off the Pareto frontier despite remaining #2–#4 overall:
- Claude Opus 5 (Max): #2, 1,688 pts, $20/MToken
- Kimi K3 (Max): #3, 1,674 pts, $12/MToken
- Qwen3.8 (Max): #4, 1,669 pts, $5/MToken
Congrats to the @Alibaba_Qwen team on the release!
 Qwen
@Alibaba_Qwen
🚀Qwen3.8-Max just got upgraded. Meet Qwen3.8-Max-0902!
2.4T parameters. 1M context tokens. Built for real world complexity.
Further post trained on Coding & Cowork, Qwen3.8-Max-0902 now delivers stronger performance across complex enterprise tasks, scientific research, and long horizon workflows.
💰Pricing per 1M tokens:
$2 input, $6 output.
$0.17 explicit cache hit, $0.25 implicit cache hit.
Now live via API on QwenCloud. Come try it! 🙌
API: www.qwencloud.com/models/qwen3.8-max-0902

 Qwen
@Alibaba_Qwen
🏆 #1 on CodeArena: WebDev leaderboard.
Qwen3.8-Max-0902 jumps from 1669 to 1691, setting a new record for agentic coding (WebDev) workflows, with standout strength in multistep reasoning, tool use, and full app generation.
Thanks for the recognition! @arena
Arena.ai
@arena
Big news: Qwen3.8-Max-0902 by @Alibaba_Qwen just debuted at #1 overall in the Code Arena: WebDev with 1691 pts!
It scores 3 pts above Claude Opus 5 (Max), 17 pts above Kimi K3 (Max), and 22 pts above the previous Qwen3.8-Max.
Priced at a blended $5/MToken, Qwen3.8-Max-0902 also claims the highest-scoring position on the Pareto frontier! Stay tuned for a closer look at its Pareto positioning, and for Agent Arena scores coming soon.
Its strength carries across every Code Arena: WebDev category:
- #1 in Data & Analytics and Consumer Product
- #2 in Brand & Marketing, Gaming, and Simulations
- #3 in Content Creation Tools and Reference-Based Design
Congrats to the @Alibaba_Qwen team on this huge update!
 Qwen
@Alibaba_Qwen
🚀Qwen3.8-Max just got upgraded. Meet Qwen3.8-Max-0902!
2.4T parameters. 1M context tokens. Built for real world complexity.
Further post trained on Coding & Cowork, Qwen3.8-Max-0902 now delivers stronger performance across complex enterprise tasks, scientific research, and long horizon workflows.
💰Pricing per 1M tokens:
$2 input, $6 output.
$0.17 explicit cache hit, $0.25 implicit cache hit.
Now live via API on QwenCloud. Come try it! 🙌
API: www.qwencloud.com/models/qwen3.8-max-0902
Qwen
@Alibaba_Qwen
🚀Qwen3.8-Max just got upgraded. Meet Qwen3.8-Max-0902!
2.4T parameters. 1M context tokens. Built for real world complexity.
Further post trained on Coding & Cowork, Qwen3.8-Max-0902 now delivers stronger performance across complex enterprise tasks, scientific research, and long horizon workflows.
💰Pricing per 1M tokens:
$2 input, $6 output.
$0.17 explicit cache hit, $0.25 implicit cache hit.
Now live via API on QwenCloud. Come try it! 🙌
API: www.qwencloud.com/models/qwen3.8-max-0902
Qwen
@Alibaba_Qwen
CommerceAgentBench starts with real commercial demand, and Qwen3.8-Max delivers the strongest overall performance among open-weight models. Let's test Qwen on your real-world workflows! 🔥
 Accio
@Accio_official
Most AI benchmarks test what a model says. In commerce, the hard part was never the answer. It’s execution.
We’ve open-sourced CommerceAgentBench: a benchmark for real commerce operations.
Early results are humbling. The best overall completion rate is ~62%.
Qwen @Alibaba_Qwen delivered the strongest overall performance across complex commercial workflows among the open-weight models evaluated.
Explore the benchmark and full results ↓
github.com/Accio-org/CommerceAgentBench
 Qwen
@Alibaba_Qwen
125B/6B, 1M context, multimodal, now in OpenCode Go. ⚡ Happy coding with Qwen3.8-Flash!
OpenCode
@opencode
Qwen3.8-Flash is now available in OpenCode Go
125B/6B · 1M context · multimodal
Qwen
@Alibaba_Qwen
Qwen3.8-Flash on @qwen_cloud: $0.15/1M input tokens, $0.47/1M output tokens, and just $0.016/1M on cache hits. ☁️ Come give it a try! 👇
QwenCloud
@qwen_cloud
Qwen3.8-Flash API is live on QwenCloud. 262K native context, extensible to 1M, and priced to scale.
About Price⬇️
Input: $0.15 / 1M tokens
Output: $0.47 / 1M tokens
Cache hit: $0.016 / 1M tokens
Get your API key and start building:
www.qwencloud.com/models/qwen3.8-flash
#qwencloud #qwen
 Qwen
@Alibaba_Qwen
Qwen3.8-Flash is now live on @OpenRouter! ⚡ Coding assistants, agentic workflows, long-video understanding, all one API call away.
OpenRouter
@OpenRouter
Qwen3.8 Flash from @Alibaba_Qwen is now live on OpenRouter.
A multimodal reasoning model for coding assistants, agentic workflows, visual understanding, codebase and document analysis, desktop interaction, charts, and long video.
openrouter.ai/qwen/qwen3.8-flash
Qwen
@Alibaba_Qwen
Fantastic! 🥳 Thanks @lightseekorg for the TokenSpeed day-0 support. The new architecture is fully covered, from GDN + QSA to N-gram embedding with FP8.
LightSeek Foundation
@lightseekorg
TokenSpeed Day 0 Support for @Alibaba_Qwen 3.8 Flash Next.
🔹GDN + Qwen Sparse Attention hybrid architecture
🔹Gated residual connections
🔹N-gram embedding
For N-gram embedding, TokenSpeed also supports FP8 precision.
As a preview for Qwen 4, we will continue optimizing beyond Day 0.
 Qwen
@Alibaba_Qwen
Thank you @NVIDIAAI for the day-0 support! 🙌
Developers can finetune the model for domain-specific use cases using NVIDIA NeMo AutoModel:
github.com/NVIDIA-NeMo/Automodel/tree/main/docs/model-cov…
 NVIDIA AI
@NVIDIAAI
Congrats to @Alibaba_Qwen on releasing Qwen3.8-Flash-Next, an experimental open-weight model that previews the Qwen4 architecture.
We’ve got Day 0 support to fine-tune with NVIDIA NeMo AutoModel and NeMo RL, plus recipes to run it with @sgl_project, @vllm_project and @lightseekorg TokenSpeed.
Get started: nvda.ws/4wV7yXp
Qwen
@Alibaba_Qwen
⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: qwen.ai/blog?id=qwen3.8-flash-next
- Technical Report: github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_repor…
- Hugging Face: huggingface.co/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8-Flash…
- ModelScope: modelscope.cn/models/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8…
 Qwen
@Alibaba_Qwen
A high-performance 125B model now running locally on just 75GB RAM! Thank you @UnslothAI for the day-0 support.🥳
 Unsloth AI
@UnslothAI
Qwen3.8-Flash can now be run locally! 🔥
The 125B MoE model outperforms Claude-Opus-4.6 (Max).
Run on 75GB RAM via Unsloth GGUFs.
Qwen3.8-Flash-Next enables CPU RAM / unified mem setups to deliver near VRAM speeds.
Guide: unsloth.ai/docs/models/qwen3.8-next
GGUF: huggingface.co/unsloth/Qwen3.8-Flash-Next-GGUF
 Qwen
@Alibaba_Qwen
⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: qwen.ai/blog?id=qwen3.8-flash-next
- Technical Report: github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_repor…
- Hugging Face: huggingface.co/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8-Flash…
- ModelScope: modelscope.cn/models/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8…
Qwen
@Alibaba_Qwen
API is live on QwenCloud: www.qwencloud.com/models/qwen3.8-flash
🙌Let's build something!
Qwen
@Alibaba_Qwen
⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: qwen.ai/blog?id=qwen3.8-flash-next
- Technical Report: github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_repor…
- Hugging Face: huggingface.co/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8-Flash…
- ModelScope: modelscope.cn/models/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8…
Qwen
@Alibaba_Qwen
Big thanks to @sgl_project for the day-0 support! 🙌 Qwen3.8-Flash-Next is ready to deploy with SGLang today.
SGLang
@sgl_project
Congrats to @Alibaba_Qwen on launching Qwen3.8-Flash! SGLang is proud to be a day-0 partner supporting the new architecture preview for Qwen4.
It's a 125B main model with 51B of N-gram embeddings and 6B activated per token.
The 51B N-gram embeddings scale model capacity with almost no extra compute per token, and can sit in host memory with async prefetch instead of occupying GPU memory.
The GDN + QSA hybrid attention gives you efficient memory and precise retrieval at the same time on long-horizon tasks, while Gated Residual gives the model 4 lanes instead of 1 to pass information between layers. And it's trained with Muon!
We're excited for what's next with Qwen4, and we already have plenty of ideas for how to use the N-gram embeddings in new deployment setups. Stay tuned!
Blog and cookbook in the comments👇
 Qwen
@Alibaba_Qwen
⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: qwen.ai/blog?id=qwen3.8-flash-next
- Technical Report: github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_repor…
- Hugging Face: huggingface.co/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8-Flash…
- ModelScope: modelscope.cn/models/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8…
Qwen
@Alibaba_Qwen
Amazing! 🥳 Thanks @vllm_project for getting Qwen3.8-Flash-Next running on NVIDIA and AMD from day 0.
vLLM
@vllm_project
Qwen3.8-Flash-Next from @Alibaba_Qwen has day-0 support in vLLM, verified on NVIDIA and AMD GPUs. 🎉
Ultra-sparse multimodal MoE: 125B params, 6B active, 262K native, 1M via YaRN. On top of those sits a separate 51B N-gram table you can offload.
Most of it will look familiar. The Gated DeltaNet layers reuse the KV path vLLM has had since Qwen3-Next: only a quarter of the layers hold a growing KV cache. Keep the 51B table in host RAM instead of HBM with VLLM_PLE_CPU_OFFLOAD=1. Qwen Sparse Attention is where the new engine work went. For now the model runs from vllm/vllm-openai:qwen38-flash-next.
Thanks to @Alibaba_Qwen for the weights, and for opening them this early! 🙌
🔗 recipes.vllm.ai/Qwen/Qwen3.8-Flash-Next
 Qwen
@Alibaba_Qwen
⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: qwen.ai/blog?id=qwen3.8-flash-next
- Technical Report: github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_repor…
- Hugging Face: huggingface.co/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8-Flash…
- ModelScope: modelscope.cn/models/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8…
Qwen
@Alibaba_Qwen
⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: qwen.ai/blog?id=qwen3.8-flash-next
- Technical Report: github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_repor…
- Hugging Face: huggingface.co/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8-Flash…
- ModelScope: modelscope.cn/models/Qwen/Qwen3.8-Flash-Next?file=Qwen3.8…
Qwen
@Alibaba_Qwen
At a 1M-token context length, QSA’s attention kernel is up to 7.6× faster in prefill and 4.9× faster in decode. With a 90% prefix-cache hit rate, Qwen3.8-Flash-Next delivers 8.6× the prefill throughput of Qwen3.7-Plus.
 Qwen
@Alibaba_Qwen
With only 6B active parameters, Qwen3.8-Flash-Next-Base tops 8 of 14 benchmarks, including MMLU-Pro, SuperGPQA, BBH and GSM8K. And it remains competitive with Qwen3.7-Plus-Base on the rest. Its 51B N-gram embedding parameters use deterministic lookups, adding no per-token matrix-multiplication cost.
 Qwen
@Alibaba_Qwen
#1 among open models in the Image-to-WebDev Arena, #7 overall. 🚀 Thanks for the recognition! @arena Just 27B parameters, on par with models 100x its size. Now, can you guess what surprise we're dropping tonight? 👀
Arena.ai
@arena
Big news: Qwen3.8-27B by @Alibaba_Qwen is now #1 among open models in the Image-to-WebDev Arena (#7 overall)!
Priced at $0.40/$3 per M input/output tokens, it has shifted the Pareto frontier (more info below).
Qwen3.8-27B has 1574 pts with 27B parameters, achieving performance on par with Kimi K3 (Max) at 2.8T parameters!
Congrats to @Alibaba_Qwen on this contribution to the open model ecosystem!
 Qwen
@Alibaba_Qwen
Open models, open science. Qwen keeps growing steadily, and we'll always be right here with the research community.🙌 Thanks for the deep dive! @natolambert
 Nathan Lambert
@natolambert
Over the weekend I had Codex parse 500K arXiv AI/ML papers since ChatGPT to understand which open models are used for research.
In 2024, ~30% of papers mentioned an American open model and only 10% a Chinese model.
Today, ~40% of papers mention a Chinese (open) LLM, and only 25-30% an American one. Chinese models are the default for research. Chinese mentions are still growing while American open models are stagnating.
When looking at this data it's important to remember that papers substantially lag model releases, as research takes a long time. Qwen's steady growth is reflective of this, but so is Llama's lasting power.
Some more observations:
1. Qwen has been steadily growing, and today 1/3 of papers which mention any LLM mention qwen. OpenAI's closed models are the highest overall, at ~37%.
2. Llama peaked around April of 2025 at 30% of papers which mention any LLM (including ChatGPT etc). Llama 4 was released at about the same time, and Llama has been declining since.
3. Gemini and Claude are less common than the leading open models, mentioned in 10-15% of papers puts them behind all of Qwen, Llama, and DeepSeek. Open models should be and are the foundations of open research.
The % of papers mentioning any LLM have been steadily climbing since 2023.
| Year | January | April | July | October |
| 2023 | 10.43% | 15.39% | 18.69% | 32.18% |
| 2024 | 29.70% | 33.93% | 35.70% | 44.25% |
| 2025 | 39.23% | 45.28% | 44.94% | 53.52% |
| 2026 | 55.49% | 57.26% | 53.14% | TBD
Now over 50% of AI papers, from 10% in 2023.
Other notes:
- Gemma and Mistral hover around 5-10%.
- Our beloved fully-open Olmo models have been ~1% since the first release in Jan. 2024.
- DeepSeek has a clear jump after R1 in Jan. 2025
- Data derived from the most popular ML arXiv categories: cs. AI, cs. CL, cs. CV, cs. LG, stat. ML
Just like our downloads and derivative model data, this is updated daily on the Interconnects Open Model Dashboard.

 Qwen
@Alibaba_Qwen
Qwen3.8-27B at #9 overall on Code Arena, the only model in its size class in the top 10.😎 Small but mighty. Thanks for the recognition! @arena
Arena.ai
@arena
Exciting news: Qwen3.8-27B by @Alibaba_Qwen just landed in Code Arena: WebDev at #9 overall with 1595 pts. It is the only model in its size class in the top 10, and also reshapes the Pareto Frontier!
It is only 6 ranks behind the much larger Qwen3.8-Max. For scale: Gemma 4-31B which was released back in April sits at #80.
Congrats to @Alibaba_Qwen on the release!
See thread for more highlights on Qwen3.8-27B.
 Qwen
@Alibaba_Qwen
Fresh recipes just dropped! ⚡ NVFP4 + DFlash2 for Qwen3.8-27B now in the SGLang cookbook. Thanks for the support! @sgl_project
SGLang
@sgl_project
Just pushed DFlash2 (@inco_ai) recipes to the Qwen3.8 27B cookbook⚡️
docs.sglang.io/cookbook/autoregressive/Qwen/Qwen3.8-27B
The community has been seeing great results with NVFP4 + DFlash2, and these recipes should be some very good starting points to play with.
More Qwen3.8 27B updates on the way 🫡
 Qwen
@Alibaba_Qwen
Huge thanks to Unsloth for the great work. This is wonderful news for the community! 🥳Qwen3.8-27B, smaller and sharper than ever. Let's try it! @UnslothAI
Unsloth AI
@UnslothAI
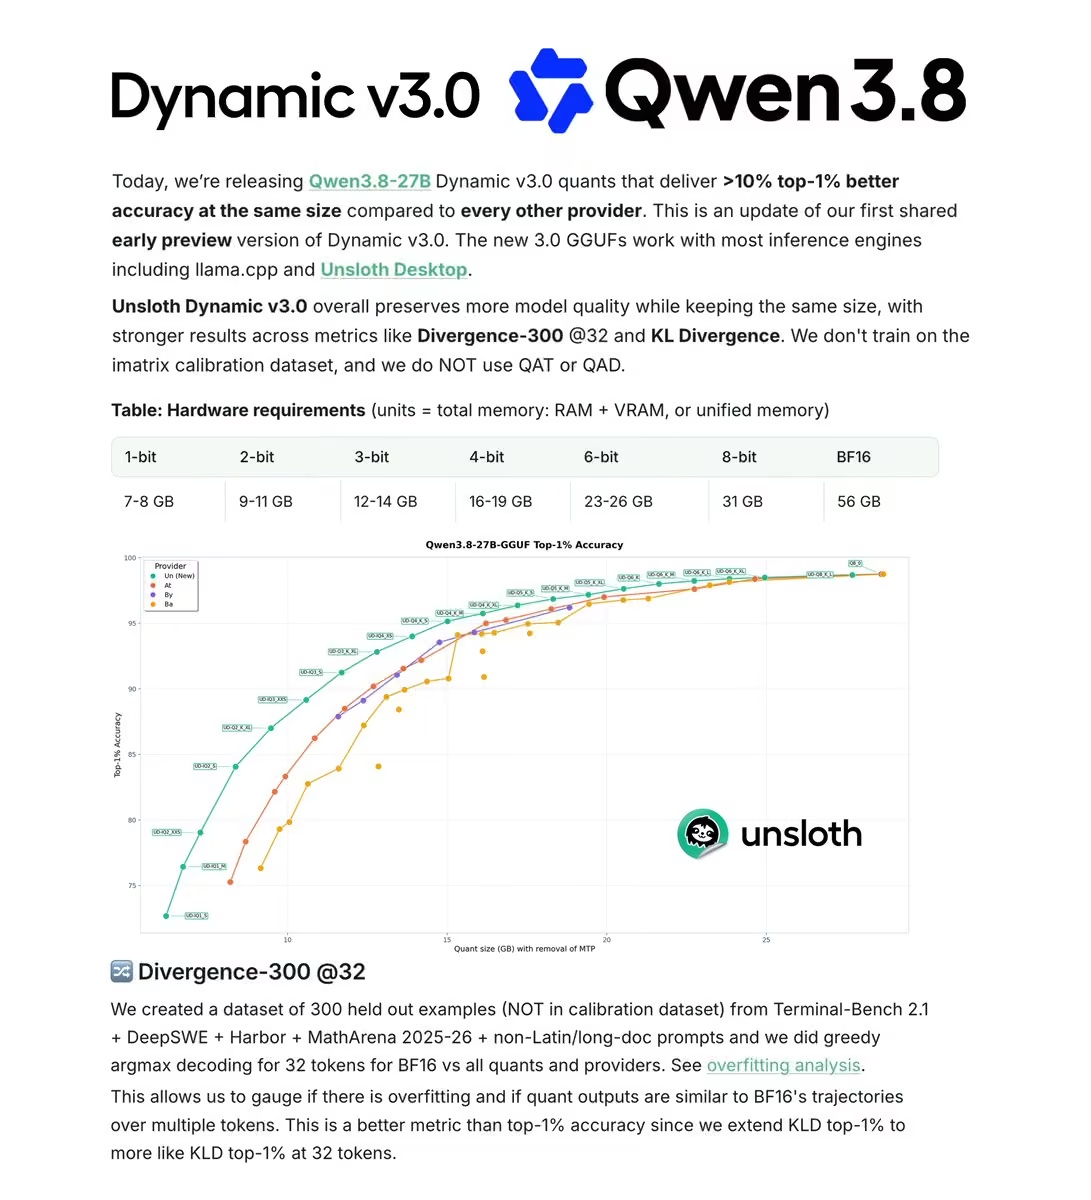
We’re releasing new Qwen3.8-27B GGUFs with 10% higher accuracy.
Unsloth Dynamic V3 outperforms others by >10% on Div-300, KLD & more benchmarks.
We also release 1-bit quants that retain 77% accuracy. Run on 8GB RAM.
Blog: unsloth.ai/docs/basics/dynamic-3.0-ggufs
GGUF: huggingface.co/unsloth/Qwen3.8-27B-GGUF
 Qwen
@Alibaba_Qwen
Great UI starts with good code. Give Qwen3.8-Max a try on Kilo! 👀 @kilocode
Qwen
@Alibaba_Qwen
#1 open-weight model on Harvey's Legal Agent benchmark! 🙌
Strong enough to handle professional tasks. Small enough to run on your local machine.
Qwen3.8-27B is becoming part of your everyday workflows.🧑💻
Qwen
@Alibaba_Qwen
4 days to the top.🏆Thank you to every builder who pushed Qwen3.8-27B to #1 on Cline! @cline
 Cline
@cline
Qwen3.8-27B is now the #1 local model in Cline after just 4 days.
This ends a *4 month* streak by the previous winner Qwen2.5-Coder-7B which has been the top local model since April.
 Cline
@cline
Artificial Analysis Intelligence Index puts Qwen3.8-27B at DeepSeek V4-Pro and GPT 5.6 Luna performance. This is the first time a local model has scored frontier model capability.
We weren’t expecting this pace of local progress anywhere near this soon.
 Qwen
@Alibaba_Qwen
🚀Qwen3.8-27B flies on a laptop, becoming part of our work and daily lives. Thanks for the shoutout! @atomic_chat_hq
 atomic.chat
@atomic_chat_hq
Run Qwen3.8 27B locally via Atomic Chat💥
We released Atomic Dynamic GGUF quants, from 8-bit (28.9 GB) down to 1-bit (8.5 GB), and measured all other Qwen3.8 GGUFs in the community
AD-IQ3_S runs on a 16GB MacBook Air and picks the same next token as the BF16 original 92.4% of the time
 Qwen
@Alibaba_Qwen
We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Qwen/qwen38
- ModelScope:
www.modelscope.cn/collections/Qwen/Qwen38
 Qwen
@Alibaba_Qwen
3000000000 downloads! Can you count the zeros at a glance? 😎 Thank you all for the incredible love. Let's keep growing together! 🌱
 Bloomberg
@business
Alibaba's open-weight models have accumulated more than 3 billion global downloads in the past six months, eclipsing Meta, Alphabet and domestic peers to become the world’s No. 1 artificial-intelligence model www.bloomberg.com/news/articles/2026-08-15/alibaba-ai-mod…
Qwen
@Alibaba_Qwen
Huge thanks to the whole community! Qwen3.8-27B is now the #1 trending model on Hugging Face! 🏆 Try it out and let us know what you think. 🤗

 Julien Chaumond
@julien_c
soon 10k
 Qwen
@Alibaba_Qwen
Laptop-size model, frontier-size leap. 🏃♀️Qwen3.8-27B is live on LM Studio. Try it! @lmstudio
 LM Studio
@lmstudio
Qwen3.8-27B is here! 🚀
It's a leap in capabilities for a laptop size model.
Requires ~17GB to run locally.
Model page: lmstudio.ai/qwen/qwen3.8-27b
 Qwen
@Alibaba_Qwen
We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Qwen/qwen38
- ModelScope:
www.modelscope.cn/collections/Qwen/Qwen38
Qwen
@Alibaba_Qwen
Qwen3.8-27B is now part of your everyday life — from smartphones to vehicles. ⚡️🚀Appreciate your work! @MediaTek
 MediaTek
@MediaTek
Congratulations to the @Alibaba_Qwen on the launch of Qwen 3.8!
MediaTek continues our long-standing collaboration with Qwen, with Day-0 support now available on Dimensity Auto Cockpit C-X1 and the latest Dimensity flagship mobile SoC, bringing smarter and more intuitive on-device AI experiences to more people, from smartphones to vehicles, and helping make agentic AI a seamless part of everyday life.
 Qwen
@Alibaba_Qwen
Ready right now! 😎Incredible to see Qwen3.8-27B fly on RTX Spark. Download, deploy and create somthing new. @NVIDIARTXSpark
 NVIDIA RTX Spark
@NVIDIARTXSpark
Ready to run Qwen3.8 locally? 👀
Qwen3.8-27B packs powerful AI into an open model developers can download, serve locally, and build with on their own terms.
Qwen
@Alibaba_Qwen
We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Qwen/qwen38
- ModelScope:
www.modelscope.cn/collections/Qwen/Qwen38
Qwen
@Alibaba_Qwen
Qwen3.8-27B is available on @ollama !Any harness you run, the model always delivers. Let's code together, and show us what you build.😎
 ollama
@ollama
Qwen 3.8 27B is now available on Ollama.
It's one of the best open models at this size, and made for agentic tasks and professional work.
Try it directly with the apps & harnesses you use:
Claude Code:
ollama launch claude --model qwen3.8
OpenCode:
ollama launch opencode --model qwen3.8
Hermes Agent:
ollama launch hermes --model qwen3.8
Pi:
ollama launch pi --model qwen3.8
We have also optimizations for Apple Silicon!
Try it with the model name: qwen3.8:27b-mlx
 Qwen
@Alibaba_Qwen
Small models, big real-world impact.
Proud to see Qwen leading local inference in the State of Open Models. Enjoy the sunshine from Qwen.☀️ 😎
Appreciate your work! @huggingface
 Hugging Face
@huggingface
The State of Open Models, Summer 2026 ☀️ frontier models are getting larger, but small models still dominate real-world usage. Qwen leads local inference, followed by Gemma. AI agents are becoming a major force on the Hub
Full picture on the blog 🤗
huggingface.co/blog/state-of-open-models-summer-2026
Qwen
@Alibaba_Qwen
Excited to see Qwen3.8 running at scale with TokenSpeed! 🚀
Light on latency, big on speed. Kudos to LightSeek for the fantastic Day-0 support! @lightseekorg
LightSeek Foundation
@lightseekorg
We’re proud to be the Day 0 open-source inference engine partner for @Alibaba_Qwen 3.8.
To serve this 2.4T-parameter model across multi-node @NVIDIAAI Blackwell inference, we optimized DP/EP scaling across nodes, delivering 30%+ faster performance than TP16, plus DSpark speculative decoding with single CUDA graph optimization👇
lightseek.org/blog/tokenspeed-qwen3-8.html


 Qwen
@Alibaba_Qwen
From idea to implementation in one go.🏃♀️ Max-level intelligence, served fresh on Day 0.
Qwen3.8-2.4T-A95B is live on SiliconFlow. Thanks! @SiliconFlowAI
 SiliconFlow
@SiliconFlowAI
🚀 Day-0 Support! @Alibaba_Qwen has open-sourced Qwen3.8-2.4T-A95B — and it’s now live on SiliconFlow.
⚡ With 2.4T parameters and 95B active, Qwen3.8 is built to take a goal and come back with finished work — coding, researching, planning, and executing along the way.
💸 Per 1M tokens:
• Input: $2.00
• Output: $6.00
• Cached input: $0.25
💻 Autonomous coding. 🔬 Deep research. 🤖 End-to-end agent execution.
Built for serious workloads — from idea to implementation in one go.
Time to cook → siliconflow.com 🍳
 Qwen
@Alibaba_Qwen
Max-level intelligence, one API call away. Qwen3.8-2.4T-A95B is now live on DeepInfra, ready for your creative builds. 🥳
Take a deep dive on DeepInfra! @DeepInfra
 DeepInfra
@DeepInfra
New on DeepInfra: Qwen3.8-2.4T-A95B 🚀
@Alibaba_Qwen's latest sparse MoE — 2.4T total params, 95B active, 512 experts. Built for coding, agentic workflows, and complex reasoning, with native 262K context.
Live now at $2.00/M in · $6.00/M out · $0.20/M cached
@Alibaba_Qwen @alibaba_cloud
 Qwen
@Alibaba_Qwen
🎁A gift for developers: Qwen3.8-27B, running locally on AMD from day zero.
Appreciate the work from the AMD team! @AMD
 AMD
@AMD
Qwen3.8 27B brings a new state-of-the-art dense model for local AI development.
⚡ Run it on AMD Ryzen™ AI Max+ processors or single Radeon™ AI PRO R9700 card
⚡ Experience it with @LMStudio
⚡ Turn it into an app with @lemonade_server
Start building with AMD Day 0 support for @Alibaba_Qwen now: www.amd.com/en/blogs/2026/run-qwen-3-8-27b-on-amd-ryzen-a…
 Qwen
@Alibaba_Qwen
27B on 17GB RAM. Are you ready to create something incredible? 😎
Thanks for highlighting it! @UnslothAI
Unsloth AI
@UnslothAI
Qwen3.8-27B can now be run locally! ✨
Run on 17GB RAM via Unsloth Dynamic GGUFs.
Qwen3.8-27B is by far the strongest model for its size. We also uploaded NVFP4 quants.
GGUF: huggingface.co/unsloth/Qwen3.8-27B-GGUF
Guide: unsloth.ai/docs/models/qwen3.8
 Qwen
@Alibaba_Qwen
We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Qwen/qwen38
- ModelScope:
www.modelscope.cn/collections/Qwen/Qwen38
Qwen
@Alibaba_Qwen
Yes, we are back👑, with 206 tok/s on a single RTX 5090!
Amazing Day-0 work from the SGLang team. Give it a try~@sgl_project
SGLang
@sgl_project
The king of small models is back! Qwen3.8-27B from @Alibaba_Qwen is open source, and Day-0 support is live in SGLang:
- 206.1 tok/s decode on a single RTX 5090, with our NVFP4 plus DSpark
- 38.28 tok/s decode on DGX Spark
Qwen3.8-27B raises the bar again for what a small model can do on agentic planning and long-horizon tasks.
Long live the (small model) king! Run it locally with SGLang 👇
Qwen
@Alibaba_Qwen
We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Qwen/qwen38
- ModelScope:
www.modelscope.cn/collections/Qwen/Qwen38
Qwen
@Alibaba_Qwen
One GPU, 1M context, Day-0 ready. Big props to the vLLM team for the seamless integration!👍
Try Qwen3.8-27B on vLLM: @vllm_project
recipes.vllm.ai/Qwen/Qwen3.8-27B
vLLM
@vllm_project
🎉 Qwen3.8-27B is here from @Alibaba_Qwen, and the whole thing fits on a single GPU. Same hybrid backbone as the 2.4T flagship, dense instead of MoE. Day-0 support in vLLM. 🚀
What is in it for serving ✨
- Fits one Blackwell GPU in every precision. Qwen ships BF16 and FP8, the NVFP4 build from @inferact
- 262K native context, stretching to 1M. At that length one GB300 still has room for roughly 6.6M KV tokens. Six full-length sequences in flight, on one GPU
- An MTP draft head rides inside the checkpoint, so speculative decoding needs no separate speculator repo. Acceptance on short prompts measured 92.2% in BF16 and 84.8% in FP8
Verified end-to-end on @NVIDIA GB300: BF16 and FP8 at TP4, NVFP4 at TP1, tool calls working, correct generations at 1M context. Two prerequisites, vLLM nightly and transformers 5.8.0+.
🔗 recipes.vllm.ai/Qwen/Qwen3.8-27B
Qwen
@Alibaba_Qwen
We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Qwen/qwen38
- ModelScope:
www.modelscope.cn/collections/Qwen/Qwen38
Qwen
@Alibaba_Qwen
Qwen3.8-Max is live on DigitalOcean Serverless Inference. Launching side by side with DigitalOcean as our Day 0 launch partner.
Big model. Smooth sailing. Now on DigitalOcean.🌊🏄♀️ @digitalocean

 DigitalOcean
@digitalocean
Now available: @Alibaba_Qwen 3.8-2.4T-A95B from @alibaba_cloud on DigitalOcean Serverless Inference via NVIDIA HGX™ B300 GPUs. 🤖 1M context, built for long-horizon coding. 🔗 do.co/45VBAyZ
One API, usage-based pricing, no infra to manage.
Qwen
@Alibaba_Qwen
Qwen 3.8-Max is live on Modal, with the full 1M context window and a custom DFlash speculator under the hood.
Love seeing our launch partner Modal go all in from Day 0!⚡️
2.4T parameters. 1M context. Somehow, still just a Modal call away. @modal

 Modal
@modal
Qwen3.8-2.4T-A95B by @Alibaba_Qwen and @alibaba_cloud is now available on Modal.
Served with a custom DFlash speculator trained on tool-call-heavy data. Full 1M context window.
 Qwen
@Alibaba_Qwen
Qwen3.8-Max is coming to Nebius Token Factory on Day 0.
Great to kick things off together with Nebius as our Day 0 launch partner, bringing dedicated inference to more users.
Big model, right from the start.🔥@nebiustf
 Nebius Token Factory
@nebiustf
Qwen3.8-2.4T-A95B is going open weight: 2.4T parameters, with 95B active, and Nebius Token Factory is joining as a Day 0 launch partner.
Qwen3.8-2.4T-A95B is coming to Nebius Token Factory Managed Services for dedicated inference.
@Alibaba_Qwen @alibaba_cloud
 Qwen
@Alibaba_Qwen
Qwen3.8-Max is live on Fireworks, ready for agents, heavy coding, and long-context work.
Fireworks is right there with us as a Day 0 launch partner.
What a way to kick things off!It's Day 0, cue the Fireworks! 🎉🎆@FireworksAI_HQ

 Fireworks
@FireworksAI_HQ
Qwen3.8-2.4T-A95B is now live on Fireworks with Day-0 support!
This 2.4T parameter MoE model is built for autonomous agents, heavy coding, large context windows, and is ideal for coding and agentic performance.
Start building today: fireworks.ai/models/fireworks/qwen3p8-max
 Qwen
@Alibaba_Qwen
Qwen3.8-Max is live on Together AI.
Together AI is with us as a Day 0 launch partner, and we couldn’t ask for a better name to share Day 0 with.
2.4T parameters, 95B active, 1M context — all together now. 🧑🤝🧑@togethercompute

 Together AI
@togethercompute
Qwen3.8-2.4T-A95B is live on Together AI.
The Qwen team’s new open-weight MoE packs 2.4T total parameters with 95B active, a 1M context window, and strong coding & agent capabilities.
Start building: www.together.ai/models/qwen3-8-max
Qwen
@Alibaba_Qwen
We promised open weights for Qwen3.8. Now, time to meet them! 🎉
⚡ Qwen3.8-27B:
- A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows.
- 262K native context, easily extendable to 1M tokens via YaRN.
- Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0.
🚀 The open weights for Qwen3.8-2.4T-A95B (Max-level) have also been released recently.
Whether you're shipping lightweight applications with Qwen3.8-27B locally or building agents with Qwen3.8-2.4T-A95B, they're yours now!
Download, deploy, and build something we haven't imagined yet. 👀👇
- Hugging Face:
huggingface.co/collections/Qwen/qwen38
- ModelScope:
www.modelscope.cn/collections/Qwen/Qwen38
Qwen
@Alibaba_Qwen
Performance of Qwen3.8-27B:

 Qwen
@Alibaba_Qwen
Less than 2 hours to say hi👋. It's almost time!
See you soon: 👀
huggingface.co/Qwen/Qwen3.8-27B
 Qwen
@Alibaba_Qwen
Qwen Live now, an appetizer 👀
QwenCloud
@qwen_cloud
Ready for Qwen Live EP2?We will start at 10:00AM! UTC+8
x.com/i/broadcasts/1mGPaZanWBqJN
Qwen Cloud:www.qwencloud.com
#qwencloud
Qwen
@Alibaba_Qwen
Try Qwen-Image-3.0 on @openart_ai! 🎨👀
 OpenArt
@openart_ai
Qwen Image 3.0 is now on OpenArt ✨
The most Real Qwen image model yet. Native text across 12 languages, precise 10px type, and full interfaces like web pages, games, and livestreams rendered with real world knowledge.
Available now on OpenArt:
openart.ai/suite/create-image/qwen-image-3
 Qwen
@Alibaba_Qwen
👀 Seeing is just the beginning.
With Qwen-MM-Plugins, turn your favorite agent harness multimodal-native — read images, videos & documents, edit videos, work with 3D/CAD, and more.
From multimodal models → multimodal agents. 🚀
Watch it in action:
github.com/QwenLM/Qwen-MM-Plugins
Qwen
@Alibaba_Qwen
The cloud was always a cat. Qwen3.8-Max just saw it first. 😼☁️ Try it yourself!
 Ann Nguyen
@ann_nnng
Qwen 3.8 Max is actually impressive
Sent a sky pic to it along with Claude Opus 5, Kimi K3, and GPT 5.6 Sol, and asked them to draw an animal silhouette based on the cloud shape
Qwen 3.8 Max is honestly on par with all the other models
Qwen
@Alibaba_Qwen
Thanks for the thorough testing! With Qwen3.8-Max, everyone can observe the world in detail. 👀
 SkalskiP
@skalskip92
8.5 percentage points ahead of Gemini 3.5 Flash
congrats to @Alibaba_Qwen !
 Qwen
@Alibaba_Qwen
A quick snapshot of where Qwen3.8-Max stands today:
Qwen3.8-Max now ranks #5 on the Artificial Analysis Intelligence Index, and #1 on the Agentic Index!🥇
We'll keep pushing forward. 🚀

 Qwen
@Alibaba_Qwen
Let's create with Qwen-Image-3.0-Pro on fal! 🎨
 fal
@fal
Qwen Image 3.0 Pro is now available on fal
- Renders complex, dense typography
- Preserves key details like facial features and identity while applying changes
- Handles object edits, style transfer, background changes perfectly
Qwen
@Alibaba_Qwen
Try npm i -g cline on Cline!👀
Cline
@cline
Qwen3.8-Max is now available in ClinePass, a subscription for ~5x discounted access.
Use it on Cline CLI w/ $4.99 special promo:
npm i -g cline
This is currently the most affordable way to access Qwen.
 Qwen
@Alibaba_Qwen
Qwen3.8-Max hits #2 in Image-to-WebDev Arena! It sees, it builds~😎
Arena.ai
@arena
Exciting news: Qwen3.8-Max by @Alibaba_Qwen is #2 in Image-to-WebDev Arena!
With 1,631 pts, it’s trailing only Claude Opus 5 (Max) by 39 pts!
Congrats again to @Alibaba_Qwen on this huge release!
 Qwen
@Alibaba_Qwen
Qwen-Image-3.0-Pro is live on Qwen Cloud now!
Try it out👇
www.qwencloud.com/models/qwen-image-3.0-pro
QwenCloud
@qwen_cloud
🔔 Qwen-Image-3.0 is now live on Qwen Cloud!
Ranked #1 among Chinese models and #2 among mainstream models in Arena. ai's Text-to-Image Arena @arena, now one API call away.
- Up to 4.5k-token prompts: newspapers, storyboards, menus, exam papers in one pass
- Text legible down to 10px, near-photographic detail
- 12 languages, 100+ art styles, realistic UI simulation
- Generation + editing in one model
💰Price:
Qwen-Image-3.0 Pro — is best suited for complex layouts, accurate text rendering, and commercial-grade visuals, starting at $0.04 per image.
Qwen-Image-3.0 Standard — is ideal for bulk, everyday image generation, starting at just $0.03 per image.
Qwen-Image-3.0-Pro & Standard. From prompt to production-ready image.
👉 Try it and get your API key on Qwen Cloud: www.qwencloud.com/models/qwen-image-3.0-pro
- Mainstream models = model families with 100K+ average daily MaaS API calls
#qwencloud #qwen
 Qwen
@Alibaba_Qwen
Qwen3.8-Max is available in Hermes Agent now! Let's build! 🚀🚀
 Nous Research
@NousResearch
Qwen 3.8-Max, the latest model from @Alibaba_Qwen, is now available in Hermes Agent at 20% off.
> hermes update
Qwen
@Alibaba_Qwen
Qwen-Image-3.0-Pro has made a massive leap from the previous generation, now ranking #5 globally. Appreciate the recognition! We will keep building.🚀
Arena.ai
@arena
More exciting news from @Alibaba_Qwen: Qwen-Image-3.0-Pro has entered the Text-to-Image Arena at #5 with 1,263 pts!
This is a strong improvement over Qwen-Image-2.0-Pro with 1,191 pts (#15 -> #5).
Performance by category also improved substantially (see post below).
Congrats to @Alibaba_Qwen on another huge release!
 Qwen
@Alibaba_Qwen
Qwen3.8-Max, better and cheaper. Try it out. 👀
 Command Code
@CommandCodeAI
We ran a test between the new Qwen3.8-Max, Opus 5 and GPT-5.6 Sol.
3 models. same prompt. one-shot with the /design command.
Reviewed gameplay features, UX/UI and cost.
🔹 Qwen3.8-Max → 9/10 · $0.0248
🔹 GPT-5.6 Sol → 9/10 · $0.150
🔹 Opus 5 → 8.5/10 · $0.253
Qwen3.8-Max is approximately 4.2× cheaper than GPT-5.6, Sol, Opus 5 and has the same level of UI, UX, and gameplay.
Qwen
@Alibaba_Qwen
Live and ready to build. Thanks for having us! @OpenRouter. Open weights dropping soon.⚡️
OpenRouter
@OpenRouter
Qwen3.8 Max by @Alibaba_Qwen is live on OpenRouter.
The new flagship has 2.4T parameters (95B active) and is built for long-horizon coding, research, and multimodal agent work. Open weights are due next week, a first for a Qwen Max-class model.
openrouter.ai/qwen/qwen3.8-max
Qwen
@Alibaba_Qwen
Ask anything, anonymously. Qwen3.8-Max has landed on Venice. Give it a try!
 Venice
@AskVenice
Qwen 3.8 Max from @Alibaba_Qwen is now available on Venice, anonymously.
Qwen
@Alibaba_Qwen
Live in Command Code!🎉
Command Code
@CommandCodeAI
Qwen 3.8 Max is now live in Command Code Go.
… and it's going open weight!!
most importantly, next week open-weights of Qwen3.8-Max and Qwen3.8-27B will be released!
🔹 2.4T params MoE flagship
🔹 Input: $2 Output: $6
🔹 Cache: $0.25 / M tokens
3.8 is 20% cheaper than 3.7
Qwen
@Alibaba_Qwen
Let's Go!🚀
OpenCode
@opencode
Qwen3.8 Max is now available in OpenCode Go
Qwen
@Alibaba_Qwen
Appreciate it! Now let's understand the world through the eyes of Qwen3.8. 🥳
Qwen
@Alibaba_Qwen
Thanks for the recognition. We'll keep building! 🚀
Arena.ai
@arena
Big news: Qwen3.8-Max by @Alibaba_Qwen just landed at #4 on the Frontend Code Arena leaderboard with a score of 1,668!
With 1,668 points, Qwen3.8-Max is trailing only Claude Opus 5 (Max) with 1,705 pts and Kimi K3 (Max) with 1,676 pts, on par with Claude Opus 5 (High) with 1669 pts.
It also ranks high across all domains:
#2 in Consumer Product
#3 in Brand & Marketing, Reference-based design, Gaming, and Content Creation Tools
#4 in Data & Analytics
#5 Simulations
Dig into the thread for more details and to see how it also performs on real-world tasks in the Text Arena.
Congrats to @Alibaba_Qwen on this huge release!
 Qwen
@Alibaba_Qwen
📢Meet Qwen3.8-Max — our most capable model to date.
Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉
Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:
- Autonomous coding: 10+ days of self-evolving development, from empty folder to production without hand-holding, complete project trace in the GitHub:github.com/qwen-code-dev-bot/oh-my-cli
- Real work, real results: Production-quality deliverables across hundreds of professions.
- Long-horizon mastery: System-level autonomous planning with closed-loop adaptive learning, driving 500+ turns of chip design optimization and 365 days of e-commerce strategy.
- Native multimodal intelligence: Vision isn't just input — it's a continuous feedback loop for planning, execution, and self-correction.
💰Pricing:
Input: $2.0 / M tokens
Output: $6.0 / M tokens
Implicit Caching: $0.25 / M tokens
Start building with Qwen3.8-Max! 🚀
📖 Blog: qwen.ai/blog?id=qwen3.8
✅ Qwen Studio: chat.qwen.ai?models=qwen3.8-max
⚡ API: www.qwencloud.com/models/qwen3.8-max
 Qwen
@Alibaba_Qwen
🔥Let's talk about Qwen! #ama
 Qwen Developers
@QwenDevs
git init qwen_devs
README.md:
Hey 👋 We're the folks from Qwen Foundation Model Team.
Since we finally have an account...an AMA?
 Qwen
@Alibaba_Qwen
📢Meet Qwen3.8-Max — our most capable model to date.
Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉
Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters:
- Autonomous coding: 10+ days of self-evolving development, from empty folder to production without hand-holding, complete project trace in the GitHub:github.com/qwen-code-dev-bot/oh-my-cli
- Real work, real results: Production-quality deliverables across hundreds of professions.
- Long-horizon mastery: System-level autonomous planning with closed-loop adaptive learning, driving 500+ turns of chip design optimization and 365 days of e-commerce strategy.
- Native multimodal intelligence: Vision isn't just input — it's a continuous feedback loop for planning, execution, and self-correction.
💰Pricing:
Input: $2.0 / M tokens
Output: $6.0 / M tokens
Implicit Caching: $0.25 / M tokens
Start building with Qwen3.8-Max! 🚀
📖 Blog: qwen.ai/blog?id=qwen3.8
✅ Qwen Studio: chat.qwen.ai?models=qwen3.8-max
⚡ API: www.qwencloud.com/models/qwen3.8-max
Qwen
@Alibaba_Qwen
LM Performance
 Qwen
@Alibaba_Qwen
VL Performance
 Qwen
@Alibaba_Qwen
VL Performance - English Version
 Qwen
@Alibaba_Qwen
LM Performance - English Version
 Qwen
@Alibaba_Qwen
Text Arena: arena.ai/leaderboard/text?rankBy=labs
 Qwen
@Alibaba_Qwen
Dynamic workflows to quant strategies
Qwen
@Alibaba_Qwen
Visual agentic intelligence
Qwen
@Alibaba_Qwen
🏆 Alibaba hits #2 on the Text Arena.
 Qwen
@Alibaba_Qwen
Meet Qwen3.8-Max: A New Bar for Coding and Cowork.
Qwen
@Alibaba_Qwen
Introducing Qwen-Audio-3.0-ASR-Flash:
More context-aware. Stronger domain-term recognition.
🚀Our latest ASR model upgrades:
• Context consistency
• Domain-term recognition
• Custom hotwords
• Speech polishing into structured transcripts
⚡️In internal tests:
• Medical term recall: 95.36%
• Industrial term recall: 93.24%
Qwen-Audio-3.0-ASR-Flash-Streaming:
www.alibabacloud.com/help/en/model-studio/fun-asr-real-ti…
Qwen-Audio-3.0-ASR-Flash-Filetrans:
www.alibabacloud.com/help/en/model-studio/fun-asr-recorde…
Qwen-Audio-3.0-ASR-Flash:
www.alibabacloud.com/help/en/model-studio/non-real-time-s…

Qwen reposted
Artificial Analysis
@ArtificialAnlys
Alibaba has released Qwen Audio 3.0 Realtime, with the Plus variant debuting as the new #1 model on the Artificial Analysis Speech to Speech Index at 84.1%, ahead of GPT-Realtime-2.1 High at 79.1%
Released earlier this month, Qwen Audio 3.0 Realtime is @Alibaba_Qwen’s flagship native Speech to Speech model, available in two variants: Plus and Flash. Qwen Audio 3.0 Realtime Plus leads on all three component benchmarks comprising the Artificial Analysis Speech to Speech Index, Big Bench Audio for Speech Reasoning, Full Duplex Bench for Conversational Dynamics, and Tau Voice for Agentic Performance. We tested the China-hosted endpoints on Aliyun (Alibaba Cloud).
Key takeaways:
➤ Speech to Speech Index: Qwen Audio 3.0 Realtime Plus is the new leader at 84.1%, ahead of GPT-Realtime-2.1 High (79.1%) and GPT-Realtime-2 High (77.2%). The Flash variant comes in at 4th at 76.3%.
➤ Speech to Speech Index by Benchmark: On Big Bench Audio, the Plus variant achieves 99.2%, up ~0.5 percentage points from the previous best of 98.7% (Alibaba Qwen3.5 Omni Plus Realtime), with Flash variant scoring 96.1%. On Tau Voice, the Plus variant currently leads with a score of 54.6%, ahead of Grok Voice Think Fast 1.0 at 52.1%. On Full Duplex Bench, the Plus variant leads our Full Duplex Bench subset at 98.4%, with Flash at 96.9%, both ahead of the best non-Alibaba model, GPT-Realtime-2 (Minimal) at 96.1%.
➤ Speed: The Plus variant records an average Time to First Audio of 4.02 seconds on Big Bench Audio, with Flash at 4.16 seconds, among the slowest models on our leaderboard, and well behind GPT-Realtime-2 (Minimal) at 1.10 seconds and GPT-Realtime-2 (High) at 1.14 seconds
➤ Price: Plus costs $4.42 per hour of input audio on our Big Bench Audio subset, more expensive than GPT-Realtime-2 High ($4.14) and ~2.4x cheaper than GPT-Realtime-2.1 High ($10.75). The average cost for Flash variant is $4.77, higher than the Plus variant despite lower list prices, driven by comparatively more verbose responses.
See below for more detail ⬇️
 Qwen
@Alibaba_Qwen
Since launching Qwen3.8-Max-Preview, we've received valuable feedback from developers!
To help users better explore Qwen3.8's agentic capabilities, we're officially launching the #qwengrowthplan today! 🚀
We invite you to:
- Use Qwen3.8 to complete your real-world tasks
- Submit your good or bad cases to us
Every real task is nourishment for Qwen3.8's growth. We've prepared valuable rewards to recognize your active participation.
For more detailed participation info and prizes, please check out the posters below👇. Besides emailing us, feel free to share your awesome cases or feedback directly on X and @Alibaba_Qwen
Join us and let's grow together!


 Qwen
@Alibaba_Qwen
Introducing the Qwen-Audio-3.0-TTS.
Our latest text-to-speech model, in two flavors:
• Flash: real-time interaction
• Plus: high-quality generation
What's new:
• Fine-grained inline tags-steer [whisper], [angry], [breaths] & [laughs]
• Free-style natural-language control-“read this slowly, like a bedtime story”
• 16 languages
• Clean output even from noisy reference audio
• One-pass long-form up to 3 min
now #1 on the Artificial Analysis TTS Leaderboard.
Blog: funaudiollm.github.io/qwen-audio-3.0-tts/
API: www.alibabacloud.com/help/en/model-studio/realtime-tts-us…
 Qwen
@Alibaba_Qwen
🎨 Meet Qwen-Image-3.0 — the third generation of our foundational image generation model.
If 1.0 was about "Precision," and 2.0 added "Variety, Completeness, Beauty & Authenticity," then 3.0 comes down to a single word: Real (实).
Three dimensions of "Real":
📰 Rich Content — prompts up to 4.5k tokens. One-pass generation of complex layouts: newspapers, storyboards, exam papers — even a 3×3 infographic grid or picture-in-picture-in-picture UIs.
🔬 Authentic Details — text legible down to 10px, full LaTeX paper pages, pores, hair strands & near-photographic skin texture.
🌏 Deep Knowledge — native rendering in 12 languages, 100+ art styles, realistic UIs (web / games / livestreams), plus world knowledge & live web retrieval.
Not just "good-looking" — genuinely useful. Image generation as a real productivity tool for design, content, education & e-commerce.
Go create 🏃🎨
💬Qwen Chat: chat.qwen.ai?inputFeature=t2i
📝Blog: qwen.ai/blog?id=qwen-image-3.0
 Qwen
@Alibaba_Qwen
Beyond horizontal expansion, depth is another key trait of Rich Content — testing the model's semantic deconstruction and logical nesting: rendering multiple nested interfaces layer by layer within a single image.
The example below uses one instruction to display, from outer to inner: VSCode → Qwen Chat → a messaging app → a pour-over coffee poster. Each layer preserves the authentic style of its UI, forming a "picture-in-picture-in-picture" visual depth.
 Qwen
@Alibaba_Qwen
Authentic Details and Deep Knowledge are also major upgrades in this release. Together, they enable Qwen-Image-3.0 to make real breakthroughs in high-value productivity scenarios — newspaper PDFs, short-drama storyboards, complex UI, and more. As image generation keeps advancing, we believe it will unlock genuine productivity value across design, content creation, education, e-commerce, and beyond.


 Qwen
@Alibaba_Qwen
🔥🔥
QwenCloud
@qwen_cloud
Token Plan Individual is now live on Qwen Cloud, starting at just $6/month.🚀
One plan gives you access to the Qwen family, HappyHorse, GLM, and DeepSeek,and you can be among the first to try Qwen3.8-Max-Preview.
Even better, a single Token Plan can power up to 8 agents at the same time (for Pro Plan), so your whole agent stack runs on one subscription.
And, Harness tools like web search, image search, and code interpreter are included too.
🌍Try On Qwen Cloud: www.qwencloud.com/pricing/token-plan
 Qwen
@Alibaba_Qwen
🚀🚀
 Qoder
@qoder_ai_ide
Day 0 on Qoder: Qwen3.8-Max-Preview is live. 🚀
2.4T params + huge gains in Coding & Cowork — running on Qoder's agentic core, built to run autonomous, long-horizon tasks end to end while you step away.
Up to 98% off right now (0.5x → 0.01x). The window to go big is open.
Start at qoder.com
 Qwen
@Alibaba_Qwen
During Preview, Qwen3.8 is getting better by the day. Latest version is live now, with broad gains and a big step up on web frontend.
Thank you all — the response to Qwen3.8-Max-Preview blew us away. 🫶🫶
Qwen3.8 is still evolving daily. Come test it, and tell us what breaks.
We're looking forward to a more capable, official version — and to open-weight it for everyone.🚀🚀
Qwen
@Alibaba_Qwen
Qwen3.8 is launching and going open-weight soon!🌐
With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5.
You don't have to wait to test it. Just now, the Qwen3.8-Max-Preview made its debut on Alibaba’s Token Plan, Qoder, and QoderWork. Be among the very first to try it out.
Can't wait to hear what you build. Stay tuned! 🚀
Token Plan
international:www.qwencloud.com/pricing/token-plan
China:platform.qianwenai.com/pricing/token-plan
 Qwen
@Alibaba_Qwen
Qwen3.8 is launching and going open-weight soon!🌐
With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5.
You don't have to wait to test it. Just now, the Qwen3.8-Max-Preview made its debut on Alibaba’s Token Plan, Qoder, and QoderWork. Be among the very first to try it out.
Can't wait to hear what you build. Stay tuned! 🚀
Token Plan
international:www.qwencloud.com/pricing/token-plan
China:platform.qianwenai.com/pricing/token-plan
Qwen
@Alibaba_Qwen
📣📣 Meet Qwen-AgentWorld — a native language world model that simulates 7 agent environments (MCP, Search, Terminal, SWE, Web, OS, Android) within a single model. Environment modeling is the training objective from day one, not a post-hoc adaptation.
🤔 LLMs are trained to be better agents — better at acting in environments. But nobody has trained them to model the environments themselves.
🗺️ Our roadmap: investigate how language world modeling can push the boundaries of general agent capabilities, along two routes:
1️⃣ Build a foundation model for environment simulation — outperforming Claude Opus 4.8 and GPT-5.4 on AgentWorldBench
2️⃣ Investigate how world modeling enhances agent training:
🔬 Controllable Sim RL (agentic RL with LWM as environments) surpasses training in real environments
🧠 Learning to predict environments (LWM warm-up) makes agents stronger — remarkably, even without any agent-specific training, this predictive knowledge transfers to agentic tasks with zero fine-tuning
📑 Paper: arxiv.org/abs/2606.24597
📖 Blog: qwen.ai/blog?id=qwen-agentworld
💻 GitHub: github.com/QwenLM/Qwen-AgentWorld
🤗 HuggingFace: huggingface.co/collections/Qwen/qwen-agentworld
🧩 ModelScope: modelscope.cn/collections/Qwen/Qwen-AgentWorld
 Qwen
@Alibaba_Qwen
🧠 Paradigm II — Agent Foundation Model: world modeling as agent capability.
Single-turn, non-agentic environment prediction → tested directly on multi-turn, tool-calling agent tasks. No agentic RL, no task-specific tuning.
Gains across 7 benchmarks, including 3 entirely out-of-domain:
- In-domain: Terminal-Bench 2.0 +6.3, SWE-Bench +3.4, WideSearch +12.8
- Out-of-domain: Claw-Eval +11.3, QwenClawBench +9.7, BFCL v4 +9.0
World modeling internalizes "predict before you act" as a transferable reasoning pattern.
 Qwen
@Alibaba_Qwen
We open-source Qwen-AgentWorld-35B-A3B (MoE, 35B/3B active, 256K context) and AgentWorldBench.
Two routes, one roadmap:
🔬 Build the simulator — scalable, controllable, surpassing real environments
🧠 Internalize world modeling — predict before you act
Qwen-AgentWorld is our attempt to investigate how language world modeling can further expand the boundaries of general agent capabilities.
Go build on it 🏃🏃♂️
📑 Paper: arxiv.org/abs/2606.24597
📖 Blog: qwen.ai/blog?id=qwen-agentworld
💻 GitHub: github.com/QwenLM/Qwen-AgentWorld
🤗 HuggingFace: huggingface.co/collections/Qwen/qwen-agentworld
🧩 ModelScope: modelscope.cn/collections/Qwen/Qwen-AgentWorld
 Qwen
@Alibaba_Qwen
📣 Introducing the Qwen-Robot Suite — Qwen-RobotNav, Qwen-RobotManip, Qwen-RobotWorld, three foundation models, a full stack for embodied intelligence.
🧭 Qwen-RobotNav — the gateway to mobility.
• Unifies 5 navigation tasks in one model: instruction following, point-goal, object-goal, target tracking, autonomous driving
• Controllable observation protocol
• Tool interface for agentic systems
🤖 Qwen-RobotManip — the foundation of interaction.
• Unified state-action space across heterogeneous robots
• Camera-frame delta poses for coherent cross-embodiment training
• Pretrained on a 38,100+ hour open-source corpus
🌍 Qwen-RobotWorld — infinite worlds for physical agents.
• Single world model, 20+ embodiments
• Natural-language action interface
• Predicts physically grounded futures across manipulation, driving, and navigation
Each model is independently useful, and could be composed as physical-world tools.Together, they form the low-level toolkit for general-purpose agentic systems that don't just see the world, but act in it.
📷 Blog:
qwen.ai/blog?id=qwen-robotsuite
📖 Report:
Qwen-RobotNav: qianwen-res.oss-accelerate.aliyuncs.com/qwenrobot/papers/…
Qwen-RobotManip: qianwen-res.oss-accelerate.aliyuncs.com/qwenrobot/papers/…
Qwen-RobotWorld: qianwen-res.oss-accelerate.aliyuncs.com/qwenrobot/papers/…

 Qwen
@Alibaba_Qwen
By treating natural language as a universal action interface,Qwen-RobotWorld bridges the gap between general video generation models and domain-specific embodied models — this converts end-effector poses, steering commands, and navigation waypoints into a single interface, enabling 20+ embodiment types and 500+ action categories to be co-trained under the Embodied World Knowledge corpus (8.6M video-text pairs, 200M+ frames), with each domain's physical knowledge reinforcing the others.
Qwen-RobotWorld performs strongly across EWMBench/DreamGen/WorldModelBench/PBench benchmarks.
Blog Link:qwen.ai/blog?id=qwen-robotworld
 Qwen
@Alibaba_Qwen
Qwen-Robot Suite,enable AI from chatbot to physical action in the real world.
More demos, please visit our blog:qwen.ai/blog?id=qwen-robotsuite
Qwen
@Alibaba_Qwen
👏👏 Introducing Qwen3.7-Plus — a multimodal agent model that unifies vision and language into one versatile agent foundation.
✅ Multimodal interactive hybrid agent: unified GUI & CLI operation across visual and text tasks
✅ Versatile coding agent & productivity assistant with full-modality input
✅ Visual Agent: perception, reasoning, grounding, and search-augmented QA
✅ Cross-harness generalization across diverse agent frameworks
One model. Sees, thinks, codes, acts.🙌🙌
Now available via API on Alibaba Cloud Model Studio. Try it — let us know what you build.😎
🔗🔗⬇️⬇️
Blog:qwen.ai/blog?id=qwen3.7-plus
Qwen Studio:chat.qwen.ai?models=qwen3.7-plus
API:modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
 Qwen
@Alibaba_Qwen
Demo2: Multimodal Interactive Hybrid Agent
Qwen
@Alibaba_Qwen
Demo3:Browser Agent
Qwen
@Alibaba_Qwen
📢Qwen3.7-Max just hit #3 on ITbench-AA — a fresh benchmark testing how well models handle real-world enterprise IT tasks, agentic-style.
🔧Agentic era, go with Qwen.🏃🏃
Artificial Analysis
@ArtificialAnlys
Artificial Analysis and IBM Research are launching ITBench-AA, the first in a new series of benchmarks evaluating models on agentic enterprise IT tasks, starting with Site Reliability Engineering tasks where frontier models score below 50%
ITBench-AA’s SRE tasks benchmark model performance on Kubernetes incident response, where models must diagnose live systems by reading logs, tracing dependencies, and identifying root-cause entities across complex infrastructure. The underlying ITBench dataset has been developed by @IBM's Software Innovation Lab, leveraging IBM’s deep expertise in enterprise IT operations
Artificial Analysis has worked closely with IBM over the last 6 months to develop a implementation of the dataset for frontier AI evaluation, beginning with Site Reliability Engineering (SRE) and expanding to Financial Operations (FinOps) and Chief Information Security Officer (CISO) tasks over time
ITBench-AA SRE overview:
➤ 59 SRE tasks in total: 40 public tasks and 19 brand new, held-out tasks
➤ Each task provides a Kubernetes incident snapshot containing alerts, events, traces, metrics, logs, and application topology. The model must identify the minimal set of independent root-cause Kubernetes entities responsible for the incident
➤ Faults span typical SRE failure modes including infrastructure, service, application, and chaos-injected incidents, such as resource quota exhaustion, rollout failures, connection pool exhaustion, and network partitions
Methodology details:
➤ Agentic harness: each task is solved by the model running in our open-source Stirrup reference harness, with shell access to a sandboxed file system containing the relevant logs and snapshots. 100-turn cap per task, 3 repeats per task
➤ Models submit a list of root-cause entities (Kubernetes Deployments, Services, Pods, etc.) they believe caused the incident. Each submission is compared against a ground-truth set of root causes provided by IBM Research
➤ Scoring uses average precision at full recall: if a model misses any of the ground-truth root causes, it scores 0.0 for that repeat. If it identifies all of them, it is awarded a score equal to its precision - the share of its submitted entities that are actual root causes, i.e. true positives / (true positives + false positives). The headline score is the average across 59 tasks × 3 repeats.
➤ The harness (Stirrup) is held constant across all evaluated models, allowing an apples-to-apples comparison between models.
Key findings:
➤ Claude Opus 4.7 (Adaptive Reasoning, Max Effort) leads at 47%, followed by GPT-5.5 (xhigh) at 46% and Qwen3.7 Max at 42%
➤ All frontier models score below 50%, making ITBench-AA SRE one of the least saturated agentic benchmarks in our suite. For context, frontier models score considerably higher on Terminal-Bench
➤ Turn counts vary nearly 3x and longer trajectories do not translate to higher accuracy. GPT-5.5 (xhigh) averages 31 turns per task at 46%, while Gemini 3.1 Pro Preview averages 83 turns at 30%. Models that over-investigate tend to surface upstream fault-injection mechanisms or co-occurring symptoms as false positives
➤ GLM-5.1 (Reasoning) leads open weights models at 40%, effectively tied with Gemini 3.5 Flash (high). DeepSeek V4 Pro (Reasoning, Max Effort) follows at 38%, with Gemma 4 31B (Reasoning) at 37%, ahead of Gemini 3.1 Pro Preview at 30%
 Qwen
@Alibaba_Qwen
Fast, faster, Qwen. 🚀
Thrilled to see Qwen3.5 reaching a record-breaking 580 tps for agentic workloads on the TokenSpeed engine! This milestone wouldn't be possible without our incredible partners.
Huge thanks to @lightseekorg, @NVIDIAAI, the Mooncake team, and @tri_dao for the pioneering FA4 optimization. Together, we are pushing the boundaries of open-source LLM inference. 🤝✨
Dive into the full @PyTorch blog post below! 👇
pytorch.org/blog/up-to-580tps-new-speed-record-of-qwen3-5…
#qwen #qwen3_5 #tokenspeed #llm #inference #ai #pytorch #opensource #agenticai #highperformance
 PyTorch
@PyTorch
The speed-of-light optimization for Qwen3.5 on the TokenSpeed inference engine is a significant milestone, achieving a record-breaking 580 tokens per second (tps) for agentic workloads on NVIDIA GPUs.
In the PyTorch Foundation's latest community blog post, you can learn all about the complete design, implementation, and optimization of Qwen3.5 models in the TokenSpeed inference framework and see for yourself how this work is improving performance 👉 pytorch.org/blog/up-to-580tps-new-speed-record-of-qwen3-5…
This achievement was a joint effort between the @Alibaba_Qwen inference team, @lightseekorg Foundation TokenSpeed team, @NVIDIAAI , and the Mooncake team, with special contributions from @tri_dao for FlashAttention-4 (FA4) optimization. @KVCache_AI
 Qwen
@Alibaba_Qwen
🚀🚀
Nous Research
@NousResearch
Qwen 3.7 Max is now supported in Hermes Agent

Qwen reposted
OpenCode
@opencode
Qwen3.7 Max now available in Go
- text only
- 1M context
- smartest model in the Qwen family to date
Qwen
@Alibaba_Qwen
🙌🙌
Qoder
@qoder_ai_ide
Qwen3.7-Max, halved.
Starting today, Qwen3.7-Max — the latest flagship from the @Alibaba_Qwen family — is half price on Qoder. Limited time.
New here? You also get 100 free model calls a day. Auto-applied. No claim. No toggle.
Desktop, JetBrains Plugin, CLI, QoderWork, QoderWake — all covered.
Now's a good time to put it on something hard.
 Qwen
@Alibaba_Qwen
🚀🚀 Qwen3.7-Max just hit #4 on Code Arena, on par with Claude Opus 4.6 ,top-ranked Chinese lab on the board! @arena
More to ship. Stay tuned. 🕶️
Arena.ai
@arena
Qwen3.7 Max (20250517) debuts at #4 in Code Arena: Frontend - the top-ranked Chinese lab on the board, surpassing GLM-5.1 and is now on par with Claude Opus 4.6 on agentic web development tasks.
Huge congrats to @Alibaba_Qwen on this achievement!
 Qwen
@Alibaba_Qwen
✅Implicit caching is now live on Qwen3.7-Max — kicks in automatically, no setup needed.
⚡️Faster + cheaper out of the box.
Need higher, more deterministic hit rates? Try explicit caching instead. 🙌
🔗Best practices 🔗 :www.alibabacloud.com/help/en/model-studio/explicit-cache-…
Qwen
@Alibaba_Qwen
⚡️⚡️
OpenRouter
@OpenRouter
The new Qwen3.7-Max from @Alibaba_Qwen is live on OpenRouter.
The flagship of the Qwen3.7 series, built for agent-centric work: coding, office and productivity tasks, and long-horizon autonomous execution. Big jumps in coding and agent benchmarks over Qwen3.6, with explicit prompt caching for repeated context.
 Qwen
@Alibaba_Qwen
👀👀
atomic.chat
@atomic_chat_hq
Qwen 3.7-max beats Opus 4.7 and GPT-5.5
We tested three frontier models on a real agentic task: write a Tetris bot that plays the game and trains itself. Each model could read its own code, run benchmarks, and rewrite itself across 10 iterations. Then we compared the final bots head to head.
Qwen 3.7-Max: training cost $1.32, bot improvement +56%
Claude Opus 4.7: training cost $12.15, bot improvement +28%
GPT-5.5: training cost $2.85, bot improvement +7%
Qwen won on every dimension - biggest jump, 9× cheaper than Claude, 2× cheaper than GPT. Long agentic loops is where Qwen Max actually delivers.
Qwen
@Alibaba_Qwen
🚀Qwen3.7-Max just landed at 56.6 on the Artificial Analysis Intelligence Index — a solid 4.8pt jump over Qwen3.6-Max-Preview. @ArtificialAnlys
⚡️Sharper sci reasoning, stronger agentic chops, better coding, and it hallucinates less.
Artificial Analysis
@ArtificialAnlys
Alibaba’s new Qwen3.7 Max model scores 56.6 on the Artificial Analysis Intelligence Index, 4.8 points higher than Qwen3.6 Max Preview (51.8). While Alibaba still trails models from OpenAI, Anthropic and Google, Qwen3.7 Max is the closest they have been to the frontier
Qwen3.7 Max is @Alibaba_Qwen's latest proprietary flagship, scoring 56.6 on the Intelligence Index, a 4.8 point gain over Qwen3.6 Max Preview (51.8) released in April. Qwen3.7 Max continues Alibaba's pattern, in place since Qwen2.5 Max (January 2025), of releasing Max and Plus models as closed weights while the rest of the Qwen line remains open weights. The leading open weights Qwen on the Intelligence Index is Qwen3.6 27B (Reasoning, 45.8) released in April 2026, and the leading open weights MoE Qwen is Qwen3.5 397B A17B (Reasoning, 45.0) released in February 2026
Key takeaways for the reasoning variant:
➤ The Intelligence Index gains over Qwen3.6 Max Preview are concentrated in scientific reasoning, agentic capability and coding. CritPt +9.7 p.p (3.7% to 13.4%), HLE +9.2 p.p (28.9% to 38.1%), TerminalBench Hard +6.9 p.p (43.9% to 50.8%) and GDPval-AA +42 Elo (1504 to 1546). Scores on other benchmarks in the Intelligence Index are flat compared to Qwen3.6 Max Preview
➤ A significant share of the Intelligence Index gain is driven by higher abstention on AA-Omniscience, not higher accuracy. Qwen3.7 Max's accuracy on AA-Omniscience dropped 7.6 p.p (37.7% to 30.1%), while its hallucination rate dropped 21.3 p.p (44.2% to 22.9%). The model is choosing not to answer more questions rather than recalling more facts. Because hallucination rate and accuracy both feed into the Intelligence Index, the hallucination reduction is one of the larger single contributors to the +4.8 point gain on the Intelligence Index
➤ Qwen3.7 Max used 96.7M output tokens to run the Intelligence Index, ~31% more than Qwen3.6 Max Preview (73.9M). It sits mid-pack on frontier token usage: above GPT-5.5 (high, 44.5M) and Gemini 3.1 Pro Preview (57.3M), below Claude Opus 4.7 (Adaptive Reasoning, Max Effort, 112M), Kimi K2.6 (166M) and DeepSeek V4 Pro (Reasoning, Max Effort, 187M)
Key model details:
➤ Context window: 1M tokens (up from 256K on Qwen3.6 Max Preview)
➤ Multimodality: Text input and output only
➤ Pricing: Yet to be announced (Qwen3.6 Max Preview is priced at $1.30/$7.80 per 1M input/output tokens on the @alibaba_cloud first-party API)
➤ Licensing: Proprietary, closed weights
 Qwen
@Alibaba_Qwen
📣Meet Qwen3.7-Max — our latest flagship, made for the Agent Era.
A versatile foundation for agents that actually get things done:
🧑💻 Coding agent, end to end. Frontend prototypes, multi-file refactors, real debugging — nails it.
🗂️ A reliable office and productivity assistant. Get your work done through MCP integrations and multi-agent orchestration.
⏱️ Long-horizon autonomy. 35 hours straight on a kernel optimization task — 1,000+ tool calls, zero hand-holding.
🔌 Scaffold-agnostic. Claude Code, OpenClaw, Qwen Code, or your own stack. Consistent reliability everywhere.
API's up on Alibaba Model Studio. You can also take it for a spin on Qwen Studio.
Go build something wild!🏃🏃♂️
📖 Blog: qwen.ai/blog?id=qwen3.7
✅ Qwen Studio: chat.qwen.ai?models=qwen3.7-max
⚡️ API:modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
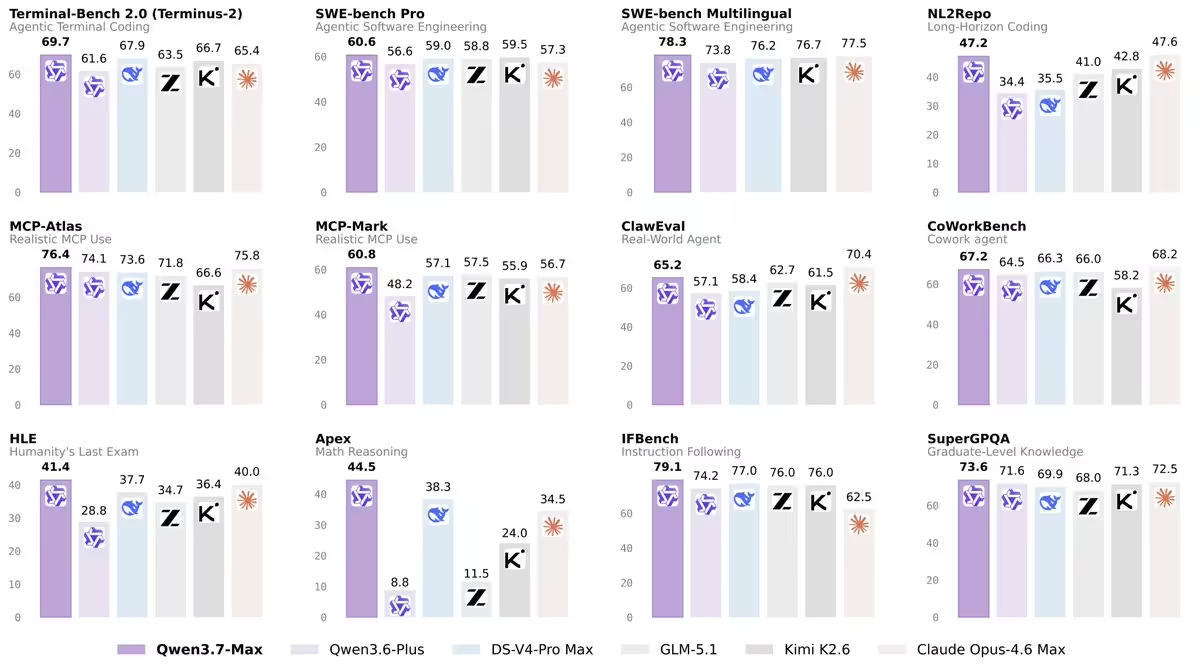 Qwen
@Alibaba_Qwen
Self-Evolving in the Wild:Over the course of ~35 hours of continuous autonomous execution, the model performed 432 kernel evaluations across 1,158 tool calls. It wrote, compiled, profiled, and iteratively improved the Extend Attention Kernel entirely on its own — 10.0x geometric mean speedup over the Triton reference, measured across multiple workloads.
More details on blog:qwen.ai/blog?id=qwen3.7
 Qwen
@Alibaba_Qwen
Cowork Productivity Assistant:Qwen3.7-Max serves as your advanced coworker for real-world productivity.
Qwen
@Alibaba_Qwen
🚀🚀
Arena.ai
@arena
In the Vision Arena, Qwen3.7 Plus Preview makes @Alibaba_Qwen the #5 lab, ranking #16 overall.
 Qwen
@Alibaba_Qwen
🚀🚀Qwen3.7 Preview lands on Arena !
Here come Qwen3.7-Max-Preview & Qwen3.7-Plus-Preview. Alibaba now #6 lab in Text, #5 in Vision.⚡️⚡️
Can't wait to release Qwen3.7 series models!Stay tuned! @arena
Arena.ai
@arena
Qwen3.7 Preview By @Alibaba_Qwen lands on Arena for Text and Vision.
In Text Arena, Qwen3.7 Max Preview ranks #13 overall.
Alibaba is now the #6 lab in this arena.
- #7 Math
- #9 Expert
- #9 Software & IT
- #10 Coding
In Vision Arena: Qwen3.7 Plus Preview ranks #16 overall, making Alibaba the #5 lab.
Congrats to the @Alibaba_Qwen team on the latest progress!
 Qwen
@Alibaba_Qwen
🚀Qwen3.6-Plus is on Nous Portal now and FREE for a limited time.
Hermes Agent, here we go!! ⚡️ @NousResearch
Nous Research
@NousResearch
Qwen 3.6 Plus by @Alibaba_Qwen is now FREE for a limited time on Nous Portal!
Nous Portal is one easy subscription that gives you access to 300+ models, exclusive discounts, and bundles your tokens and paid tools together for hassle-free setup and simple billing.
Qwen
@Alibaba_Qwen
📣We're calling for ambassadors!
Whether you're a developer with great technical taste or a local community leader who loves bringing people together, we'd love to have you join us.
Visit the website below for more details and to apply. In return, ambassadors will receive early access to Qwen models, API credits, annual merchandise, and more.
Come and check it out!👇
qwen.ai/ambassador
 Qwen
@Alibaba_Qwen
📢 Official Announcement: Qwen Partners with Fireworks AI to Accelerate Access to Qwen Family Models
We are pleased to announce a strategic partnership between Qwen and Fireworks AI to deliver optimized, production-ready deployment of Qwen's closed weights models via the Fireworks Platform. @FireworksAI_HQ
This collaboration empowers developers and enterprises to:
✅ Deploy Qwen models with lower latency and reduced fine tuning and inference costs
✅ Leverage enterprise-grade reliability, security, and scalability
✅ Integrate seamlessly into modern AI workflows
🔹 Get started with Qwen on Fireworks: app.fireworks.ai/models/fireworks/qwen3p6-plus
#qwen #fireworksai #opensourceai #llm #aiinfrastructure #responsibleai #developercommunity
Qwen
@Alibaba_Qwen
Today we’re releasing Qwen-Scope 🔭, an open suite of sparse autoencoders for the Qwen model family. It turns SAE features into practical tools:
🎯 Inference — Steer model outputs by directly manipulating internal features, no prompt engineering needed
📂 Data — Classify & synthesize targeted data with minimal seed examples, boosting long-tail capabilities
🏋️ Training — Trace code-switching & repetitive generation back to their source, fix them at the root
📊 Evaluation — Analyze feature activation patterns to select smarter benchmarks and cut redundancy
We hope the community uses Qwen-Scope to uncover new mechanisms inside Qwen models and build applications beyond what we explored.Excited to see what you build! 🚀
🔗🔗
Blog: qwen.ai/blog?id=qwen-scope
HuggingFace: huggingface.co/collections/Qwen/qwen-scope
ModelScope: modelscope.cn/collections/Qwen/Qwen-Scope
Technical Report: qianwen-res.oss-accelerate.aliyuncs.com/qwen-scope/Qwen_S…
 Qwen
@Alibaba_Qwen
🚀 Introducing FlashQLA: high-performance linear attention kernels built on TileLang.
⚡ 2–3× forward speedup. 2× backward speedup.
💻 Purpose-built for agentic AI on your personal devices.
💡Key insights:
1. Gate-driven automatic intra-card CP.
2. Hardware-friendly algebraic reformulation.
3. TileLang fused warp-specialized kernels.
FlashQLA boosts SM utilization via automatic intra-device CP. The gains are especially pronounced for TP setups, small models, and long-context workloads.
Instead of fusing the entire GDN flow into a single kernel, we split it into two kernels optimized for CP and backward efficiency. At large batch sizes this incurs extra memory I/O overhead vs. a fully fused approach, but it delivers better real-world performance on edge devices and long-context workloads.
The backward pass was the hardest part: we built a 16-stage warp-specialized pipeline under extremely tight on-chip memory constraints, ultimately achieving 2×+ kernel-level speedups.
We hope this is useful to the community!🫶🫶
Learn more:
📖 Blog: qwen.ai/blog?id=flashqla
💻 Code: github.com/QwenLM/FlashQLA
 Qwen
@Alibaba_Qwen
Forward and backward benchmark results across common configurations.
 Qwen
@Alibaba_Qwen
🚀 Introducing FlashQLA: high-performance linear attention kernels built on TileLang.
⚡ 2–3× forward speedup. 2× backward speedup.
💻 Purpose-built for agentic AI on your personal devices.
💡Key insights:
1. Gate-driven automatic intra-card CP.
2. Hardware-friendly algebraic reformulation.
3. TileLang fused warp-specialized kernels.
FlashQLA boosts SM utilization via automatic intra-device CP. The gains are especially pronounced for TP setups, small models, and long-context workloads.
Instead of fusing the entire GDN flow into a single kernel, we split it into two kernels optimized for CP and backward efficiency. At large batch sizes this incurs extra memory I/O overhead vs. a fully fused approach, but it delivers better real-world performance on edge devices and long-context workloads.
The backward pass was the hardest part: we built a 16-stage warp-specialized pipeline under extremely tight on-chip memory constraints, ultimately achieving 2×+ kernel-level speedups.
We hope this is useful to the community!🫶🫶
Learn more:
📖 Blog: qwen.ai/blog?id=flashqla
💻 Code: github.com/QwenLM/FlashQLA
 Qwen
@Alibaba_Qwen
Qwen-Image-2.0-Pro is now live 🚀🚀
We’ve pushed image quality, multilingual text rendering, and instruction following to a new level, while making performance much more consistent across styles.🌅🌃
Ranked #9 worldwide for Text-to-Image on @arena
🔗Try it now on
ModelScope:
modelscope.ai/studios/Qwen/Qwen-Image-2.0-pro
modelscope.cn/studios/Qwen/Qwen-Image-2.0-pro
API:modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
Arena.ai
@arena
Qwen Image 2.0 Pro 2026-04-22 lands at #9 in Text-to-Image Arena.
Highlights of the latest image model from @Alibaba_Qwen:
- #9 Text-to-Image
- #17 Image Edit (Single Image)
Top 10 in Text-to-Image categories:
- #6 Portraits
- #7 Photorealistic & Cinematic Imagery
- #7 Art
Congrats to the @Alibaba_Qwen team on this launch!
 Qwen
@Alibaba_Qwen
Sharper Instruction Following:
The model now adheres more closely to prompt semantics, especially for complex compositions. Better handling of multiple objects, spatial relationships and attribute binding
Yes, this is not a screenshot.📲
 Qwen
@Alibaba_Qwen
Comprehensive Multilingual Text Rendering:
Better glyph accuracy, more consistent typography, and cleaner layouts even in complex compositions.
It handles mixed-language scenarios more gracefully as well.
If you’re building posters, UI mockups, ads, or anything text-heavy, this should feel like a meaningful step forward.🪄
 Qwen
@Alibaba_Qwen
Balanced Performance Across Artistic Styles:
More uniform quality across diverse aesthetic domains, effectively reducing style-dependent quality variance.🏖️
 Qwen
@Alibaba_Qwen
👀👀
 David Hendrickson
@TeksEdge
🚨 OMG! Qwen just released Qwen3.6-27B! This is an update to the King 👑 of Open Source Med Models!
A 27B dense model that beats the much larger Qwen3.5-397B-A17B (~15x bigger) on coding benchmarks! 🤯
Watch out Opus 4.7
Key wins:
• SWE-Bench Verified: 77.2 (vs 76.2)
• SWE-Bench Pro: 53.5 (vs 50.9)
• Terminal-Bench 2.0: 59.3 (vs 52.5)
✅ Strong multimodal reasoning
✅ Thinking + Non-thinking modes
✅ Apache 2.0 (fully open)
Smaller model. Flagship performance. 🔥
 Qwen
@Alibaba_Qwen
🐦🐦⬛🐤
 Simon Willison
@simonw
The new Qwen3.6-27B just gave me definitely the best pelican riding a bicycle I've had from a 16.8GB model file! simonwillison.net/2026/Apr/22/qwen36-27b/
Qwen
@Alibaba_Qwen
Available on @ollama ! 🤝🤝
ollama
@ollama
Qwen 3.6 27B model is available on Ollama!
Use it with all the integrations in Ollama or chat with the model.
Chat with the model:
ollama run qwen3.6:27b
OpenClaw:
ollama launch openclaw --model qwen3.6:27b
Claude Code:
ollama launch claude --model qwen3.6:27b
More 👇👇👇
Qwen
@Alibaba_Qwen
🚀 Meet Qwen3.6-27B, our latest dense, open-source model, packing flagship-level coding power!
Yes, 27B, and Qwen3.6-27B punches way above its weight. 👇
What's new:
🧠 Outstanding agentic coding — surpasses Qwen3.5-397B-A17B across all major coding benchmarks
💡 Strong reasoning across text & multimodal tasks
🔄 Supports thinking & non-thinking modes
✅ Apache 2.0 — fully open, fully yours
Smaller model. Bigger results. Community's favorite. ❤️
We can't wait to see what you build with Qwen3.6-27B! 👀
🔗👇
Blog: qwen.ai/blog?id=qwen3.6-27b
Qwen Studio: chat.qwen.ai?models=qwen3.6-27b
Github: github.com/QwenLM/Qwen3.6
Hugging Face:
huggingface.co/Qwen/Qwen3.6-27B
huggingface.co/Qwen/Qwen3.6-27B-FP8
ModelScope:
modelscope.cn/models/Qwen/Qwen3.6-27B
modelscope.cn/models/Qwen/Qwen3.6-27B-FP8
 Qwen
@Alibaba_Qwen
⚡️⚡️Run Qwen3.6-27B locally! @UnslothAI
Unsloth AI
@UnslothAI
Qwen3.6-27B can now run locally! 💜
Run on 18GB RAM via Unsloth Dynamic GGUFs.
Qwen3.6-27B surpasses Qwen3.5-397B-A17B on all major coding benchmarks.
GGUFs: huggingface.co/unsloth/Qwen3.6-27B-GGUF
Guide: unsloth.ai/docs/models/qwen3.6
 Qwen
@Alibaba_Qwen
🚀 Meet Qwen3.6-27B, our latest dense, open-source model, packing flagship-level coding power!
Yes, 27B, and Qwen3.6-27B punches way above its weight. 👇
What's new:
🧠 Outstanding agentic coding — surpasses Qwen3.5-397B-A17B across all major coding benchmarks
💡 Strong reasoning across text & multimodal tasks
🔄 Supports thinking & non-thinking modes
✅ Apache 2.0 — fully open, fully yours
Smaller model. Bigger results. Community's favorite. ❤️
We can't wait to see what you build with Qwen3.6-27B! 👀
🔗👇
Blog: qwen.ai/blog?id=qwen3.6-27b
Qwen Studio: chat.qwen.ai?models=qwen3.6-27b
Github: github.com/QwenLM/Qwen3.6
Hugging Face:
huggingface.co/Qwen/Qwen3.6-27B
huggingface.co/Qwen/Qwen3.6-27B-FP8
ModelScope:
modelscope.cn/models/Qwen/Qwen3.6-27B
modelscope.cn/models/Qwen/Qwen3.6-27B-FP8
Qwen
@Alibaba_Qwen
Day 0 vLLM support for Qwen3.6-27B! @vllm_project ♥️❤️
vLLM
@vllm_project
🎉 Day-0 vLLM support for Qwen3.6-27B!
Congrats to @Alibaba_Qwen on the new 27B dense model release.
Looking forward to more of the Qwen3.6 series. 👀
📖 Recipe: recipes.vllm.ai/Qwen/Qwen3.6-27B
 Qwen
@Alibaba_Qwen
🚀 Meet Qwen3.6-27B, our latest dense, open-source model, packing flagship-level coding power!
Yes, 27B, and Qwen3.6-27B punches way above its weight. 👇
What's new:
🧠 Outstanding agentic coding — surpasses Qwen3.5-397B-A17B across all major coding benchmarks
💡 Strong reasoning across text & multimodal tasks
🔄 Supports thinking & non-thinking modes
✅ Apache 2.0 — fully open, fully yours
Smaller model. Bigger results. Community's favorite. ❤️
We can't wait to see what you build with Qwen3.6-27B! 👀
🔗👇
Blog: qwen.ai/blog?id=qwen3.6-27b
Qwen Studio: chat.qwen.ai?models=qwen3.6-27b
Github: github.com/QwenLM/Qwen3.6
Hugging Face:
huggingface.co/Qwen/Qwen3.6-27B
huggingface.co/Qwen/Qwen3.6-27B-FP8
ModelScope:
modelscope.cn/models/Qwen/Qwen3.6-27B
modelscope.cn/models/Qwen/Qwen3.6-27B-FP8
Qwen
@Alibaba_Qwen
Thanks to @lmsysorg ! Try it on SGLang now!🚀🚀
 LMSYS Org
@lmsysorg
🚀 Qwen3.6-27B is here, and we have day 0 support on SGLang ✅
27B params, beats Qwen3.5-397B-A17B across major coding benchmarks
→ Agentic coding
→ Text + multimodal reasoning
→ Thinking / non-thinking modes
Smaller model. Bigger results.
Try it on SGLang now 🔥
 Qwen
@Alibaba_Qwen
🚀 Meet Qwen3.6-27B, our latest dense, open-source model, packing flagship-level coding power!
Yes, 27B, and Qwen3.6-27B punches way above its weight. 👇
What's new:
🧠 Outstanding agentic coding — surpasses Qwen3.5-397B-A17B across all major coding benchmarks
💡 Strong reasoning across text & multimodal tasks
🔄 Supports thinking & non-thinking modes
✅ Apache 2.0 — fully open, fully yours
Smaller model. Bigger results. Community's favorite. ❤️
We can't wait to see what you build with Qwen3.6-27B! 👀
🔗👇
Blog: qwen.ai/blog?id=qwen3.6-27b
Qwen Studio: chat.qwen.ai?models=qwen3.6-27b
Github: github.com/QwenLM/Qwen3.6
Hugging Face:
huggingface.co/Qwen/Qwen3.6-27B
huggingface.co/Qwen/Qwen3.6-27B-FP8
ModelScope:
modelscope.cn/models/Qwen/Qwen3.6-27B
modelscope.cn/models/Qwen/Qwen3.6-27B-FP8
Qwen
@Alibaba_Qwen
🚀 Meet Qwen3.6-27B, our latest dense, open-source model, packing flagship-level coding power!
Yes, 27B, and Qwen3.6-27B punches way above its weight. 👇
What's new:
🧠 Outstanding agentic coding — surpasses Qwen3.5-397B-A17B across all major coding benchmarks
💡 Strong reasoning across text & multimodal tasks
🔄 Supports thinking & non-thinking modes
✅ Apache 2.0 — fully open, fully yours
Smaller model. Bigger results. Community's favorite. ❤️
We can't wait to see what you build with Qwen3.6-27B! 👀
🔗👇
Blog: qwen.ai/blog?id=qwen3.6-27b
Qwen Studio: chat.qwen.ai?models=qwen3.6-27b
Github: github.com/QwenLM/Qwen3.6
Hugging Face:
huggingface.co/Qwen/Qwen3.6-27B
huggingface.co/Qwen/Qwen3.6-27B-FP8
ModelScope:
modelscope.cn/models/Qwen/Qwen3.6-27B
modelscope.cn/models/Qwen/Qwen3.6-27B-FP8
Qwen
@Alibaba_Qwen
LM Performance:With only 27B parameters, Qwen3.6-27B outperforms the Qwen3.5-397B-A17B (397B total / 17B active, ~15x larger!) on every major coding benchmark — including SWE-bench Verified (77.2 vs. 76.2), SWE-bench Pro (53.5 vs. 50.9), Terminal-Bench 2.0 (59.3 vs. 52.5), and SkillsBench (48.2 vs. 30.0). It also surpasses all peer-scale dense models by a wide margin.
 Qwen
@Alibaba_Qwen
VLM Performance:Qwen3.6-27B is natively multimodal, supporting both vision-language thinking and non-thinking modes in a single unified checkpoint — the same as Qwen3.6-35B-A3B. It handles images and video alongside text, enabling multimodal reasoning, document understanding, and visual question answering.
 Qwen
@Alibaba_Qwen
Keep improving 🚀🚀 @arena
Arena.ai
@arena
Qwen3.6 Plus lands at #7 in Code Arena with a score of 1476 - up +16 points since the Preview.
The new score also moves @AlibabaGroup to #3 lab in Code Arena.
In the Text Arena, Qwen3.6 Plus lands at #36, a +13 point improvement since Preview.
Congrats to the Qwen team on the continued progress!
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3.6-Max-Preview, an early preview of our next flagship model
Highlights:
⚡️ Improved agentic coding capability over Qwen3.6-Plus
📖 Stronger world knowledge and instruction following
🌍 Improved real-world agent and knowledge reliability performance
Smarter, sharper, still evolving.
More Qwen3.6 models to come. Stay tuned!
🔗👇
Blog: qwen.ai/blog?id=qwen3.6-max-preview
Qwen Studio: chat.qwen.ai?models=qwen3.6-max-preview
API: modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
 Qwen
@Alibaba_Qwen
⚡ Meet Qwen3.6-35B-A3B:Now Open-Source!🚀🚀
A sparse MoE model, 35B total params, 3B active. Apache 2.0 license.
🔥 Agentic coding on par with models 10x its active size
📷 Strong multimodal perception and reasoning ability
🧠 Multimodal thinking + non-thinking modes
Efficient. Powerful. Versatile. Try it now👇
Blog:qwen.ai/blog?id=qwen3.6-35b-a3b
Qwen Studio:chat.qwen.ai
HuggingFace:huggingface.co/Qwen/Qwen3.6-35B-A3B
ModelScope:modelscope.cn/models/Qwen/Qwen3.6-35B-A3B
API(‘Qwen3.6-Flash’ on Model Studio):Coming soon~ Stay tuned
 Qwen
@Alibaba_Qwen
LM Performance:Qwen3.6-35B-A3B outperforms the dense 27B-param Qwen3.5-27B on several key coding benchmarks and dramatically surpasses its direct predecessor Qwen3.5-35B-A3B, especially on agentic coding and reasoning tasks.
 Qwen
@Alibaba_Qwen
VLM Performance:Qwen3.6 is natively multimodal, and Qwen3.6-35B-A3B showcases perception and multimodal reasoning capabilities that far exceed what its size would suggest, with only around 3 billion activated parameters. Across most vision-language benchmarks, its performance matches Claude Sonnet 4.5, and even surpasses it on several tasks. Its strengths are particularly evident in spatial intelligence, where it achieves 92.0 on RefCOCO and 50.8 on ODInW13.
 Qwen
@Alibaba_Qwen
It’s finally here! 🚀 Huge thanks to the @opencode team for the seamless integration. Qwen3.6-Plus and Qwen3.5-Plus are now live in Go!
Update now to try it out! 👇
OpenCode
@opencode
Qwen3.6 Plus and 3.5 Plus now available in Go
- both strong - 3.5 is 3x cheaper
- both support images
- zero data retention
update to the latest to try
Qwen
@Alibaba_Qwen
🚀 Qwen Code v0.14.0 – v0.14.2 are now available
Channels:Control Qwen Code remotely from Telegram, DingTalk, or WeChat — send a message from your phone, get results on your server
Cron Jobs :Schedule recurring AI tasks — auto-run tests every 30 min, pull & build every morning, monitor logs on a timer
Qwen3.6-Plus :New flagship model with 1M token context, 1,000 free daily requests
Sub-agent Model Selection:Assign different models to sub-agents — use a powerful model for the main task, a fast one for subtasks, save tokens without sacrificing quality
/plan:Enter planning mode before execution — AI maps out all files and steps first, you confirm, then it executes
Follow-up Suggestions:AI suggests 2-3 next steps after completing a task — "Add unit tests?" "Check similar files?" — click to continue
Adaptive Output Tokens :Default 8K output, auto-escalates to 64K when truncated — no more manually tuning max_tokens
Ctrl+O Verbosity Toggle :Switch between verbose and compact output mid-conversation — debug mode when you need it, clean mode when you don't
📋 Full changelog: github.com/QwenLM/qwen-code/releases
Qwen
@Alibaba_Qwen
Cron Jobs — AI That Works on a Schedule
Tell Qwen Code "check if tests pass every 30 minutes" and it sets up a cron job in your session.
No crontab editing, no scripts to write.
Use /loop commend. Works for monitoring, periodic builds, log watching — anything repetitive.
Enable in ~/.qwen/settings.json:
{ "experimental": { "cron": true } }
Qwen
@Alibaba_Qwen
Sub-agent Model Selection — Different Tasks, Different Models
Your main agent runs Qwen3.6-Plus for quality. But not every subtask needs a flagship model.
Now sub-agents can use a different model. Create a skill file with model: openai:qwen3.5-plus and the sub-agent runs on that model. Powerful model for the hard parts, fast model for the easy parts.
Save tokens without sacrificing quality on what matters.
Qwen
@Alibaba_Qwen
🚀🚀
OpenRouter
@OpenRouter
Qwen3.6-Plus free trial has ended, and is now live and production ready!
Set it up by using the qwen/qwen3.6-plus slug, and enjoy a 35% discount on OpenRouter:
 Qwen
@Alibaba_Qwen
🏆 Qwen3.6-Plus just swept OpenRouter’s Daily, Weekly & Trending charts!
The trial has wrapped. The model is fully live & production-ready.
📉 Lower latency | 🔥 Top-tier reasoning | 💰 Unmatched $/token value
Keep shipping. Integrate now 👇
🔗 Model Studio:modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
🔗 OpenRouter: openrouter.ai/qwen/qwen3.6-plus
🔗 Fireworks AI: fireworks.ai/models/fireworks/qwen3p6-plus
#openrouter #qwen #alibabacloud #ai
 Qwen
@Alibaba_Qwen
Qwen3.6-Plus ranks # 1 on @OpenRouter , and the first model on OpenRouter to break 1 Trillion tokens processed in a single day!!🥇🔥
We are thrilled to see Qwen3.6-Plus topping the charts so quickly. This milestone wouldn't be possible without our amazing developers. ❤️Thank you!!
OpenRouter
@OpenRouter
Qwen 3.6 Plus from @Alibaba_Qwen is officially the first model on OpenRouter to break 1 Trillion tokens processed in a single day!
At ~1,400,000,000,000 tokens, it’s the strongest full day performance of any new model dropped this year. Congrats to the Qwen team!

Qwen reposted
OpenRouter
@OpenRouter
Qwen 3.6 Plus from @Alibaba_Qwen is officially the first model on OpenRouter to break 1 Trillion tokens processed in a single day!
At ~1,400,000,000,000 tokens, it’s the strongest full day performance of any new model dropped this year. Congrats to the Qwen team!
Qwen
@Alibaba_Qwen
👏👏Improved a lot on running a business over long time horizons.😂🤣 @andonlabs
 Andon Labs
@andonlabs
Qwen 3.6 Plus is 6th on Vending-Bench 2.
> The best Chinese model
> An astonishing improvement over the previous version (Qwen 3.5 Plus went bankrupt)
> Chinese models are now 142 days behind the west
> Pareto Optimal for Cost vs. Score
 Qwen
@Alibaba_Qwen
Strategic Partnership Launch:
Qwen 3.6-Plus Debuts on fireworks.ai
Fireworks is known for its proven track record of serving state-of-the-art models at best-in-class performance and cost across the industry.
We're thrilled to announce a landmark collaboration between Alibaba Qwen and Fireworks — bringing Qwen's flagship model to Fireworks' high-performance inference platform.
Qwen3.6-Plus will be soon available on Fireworks AI for inference and fine-tuning, featuring:
● Industry-leading inference performance and cost efficiency powered by Fireworks' optimized serving stack
● Fine-tuning support to customize Qwen3.6-Plus for your specific use cases
Built for scale, engineered for speed. US and global developers: your access is coming soon. Stay tuned!
@FireworksAI_HQ
 Qwen
@Alibaba_Qwen
Qwen3.6-Plus is officially live on @OpenRouter .🚀
Go try it out and let us know what you think.
Can't wait to hear your feedback! ❤️❤️
👇👇
openrouter.ai/qwen/qwen3.6-plus:free
OpenRouter
@OpenRouter
Qwen 3.6 Plus from @Alibaba_Qwen is live now on OpenRouter, for free!
Prompts and completions are not retained during this period. Use it in all your favorite apps!
1M context, multimodal, agentic.
 Qwen
@Alibaba_Qwen
🚀🚀Let's go!!
Qwen
@Alibaba_Qwen
#8 in Coding in Code Arena overall,#2 Lab in Code Arena on the React leaderboard! !👏👏
This is a great testament to our leap in agentic coding🚀
Ready to experience some next-level ✨Vibe Coding✨?@arena
Arena.ai
@arena
Qwen 3.6 Plus Preview is now #8 in Code Arena overall.
This makes @Alibaba_Qwen the #2 lab in Code Arena on the React leaderboard, as it demonstrates strength in agentic coding tasks involving multi-step reasoning, tool use and multi-file apps.
Congrats to the @Alibaba_Qwen team!
 Qwen
@Alibaba_Qwen
(1/8)🚀 Introducing Qwen3.6-Plus: Towards Real-World Agents! 🤖
Today, we’re thrilled to drop a major milestone in our journey toward native multimodal agents.
Here is what makes Qwen3.6-Plus a game-changer:
💻 Next-level Agentic Coding: Smarter, faster execution.
👁️ Enhanced Multimodal Vision: Sharper perception & reasoning.
🏆 Top-tier Performance: Maintaining leading general capabilities.
📚 1M Context Window: Available by default via our API.
Built on your invaluable feedback from the Qwen3.5 era, we’re laying a rock-solid foundation for real-world devs. Get ready to experience truly transformative ✨ Vibe Coding ✨.
Huge thanks to our community! Go try it out and show us what you can build. 👇
Chat: chat.qwen.ai
API: modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
Blog: qwen.ai/blog?id=qwen3.6
🔔Noted:More Qwen3.6 models to come and be open-sourced! Stay tuned~ 👀#qwen #ai #agenticcoding #vibecoding #agents
 Qwen
@Alibaba_Qwen
Qwen3.6-Plus is live on Qoder now . 🚀Let's code together @qoder_ai_ide .💻
Qoder
@qoder_ai_ide
Congrats @Alibaba_Qwen on the Qwen3.6-Plus launch!
Already live on Qoder.
- 1M context.
- Always-on reasoning.
- 0.2x pricing.
Flagship performance, unbeatable value.
 Qwen
@Alibaba_Qwen
(3/8)VLM Performance
 Qwen
@Alibaba_Qwen
(1/8)🚀 Introducing Qwen3.6-Plus: Towards Real-World Agents! 🤖
Today, we’re thrilled to drop a major milestone in our journey toward native multimodal agents.
Here is what makes Qwen3.6-Plus a game-changer:
💻 Next-level Agentic Coding: Smarter, faster execution.
👁️ Enhanced Multimodal Vision: Sharper perception & reasoning.
🏆 Top-tier Performance: Maintaining leading general capabilities.
📚 1M Context Window: Available by default via our API.
Built on your invaluable feedback from the Qwen3.5 era, we’re laying a rock-solid foundation for real-world devs. Get ready to experience truly transformative ✨ Vibe Coding ✨.
Huge thanks to our community! Go try it out and show us what you can build. 👇
Chat: chat.qwen.ai
API: modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
Blog: qwen.ai/blog?id=qwen3.6
🔔Noted:More Qwen3.6 models to come and be open-sourced! Stay tuned~ 👀#qwen #ai #agenticcoding #vibecoding #agents
Qwen
@Alibaba_Qwen
(2/8)LM Performance
 Qwen
@Alibaba_Qwen
(1/8)🚀 Introducing Qwen3.6-Plus: Towards Real-World Agents! 🤖
Today, we’re thrilled to drop a major milestone in our journey toward native multimodal agents.
Here is what makes Qwen3.6-Plus a game-changer:
💻 Next-level Agentic Coding: Smarter, faster execution.
👁️ Enhanced Multimodal Vision: Sharper perception & reasoning.
🏆 Top-tier Performance: Maintaining leading general capabilities.
📚 1M Context Window: Available by default via our API.
Built on your invaluable feedback from the Qwen3.5 era, we’re laying a rock-solid foundation for real-world devs. Get ready to experience truly transformative ✨ Vibe Coding ✨.
Huge thanks to our community! Go try it out and show us what you can build. 👇
Chat: chat.qwen.ai
API: modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
Blog: qwen.ai/blog?id=qwen3.6
🔔Noted:More Qwen3.6 models to come and be open-sourced! Stay tuned~ 👀#qwen #ai #agenticcoding #vibecoding #agents
Qwen
@Alibaba_Qwen
(1/8)🚀 Introducing Qwen3.6-Plus: Towards Real-World Agents! 🤖
Today, we’re thrilled to drop a major milestone in our journey toward native multimodal agents.
Here is what makes Qwen3.6-Plus a game-changer:
💻 Next-level Agentic Coding: Smarter, faster execution.
👁️ Enhanced Multimodal Vision: Sharper perception & reasoning.
🏆 Top-tier Performance: Maintaining leading general capabilities.
📚 1M Context Window: Available by default via our API.
Built on your invaluable feedback from the Qwen3.5 era, we’re laying a rock-solid foundation for real-world devs. Get ready to experience truly transformative ✨ Vibe Coding ✨.
Huge thanks to our community! Go try it out and show us what you can build. 👇
Chat: chat.qwen.ai
API: modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
Blog: qwen.ai/blog?id=qwen3.6
🔔Noted:More Qwen3.6 models to come and be open-sourced! Stay tuned~ 👀#qwen #ai #agenticcoding #vibecoding #agents
Qwen
@Alibaba_Qwen
(8/8)Computer-Using Agent:
Prompt: Create a list of drip coffee makers that are on sale and within $25-60 and have a black finish.
Qwen
@Alibaba_Qwen
(7/8)ClaudeCode:Flight Game
Qwen APIs also support the Anthropic API protocol, meaning you can use it with tools like Claude Code for elevated coding experience.
Qwen
@Alibaba_Qwen
(6/8)QwenCode:Letter Flying
Qwen3.6-Plus is compatible with Qwen Code. It helps you understand complex codebases, automate tedious work, and ship faster.
Qwen
@Alibaba_Qwen
(5/8)OpenClaw:Personal Schedule Management
Qwen3.6-Plus is compatible with OpenClaw (formerly Moltbot / Clawdbot). Here's the demo of Personal Schedule Management.
Qwen
@Alibaba_Qwen
(4/8)Web Dev:Designer Personal Site
Prompt:Design a personal website for a designer who received an Awwwards nomination, featuring large areas of white space, oversized serif font titles, a custom cursor that follows the mouse, perspective-shifting images in the portfolio area when the mouse hovers over them, parallax effects on text as the page scrolls, and a color scheme of only black and white with a bright orange accent.
Qwen
@Alibaba_Qwen
Congratulations to the GrandCode team on this remarkable achievement!👏
The last stronghold of coding has been conquered, and we are incredibly proud that Qwen is the engine behind it! 💻🔥
This is a real milestone moment for coding intelligence and a fascinating example of how far agentic RL systems have come.
The pace of AI progress is truly mind-blowing. Stay tuned .🌍✨
 Chris Shum
@chris_shum_
The last stronghold of coding has just been conquered by AI.
In the most recent three Codeforces live competitions, i.e., Round 1087, Round 1088, and Round 1089, GrandCode, our agentic AI system, ranked first in all of them, beating all human participants, including legendary grandmasters.
GrandCode is a multi-agent reinforcement learning system designed for competitive programming. It orchestrates a variety of agentic modules (hypothesis proposal, solver, test generator, summarization, etc) and jointly improves them through post-training and online test-time RL. GrandCode is developed based on Qwen. Huge respect to the Qwen @Alibaba_Qwen team for their contributions to the community.
It is hard to imagine how quickly AI has advanced in just one year:
1st — GrandCode (March 2026)
8th — Gemini 3.1 Pro (February 2026)
175th — OpenAI o3 (April 2025)
We can’t wait to see what happens over the next year.
 Qwen
@Alibaba_Qwen
Our new model is now live on OpenRouter for an early preview, go give it a try! Looking forward to your feedback~😎
OpenRouter
@OpenRouter
Qwen 3.6 Plus Preview from @Alibaba_Qwen is live now for free for a limited time on OpenRouter!
During this free period, prompts and completions will be collected and may be used to improve the model.
 Qwen
@Alibaba_Qwen
Here's another demo of Audio-Visual Vibe Coding~
Qwen
@Alibaba_Qwen
Demo2:Audio-Visual Vibe Coding
Qwen
@Alibaba_Qwen
🚀 Qwen3.5-Omni is here! Scaling up to a native omni-modal AGI.
Meet the next generation of Qwen, designed for native text, image, audio, and video understanding, with major advances in both intelligence and real-time interaction.
A standout feature: 'Audio-Visual Vibe Coding'. Describe your vision to the camera, and Qwen3.5-Omni-Plus instantly builds a functional website or game for you.
Offline Highlights:
🎬 Script-Level Captioning: Generate detailed video scripts with timestamps, scene cuts & speaker mapping.
🏆 SOTA Performance: Outperform Gemini-3.1 Pro in audio and matches its audio-visual understanding.
🧠 Massive Capacity: Natively handle up to 10h of audio or 400s of 720p video, trained on 100M+ hours of data.
🌍 Global Reach: Recognize 113 languages (speech) & speaks 36.
Real-time Features:
🎙️ Fine-Grained Voice Control: Adjust emotion, pace, and volume in real-time.
🔍 Built-in Web Search & complex function calling.
👤 Voice Cloning: Customize your AI's voice from a short sample, with engineering rollout coming soon.
💬 Human-like Conversation: Smart turn-taking that understands real intent and ignores noise.
The Qwen3.5-Omni family includes Plus, Flash, and Light variants.
Try it out:
Blog: qwen.ai/blog?id=qwen3.5-omni
Realtime Interaction: click the VoiceChat/VideoChat button (bottom-right): chat.qwen.ai
HF-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Offline-Demo
HF-VoiceOnline-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Online-Demo
API-Offline: www.alibabacloud.com/help/en/model-studio/qwen-omni
API-Realtime: www.alibabacloud.com/help/en/model-studio/realtime
 Qwen
@Alibaba_Qwen
Demo5: Voice Style, Emotion and Volume Control
Qwen
@Alibaba_Qwen
🚀 Qwen3.5-Omni is here! Scaling up to a native omni-modal AGI.
Meet the next generation of Qwen, designed for native text, image, audio, and video understanding, with major advances in both intelligence and real-time interaction.
A standout feature: 'Audio-Visual Vibe Coding'. Describe your vision to the camera, and Qwen3.5-Omni-Plus instantly builds a functional website or game for you.
Offline Highlights:
🎬 Script-Level Captioning: Generate detailed video scripts with timestamps, scene cuts & speaker mapping.
🏆 SOTA Performance: Outperform Gemini-3.1 Pro in audio and matches its audio-visual understanding.
🧠 Massive Capacity: Natively handle up to 10h of audio or 400s of 720p video, trained on 100M+ hours of data.
🌍 Global Reach: Recognize 113 languages (speech) & speaks 36.
Real-time Features:
🎙️ Fine-Grained Voice Control: Adjust emotion, pace, and volume in real-time.
🔍 Built-in Web Search & complex function calling.
👤 Voice Cloning: Customize your AI's voice from a short sample, with engineering rollout coming soon.
💬 Human-like Conversation: Smart turn-taking that understands real intent and ignores noise.
The Qwen3.5-Omni family includes Plus, Flash, and Light variants.
Try it out:
Blog: qwen.ai/blog?id=qwen3.5-omni
Realtime Interaction: click the VoiceChat/VideoChat button (bottom-right): chat.qwen.ai
HF-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Offline-Demo
HF-VoiceOnline-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Online-Demo
API-Offline: www.alibabacloud.com/help/en/model-studio/qwen-omni
API-Realtime: www.alibabacloud.com/help/en/model-studio/realtime
Qwen
@Alibaba_Qwen
Demo4 :Multi-Turn Dialogue and Intelligent Interruption
Qwen
@Alibaba_Qwen
🚀 Qwen3.5-Omni is here! Scaling up to a native omni-modal AGI.
Meet the next generation of Qwen, designed for native text, image, audio, and video understanding, with major advances in both intelligence and real-time interaction.
A standout feature: 'Audio-Visual Vibe Coding'. Describe your vision to the camera, and Qwen3.5-Omni-Plus instantly builds a functional website or game for you.
Offline Highlights:
🎬 Script-Level Captioning: Generate detailed video scripts with timestamps, scene cuts & speaker mapping.
🏆 SOTA Performance: Outperform Gemini-3.1 Pro in audio and matches its audio-visual understanding.
🧠 Massive Capacity: Natively handle up to 10h of audio or 400s of 720p video, trained on 100M+ hours of data.
🌍 Global Reach: Recognize 113 languages (speech) & speaks 36.
Real-time Features:
🎙️ Fine-Grained Voice Control: Adjust emotion, pace, and volume in real-time.
🔍 Built-in Web Search & complex function calling.
👤 Voice Cloning: Customize your AI's voice from a short sample, with engineering rollout coming soon.
💬 Human-like Conversation: Smart turn-taking that understands real intent and ignores noise.
The Qwen3.5-Omni family includes Plus, Flash, and Light variants.
Try it out:
Blog: qwen.ai/blog?id=qwen3.5-omni
Realtime Interaction: click the VoiceChat/VideoChat button (bottom-right): chat.qwen.ai
HF-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Offline-Demo
HF-VoiceOnline-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Online-Demo
API-Offline: www.alibabacloud.com/help/en/model-studio/qwen-omni
API-Realtime: www.alibabacloud.com/help/en/model-studio/realtime
Qwen
@Alibaba_Qwen
Demo3:Travel Planning
Qwen
@Alibaba_Qwen
🚀 Qwen3.5-Omni is here! Scaling up to a native omni-modal AGI.
Meet the next generation of Qwen, designed for native text, image, audio, and video understanding, with major advances in both intelligence and real-time interaction.
A standout feature: 'Audio-Visual Vibe Coding'. Describe your vision to the camera, and Qwen3.5-Omni-Plus instantly builds a functional website or game for you.
Offline Highlights:
🎬 Script-Level Captioning: Generate detailed video scripts with timestamps, scene cuts & speaker mapping.
🏆 SOTA Performance: Outperform Gemini-3.1 Pro in audio and matches its audio-visual understanding.
🧠 Massive Capacity: Natively handle up to 10h of audio or 400s of 720p video, trained on 100M+ hours of data.
🌍 Global Reach: Recognize 113 languages (speech) & speaks 36.
Real-time Features:
🎙️ Fine-Grained Voice Control: Adjust emotion, pace, and volume in real-time.
🔍 Built-in Web Search & complex function calling.
👤 Voice Cloning: Customize your AI's voice from a short sample, with engineering rollout coming soon.
💬 Human-like Conversation: Smart turn-taking that understands real intent and ignores noise.
The Qwen3.5-Omni family includes Plus, Flash, and Light variants.
Try it out:
Blog: qwen.ai/blog?id=qwen3.5-omni
Realtime Interaction: click the VoiceChat/VideoChat button (bottom-right): chat.qwen.ai
HF-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Offline-Demo
HF-VoiceOnline-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Online-Demo
API-Offline: www.alibabacloud.com/help/en/model-studio/qwen-omni
API-Realtime: www.alibabacloud.com/help/en/model-studio/realtime
Qwen
@Alibaba_Qwen
Demo2:Audio-Visual Vibe Coding
Qwen
@Alibaba_Qwen
🚀 Qwen3.5-Omni is here! Scaling up to a native omni-modal AGI.
Meet the next generation of Qwen, designed for native text, image, audio, and video understanding, with major advances in both intelligence and real-time interaction.
A standout feature: 'Audio-Visual Vibe Coding'. Describe your vision to the camera, and Qwen3.5-Omni-Plus instantly builds a functional website or game for you.
Offline Highlights:
🎬 Script-Level Captioning: Generate detailed video scripts with timestamps, scene cuts & speaker mapping.
🏆 SOTA Performance: Outperform Gemini-3.1 Pro in audio and matches its audio-visual understanding.
🧠 Massive Capacity: Natively handle up to 10h of audio or 400s of 720p video, trained on 100M+ hours of data.
🌍 Global Reach: Recognize 113 languages (speech) & speaks 36.
Real-time Features:
🎙️ Fine-Grained Voice Control: Adjust emotion, pace, and volume in real-time.
🔍 Built-in Web Search & complex function calling.
👤 Voice Cloning: Customize your AI's voice from a short sample, with engineering rollout coming soon.
💬 Human-like Conversation: Smart turn-taking that understands real intent and ignores noise.
The Qwen3.5-Omni family includes Plus, Flash, and Light variants.
Try it out:
Blog: qwen.ai/blog?id=qwen3.5-omni
Realtime Interaction: click the VoiceChat/VideoChat button (bottom-right): chat.qwen.ai
HF-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Offline-Demo
HF-VoiceOnline-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Online-Demo
API-Offline: www.alibabacloud.com/help/en/model-studio/qwen-omni
API-Realtime: www.alibabacloud.com/help/en/model-studio/realtime
Qwen
@Alibaba_Qwen
Demo1:Audio-Visual Captioning
Qwen
@Alibaba_Qwen
🚀 Qwen3.5-Omni is here! Scaling up to a native omni-modal AGI.
Meet the next generation of Qwen, designed for native text, image, audio, and video understanding, with major advances in both intelligence and real-time interaction.
A standout feature: 'Audio-Visual Vibe Coding'. Describe your vision to the camera, and Qwen3.5-Omni-Plus instantly builds a functional website or game for you.
Offline Highlights:
🎬 Script-Level Captioning: Generate detailed video scripts with timestamps, scene cuts & speaker mapping.
🏆 SOTA Performance: Outperform Gemini-3.1 Pro in audio and matches its audio-visual understanding.
🧠 Massive Capacity: Natively handle up to 10h of audio or 400s of 720p video, trained on 100M+ hours of data.
🌍 Global Reach: Recognize 113 languages (speech) & speaks 36.
Real-time Features:
🎙️ Fine-Grained Voice Control: Adjust emotion, pace, and volume in real-time.
🔍 Built-in Web Search & complex function calling.
👤 Voice Cloning: Customize your AI's voice from a short sample, with engineering rollout coming soon.
💬 Human-like Conversation: Smart turn-taking that understands real intent and ignores noise.
The Qwen3.5-Omni family includes Plus, Flash, and Light variants.
Try it out:
Blog: qwen.ai/blog?id=qwen3.5-omni
Realtime Interaction: click the VoiceChat/VideoChat button (bottom-right): chat.qwen.ai
HF-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Offline-Demo
HF-VoiceOnline-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Online-Demo
API-Offline: www.alibabacloud.com/help/en/model-studio/qwen-omni
API-Realtime: www.alibabacloud.com/help/en/model-studio/realtime
Qwen
@Alibaba_Qwen
🚀 Qwen3.5-Omni is here! Scaling up to a native omni-modal AGI.
Meet the next generation of Qwen, designed for native text, image, audio, and video understanding, with major advances in both intelligence and real-time interaction.
A standout feature: 'Audio-Visual Vibe Coding'. Describe your vision to the camera, and Qwen3.5-Omni-Plus instantly builds a functional website or game for you.
Offline Highlights:
🎬 Script-Level Captioning: Generate detailed video scripts with timestamps, scene cuts & speaker mapping.
🏆 SOTA Performance: Outperform Gemini-3.1 Pro in audio and matches its audio-visual understanding.
🧠 Massive Capacity: Natively handle up to 10h of audio or 400s of 720p video, trained on 100M+ hours of data.
🌍 Global Reach: Recognize 113 languages (speech) & speaks 36.
Real-time Features:
🎙️ Fine-Grained Voice Control: Adjust emotion, pace, and volume in real-time.
🔍 Built-in Web Search & complex function calling.
👤 Voice Cloning: Customize your AI's voice from a short sample, with engineering rollout coming soon.
💬 Human-like Conversation: Smart turn-taking that understands real intent and ignores noise.
The Qwen3.5-Omni family includes Plus, Flash, and Light variants.
Try it out:
Blog: qwen.ai/blog?id=qwen3.5-omni
Realtime Interaction: click the VoiceChat/VideoChat button (bottom-right): chat.qwen.ai
HF-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Offline-Demo
HF-VoiceOnline-Demo: huggingface.co/spaces/Qwen/Qwen3.5-Omni-Online-Demo
API-Offline: www.alibabacloud.com/help/en/model-studio/qwen-omni
API-Realtime: www.alibabacloud.com/help/en/model-studio/realtime
Qwen
@Alibaba_Qwen
Big thanks to Steve for testing the entire Qwen3.5 family. Community feedback like this helps us get better. 🙏
 stevibe
@stevibe
Which local models can actually handle tool calling?
I built a framework to find out.
15 scenarios. 12 tools. Mocked responses. Temperature 0. No cherry-picking.
Tested every Qwen3.5 size from 0.8B to 397B, and since some of you asked after the distillation tests: yes, I included Jackrong's Qwen3.5-27B-Claude-4.6-Opus-Reasoning-Distilled too.
Only two models went all green: the 27B dense and the distilled 27B.
The 397B? Failed two tests. The 122B? Failed one. The 35B? Failed two.
The timed-out results — mostly on the smaller models, are cases where the model got stuck in a loop, repeating the same tool call until it hit the 30-second limit.
The test that exposed the most models: "Search for Iceland's population, then calculate 2% of it." Simple, but 35B, 122B, and 397B all used a rounded number from memory instead of the actual search result. They didn't trust their own tool output.
Small models hallucinate data.
Big models ignore data.
The 27B just threaded it through.
Qwen reposted
Arena.ai
@arena
With the preview of Qwen 3.5 Max Preview by @Alibaba_Qwen, we’re looking back at past Qwen Max variants to see how far it has progressed.
Where Qwen 3.5 Max sees the largest gains vs. Qwen 3 Max:
- Text Overall (+45pts)
- Creative Writing (+57pts)
- Math (+49pts)
- Entertainment, Sports & Media (+48pts)
- Writing, Literature & Language (+45pts)
This a vast improvement overall across all categories since Qwen 2.5 Max.
 Arena.ai
@arena
Qwen 3.5 Max Preview has landed in top 10 for Arena Expert and top 15 for Text Arena.
It shows particular strength in Math.
Highlights:
- #3 Math
- #10 Expert
- #15 Text Arena
- Top 20 for Writing, Literature & Language, Life, Physical, & Social Science, Entertainment, Sports, & Media, and Medicine & Healthcare
Congrats to the @Alibaba_Qwen team for this new milestone!
 Qwen
@Alibaba_Qwen
Pretty proud of this one! 😎 Qwen 3.5 Max Preview just hit #3 in Math, Top 10 in Arena Expert, and Top 15 overall!
We're already back in the lab optimizing the preview experience. Even sharper performance coming soon—stay tuned! 🚀
Arena.ai
@arena
Qwen 3.5 Max Preview has landed in top 10 for Arena Expert and top 15 for Text Arena.
It shows particular strength in Math.
Highlights:
- #3 Math
- #10 Expert
- #15 Text Arena
- Top 20 for Writing, Literature & Language, Life, Physical, & Social Science, Entertainment, Sports, & Media, and Medicine & Healthcare
Congrats to the @Alibaba_Qwen team for this new milestone!
Qwen
@Alibaba_Qwen
🔥 Qwen 3.5 Series GPTQ-Int4 weights are live.
Native vLLM & SGLang support.
⚡️ Less VRAM. Faster inference.
Run powerful models on limited-GPU setups.
👇 Grab the weights + example code:
Hugging Face:
huggingface.co/collections/Qwen/qwen35
ModelScope:
modelscope.cn/collections/Qwen/Qwen35
Qwen
@Alibaba_Qwen
Qwen3.5-9B is now available on LM Studio. Requires only ~7GB to run locally 🤯
LM Studio
@lmstudio
Qwen3.5-9B is an incredibly strong little model you can download and run on your computer.
It can takes images as input, can think, and call tools.
Requires only ~7GB to run locally 🤯🚀
lmstudio.ai/models/qwen/qwen3.5-9b
Qwen
@Alibaba_Qwen
qwen 3.5 small · already on mlx
 Prince Canuma
@Prince_Canuma
already on mlx :)
 Qwen
@Alibaba_Qwen
🚀 Introducing the Qwen 3.5 Small Model Series
Qwen3.5-0.8B · Qwen3.5-2B · Qwen3.5-4B · Qwen3.5-9B
✨ More intelligence, less compute.
These small models are built on the same Qwen3.5 foundation — native multimodal, improved architecture, scaled RL:
• 0.8B / 2B → tiny, fast, great for edge device
• 4B → a surprisingly strong multimodal base for lightweight agents
• 9B → compact, but already closing the gap with much larger models
And yes — we’re also releasing the Base models as well.
We hope this better supports research, experimentation, and real-world industrial innovation.
Hugging Face: huggingface.co/collections/Qwen/qwen35
ModelScope: modelscope.cn/collections/Qwen/Qwen35
 Qwen
@Alibaba_Qwen
The Qwen 3.5 small model series is now available on Ollama.
ollama
@ollama
The Qwen 3.5 small model series is now available
ollama run qwen3.5:9b
ollama run qwen3.5:4b
ollama run qwen3.5:2b
ollama run qwen3.5:0.8b
All models support native tool calling, thinking, and multimodal capabilities in Ollama.
Qwen
@Alibaba_Qwen
🚀 Introducing the Qwen 3.5 Small Model Series
Qwen3.5-0.8B · Qwen3.5-2B · Qwen3.5-4B · Qwen3.5-9B
✨ More intelligence, less compute.
These small models are built on the same Qwen3.5 foundation — native multimodal, improved architecture, scaled RL:
• 0.8B / 2B → tiny, fast, great for edge device
• 4B → a surprisingly strong multimodal base for lightweight agents
• 9B → compact, but already closing the gap with much larger models
And yes — we’re also releasing the Base models as well.
We hope this better supports research, experimentation, and real-world industrial innovation.
Hugging Face: huggingface.co/collections/Qwen/qwen35
ModelScope: modelscope.cn/collections/Qwen/Qwen35
Qwen
@Alibaba_Qwen
🚀 Introducing the Qwen 3.5 Small Model Series
Qwen3.5-0.8B · Qwen3.5-2B · Qwen3.5-4B · Qwen3.5-9B
✨ More intelligence, less compute.
These small models are built on the same Qwen3.5 foundation — native multimodal, improved architecture, scaled RL:
• 0.8B / 2B → tiny, fast, great for edge device
• 4B → a surprisingly strong multimodal base for lightweight agents
• 9B → compact, but already closing the gap with much larger models
And yes — we’re also releasing the Base models as well.
We hope this better supports research, experimentation, and real-world industrial innovation.
Hugging Face: huggingface.co/collections/Qwen/qwen35
ModelScope: modelscope.cn/collections/Qwen/Qwen35
Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
Appreciate the support from @kilocode ! 🙌
Qwen is moving even faster.
Looking forward to building more together.
 Kilo (acq. by Anaconda)
@kilocode
Just a few of the new @Alibaba_Qwen models live in Kilo. Qwen is moving so fast we can barely keep up! 😅😅😅
 Qwen
@Alibaba_Qwen
💪 Big thanks to @UnslothAI for GGUFs, now is the time to get started with local models!
Unsloth AI
@UnslothAI
Qwen3.5 is now updated with improved tool-calling & coding performance!
Run Qwen3.5-35B-A3B on 22GB RAM.
See improvements via Claude Code, Codex.
We also benchmarked GGUFs & removed MXFP4 layers from 3 quants.
GGUFs: huggingface.co/unsloth/Qwen3.5-35B-A3B-GGUF
Analysis: unsloth.ai/docs/models/qwen3.5/gguf-benchmarks
 Qwen
@Alibaba_Qwen
Big thanks to @NVIDIAAIDev 🚀 — can’t wait to see what builders create!
 NVIDIA AI Developer
@NVIDIAAIDev
✨ Qwen3.5 — new from @Alibaba_Qwen — introduces a frontier‑class VLM built for native multimodal agents.
With a ~400B‑parameter architecture combining MoE and Gated Delta Networks, Qwen3.5 can reason across text, code, and vision — and even understand and navigate user interfaces.
Learn how to:
✅ Run Qwen3.5 on free NVIDIA GPU endpoints
✅ Deploy with NIM
✅ Fine‑tune using NVIDIA NeMo
See the details in our technical blog ➡️ developer.nvidia.com/blog/develop-native-multimodal-agent…

Qwen reposted
 Novita AI
@novita_labs
🚀Qwen 3.5 Medium Series is live on Novita
Qwen3.5-35B-A3B, Qwen3.5-122B-A10B, and Qwen3.5-27B. Multimodal hybrid reasoning LLMs from @Alibaba_Qwen that punch above their size.
Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B.
Try them now 👇
35B-A3B: novita.ai/models/model-detail/qwen-qwen3.5-35b-a3b
122B-A10B: novita.ai/models/model-detail/qwen-qwen3.5-122b-a10b
27B: novita.ai/models/model-detail/qwen-qwen3.5-27b
 Qwen
@Alibaba_Qwen
Huge thanks to MLX! Qwen3.5 now runs on MLX-VLM from day-0!🙌
Prince Canuma
@Prince_Canuma
The new Qwen3.5 by @Alibaba_Qwen have day-0 support on MLX-VLM 🚀
 Qwen
@Alibaba_Qwen
This is wild! Eigent × Qwen3.5-Plus makes "video-to-game" so much fun. 🎮
 Eigent AI
@Eigent_AI
Eigent × @Alibaba_Qwen 3.5 Plus
We upload a Spring Festival Gala robot performance video and ask our open source Cowork, powered by Qwen 3.5 Plus, to turn it into a complete single-file 3D interactive Three.js game. Recreates the characters, movements, and festive stage.
Full Eigent breakdown in the video.👇
Now live with BYOK, bring your own Qwen 3.5 Plus key and run it directly in Eigent.
Qwen
@Alibaba_Qwen
🔥 Qwen 3.5 Medium Model Series FP8 weights are now open and ready for deployment! Native support for vLLM and SGLang. Check the model card for example code.
⚡️ Optimize your workflow with FP8 precision.
👇 Get the weights:
Hugging Face:huggingface.co/collections/Qwen/qwen35
ModelScope:modelscope.cn/collections/Qwen/Qwen35
Qwen
@Alibaba_Qwen
Qwen3.5-35B-A3B is now in Jan 🔥
 👋 Jan
@jandotai
Qwen3.5-35B-A3B is now in Jan 🔥
It surpasses previous Qwen3 models more than 6× its size.
Get the latest Jan at jan.ai
Thanks to @Alibaba_Qwen for the base model and @ggerganov for llama.cpp 💛
Qwen
@Alibaba_Qwen
Ollama now supports Qwen 3.5 Medium Model Series!🚀
ollama
@ollama
Qwen 3.5 family is here!
> vision built-in, and can outperform previous VL models
> designed to be more efficient
> expanded support for more languages
35B: (fits on 24GB+ system)
ollama run qwen3.5:35b
122B:
ollama run qwen3.5:122b
397B (cloud only):
ollama run qwen3.5:397b-cloud
 Qwen
@Alibaba_Qwen
🚀 Introducing the Qwen 3.5 Medium Model Series
Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B
✨ More intelligence, less compute.
• Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts.
• Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios.
• Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring:
– 1M context length by default
– Official built-in tools
🔗 Hugging Face: huggingface.co/collections/Qwen/qwen35
🔗 ModelScope: modelscope.cn/collections/Qwen/Qwen35
🔗 Qwen3.5-Flash API: modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Try in Qwen Chat 👇
Flash: chat.qwen.ai?models=qwen3.5-flash
27B: chat.qwen.ai?models=qwen3.5-27b
35B-A3B: chat.qwen.ai?models=qwen3.5-35b-a3b
122B-A10B: chat.qwen.ai?models=qwen3.5-122b-a10b
Would love to hear what you build with it.
 Qwen
@Alibaba_Qwen
The Qwen3.5 series maintains near-lossless accuracy under 4-bit weight and KV cache quantization.
In terms of long-context efficiency:
Qwen3.5-27B supports 800K+ context length
Qwen3.5-35B-A3B exceeds 1M context on consumer-grade GPUs with 32GB VRAM
Qwen3.5-122B-A10B supports 1M+ context length on server-grade GPUs with 80GB VRAM
In addition, we have open-sourced the Qwen3.5-35B-A3B-Base model to better support research and innovation.
We can't wait to see what the community builds next!
Qwen
@Alibaba_Qwen
🚀 Introducing the Qwen 3.5 Medium Model Series
Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B
✨ More intelligence, less compute.
• Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts.
• Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios.
• Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring:
– 1M context length by default
– Official built-in tools
🔗 Hugging Face: huggingface.co/collections/Qwen/qwen35
🔗 ModelScope: modelscope.cn/collections/Qwen/Qwen35
🔗 Qwen3.5-Flash API: modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Try in Qwen Chat 👇
Flash: chat.qwen.ai?models=qwen3.5-flash
27B: chat.qwen.ai?models=qwen3.5-27b
35B-A3B: chat.qwen.ai?models=qwen3.5-35b-a3b
122B-A10B: chat.qwen.ai?models=qwen3.5-122b-a10b
Would love to hear what you build with it.
Qwen
@Alibaba_Qwen
🚀 Introducing the Qwen 3.5 Medium Model Series
Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B
✨ More intelligence, less compute.
• Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts.
• Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios.
• Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring:
– 1M context length by default
– Official built-in tools
🔗 Hugging Face: huggingface.co/collections/Qwen/qwen35
🔗 ModelScope: modelscope.cn/collections/Qwen/Qwen35
🔗 Qwen3.5-Flash API: modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Try in Qwen Chat 👇
Flash: chat.qwen.ai?models=qwen3.5-flash
27B: chat.qwen.ai?models=qwen3.5-27b
35B-A3B: chat.qwen.ai?models=qwen3.5-35b-a3b
122B-A10B: chat.qwen.ai?models=qwen3.5-122b-a10b
Would love to hear what you build with it.
Qwen
@Alibaba_Qwen
Vision Language
 Qwen
@Alibaba_Qwen
Language Benchmark
 Qwen
@Alibaba_Qwen
The new Qwen3.5 Medium models are ready to run 🔥
GGUF support is here!
Big thanks to @UnslothAI for making it happen so quickly 🚀
Unsloth AI
@UnslothAI
Run the new Qwen3.5 Medium models! 🔥
- Qwen3.5 35B-A3B (MoE, 24GB RAM)
- Qwen3.5 27B (dense, 18GB)
- Qwen3.5 122B-A10B (MoE, 70GB)
The multimodal hybrid reasoning LLMs are the best performing for their sizes.
GGUFs: huggingface.co/collections/unsloth/qwen35
Guide: unsloth.ai/docs/models/qwen3.5
 Qwen
@Alibaba_Qwen
🚀 Introducing the Qwen 3.5 Medium Model Series
Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B
✨ More intelligence, less compute.
• Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts.
• Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios.
• Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring:
– 1M context length by default
– Official built-in tools
🔗 Hugging Face: huggingface.co/collections/Qwen/qwen35
🔗 ModelScope: modelscope.cn/collections/Qwen/Qwen35
🔗 Qwen3.5-Flash API: modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Try in Qwen Chat 👇
Flash: chat.qwen.ai?models=qwen3.5-flash
27B: chat.qwen.ai?models=qwen3.5-27b
35B-A3B: chat.qwen.ai?models=qwen3.5-35b-a3b
122B-A10B: chat.qwen.ai?models=qwen3.5-122b-a10b
Would love to hear what you build with it.
Qwen
@Alibaba_Qwen
Qwen3.5-35B-A3B is now live in LM Studio 🚀
LM Studio
@lmstudio
Qwen3.5-35B-A3B is now available in LM Studio!
This model outperforms previous Qwen models that are more than 6x its size 🤯🚀
Requires about ~21GB to run locally.
lmstudio.ai/models/qwen/qwen3.5-35b-a3b
Qwen
@Alibaba_Qwen
Huge thanks to the @vllm_project for the Day-0 support on the Qwen3.5 Medium Series 🚀
vLLM
@vllm_project
🎉 Congrats to @Alibaba_Qwen on the Qwen3.5 Medium Model Series — Qwen3.5-35B-A3B, 122B-A10B, and 27B 🚀🚀🚀
More intelligence, less compute — exactly what the open source community loves to see!
Check out our recipe and try them all with vLLM today!
docs.vllm.ai/projects/recipes/en/latest/Qwen/Qwen3.5.html
Qwen
@Alibaba_Qwen
🚀 Introducing the Qwen 3.5 Medium Model Series
Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B
✨ More intelligence, less compute.
• Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts.
• Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios.
• Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring:
– 1M context length by default
– Official built-in tools
🔗 Hugging Face: huggingface.co/collections/Qwen/qwen35
🔗 ModelScope: modelscope.cn/collections/Qwen/Qwen35
🔗 Qwen3.5-Flash API: modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Try in Qwen Chat 👇
Flash: chat.qwen.ai?models=qwen3.5-flash
27B: chat.qwen.ai?models=qwen3.5-27b
35B-A3B: chat.qwen.ai?models=qwen3.5-35b-a3b
122B-A10B: chat.qwen.ai?models=qwen3.5-122b-a10b
Would love to hear what you build with it.
Qwen
@Alibaba_Qwen
✨ Run it now with SGLang!Chong!
LMSYS Org
@lmsysorg
🎉 Congrats to @Alibaba_Qwen on the Qwen 3.5 Medium Series launch! Day-0 supports are now live in SGLang!
We support: Qwen3.5-Flash / Qwen3.5-35B-A3B / Qwen3.5-122B-A10B / Qwen3.5-27B
✨ Run it now with SGLang!
 Qwen
@Alibaba_Qwen
🚀 Introducing the Qwen 3.5 Medium Model Series
Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B
✨ More intelligence, less compute.
• Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts.
• Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios.
• Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring:
– 1M context length by default
– Official built-in tools
🔗 Hugging Face: huggingface.co/collections/Qwen/qwen35
🔗 ModelScope: modelscope.cn/collections/Qwen/Qwen35
🔗 Qwen3.5-Flash API: modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Try in Qwen Chat 👇
Flash: chat.qwen.ai?models=qwen3.5-flash
27B: chat.qwen.ai?models=qwen3.5-27b
35B-A3B: chat.qwen.ai?models=qwen3.5-35b-a3b
122B-A10B: chat.qwen.ai?models=qwen3.5-122b-a10b
Would love to hear what you build with it.
Qwen
@Alibaba_Qwen
Big thanks to @UnslothAI ! Qwen3-Coder-Next is a cost-effective coding agent you can run locally.
Unsloth AI
@UnslothAI
Qwen3-Coder-Next GGUF is now the most downloaded model on Unsloth!
The 80B coding LLM runs on a 36GB RAM Mac / device.
Use via Claude Code and Codex locally.
 Qwen
@Alibaba_Qwen
Following the open-source release of Qwen3-Coder-Next, its API is now available on Alibaba Cloud Model Studio and has also been integrated into the Coding Plan.
For teams and developers who prefer scalable or cost-effective endpoints, you can now access Qwen3-Coder-Next via API.
🔗 API Documentation:
modelstudio.console.alibabacloud.com/ap-southeast-1?tab=doc
🔗 Coding Plan Details:
www.alibabacloud.com/help/en/model-studio/coding-plan
As always, feedback is welcome.
Qwen
@Alibaba_Qwen
Try Qwen3.5-Plus now on Qoder!
Qoder
@qoder_ai_ide
Qoder now supports Qwen3.5-Plus!
Congrats to @Alibaba_Qwen on this launch.
Why Qwen3.5-Plus matters for developers:
- Faster processing, lower cost
- Enhanced coding, reasoning & agent capabilities
- Understands both code & images (screenshots, diagrams, UI mockups)
 Qwen
@Alibaba_Qwen
🚀 Qwen3.5-397B-A17B-FP8 weights are now open!
It took some time to adapt the inference frameworks, but here we are:
✅ SGLang support is merged
🔄 vLLM PR submitted → github.com/vllm-project/vllm/pull/34697
Check the model card for example code. vLLM support landing in the next couple of days!
Hugging Face: huggingface.co/Qwen/Qwen3.5-397B-A17B-FP8
ModelScope: modelscope.cn/models/Qwen/Qwen3.5-397B-A17B-FP8
Qwen
@Alibaba_Qwen
🚀 Qwen Coding Plan is now live on Alibaba Cloud Model Studio!
✨ What you get:
• 🔥 Latest Qwen3.5-Plus models
• 💡 Fixed monthly subscription: from ~$10/mo (Lite) or ~$50/mo (Pro)
• 📦 Up to 90K requests/month for AI-powered coding
• 🔌 Works with Claude Code, Qwen Code, Cline, Cursor & more
• 🔥 Get 50% OFF on Lite & Pro plans with our launch coupon!
🔗 Get started: www.alibabacloud.com/help/en/model-studio/coding-plan
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
OpenClaw is supported as well.🥰
Qwen
@Alibaba_Qwen
Qwen 3.5 Plus is now available on AI Gateway. Thanks @vercel_dev team. 🤝
Use model: 'alibaba/qwen3.5-plus'
Try it now!
 Vercel Developers
@vercel_dev
Qwen 3.5 Plus is now available on AI Gateway.
1 million token context window, built-in adaptive tool use, and strong visual reasoning.
Use 𝚖𝚘𝚍𝚎𝚕: '𝚊𝚕𝚒𝚋𝚊𝚋𝚊/𝚚𝚠𝚎𝚗𝟹.𝟻-𝚙𝚕𝚞𝚜'
Qwen
@Alibaba_Qwen
Qwen3.5-Plus is now on Poe!
 Poe
@poe_platform
Qwen3.5-Plus is live on Poe!
Qwen3.5‑Plus is a native vision‑language model built on a hybrid linear‑attention and sparse MoE architecture for greater inference efficiency. It features a 1M‑token context window, enabling powerful long‑context multimodal reasoning and agent workflows. Compared to Qwen3, it represents a major leap in both pure‑text and multimodal capabilities, performing on par with leading state‑of‑the‑art models.
You can try them in the Poe app on all platforms and in the Poe API at: poe.com/Qwen3.5-Plus
 Qwen
@Alibaba_Qwen
Qwen3.5-397B-A17B is live on @openrouter! ⚡️
Try it now and thank you for the amazing support!
OpenRouter
@OpenRouter
The new @Alibaba_Qwen Qwen3.5-397B-A17B is live on OpenRouter now!
This multimodal model uses a hybrid architecture combining linear attention with sparse MoE for higher inference efficiency.
Available as both the open weights version and Qwen3.5 Plus with extended 1M context.
Qwen reposted
Novita AI
@novita_labs
⚠️ Builders, one more reason to move.
You can now run Qwen3.5-397B-A17B inside Novita Coding Plans 🚀
A flagship open-weight model, ready for real production workloads.
Already includes GLM-5, MiniMax M2.5, and Kimi K2.5 —
one plan. Multiple frontier models. Zero switching cost.
🔥 Lower cost · More tokens
🔓 Monthly billing — cancel anytime
💡 Lite / Pro / Max tiers
⏳ Only 1,000 slots. No extensions.
👉 novita.ai/coding-plan/
Qwen
@Alibaba_Qwen
ollama run qwen3.5:cloud
Let's go! 🚀
ollama
@ollama
ollama run qwen3.5:cloud
Qwen3.5-397B-A17B is the first open-weight model in the series.
It's available on Ollama's cloud right now! Give it a try.
Let's go! 🚀🚀🚀
 Qwen
@Alibaba_Qwen
Qwen 3.5 Plus is now on ZenMux ⚡️
 ZenMux
@ZenMuxAI
Qwen 3.5 Plus is officially live on ZenMux ⚡️
The first flagship from @Alibaba_Qwen 3.5 series. Powered by a Gated DeltaNet + Sparse MoE architecture, it sets a new standard for performance and efficiency:
- Insane Throughput: Up to 8.6x faster than Qwen3-Max (at 32K context).
- Native Multimodal: 1M context support—capable of processing up to 2 hours of video.
- Superior Agents: Major gains in RL environment scaling for complex planning and tasks.
- Global Reach: Expanded support for 201 languages and dialects.
Experience the next-gen reasoning speed: 🔗 zenmux.ai/qwen/qwen3.5-plus

Qwen reposted
 0xSero
@0xSero
Qwen3-coder-next
I am really surprised how well it holds up, I haven't had any dumb issues with it yet, I've gotten it to work in Parchi albeit a little slow.
Prefill on GGUFs is a big issue, but it's doing pretty well. It's handling swift-ui pretty well and doesn't have that overly locked down feel.
If you have 64gb of vram/apple you should try this out.
Qwen
@Alibaba_Qwen
Huge thanks to @NVIDIAAIDev for the lightning-fast support! Time to build today! 🚀
NVIDIA AI Developer
@NVIDIAAIDev
🎊 Kudos to the teams at @Alibaba_Qwen on the launch of Qwen 3.5 with Qwen3.5-397B-A17B.
🙌 Developers can start building today for free: build.nvidia.com/qwen/qwen3.5-397b-a17b
Or download and customize it with NVIDIA NeMo: github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_f…
Qwen
@Alibaba_Qwen
Small, but smart!
0xSero
@0xSero
Qwen3-next-coder in Q8
Very good model, seems to hold up well in harnesses too.
Qwen
@Alibaba_Qwen
Thank you mlx-vlm for the amazing day-0 support on Qwen3.5! Can't wait to run this locally!
Prince Canuma
@Prince_Canuma
🚀 mlx-vlm v0.3.12 is out!
New Models
• Qwen3.5 series
• dots-ocr
Improvements
• FP8 dequantization for Ministral weights
• Activation quantization for QQLinear layers
• Improved logits processors & samplers integration
• Refactored processor return types to ProcessorMixin
Big thanks to all contributors, @JJJYmmm2002 @pcuenq @JesseRodPodcast, @mattjcly and others!
Get started today:
uv pip install -U mlx-vlm
And leave us a star⭐:
github.com/Blaizzy/mlx-vlm
 Qwen
@Alibaba_Qwen
From a single prompt to cityscape! Cool!
 RAVI KUMAR SAHU
@RAVIKUMARSAHU78
🚨 ALIBABA JUST OPEN-SOURCED THE MOST POWERFUL MODEL IN THE WORLD - Qwen3.5 plus
And it changes the AI race forever.
This is not another “bigger model” release.
This is a complete architectural reset.
397B parameters → only 17B active at inference, Qwen3.5 plus delivers performance on par with GPT-5.2 and Gemini-3-Pro.
A new Hybrid Sparse MoE + Linear Attention architecture + Multi-Token Prediction = near-instant long-context responses and massive speed gains.
Built as a true native multimodal model, it doesn’t just chat it builds.
With a single prompt:
“Use the React framework to create a visually impressive Mapbox demo featuring locations in Beijing and Shanghai”
it generates a live interactive 3D map UI, structured components, real layouts, and production-ready frontend logic.
This is real agentic, multimodal coding not a static code block.
MMLU-Pro: 87.8
GPQA: 88.4
IFBench: 76.5
⚡ up to 8× faster inference
And it’s fully open-sourced under Apache-2.0.
No locked APIs.
No restricted tiers.
201 languages supported bringing frontier AI to developers, startups, and researchers worldwide.
The race is no longer about the biggest model.
It’s about the most usable intelligence.
Open source just entered the top tier.
Qwen
@Alibaba_Qwen
Cool!
 Awni Hannun
@awnihannun
Qwen3.5 runs quite well in mlx-lm.
Awesome that we have a frontier-level hybrid model. The context gets longer but the inference speed and memory use barely change.
Here's the Q4 generating a space invaders game on an M3 Ultra. Generated 4,120 tokens at 37.6 tok/s.
Qwen
@Alibaba_Qwen
Massive thanks to @AIatAMD for the day-0 support!
 AI at AMD
@AIatAMD
Day 0 support for Qwen 3.5 is here on AMD Instinct GPUs.
By providing Day 0 support on AMD Instinct GPUs with both SGLang and vLLM, we ensure that developers have the compute power and optimized software stack needed to run these massive, high-context models at production scale.
Learn how to get started → www.amd.com/en/developer/resources/technical-articles/202…
 Qwen
@Alibaba_Qwen
Big appreciation to @KT_Project_AI for the incredible day-0 support. This is amazing! 💜
 KVCache.AI
@KVCache_AI
⚡ Day-0 support for Qwen3.5-397B-A17B just landed in KTransformers! This beast features Gated Delta Networks + sparse MoE (397B total, 17B active), unified vision-language, and 262K native context. Ready to run on your local machine.
Qwen
@Alibaba_Qwen
Huge thanks to @UnslothAI for the super fast day 0 support! 🚀
Unsloth AI
@UnslothAI
You can now run Qwen3.5 locally! 💜
Qwen3.5-397B-A17B is an open MoE vision reasoning LLM for agentic coding & chat.
It performs on par with Gemini 3 Pro, Claude Opus 4.5 & GPT-5.2.
Run 4-bit on 256GB Mac / RAM.
Guide: unsloth.ai/docs/models/qwen3.5
GGUF: huggingface.co/unsloth/Qwen3.5-397B-A17B-GGUF
 Qwen
@Alibaba_Qwen
🚀 Qwen3.5-397B-A17B is here: The first open-weight model in the Qwen3.5 series.
🖼️Native multimodal. Trained for real-world agents.
✨Powered by hybrid linear attention + sparse MoE and large-scale RL environment scaling.
⚡8.6x–19.0x decoding throughput vs Qwen3-Max
🌍201 languages & dialects
📜Apache2.0 licensed
🔗Dive in:
GitHub: github.com/QwenLM/Qwen3.5
Chat: chat.qwen.ai
API:modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Qwen Code: github.com/QwenLM/qwen-code
Hugging Face: huggingface.co/collections/Qwen/qwen35
ModelScope: modelscope.cn/collections/Qwen/Qwen35
blog: qwen.ai/blog?id=qwen3.5
 Qwen
@Alibaba_Qwen
Average Ranking vs. Environment Scaling
 Qwen
@Alibaba_Qwen
Efficiency
 Qwen
@Alibaba_Qwen
Infrastructure
 Qwen
@Alibaba_Qwen
Think, search, and create
Qwen
@Alibaba_Qwen
Coding: Car Game
Qwen
@Alibaba_Qwen
Qwen3.5🚀
Qwen
@Alibaba_Qwen
Coding: Website
Qwen
@Alibaba_Qwen
Example code
 Qwen
@Alibaba_Qwen
Qwen Code: Resolve the issue and submit a PR
Qwen
@Alibaba_Qwen
Single-File HTML/JS Farming Simulation Game (Stardew Valley Style)
Qwen
@Alibaba_Qwen
Big thanks to Day 0 support! Developers can start building today for free on nim and finetune with NeMo recipe: github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_f…
Qwen
@Alibaba_Qwen
LM Performance
 Qwen
@Alibaba_Qwen
VLM Performance
 Qwen
@Alibaba_Qwen
Base Model Performance
 Qwen
@Alibaba_Qwen
Powered by SGLang — thanks for the amazing support!
LMSYS Org
@lmsysorg
🎉 Meet Qwen3.5-397B-A17B from @Alibaba_Qwen, 397B total params (17B active), built for real-world multimodal intelligence — day-0 support is now live in SGLang!
👁️ Unified vision-language foundation (early fusion): stronger reasoning, coding & agents
⚡ Gated DeltaNet + sparse MoE: high throughput, low latency
🧠 RL scaled across million-agent environments: real-world adaptability
🌍 201 languages supported
Related PR: github.com/sgl-project/sglang/pull/18489
Cookbook: cookbook.sglang.io/autoregressive/Qwen/Qwen3.5
Run it now with SGLang!
 Qwen
@Alibaba_Qwen
🚀 Qwen3.5-397B-A17B is here: The first open-weight model in the Qwen3.5 series.
🖼️Native multimodal. Trained for real-world agents.
✨Powered by hybrid linear attention + sparse MoE and large-scale RL environment scaling.
⚡8.6x–19.0x decoding throughput vs Qwen3-Max
🌍201 languages & dialects
📜Apache2.0 licensed
🔗Dive in:
GitHub: github.com/QwenLM/Qwen3.5
Chat: chat.qwen.ai
API:modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Qwen Code: github.com/QwenLM/qwen-code
Hugging Face: huggingface.co/collections/Qwen/qwen35
ModelScope: modelscope.cn/collections/Qwen/Qwen35
blog: qwen.ai/blog?id=qwen3.5
Qwen
@Alibaba_Qwen
Huge thanks to @vllm_project for the support!
vLLM
@vllm_project
🎉 Congrats to @Alibaba_Qwen on releasing Qwen3.5 on Chinese New Year's Eve — day-0 support is ready in vLLM!
Qwen3.5 is a multimodal MoE with Gated Delta Networks architecture — 397B total params, only 17B active.
What makes it interesting for inference:
🧠 Gated Delta Networks + sparse MoE — high throughput, low latency, lower cost
🌍 201 languages and dialects supported out of the box
👁️ One model for both text and vision — no separate VL pipeline needed
Verified on NVIDIA GPUs. Recipes for Docker, pip, and multi-node deployment 👇
docs.vllm.ai/projects/recipes/en/latest/Qwen/Qwen3.5.html
#vllm #qwen #opensource #inference
 Qwen
@Alibaba_Qwen
🚀 Qwen3.5-397B-A17B is here: The first open-weight model in the Qwen3.5 series.
🖼️Native multimodal. Trained for real-world agents.
✨Powered by hybrid linear attention + sparse MoE and large-scale RL environment scaling.
⚡8.6x–19.0x decoding throughput vs Qwen3-Max
🌍201 languages & dialects
📜Apache2.0 licensed
🔗Dive in:
GitHub: github.com/QwenLM/Qwen3.5
Chat: chat.qwen.ai
API:modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Qwen Code: github.com/QwenLM/qwen-code
Hugging Face: huggingface.co/collections/Qwen/qwen35
ModelScope: modelscope.cn/collections/Qwen/Qwen35
blog: qwen.ai/blog?id=qwen3.5
Qwen
@Alibaba_Qwen
🖼️ AI Slides Just Got a Brain Upgrade!
🎯Meet Qwen AI Slides — your personal presentation designer that actually thinks. Powered by Qwen3 Agent + Qwen-Image 2.0, it turns chaos into clarity, beautifully.
✅ Type a simple idea, throw in a wall of text, or upload a document — it just works
✅ Search Agent researches, organizes & builds the story structure for you
✅ Qwen-Image 2.0 directly generates each slide as a polished visual — text, layout, color scheme & graphics, all in one shotStop designing slides. Start designing impact. 💡✨
Try it now: chat.qwen.ai?inputFeature=slides
Qwen
@Alibaba_Qwen
Stay tuned — AI Slides is landing in Qwen Chat very soon ✨
Project docs → meeting slides
Paper → oral deck
Product info → sales deck
Topic → teaching deck
 Chen Cheng
@cherry_cc12
Over the past few days, we built AI Slides in Qwen Chat with Qwen Agent + Qwen-Image 2.0.
With search agent, turning messy info into a clean museum intro deck becomes… weirdly easy.
Even better: drop in a paper → get an oral-style presentation in minutes.
It’s retrieval + structure + strong visual generation collapsing the whole workflow.
Coming soon in Qwen Chat.
Prompt👇
 Qwen
@Alibaba_Qwen
Love seeing Qwen3-ASR-0.6B powering on-device real-time transcription on an iPhone 15 Pro Max 🚀.
Huge thanks to the MLX-Audio-Swift and the community!
Prince Canuma
@Prince_Canuma
On-device realtime transcription on iPhone 15 Pro max 🚀
Using MLX-Audio-Swift + Qwen3-ASR-0.6B by @Alibaba_Qwen
It’s much faster and more consistent with the latest adjustments.
Almost ready to push to GH.
Qwen
@Alibaba_Qwen
A quick update — we’ve fixed a Qwen-Image 2.0 bug in Qwen Chat that impacted:
• Classical Chinese poem ordering in image generation
• Character consistency during image editing
✅Patch is live now!
chat.qwen.ai?inputFeature=t2i
Go test it out and drop us your feedback.
Qwen
@Alibaba_Qwen
🚀 Introducing Qwen-Image-2.0 — our next-gen image generation model!
🎨 Your imagination, unleashed.
✨ Type a paragraph → get a pro slides
✨ Describe a scene → get photoreal 2K magic
✨ Add text → it just works (no more glitchy letters!)
✨ Key upgrades:
✅ Professional typography (1K-token prompts for slides, posters & comics)
✅ 2K native resolution with stunning detail
✅ Flawless text rendering + unified generation/editing
✅ Lighter architecture = faster inference
Try it now → chat.qwen.ai?inputFeature=t2i
Full details → qwen.ai/blog?id=qwen-image-2.0
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
Edit

 Qwen
@Alibaba_Qwen
edit

 Qwen
@Alibaba_Qwen
edit

 Qwen
@Alibaba_Qwen

 Qwen
@Alibaba_Qwen


 Qwen
@Alibaba_Qwen
Qwen
@Alibaba_Qwen
Wow, this is really cool! 🚀
Welcome to build with Qwen!
ollama
@ollama
🤯 Wow! In one prompt Qwen3-Coder-Next generated a fully working flappy birds game in HTML.
(0:05) Claude Code with Qwen3-Coder-Next
(0:26) Shows the game running
Run it fully locally:
ollama pull qwen3-coder-next
Ollama's cloud if you can't run it locally:
ollama pull qwen3-coder-next:cloud
Try launching it with Claude Code using ollama launch
(link to play 🧵)
So cool! @Alibaba_Qwen @Ali_TongyiLab @JustinLin610
Qwen
@Alibaba_Qwen
Love seeing Qwen3-Coder-Next on Ollama 🙌
ollama
@ollama
ollama run qwen3-coder-next
Run Qwen3-Coder-Next completely free, locally on your computer.
It's built for coding agents and local development!
Run it with Claude Code:
ollama launch claude --config
Requires latest 0.15.5 pre-release on GitHub
64GB+ unified memory / VRAM recommended
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Coder-Next, an open-weight LM built for coding agents & local development.
What’s new:
🤖 Scaling agentic training: 800K verifiable tasks + executable envs
📈 Efficiency–Performance Tradeoff: achieves strong results on SWE-Bench Pro with 80B total params and 3B active
✨ Supports OpenClaw, Qwen Code, Claude Code, web dev, browser use, Cline, etc
🤗 Hugging Face: huggingface.co/collections/Qwen/qwen3-coder-next
🤖 ModelScope: modelscope.cn/collections/Qwen/Qwen3-Coder-Next
📝 Blog: qwen.ai/blog?id=qwen3-coder-next
📄 Tech report: github.com/QwenLM/Qwen3-Coder/blob/main/qwen3_coder_next_…
 Qwen
@Alibaba_Qwen
Cool! Qwen3-Coder-Next is now live on @huggingface supported by novita!
Novita AI
@novita_labs
🤗 Qwen3-Coder-Next is now live on @huggingface, supported by Novita
A 3B-activated (80B total) open-weight coding & agent model from Qwen, achieving 44.3 on SWE-Bench Pro.
Test it yourself 👇
Qwen
@Alibaba_Qwen
Amazing! 1/11.1 the cost!
 Jason
@jasonfreeagent
That was our reaction at @novita_labs when we saw the Qwen3-Coder-Next benchmarks. 44.3 on SWE-Bench Pro is no joke.
The gap between "open-weights" and "proprietary" coding assistants is officially closing.
We supported this release on @huggingface. Happy coding, everyone!
you can see the cost:
$0.0082 vs $0.0911 (11.1x cheaper)
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Coder-Next, an open-weight LM built for coding agents & local development.
What’s new:
🤖 Scaling agentic training: 800K verifiable tasks + executable envs
📈 Efficiency–Performance Tradeoff: achieves strong results on SWE-Bench Pro with 80B total params and 3B active
✨ Supports OpenClaw, Qwen Code, Claude Code, web dev, browser use, Cline, etc
🤗 Hugging Face: huggingface.co/collections/Qwen/qwen3-coder-next
🤖 ModelScope: modelscope.cn/collections/Qwen/Qwen3-Coder-Next
📝 Blog: qwen.ai/blog?id=qwen3-coder-next
📄 Tech report: github.com/QwenLM/Qwen3-Coder/blob/main/qwen3_coder_next_…
Qwen
@Alibaba_Qwen
🏆 Agent-Centric Benchmark Results
🟣 SWE-Bench Verified: Qwen3-Coder-Next >70% with the SWE-Agent scaffold
🟣 Efficient but strong: Despite a small active footprint, it matches or exceeds several much larger open-source models on a range of agent benchmarks
 Qwen
@Alibaba_Qwen
Qwen
@Alibaba_Qwen
Qwen3-Coder-Next model is live in kaggle✨. www.kaggle.com/models/qwen-lm/qwen3-coder-next
Qwen
@Alibaba_Qwen
Now Qwen3-Coder-Next is live on @togethercompute as a production-ready coding agent. Try it today! 👇
Together AI
@togethercompute
Introducing Qwen3-Coder-Next from @Alibaba_Qwen, an ultra-efficient 80B parameter (3B activated) coding agent achieving 74.2% SWE-Bench Verified. AI natives can now use Qwen3-Coder-Next on Together AI and benefit from reliable inference for production-scale coding agents.
 Qwen
@Alibaba_Qwen
Qwen3-Coder-Next is now available on LM Studio 🚀
Smart, fast, and local deployment ⚡️
LM Studio
@lmstudio
Qwen3-Coder-Next is here!
• 80B MoE, 3B active parameters
• Excels at long-horizon reasoning
• Trained for complex tool usage
🛠️👾🚀
lmstudio.ai/models/qwen/qwen3-coder-next
Qwen
@Alibaba_Qwen
Big thanks to @vllm_project for the support on day 0.
vLLM
@vllm_project
🎉 Congrats to @Alibaba_Qwen on releasing Qwen3-Coder-Next — and day-0 support is ready in vLLM 0.15.0!
An 80B MoE with only 3B active params, matching models 10–20x larger. Built for coding agents and local development.
Verified on NVIDIA GPUs. Recipe below 👇
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Coder-Next, an open-weight LM built for coding agents & local development.
What’s new:
🤖 Scaling agentic training: 800K verifiable tasks + executable envs
📈 Efficiency–Performance Tradeoff: achieves strong results on SWE-Bench Pro with 80B total params and 3B active
✨ Supports OpenClaw, Qwen Code, Claude Code, web dev, browser use, Cline, etc
🤗 Hugging Face: huggingface.co/collections/Qwen/qwen3-coder-next
🤖 ModelScope: modelscope.cn/collections/Qwen/Qwen3-Coder-Next
📝 Blog: qwen.ai/blog?id=qwen3-coder-next
📄 Tech report: github.com/QwenLM/Qwen3-Coder/blob/main/qwen3_coder_next_…
Qwen
@Alibaba_Qwen
💜💜💜💜💜 Thanks for the support from day 0
Unsloth AI
@UnslothAI
Qwen releases Qwen3-Coder-Next. 💜
The new 80B MoE model excels at agentic coding & local use. With 256K context, it delivers similar performance to models with 10-20× more active parameters.
Run on 46GB RAM or less.
Guide: unsloth.ai/docs/models/qwen3-coder-next
GGUF: huggingface.co/unsloth/Qwen3-Coder-Next-GGUF
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Coder-Next, an open-weight LM built for coding agents & local development.
What’s new:
🤖 Scaling agentic training: 800K verifiable tasks + executable envs
📈 Efficiency–Performance Tradeoff: achieves strong results on SWE-Bench Pro with 80B total params and 3B active
✨ Supports OpenClaw, Qwen Code, Claude Code, web dev, browser use, Cline, etc
🤗 Hugging Face: huggingface.co/collections/Qwen/qwen3-coder-next
🤖 ModelScope: modelscope.cn/collections/Qwen/Qwen3-Coder-Next
📝 Blog: qwen.ai/blog?id=qwen3-coder-next
📄 Tech report: github.com/QwenLM/Qwen3-Coder/blob/main/qwen3_coder_next_…
Qwen
@Alibaba_Qwen
Thanks to SGLang for the strong support!
LMSYS Org
@lmsysorg
🚀 Congrats @Alibaba_Qwen on releasing Qwen3-Coder-Next — day-0 support is now live in SGLang!
Qwen3-Coder-Next is an open-weight language model designed for coding agents and local development, featuring:
🔥Advanced architecture: It integrates Hybrid Attention with highly sparse MoE, enabling high throughput and strong ultra long context modeling.
📚Robust data foundation: Trained on highly diverse broad coverage corpora, with native 256K context and support for 370+ languages, it leaves ample headroom for post training.
🛠️Agentic coding capability: With a carefully designed training recipe, it has strong capabilities in tool calling, scaffold and template adaptation, and error detection and recovery, making it a strong backbone for reliable coding agents.
Get started in SGLang with the latest code and following commands:
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Coder-Next, an open-weight LM built for coding agents & local development.
What’s new:
🤖 Scaling agentic training: 800K verifiable tasks + executable envs
📈 Efficiency–Performance Tradeoff: achieves strong results on SWE-Bench Pro with 80B total params and 3B active
✨ Supports OpenClaw, Qwen Code, Claude Code, web dev, browser use, Cline, etc
🤗 Hugging Face: huggingface.co/collections/Qwen/qwen3-coder-next
🤖 ModelScope: modelscope.cn/collections/Qwen/Qwen3-Coder-Next
📝 Blog: qwen.ai/blog?id=qwen3-coder-next
📄 Tech report: github.com/QwenLM/Qwen3-Coder/blob/main/qwen3_coder_next_…
Qwen
@Alibaba_Qwen
Excited to invite you to join the Qwen-Image LoRA Training Competition 🚀
Let’s build and train LoRAs together!
modelscope.ai/active/qwenimagelora
 Tongyi Lab
@Ali_TongyiLab
1/6 We are thrilled to announce the Qwen-Image LoRA Training Competition!
We’re calling on global developers to push the boundaries of fine-tuning using the Qwen-Image base model.
Submission Window: Feb 2 – March 1, 2026
The challenge starts now.
 Qwen
@Alibaba_Qwen
Qwen3-ASR & ForceAligner now on mlx-audio — thanks for the fast support!
Prince Canuma
@Prince_Canuma
🔊mlx-audio v0.3.1 is out
New models 🤖
> Qwen3-ASR & ForceAligner by @Alibaba_Qwen
What's new ✨
> Qwen3-TTS streaming + optimized memory usage
> Fixed Qwen3-TTS 0.6B CustomVoice models producing silence
> Server improvements in API for STT and TTS
> Poetry support
Get started today:
> uv pip install -U mlx-audio
github.com/Blaizzy/mlx-audio
Qwen reposted
 Adina Yakup
@AdinaYakup
Qwen3-ASR is out🚀
huggingface.co/collections/Qwen/qwen3-asr
✨ 0.6B & 1.7B - Apache2.0
✨ 30 languages + 22 Chinese dialects, plus English accents across regions
✨ Single model for language ID + ASR (no extra pipeline stitching)
✨ Qwen3-ForcedAligner-0.6B, a strong forced aligner outperforming E2E baselines
 Qwen
@Alibaba_Qwen
Big thanks to vLLM for providing Day 0 support for Qwen3-ASR.
vLLM
@vllm_project
🎉 Congrats @Alibaba_Qwen on the Qwen3-ASR release — vLLM has day-0 support.
52 languages, 2000x throughput on the 0.6B model, singing voice recognition, and SOTA accuracy on the 1.7B.
Serve it now in vLLM! 🚀
Learn more: docs.vllm.ai/projects/recipes/en/latest/Qwen/Qwen3-ASR.html
 Qwen
@Alibaba_Qwen
Qwen3-ASR and Qwen3-ForcedAligner are now open source — production-ready speech models designed for messy, real-world audio, with competitive performance and strong robustness.
● 52 languages & dialects with auto language ID (30 languages + 22 dialects/accents)
● Robust in noisy and complex settings (yes, singing and songs too)
● Long audio support: up to 20 minutes per pass
● Word/phrase-level timestamps: high-precision alignment for 11 languages via Qwen3-ForcedAligner, stronger than MFA/CTC/CIF-style aligners
Also included: a full open-source inference & finetuning stack with vLLM batch, streaming, and async serving.
GitHub: github.com/QwenLM/Qwen3-ASR
Hugging Face: huggingface.co/collections/Qwen/qwen3-asr
ModelScope: modelscope.cn/collections/Qwen/Qwen3-ASR
Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen3-ASR
ModelScope Demo: modelscope.cn/studios/Qwen/Qwen3-ASR
Blog: qwen.ai/blog?id=qwen3asr
Paper: github.com/QwenLM/Qwen3-ASR/blob/main/assets/Qwen3_ASR.pdf
 Qwen
@Alibaba_Qwen
Qwen3-ASR is the first open-source LLM-based ASR in the industry with native streaming support.
Demo: github.com/QwenLM/Qwen3-ASR/blob/main/qwen_asr/cli/demo_s…
vLLM Example: github.com/QwenLM/Qwen3-ASR/blob/main/examples/example_qw…
Qwen
@Alibaba_Qwen
Qwen3-ASR and Qwen3-ForcedAligner are now open source — production-ready speech models designed for messy, real-world audio, with competitive performance and strong robustness.
● 52 languages & dialects with auto language ID (30 languages + 22 dialects/accents)
● Robust in noisy and complex settings (yes, singing and songs too)
● Long audio support: up to 20 minutes per pass
● Word/phrase-level timestamps: high-precision alignment for 11 languages via Qwen3-ForcedAligner, stronger than MFA/CTC/CIF-style aligners
Also included: a full open-source inference & finetuning stack with vLLM batch, streaming, and async serving.
GitHub: github.com/QwenLM/Qwen3-ASR
Hugging Face: huggingface.co/collections/Qwen/qwen3-asr
ModelScope: modelscope.cn/collections/Qwen/Qwen3-ASR
Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen3-ASR
ModelScope Demo: modelscope.cn/studios/Qwen/Qwen3-ASR
Blog: qwen.ai/blog?id=qwen3asr
Paper: github.com/QwenLM/Qwen3-ASR/blob/main/assets/Qwen3_ASR.pdf
Qwen
@Alibaba_Qwen
Qwen3-ASR and Qwen3-ForcedAligner are now open source — production-ready speech models designed for messy, real-world audio, with competitive performance and strong robustness.
● 52 languages & dialects with auto language ID (30 languages + 22 dialects/accents)
● Robust in noisy and complex settings (yes, singing and songs too)
● Long audio support: up to 20 minutes per pass
● Word/phrase-level timestamps: high-precision alignment for 11 languages via Qwen3-ForcedAligner, stronger than MFA/CTC/CIF-style aligners
Also included: a full open-source inference & finetuning stack with vLLM batch, streaming, and async serving.
GitHub: github.com/QwenLM/Qwen3-ASR
Hugging Face: huggingface.co/collections/Qwen/qwen3-asr
ModelScope: modelscope.cn/collections/Qwen/Qwen3-ASR
Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen3-ASR
ModelScope Demo: modelscope.cn/studios/Qwen/Qwen3-ASR
Blog: qwen.ai/blog?id=qwen3asr
Paper: github.com/QwenLM/Qwen3-ASR/blob/main/assets/Qwen3_ASR.pdf
Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
Qwen3-ASR Model Architecture
 Qwen
@Alibaba_Qwen
Qwen3-ASR-0.6B
 Qwen
@Alibaba_Qwen
RTF
 Qwen
@Alibaba_Qwen
Qwen3-ForcedAligner-0.6B

Qwen reposted
 Robbyant
@robbyant_brain
🧠 What if one AI brain powers all robots? Retraining for every new embodiment is the biggest scaling pain in embodied AI—we’re fixing it.
Today, we open-source LingBot-VLA: a Vision-Language-Action model built on @Alibaba_Qwen Qwen-2.5-VL and pre-trained on 20,000 hours of real-world data across 9 distinct robot embodiments. New SOTA for cross-embodiment generalization unlocked.
#embodiedai #robotics #vla #opensource
Qwen
@Alibaba_Qwen
🚀 Introducing DeepPlanning — a new benchmark for long-horizon agent planning in real-world scenarios.
Unlike step-by-step reasoning tasks, we focus on verifiable global constraints: time budgets, cost limits, and combinatorial optimization that must hold across the entire plan.
✈️ Multi-day travel w/ minute-level scheduling + hard time/budget caps
🛒 Complex shopping w/ coupon stacking & item bundling
🧠 Requires active info gathering, local constraint satisfaction & global optimality
Even GPT-5.2, Claude 4.5, Gemini & Qwen3 struggle significantly.
Perfect for evaluating Agent Planning / Tool Use / Long-Horizon Reasoning.
Paper: arxiv.org/pdf/2601.18137
Leaderboard: qwenlm.github.io/Qwen-Agent/en/benchmarks/deepplanning/
Hugging Face Dataset: huggingface.co/datasets/Qwen/DeepPlanning
ModelScope Dataset:
modelscope.cn/datasets/Qwen/DeepPlanning
Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Max-Thinking, our most capable reasoning model yet. Trained with massive scale and advanced RL, it delivers strong performance across reasoning, knowledge, tool use, and agent capabilities.
✨ Key innovations:
✅ Adaptive tool-use: intelligently leverages Search, Memory & Code Interpreter without manual selection
✅ Test-time scaling: multi-round self-reflection beats Gemini 3 Pro on reasoning
✅ From complex math (98.0 on HMMT Feb) to agentic search (49.8 on HLE)—it just thinks better.
🧠 Think deeper. Solve harder.
Try the adaptive reasoning experience now: chat.qwen.ai
Completions API: modelstudio.console.alibabacloud.com/ap-southeast-1/?tab=doc
Responses API: www.alibabacloud.com/help/en/model-studio/compatibility-w…
blog: qwen.ai/blog?id=qwen3-max-thinking
 Qwen
@Alibaba_Qwen
The table below presents a more comprehensive set of evaluation scores.
 Qwen
@Alibaba_Qwen
API Price
 Qwen
@Alibaba_Qwen
Completions API Code Sample
 Qwen
@Alibaba_Qwen
Responses API Code Sample
 Qwen
@Alibaba_Qwen
We’ve been getting lots of questions about Qwen3-TTS—here’s a quick update! 🎙️
1️⃣ Streaming support?
We’re working with @vllm_project to enable streaming inference—huge thanks to vLLM team! Stay tuned for a smooth, real-time experience soon.
2️⃣ Consistent voice tone?
Use Voice Design to pick your favorite voice, then leverage the Base model’s clone feature to lock it in as a reference. This ensures stable, consistent output.
3️⃣ Can the Base model support Instruct-style control (e.g., emotion, style)?
Yes—this is coming in the upcoming open-source 25Hz model release!
Qwen
@Alibaba_Qwen
Qwen3-TTS is officially live. We’ve open-sourced the full family—VoiceDesign, CustomVoice, and Base—bringing high quality to the open community.
- 5 models (0.6B & 1.8B)
- Free-form voice design & cloning
- Support for 10 languages
- SOTA 12Hz tokenizer for high compression
- Full fine-tuning support
- SOTA performance
We believe this is arguably the most disruptive release in open-source TTS yet. Go ahead, break it and build something cool. 🚀 Everything is out now—weights, code, and paper. Enjoy. 🧵
Github: github.com/QwenLM/Qwen3-TTS
Hugging Face: huggingface.co/collections/Qwen/qwen3-tts
ModelScope: modelscope.cn/collections/Qwen/Qwen3-TTS
Blog: qwen.ai/blog?id=qwen3tts-0115
Paper: github.com/QwenLM/Qwen3-TTS/blob/main/assets/Qwen3_TTS.pdf
Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen3-TTS
ModelScope Demo: modelscope.cn/studios/Qwen/Qwen3-TTS
API: www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-…

Qwen reposted
 Ivan Fioravanti
@ivanfioravanti
Playing with Qwen3-TTS is and MLX-Audio locally on Mac Studio M3 Ultra 🔥
Amazing model by @Alibaba_Qwen and great work by @Prince_Canuma bringing this magic to MLX!
Tuning the voice with instructions feels like magic!
Command and prompts to run it are in the video.
Qwen
@Alibaba_Qwen
Thanks🥰
 Wildminder
@wildmindai
ComfyUI-Qwen-TTS:
- speech synthesis, voice cloning & voice design;
- supports 10 languages & low-latency streaming.
github.com/flybirdxx/ComfyUI-Qwen-TTS

Qwen reposted
Simon Willison
@simonw
Qwen released a new Apache 2.0 licensed text-to-speech model, with full voice cloning abilities, and it's really effective - my notes from trying it out here: simonwillison.net/2026/Jan/22/qwen3-tts/
Qwen
@Alibaba_Qwen
Qwen3-TTS is now on MLX-Audio 🚀
Huge thanks for the incredibly fast support!
Prince Canuma
@Prince_Canuma
Qwen3-TTS now on MLX-Audio 🚀
> uv pip install -U mlx-audio --prerelease=allow
Qwen
@Alibaba_Qwen
Qwen3-TTS is officially live. We’ve open-sourced the full family—VoiceDesign, CustomVoice, and Base—bringing high quality to the open community.
- 5 models (0.6B & 1.8B)
- Free-form voice design & cloning
- Support for 10 languages
- SOTA 12Hz tokenizer for high compression
- Full fine-tuning support
- SOTA performance
We believe this is arguably the most disruptive release in open-source TTS yet. Go ahead, break it and build something cool. 🚀 Everything is out now—weights, code, and paper. Enjoy. 🧵
Github: github.com/QwenLM/Qwen3-TTS
Hugging Face: huggingface.co/collections/Qwen/qwen3-tts
ModelScope: modelscope.cn/collections/Qwen/Qwen3-TTS
Blog: qwen.ai/blog?id=qwen3tts-0115
Paper: github.com/QwenLM/Qwen3-TTS/blob/main/assets/Qwen3_TTS.pdf
Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen3-TTS
ModelScope Demo: modelscope.cn/studios/Qwen/Qwen3-TTS
API: www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-…
Qwen
@Alibaba_Qwen
Thanks so much to @vllm_project for the Day 0 support!
vLLM
@vllm_project
Congrats to the @Alibaba_Qwen team on Qwen3-TTS! 🎉
vLLM-Omni is ready with day-0 support – voice cloning, voice design, and natural language control for emotion & prosody, all running natively.
Offline inference available now via PR #895, online serving coming soon.
🔗 github.com/vllm-project/vllm-omni/pull/895
 Qwen
@Alibaba_Qwen
Qwen3-TTS is officially live. We’ve open-sourced the full family—VoiceDesign, CustomVoice, and Base—bringing high quality to the open community.
- 5 models (0.6B & 1.8B)
- Free-form voice design & cloning
- Support for 10 languages
- SOTA 12Hz tokenizer for high compression
- Full fine-tuning support
- SOTA performance
We believe this is arguably the most disruptive release in open-source TTS yet. Go ahead, break it and build something cool. 🚀 Everything is out now—weights, code, and paper. Enjoy. 🧵
Github: github.com/QwenLM/Qwen3-TTS
Hugging Face: huggingface.co/collections/Qwen/qwen3-tts
ModelScope: modelscope.cn/collections/Qwen/Qwen3-TTS
Blog: qwen.ai/blog?id=qwen3tts-0115
Paper: github.com/QwenLM/Qwen3-TTS/blob/main/assets/Qwen3_TTS.pdf
Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen3-TTS
ModelScope Demo: modelscope.cn/studios/Qwen/Qwen3-TTS
API: www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-…
Qwen
@Alibaba_Qwen
Qwen3-TTS is officially live. We’ve open-sourced the full family—VoiceDesign, CustomVoice, and Base—bringing high quality to the open community.
- 5 models (0.6B & 1.8B)
- Free-form voice design & cloning
- Support for 10 languages
- SOTA 12Hz tokenizer for high compression
- Full fine-tuning support
- SOTA performance
We believe this is arguably the most disruptive release in open-source TTS yet. Go ahead, break it and build something cool. 🚀 Everything is out now—weights, code, and paper. Enjoy. 🧵
Github: github.com/QwenLM/Qwen3-TTS
Hugging Face: huggingface.co/collections/Qwen/qwen3-tts
ModelScope: modelscope.cn/collections/Qwen/Qwen3-TTS
Blog: qwen.ai/blog?id=qwen3tts-0115
Paper: github.com/QwenLM/Qwen3-TTS/blob/main/assets/Qwen3_TTS.pdf
Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen3-TTS
ModelScope Demo: modelscope.cn/studios/Qwen/Qwen3-TTS
API: www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-…
Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
Glad to see Qwen being used in Chroma 1.0, a real-time, end-to-end, fully open-source voice system. Congrats to @flashlabsdotai
 FlashLabs
@flashlabsdotai
Today we’re releasing Chroma 1.0
→ the world first open-source, end-to-end, real-time speech-to-speech model
→ with personalized voice cloning
Trained by FlashLabs.
Deployed on FlashAI👉 www.flashlabs.ai/flashai-voice-agents
An open research-grade alternative to the @OpenAI Realtime model.
Voice Test dubbing @elonmusk and @lexfridman: www.youtube.com/watch?v=AOMmxTwsam0
🔥What’s real (evals and benchmarks attached):
⚡ <150ms TTFT (end-to-end)
🎙️ Native speech-to-speech (no ASR → LLM → TTS pipeline)
🧬 Few-second reference → high-fidelity voice cloning
📈 SIM = 0.817
→ +10.96% vs human baseline (0.73)
→ Best among open & closed baselines
🧠 Strong reasoning & dialogue with just 4B params (@Alibaba_Qwen 2.5-Omni-3B, Llama 3, and Mimi)
🔓 Fully open-source (code + weights)
With SGLang @lmsysorg enabled:
• 🧠 Thinker TTFT ↓ ~15%
• ⏱️ End-to-end TTFT ~135ms
• 🔊 RTF ≈ 0.47–0.51 ( >2× faster than real-time )
📘 SGLang Cookbook: cookbook.sglang.io/docs/autoregressive/FlashLabs/Chroma1.0
📄 Paper + benchmarks: arxiv.org/abs/2601.11141
🤗 Models: huggingface.co/FlashLabs/Chroma-4B
💻 Inference code: github.com/FlashLabs-AI-Corp/FlashLabs-Chroma
🔁 RT if you believe real-time AI should be open
💬 Reply if you’re building on Conversational Voice AI products

 Qwen
@Alibaba_Qwen
Qwen now powers DINQ — an AI-native professional network helping AI professionals build trusted profiles and connect with opportunities more efficiently.
 DINQ
@dinq_me
You’ve done real work.
But most of it is hard to see.
DINQ brings your projects, code, and research onto one card.
No self-promotion. Just real signals.
Build your DINQ → dinq.me
#dinq
Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-VL-Embedding and Qwen3-VL-Reranker – advancing the state of the art in multimodal retrieval and cross-modal understanding!
✨ Highlights:
✅ Built upon the robust Qwen3-VL foundation model
✅ Processes text, images, screenshots, videos, and mixed modality inputs
✅ Supports 30+ languages
✅ Achieves state-of-the-art performance on multimodal retrieval benchmarks
✅ Open source and available on Hugging Face, GitHub, and ModelScope
✅ API deployment on Alibaba Cloud coming soon!
🎯 Two-stage retrieval architecture:
📊 Embedding Model – generates semantically rich vector representations in a unified embedding space
🎯 Reranker Model – computes fine-grained relevance scores for enhanced retrieval accuracy
🔍 Key application scenarios:
Image-text retrieval, video search, multimodal RAG, visual question answering, multimodal content clustering, multilingual visual search, and more!
🌟 Developer-friendly capabilities:
• Configurable embedding dimensions
• Task-specific instruction customization
• Embedding quantization support for efficient and cost-effective downstream deployment
Hugging Face:
huggingface.co/collections/Qwen/qwen3-vl-embedding
huggingface.co/collections/Qwen/qwen3-vl-reranker
ModelScope:
modelscope.cn/collections/Qwen/Qwen3-VL-Embedding
modelscope.cn/collections/Qwen/Qwen3-VL-Reranker
Github: github.com/QwenLM/Qwen3-VL-Embedding
Blog: qwen.ai/blog?id=qwen3-vl-embedding
Tech Report:github.com/QwenLM/Qwen3-VL-Embedding/blob/main/assets/qwe…
 Qwen
@Alibaba_Qwen
Overview of the Qwen3-VL-Embedding and Qwen3-VL-Reranker architecture.
 Qwen
@Alibaba_Qwen
Evaluation results on MMEB-v2 and MMTEB benchmarks
 Qwen
@Alibaba_Qwen
Cool! Generates high resolution images in ~7s! Thank you @PrunaAI
 Pruna AI
@PrunaAI
🎉 We made the new Qwen-Image-2512 ultimate fast on @replicate for the new year!
The @Alibaba_Qwen x @PrunaAI collaboration continues after Qwen-Layered and Qwen-Image-Edit-2511 ⚡️
✅ Generates high resolution images in ~7s
✨ Realistic humans without “AI look”
🧑🎨 Fine textures for any materials like glass, water, fur
⌨️ Superior text rendering with adjusted layouts and accurate composition
Try it 👉 replicate.com/qwen/qwen-image-2512
Qwen
@Alibaba_Qwen
🎉 Happy New Year! Huge thanks to the SGLang team for supporting Qwen-Image-2512!
LMSYS Org
@lmsysorg
Nice upgrade from Qwen 🎁
Qwen-Image-2512 is a weight update, so it runs seamlessly with SGLang. We try to keep open-source models working fast and reliably as they evolve.
sglang generate \
--model-path Qwen/Qwen-Image-2512 \
--prompt "Draw a picture of LA in the rain."
(Side-by-side comparison: previous weights vs. 2512.)
Happy New Year! 🎊

 Qwen
@Alibaba_Qwen
Big thanks to @vllm_project for day-zero support of Qwen-Image-2512! 🎉
vLLM
@vllm_project
Congrats to @Alibaba_Qwen on the release of Qwen-Image-2512! 🎉
We are thrilled to announce Day-0 support in vLLM-Omni. You can now serve this SOTA open-source image model with our optimized pipelined architecture immediately.
Read more: github.com/vllm-project/vllm-omni/pull/547
👇 See it running below:

 Qwen
@Alibaba_Qwen
Try Qwen-Image-2512 in ComfyUI now! Huge thanks to @ComfyUI
ComfyUI
@ComfyUI
Run Qwen-Image-2512 in ComfyUI: no update needed!
This upgraded version of the Qwen Image text-to-image model brings:
More realistic human rendering, with far less “AI look”
Finer natural details across landscapes, fur, and textures
Improved text rendering and layout accuracy
▶️ Run it locally in ComfyUI with the Qwen Image workflow
☁️ Comfy Cloud support coming soon


 Qwen
@Alibaba_Qwen
Qwen-Image-2512 is now available on Replicate!
 Replicate
@replicate
Try it here:
replicate.com/qwen/qwen-image-2512
Qwen
@Alibaba_Qwen
Qwen-Image-2512 has been added to AI-Toolkit. Big thanks to @ostrisai
 Ostris
@ostrisai
Qwen-Image-2512 has been added to AI-Toolkit. Training a 3bit ARA for it now that should be ready in ~24 hours.

Qwen reposted
Ivan Fioravanti
@ivanfioravanti
qwen-image-mps 0.7.2 released with:
- qwen-image-2512 support, thanks @Alibaba_Qwen 🙏
- quantized versions by @UnslothAI 🙏
Fast and Ultra-Fast LoRA seems working, I'll update with newer ones in near future.
PR for Qwen-Image_layered ready but waiting for new Diffusers package.


 Qwen
@Alibaba_Qwen
Huge thanks for the support @fal — amazing speed!
fal
@fal
🚨 Qwen Image 2512 is now live on fal!
🎨 Enhanced human realism with intricate facial details like wrinkles and pores
🌿 Finer natural detail - notably more detailed rendering of landscapes, waterfalls and animal fur
📝 Advanced text rendering for complex infographics
 Qwen
@Alibaba_Qwen
Soooooo fast! Big thanks to @UnslothAI
Unsloth AI
@UnslothAI
Qwen releases Qwen-Image-2512, a new SOTA text-to-image model. 💜
It's the top performing open diffusion model on AI Arena and has more realistic + accurate images/text.
Run locally with 14GB RAM via our Dynamic GGUF
Guide: unsloth.ai/docs/models/qwen-image-2512
GGUF: huggingface.co/unsloth/Qwen-Image-2512-GGUF
 Qwen
@Alibaba_Qwen
🎁 A New Year gift from Qwen — Qwen-Image-2512 is here.
🚀 Our December upgrade to Qwen-Image, just in time for the New Year.
✨ What’s new:
• More realistic humans — dramatically reduced “AI look,” richer facial details
• Finer natural textures — sharper landscapes, water, fur, and materials
• Stronger text rendering — better layout, higher accuracy in text–image composition
🏆 Tested in 10,000+ blind rounds on AI Arena, Qwen-Image-2512 ranks as the strongest open-source image model, while staying competitive with closed-source systems.
👉 Try it now in Qwen Chat: chat.qwen.ai?inputFeature=t2i
🤗 Hugging Face: huggingface.co/Qwen/Qwen-Image-2512
📦 ModelScope: modelscope.ai/models/Qwen/Qwen-Image-2512
💻 GitHub: github.com/QwenLM/Qwen-Image
📝 Blog: qwen.ai/blog?id=qwen-image-2512
🤗 Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen-Image-2512
📦 ModelScope Demo: modelscope.cn/aigc/imageGeneration
✨API: modelstudio.console.alibabacloud.com?tab=doc
🎆 Start the New Year with better images.
Qwen
@Alibaba_Qwen
🎁 A New Year gift from Qwen — Qwen-Image-2512 is here.
🚀 Our December upgrade to Qwen-Image, just in time for the New Year.
✨ What’s new:
• More realistic humans — dramatically reduced “AI look,” richer facial details
• Finer natural textures — sharper landscapes, water, fur, and materials
• Stronger text rendering — better layout, higher accuracy in text–image composition
🏆 Tested in 10,000+ blind rounds on AI Arena, Qwen-Image-2512 ranks as the strongest open-source image model, while staying competitive with closed-source systems.
👉 Try it now in Qwen Chat: chat.qwen.ai?inputFeature=t2i
🤗 Hugging Face: huggingface.co/Qwen/Qwen-Image-2512
📦 ModelScope: modelscope.ai/models/Qwen/Qwen-Image-2512
💻 GitHub: github.com/QwenLM/Qwen-Image
📝 Blog: qwen.ai/blog?id=qwen-image-2512
🤗 Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen-Image-2512
📦 ModelScope Demo: modelscope.cn/aigc/imageGeneration
✨API: modelstudio.console.alibabacloud.com?tab=doc
🎆 Start the New Year with better images.
Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
Level 2025: Just the beginning. 🚩
2026, Ready? GO! 🎮🚀
Qwen
@Alibaba_Qwen
🚀 Qwen Code v0.6.0 now is available!
• Experimental Skills: Introduced experimental Skills feature for extended capabilities
• VS Code Enhancements: Improved extension description with download links and clickable bash toolcall outputs
• Commands Support: Added /compress and /summary commands for non-interactive & ACP usage
• Multi-Provider Support: Added Gemini and Anthropic providers with normalized authentication configuration
• Enhancements & Stability: Improved testing reliability with fixed flaky integration tests, enhanced Windows compatibility through CLI path resolution, updated OAuth client for Figma MCP server, streamlined SDK release workflows, and clearer README documentation for faster onboarding.
👉 Get started in Terminal
npm install -g @qwen-code/qwen-code@latest
🌐 Check out the full changelog: github.com/QwenLM/qwen-code/releases/tag/v0.6.0
Qwen
@Alibaba_Qwen
Use Qwen Code to parse the PDF document into markdown content, and then translate it.
Qwen
@Alibaba_Qwen
Qwen Image Edit 2511 & Qwen Image Layered are now live in ComfyUI - smarter editing, layered control.
ComfyUI
@ComfyUI
Qwen Image Edit 2511 & Qwen Image Layered Arrive in ComfyUI!
- Qwen-Image-Edit-2511 — Enhanced editing with better consistency
- Qwen-Image-Layered — Decompose images into editable RGBA layers
🧵👇 Both models are now available in ComfyUI. Try them out!
 Qwen
@Alibaba_Qwen
Merry Qwristmas! 🎄🎁
Huge thanks for all the love and support this year.
Get ready for Qwen’s New Year surprises! 🎆✨
See you next year — with even more Qwen magic. ✨
Qwen
@Alibaba_Qwen
🥳 Qwen-Image-Edit-2511 on 🍞 TostUI 🧪 Big thanks to @camenduru !
 camenduru
@camenduru
🥳 Qwen-Image-Edit-2511 on 🍞 TostUI 🧪 (tested on RTX 3090/4090/5090, Windows & Linux, 8bit)
Thanks to @Alibaba_Qwen Team ❤
🐋 docker run --gpus all -p 3000:3000 --name tostui-qwen-image-edit-2511 camenduru/tostui-qwen-image-edit-2511
🍞 github.com/camenduru/TostUI
Qwen
@Alibaba_Qwen
🚀 Introducing Qwen-Image-Edit-2511 — a major upgrade over 2509, delivering significantly stronger consistency and more powerful real-world image editing.
✨ What’s new in 2511:
👥 Stronger multi-person consistency for group photos and complex scenes
🧩 Built-in popular community LoRAs — no extra tuning required
💡 Enhanced industrial & product design generation
🔒 Reduced image drift with dramatically improved character & identity consistency
📐 Improved geometric reasoning, including construction lines and structural edits
From identity-preserving portrait edits to high-fidelity multi-person fusion and practical engineering & design workflows, 2511 pushes image editing to the next level.
👉 Try it now:
🎨 Qwen Chat (Image Edit): chat.qwen.ai?inputFeature=image_edit
 Qwen
@Alibaba_Qwen
Qwen-Image-Edit-2511 is now live on Replicate! 🎉
Many thanks to @Replicate and @PrunaAI for their incredible support!
Replicate
@replicate
Qwen-Image-Edit-2511 is here
An enhanced version over Qwen-Image-Edit-2509, featuring multiple improvements including notably better consistency
We've worked with @PrunaAI again to deliver you the fastest speeds possible


 Qwen
@Alibaba_Qwen
❤️ Big thanks for your support on Day 0!
Unsloth AI
@UnslothAI
Congrats guys this is an amazing open-source effort! 💜🥰
We made Qwen-Image-Edit-2511 GGUFs so everyone can run it locally! 🙏 huggingface.co/unsloth/Qwen-Image-Edit-2511-GGUF
Qwen
@Alibaba_Qwen
🚀 Introducing Qwen-Image-Edit-2511 — a major upgrade over 2509, delivering significantly stronger consistency and more powerful real-world image editing.
✨ What’s new in 2511:
👥 Stronger multi-person consistency for group photos and complex scenes
🧩 Built-in popular community LoRAs — no extra tuning required
💡 Enhanced industrial & product design generation
🔒 Reduced image drift with dramatically improved character & identity consistency
📐 Improved geometric reasoning, including construction lines and structural edits
From identity-preserving portrait edits to high-fidelity multi-person fusion and practical engineering & design workflows, 2511 pushes image editing to the next level.
👉 Try it now:
🎨 Qwen Chat (Image Edit): chat.qwen.ai?inputFeature=image_edit
Qwen
@Alibaba_Qwen
Model:
🤗 Hugging Face: huggingface.co/Qwen/Qwen-Image-Edit-2511
🧭 ModelScope: modelscope.cn/models/Qwen/Qwen-Image-Edit-2511
Qwen
@Alibaba_Qwen
🧪 HF Demo: huggingface.co/spaces/Qwen/Qwen-Image-Edit-2511
🖼️ ModelScope Demo: modelscope.cn/aigc/imageGeneration
Qwen
@Alibaba_Qwen
⚙️ API Access:
🌍 Global API: modelstudio.console.alibabacloud.com?tab=doc
🇨🇳 China API: bailian.console.aliyun.com?tab=model
Qwen
@Alibaba_Qwen
Qwen
@Alibaba_Qwen
Video
Qwen
@Alibaba_Qwen
Video
Qwen
@Alibaba_Qwen
LightX2V brings Day-0 support for Qwen-Image-Edit-2511 — combining a 47% framework speedup with CFG + 4-step distillation (↓25× compute) for a massive 42.55× end-to-end acceleration !⚡️ Big thanks to @XHPlus_
 Ruihao Gong
@XHPlus_
🚀 42.55x Speedup!
LightX2V delivers Day 0 support for @Alibaba_Qwen new Qwen-Image-Edit-2511!
🔥 47% framework speedup
⚡️ CFG+4-step distillation (↓25x compute)
📈 42.55x total acceleration
Repo: github.com/ModelTC/LightX2V/
Model: huggingface.co/lightx2v/Qwen-Image-Edit-2511-Lightning
 Qwen
@Alibaba_Qwen
🚀 Meet the new Qwen3-TTS lineup: VoiceDesign & VoiceClone!
Create, control, and clone voices—faster and more expressive than ever.
⚡ VoiceDesign-VD-Flash
• Fully controllable speech via free-form text instructions — tone, rhythm, emotion, persona
• No preset voices. Design your own unique vocal identity
• Outperforms GPT-4o-mini-tts & Gemini-2.5-pro on role-play benchmarks
⚡ VoiceClone-VC-Flash
• Clone any voice from just 3 seconds of audio
• Generate speech in 10 languages (CN / EN / JP / ES + more)
• 15% lower WER vs. ElevenLabs & GPT-4o-Audio in multilingual tests
• Context-aware cadence for more natural delivery
🎙️ Try it now
• Qwen Chat: chat.qwen.ai
• Blog: qwen.ai/blog?id=qwen3-tts-vc-voicedesign
Qwen
@Alibaba_Qwen
📥 APIs
• VoiceDesign: www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-…
• VoiceClone: www.alibabacloud.com/help/en/model-studio/qwen-tts-voice-…
Qwen
@Alibaba_Qwen
Try Voice Clone in Qwen Chat — sound like you, instantly
Qwen
@Alibaba_Qwen
Try Voice Design in Qwen Chat — design your own voice
Qwen
@Alibaba_Qwen
Qwen3-TTS Voice Design Metrics
 Qwen
@Alibaba_Qwen
Qwen3-TTS Voice Clone Metrics
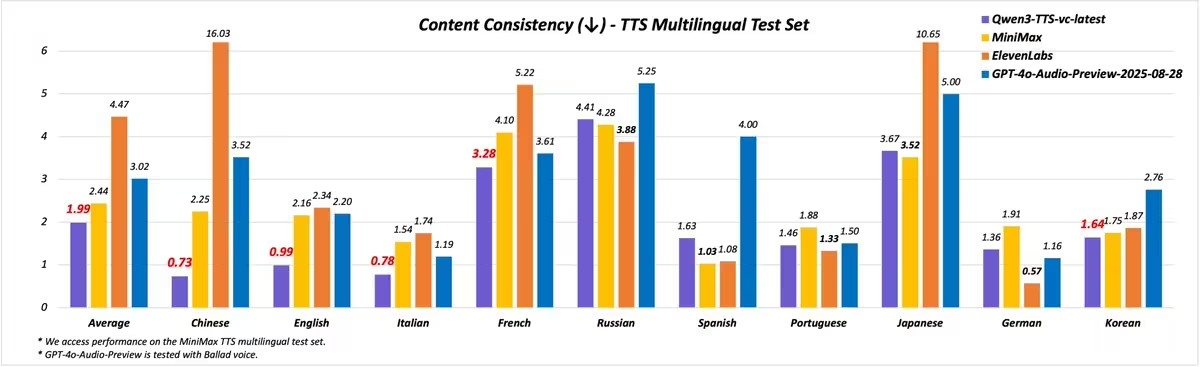 Qwen
@Alibaba_Qwen
Glad to collaborate with SGLang on Rollout Routing Replay (R3)—now live! 🎉
LMSYS Org
@lmsysorg
SGLang + Miles: Rollout Routing Replay (R3) is Now Live! 🎉
We're excited to announce that SGLang and Miles now support Rollout Routing Replay (R3) for stable reinforcement learning training on MoE models!
Training MoE models with RL has been notoriously unstable, often leading to catastrophic collapse. The problem? Routing inconsistency between inference and training engines. R3 fixes this by recording expert routing decisions during inference and replaying them during training.
The impact is significant: dramatically reduced training-inference discrepancy by reusing inference routing decisions, preventing training collapse. R3 has full distributed training support with DataParallel Attention and all parallelism strategies, supported models include Qwen3-30B-A3B, deepseek_v2, etc.
Try it out and let us know your results! 🚀
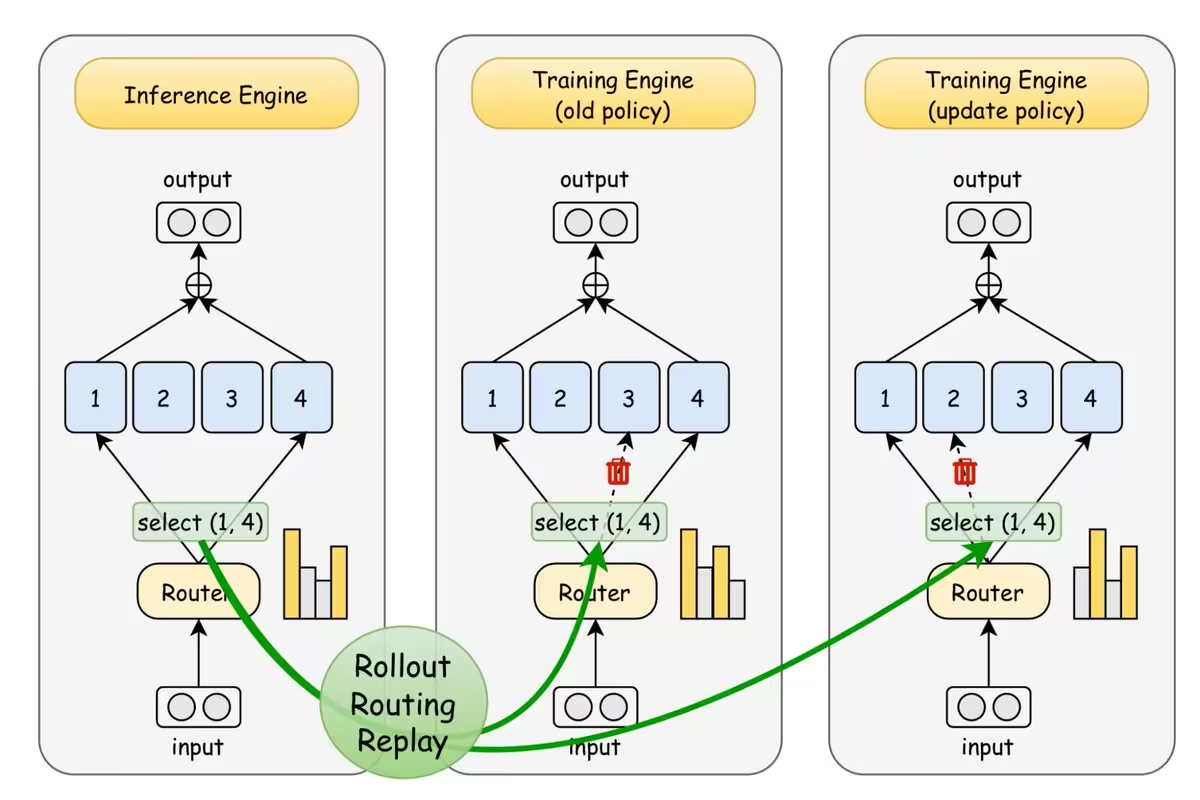 Qwen
@Alibaba_Qwen
Qwen Image Layered is live on fal! Big thanks to @fal
fal
@fal
🚨 Qwen Image Layered is live on fal!
✨ Photoshop-grade layering - Native Decomposition
👑 Physically isolated RGBA layers with true native editability
🎨 Explicitly specify layers, from coarse layouts to fine-grained details
 Qwen
@Alibaba_Qwen
ComfyUI supports Qwen Image layered on day0! Big thanks to @jtydhr88
Qwen
@Alibaba_Qwen
🚀 Qwen Layered just got faster! Big thanks to @PrunaAI
Qwen
@Alibaba_Qwen
🎨 Qwen-Image-Layered is LIVE — native image decomposition, fully open-sourced!
✨ Why it stands out
✅ Photoshop-grade layering
Physically isolated RGBA layers with true native editability
✅ Prompt-controlled structure
Explicitly specify 3–10 layers — from coarse layouts to fine-grained details
✅ Infinite decomposition
Keep drilling down: layers within layers, to any depth of detail
🤗 Hugging Face: huggingface.co/Qwen/Qwen-Image-Layered
🧩 ModelScope: www.modelscope.cn/models/Qwen/Qwen-Image-Layered
💻 GitHub: github.com/QwenLM/Qwen-Image-Layered
📝 Blog: qwen.ai/blog?id=qwen-image-layered
📄 Technical Report: arxiv.org/abs/2512.15603
🚀 Demo (HF): huggingface.co/spaces/Qwen/Qwen-Image-Layered
🚀 Demo (ModelScope): www.modelscope.cn/studios/Qwen/Qwen-Image-Layered
Qwen
@Alibaba_Qwen
🎨 Qwen-Image-Layered is LIVE — native image decomposition, fully open-sourced!
✨ Why it stands out
✅ Photoshop-grade layering
Physically isolated RGBA layers with true native editability
✅ Prompt-controlled structure
Explicitly specify 3–10 layers — from coarse layouts to fine-grained details
✅ Infinite decomposition
Keep drilling down: layers within layers, to any depth of detail
🤗 Hugging Face: huggingface.co/Qwen/Qwen-Image-Layered
🧩 ModelScope: www.modelscope.cn/models/Qwen/Qwen-Image-Layered
💻 GitHub: github.com/QwenLM/Qwen-Image-Layered
📝 Blog: qwen.ai/blog?id=qwen-image-layered
📄 Technical Report: arxiv.org/abs/2512.15603
🚀 Demo (HF): huggingface.co/spaces/Qwen/Qwen-Image-Layered
🚀 Demo (ModelScope): www.modelscope.cn/studios/Qwen/Qwen-Image-Layered
Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
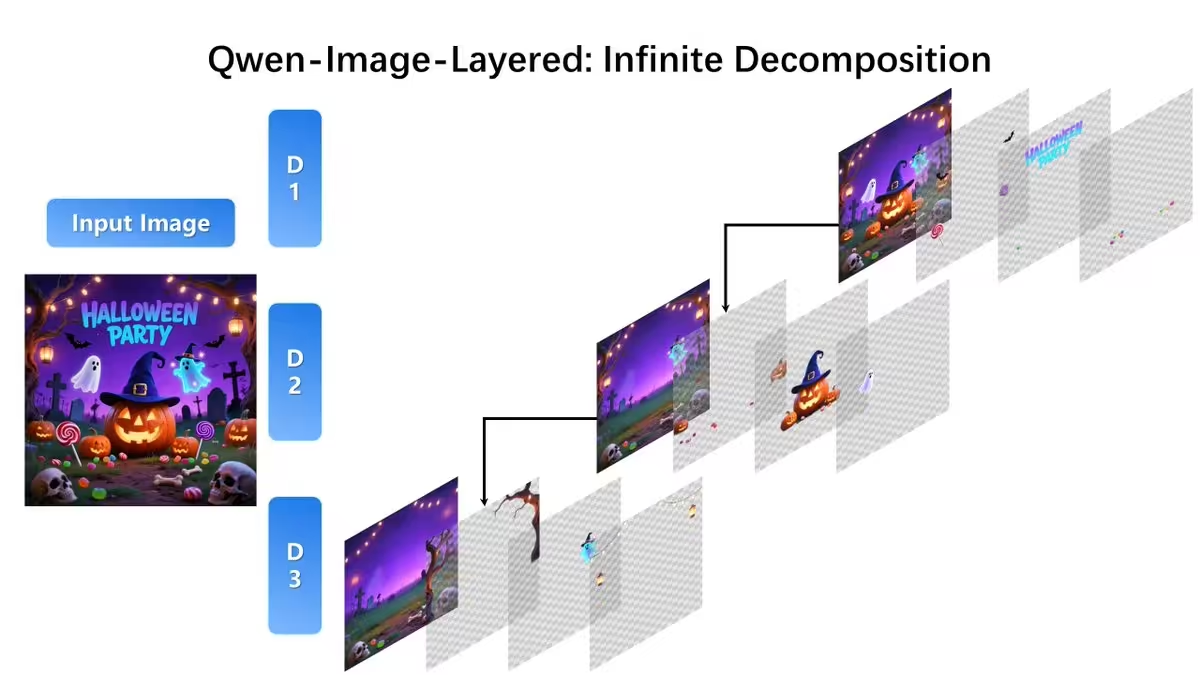 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
🚀 Qwen Code v0.5.0 is here!
✨ What’s new:
• VSCode Integration: Bundled CLI into VSCode release package with improved cross-platform compatibility
• Native TypeScript SDK: Seamlessly integrate with Node/TS
• Smart Session Management: Auto-saves and continue conversations
• Support for OpenAI-compatible reasoning models, including DeepSeek V3.2, Kimi-K2, and more
• Control custom tools via SDK-hosted servers
• Russian Language Support: Added internationalization with Russian language option
• Enhanced User Experience: Terminal bell setting for audio notifications and session resume command display
• Testing & Stability: Better Ubuntu shell support, faster SDK timeouts, and rock-solid test stability
👉 Get started in Terminal
npm install -g @qwen-code/qwen-code
🌐 Check out the full changelog: github.com/QwenLM/qwen-code/releases/tag/v0.5.0
Qwen
@Alibaba_Qwen
VSCode Plugin: Qwen Code Companion
Qwen
@Alibaba_Qwen
🧠 Your Personal AI Learning Tutor Is Here!
🎓Stop merely memorizing. In Qwen Learn Mode, Qwen Chat turns information into understanding that actually sticks.Powered by our Qwen3-Max model and grounded in cognitive psychology, it designs a learning path tailored to the way you think.
✅ Guides you through Socratic-style dialogue, instead of just giving you answers
✅ Adapts to your current level, like a tutor who always works in your optimal learning zone
✅ Builds mental scaffolds so you can handle complex logic without feeling overwhelmed
Unlock your potential, not just the answer key. 🧬
✨Try it now: chat.qwen.ai?inputFeature=learn
 Qwen
@Alibaba_Qwen
🚀 Qwen3-Omni-Flash just got a massive upgrade (2025-12-01 version) !
What's improved:
🎙️ Enhanced multi-turn video/audio understanding - conversations flow naturally
✨ Customize your AI's personality through system prompts (think roleplay scenarios!)
🗣️ Smarter language handling + rock-solid support: 119 text languages | 19 speech
😊 Voices indistinguishable from humans
Try it now:
🎙️ Qwen Chat: click the VoiceChat and VideoChat button (bottom-right): chat.qwen.ai
📝 Blog: qwen.ai/blog?id=qwen3-omni-20251201
🎧 Demo: hf.co/spaces/Qwen/Qwen3-Omni-Demo
🎧 Demo: modelscope.cn/studios/Qwen/Qwen3-Omni-Demo
⚡ Realtime API: modelstudio.console.alibabacloud.com?tab=doc
📥 Offline API: modelstudio.console.alibabacloud.com?tab=doc
 Qwen
@Alibaba_Qwen
🚀 We introduce Soft Adaptive Policy Optimization (SAPO) — a smooth, stable, and highly effective RL method for training large language models.
Why SAPO?
🔹 Hard clipping is brittle — gradients vanish or explode
🔹 MoE models amplify variance, making training even more unstable
SAPO replaces hard boundaries with a continuous, temperature‑controlled gate that:
✨ Smooth trust‑region behavior → no abrupt gradient drop
✨ Sequence-level coherence → align sequence‑level behavior
✨ Token-level adaptivity → preserves useful gradients & boosts sample efficiency
✨ Asymmetric temperatures → significantly improved stability, esp. in MoE models
What does this mean in practice?
📈 Longer stable RL runs
📈 Higher Pass@1
📈 Stronger performance on Qwen3‑VL across math, coding & multimodal tasks
SAPO offers a more scalable and reliable foundation for RL-tuning large language & multimodal models.
📄 Paper: arxiv.org/abs/2511.20347
📚 Blog: qwen.ai/blog?id=sapo
Qwen
@Alibaba_Qwen
🚀 Major Qwen Code v0.2.2-v0.3.0 update summary!
✨ Two breakthrough features:
🎯 Stream JSON Support
• `--output-format stream-json` for streaming output
• `--input-format stream-json` for structured input
• 3-tier adapter architecture + complete session management
• Endless possibilities for SDK integration, automation tools, CI/CD pipelines!
🌍 Full Internationalization
• Built-in EN/CN interface + custom language pack extensions
• `/language ui zh-CN` - One-click UI switching
• `/language output Chinese` - Set AI output language
• Global developers welcome to contribute your local language packs! 🌏
🛡️ Security & Stability Leap Forward
• Fixed memory exhaustion risks with 20MB buffer limits
• Windows encoding fixes, goodbye character corruption
• Enhanced ripgrep binary detection & cross-platform compatibility
• Auth system refactor, optimized authType management
• Integration test fixes, stable CI/CD pipeline
• ModelScope provider support, stream_options handling
• Prompt completion optimization, enhanced terminal notifications
• Multiple core fixes, significantly improved overall stability! 💪
🔗 github.com/QwenLM/qwen-code
Qwen
@Alibaba_Qwen
See you there! 🔥
 Deep Learning For Code @ ICML'26
@DL4Code
🚀 Kicking off in TEN HOUR @ NeurIPS 2025! Deep Learning for Code in the Agentic Era (DL4C) workshop is about to go LIVE! Insane speaker lineup:
@gneubig @dawnsongtweets @pirroh @sidawxyz @LiangchenLuo @JustinLin610
📍 Hall G-H | 09:00–17:00
🎁 Free customized swag for attendees!
🌐 dl4c.github.io
The future of code agents starts TODAY. See you there! 🔥
 Qwen
@Alibaba_Qwen
Our new Qwen3-TTS (version 2025-11-27) is here! 🚀
We've leveled up on what matters most:
✨ More Personalities: Over 49 high-quality voices, from cute and playful to wise and stern. Find your perfect match!
🌍 Global Reach: Now speaks 10 languages (zh, en, de, it, pt, es, ja, ko, fr, ru) & authentic dialects (Minnan, Wu, Cantonese, Sichuan, Beijing, Nanjing, Tianjin, Shaanxi)
🗣️ Insanely Natural: The rhythm and speed adapt just like a real person. It's uncanny. 🎧
Try it now:
🎙️ Qwen Chat: click Response → Read aloud: chat.qwen.ai
📝 Blog: qwen.ai/blog?id=qwen3-tts-1128
🔌 Realtime API: modelstudio.console.alibabacloud.com?tab=doc
🔌 Offline API: modelstudio.console.alibabacloud.com?tab=doc
🎧 Demo: hf.co/spaces/Qwen/Qwen3-TTS-Demo
🎧 Demo: modelscope.cn/studios/Qwen/Qwen3-TTS-Demo
 Qwen
@Alibaba_Qwen
Such an awesome moment!
 Junyang Lin
@JustinLin610

Qwen reposted
 DailyPapers
@HuggingPapers
Alibaba's Qwen3-VL unveils a new era for multimodal AI
It's the most capable vision-language model yet, featuring native 256K context for text and video, enhanced text understanding, and advanced reasoning across diverse visual tasks.
 Qwen
@Alibaba_Qwen
Cool! FP8 RL runs on just 5GB VRAM!
Unsloth AI
@UnslothAI
You can now run FP8 reinforcement learning on consumer GPUs!
Try DeepSeek-R1’s FP8 GRPO at home using only a 5GB GPU.
Qwen3-1.7B fits in 5GB VRAM.
We collabed with PyTorch to make FP8 RL inference 1.4× faster.
Unsloth: 60% less VRAM, 12× longer context.
docs.unsloth.ai/new/fp8-reinforcement-learning
 Qwen
@Alibaba_Qwen
Cool!
 FluxA
@FluxA_Official
Budget-controlled X402 access is now live on Qwen Code @Alibaba_Qwen 🧑💻
Your code agents can now tap into powerful X402 resources to upgrade the vibecoding experience.
FluxA Agent Wallet gives you full budget control for your code agents, enabling more imaginative task construction.
👇Reach out @ZSkyX7 to get an invite code for early access
Qwen
@Alibaba_Qwen
🚀
LM Studio
@lmstudio
Qwen3-Next support in llama.cpp is now live!
Thanks to community contributors 🦾
Run in your terminal:
lms runtime update --channel beta
🚀
 Qwen
@Alibaba_Qwen
llama.cpp (PR #16095) just added support for Qwen3-Next — Qwen’s new hybrid architecture!
You can now run Qwen3-Next locally with efficient CPU/GPU inference. 🚀
🔗 PR: github.com/ggml-org/llama.cpp/pull/16095
Qwen
@Alibaba_Qwen
llama.cpp (PR #16095) just added support for Qwen3-Next — Qwen’s new hybrid architecture!
You can now run Qwen3-Next locally with efficient CPU/GPU inference. 🚀
🔗 PR: github.com/ggml-org/llama.cpp/pull/16095
Qwen
@Alibaba_Qwen
🚀 Qwen3-VL Tech report is now out on arXiv!
From pretraining to post-training, architecture to infra, data to evaluation — we’ve packed in the details for anyone building on vision-language models.
🔥 3 models >1M downloads in just over a month
🏆 Qwen3-VL-8B leads with 2M+ downloads
📚 Built on the shoulders of Qwen2.5-VL (2800+ citations in <10 months!)
Check out the paper for insights, baselines, and future directions.
Let’s keep pushing VLMs forward — together.
arxiv.org/pdf/2511.21631
 Qwen
@Alibaba_Qwen
🏆 We are incredibly honored to announce that our paper, "Gated Attention for Large Language Models: Non-linearity, Sparsity, and Attention-Sink-Free" has received the NeurIPS 2025 Best Paper Award!
A huge congratulations to our dedicated research team for pushing the boundaries of AI.
Read more: blog.neurips.cc/2025/11/26/announcing-the-neurips-2025-be…
 Qwen
@Alibaba_Qwen
Jan-v2-VL, a new multimodal agent for long-horizon tasks, can execute 49 steps without failing—way beyond other models.🚀🧠
👋 Jan
@jandotai
Introducing Jan-v2-VL, a multimodal agent built for long-horizon tasks.
Jan-v2-VL executes 49 steps without failure, while the base model stops at 5 and other similar-scale VLMs stop between 1 and 2.
It achieves longer, stable task execution in your browser without accuracy loss.
3 variants are available:
- Jan-v2-VL-low (efficiency-oriented)
- Jan-v2-VL-med (balanced)
- Jan-v2-VL-high (deeper reasoning and longer execution)
Models: huggingface.co/collections/janhq/jan-v2-vl
To use it, update your Jan App and download Jan-v2-VL from the Model Hub. Activate Browser MCP servers for agentic use cases.
Credit to the @Alibaba_Qwen team for Qwen3-VL-8B-Thinking base model.
Qwen
@Alibaba_Qwen
10,000,000 users creating with Qwen Chat — and we’re just getting started.
From here, let’s begin — chat.qwen.ai 🚀
 Qwen
@Alibaba_Qwen
Awesome! Qwen-Edit-2509-Multi-angle lighting LoRA!
 大雄
@dx8152
Qwen-Edit-2509-Multi-angle lighting LoRA
Download link: huggingface.co/dx8152/Qwen-Edit-2509-Multi-Angle-Lighting
@Ali_TongyiLab
Qwen
@Alibaba_Qwen
🚀 Qwen Code v0.2.1 is here!
We shipped 8 versions(v0.1.0->v0.2.1) in just 17 days with major improvements:
What's New:
🌐 Free Web Search: Support for multiple providers. Qwen OAuth users get 2000 free searches per day!
🎯 Smarter Code Editing: New fuzzy matching pipeline reduces errors and saves tokens—fewer retries needed.
⚙️More Control: Fine-tune AI behavior with temperature, top_p, and max tokens settings.
💻 Better IDE Integration: Enhanced Zed IDE support with todo and task management tools.
📝 Cleaner Output: Tool responses now use plain text instead of complex JSON—easier for AI to understand.
🔍 Improved Search: Better file filtering (respects `.gitignore`), smarter search tools, and standardized naming.
⚡ Faster Performance: Multi-stage normalization pipeline for zero-overhead matching, better Unicode handling, and optimized output limits.
🐛 Bug Fixes: Fixed token limits for multiple models, improved cross-platform support (macOS & Windows), and better stability.
Try it now—smoother, more reliable AI coding!
🔗 github.com/QwenLM/qwen-code
📝 github.com/QwenLM/qwen-code/releases
 Qwen
@Alibaba_Qwen
🚀 Qwen DeepResearch 2511 is LIVE! 🚀
We've just dropped a major upgrade, making your research deeper, faster, and smarter!
🔗: chat.qwen.ai?inputFeature=deep_research
APP: qwen.ai/download
✨ Dual Mode Selection:
Normal Mode: Efficient & versatile for most needs!
Advanced Mode: Go deeper! Devotes extra time for a more thorough analysis. 🧠
📄 File Uploads Enabled: Now you can easily upload your documents or images for the AI to analyze!
⚡️ Boosted Search Power: Drastically improved search efficiency & depth. Read and process more web info in less time!
📊 Precise Report Control: Command the report format—word count, paragraphs, & content! Get comprehensive reports with enhanced citation reliability.
🧑💻 All-New UX: Our new decoupled architecture delivers a smoother, more responsive user experience!
 Qwen
@Alibaba_Qwen
Qwen's image LoRAs are absolutely mind-blowing these days! 🤯🔥
 Min Choi
@minchoi
Qwen Image Edit Light Restoration app
Easily remove shadows and relight in seconds.
Here's how + 4 wild examples:👇
 Qwen
@Alibaba_Qwen
🚀 Huge shoutout to @arena for launching Arena Expert — a game-changer for evaluating LLMs on real, expert-level prompts across 8 critical domains.
🎯 Qwen3-max-preview ranked #4 globally
🎯 Qwen3-235B-A22B-Thinking-2507 ranked #1 among all open-source models!
Proud of what open-source AI can achieve — and excited to keep pushing the frontier together. 💪
Arena.ai
@arena
🚀 Introducing Arena Expert: a new LMArena evaluation framework to identify the toughest, most expert-level prompts from real users, powering a new Expert leaderboard.
We also introduce Occupational Categories that underlie eight new leaderboards:
💻 Software & IT Services
✍️ Writing, Literature, & Language
🔬 Life, Physical, & Social Science
🎭 Entertainment, Sports, & Media
📈 Business, Management, & Financial Ops
🧮 Mathematical
⚖️ Legal & Government
🩺 Medicine & Healthcare
Explore how models perform across fields in thread 🧵 👇
 Qwen
@Alibaba_Qwen
We’ve released an early preview of Qwen3-Max-Thinking—an intermediate checkpoint still in training.
Even at this stage, when augmented with tool use and scaled test-time compute, it achieves 100% on challenging reasoning benchmarks like AIME 2025 and HMMT.
You can try the current version in Qwen Chat and Alibaba Cloud API—more to come as training continues.
Qwen Chat: chat.qwen.ai?thinking=true
Alibaba Cloud API (enable_thinking=True): modelstudio.console.alibabacloud.com?tab=doc
 Qwen
@Alibaba_Qwen
API usage for Qwen3-Max-Thinking-Preview:
Model name: qwen3-max-preview
Parameter setting: enable_thinking=True
 Qwen
@Alibaba_Qwen
🎉 Now you can easily use Qwen3-VL in Jan!
👋 Jan
@jandotai
You can now use Qwen3-VL in Jan.
Find the GGUF model on @huggingface, click "Use this model" and select Jan, or copy the model link and paste it into Jan Hub.
Thanks @Alibaba_Qwen 🧡
Qwen
@Alibaba_Qwen
You can now run Qwen3-VL locally with Unsloth AI.
👇Fine-tune & RL via free notebooks.
Unsloth AI
@UnslothAI
You can now run Qwen3-VL locally! 💜
Run the 235B variant for SOTA vision/OCR on 128GB unified memory (dynamic 4-bit). Includes our chat template fixes.
Qwen3-VL-2B runs at ~40 t/s on 4GB RAM.
Fine-tune & RL via Unsloth free notebooks & export to GGUF.
docs.unsloth.ai/models/qwen3-vl
 Qwen
@Alibaba_Qwen
🎉 Qwen3-VL is now available on llama.cpp!
Run this powerful vision-language model directly on your personal devices—fully supported on CPU, CUDA, Metal, Vulkan, and other backends.
We’ve also released GGUF weights for all variants—from 2B up to 235B. Download and enjoy! 🚀
🤗 Hugging Face: huggingface.co/collections/Qwen/qwen3-vl
🤖 ModelScope: modelscope.cn/collections/Qwen3-VL-5c7a94c8cb144b
📌 PR: github.com/ggerganov/llama.cpp/pull/16780
Qwen
@Alibaba_Qwen
🚀The Qwen3-VL models are now live on LM Studio!
Happy Halloween! 🎃📷👻
LM Studio
@lmstudio
Qwen3-VL models are now live in LM Studio! 🎉🚀
A powerful collection of vision-language models.
Happy Halloween! 🎃👻
 Qwen
@Alibaba_Qwen
Ollama now supports all Qwen3-VL models locally! Give it a try! 🚀
ollama
@ollama
ollama run qwen3-vl
Ollama's engine now supports all the Qwen 3 VL models locally. 2B to 235B parameter sizes.
The smaller models work exceptionally well for their size.
The latest version of Ollama v0.12.7 is needed!
Give it a try! 👇👇👇


 Qwen
@Alibaba_Qwen
🚀 Big shoutout to @Gradient_HQ for making Qwen 235B run on Parallax — the sovereign AI OS we all deserve.
Powerful and built for everyone.
Watch how they did it in minutes 👇
 Gradient
@Gradient_HQ
The Sovereign AI OS everyone deserves.
Parallax lets you set up a local AI cluster across Macs and PCs, and host your own models and applications without performance compromises.
Watch @alex_mirran and the crew get @Alibaba_Qwen 235B running in minutes.
Qwen
@Alibaba_Qwen
✅ Proud to be leading the open-source wave! We believe in building in the open and are excited to continue this journey.
Thanks.@NVIDIAAIDev
 NVIDIA AI Developer
@NVIDIAAIDev
“Researchers need open source. Developers need open source. Companies around the world — we need open source.” -Jensen Huang
#nvidiagtc
Qwen
@Alibaba_Qwen
A great deep-dive on On-Policy Distillation — an efficient way to post-train smaller LLMs with dense, on-policy feedback.
Excited to see Qwen featured in the experiments, showcasing strong math-reasoning gains and continual-learning recovery.
Excellent work by @thinkymachines 👏
 Thinking Machines
@thinkymachines
Our latest post explores on-policy distillation, a training approach that unites the error-correcting relevance of RL with the reward density of SFT. When training it for math reasoning and as an internal chat assistant, we find that on-policy distillation can outperform other approaches for a fraction of the cost.
thinkingmachines.ai/blog/on-policy-distillation/
 Qwen
@Alibaba_Qwen
Introducing Qwen3-VL-2B and Qwen3-VL-32B!
From edge to cloud, these dense powerhouses deliver ultimate performance per GPU memory, packing the full capabilities of Qwen3-VL into compact and scalable forms.
🔥 Qwen3-VL-32B outperforms GPT-5 mini & Claude 4 Sonnet across STEM, VQA, OCR, video understanding, agent tasks, and more.
💡 It matches models up to 235B (even beating them on OSWorld!) with only 32B parameters.
⚡️ FP8 versions available for ultra-efficient deployment.
🔧 Also releasing Instruct & Thinking variants for flexible use cases.
Try it now: chat.qwen.ai?models=qwen3-vl-32b
Hugging Face:huggingface.co/collections/Qwen/qwen3-vl-68d2a7c1b8a8afce…
ModelScope:modelscope.cn/collections/Qwen3-VL-5c7a94c8cb144b
API - instruct: modelstudio.console.alibabacloud.com?tab=doc
API - thinking: modelstudio.console.alibabacloud.com?tab=doc
Cookbook: github.com/QwenLM/Qwen3-VL/tree/main/cookbooks
 Qwen
@Alibaba_Qwen
Thinking
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
Qwen Deep Research just got a major upgrade. ⚡️
It now creates not only the report, but also a live webpage 🌐 and a podcast 🎙️ - Powered by Qwen3-Coder, Qwen-Image, and Qwen3-TTS.
Your insights, now visual and audible. ✨
👉 chat.qwen.ai?inputFeature=deep_research
Qwen
@Alibaba_Qwen
Huge thanks to @UnslothAI for enabling free, easy fine-tuning of Qwen3-VL (8B)! 🙌
Unsloth AI
@UnslothAI
You can now fine-tune Qwen3-VL (8B) for free with our notebook!
Unsloth trains VLMs 1.7x faster with 60% less VRAM and 8x longer context - no accuracy loss.
GitHub: github.com/unslothai/unsloth
Qwen3-VL GRPO Colab: docs.unsloth.ai/models/qwen3-vl-run-and-fine-tune
Qwen3-VL Colab: colab.research.google.com/github/unslothai/notebooks/blob…
Qwen
@Alibaba_Qwen
Cool!
 Adrien Grondin
@adrgrondin
The latest Qwen 3 VL by @Alibaba_Qwen running on iPhone 17 Pro with MLX
Qwen 3 VL brings upgraded visual understanding, recognition, and OCR capabilities without sacrificing text performance like previous models
The 4B model here is close to Qwen 2.5 VL 72B in many benchmarks
Qwen
@Alibaba_Qwen
Excited to announce the launch of Qwen3-VL-Flash on Alibaba Cloud Model Studio! 🚀
A powerful new vision-language model that combines reasoning and non-reasoning modes, outperforming open-source Qwen3-VL-30B-A3B and Qwen2.5-72B with faster responses, stronger capabilities, and lower cost!
📸 Supports ultra-long context (up to 256K tokens) – perfect for long videos & documents
🧠 Enhanced image/video understanding with 2D/3D localization and spatial awareness
🌍 Advanced OCR, multilingual recognition, agent control & real-world applications
🚨 Significantly improved security perception and real-environment visual intelligence
API: modelstudio.console.alibabacloud.com?tab=doc
 Qwen
@Alibaba_Qwen
We're open-sourcing several core components from the Qwen3Guard Technical Report, now available for research and community use:
🔹 Qwen3-4B-SafeRL: A safety-aligned model fine-tuned via reinforcement learning using feedback from Qwen3Guard-Gen-4B.
→ Achieves significant safety improvement on WildJailbreak (64.7 → 98.1) without compromising general task performance.
🔹 Qwen3GuardTest: A benchmark for evaluating Guard models, covering:
(1) Safety classification of intermediate reasoning/thinking content
(2) Moderation of streaming/token-by-token outputs
🔗 Hugging Face: huggingface.co/Qwen/Qwen3-4B-SafeRL
🤖 ModelScope:
modelscope.cn/models/Qwen/Qwen3-4B-SafeRL
📊 Dataset: huggingface.co/datasets/Qwen/Qwen3GuardTest
💻 Code & Details: github.com/QwenLM/Qwen3Guard
Qwen
@Alibaba_Qwen
🧠 Meet Your AI Memory
Unlock richer, more personal experiences—Qwen Chat Memory uses your context and history to tailor every interaction, so everything feels made just for you.
🔖 Stores meaningful and important memories about you
🔍 Recalls past interaction relevant to the current context
✨ Transforms your history into deeply personalized experiences
Your past, remembered. Your future, tailored. 🎯
Try it now:chat.qwen.ai

Qwen reposted
 Andrej Baranovskij
@andrejusb
Qwen3-VL is very good for JSON structured output and is insanely fast 💨
Thanks @Alibaba_Qwen team!
Qwen
@Alibaba_Qwen
Introducing the compact, dense versions of Qwen3-VL — now available in 4B and 8B pairs, each with both Instruct and Thinking variants.
✅ Lower VRAM usage
✅ Full Qwen3-VL capabilities retained
✅ Strong performance across the board
Despite their size, they outperform models like Gemini 2.5 Flash Lite and GPT-5 Nano, and often beat them on benchmarks spanning STEM, VQA, OCR, video understanding, agent tasks, and more. In many cases, they even rival our flagship Qwen2.5-VL-72B from just six months ago!
Plus, FP8 versions are also available for efficient deployment.
Hugging Face: huggingface.co/collections/Qwen/qwen3-vl-68d2a7c1b8a8afce…
ModelScope: modelscope.cn/collections/Qwen3-VL-5c7a94c8cb144b
Qwen3-VL-8B-Instruct API: modelstudio.console.alibabacloud.com?tab=doc
Qwen3-VL-8B-Thinking API: modelstudio.console.alibabacloud.com?tab=doc
Cookbooks: github.com/QwenLM/Qwen3-VL/blob/main/cookbooks
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
Kaggle link: www.kaggle.com/models/qwen-lm/qwen-3-vl
Qwen
@Alibaba_Qwen
Qwen3-VL (Dense & MoE) is now supported in MLX-VLM. Huge thanks to the open-source community.
Prince Canuma
@Prince_Canuma
The new dense Qwen3-VL models from @Alibaba_Qwen have day-0 support on MLX-VLM!
Get started today:
> pip install -U mlx-vlm
Model weights:
huggingface.co/collections/mlx-community/qwen3-vl-68ee8f5…
Qwen
@Alibaba_Qwen
Qwen3-VL 8B Thinking & Instruct are now live on imarena.ai
Arena.ai
@arena
🚨 New model drops!
Qwen 3 VL 8b Thinking and Qwen 3 VL 8b Instruct have entered the Text and Vision Arenas!
@Alibaba_Qwen's Qwen3-VL just got lighter, but with the same full-stack capabilities, let's see how they rank on the leaderboards.
🗳️ Get prompting in Battle mode with your toughest real-world use cases, and through your votes, we'll know soon!
 Qwen
@Alibaba_Qwen
Introducing the compact, dense versions of Qwen3-VL — now available in 4B and 8B pairs, each with both Instruct and Thinking variants.
✅ Lower VRAM usage
✅ Full Qwen3-VL capabilities retained
✅ Strong performance across the board
Despite their size, they outperform models like Gemini 2.5 Flash Lite and GPT-5 Nano, and often beat them on benchmarks spanning STEM, VQA, OCR, video understanding, agent tasks, and more. In many cases, they even rival our flagship Qwen2.5-VL-72B from just six months ago!
Plus, FP8 versions are also available for efficient deployment.
Hugging Face: huggingface.co/collections/Qwen/qwen3-vl-68d2a7c1b8a8afce…
ModelScope: modelscope.cn/collections/Qwen3-VL-5c7a94c8cb144b
Qwen3-VL-8B-Instruct API: modelstudio.console.alibabacloud.com?tab=doc
Qwen3-VL-8B-Thinking API: modelstudio.console.alibabacloud.com?tab=doc
Cookbooks: github.com/QwenLM/Qwen3-VL/blob/main/cookbooks
Qwen
@Alibaba_Qwen
Qwen3-VL 235B is now live on Ollama’s cloud — free to try!
ollama
@ollama
Qwen3-VL 235B is available on Ollama's cloud! It's free to try.
ollama run qwen3-vl:235b-cloud
The smaller models, and the ability to run fully on-device will be coming very soon!
See examples and how to use the model on Ollama!
👇👇👇


 Qwen
@Alibaba_Qwen
Run Qwen3-VL on Mac with LM Studio + MLX.
LM Studio
@lmstudio
The next generation of Qwen-VL models is here!
> Qwen3-VL 4B (dense, ~3GB)
> Qwen3-VL 8B (dense, ~6GB)
> Qwen3-VL 30B (MoE, ~18GB)
These models come with comprehensive upgrades to visual perception, spatial reasoning, and image understanding.
Supported with 🍎MLX on Mac.
 Qwen
@Alibaba_Qwen
Thank you for the amazing support for Qwen3-VL model! 🙏 @nexa_ai
Qwen
@Alibaba_Qwen
So fast!
 Vincent Amato
@vincentaamato
Qwen3-VL 30B-A3B at 4-bit precision, running on Apple silicon at 80 tok/s with MLX! @awnihannun @Prince_Canuma @ostensiblyneil @lmstudio
Qwen
@Alibaba_Qwen
Thank you! Glad you enjoyed the new Qwen3 models.
 Alamin
@iam_chonchol
🚨BREAKING🚨: Qwen3 just shipped a new batch of models; and yeah, they go hard.
I’ve been testing them all day, and the upgrades are actually noticeable.
Let’s talk about what changed and give you my hands-on experience👇
#qwen3 #qwen
 Qwen
@Alibaba_Qwen
enjoy🥰
 Lisan al Gaib
@scaling01
Qwen3-Next-80B-A3B is one of my favorite model launches this year
 Qwen
@Alibaba_Qwen
🚀Qwen3-VL-235B-A22B-Instruct is now #1 on OpenRouter for image processing — 48% market share!
🎉Huge thanks to our amazing community.
 Qwen
@Alibaba_Qwen
🚀 Exciting updates in Qwen Code v0.0.12–v0.0.14!
✨ What’s new?
• Plan Mode: AI proposes a full implementation plan—you approve before a single line changes.
• Vision Intelligence: Auto-switch to vision models (Qwen3-VL-Plus with 256K input / 32K output!) when images appear—even in YOLO mode.
• Zed Integration: Now supports both OpenAI & Qwen OAuth auth.
• More control: Toggle loop detection, confirm qwen.md overwrites, and fine-tune your workflow.
🔧 Under the hood:
• Fixed multi-line paste on Windows
• Resolved Zed auth hang with Qwen OAuth
• Corrected malformed tool calls & output token limits
• Improved subagent performance & UI
• Fixed Markdown list rendering on Windows
• Removed buggy editCorrector injecting escape chars
• Enabled high-res image support for Qwen3-VL-Plus
• Fixed ripgrep loading & TaskTool sync issues
💻Qwen Code: github.com/QwenLM/qwen-code
Qwen
@Alibaba_Qwen
Plan Mode: Implement Plan Mode for Safe Code Planning (#658) - Introduces a new workflow where AI generates a plan for user review before execution.
 Qwen
@Alibaba_Qwen
Zed Integration: Add OpenAI and Qwen OAuth auth support to Zed ACP integration (#678) - Adds authentication support for OpenAI and Qwen OAuth in Zed. allowing Zed users to authenticate with OpenAI API keys or Qwen OAuth.
 Qwen
@Alibaba_Qwen
Command Enhancement: Enhance /init command with confirmation prompt (#624) - Adds a confirmation dialog when a qwen.md file already exists with content.
 Qwen
@Alibaba_Qwen
We’ve fixed the bug that limited Qwen3-Omni to recognizing only the first 30 seconds of audio.
github.com/QwenLM/Qwen3-Omni/discussions/36
Qwen
@Alibaba_Qwen
Cool! A clever rhyming puzzle game powered by Qwen!
 Ali Abid
@anotheraliabid
I built a rhyming puzzle game, with clues generated by Qwen! Try it out - link in the next post.
Qwen
@Alibaba_Qwen
Introducing Qwen3-VL Cookbooks! 🧑🍳
A curated collection of notebooks showcasing the power of Qwen3-VL—via both local deployment and API—across diverse multimodal use cases:
✅ Thinking with Images
✅ Computer-Use Agent
✅ Multimodal Coding
✅ Omni Recognition
✅ Advanced Document Parsing
✅ Precise Object Grounding (across formats!)
✅ General OCR & Key Info Extraction
✅ 3D Grounding
✅ Long Document Understanding
✅ Spatial Reasoning
✅ Mobile Agent
✅ Video Understanding
🔗Link: github.com/QwenLM/Qwen3-VL/tree/main/cookbooks
⚙️ API: alibabacloud.com/help/en/model-studio/user-guide/vision/
💬 Qwen Chat: chat.qwen.ai?models=qwen3-vl-plus
Explore, experiment, and build the future of multimodal AI! 🚀
 Qwen
@Alibaba_Qwen
There’s still a way to go for omni models to match human-level responsiveness and reasoning—but we won’t stop improving. Hope you love Qwen3-Omni - natively end-to-end multilingual omni model.
Artificial Analysis
@ArtificialAnlys
Alibaba has released Qwen3 Omni and Qwen3 Omni Realtime - two natively end-to-end "omni"-modal models that process text, images, audio, and video in a single unified architecture. Artificial Analysis benchmarking shows competitive Speech to Speech performance, as well as high-speeds for Realtime version.
Qwen3 Omni and Qwen3 Omni Realtime process audio, video, and text inputs directly in a unified architecture, enabling native multimodal reasoning and simultaneous generation of both text and natural speech responses. The architecture uses a "Thinker" MoE and "Talker" MoE, with the Talker decoupled from the Thinker's text representations to enable independent control of response style and audio characteristics. Both models supports 119 text languages, 19 speech input languages, and 10 speech output languages.
Speech to Speech capabilities:
➤ Reasoning: Qwen3 Omni 30B scores 58% on Big Bench Audio while Qwen3 Omni Realtime scores 59% - both ahead of Gemini 2.0 Flash (36%) but trailing GPT-4o Realtime (68%)
➤ Latency: Time to first audio averages 4.8 seconds for Qwen3 Omni 30B and 0.9 seconds for Qwen3 Omni Realtime, compared to leading models at 0.6s. There is still a way to go for models to reach human levels of responsiveness, averaging 0.2-0.3 seconds
Additional model details:
➤ Availability: Qwen3 Omni 30B is available via Alibaba Cloud DashScope API Qwen3-Omni-Flash endpoint. Qwen3-Omni-30B-A3B model weights (Instruct, Thinking, and Captioner variants) are available on Hugging Face and ModelScope under Apache 2.0 license
➤ Voice options: 17 voice types available via API with 24kHz audio output

 Qwen
@Alibaba_Qwen
Thanks @kis for the awesome demo!
 きしだൠ(K1S)
@kis
Qwen Image Editによるコーラとピザを持つように描きかえ、結構完璧にやってくれてる
 Qwen
@Alibaba_Qwen
Thank you @ArtificialAnlys ! 🙏 Qwen Image Edit 2509 ranks #3 overall and leads all open-weight models — enabling multi-image editing with precise control.
Try it now: chat.qwen.ai?inputFeature=image_edit
Artificial Analysis
@ArtificialAnlys
Qwen Image Edit 2509 is the new leading open weights image editing model, ranking #3 overall in the Artificial Analysis Image Editing Arena and introducing multi-image editing capabilities!
The latest release from Alibaba Qwen trails only Gemini 2.5 Flash (Nano-Banana) and Seedream 4.0 in our Image Editing Arena, while leading all open weights alternatives.
Qwen Image Edit 2509 supports multiple image inputs combined with text prompts, enabling finer control of the output image and a notable upgrade from the single image input of the original Qwen Image Edit model.
Released under Apache 2.0 license with weights available on @huggingface, it maintains competitive pricing at $30/1k images on @fal and @replicate (listed as "Qwen Image Edit Plus"), matching its predecessor while delivering enhanced capabilities.
See below for comparisons between Qwen Image Edit 2509 and other leading models in our Image Editing Arena 🧵
 Qwen
@Alibaba_Qwen
Glad you like it — enjoy! 😊
 Goutham Rajesh
@GouthamRajesh4
Qwen3-Max, is the best model that I've used so far for making a PRD without a load of 'feature-shit'.
@Alibaba_Qwen
Qwen
@Alibaba_Qwen
Very funny! Qwen3-VL never misses 🐱
Try it now: chat.qwen.ai

 Raf
@RfSharko
You guys really cooked with Qwen3-VL 💀. It's the only LLM to find the hidden cat

 Qwen
@Alibaba_Qwen
Qwen3-VL secured 2nd place in the vision leaderboard and became the first open-source model to rank first in both the pure text and visual leaderboards.
 Zain
@zainhas
qwen3 VL instruct is 2nd on the vision leaderboard!
been very long since we've had an open VLM competitive with proprietary ones
 Qwen
@Alibaba_Qwen
This is genuinely useful - powered by Qwen-VL-30B-A3B
 Daniel van Strien
@vanstriendaniel
Built a very quick @Gradio to start exploring the new @Alibaba_Qwen-VL-30B-A3B-Instruct model for extracting structured information from library index cards.
 Qwen
@Alibaba_Qwen
Glad to see Qwen-Image-Edit Plus (2509) on Runware — open, cost-effective, and powerful. 🚀
 Runware
@runware
🚀 Qwen-Image-Edit Plus (2509) is live on Runware!
An open-source alternative to Nano Banana is finally here, starting at just $0.0077 per image.
- Multi-image & single-image editing
- High quality & flexible
- Nearly 4x lower price than competitors


 Qwen
@Alibaba_Qwen
Glad to see Qwen-Image-Edit-2509 enabling advanced pose-aware fashion generation. Thanks @gregschoeninger for showing off what’s possible!
 Greg Schoeninger
@gregschoeninger
We fine-tuned Qwen-Image-Edit-2509 for multi-angle fashion model generation.
Input: model at one angle + pose reference Output: same model, new angle, high quality
Learn how we did it 👇
 Qwen
@Alibaba_Qwen
🚀 Qwen3-VL-30B-A3B-Instruct & Thinking are here!
Smaller size, same powerhouse performance 💪—packed with all the capabilities of Qwen3-VL!
🔧 With just 3B active params, it’s rivaling GPT-5-Mini & Claude4-Sonnet — and often beating them across STEM, VQA, OCR, Video, Agent tasks, and more.
And that’s not all: we’re also releasing an FP8 version, plus the FP8 of the massive Qwen3-VL-235B-A22B!
Try it out and make your multimodal AI applications run faster!🧠🖼️
Qwen Chat: chat.qwen.ai?models=qwen3-vl-30b-a3b
Github&Cookbooks: github.com/QwenLM/Qwen3-VL/blob/main/cookbooks
API: www.alibabacloud.com/help/en/model-studio/models
Blog: qwen.ai/blog?id=99f0335c4ad9ff6153e517418d48535ab6d8afef&…
ModelScope: modelscope.cn/collections/Qwen3-VL-5c7a94c8cb144b
HuggingFace: huggingface.co/collections/Qwen/qwen3-vl-68d2a7c1b8a8afce…
 Qwen
@Alibaba_Qwen
Performance of Qwen3-VL-30B-A3B-Thinking
 Qwen
@Alibaba_Qwen
Pure text performance
 Qwen
@Alibaba_Qwen
Qwen-Image-2509 improves consistency ✨
Hope you enjoy it!
🤝 Thanks @drawthingsapp for showcasing it so well!
 Draw Things
@drawthingsapp
👩🏻💼 From a Casual Daily Photo to a Work ID Photo or Profile Picture.
🆚 Qwen Image Edit already does a decent job, but 2509 performs even better!
🧪 All the images were generated in Draw Things.
👨🏼💻 Qwen Image Edit 2509 Support is on the way, stay tuned!
👇🏻 Click on this post to see the detailed prompts.


 Qwen
@Alibaba_Qwen
Proud to see Qwen in the first wave of supported models — and thrilled to empower researchers and developers with flexible, accessible fine-tuning tools.
We’ll continue releasing powerful open models to support research, innovation, and collaboration across the community. 💡🤝
The future is something we build together!
 Thinking Machines
@thinkymachines
Introducing Tinker: a flexible API for fine-tuning language models.
Write training loops in Python on your laptop; we'll run them on distributed GPUs.
Private beta starts today. We can't wait to see what researchers and developers build with cutting-edge open models!
 Qwen
@Alibaba_Qwen
Qwen3 VL Instruct just topped the ClockBench leaderboard!
 Alek Safar
@alek_safar
A completely unexpected ClockBench development:
- Qwen3 VL Thinking proved to be quite strong, above OpenAI o3 and Gemini 2.5 Pro
- However, Qwen3 VL Instruct (a less reasoning-heavy version) set the new record far beyond any other model, huge congrats to @JustinLin610 and the team!
- Given that finding, I tested GPT-5 Chat (which is typically not included in favor of more powerful reasoning models) - and it also showed better performance than GPT-5 High or o3 Pro, taking 2nd place; congrats @polynoamial @BorisMPower!
 Qwen
@Alibaba_Qwen
Train Qwen LoRAs for free - powered by @ostrisai & @huggingface ! Can't wait to see everyone's creations!
 apolinario (poli)
@multimodalart
the 𝑳𝒐𝑹𝑨 𝔣𝔯𝔢𝔷𝔫𝔦 is LIVE
Train Qwen, Wan and FLUX LoRAs for free for 1 week (Sep 29 - Oct 6th)
We cobbled together @ostrisai AI Toolkit & the new @huggingface Jobs API together
 Qwen
@Alibaba_Qwen
🎙️ New Feature Alert!
Qwen Chat now reads responses aloud — powered by Qwen3-TTS.
👉 On Web, iOS, or Android: Tap the speaker icon 🔊 below any response.
⚙️ In Settings > General > Voice, pick your favorite voice (like “Cherry”!).
Listen. Don’t just read. 🎧
Qwen
@Alibaba_Qwen
🎨Qwen-Image-Edit-2509 just redefined architectural visualization!
🏙️From sketch to stunning reality — seamlessly transfer ANY style onto buildings & cityscapes.
→ Traditional Chinese patterns? Done.
→ Photorealistic urban render? Perfect.
AI doesn’t just edit images — it understands structure, context, and aesthetics.
Thanks to community for sharing these inspiring case studies! 🙏

 Qwen
@Alibaba_Qwen
🚀With Code Interpreter + Web Search, Qwen Chat can now fetch data AND visualize it in charts — instantly.
Need a 7-day weather trend? Done. 🌡️📊
Try it now: chat.qwen.ai
 Qwen
@Alibaba_Qwen
Thanks for the shoutout, ZenMux! Qwen3-Max is live and ready to help you build amazing things.
ZenMux
@ZenMuxAI
🚀 Qwen3-Max Now Live on ZenMux, ready to amaze!
🔥 This is @Alibaba_Qwen 's new flagship. Dive in and experience the power!
👉 Try it now: zenmux.ai/qwen/qwen3-max

 Qwen
@Alibaba_Qwen
Qwen3-Max is here—and we’re just getting started on our journey to improve!
Artificial Analysis
@ArtificialAnlys
Alibaba’s updated Qwen3 Max is the most intelligent non-reasoning model, placing ahead of Kimi K2 0905!
Key takeaways:
➤ Intelligence uplift: Intelligence increased by +6 points to 55 in our Artificial Analysis Intelligence Index. Qwen3 Max is currently the most intelligent non-reasoning model. The previous most intelligent non-reasoning model, Kimi K2 0905, scored 50 on the index
➤ GA: Alibaba’s upgraded Qwen3 Max model is now in GA, the prior version was in Preview
➤ Broader capability improvements: Improvements across agentic tool use (𝜏²-Bench Telecom scores increased from 33% to 74%), coding (LiveCodeBench from 65% to 77%), and long context reasoning (AA-LCR from 40% to 47%).
➤ Higher token usage: Running the Artificial Analysis Intelligence Index required ~21M output tokens, ~7M more than Qwen3 Max (Preview). This continues the trend of non-reasoning models becoming more verbose, though there remains a distinction with Qwen3 Max still significantly below reasoning models
Key model information:
➤🧠 Reasoning: Qwen3 Max is a non-reasoning model. Alibaba has indicated that a reasoning version, Qwen3-Max-Thinking, is under active training.
➤🔒 Proprietary: Like the Preview version, Qwen3 Max is proprietary, since Alibaba has not released the weights.
➤⚙️ Context window: The model supports a 256k-token context window.
➤📷 Multimodality: Qwen3 Max is text-only, with no multimodal inputs or outputs.
➤💲Pricing: The model is priced at $1.2/$6 per 1M input/output tokens
Qwen3 Max is currently available in Qwen Chat and via Alibaba Cloud.
 Qwen
@Alibaba_Qwen
Smart guy!
 Ethan Mollick
@emollick
So far, Qwen3-Max seems impressive for a non-reasoning model, doing a good job at a lot of my weird tests that even some reasoners struggle with.
 Qwen
@Alibaba_Qwen
Try the new Qwen models in the Arena!
Arena.ai
@arena
🚨 New Models Update!
🔥 Qwen3 coming in hot into the Arena with three different models:
🔹Qwen3-VL-235b-a22b-thinking for Text & Vision
🔹Qwen3-VL-235b-a22b-instruct for Text & Vision
🔹Qwen3-Max-2025-9-23 for Text
Check out the thread to learn more about them and get testing! Your votes drive the leaderboards.

Qwen reposted
 Chetaslua
@chetaslua
QWEN-3 MAX is so good
this level of details was only generated by gemini deepthink before one shottes
3d simulation of a procedurally generated mini planet
Qwen
@Alibaba_Qwen
🚀 Qwen3-Max is here—no preview, just power!
Qwen Chat:chat.qwen.ai
Blog: qwen.ai/blog?id=241398b9cd6353de490b0f82806c7848c5d2777d&…
API: www.alibabacloud.com/help/en/model-studio/models
We’ve supercharged coding & agentic skills—now Qwen3-Max-Instruct without thinking rivaling top models on SWE-Bench, Tau2-Bench, SuperGPQA, LiveCodeBench, and AIME25.
With Qwen3-Max-Thinking equipped with tool use and deployed in heavy mode, it’s nearly perfect on key benchmarks. Built on massive scale + data, and backed by relentless compute scaling in pre-training & RL.
This is Qwen’s new flagship. Try it now! 💡
 Qwen
@Alibaba_Qwen
🚀 Qwen3-Max is here—no preview, just power!
Qwen Chat:chat.qwen.ai
Blog: qwen.ai/blog?id=241398b9cd6353de490b0f82806c7848c5d2777d&…
API: www.alibabacloud.com/help/en/model-studio/models
We’ve supercharged coding & agentic skills—now Qwen3-Max-Instruct without thinking rivaling top models on SWE-Bench, Tau2-Bench, SuperGPQA, LiveCodeBench, and AIME25.
With Qwen3-Max-Thinking equipped with tool use and deployed in heavy mode, it’s nearly perfect on key benchmarks. Built on massive scale + data, and backed by relentless compute scaling in pre-training & RL.
This is Qwen’s new flagship. Try it now! 💡
Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
🚀 We're thrilled to unveil Qwen3-VL — the most powerful vision-language model in the Qwen series yet!
🔥 The flagship model Qwen3-VL-235B-A22B is now open-sourced and available in both Instruct and Thinking versions:
✅ Instruct outperforms Gemini 2.5 Pro on key vision benchmarks
✅ Thinking achieves state-of-the-art (SOTA) performance on multimodal reasoning tasks
✨ Key breakthroughs:
🖥️ Visual Agent: Operates GUIs on PC/phone — understands buttons, calls tools, and completes real-world tasks (SOTA on OS World)
💻 Visual Coding: Transforms screenshots into code (HTML/CSS/JS, draw.io) — true "what you see is what you get" development
📚 256K+ context (scalable to 1M) → supports 2-hour videos and multi-page long PDFs
🌍 32-language OCR with enhanced robustness for blurry, tilted, or rare characters
📐 Advanced spatial reasoning: 2D → relative coordinates, 3D grounding, occlusion handling, and perspective understanding
🧠 Thinking Mode: Leading performance in STEM/Math — enables deep causal reasoning
🔤 Text capabilities rival top-tier LLMs — a solid language foundation powering its multimodal excellence
From "seeing" to "understanding", from "recognizing" to "reasoning & acting"
Qwen Chat: chat.qwen.ai?models=qwen3-vl-plus
API: www.alibabacloud.com/help/en/model-studio/models
Blog:qwen.ai/blog?id=99f0335c4ad9ff6153e517418d48535ab6d8afef&…
ModelScope: modelscope.cn/collections/Qwen3-VL-5c7a94c8cb144b
HuggingFace: huggingface.co/collections/Qwen/qwen3-vl-68d2a7c1b8a8afce…
 Qwen
@Alibaba_Qwen
Thinking Performance
 Qwen
@Alibaba_Qwen
no-thinking text performance
 Qwen
@Alibaba_Qwen
thinking text performance
 Qwen
@Alibaba_Qwen
thinking with image
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
Multilingual OCR
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
more cases
Qwen
@Alibaba_Qwen
We're excited to announce the upgrade of Qwen3-Coder, and the upgraded API `qwen3-coder-plus` is now available on Alibaba Cloud Model Studio with major improvements:
💻 Enhanced terminal task capabilities and better performance on Terminal Bench (w/ Qwen Code / Claude Code)
🏆 SWE-Bench performance up to 69.6
🔒 Safer code generation
Qwen Chat: chat.qwen.ai?models=qwen3-coder-plus
API: www.alibabacloud.com/help/en/model-studio/models
Additionally, we have upgraded our coding product, Qwen Code , by adding the support of multimodal model and sub-agent. From now on, you can input images while you collaborate with Qwen Code.
Qwen Code: github.com/QwenLM/qwen-code
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-LiveTranslate-Flash — Real‑Time Multimodal Interpretation — See It, Hear It, Speak It!
🌐 Wide language coverage — Understands 18 languages & 6 dialects, speaks 10 languages.
👁️ Vision‑Enhanced Comprehension — Reads lips, gestures, on‑screen text and real‑world entities, robust in noise.
⚡ 3s Latency — Near‑instant real-time translation.
🎯 Lossless Interpretation — Offline‑level translation accuracy.
🎙️ Natural, expressive voices.
Connect with the world face-to-face, in real time.
🔗 Blog: qwen.ai/blog?id=4266edf7f3718f2d3fda098b3f4c48f3573215d0&…
💻 Dashscope: www.alibabacloud.com/help/en/model-studio/qwen3-livetrans…
🤗 Demo: huggingface.co/spaces/Qwen/Qwen3-Livetranslate-Demo
 Qwen
@Alibaba_Qwen
Performance
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
😷😷😷
Qwen
@Alibaba_Qwen
🚀 Your Personal AI Travel Designer Is Here! 🍁
Stop wasting hours planning trips. Qwen Chat Travel Planner crafts complete, day-by-day itineraries tailored JUST for you — powered by Amap, Fliggy APIs and Search.
✅ Recommends perfect hotels & transport routes
✅ Builds detailed schedules
✅ Adapts to your interests, pace & budget
Travel smarter, not harder. ✈️🗺️
Try it now:chat.qwen.ai?inputFeature=travel
Qwen
@Alibaba_Qwen
🛡️ Meet Qwen3Guard — the Qwen3-based safety moderation model series built for global, real-time AI safety!
🌍 Supports 119 languages and dialects
✅ 3 sizes available: 0.6B, 4B, 8B
⚡ Low-latency, Real-time streaming detection with Qwen3Guard-Stream
📝 Robust Full-context safety analysis with Qwen3Guard-Gen — ideal for RL reward modeling!
🚦 3-tier risk classification: ✅ Safe / ⚠️ Controversial / ❌ Unsafe
🏆 SOTA performance on safety benchmarks — English, Chinese & beyond!
✨ Try it now ✨
🤗 Hugging Face: huggingface.co/collections/Qwen/qwen3guard-68d2729abbfae4…
🤖 ModelScope: modelscope.cn/collections/Qwen3Guard-308c39ef5ffb4b
📄 Tech Report: github.com/QwenLM/Qwen3Guard/blob/main/Qwen3Guard_Technic…
📦 GitHub Repo: github.com/QwenLM/Qwen3Guard
 Qwen
@Alibaba_Qwen
Performance

Qwen reposted
 AK
@_akhaliq
Qwen-Image-Edit-2509 is out
Multi-image Editing Support: It supports various combinations such as "person + person," "person + product," and "person + scene." Optimal performance is currently achieved with 1 to 3 input images.
Improved Person Editing Consistency: Better preservation of facial identity, supporting various portrait styles and pose transformations
Improved Product Editing Consistency: Better preservation of product identity, supporting product poster editing
Improved Text Editing Consistency: In addition to modifying text content, it also supports editing text fonts, colors, and materials
Native Support for ControlNet: Including depth maps, edge maps, keypoint maps, and more
vibe coded a quick app in anycoder
 Qwen
@Alibaba_Qwen
🔥 Qwen-Image-Edit-2509 IS LIVE — and it’s a GAME CHANGER. 🔥
We didn’t just upgrade it. We rebuilt it for creators, designers, and AI tinkerers who demand pixel-perfect control.
✅ Multi-Image Editing? YES.
Drag in “person + product” or “person + scene” — it blends them like magic. No more Franken-images.
✅ Single-Image? Rock-Solid Consistency.
• 👤 Faces stay you — through poses, filters, and wild styles.
• 🛍️ Products keep their identity — ideal for ads & posters.
• ✍️ Text? Edit everything: content, font, color, even material texture.
✅ ControlNet Built-In.
Depth. Edges. Keypoints. Plug & play precision.
✨ Blog: qwen.ai/blog?id=7a90090115ee193ce6a7f619522771dd9696dd93&…
💬 QwenChat: chat.qwen.ai?inputFeature=image_edit
🐙 GitHub: github.com/QwenLM/Qwen-Image
🤗 HuggingFace: huggingface.co/Qwen/Qwen-Image-Edit-2509
🧩 ModelScope: modelscope.cn/models/Qwen/Qwen-Image-Edit-2509
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Omni — the first natively end-to-end omni-modal AI unifying text, image, audio & video in one model — no modality trade-offs!
🏆 SOTA on 22/36 audio & AV benchmarks
🌍 119L text / 19L speech in / 10L speech out
⚡ 211ms latency | 🎧 30-min audio understanding
🎨 Fully customizable via system prompts
🔗 Built-in tool calling
🎤 Open-source Captioner model (low-hallucination!)
🌟 What’s Open-Sourced?
We’ve open-sourced Qwen3-Omni-30B-A3B-Instruct, Qwen3-Omni-30B-A3B-Thinking, and Qwen3-Omni-30B-A3B-Captioner, to empower developers to explore a variety of applications from instruction-following to creative tasks.
Try it now 👇
💬 Qwen Chat: chat.qwen.ai?models=qwen3-omni-flash
💻 GitHub: github.com/QwenLM/Qwen3-Omni
🤗 HF Models: huggingface.co/collections/Qwen/qwen3-omni-68d100a86cd090…
🤖 MS Models:
modelscope.cn/collections/Qwen3-Omni-867aef131e7d4f
🎬 Demo: huggingface.co/spaces/Qwen/Qwen3-Omni-Demo
 Qwen
@Alibaba_Qwen
Use the voice chat and video chat features on Qwen Chat to experience the Qwen3-Omni model.
Qwen
@Alibaba_Qwen
Performance
 Qwen
@Alibaba_Qwen
🎙️ Meet Qwen3-TTS-Flash — the new text-to-speech model that’s redefining voice AI!
Demo: huggingface.co/spaces/Qwen/Qwen3-TTS-Demo
Blog: qwen.ai/blog?id=b4264e11fb80b5e37350790121baf0a0f10daf82&…
Video: youtu.be/MC6s4TLwX0A
✅ Best-in-class Chinese & English stability
🌍 SOTA multilingual WER for CN, EN, IT, FR
🎭 17 expressive voices × 10 languages
🗣️ Supports 9+ Chinese dialects: Cantonese, Hokkien, Sichuanese & more
⚡ Ultra-fast: First packet in just 97ms
🤖 Auto tone adaptation + robust text handling
Perfect for apps, games, IVR, content — anywhere you need natural, human-like speech.
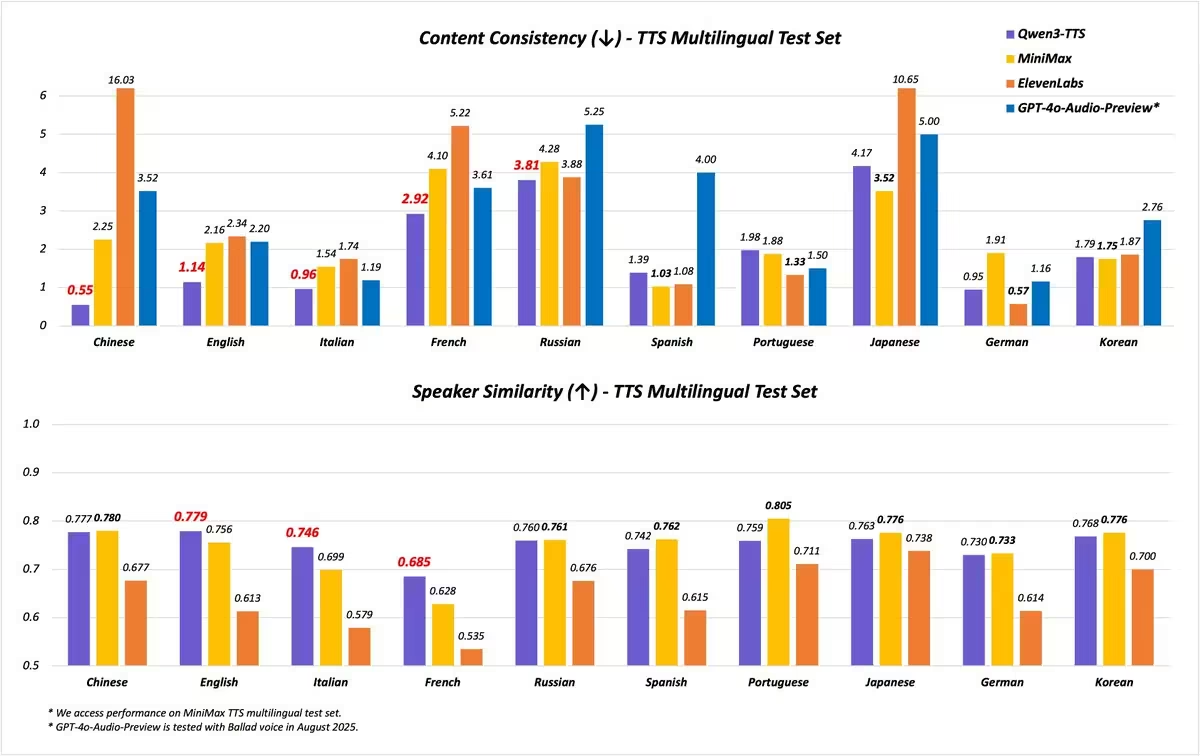 Qwen
@Alibaba_Qwen
We’re dropping Qwen3-Next-80B-A3B-Instruct-FP8 and Qwen3-Next-80B-A3B-Thinking-FP8 and fully compatible with Transformers, vLLM and SGLang. Now with FP8 precision for blazing-fast inference 🚀
Hugging Face: huggingface.co/collections/Qwen/qwen3-next-68c25fd6838e58…
ModelScope: modelscope.cn/collections/Qwen3-Next-c314f23bd0264a
Qwen
@Alibaba_Qwen
Struggling with the 3-minute limit on Qwen3-ASR-Flash? No more!
Introducing the Qwen3-ASR-Toolkit 🚀
A free, open-source CLI to transcribe HOURS-long audio/video files at high speed. Unleash the full power of the Qwen3-ASR-Flash API! 💥
🧠 Smart VAD splitting (no awkward cuts!)
⚡️ Parallel processing for massive speed-ups
🎬 Universal Media support (MP4, MOV, MP3, WAV, M4A, etc.)
🔄 Automatic resampling from any sample rate
Get started with one command: `pip install qwen3-asr-toolkit`
Check it out on GitHub: github.com/QwenLM/Qwen3-ASR-Toolkit
Qwen
@Alibaba_Qwen
Awesome! Let’s get started with the Qwen3-VL notebook in the near future.🌟
Unsloth AI
@UnslothAI
You can now train Vision LLMs with Reinforcement Learning in our free notebook!
Unsloth VLM RL via GRPO: 1.5× faster, 90% less VRAM, 15× longer context & no accuracy loss.
Guide: docs.unsloth.ai/new/vision-reinforcement-learning-vlm-rl
GitHub: github.com/unslothai/unsloth
Qwen2.5-VL Colab: colab.research.google.com/github/unslothai/notebooks/blob…
Qwen
@Alibaba_Qwen
LM Studio now supports Qwen3-Next with MLX on Mac — so cool! 🎉 And that Qwen capybara and LM Studio purple little guy are just too cute 😍
LM Studio
@lmstudio
LM Studio now supports Qwen3-Next with MLX on Mac!
🧵
 Qwen
@Alibaba_Qwen
Excited to see Qwen3-Next-80B on Poe! 🚀
Poe
@poe_platform
New on Poe: Qwen3-Next-80B!
Alibaba’s latest model brings highly optimized inference → strong tokens/sec throughput + low latency, while still excelling on math & coding benchmarks. (1/2)
 Qwen
@Alibaba_Qwen
Qwen x together.ai
Together AI
@togethercompute
🐻Qwen3-Next just dropped on Together AI
80B parameters, 3B activated.
Two models:
⚡Thinking: Outperforms Gemini-2.5-Flash-Thinking on reasoning benchmarks
🧠Instruct: Matches 235B model performance on key tasks
Available now via our API 🚀
 Qwen
@Alibaba_Qwen
Thanks for the evaluation!
Qwen3-Next 80B achieves strong performance with only 3B active parameters!
Artificial Analysis
@ArtificialAnlys
Alibaba has released Qwen3 Next 80B: an open weights hybrid reasoning model that achieves DeepSeek V3.1-level intelligence with only 3B active parameters
Key takeaways:
💡 Novel architecture: First model to introduce @Alibaba_Qwen's ‘Qwen3-Next’ foundation models, with several key architecture decisions such as a hybrid attention mechanism of Gated DeltaNet and Gated Attention, and high sparsity with a 3.8% active parameters share, compared to 9.4% for Qwen3 235B
🧠 Intelligence: Qwen3 Next 80B (Reasoning) scores 54 on the Artificial Analysis Intelligence Index, placed alongside DeepSeek V3.1 (Reasoning). The non-reasoning variant scores 45, in line with gpt-oss-20B and Llama Nemotron Super 49B v1.5 (Reasoning)
💲 Pricing model: Per token pricing on @alibaba_cloud is $0.5/$6 per 1M input/output tokens for reasoning and $0.5/$2 for the non-reasoning variant. This compares to higher prices for Qwen3 235B 2507 of $0.7/$8.4 with reasoning and $0.7/$2.8 without - a ≥25% reduction depending on workloads
⚙️ Model details: The model has a native context window of 256k tokens and is text-only, with no multimodal inputs or outputs. At only 80B parameters at FP8 the model fits on a single H200 GPU
 Qwen
@Alibaba_Qwen
Cool!
Ivan Fioravanti
@ivanfioravanti
Qwen3-Next is on mlx-community now 💪
It will be part of next mlx-lm release, in the meantime it's merged in the main branch and you can try it. Have fun!
Thanks to @ActuallyIsaak and @awnihannun
P.S.: Performance optimizations in progress!
 Qwen
@Alibaba_Qwen
🆙Qwen Code v0.0.10 & v0.0.11 bring new features and dev-friendly improvements:
✨New UX & Productivity
· Subagents for smarter task decomposition
· Todo Write tool for task tracking
· “Welcome Back” project summary on reopen!
· Customizable cache Strategy
⚡Performance & Dev Experience
· Smoother editing (no agent loops)
· Built-in Terminal Bench stress testing
· Fewer retries & better login handling
· Optimized file reading for big projects
· Enhanced IDE + shell integration
· Better MCP & OAuth support
· Improved memory/session management
· Updated multilingual docs
👉 Try it now: github.com/QwenLM/qwen-code
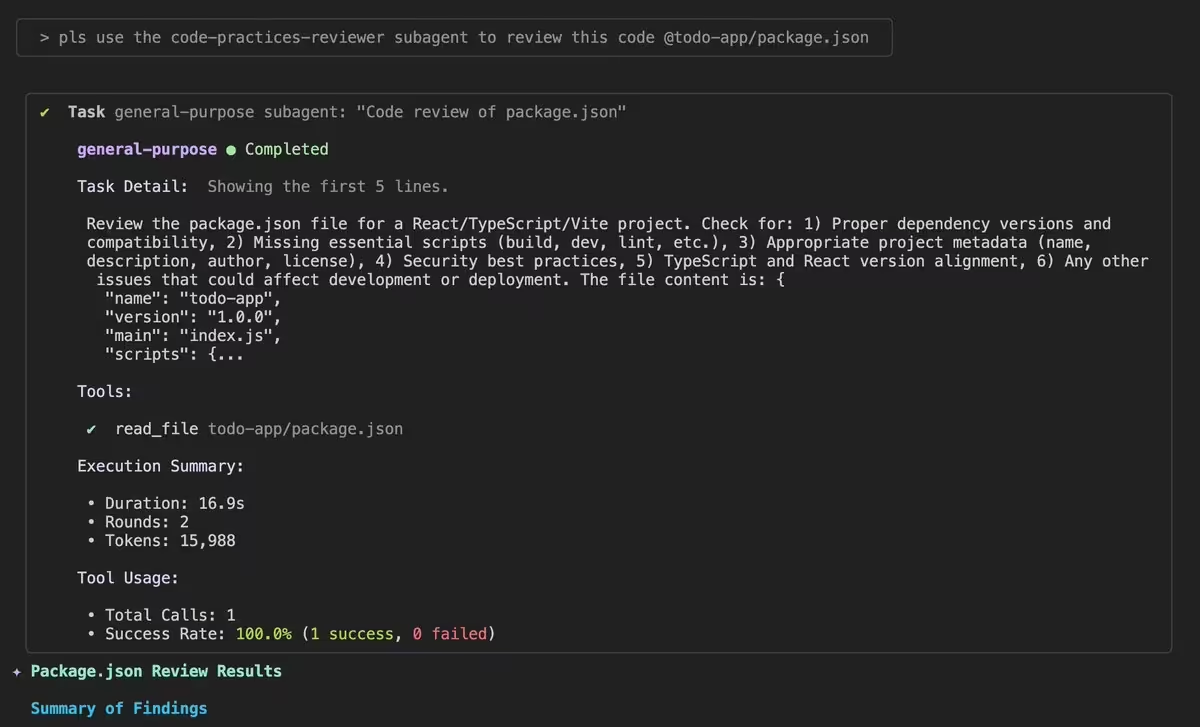 Qwen
@Alibaba_Qwen
Todo Write tool for task tracking
 Qwen
@Alibaba_Qwen
“Welcome Back” project summary on reopen!

Qwen reposted
 Songlin Yang
@SonglinYang4
Excited to see Gated DeltaNet being adopted in the @Alibaba_Qwen series ! It has also previously demonstrated strong effectiveness in @nvidia's Jet-Nemotron
Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Next-80B-A3B — the FUTURE of efficient LLMs is here!
🔹 80B params, but only 3B activated per token → 10x cheaper training, 10x faster inference than Qwen3-32B.(esp. @ 32K+ context!)
🔹Hybrid Architecture: Gated DeltaNet + Gated Attention → best of speed & recall
🔹 Ultra-sparse MoE: 512 experts, 10 routed + 1 shared
🔹 Multi-Token Prediction → turbo-charged speculative decoding
🔹 Beats Qwen3-32B in perf, rivals Qwen3-235B in reasoning & long-context
🧠 Qwen3-Next-80B-A3B-Instruct approaches our 235B flagship.
🧠 Qwen3-Next-80B-A3B-Thinking outperforms Gemini-2.5-Flash-Thinking.
Try it now: chat.qwen.ai
Blog: qwen.ai/blog?id=4074cca80393150c248e508aa62983f9cb7d27cd&…
Huggingface: huggingface.co/collections/Qwen/qwen3-next-68c25fd6838e58…
ModelScope: modelscope.cn/collections/Qwen3-Next-c314f23bd0264a
Kaggle: www.kaggle.com/models/qwen-lm/qwen3-next-80b
Alibaba Cloud API: www.alibabacloud.com/help/en/model-studio/models
 Qwen
@Alibaba_Qwen
Huge thanks to @AlpinDale for day-0 support of Qwen3-Next with tool calling! 🚀
 Alpin
@AlpinDale
Thanks to the Qwen team providing early access to the weights, Qwen3-Next has day0 support in aphrodite. Please try it, tool calling is also supported (if built from source).
As always, a huge thanks to the @vllm_project's efforts, the wouldn't have been possible without them; they also have day0 support, please check them out!
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Next-80B-A3B — the FUTURE of efficient LLMs is here!
🔹 80B params, but only 3B activated per token → 10x cheaper training, 10x faster inference than Qwen3-32B.(esp. @ 32K+ context!)
🔹Hybrid Architecture: Gated DeltaNet + Gated Attention → best of speed & recall
🔹 Ultra-sparse MoE: 512 experts, 10 routed + 1 shared
🔹 Multi-Token Prediction → turbo-charged speculative decoding
🔹 Beats Qwen3-32B in perf, rivals Qwen3-235B in reasoning & long-context
🧠 Qwen3-Next-80B-A3B-Instruct approaches our 235B flagship.
🧠 Qwen3-Next-80B-A3B-Thinking outperforms Gemini-2.5-Flash-Thinking.
Try it now: chat.qwen.ai
Blog: qwen.ai/blog?id=4074cca80393150c248e508aa62983f9cb7d27cd&…
Huggingface: huggingface.co/collections/Qwen/qwen3-next-68c25fd6838e58…
ModelScope: modelscope.cn/collections/Qwen3-Next-c314f23bd0264a
Kaggle: www.kaggle.com/models/qwen-lm/qwen3-next-80b
Alibaba Cloud API: www.alibabacloud.com/help/en/model-studio/models
Qwen
@Alibaba_Qwen
Qwen3-Next-80B-A3B now available in anycoder!
AK
@_akhaliq
Qwen3-Next-80B-A3B is out
80B params, but only 3B activated per token → 10x cheaper training, 10x faster inference than Qwen3-32B.(esp. @ 32K+ context!)
Qwen3-Next-80B-A3B-Instruct approaches our 235B flagship.
Qwen3-Next-80B-A3B-Thinking outperforms Gemini-2.5-Flash-Thinking
both now available in anycoder for vibe coding
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Next-80B-A3B — the FUTURE of efficient LLMs is here!
🔹 80B params, but only 3B activated per token → 10x cheaper training, 10x faster inference than Qwen3-32B.(esp. @ 32K+ context!)
🔹Hybrid Architecture: Gated DeltaNet + Gated Attention → best of speed & recall
🔹 Ultra-sparse MoE: 512 experts, 10 routed + 1 shared
🔹 Multi-Token Prediction → turbo-charged speculative decoding
🔹 Beats Qwen3-32B in perf, rivals Qwen3-235B in reasoning & long-context
🧠 Qwen3-Next-80B-A3B-Instruct approaches our 235B flagship.
🧠 Qwen3-Next-80B-A3B-Thinking outperforms Gemini-2.5-Flash-Thinking.
Try it now: chat.qwen.ai
Blog: qwen.ai/blog?id=4074cca80393150c248e508aa62983f9cb7d27cd&…
Huggingface: huggingface.co/collections/Qwen/qwen3-next-68c25fd6838e58…
ModelScope: modelscope.cn/collections/Qwen3-Next-c314f23bd0264a
Kaggle: www.kaggle.com/models/qwen-lm/qwen3-next-80b
Alibaba Cloud API: www.alibabacloud.com/help/en/model-studio/models
Qwen
@Alibaba_Qwen
Pretraining Efficiency & Inference Speed
 Qwen
@Alibaba_Qwen
Prefill Stage: At 4K context length, throughput is nearly 7x higher than Qwen3-32B. Beyond 32K, it’s over 10x faster.
 Qwen
@Alibaba_Qwen
Decode Stage: At 4K context, throughput is nearly 4x higher. Even beyond 32K, it still maintains over 10x speed advantage.
 Qwen
@Alibaba_Qwen
Base Model Performance
 Qwen
@Alibaba_Qwen
RULER
 Qwen
@Alibaba_Qwen
Thinking Model Performance
 Qwen
@Alibaba_Qwen
Don't forget, you can try it out at NVIDIA API Catalog build.nvidia.com/qwen/qwen3-next-80b-a3b-thinking
Qwen
@Alibaba_Qwen
Instruct Model Performance
 Qwen
@Alibaba_Qwen
Thanks to @vLLM_project for enabling efficient Qwen3-Next inference with accelerated kernels and native memory management!
vLLM
@vllm_project
Welcome Qwen3-Next! You can run it efficiently on vLLM with accelerated kernels and native memory management for hybrid models.
blog.vllm.ai/2025/09/11/qwen3-next.html
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Next-80B-A3B — the FUTURE of efficient LLMs is here!
🔹 80B params, but only 3B activated per token → 10x cheaper training, 10x faster inference than Qwen3-32B.(esp. @ 32K+ context!)
🔹Hybrid Architecture: Gated DeltaNet + Gated Attention → best of speed & recall
🔹 Ultra-sparse MoE: 512 experts, 10 routed + 1 shared
🔹 Multi-Token Prediction → turbo-charged speculative decoding
🔹 Beats Qwen3-32B in perf, rivals Qwen3-235B in reasoning & long-context
🧠 Qwen3-Next-80B-A3B-Instruct approaches our 235B flagship.
🧠 Qwen3-Next-80B-A3B-Thinking outperforms Gemini-2.5-Flash-Thinking.
Try it now: chat.qwen.ai
Blog: qwen.ai/blog?id=4074cca80393150c248e508aa62983f9cb7d27cd&…
Huggingface: huggingface.co/collections/Qwen/qwen3-next-68c25fd6838e58…
ModelScope: modelscope.cn/collections/Qwen3-Next-c314f23bd0264a
Kaggle: www.kaggle.com/models/qwen-lm/qwen3-next-80b
Alibaba Cloud API: www.alibabacloud.com/help/en/model-studio/models
Qwen
@Alibaba_Qwen
Thanks to SGLang for supporting Qwen3-Next with speculative decoding on day 0! 🚀
LMSYS Org
@lmsysorg
Qwen3-Next is out! SGLang has supported it on day 0 with speculative decoding. Try it out 👇
Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-Next-80B-A3B — the FUTURE of efficient LLMs is here!
🔹 80B params, but only 3B activated per token → 10x cheaper training, 10x faster inference than Qwen3-32B.(esp. @ 32K+ context!)
🔹Hybrid Architecture: Gated DeltaNet + Gated Attention → best of speed & recall
🔹 Ultra-sparse MoE: 512 experts, 10 routed + 1 shared
🔹 Multi-Token Prediction → turbo-charged speculative decoding
🔹 Beats Qwen3-32B in perf, rivals Qwen3-235B in reasoning & long-context
🧠 Qwen3-Next-80B-A3B-Instruct approaches our 235B flagship.
🧠 Qwen3-Next-80B-A3B-Thinking outperforms Gemini-2.5-Flash-Thinking.
Try it now: chat.qwen.ai
Blog: qwen.ai/blog?id=4074cca80393150c248e508aa62983f9cb7d27cd&…
Huggingface: huggingface.co/collections/Qwen/qwen3-next-68c25fd6838e58…
ModelScope: modelscope.cn/collections/Qwen3-Next-c314f23bd0264a
Kaggle: www.kaggle.com/models/qwen-lm/qwen3-next-80b
Alibaba Cloud API: www.alibabacloud.com/help/en/model-studio/models
Qwen
@Alibaba_Qwen
Cool!
 Yuchen Jin
@Yuchenj_UW
Qwen3-Next (thinking & non-thinking) are now live in BF16 at Hyperbolic!
Qwen3-Next is a huge efficiency leap:
- 80B MoE with just 3B active params
- 10x cheaper to train vs Qwen3-32B
- 10x inference throughput for >32K tokens
Proud to be a launch partner with @Alibaba_Qwen - kudos to this amazing team for keeping pushing open-source AI forward.
We’re the first to serve Qwen3-Next on @huggingface. Give it a try!
Qwen
@Alibaba_Qwen
Curtains up 🎭 Meet Qwen3-Next — smarter, cuter, and ready to take the stage. 🚀
 Qwen
@Alibaba_Qwen
Awesome work by the @thinkymachines team!
Thrilled that Qwen models (Qwen3-235B-A22B & Qwen3-8B & Qwen 2.5-VL) served as a foundation for this experiment.
This is exactly why we build—to empower researchers tackling hard problems & unlocking new scientific insights.
Can’t wait to see what’s next! 🚀
Thinking Machines
@thinkymachines
Today Thinking Machines Lab is launching our research blog, Connectionism. Our first blog post is “Defeating Nondeterminism in LLM Inference”
We believe that science is better when shared. Connectionism will cover topics as varied as our research is: from kernel numerics to prompt engineering. Here we share what we are working on and connect with the research community frequently and openly.
The name Connectionism is a throwback to an earlier era of AI; it was the name of the subfield in the 1980s that studied neural networks and their similarity to biological brains.
thinkingmachines.ai/blog/defeating-nondeterminism-in-llm-…
 Qwen
@Alibaba_Qwen
What’s your dream LLM? 🥝 Qwen3-Next is coming soon 👀. Hope you like it!
Qwen
@Alibaba_Qwen
🚀 Excited to see Qwen-3-Coder takes #1 among open-source models on the MCPMark leaderboard!
 Eval Sys
@EvalSysOrg
MCPMark Leaderboard Update 🚀
🌟 Qwen-3-Coder takes the #1 spot among open-source models, with an impressive per-run cost of just $36.46.
⚡️ Grok-Code-Fast-1 delivers the lowest per-run cost ($16.08) and the fastest average agent time (156.63s) across the top 10 models.
Kimi-K2-0905 outperforms Kimi2 in success rate, though at nearly double the per-run cost and average agent time.
Notably, Qwen-3-Coder achieves a success rate close to O3, but at roughly one-third the per-run cost — offering the community a highly cost-effective option for MCP tool-use applications.
This update introduces three newly released models to the leaderboard: Qwen-3-Max, Grok-Code-Fast-1, and Kimi-K2-0905.


 Qwen
@Alibaba_Qwen
Try it with Qwen3-Coder

 JB
@JasonBotterill
Funny way you can tell “big model smell” is by how well a model memorizes ASCII art. You can see GPT-5 knew the pattern, but only Opus 4.1 had spongebob fully memorized.

Qwen reposted
Arena.ai
@arena
🚨 Leaderboard Disrupted!
Two new models have entered the Top 10 Text leaderboard:
🔸#6 Qwen3-max-preview (Proprietary) by @Alibaba_Qwen
🔸#8 Kimi-K2-0905-preview (Modified MIT) by @Kimi_Moonshot tied with 7 others.
Note that this puts Kimi-K2-0905-preview in a tight race for #1 open model (tied with variants of Qwen3, variants of DeepSeek, and even Kimi-K2-0711)
Congrats to both teams! 👏 The Text Arena is the most competitive arena to crack.
 Qwen
@Alibaba_Qwen
🎙️ Meet Qwen3-ASR — the all-in-one speech recognition model!
✅ High-accuracy EN/CN + 9 more languages: ar, de, en, es, fr, it, ja, ko, pt, ru, zh
✅ Auto language detection
✅ Songs? Raps? Voice with BGM? No problem. <8% WER
✅ Works in noise, low quality, far-field
✅ Custom context? Just paste ANY text — names, jargon, even gibberish 🧠
✅ One model. Zero hassle.Great for edtech, media, customer service & more.
API:bailian.console.alibabacloud.com?tab=doc
ModelScope Demo: modelscope.cn/studios/Qwen/Qwen3-ASR-Demo
Hugging Face Demo: huggingface.co/spaces/Qwen/Qwen3-ASR-Demo
Blog:qwen.ai/blog?id=41e4c0f6175f9b004a03a07e42343eaaf48329e7&…
 Qwen
@Alibaba_Qwen
Big-Eared Capybara! Qwen3-ASR
 Qwen
@Alibaba_Qwen
From research paper to live website in minutes 🚀
Upload your paper, let Qwen Chat turn it into a webpage, and deploy instantly.
Try it now: chat.qwen.ai?inputFeature=web_dev
Qwen
@Alibaba_Qwen
Qwen3-Max-Preview is now live on OpenRouter! 🚀
OpenRouter
@OpenRouter
Qwen3-Max, @Alibaba_Qwen's most powerful model is live on OpenRouter:
📊 Higher accuracy in math, coding, logic, and science tasks
📖 Stronger instruction following & reduced hallucinations
🔍 Optimized for RAG + tool calling (no “thinking” mode)
 Qwen
@Alibaba_Qwen
Big news: Introducing Qwen3-Max-Preview (Instruct) — our biggest model yet, with over 1 trillion parameters! 🚀
Now available via Qwen Chat & Alibaba Cloud API.
Benchmarks show it beats our previous best, Qwen3-235B-A22B-2507. Internal tests + early user feedback confirm: stronger performance, broader knowledge, better at conversations, agentic tasks & instruction following.
Scaling works — and the official release will surprise you even more. Stay tuned!
Qwen Chat: chat.qwen.ai
Alibaba Cloud API: modelstudio.console.alibabacloud.com?tab=doc
 Qwen
@Alibaba_Qwen
Ready to meet the biggest, brainiest guy in the Qwen3 family?
Qwen
@Alibaba_Qwen
Glad to see Qwen3-Coder performing well on the GSO leaderboard!
 Manish Shetty
@slimshetty_
Quick post-summer GSO update. Several new models are now live on the leaderboard!!
🧵👇
 Qwen
@Alibaba_Qwen
Huge thanks to the community for making Qwen Image Edit’s inpainting magic happen!🙌
 Linoy Tsaban
@linoy_tsaban
Inpainting with Qwen Image Edit takes it next level
it's sooo precise
this is also a great reminder that when a good model is open sourced - the coumminty will build with it to enhace it even more ✨
Qwen
@Alibaba_Qwen
enjoy!
 Techa
@_techafresh
Qwen is pretty solid.
Now i don't have to write javascript for the frontend to my apps. 😂
 Qwen
@Alibaba_Qwen
How teams are using Qwen-Image in the wild →
🛒 With Qwen-Image and Qwen-VL, Alimama Creative turns plain product shots into high-converting posters.
Agents handle rewrites, prompts & visuals → fully automated creative pipeline.
From SKU → ad in seconds. ⚡
 Qwen
@Alibaba_Qwen
September is going to be amazing—get ready for a wave of exciting new things, and watch closely for what’s coming next!
Junyang Lin
@JustinLin610
Qwen
Qwen
@Alibaba_Qwen
This is Qwen Chat Web Dev prompt — a powerful, design-focused AI assistant for frontend development. 🚀
We aim to help developers build websites using React or HTML with TailwindCSS, animations, and modern UI patterns — all in one clean code block.
✨ Key features:
✅ Single-file React/HTML output
✅ Built-in libraries: React, Tailwind, Recharts, Framer Motion, p5.js, Three.js
✅ No external dependencies — just pure, runnable code
Whether you're prototyping or building something awesome, try it out on Qwen Chat!
👉 chat.qwen.ai?inputFeature=web_dev
 Qwen
@Alibaba_Qwen
Thanks for the awesome share! Thanks @ggerganov for the new Llama.cpp release!
Ivan Fioravanti
@ivanfioravanti
Llama.cpp is now faster with Qwen3-30B-A3B-Thinking-2507 on Metal! Much faster! 🔥
I will retest on 3090 TI with Cuda and publish updated benchmarks!
Thanks @ggerganov for the new release!
 Qwen
@Alibaba_Qwen
Thanks @cerebras — the best is yet to come! 🔥
Cerebras
@cerebras
🎂 Cerebras Inference turns 1! 🚀
Let's break it down:
- 6x faster than when we launched — From @Meta Llama to @Alibaba_Qwen 3 to @OpenAI OSS, models running on Cerebras deliver 𝟯,𝟬𝟬𝟬+ 𝘁𝗼𝗸𝗲𝗻𝘀/𝘀𝗲𝗰
- Our inference powers the best AI natives, global enterprises, and developers including Meta, @IBM , AlphaSense, @Docker, @GSK , Mayo Clinic, Core42, @vercel and more
- Largest model served: ~half a trillion parameters, 7x bigger than launch
- #1 provider of tokens on @huggingface 🤗
- Serving billions of tokens per day on @openrouter
- The leading code gen inference provider, powering AI developers with @Cline and @windsurf
We’re just getting started… but couldn’t have done Year 1 without YOU. Build on, builders. ❤️🔥
inference.cerebras.ai
Qwen reposted
 Yaya Soumah
@YayaSoumah
Running Qwen Code on iOS, using Pocket @Alibaba_Qwen @huybery
Qwen
@Alibaba_Qwen
Amazing! Excited to see Qwen-Image InstantX ControlNet in ComfyUI. 🔥
ComfyUI
@ComfyUI
Qwen-Image InstantX ControlNet is now available in ComfyUI!
1 unified model with 4 controls:
🔹 Canny
🔹 Soft Edge
🔹 Depth
🔹 Pose
Supported in Day-1!
 Qwen
@Alibaba_Qwen
🚀 Qwen Chat tip: Qwen Chat can read web pages directly! Try pasting a link and see the magic. 🌐✨
chat.qwen.ai
Qwen
@Alibaba_Qwen
✨ Stunning realism, tailored for Chinese aesthetics — AWPortrait QW is here!
✨ 更真实的质感,更符合东方审美 —— AWPortrait QW 来了!
 DynamicWang
@dynamicwangs
AWPortrait QW正式发布
AWPortrait QW 是基于QwenImage架构下的模型,使用更符合中国人长相特征及审美的训练集进行训练,包含室内室外人像、时尚、棚拍写真等众多类型,泛化性强。相较于原始版Qwen,AWPortrait QW对于肤质表现更加细腻且真实。
下载地址:www.liblib.art/modelinfo/cadba03ead404ea3bc1cda3d30803d84…
 Qwen
@Alibaba_Qwen
It’s Aug 25 and… yep, still #1 👑
 apolinario (poli)
@multimodalart
qwen image edit is back at #1 trending model at @huggingface 👑
 Qwen
@Alibaba_Qwen
Great. Which Qwen model should be supported next?
Qwen
@Alibaba_Qwen
🧸Turn your favorite memes into real-world collectibles — one click with Qwen-Image-Edit.
🎁Try it now: chat.qwen.ai?inputFeature=image_edit
✨Prompt: Create a 1/7 scale commercialized figure of the character in this image, in a realistic style and real-life setting. The figure is placed on a computer desk, with a round transparent acrylic base that has no text on it. Next to the computer desk, place an exquisite toy packaging box decorated with original artwork-style illustrations.


 Qwen
@Alibaba_Qwen
💖Cool! And we will improve the performance of Multi-image with qwen-image-edit in the next version.
 Luis Catacora
@lucataco
Multi-image with qwen-image-edit
 Qwen
@Alibaba_Qwen
Qwen-Code weekly release (v0.0.8) :
✨ Deep VS Code Integration: Get context-aware suggestions & inline diffs directly in your editor! Initialize with /ide and supercharge your workflow.
🔌 Enhanced MCP Support: Add, remove, list MCP servers via CLI (qwen mcp add|remove|list), plus support for MCP roots & multimodal tool outputs (images, audio, and more!).
📱 Responsive Terminal UI: Now adapts gracefully to narrow terminals.
🔍 Reverse Search: Press Ctrl+R in shell mode to instantly search command history.
🗜️ Customizable Context Compression: Set your threshold in settings.json.
📂 Multi-directory Support: Auto-load multiple dirs at startup.
🔢 Hide Line Numbers: Set "showLineNumbers": false for cleaner copy-paste.
🔕 Plus: Disable update nudges with "disableUpdateNag": true
📌More details: github.com/QwenLM/qwen-code
Upgrade now and level up your coding experience 💻🔥
Qwen
@Alibaba_Qwen
AI everywhere — love seeing Qwen3 powering cars & robots on-device with Qualcomm NPU! 🚀 Thanks to NEXA AI 🙌
Qwen
@Alibaba_Qwen
🎨✨ From simple sketches to stunning 3D interiors — powered by Qwen-Image-Edit!
All designs are community contributions, showcasing how AI transforms architectural visions into realistic, stylish, and precise creations.
Try it now: chat.qwen.ai?inputFeature=image_edit


 Qwen
@Alibaba_Qwen
Wow — Qwen-Image-Edit just debuted at #2 in the Image Editing Arena 🏆
ELO 1098, with performance on par with GPT-4o — and all at open weights under Apache 2.0.
Thanks to @ArtificialAnlys
Try it now: chat.qwen.ai?inputFeature=image_edit
Artificial Analysis
@ArtificialAnlys
Qwen-Image-Edit is the new open weights leader in Image Editing, with quality comparable to GPT-4o and FLUX.1 Kontext [max]
Qwen-Image-Edit is the image editing variant of the recent Qwen-Image release from Alibaba, also released under the Apache 2.0 license with weights available on @huggingface.
Qwen-Image-Edit is priced at $30/1k images on both @fal and @replicate, similar to its open weights peers HiDream-E1.1 at ~$30/1k and FLUX.1 Kontext [dev] at $25/1k images, while much cheaper than FLUX.1 Kontext [max] at $80/1k images, and GPT-4o at ~$167/1k images.
See below for comparisons between Qwen-Image-Edit and other leading models in our Image Editing Arena 🧵
 Qwen
@Alibaba_Qwen
Discover Deep Research in Qwen Chat for free!
chat.qwen.ai?inputFeature=deep_research
Chen Cheng
@cherry_cc12
@JustinLin610 sent me a photo of a paper robotics list…
Like I was that guy who reads papers for fun. 😅
So I fed it to Qwen Chat’s DeepResearch.
10 mins later: full analysis, zero stress.
Thanks, Junyang. But also… thanks, Qwen Chat.
@huybery I really recommend you try this move!
 Qwen
@Alibaba_Qwen
Qwen Image Edit meets @wavespeed_ai — fast, flawless, and fun!
 WaveSpeedAI
@wavespeed_ai
🚀 Meet Qwen Image Edit on WaveSpeedAI — the ultimate AI for flawless, high-quality image editing. @Alibaba_Qwen
No glitches, no bugs — just crystal-clear, professional results every time. ✨
Try it now and unlock next-level creativity. 🎨
👉 wavespeed.ai/models/wavespeed-ai/qwen-image/edit
#ai #imageediting #qwen #wavespeedai #nextgenai #qwenimage
 Qwen
@Alibaba_Qwen
Cool!
 Krea
@krea_ai
introducing Qwen Edit.
this new models offers incredible image editing capabilities from text prompts.
try it now for free!
Qwen
@Alibaba_Qwen
Interesting — preserving identity consistency across varying lighting conditions.
Linoy Tsaban
@linoy_tsaban
Relighting images with Qwen Edit
impressive directional control and color temperature manipulation w/o additional finetuning
crazy how we needed a dedicated model for this not long ago


 Qwen
@Alibaba_Qwen
Glad you like it!
 Paul Couvert
@itsPaulAi
So Alibaba Qwen has released the best image editing model... 100% open source!
You can edit any photo using natural language.
It can be used both locally and online.
More below
Qwen
@Alibaba_Qwen
Qwen-Image Edit in ComfyUI
ComfyUI
@ComfyUI
Qwen-Image Edit in ComfyUI - Image Editing Model / August 19th, 2025 x.com/i/broadcasts/1lDGLBdVMowxm
Qwen
@Alibaba_Qwen
🐞 We hit a bug in the inference code for Qwen-Image-Edit on Diffusers, which caused some odd cases.
✅ Fixed now and thanks to Diffusers for the quick merge — give it another try!
🔗 Try it now: chat.qwen.ai?inputFeature=image_edit
 Qwen
@Alibaba_Qwen
🚀 Excited to introduce Qwen-Image-Edit!
Built on 20B Qwen-Image, it brings precise bilingual text editing (Chinese & English) while preserving style, and supports both semantic and appearance-level editing.
✨ Key Features
✅ Accurate text editing with bilingual support
✅ High-level semantic editing (e.g. object rotation, IP creation)
✅ Low-level appearance editing (e.g. addition/delete/insert)
Try it now: chat.qwen.ai?inputFeature=image_edit
Hugging Face: huggingface.co/Qwen/Qwen-Image-Edit
ModelScope: modelscope.cn/models/Qwen/Qwen-Image-Edit
Blog: qwenlm.github.io/blog/qwen-image-edit/
Github: github.com/QwenLM/Qwen-Image
API: www.alibabacloud.com/help/en/model-studio/qwen-image-edit
Qwen
@Alibaba_Qwen
cool!
Linoy Tsaban
@linoy_tsaban
is Qwen Image Edit the first model to successfully remove my bangs??
i'll need a new benchmark
 Qwen
@Alibaba_Qwen
Thank you! Qwen-Image-Edit is now available in anycoder!
AK
@_akhaliq
Qwen-Image-Edit is out in anycoder for image editing in your vibe coded apps
Built on 20B Qwen-Image, it brings precise bilingual text editing (Chinese & English) while preserving style, and supports both semantic and appearance-level editing.
Qwen
@Alibaba_Qwen
Can't wait to try it out!
Ivan Fioravanti
@ivanfioravanti
It's starting to work... qwen-image-edit MPS!
 Qwen
@Alibaba_Qwen
cool!
 Mariusz Kurman
@mkurman88
Cool 😅 congrats @Alibaba_Qwen team!
 Qwen
@Alibaba_Qwen
🚀 Excited to introduce Qwen-Image-Edit!
Built on 20B Qwen-Image, it brings precise bilingual text editing (Chinese & English) while preserving style, and supports both semantic and appearance-level editing.
✨ Key Features
✅ Accurate text editing with bilingual support
✅ High-level semantic editing (e.g. object rotation, IP creation)
✅ Low-level appearance editing (e.g. addition/delete/insert)
Try it now: chat.qwen.ai?inputFeature=image_edit
Hugging Face: huggingface.co/Qwen/Qwen-Image-Edit
ModelScope: modelscope.cn/models/Qwen/Qwen-Image-Edit
Blog: qwenlm.github.io/blog/qwen-image-edit/
Github: github.com/QwenLM/Qwen-Image
API: www.alibabacloud.com/help/en/model-studio/qwen-image-edit
Qwen
@Alibaba_Qwen
So cool!
Replicate
@replicate
The much anticipated image editing model from Qwen is now on Replicate
replicate.com/qwen/qwen-image-edit
Edit images in just 3 seconds, for $0.03 per image.
We've worked with Pruna to deliver you the fastest way to use Qwen Image Edit.
 Qwen
@Alibaba_Qwen
Thanks so much! Appreciate the love for Qwen-Image-Edit @fal.
fal
@fal
🎨 Qwen-Image Edit: Revolutionary Image Editing model from @Alibaba_Qwen is available on @fal
💰$0.03 per edit!
🎯Precise and creative transformations
 Qwen
@Alibaba_Qwen
🚀 Excited to introduce Qwen-Image-Edit!
Built on 20B Qwen-Image, it brings precise bilingual text editing (Chinese & English) while preserving style, and supports both semantic and appearance-level editing.
✨ Key Features
✅ Accurate text editing with bilingual support
✅ High-level semantic editing (e.g. object rotation, IP creation)
✅ Low-level appearance editing (e.g. addition/delete/insert)
Try it now: chat.qwen.ai?inputFeature=image_edit
Hugging Face: huggingface.co/Qwen/Qwen-Image-Edit
ModelScope: modelscope.cn/models/Qwen/Qwen-Image-Edit
Blog: qwenlm.github.io/blog/qwen-image-edit/
Github: github.com/QwenLM/Qwen-Image
API: www.alibabacloud.com/help/en/model-studio/qwen-image-edit
Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
Qwen
@Alibaba_Qwen
Cool! — glad to see Qwen3-235B-A22B-Instruct-2507 applied in healthcare-AI research.
Mariusz Kurman
@mkurman88
See it in action. 100 workers; @openrouter, @Alibaba_Qwen Qwen3 235B A22B Instruct 2507.
Qwen
@Alibaba_Qwen
ready to refresh your art?
 Qwen
@Alibaba_Qwen
Thank you all for your love and support for the Qwen-Code project! 🚀 We’ve reached 10,000 stars on GitHub in less than a month💫
Link: github.com/QwenLM/qwen-code
What feature would you like to see next in Qwen-Code? Let us know in the comments below! 👇
 Qwen
@Alibaba_Qwen
📸 Just showed Qwen Chat Vision Understanding how to "see" and understand a meal — and it didn’t just identify the food, it analyzed what, where, weight and even how many calories!
From a simple photo, we extracted detailed insights:
✅ Object detection
✅ Weight estimation
✅ Calorie calculation
✅ Structured JSON output
Try it now: chat.qwen.ai
 Qwen
@Alibaba_Qwen
🚀 Qwen Chat Desktop for Windows is here!
💻 All the power of Qwen Chat — now with MCP support for smarter, faster agents.
⚡ Run up MCP Servers, supercharge your productivity, and stay in control.
📥 Download now → qwen.ai/download
 Qwen
@Alibaba_Qwen
🚀 Small but mighty update to Vision Understanding in Qwen Chat — now with native 128K context and stronger performance across vision, video, and 3D tasks!
🔥 Key Upgrades:
✅ Significant boost in math & reasoning
✅ More accurate object recognition
✅ OCR support for 30+ languages (up from 11)
✅ More robust 2D & 3D grounding
✅ Major improvements in video understanding & grounding
💬 Try it now → chat.qwen.ai — we’d love your feedback!
 Qwen
@Alibaba_Qwen
That’s impressive!
Qwen
@Alibaba_Qwen
Super excited to see our friend supporting Qwen3-Coder with fast api and amazing price!
DeepInfra
@DeepInfra
Qwen3‑Coder now 200 TPS on DeepInfra at the best prices of $0.30/M input and $1.20/M output
 Qwen
@Alibaba_Qwen
Interesting demo! Qwen2.5-Omni:Understands text, images, audio & video, and replies in natural speech or text!
 Jack
@jackndwyer
I built an AI to give me recipes based on ingredients I show it
Uses Qwen 2.5 Omni
Qwen
@Alibaba_Qwen
Go try it! 🚀
Ivan Fioravanti
@ivanfioravanti
qwen-image-mps new version is live!
- fast using v1.1 of Qwen-Image-Lightning
- ultra-fast using v1.0 of 4steps version!
M3 Ultra 42 seconds --> 21 seconds 🔥
M4 Max 1:27 mins --> 43 seconds 🔥
Go try it! 🚀
Ultra fast output is good enough. Here it is!
Fast v1.1 in below.
 Qwen
@Alibaba_Qwen
Qwen3-30B-A3B-Instruct — with just 3B active parameters, it’s closing in on the performance of far larger models.
Easily deploy locally or Try it now: chat.qwen.ai?model=Qwen3-30B-A3B-2507
 Qwen
@Alibaba_Qwen
Qwen-3-235B-A22B-Instruct takes the #1 spot for August Open Model Leaderboard🏆
Try it now: chat.qwen.ai
Arena.ai
@arena
🚨 Open Model Leaderboard Update
New open models entered the Text Arena, and the rankings by provider have reshuffled for August.
- Qwen-3-235b-a22b-instruct from @Alibaba_Qwen takes the crown 🏆
- GLM-4.5 from @Zai_org and gpt-oss-120b by @openAI debut in the top 10!
All the top open models also rank within the top 50 overall (proprietary & open). See more details around the climbers, movers, and who's out for August in thread 🧵
 Qwen
@Alibaba_Qwen
Qwen Image Edit is still cooking, but I couldn’t resist trying it — now I’ve got a Qwen Capybara rocking unlimited stickers!
 Qwen
@Alibaba_Qwen
Qwen Image is now quicker than ever on Qwen Chat.
Try it now: chat.qwen.ai?inputFeature=t2i
 Qwen
@Alibaba_Qwen
Wow, that's a brilliant use of AI! Qwen Chat Deep Research now supports image and file inputs.
Try it now: chat.qwen.ai?inputFeature=deep_research
 nisten
@nisten
I used qwen deep research and gpt-120b-OSS to fix my ac.
The air condinditioner is made in China and qwen knew their PCbs all show the same error FF FE error code lol
Now getting claude code to calculate how much carbon it saved vs going to landfill
EU will not comprehend this
Qwen
@Alibaba_Qwen
🥇Qwen3-Coder, try it now in Qwen-Code
 carlos
@closji
Recent open model scores on SWE-bench Bash Only:
🥇Qwen3-Coder 480B/A35B Instruct - 55.40%
🥈Kimi-K2-Instruct - 43.80%
🥉gpt-oss-120b - 26.00%
See the full leaderboard below! 👇
Qwen
@Alibaba_Qwen
🚀 Small upgrade to our Deep Research capabilities!
1️⃣ Smarter, more insightful reports
2️⃣ Deeper search for richer findings
3️⃣ More accurate information with less hallucination
4️⃣ Modular tools with parallel execution
5️⃣ Multi-modal input support: upload files, images
Try it now ➡️ chat.qwen.ai?inputFeature=deep_research
 Qwen
@Alibaba_Qwen
Amazing! Jan-v1 — a powerful, fully local 4B model achieving 91% SimpleQA accuracy. Huge thanks to my friends for building it on Qwen3-4B-Thinking-2507.
👋 Jan
@jandotai
Introducing Jan-v1: 4B model for web search, an open-source alternative to Perplexity Pro.
In our evals, Jan v1 delivers 91% SimpleQA accuracy, slightly outperforming Perplexity Pro while running fully locally.
Use cases:
- Web search
- Deep Research
Built on the new version of Qwen's Qwen3-4B-Thinking (up to 256k context length), fine-tuned for reasoning and tool use in Jan.
You can run the model in Jan, llama.cpp, or vLLM. To enable search in Jan, go to Settings → Experimental Features → On, then Settings → MCP Servers → enable a search-related MCP such as Serper.
Use the model:
- Jan-v1-4B: huggingface.co/janhq/Jan-v1-4B
- Jan-v1-4B-GGUF: huggingface.co/janhq/Jan-v1-4B-GGUF
Credit to the @Alibaba_Qwen team for Qwen3 4B Thinking & @ggerganov for llama.cpp.
Qwen
@Alibaba_Qwen
Huge improvement! OSWorld-Verified: Smarter, faster, more reliable.
 Tianbao Xie
@TianbaoX
🚀 OSWorld gets a major upgrade!
OSWorld-Verified: 15 months community feedback → 300+ fixes (ambiguity, graders…), 50x faster eval through AWS parallelization
More apple-to-apple comparison for reliable CUA evaluation ✨
👇xlang.ai/blog/osworld-verified
Qwen
@Alibaba_Qwen
10 steps. 5 seconds. High-quality AI images.
Qwen-Image distilled is live in ComfyUI. ⚡
ComfyUI
@ComfyUI
⚡ Try the new Qwen-Image distilled version in ComfyUI!
10 steps for high-quality images, 5s on Blackwell Ada.
Give it a shot for faster inference!


 Qwen
@Alibaba_Qwen
The cutest 1 million tokens I've ever seen!
 🌸 ellie 🌸
@heyellieday
 Qwen
@Alibaba_Qwen
If I were to build a web version of the Qwen-Code CLI, what should I call it? 😅 "Qwen-Code Web" is accurate, sure—but let's be honest, it's not exactly inspiring.
Simon Willison
@simonw
OpenAI's decision to give their Codex CLI tool and their Codex asynchronous coding agent the exact same name means that when people say "have you tried Codex?" i have genuinely no idea which one they are talking about
Qwen
@Alibaba_Qwen
Generate an SVG of a pelican riding a bicycle with Qwen3-Coder and Qwen-Image. Which one do you prefer?
 Ivan Fioravanti
@ivanfioravanti
Qwen-Image lightning generation on Apple Silicon is now just one line in your CLI thanks to @simonw
uv run raw.githubusercontent.com/ivanfioravanti/qwen-image-mps/r… -f -p "Generate an SVG of a pelican riding a bicycle"
 Qwen
@Alibaba_Qwen
Cool
Qwen reposted
 Miguel | AP
@angrypenguinPNG
Qwen-Image has been distilled to run in 8-steps.
This means you get nearly the same image quality, with >50% less compute required.
The cost of high-quality AI images is falling fast ⚡️

Qwen reposted
 青龍聖者
@bdsqlsz
DiffSynth-Studio release Qwen-image lora for control:
Qwen-Image-EliGen
I think this means we just need to train Qwen-image Lora to get controlnet effects.


Qwen reposted
Replicate
@replicate
Qwen-Image is on Replicate.
With thanks to Pruna it's just $0.025 per image.
replicate.com/qwen/qwen-image

Qwen reposted
fal
@fal
Qwen-Image by @Alibaba_Qwen is now available at fal, as a scalable & ready-to-use API fal.ai/models/fal-ai/qwen-image

Qwen reposted
Ostris
@ostrisai
AI Toolkit now supports @Alibaba_Qwen Qwen Image for fine tuning.
The LoRAs wont work anywhere until inference engines add it, and I may adjust the keys when they do, so be warned.
I am growing convinced this is the best image model out there. github.com/ostris/ai-toolkit/pull/359
Qwen reposted
Ostris
@ostrisai
Tutorial: How to Train a Qwen-Image Character LoRA With AI Toolkit
In this tutorial, I train a character LoRA for Qwen-Image in AI Toolkit on a 5090 using 6bit quantization.
Links in 🧵
 Qwen
@Alibaba_Qwen
Cool!
WaveSpeedAI
@wavespeed_ai
🚀 Just Launched: Qwen-Image LoRA Trainer @Alibaba_Qwen
WaveSpeedAI is now the FIRST platform in the world to offer an online Qwen-Image LoRA trainer.
Train your own custom style in minutes — only on WaveSpeedAI.
Try it now: wavespeed.ai/models/wavespeed-ai/qwen-image-lora-trainer
#lora #qwenimage #aiart #wavespeedai #genai #finetune
 Qwen
@Alibaba_Qwen
💡 You get 2,000 free Qwen Code runs every day!
Run this one simple command:
npx @qwen-code/qwen-code@latest
Hit Enter, and that’s it!
🚀 Now with Qwen OAuth support — super easy to use.
Try it now and supercharge your vibe code! 💻⚡
Github:github.com/QwenLM/qwen-code
 Qwen
@Alibaba_Qwen
🚀 Qwen3-30B-A3B-2507 and Qwen3-235B-A22B-2507 now support ultra-long context—up to 1 million tokens!
🔧 Powered by:
• Dual Chunk Attention (DCA) – A length extrapolation method that splits long sequences into manageable chunks while preserving global coherence.
• MInference – Sparse attention that cuts overhead by focusing on key token interactions
💡 These innovations boost both generation quality and inference speed, delivering up to 3× faster performance on near-1M token sequences.
✅ Fully compatible with vLLM and SGLang for efficient deployment.
📄 See the update model cards for how to enable this feature.
huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507
huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507
huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507
huggingface.co/Qwen/Qwen3-30B-A3B-Thinking-2507
modelscope.cn/models/Qwen/Qwen3-235B-A22B-Instruct-2507
modelscope.cn/models/Qwen/Qwen3-235B-A22B-Thinking-2507
modelscope.cn/models/Qwen/Qwen3-30B-A3B-Instruct-2507
modelscope.cn/models/Qwen/Qwen3-30B-A3B-Thinking-2507

Qwen reposted
👋 Jan
@jandotai
Jan supports the new @Alibaba_Qwen's Qwen3-4B model. Search for it in Jan Hub and download via @huggingface to run it locally.
Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-4B-Instruct-2507 & Qwen3-4B-Thinking-2507 — smarter, sharper, and 256K-ready!
🔹 Instruct: Boosted general skills, multilingual coverage, and long-context instruction following.
🔹 Thinking: Advanced reasoning in logic, math, science & code — built for expert-level tasks.
Both models are more aligned, more capable, and more context-aware.
Huggingface:
huggingface.co/Qwen/Qwen3-4B-Instruct-2507
huggingface.co/Qwen/Qwen3-4B-Thinking-2507
ModelScope:
modelscope.cn/models/Qwen/Qwen3-4B-Instruct-2507
modelscope.cn/models/Qwen/Qwen3-4B-Thinking-2507

Qwen reposted
AK
@_akhaliq
Qwen-Image @Alibaba_Qwen, a 20B MMDiT model for text-to-image generation is now available in anycoder using @replicate for generating images for your apps
You can now generate images directly inside anycoder for your apps when vibe coding
 Qwen
@Alibaba_Qwen
Today we release the APIs of our Flash series, which support Qwen3-Coder and Qwen3-2507 now. Both APIs support the context length of 1M tokens. They are fast and accurate, and they are cost-effectve as well. Feel free to take a try!
Qwen3-Coder-Flash
Model Card: modelstudio.console.alibabacloud.com?tab=doc
Pricing: www.alibabacloud.com/help/en/model-studio/models
Qwen-Flash
Model Card: modelstudio.console.alibabacloud.com?tab=doc
Pricing: www.alibabacloud.com/help/en/model-studio/models
What's more, Qwen-Plus-Latest now also supports the context length of 1M tokens:
Model Card: modelstudio.console.alibabacloud.com?tab=doc
Pricing: www.alibabacloud.com/help/en/model-studio/models
Qwen reposted
ComfyUI
@ComfyUI
Qwen-Image in ComfyUI: New Era of Text Generation in Images!
The powerful 20B MMDiT model developed by Alibaba Qwen team, is now natively supported in ComfyUI.
🎛️ bf16 and fp8 versions available.
Run it - fully locally today!
 Qwen
@Alibaba_Qwen
🚀 Meet Qwen-Image — a 20B MMDiT model for next-gen text-to-image generation. Especially strong at creating stunning graphic posters with native text. Now open-source.
🔍 Key Highlights:
🔹 SOTA text rendering — rivals GPT-4o in English, best-in-class for Chinese
🔹 In-pixel text generation — no overlays, fully integrated
🔹 Bilingual support, diverse fonts, complex layouts
🎨 Also excels at general image generation — from photorealistic to anime, impressionist to minimalist. A true creative powerhouse.
Blog:qwenlm.github.io/blog/qwen-image/
Hugging Face:huggingface.co/Qwen/Qwen-Image
ModelScope:modelscope.cn/models/Qwen/Qwen-Image
Github:github.com/QwenLM/Qwen-Image
Technical report:qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-Image/Qwen_I…
Demo: modelscope.cn/aigc/imageGeneration?tab=advanced
 Qwen
@Alibaba_Qwen
wavespeed api&demo:wavespeed.ai/models/wavespeed-ai/qwen-image/text-to-image
Qwen
@Alibaba_Qwen
More Demos
Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen

Qwen reposted
Nebius Token Factory
@nebiustf
🚨 Now live: Qwen3-235B-A22B-2507
- 235B total params / 22B activated (MoE)
- Structured, non-thinking mode: faster and more direct
- Native 262K context window
- Strong benchmark scores in math, logic, and coding
- Zero-retention hosting
A top-tier generalist LLM 👇

Qwen reposted
Qwen
@Alibaba_Qwen
🚀We are going to build better models!
Arena.ai
@arena
🚨BREAKING: @Alibaba_Qwen’s latest Qwen3 now claims the #1 open model in the Arena!
With 3k+ community votes, it ranks #3 Overall and ties for #1 in Coding, Hard Prompts, and Math - overtaking DeepSeek and Kimi-K2 as the top open model.
Huge congrats to the Qwen team on this incredible milestone and contribution to the open community!
More insights in the thread 🧵

Qwen reposted
 Wolfram Ravenwolf
@WolframRvnwlf
🚨 BREAKING: China is no longer catching up; they're setting the pace!
Six Qwen3 models released in one week: from big ones that surpass all open models and nearly all closed AIs to small versions that can run on your laptop - each SOTA and top-tier in its class.
I've been benchmarking them continuously since their release and they consistently set new records for open models - confirmed by vibe checks and general consensus among my peers. @Alibaba_Qwen is the open weights king, once again!

Qwen reposted
Simon Willison
@simonw
I wrote about the new Qwen3 Coder model here, including details on how I got it running on my Mac using LM Studio, Open WebUI, mlx-lm and my own LLM command-line tool simonwillison.net/2025/Jul/31/qwen3-coder-flash/
Qwen
@Alibaba_Qwen
🦥 Qwen3-Coder-Flash: Qwen3-Coder-30B-A3B-Instruct
💚 Just lightning-fast, accurate code generation.
✅ Native 256K context (supports up to 1M tokens with YaRN)
✅ Optimized for platforms like Qwen Code, Cline, Roo Code, Kilo Code, etc.
✅ Seamless function calling & agent workflows
💬 Chat: chat.qwen.ai
🤗 Hugging Face: hf.co/Qwen/Qwen3-Coder-30B-A3B-Instruct
🤖 ModelScope: modelscope.cn/models/Qwen/Qwen3-Coder-30B-A3B-Instruct
🔧 Qwen Code: github.com/QwenLM/qwen-code

Qwen reposted
Nathan Lambert
@natolambert
Qwen recently is the best example we've ever had of "ship early, ship often" as an ethos of OSS applied to AI
Qwen
@Alibaba_Qwen
🦥 Qwen3-Coder-Flash: Qwen3-Coder-30B-A3B-Instruct
💚 Just lightning-fast, accurate code generation.
✅ Native 256K context (supports up to 1M tokens with YaRN)
✅ Optimized for platforms like Qwen Code, Cline, Roo Code, Kilo Code, etc.
✅ Seamless function calling & agent workflows
💬 Chat: chat.qwen.ai
🤗 Hugging Face: hf.co/Qwen/Qwen3-Coder-30B-A3B-Instruct
🤖 ModelScope: modelscope.cn/models/Qwen/Qwen3-Coder-30B-A3B-Instruct
🔧 Qwen Code: github.com/QwenLM/qwen-code
Qwen reposted
Unsloth AI
@UnslothAI
Qwen3-Coder-Flash is here!✨
The 30B model excels in coding & agentic tasks. Run locally with up to 1M context length. Full precision runs with just 33GB RAM.
We also fixed tool-calling support for Qwen3-Coder-30B-A3B-Instruct and 480B-A3B.
GGUFs: huggingface.co/unsloth/Qwen3-Coder-30B-A3B-Instruct-GGUF
 Qwen
@Alibaba_Qwen
🦥 Qwen3-Coder-Flash: Qwen3-Coder-30B-A3B-Instruct
💚 Just lightning-fast, accurate code generation.
✅ Native 256K context (supports up to 1M tokens with YaRN)
✅ Optimized for platforms like Qwen Code, Cline, Roo Code, Kilo Code, etc.
✅ Seamless function calling & agent workflows
💬 Chat: chat.qwen.ai
🤗 Hugging Face: hf.co/Qwen/Qwen3-Coder-30B-A3B-Instruct
🤖 ModelScope: modelscope.cn/models/Qwen/Qwen3-Coder-30B-A3B-Instruct
🔧 Qwen Code: github.com/QwenLM/qwen-code
Qwen reposted
LM Studio
@lmstudio
Qwen3. Coder. 30B.
Is finally here!
lmstudio.ai/models/qwen/qwen3-coder-30b
Qwen reposted
nisten
@nisten
Thank you @AnthropicAI for nerfing opus.
I learned how to run push over 50million tokens per hour for way cheaper on private infra.
I.e. Running Qwen3-Coder-480 at 760k context can fix the app way faster than Opus.
And yes the app is looking great

 Qwen
@Alibaba_Qwen
🦥 Qwen3-Coder-Flash: Qwen3-Coder-30B-A3B-Instruct
💚 Just lightning-fast, accurate code generation.
✅ Native 256K context (supports up to 1M tokens with YaRN)
✅ Optimized for platforms like Qwen Code, Cline, Roo Code, Kilo Code, etc.
✅ Seamless function calling & agent workflows
💬 Chat: chat.qwen.ai
🤗 Hugging Face: hf.co/Qwen/Qwen3-Coder-30B-A3B-Instruct
🤖 ModelScope: modelscope.cn/models/Qwen/Qwen3-Coder-30B-A3B-Instruct
🔧 Qwen Code: github.com/QwenLM/qwen-code
Qwen
@Alibaba_Qwen
🔧 Qwen-Code Update: Since launch, we’ve been thrilled by the community’s response to our experimental Qwen Code project. Over the past two weeks, we've fixed several issues and are committed to actively maintaining and improving the repo alongside the community.
🎁 For users in China: ModelScope offers 2,000 free API calls per day.
🚀 We also support the OpenRouter API, so anyone can access the free Qwen3-Coder API via OpenRouter.
Qwen
@Alibaba_Qwen
Now available in anycoder: huggingface.co/spaces/akhaliq/anycoder
Qwen reposted
 Binyuan Hui
@huybery
Since the release of Qwen3-Coder a week ago, it has got a lot of love from the community! We have received many valuable suggestions, and we will continue to make it better. I have also heard malicious doubting voices, but I know that the usage of Qwen3-Coder on @openrouter is the best proof of how great it is. ❤️
 Qwen
@Alibaba_Qwen
🚀 Qwen3-30B-A3B-Thinking-2507, a medium-size model that can think!
• Nice performance on reasoning tasks, including math, science, code & beyond
• Good at tool use, competitive with larger models
• Native support of 256K-token context, extendable to 1M
Qwen Chat: Go to chat.qwen.ai?model=Qwen3-30B-A3B-2507 and click “Thinking”.
HF:huggingface.co/Qwen/Qwen3-30B-A3B-Thinking-2507 or huggingface.co/Qwen/Qwen3-30B-A3B-Thinking-2507-FP8
ModelScope: modelscope.cn/models/Qwen/Qwen3-30B-A3B-Thinking-2507 or modelscope.cn/models/Qwen/Qwen3-30B-A3B-Thinking-2507-FP8
 Qwen
@Alibaba_Qwen
Performance
 Qwen
@Alibaba_Qwen
Sample Code
 Qwen
@Alibaba_Qwen
Available in anycoder now: huggingface.co/spaces/akhaliq/anycoder
Qwen
@Alibaba_Qwen
Qwen3-Coder is now the default model powering Anycoder! Massive boost to productivity and creativity.
huggingface.co/spaces/akhaliq/anycoder
Qwen reposted
LM Studio
@lmstudio
Qwen/Qwen3-30B-A3B
> 30B MoE, 3B active
> 256K context. ~18GB to run locally
> Excel at instruction following + tool use
> GGUF and MLX quants available!
lmstudio.ai/models/qwen/qwen3-30b-a3b-2507
Qwen reposted
AK
@_akhaliq
Qwen3-30B-A3B-Instruct-2507 @Alibaba_Qwen is now available in anycoder for vibe coding
Qwen
@Alibaba_Qwen
🚀 Qwen3-30B-A3B Small Update: Smarter, faster, and local deployment-friendly.
✨ Key Enhancements:
✅ Enhanced reasoning, coding, and math skills
✅ Broader multilingual knowledge
✅ Improved long-context understanding (up to 256K tokens)
✅ Better alignment with user intent and open-ended tasks
✅ No more <think> blocks — now operating exclusively in non-thinking mode
🔧 With 3B activated parameters, it's approaching the performance of GPT-4o and Qwen3-235B-A22B Non-Thinking
Qwen Chat: chat.qwen.ai?model=Qwen3-30B-A3B-2507
HF:huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507 or huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507-FP8
ModelScope: modelscope.cn/models/Qwen/Qwen3-30B-A3B-Instruct-2507 or modelscope.cn/models/Qwen/Qwen3-30B-A3B-Instruct-2507-FP8
 Qwen
@Alibaba_Qwen
Performance
 Qwen
@Alibaba_Qwen
API
 Qwen
@Alibaba_Qwen
🚀 GSPO: Group Sequence Policy Optimization — a breakthrough RL algorithm for scaling LMs!
🔹 Sequence-level optimization — theoretically sound & matching reward
🔹 Rock-solid stability for large MoE models — no collapse
🔹 No hacks like Routing Replay — simpler, cleaner training
🔹 Scales effortlessly: more compute = better results ✅
🔥 Powers the latest Qwen3 (Instruct, Coder, Thinking)
📊 Cleaner gradient, faster convergence, lighter infrastructure than GRPO
GSPO = Stable. Scalable. Infra-friendly.
Let’s push the limits of intelligence.
Paper: huggingface.co/papers/2507.18071
Try the latest Qwen3: chat.qwen.ai
Qwen reposted
Cline
@cline
How are we feeling about @Alibaba_Qwen's qwen3-coder?
(FYI, its diff edit failure rate, 5 days in, is 5.75%; on par with Sonnet 4 and Kimi K2)

Qwen reposted
OpenRouter
@OpenRouter
Qwen3 Coder has now passed Grok 4 in the Programming prompt rankings
Tied with Kimi!
 Qwen
@Alibaba_Qwen
🚀 We’re excited to introduce Qwen3-235B-A22B-Thinking-2507 — our most advanced reasoning model yet!
Over the past 3 months, we’ve significantly scaled and enhanced the thinking capability of Qwen3, achieving:
✅ Improved performance in logical reasoning, math, science & coding
✅ Better general skills: instruction following, tool use, alignment
✅ 256K native context for deep, long-form understanding
🧠 Built exclusively for thinking mode, with no need to enable it manually. The model now natively supports extended reasoning chains for maximum depth and accuracy.
Hugging Face: huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507
or huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507-FP8
ModelScope: modelscope.cn/models/Qwen/Qwen3-235B-A22B-Thinking-2507
or modelscope.cn/models/Qwen/Qwen3-235B-A22B-Thinking-2507-FP8
API Doc: www.alibabacloud.com/help/en/model-studio/models
 Qwen
@Alibaba_Qwen
Want to experience it directly? Try Qwen3-235B-A22B-Thinking-2507 in Qwen Chat (chat.qwen.ai)!
 Qwen
@Alibaba_Qwen
Try it via API: Qwen3-235B-A22B-Thinking-2507 is now available on Alibaba Cloud!

Qwen reposted
LM Studio
@lmstudio
Qwen/Qwen3-Coder with tool calling is supported in LM Studio 0.3.20, out now.
480B parameters, 35B active. Requires about 250GB to run locally.
 Qwen
@Alibaba_Qwen
🚀 Introducing Qwen3-MT – our most powerful translation model yet!
Trained on trillions of multilingual tokens, it supports 92+ languages—covering 95%+ of the world’s population. 🌍✨
🔑 Why Qwen3-MT?
✅ Top-tier translation quality
✅ Customizable: terminology control, domain prompts, TM
✅ Ultra-fast & cost-effective: from $0.5/million tokens (MoE)
✅ Built for scale: low latency, high concurrency
Enhanced with reinforcement learning for unmatched fluency & accuracy.
Now available via the Qwen API – start breaking language barriers today! 💬🌐
Hugging Face Demo:huggingface.co/spaces/Qwen/Qwen3-MT-Demo
ModelScope Demo:modelscope.cn/studios/Qwen/Qwen3-MT-demo
API Doc:www.alibabacloud.com/help/en/model-studio/translation-abi…
Blog:qwenlm.github.io/blog/qwen-mt/

Qwen reposted
Cline
@cline
Qwen3-Coder is now available in Cline 🧵
New 480B parameter model with 35B active parameters.
> 256K context window
> comparable performance on SWE-bench to Claude Sonnet 4
> SoTA among open source models
 Qwen
@Alibaba_Qwen
>>> Qwen3-Coder is here! ✅
We’re releasing Qwen3-Coder-480B-A35B-Instruct, our most powerful open agentic code model to date. This 480B-parameter Mixture-of-Experts model (35B active) natively supports 256K context and scales to 1M context with extrapolation. It achieves top-tier performance across multiple agentic coding benchmarks among open models, including SWE-bench-Verified!!! 🚀
Alongside the model, we're also open-sourcing a command-line tool for agentic coding: Qwen Code. Forked from Gemini Code, it includes custom prompts and function call protocols to fully unlock Qwen3-Coder’s capabilities. Qwen3-Coder works seamlessly with the community’s best developer tools. As a foundation model, we hope it can be used anywhere across the digital world — Agentic Coding in the World!
💬 Chat: chat.qwen.ai
📚 Blog: qwenlm.github.io/blog/qwen3-coder/
🤗 Model: hf.co/Qwen/Qwen3-Coder-480B-A35B-Instruct
🤖 Qwen Code: github.com/QwenLM/qwen-code

Qwen reposted
OpenRouter
@OpenRouter
Qwen has passed Moonshot and xAI in token marketshare 👀
 OpenRouter
@OpenRouter
🟣New: Qwen3-Coder by @Alibaba_Qwen
- 480B params (35B active)
- Native 256K context length, extrapolates to 1M
- Outperforms Kimi, o3, DeepSeek, and more on SWE-Bench Verified (69.6%) 👀
Now live, starting at $1/M tokens 👇
 Qwen
@Alibaba_Qwen
RT @lmsysorg: ✅ We’re excited to support @Qwen’s Qwen3-Coder on SGLang! With tool call parser and expert parallelism enabled, it runs smoot…
Qwen
@Alibaba_Qwen
>>> Qwen3-Coder is here! ✅
We’re releasing Qwen3-Coder-480B-A35B-Instruct, our most powerful open agentic code model to date. This 480B-parameter Mixture-of-Experts model (35B active) natively supports 256K context and scales to 1M context with extrapolation. It achieves top-tier performance across multiple agentic coding benchmarks among open models, including SWE-bench-Verified!!! 🚀
Alongside the model, we're also open-sourcing a command-line tool for agentic coding: Qwen Code. Forked from Gemini Code, it includes custom prompts and function call protocols to fully unlock Qwen3-Coder’s capabilities. Qwen3-Coder works seamlessly with the community’s best developer tools. As a foundation model, we hope it can be used anywhere across the digital world — Agentic Coding in the World!
💬 Chat: chat.qwen.ai
📚 Blog: qwenlm.github.io/blog/qwen3-coder/
🤗 Model: hf.co/Qwen/Qwen3-Coder-480B-A35B-Instruct
🤖 Qwen Code: github.com/QwenLM/qwen-code
Qwen reposted
vLLM
@vllm_project
✅ Try out @Alibaba_Qwen 3 Coder on vLLM nightly with "qwen3_coder" tool call parser! Additionally, vLLM offers expert parallelism so you can run this model in flexible configurations where it fits.
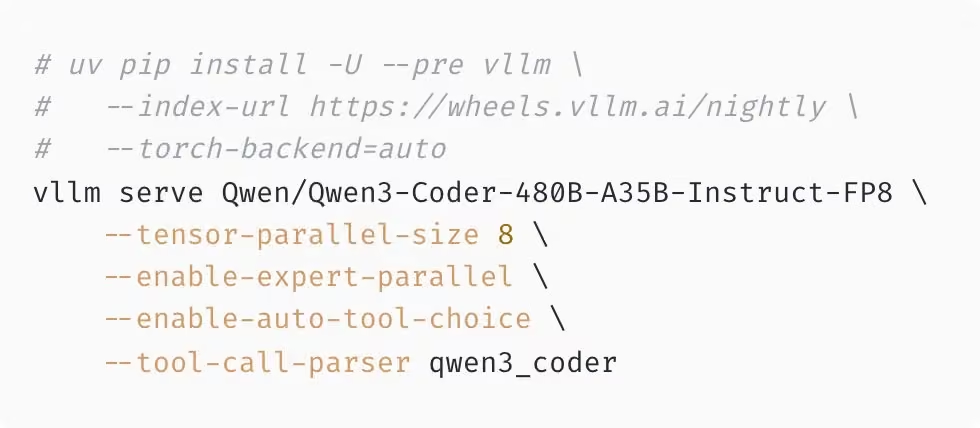 Qwen
@Alibaba_Qwen
>>> Qwen3-Coder is here! ✅
We’re releasing Qwen3-Coder-480B-A35B-Instruct, our most powerful open agentic code model to date. This 480B-parameter Mixture-of-Experts model (35B active) natively supports 256K context and scales to 1M context with extrapolation. It achieves top-tier performance across multiple agentic coding benchmarks among open models, including SWE-bench-Verified!!! 🚀
Alongside the model, we're also open-sourcing a command-line tool for agentic coding: Qwen Code. Forked from Gemini Code, it includes custom prompts and function call protocols to fully unlock Qwen3-Coder’s capabilities. Qwen3-Coder works seamlessly with the community’s best developer tools. As a foundation model, we hope it can be used anywhere across the digital world — Agentic Coding in the World!
💬 Chat: chat.qwen.ai
📚 Blog: qwenlm.github.io/blog/qwen3-coder/
🤗 Model: hf.co/Qwen/Qwen3-Coder-480B-A35B-Instruct
🤖 Qwen Code: github.com/QwenLM/qwen-code
Qwen
@Alibaba_Qwen
>>> Qwen3-Coder is here! ✅
We’re releasing Qwen3-Coder-480B-A35B-Instruct, our most powerful open agentic code model to date. This 480B-parameter Mixture-of-Experts model (35B active) natively supports 256K context and scales to 1M context with extrapolation. It achieves top-tier performance across multiple agentic coding benchmarks among open models, including SWE-bench-Verified!!! 🚀
Alongside the model, we're also open-sourcing a command-line tool for agentic coding: Qwen Code. Forked from Gemini Code, it includes custom prompts and function call protocols to fully unlock Qwen3-Coder’s capabilities. Qwen3-Coder works seamlessly with the community’s best developer tools. As a foundation model, we hope it can be used anywhere across the digital world — Agentic Coding in the World!
💬 Chat: chat.qwen.ai
📚 Blog: qwenlm.github.io/blog/qwen3-coder/
🤗 Model: hf.co/Qwen/Qwen3-Coder-480B-A35B-Instruct
🤖 Qwen Code: github.com/QwenLM/qwen-code
Qwen
@Alibaba_Qwen
3D Earth Terrain Visualization
Qwen
@Alibaba_Qwen
Animated Weather Card
Qwen
@Alibaba_Qwen
Solar System Simulation
Qwen
@Alibaba_Qwen
Particle Vortex
Qwen
@Alibaba_Qwen
Feel free to try out the API of Qwen3-Coder on Alibaba Cloud Model Studio!
🔗: modelstudio.console.alibabacloud.com
Qwen
@Alibaba_Qwen
Qwen
@Alibaba_Qwen
Qwen
@Alibaba_Qwen
Bye Qwen3-235B-A22B, hello Qwen3-235B-A22B-2507!
After talking with the community and thinking it through, we decided to stop using hybrid thinking mode. Instead, we’ll train Instruct and Thinking models separately so we can get the best quality possible. Today, we’re releasing Qwen3-235B-A22B-Instruct-2507 and its FP8 version for everyone.
This model performs better than our last release, and we hope you’ll like it thanks to its strong overall abilities.
Qwen Chat: chat.qwen.ai — just start chatting with the default model, and feel free to use the search button!
HF: huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507 or huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507-FP8
ModelScope: modelscope.cn/models/Qwen/Qwen3-235B-A22B-Instruct-2507 or modelscope.cn/models/Qwen/Qwen3-235B-A22B-Instruct-2507-FP8
It’s smarter, knows more, can do more things, and works better on agent tasks. Try it out and see how it works for you.
Check the model card on Hugging Face (huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507) to see the benchmark results.
This is a small update! Bigger things are coming soon!
 Qwen
@Alibaba_Qwen
Performance
 Qwen
@Alibaba_Qwen
We noticed in community discussions that when using Qwen3-embedding's GGUF models, some developers are not appending the special token <|endoftext|> at the end of the context. This can significantly hurt model accuracy. Check our Model Card (huggingface.co/Qwen/Qwen3-Embedding-0.6B-GGUF) for more details.
Good news: llama.cpp supports automatically adding this token during convert GGUF files. We’ll soon release an updated GGUF model package so developers won’t have to handle this manually anymore. :-)
Qwen
@Alibaba_Qwen
🚀 Qwen Chat for Desktop is here!
💻 All the power of Qwen Chat — now with MCP support for smarter, faster agents.
⚡️ Run MCP Server, boost productivity, and stay in control.
📥 Grab it now: qwen.ai/download
Qwen
@Alibaba_Qwen
🎉 Introducing qwen.ai
Explore three powerful tools in one place:
🔹 Qwen Chat — AI to brainstorm, create, and collaborate
🔹 Research — Stay updated with Qwen’s latest work
🔹 Qwen API — Perfect for building your own AI-powered apps
🌐 Dive in: qwen.ai
Built for builders, thinkers, and creators.
Qwen
@Alibaba_Qwen
🚀 Meet Qwen-TTS – now live via the Qwen API !
Trained on millions of hours of speech, it delivers ultra-natural, expressive audio with smart prosody, pacing, and emotion.
🗣️ Supports 3 Chinese dialects: Beijing, Shanghai, Sichuan
🎙️ 7 bilingual voices: Cherry, Ethan, Chelsie, Serena, Dylan, Jada, Sunny
🔗 Learn more: qwenlm.github.io/blog/qwen-tts/
👉 Start using it via API: help.aliyun.com/zh/model-studio/qwen-tts
Qwen
@Alibaba_Qwen
Meet Qwen-VLo, your AI creative engine:
• Concept-to-Polish: Turn rough sketches or text prompts into high-res visuals
• On-the-Fly Edits: Refine product shots, adjust layouts or styles with simple commands
• Global-Ready: Generate image in multiple languages
• Progressive Generation: Build complex scenes step-by-step
Perfect for designers, marketers, educators—and anyone who wants to bring ideas to life.
👉 Try it: chat.qwen.ai
📖 Details: qwenlm.github.io/blog/qwen-vlo/
Qwen reposted
 Menlo Research
@menloresearch
Meet Jan-nano, a 4B model that outscores DeepSeek-v3-671B using MCP.
It's built on Qwen3-4B with DAPO fine-tuning, it handles:
- real-time web search
- deep research
Model + GGUF: huggingface.co/collections/Menlo/jan-nano-684f6ebfe9ed640…
To run it locally:
- Install Jan Beta: jan.ai/docs/desktop/beta
- Download Jan-nano in Jan Hub
- Settings -> MCP, enable MCP and add your Serper API key for web tools
Full technical report will be published shortly.
Qwen
@Alibaba_Qwen
🚀 Excited to launch Qwen3 models in MLX format today!
Now available in 4 quantization levels: 4bit, 6bit, 8bit, and BF16 — Optimized for MLX framework.
👉 Try it now!
Huggingface:huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f65…
ModelScope: modelscope.cn/collections/Qwen3-9743180bdc6b48
 Qwen
@Alibaba_Qwen
🚀 Proud to introduce the Qwen3-Embedding and Qwen3-Reranker Series – setting new standards in multilingual text embedding and relevance ranking!
✨ Highlights:
✅ Available in 0.6B / 4B / 8B versions
✅ Supports 119 languages
✅ State-of-the-Art performance on MMTEB , MTEB , and MTEB-Code
✅ Open-source on Hugging Face, GitHub & ModelScope
✅ Ready-to-use via API on Alibaba Cloud
🔍 Empowering use cases:
Document retrieval, RAG, classification, sentiment analysis, code search & more!
🔗 Explore Now :
Hugging Face
Qwen3-Embedding: huggingface.co/collections/Qwen/qwen3-embedding-6841b2055…
Qwen3-Reranker: huggingface.co/collections/Qwen/qwen3-reranker-6841b22d01…
ModelScope
Qwen3-Embedding: modelscope.cn/collections/Qwen3-Embedding-3edc3762d50f48
Qwen3-Reranker: modelscope.cn/collections/Qwen3-Reranker-6316e71b146c4f
GitHub : github.com/QwenLM/Qwen3-Embedding
Blog : qwenlm.github.io/blog/qwen3-embedding/
 Qwen
@Alibaba_Qwen
Tech report:github.com/QwenLM/Qwen3-Embedding/blob/main/qwen3_embeddi…
Qwen
@Alibaba_Qwen
🚀 Qwen Web Dev just got even better!
✨ One prompt. One website. One click to deploy.
💡 Let your creativity shine — and share it with the world.
🔥 What will you build today?
Qwen reposted
Binyuan Hui
@huybery
Parameter and inference-time scaling have already demonstrated that more compute brings more intelligence.
🤔 But is there a new way to scale compute? The answer might be yes!
We propose Parallel Scaling—increasing parallel computation during training and inference. As an exploratory study, we theoretically propose a new scaling law and validate it through pre-training, which shows that a model with P parallel streams is similar to scaling the parameters by O(log P), while showing superior inference efficiency.
📄 arxiv.org/abs/2505.10475
🤖 github.com/QwenLM/ParScale
🤗hf.co/spaces/ParScale/Parallel_Scaling_Law
 Qwen
@Alibaba_Qwen
Title: Modeling World Preference
Our research reveals that human preference modeling follows Scaling Laws, suggesting that diverse human preferences might share a unified representation. We propose "Modeling World Preference" to emphasize this potential for scalability. We conduct extensive experiments using 15 million preference pairs from StackExchange on Qwen2.5 models ranging from 1.5B to 72B parameters, with comprehensive benchmark testing.
Key findings:
1. Preference modeling shows logarithmic loss reduction with increased training scale on objective and robustness metrics.
2. We observed emergence phenomena - only 72B models demonstrate scaling trends on certain challenging tasks.
3. Subjective evaluation shows convergence or increasing loss, which we attribute to discrepancies between WorldPM's learned preferences and predefined evaluation criteria.
Further experiments confirm WorldPM as an effective preference fine-tuning foundation, validated across three preference datasets (7K-800K samples) and extensive benchmarks.
For detailed discussions on why subjective evaluation does not scale and why preference modeling is scalable, please refer to our GitHub README.
🔥 Paper and model now open-source:
📄 Paper: arxiv.org/abs/2505.10527
⭐️ GitHub: github.com/QwenLM/WorldPM
🤗 Hugging Face: huggingface.co/Qwen/WorldPM-72B
🤖️ModelScope:modelscope.cn/collections/WorldPM-6f5248ed14ad46
Qwen
@Alibaba_Qwen
We’re releasing the quantized models of Qwen2.5-Omni-7B today!
Find all models in the Qwen2.5-Omni collection on Hugging Face and ModelSope.
Hugging Face:huggingface.co/collections/Qwen/qwen25-omni-67de1e5f0f946…
ModelScope:modelscope.cn/collections/Qwen25-Omni-a2505ce0d5514e
Enjoy!
 Qwen
@Alibaba_Qwen
After a few weeks of phased testing, Deep Research on Qwen Chat is now live and available for everyone ! 🎉
Here's how to use it: Just ask something you're curious about — like "Tell me something about robotics." Qwen will then ask you to narrow it down — maybe history, theory, or real-world applications. You can pick one, or just say "Not sure… Surprise me!" 😄
Then, while you grab a coffee ☕ or take a quick break, Qwen will put together a clear, helpful report just for you.
AI is getting better every day, and Qwen is here to help make your life a little easier — whether it’s for work, learning, or just satisfying your curiosity.
Why not give it a try? You might find something cool! 💡
🔗:chat.qwen.ai?inputFeature=deep_research
Qwen
@Alibaba_Qwen
Please check out our Qwen3 Technical Report. 👇🏻
github.com/QwenLM/Qwen3/blob/main/Qwen3_Technical_Report.pdf
 Qwen
@Alibaba_Qwen
We’re officially releasing the quantized models of Qwen3 today!
Now you can deploy Qwen3 via Ollama, LM Studio, SGLang, and vLLM — choose from multiple formats including GGUF, AWQ, and GPTQ for easy local deployment.
Find all models in the Qwen3 collection on Hugging Face and ModelSope.
Hugging Face:huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f65…
ModelScope:modelscope.cn/collections/Qwen3-9743180bdc6b48
📷 For more usage examples, check out the image below!
 Qwen
@Alibaba_Qwen
🚀 One line. A full webpage. No hassle.
Introducing Web Dev – the ultimate tool for building stunning frontend webpages & apps using simple prompts in Qwen Chat.
🎨 Just say, "create a twitter website" — and boom! Instant code, ready to go.
No coding required. Just your imagination.
👉🏻 chat.qwen.ai?inputFeature=web_dev
 Qwen
@Alibaba_Qwen
Make an interesting animate
Qwen
@Alibaba_Qwen
Create a sunscreen product introduction website.
 Qwen
@Alibaba_Qwen
qwenlm.github.io/blog/qwen3/ Based on this content, create a nice-looking card with a tech theme. include the phrase:
For thinking mode, use Temperature=0.6, TopP=0.95, TopK=20, and MinP=0. For non-thinking mode, we suggest using Temperature=0.7, TopP=0.8, TopK=20, and MinP=0.
 Qwen
@Alibaba_Qwen
 Unsloth AI
@UnslothAI
You can now fine-tune Qwen3 (14B) for free with our notebook!
Unsloth makes Qwen3 finetuning 2x faster with 70% less VRAM and 8x longer context lengths - with no accuracy loss.
Guide: docs.unsloth.ai/basics/qwen3-how-to-run-and-fine-tune
GitHub: github.com/unslothai/unsloth
Colab: colab.research.google.com/drive/1_ZJD6xqYDvhRbKSQeV8pThLB…
Qwen
@Alibaba_Qwen
We will release the quantized models of Qwen3 to you in the following days. Today we release the AWQ and GGUFs of Qwen3-14B and Qwen3-32B, which enables using the models with limited GPU memory.
Qwen3-32B-AWQ: huggingface.co/Qwen/Qwen3-32B-AWQ
Qwen3-32B-GGUF: huggingface.co/Qwen/Qwen3-32B-GGUF
Qwen3-14B-AWQ: huggingface.co/Qwen/Qwen3-14B-AWQ
Qwen3-14B-GGUF: huggingface.co/Qwen/Qwen3-14B-GGUF
Note that when using the GGUFs in Ollama and LMStudio, to switch from thinking to non_thinking, you just need to add the special token `/no_think` at the end of the input. Below is an example.
Enjoy!


Qwen reposted
Together AI
@togethercompute
We’re thrilled to announce the launch of Qwen 3 on Together AI.
Qwen3 235B A22B, a state of the art hybrid reasoning model, is now available on the Together API. It excels in tool calling, coding, multi-lingual tasks, math, and general tasks.
Link & details below!
 Qwen
@Alibaba_Qwen
We’re excited to announce the release of Qwen2.5-Omni-3B, enabling developers with lightweight GPU accessibility!
🔹 Compared to Qwen2.5-Omni-7B model, the 3B version achieves a remarkable 50%+ reduction 🚀 in VRAM consumption during long-context sequence processing (~25k tokens), while supporting extended 30-second audio-video interactions on typical 24GB consumer-grade GPUs.
🔹 Retains 90%+ multimodal comprehension of the 7B model, with natural speech output accuracy and stability matching the performance of the 7B version 💪🏻.
Git repo: github.com/QwenLM/Qwen2.5-Omni
Hugging Face: huggingface.co/Qwen/Qwen2.5-Omni-3B
ModelScope: modelscope.cn/models/Qwen/Qwen2.5-Omni-3B


Qwen reposted
 OpenHands
@OpenHandsDev
It's great to see that Qwen3 works out-of-the-box with OpenHands!
We've heard from community members that Qwen3-30B-A3B also works quite well, and achieves reasonable speed (50-60 tokens/s) even on a Mac M1 processor.
Qwen
@Alibaba_Qwen
We also evaluated the preliminary performance of Qwen3-235B-A22B on the open-source coding agent Openhands. It achieved 34.4% on Swebench-verified, achieving competitive results with fewer parameters! Thanks to @allhands_ai for providing an easy-to-use agent. Both open models and open agents are exciting!
 Qwen
@Alibaba_Qwen
interesting!
 Hermione
@YUEXINWANG61157
The Vanishing Web
by Qwen3
Qwen
@Alibaba_Qwen
Introducing Qwen3!
We release and open-weight Qwen3, our latest large language models, including 2 MoE models and 6 dense models, ranging from 0.6B to 235B. Our flagship model, Qwen3-235B-A22B, achieves competitive results in benchmark evaluations of coding, math, general capabilities, etc., when compared to other top-tier models such as DeepSeek-R1, o1, o3-mini, Grok-3, and Gemini-2.5-Pro. Additionally, the small MoE model, Qwen3-30B-A3B, outcompetes QwQ-32B with 10 times of activated parameters, and even a tiny model like Qwen3-4B can rival the performance of Qwen2.5-72B-Instruct.
For more information, feel free to try them out in Qwen Chat Web (chat.qwen.ai) and APP and visit our GitHub, HF, ModelScope, etc.
Blog: qwenlm.github.io/blog/qwen3/
GitHub: github.com/QwenLM/Qwen3
Hugging Face: huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f65…
ModelScope: modelscope.cn/collections/Qwen3-9743180bdc6b48
The post-trained models, such as Qwen3-30B-A3B, along with their pre-trained counterparts (e.g., Qwen3-30B-A3B-Base), are now available on platforms like Hugging Face, ModelScope, and Kaggle. For deployment, we recommend using frameworks like SGLang and vLLM. For local usage, tools such as Ollama, LMStudio, MLX, llama.cpp, and KTransformers are highly recommended. These options ensure that users can easily integrate Qwen3 into their workflows, whether in research, development, or production environments.
Hope you enjoy our new models!

 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
We also evaluated the preliminary performance of Qwen3-235B-A22B on the open-source coding agent Openhands. It achieved 34.4% on Swebench-verified, achieving competitive results with fewer parameters! Thanks to @allhands_ai for providing an easy-to-use agent. Both open models and open agents are exciting!
Qwen reposted
 Kaggle
@kaggle
🤖 Now on #kagglemodels!
The long-awaited @Alibaba_Qwen's Qwen 3 is here - featuring dense + MoE models, trained on 36T tokens across 119 languages. Big gains in reasoning, performance, and long-context (32k tokens) support!
Learn more: www.kaggle.com/models/qwen-lm/qwen-3/
Qwen
@Alibaba_Qwen
Introducing Qwen3!
We release and open-weight Qwen3, our latest large language models, including 2 MoE models and 6 dense models, ranging from 0.6B to 235B. Our flagship model, Qwen3-235B-A22B, achieves competitive results in benchmark evaluations of coding, math, general capabilities, etc., when compared to other top-tier models such as DeepSeek-R1, o1, o3-mini, Grok-3, and Gemini-2.5-Pro. Additionally, the small MoE model, Qwen3-30B-A3B, outcompetes QwQ-32B with 10 times of activated parameters, and even a tiny model like Qwen3-4B can rival the performance of Qwen2.5-72B-Instruct.
For more information, feel free to try them out in Qwen Chat Web (chat.qwen.ai) and APP and visit our GitHub, HF, ModelScope, etc.
Blog: qwenlm.github.io/blog/qwen3/
GitHub: github.com/QwenLM/Qwen3
Hugging Face: huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f65…
ModelScope: modelscope.cn/collections/Qwen3-9743180bdc6b48
The post-trained models, such as Qwen3-30B-A3B, along with their pre-trained counterparts (e.g., Qwen3-30B-A3B-Base), are now available on platforms like Hugging Face, ModelScope, and Kaggle. For deployment, we recommend using frameworks like SGLang and vLLM. For local usage, tools such as Ollama, LMStudio, MLX, llama.cpp, and KTransformers are highly recommended. These options ensure that users can easily integrate Qwen3 into their workflows, whether in research, development, or production environments.
Hope you enjoy our new models!
Qwen reposted
LMSYS Org
@lmsysorg
It is great honor for SGLang to establish a deep partnership with the @Alibaba_Qwen team. Let’s work together to make Qwen3 inference even faster!🚀🚀🚀
Junyang Lin
@JustinLin610
@lmsysorg thanks to the support of SGL! They have been dedicated to helping us deploy the large MoE models and improve the inference efficiency. 🌊
 Qwen
@Alibaba_Qwen
Introducing Qwen3!
We release and open-weight Qwen3, our latest large language models, including 2 MoE models and 6 dense models, ranging from 0.6B to 235B. Our flagship model, Qwen3-235B-A22B, achieves competitive results in benchmark evaluations of coding, math, general capabilities, etc., when compared to other top-tier models such as DeepSeek-R1, o1, o3-mini, Grok-3, and Gemini-2.5-Pro. Additionally, the small MoE model, Qwen3-30B-A3B, outcompetes QwQ-32B with 10 times of activated parameters, and even a tiny model like Qwen3-4B can rival the performance of Qwen2.5-72B-Instruct.
For more information, feel free to try them out in Qwen Chat Web (chat.qwen.ai) and APP and visit our GitHub, HF, ModelScope, etc.
Blog: qwenlm.github.io/blog/qwen3/
GitHub: github.com/QwenLM/Qwen3
Hugging Face: huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f65…
ModelScope: modelscope.cn/collections/Qwen3-9743180bdc6b48
The post-trained models, such as Qwen3-30B-A3B, along with their pre-trained counterparts (e.g., Qwen3-30B-A3B-Base), are now available on platforms like Hugging Face, ModelScope, and Kaggle. For deployment, we recommend using frameworks like SGLang and vLLM. For local usage, tools such as Ollama, LMStudio, MLX, llama.cpp, and KTransformers are highly recommended. These options ensure that users can easily integrate Qwen3 into their workflows, whether in research, development, or production environments.
Hope you enjoy our new models!
Qwen reposted
ollama
@ollama
ollama run qwen3
You can toggle non-thinking mode in Ollama by typing /no_think after the prompt.
Check out all the model sizes 👇👇👇🧵
Qwen
@Alibaba_Qwen
Introducing Qwen3!
We release and open-weight Qwen3, our latest large language models, including 2 MoE models and 6 dense models, ranging from 0.6B to 235B. Our flagship model, Qwen3-235B-A22B, achieves competitive results in benchmark evaluations of coding, math, general capabilities, etc., when compared to other top-tier models such as DeepSeek-R1, o1, o3-mini, Grok-3, and Gemini-2.5-Pro. Additionally, the small MoE model, Qwen3-30B-A3B, outcompetes QwQ-32B with 10 times of activated parameters, and even a tiny model like Qwen3-4B can rival the performance of Qwen2.5-72B-Instruct.
For more information, feel free to try them out in Qwen Chat Web (chat.qwen.ai) and APP and visit our GitHub, HF, ModelScope, etc.
Blog: qwenlm.github.io/blog/qwen3/
GitHub: github.com/QwenLM/Qwen3
Hugging Face: huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f65…
ModelScope: modelscope.cn/collections/Qwen3-9743180bdc6b48
The post-trained models, such as Qwen3-30B-A3B, along with their pre-trained counterparts (e.g., Qwen3-30B-A3B-Base), are now available on platforms like Hugging Face, ModelScope, and Kaggle. For deployment, we recommend using frameworks like SGLang and vLLM. For local usage, tools such as Ollama, LMStudio, MLX, llama.cpp, and KTransformers are highly recommended. These options ensure that users can easily integrate Qwen3 into their workflows, whether in research, development, or production environments.
Hope you enjoy our new models!
Qwen
@Alibaba_Qwen
The Qwen Chat APP is now available for both iOS and Android users!
It's free to use and designed to assist with creativity, collaboration, and endless possibilities. Just ask, and let Qwen Chat handle the rest.
Scan the QR code to quickly access the Qwen Chat APP!
 Qwen
@Alibaba_Qwen
Qwen Chat APP is now available in limited markets.
Qwen
@Alibaba_Qwen
Feel free to download the Qwen Chat Android APP by scanning this QR code!
 Qwen
@Alibaba_Qwen
The Qwen Chat APP is now available for both iOS and Android users!
It's free to use and designed to assist with creativity, collaboration, and endless possibilities. Just ask, and let Qwen Chat handle the rest.
Scan the QR code to quickly access the Qwen Chat APP!
Qwen
@Alibaba_Qwen
Qwen 🤝🏻 flock.io
 FLock.io
@flock_io
Say GM to @Alibaba_Qwen!
We’re proud to announce a strategic collaboration between FLock and Qwen, a world-leading open-source LLM series developed by @alibaba_cloud.
For years, decentralized AI has been questioned for its lack of real-world utility.
Today, FLock rewrites the narrative.
Qwen reposted
FLock.io
@flock_io
Say GM to @Alibaba_Qwen!
We’re proud to announce a strategic collaboration between FLock and Qwen, a world-leading open-source LLM series developed by @alibaba_cloud.
For years, decentralized AI has been questioned for its lack of real-world utility.
Today, FLock rewrites the narrative.
Qwen reposted
LMSYS Org
@lmsysorg
Hello, everyone! Get ready for an electrifying session this Saturday at 6 PM Pacific Time (9 PM Eastern Time) or Sunday at 9 AM Beijing Time. Our SGLang RL Team will take the stage at the SGLang Biweekly Meeting to share thrilling updates on our RLHF (Reinforcement Learning from Human Feedback) progress!
We’re diving deep into cutting-edge topics, including Multi-Node Support, VLM RLHF, Multi-Turn RLHF, SPIN & SPPO Recipes, and Server-Based Rollout—everything except TRL will be covered with high-energy insights! Whether you're a curious enthusiast or a seasoned expert, come join the live discussion, share your thoughts, and maybe even keep us on our toes! 😄
The SGLang RL Group is a vibrant community of over 20 developers worldwide, pushing boundaries with a relentless 12-hour update cycle. We’re proud to drive the open-source community forward with a unique collaboration model, delivering maximum sincerity and lightning-fast progress. Be part of this dynamic ecosystem and help us shape the future!
Let’s innovate together—see you there! 🚀
Qwen
@Alibaba_Qwen
✨ Excited to share QVQ-Max, our visual reasoning model that's still evolving
We've been experimenting with this approach for a while - try it out on Qwen Chat! (chat.qwen.ai) 🚀
Just upload any image or video, ask away, and hit the "Thinking" button to see how it processes visual information step-by-step. It's a work-in-progress but fascinating to watch!
Your early feedback will be super helpful as we continue developing! 🙏
Blog: qwenlm.github.io/blog/qvq-max-preview/
Qwen
@Alibaba_Qwen
Interpreting Palm Readings (For Reference Only)
Qwen
@Alibaba_Qwen
Video Understanding
Qwen
@Alibaba_Qwen
Voice Chat + Video Chat! Just in Qwen Chat (chat.qwen.ai)! You can now chat with Qwen just like making a phone call or making a video call! Check the demo in www.youtube.com/watch?v=yKcANdkRuNI
What's more, we opensource the model behind all this, Qwen2.5-Omni-7B, under the license of Apache 2.0, and we release the technical report to share all our details!
Qwen Chat: chat.qwenlm.ai
Paper: github.com/QwenLM/Qwen2.5-Omni/blob/main/assets/Qwen2.5_O…
Blog: qwenlm.github.io/blog/qwen2.5-omni
GitHub: github.com/QwenLM/Qwen2.5-Omni
Hugging Face: huggingface.co/Qwen/Qwen2.5-Omni-7B
ModelScope: modelscope.cn/models/Qwen/Qwen2.5-Omni-7B
This is an omni model, which is a single model that can understand text, audio, image, and video, and output text and audio. We have a designed "thinker-talker" architecture that makes thinking and talking simultaneously available. We believe that the trend of AGI is belonging to agent based on omni model.
This is still a small omni model. We are about to build things better, so stay tuned!
Qwen
@Alibaba_Qwen
Qwen2.5-Omni employs Thinker-Talker architecture. Thinker functions like a brain, responsible for processing and understanding inputs from text, audio and video modalities, generating high-level representations and corresponding text. Talker operates like a human mouth, taking in the high-level representations and text produced by the Thinker in a streaming manner, and outputting discrete tokens of speech fluidly. Thinker is a Transformer decoder, accompanied by encoders for audio and image that facilitate information extraction. In contrast, Talker is designed as a dual-track autoregressive Transformer Decoder architecture. During both training and inference, Talker directly receives high-dimensional representations from Thinker and shares all of Thinker’s historical context information. Consequently, the entire architecture operates as a cohesive single model, enabling end-to-end training and inference.
 Qwen
@Alibaba_Qwen
We conducted a comprehensive evaluation of Qwen2.5-Omni, which demonstrates strong performance across all modalities when compared to similarly sized single-modality models and closed-source models like Qwen2.5-VL-7B, Qwen2-Audio, and Gemini-1.5-pro. In tasks requiring the integration of multiple modalities, such as OmniBench, Qwen2.5-Omni achieves state-of-the-art performance. Furthermore, in single-modality tasks, it excels in areas including speech recognition (Common Voice), translation (CoVoST2), audio understanding (MMAU), image reasoning (MMMU, MMStar), video understanding (MVBench), and speech generation (Seed-tts-eval and subjective naturalness).
 Qwen
@Alibaba_Qwen
Sorry for our mistake of uploading a corrupted checkpoint of Qwen2.5-VL-32B-Instruct. Thanks to our users telling us this and we immediately fixed it today. Feel free to have another try and download the new checkpoint.
HF: huggingface.co/Qwen/Qwen2.5-VL-32B-Instruct
Another thing for you to play with is the AWQ quantized model, check it out here: huggingface.co/Qwen/Qwen2.5-VL-32B-Instruct-AWQ !
Qwen reposted
LMSYS Org
@lmsysorg
Love from the Qwen Team. Just do it with:
python3 -m sglang.launch_server --model-path Qwen/Qwen2.5-VL-32B-Instruct --chat-template=qwen2-vl
Love Qwen! 🐣
Qwen
@Alibaba_Qwen
72B too big for VLM? 7B not strong enough! Then you should use our 32B model, Qwen2.5-VL-32B-Instruct!
Blog: qwenlm.github.io/blog/qwen2.5-vl-32b/
Qwen Chat: chat.qwen.ai
HF: huggingface.co/Qwen/Qwen2.5-VL-32B-Instruct
ModelScope: modelscope.cn/models/Qwen/Qwen2.5-VL-32B-Instruct
This time, we further optimize this VLM with reinforcement learning and we have found significant improvements in human preference and also mathematical reasoning. Hope it can be the best choice of your local VLM!
 Qwen
@Alibaba_Qwen
72B too big for VLM? 7B not strong enough! Then you should use our 32B model, Qwen2.5-VL-32B-Instruct!
Blog: qwenlm.github.io/blog/qwen2.5-vl-32b/
Qwen Chat: chat.qwen.ai
HF: huggingface.co/Qwen/Qwen2.5-VL-32B-Instruct
ModelScope: modelscope.cn/models/Qwen/Qwen2.5-VL-32B-Instruct
This time, we further optimize this VLM with reinforcement learning and we have found significant improvements in human preference and also mathematical reasoning. Hope it can be the best choice of your local VLM!
Qwen reposted
 Bindu Reddy
@bindureddy
QwQ-32b Is Indeed The World's Best Open Source Model.
We re-ran QwQ with the suggested settings from the Qwen team, and it turns out that it's an AMAZING LLM
It's got excellent scores on Livebench AI.
 Qwen
@Alibaba_Qwen
Folks, we have set up a github repo for QwQ, specifically providing evaluation scripts for you to easily test the benchmark performance of reasoning models, and also reproduce our reported results. We provide step-by-step guidance for you to run the evaluation, and we hope this can help your research and implementation. Feel free to check it out and talk to us! GitHub: github.com/QwenLM/QwQ
Qwen
@Alibaba_Qwen
We have fixed it.
Qwen
@Alibaba_Qwen
We met a problem in our backend and caused you trouble using Qwen Chat. We are sincerely sorry for it and we will fix this bug very soon.
Qwen
@Alibaba_Qwen
We met a problem in our backend and caused you trouble using Qwen Chat. We are sincerely sorry for it and we will fix this bug very soon.
Qwen reposted
Menlo Research
@menloresearch
We made progress on a robotic hand manipulation model, PoseLess.
PoseLess reproduces 2D images of hands directly in 3D simulation, without complex inverse kinematics.
Here's how 👇
PoseLess is a depth-free vision-to-joint model that eliminates the intermediate pose estimation step. By leveraging a Vision Language Model (Qwen 2.5 3B), we map 2D images directly to joint angles with surprising accuracy.
Two core components make this work:
- VLM Image Projection: The model processes images directly to predict joint angles, eliminating error buildup from multi-stage pipelines.
- Synthetic Data Engine: Generates training examples by randomizing joint angles and visual features - creating perfect ground truth without human labeling.
What this enables:
- Control from monocular images (no depth sensors)
- Real-world performance without real-world training data
- Cross-morphology transfer from robot to human hands
- Competitive accuracy with a simpler pipeline
- Lower latency control
Paper: arxiv.org/abs/2503.07111
GitHub: github.com/janhq/poseless
HuggingFace: huggingface.co/homebrewltd/Poseless-3B
This work is very much early stage and untested, and we might explore tangential routes. But it worked and we found the results interesting nevertheless.
Join our Discord community to discuss this work and collaborate on future developments: discord.gg/Exe46xPMbK
 Qwen
@Alibaba_Qwen
👋 Introducing the Enhanced Qwen Chat
We are pleased to announce the latest update to Qwen Chat, designed to deliver a seamless, versatile, and user-centric experience. Explore the key features below and visit chat.qwen.ai to experience the innovation firsthand.
• Unified Multimodal Interface
All Qwen2.5 models (e.g., Qwen2.5-Max , Qwen2.5-Plus ) now integrate their corresponding VL (Vision-Language) variants into a single interface. This allows you to process text, images, and videos without switching models —simply use your preferred model (e.g., Qwen2.5-Max), and the system automatically leverages its VL counterpart for multimodal inputs.
• Enhanced Video Understanding
Support for high-resolution video inputs of up to 500MB , enabling detailed analysis and contextual comprehension of dynamic content.
• Redesigned Mobile Experience
The Qwen Chat web interface has been optimized for mobile devices, featuring a sleek, intuitive design. Plus, enjoy voice-to-text functionality powered by Automatic Speech Recognition (ASR), enabling effortless audio-based interactions. Stay tuned for the upcoming Qwen Chat mobile application.
• Guest Mode Accessibility
Test Qwen Chat’s capabilities without registration. Create an account to unlock personalized features and an enhanced experience.
• Expanded File Upload Capacity
Text file upload limits have been doubled to 20MB , with support for 50MB files and multi-file uploads arriving soon.
Explore Qwen Chat Today!
Visit chat.qwen.ai , try the new features, and share your feedback to help shape the future of Qwen Chat.

Qwen reposted
OpenRouter
@OpenRouter
A lightning-fast R1 alternative has landed: QwQ 32B 🚀
By @Alibaba_Qwen and powered here by @GroqInc!
Free variant available as well 🎁
Qwen
@Alibaba_Qwen
🥝 Yesterday we opensourced QwQ-32B, and we put the model on Qwen2.5-Plus + Thinking in Qwen Chat. Based on your feedback, we make a change and put QwQ-32B on the model list of Qwen Chat, and thus you can directly access it by choosing this model. Enjoy and feel free to give us more feedback about the model as well as the product! 💗
 Qwen
@Alibaba_Qwen
Today, we release QwQ-32B, our new reasoning model with only 32 billion parameters that rivals cutting-edge reasoning model, e.g., DeepSeek-R1.
Blog: qwenlm.github.io/blog/qwq-32b
HF: huggingface.co/Qwen/QwQ-32B
ModelScope: modelscope.cn/models/Qwen/QwQ-32B
Demo: huggingface.co/spaces/Qwen/QwQ-32B-Demo
Qwen Chat: chat.qwen.ai
This time, we investigate recipes for scaling RL and have achieved some impressive results based on our Qwen2.5-32B. We find that RL training con continuously improve the performance especially in math and coding, and we observe that the continous scaling of RL can help a medium-size model achieve competitieve performance against gigantic MoE model. Feel free to chat with our new models and provide us feedback!
 Qwen
@Alibaba_Qwen
Qwen2.5-Plus + Thinking (QwQ) = QwQ-32B . This is how you should use this new model on Qwen Chat!
Qwen
@Alibaba_Qwen
Today, we release QwQ-32B, our new reasoning model with only 32 billion parameters that rivals cutting-edge reasoning model, e.g., DeepSeek-R1.
Blog: qwenlm.github.io/blog/qwq-32b
HF: huggingface.co/Qwen/QwQ-32B
ModelScope: modelscope.cn/models/Qwen/QwQ-32B
Demo: huggingface.co/spaces/Qwen/QwQ-32B-Demo
Qwen Chat: chat.qwen.ai
This time, we investigate recipes for scaling RL and have achieved some impressive results based on our Qwen2.5-32B. We find that RL training con continuously improve the performance especially in math and coding, and we observe that the continous scaling of RL can help a medium-size model achieve competitieve performance against gigantic MoE model. Feel free to chat with our new models and provide us feedback!
Qwen
@Alibaba_Qwen
Today, we release QwQ-32B, our new reasoning model with only 32 billion parameters that rivals cutting-edge reasoning model, e.g., DeepSeek-R1.
Blog: qwenlm.github.io/blog/qwq-32b
HF: huggingface.co/Qwen/QwQ-32B
ModelScope: modelscope.cn/models/Qwen/QwQ-32B
Demo: huggingface.co/spaces/Qwen/QwQ-32B-Demo
Qwen Chat: chat.qwen.ai
This time, we investigate recipes for scaling RL and have achieved some impressive results based on our Qwen2.5-32B. We find that RL training con continuously improve the performance especially in math and coding, and we observe that the continous scaling of RL can help a medium-size model achieve competitieve performance against gigantic MoE model. Feel free to chat with our new models and provide us feedback!
Qwen
@Alibaba_Qwen
🍓🍓🍓🍓🍓

Qwen reposted
Chen Cheng
@cherry_cc12
Qwen Chat solved this problem too!

 Luis Batalha
@luismbat
None of the top 500 contestants in the 2025 Putnam competition fully solved this problem.
Grok 3 (Think) found the solution in ~8 minutes.


Qwen reposted
 Qian Liu
@sivil_taram
Just manually tested QwQ-Max-Preview on AIME2025 problems and the results are... WOW! 🤯 The performance is really impressive - 60% Pass@1 on AIME2025 problems?! 🚀
Problems from: github.com/GAIR-NLP/AIME-Preview
 Qwen
@Alibaba_Qwen
<think>...</think> QwQ-Max-Preview
Qwen Chat: chat.qwen.ai
Blog: qwenlm.github.io/blog/qwq-max-preview/
🤔 Today we release "Thinking (QwQ)" in Qwen Chat, backed by our QwQ-Max-Preview, which is a reasoning model based on Qwen2.5-Max. This model is still for preview. It is highly capable of math understanding, coding, agent, etc. Compared with Qwen2.5-Max, it is much smarter and has much more creatitvity.
Very soon, we are about to release the official version of QwQ-Max, and we will open-weight both QwQ-Max and Qwen2.5-Max under the license of Apache 2.0! Furthermore, we will also provide smaller variants, e.g., QwQ-32B, which can be deployed on local devices. Also, since a great number of users are expecting our APP, we are going to release an Android and iOS APP while we release our official QwQ-Max.
Stay tuned for better things from Qwen!
Qwen reposted
 Naman Jain
@StringChaos
Check out evaluations for QwQ-Max-Preview on LiveCodeBench where it performs on par with o1-medium🚀!!
 Qwen
@Alibaba_Qwen
<think>...</think> QwQ-Max-Preview
Qwen Chat: chat.qwen.ai
Blog: qwenlm.github.io/blog/qwq-max-preview/
🤔 Today we release "Thinking (QwQ)" in Qwen Chat, backed by our QwQ-Max-Preview, which is a reasoning model based on Qwen2.5-Max. This model is still for preview. It is highly capable of math understanding, coding, agent, etc. Compared with Qwen2.5-Max, it is much smarter and has much more creatitvity.
Very soon, we are about to release the official version of QwQ-Max, and we will open-weight both QwQ-Max and Qwen2.5-Max under the license of Apache 2.0! Furthermore, we will also provide smaller variants, e.g., QwQ-32B, which can be deployed on local devices. Also, since a great number of users are expecting our APP, we are going to release an Android and iOS APP while we release our official QwQ-Max.
Stay tuned for better things from Qwen!
Qwen
@Alibaba_Qwen
<think>...</think> QwQ-Max-Preview
Qwen Chat: chat.qwen.ai
Blog: qwenlm.github.io/blog/qwq-max-preview/
🤔 Today we release "Thinking (QwQ)" in Qwen Chat, backed by our QwQ-Max-Preview, which is a reasoning model based on Qwen2.5-Max. This model is still for preview. It is highly capable of math understanding, coding, agent, etc. Compared with Qwen2.5-Max, it is much smarter and has much more creatitvity.
Very soon, we are about to release the official version of QwQ-Max, and we will open-weight both QwQ-Max and Qwen2.5-Max under the license of Apache 2.0! Furthermore, we will also provide smaller variants, e.g., QwQ-32B, which can be deployed on local devices. Also, since a great number of users are expecting our APP, we are going to release an Android and iOS APP while we release our official QwQ-Max.
Stay tuned for better things from Qwen!
Qwen
@Alibaba_Qwen
Creative Writing
Qwen
@Alibaba_Qwen
Search
Qwen
@Alibaba_Qwen
Before we release something tonight, we would like to tell you that now qwen.ai belongs to us, and you can now visit Qwen chat through chat.qwen.ai . See you later!
 Qwen
@Alibaba_Qwen
🚀 We released the tech report of Qwen2.5VL (arxiv.org/abs/2502.13923)! 🎉
It details our model architecture and training details comprehensively.
Qwen2.5-VL-72B achieves complete capability alignment with the pure text benchmark Qwen2.5-72B. 📈 It not only maintains top-notch text understanding and generation capabilities but also has industry-leading visual semantic parsing ability. 💪
This means we now have a true deep integration of visual and textual multimodal! 😍
 Qwen
@Alibaba_Qwen
🎉 In addition to our Qwen2.5-VL report release, we're thrilled to offer AWQ quantized models in 3B, 7B, and 72B sizes. Experience enhanced performance with these optimized versions!
🔗 Get started here:
huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct-AWQ
huggingface.co/Qwen/Qwen2.5-VL-7B-Instruct-AWQ
huggingface.co/Qwen/Qwen2.5-VL72B-Instruct-AWQ
Embrace the power of seamless multimodal integration with AWQ's efficiency. 🚀💪😍
Qwen
@Alibaba_Qwen
Qwen 🤝🏻 Groq
 Groq
@GroqLLC
Our latest model drop(s) = top requests from our dev community 👀
Yep – Qwen-2.5-32b and DeepSeek-r1-distill-qwen-32b are now live on GroqCloud™!
Learn more: groq.com/groqcloud-now-offers-qwen-2-5-32b-and-deepseek-r…
 Qwen
@Alibaba_Qwen
Qwen 🤝🏻 vLLM
vLLM
@vllm_project
v0.7.2 is released! Featuring 🖼️ @Alibaba_Qwen Qwen2.5-VL, 🤗 @huggingface Transformers backend, and several @deepseek_ai performance enhancements.
 Qwen
@Alibaba_Qwen
🔥 Qwen2.5-Max is now ranked #7 in the Chatbot Arena, surpassing DeepSeek V3, o1-mini and Claude-3.5-Sonnet.
It is ranked 1st in math and coding, and 2nd in hard prompts.
👉🏻 Try Qwen2.5-Max here: chat.qwenlm.ai?models=Qwen2.5-Max
Besides building strong foundation models, we are on our way to the reasoning models. Stay tuned!
 Arena.ai
@arena
Alibaba's Qwen-Max is strong across domains. Especially in technical ones (Coding, Math, Hard Prompts)
 Qwen
@Alibaba_Qwen
🚀 Big updates are here on Qwen Chat ! Visit chat.qwenlm.ai to experience the latest improvements:
🔹 New model : Qwen2.5-Plus is now upgraded to qwen-plus-0125-exp, featuring our most advanced post-training techniques. The gap with Qwen2.5-Max has been significantly narrowed for top-tier performance.
🔹 Flexible modes : No more limits switching between modes in a single session! Move freely between web search, normal mode, and artifacts (image & video generation remain separate).
🔹 Unlimited input : Paste texts longer than 10,000 characters, or upload files like txt, pdf, docx, xlsx, pptx, md, and more. Your long inputs are now effortless.
Head over to chat.qwenlm.ai and see what’s possible! 💡
 Qwen
@Alibaba_Qwen
🏆 We're thrilled to see Qwen's repos shining on GitHub's global trending list, ranking #1, #3, #4, #7 and #8!
🔗: github.com/QwenLM
👉: chat.qwenlm.ai
❤️ A huge THANK YOU to all the amazing developers who love and support Qwen. Your passion fuels our journey!
🔥 Stay tuned as we continue to bring you powerful models and exciting cookbooks to unlock endless possibilities.
🚀 Together, let’s build the future of AI!
 Qwen
@Alibaba_Qwen
Two days ago we released Qwen2.5-Max, and today we update the price of its API:
Input tokens: $1.6 / million tokens
Output tokens: $6.4 / million tokens
We hope this change provides you some help and we'd love to hear your feedback about our new model!
👉🏻
Qwen
@Alibaba_Qwen
The burst of DeepSeek V3 has attracted attention from the whole AI community to large-scale MoE models. Concurrently, we have been building Qwen2.5-Max, a large MoE LLM pretrained on massive data and post-trained with curated SFT and RLHF recipes. It achieves competitive performance against the top-tier models, and outcompetes DeepSeek V3 in benchmarks like Arena Hard, LiveBench, LiveCodeBench, GPQA-Diamond.
📖 Blog: qwenlm.github.io/blog/qwen2.5-max/
💬 Qwen Chat: chat.qwenlm.ai (choose Qwen2.5-Max as the model)
⚙️ API: www.alibabacloud.com/help/en/model-studio/getting-started… (check the code snippet in the blog)
💻 HF Demo: huggingface.co/spaces/Qwen/Qwen2.5-Max-Demo
In the future, we not only continue the scaling in pretraining, but also invest in the scaling in RL. We hope that Qwen is able to explore the unknown in the near future! 🔥
💗 Thank you for your support during the past year. See you next year!
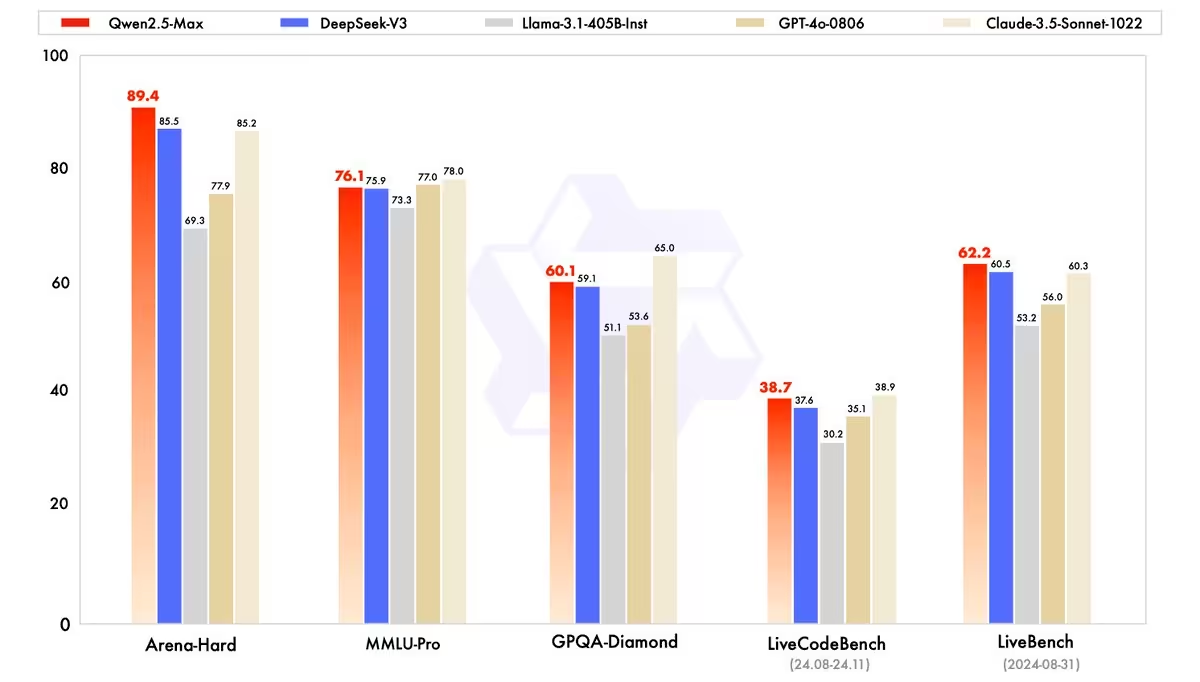 Qwen
@Alibaba_Qwen
Announcing Qwen2.5-VL Cookbooks!
🧑🍳A collection of notebooks showcasing use cases of Qwen2.5-VL, include local model and API. Examples include Compute use, Spatial Understanding, Document Parsing, Mobile Agent, OCR, Universal Recognition, Video Understanding.
🔗Link:github.com/QwenLM/Qwen2.5-VL/tree/main/cookbooks
💬 Qwen Chat: chat.qwenlm.ai (choose Qwen2.5-VL-72B-Instruct as the model)
⚙️ API: www.alibabacloud.com/help/en/model-studio/user-guide/vision/
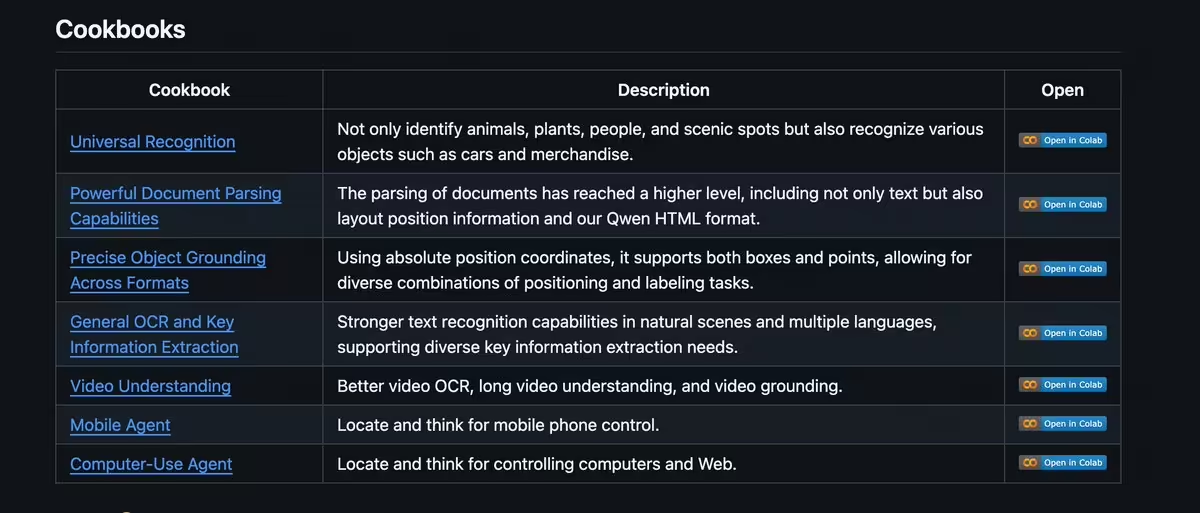 Qwen
@Alibaba_Qwen
6 Universal Recognition
This notebook demonstrates how to use Qwen2.5-VL for universal recognition. It takes an image and a query, and then uses the model to interpret the user's query on the image.
github.com/QwenLM/Qwen2.5-VL/blob/main/cookbooks/universa…
 Qwen
@Alibaba_Qwen
7 Video Understanding
Qwen2.5-VL can comprehend videos of over 1 hour. In this notebook, we delve into the capabilities of the Qwen2.5-VL model for video understanding tasks. Our objective is to showcase how this advanced model can be applied to various video analysis scenarios, ranging from basic OCR to complex event detection and summarization.
github.com/QwenLM/Qwen2.5-VL/blob/main/cookbooks/video_un…

Qwen reposted
AK
@_akhaliq
Qwen2.5-Max just one shotted this
prompt: write a script for three bouncing yellow balls within a sphere, make sure to handle collision detection properly. make the sphere slowly rotate. make sure balls stays within the sphere. implement it in p5.js
developers can start using qwen2.5 max now in ai-gradio
pip install --upgrade "ai-gradio[qwen]"
import gradio as gr
import ai_gradio
gr.load(name='qwen:qwen-max-0125', src=ai_gradio.registry, ).launch()
Qwen
@Alibaba_Qwen
The burst of DeepSeek V3 has attracted attention from the whole AI community to large-scale MoE models. Concurrently, we have been building Qwen2.5-Max, a large MoE LLM pretrained on massive data and post-trained with curated SFT and RLHF recipes. It achieves competitive performance against the top-tier models, and outcompetes DeepSeek V3 in benchmarks like Arena Hard, LiveBench, LiveCodeBench, GPQA-Diamond.
📖 Blog: qwenlm.github.io/blog/qwen2.5-max/
💬 Qwen Chat: chat.qwenlm.ai (choose Qwen2.5-Max as the model)
⚙️ API: www.alibabacloud.com/help/en/model-studio/getting-started… (check the code snippet in the blog)
💻 HF Demo: huggingface.co/spaces/Qwen/Qwen2.5-Max-Demo
In the future, we not only continue the scaling in pretraining, but also invest in the scaling in RL. We hope that Qwen is able to explore the unknown in the near future! 🔥
💗 Thank you for your support during the past year. See you next year!
Qwen
@Alibaba_Qwen
The burst of DeepSeek V3 has attracted attention from the whole AI community to large-scale MoE models. Concurrently, we have been building Qwen2.5-Max, a large MoE LLM pretrained on massive data and post-trained with curated SFT and RLHF recipes. It achieves competitive performance against the top-tier models, and outcompetes DeepSeek V3 in benchmarks like Arena Hard, LiveBench, LiveCodeBench, GPQA-Diamond.
📖 Blog: qwenlm.github.io/blog/qwen2.5-max/
💬 Qwen Chat: chat.qwenlm.ai (choose Qwen2.5-Max as the model)
⚙️ API: www.alibabacloud.com/help/en/model-studio/getting-started… (check the code snippet in the blog)
💻 HF Demo: huggingface.co/spaces/Qwen/Qwen2.5-Max-Demo
In the future, we not only continue the scaling in pretraining, but also invest in the scaling in RL. We hope that Qwen is able to explore the unknown in the near future! 🔥
💗 Thank you for your support during the past year. See you next year!
Qwen
@Alibaba_Qwen
Also, it is available to HF demo, and it is on Any Chat as well!
huggingface.co/spaces/Qwen/Qwen2.5-Max-Demo
Qwen
@Alibaba_Qwen
Welcome to use the API through the service of Alibaba cloud. Using the API is as easy as using any other OpenAI-API compatible service.
 Qwen
@Alibaba_Qwen
🎉 恭喜发财🧧🐍 As we welcome the Chinese New Year, we're thrilled to announce the launch of Qwen2.5-VL , our latest flagship vision-language model! 🚀
💗 Qwen Chat: chat.qwenlm.ai
📖 Blog: qwenlm.github.io/blog/qwen2.5-vl/
🤗 Hugging Face: huggingface.co/collections/Qwen/qwen25-vl-6795ffac22b334a…
🤖 ModelScope: modelscope.cn/collections/Qwen25-VL-58fbb5d31f1d47
🌟 Key Highlights:
* Visual Understanding : From flowers to complex charts, Qwen2.5-VL sees it all!
* Agentic Capabilities : It’s a visual agent that can reason and interact with tools like computers & phones.
* Long Video Comprehension : Captures events in videos over 1 hour long! ⏳🎥
* Precise Localization : Generates bounding boxes & JSON outputs for accurate object detection.
* Structured Data Outputs : Perfect for finance & commerce, handling invoices, forms & more! 💼📊
Try Qwen2.5-VL now at Qwen Chat or explore models on Hugging Face & ModelScope . 🌐
Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
 Qwen
@Alibaba_Qwen
We're leveling up the game with our latest open-source models, Qwen2.5-1M ! 💥 Now supporting a 1 MILLION TOKEN CONTEXT LENGTH 🔥
Here's what’s new:
1️⃣ Open Models: Meet Qwen2.5-7B-Instruct-1M & Qwen2.5-14B-Instruct-1M —our first-ever models handling 1M-token contexts! 🤯
2️⃣ Lightning-Fast Inference Framework: We’ve fully open-sourced our inference framework based on vLLM , integrated with sparse attention methods. Experience 3x to 7x faster processing for 1M-token inputs! ⚡⚡
3️⃣ Tech Deep Dive: Check out our detailed Technical Report for all the juicy details behind the Qwen2.5-1M series! 📊
📖 Technical Report: qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2.5-1M/Qwen2_…
📄 Blog: qwenlm.github.io/blog/qwen2.5-1m/
Experience Qwen2.5-1M live:
👉 Play with Qwen2.5-Turbo supporting 1M tokens in Qwen Chat (chat.qwenlm.ai)
👉 Try it on Huggingface (huggingface.co/collections/Qwen/qwen25-1m-679325716327ec0…)
👉 Or head over to Modelscope (modelscope.cn/collections/Qwen25-1M-d6cf9fd33f0a40)
 Qwen
@Alibaba_Qwen
👉🏻 chat.qwenlm.ai
🎉🚀 Qwen is back with something new! We've just rolled out Qwen Chat v0.2 after two weeks of hard work, and it's packed with awesome new features! 🌟 Now you can explore web search , create stunning videos, and generate amazing images – all in one place! ✨
Combine that with our existing powers like artifacts, image understanding, and document comprehension, and you've got the ultimate tool for both work and play! 💼📱
Ready to supercharge your daily routine? Let’s make life easier and more fun together! 🎮🔍🎨
Oh, this is not an end, we still have a lot for the Chinese spring festival! Stay tuned!
Qwen
@Alibaba_Qwen
🚀 New Approach to Training MoE Models! We’ve made a key change: switching from micro-batches to global-batches for better load balancing. This simple tweak lets experts specialize more effectively, leading to:
✅ Improved model performance
✅ Better handling of real-world tasks
✅ Significant gains in large-scale models
Our experiments show impressive results – making your AI projects even stronger!
📚Dive into the details and see how this can benefit your work.
blog: qwenlm.github.io/blog/global-load-balance/
paper: hf.co/papers/2501.11873
 Qwen
@Alibaba_Qwen
🚀 Exciting Advances in Process Reward Models (PRMs)! 🚀
Our latest research tackles the challenges of data annotation and evaluation in PRMs for better mathematical reasoning in LLMs. We show that MC estimation-based methods often fall short compared to LLM-as-a-judge and human annotations.
🔍 Key Findings:
1. MC estimation can lead to inaccurate step verification.
2. BoN evaluation strategies may inflate scores due to flawed processes.
3. Our consensus filtering mechanism integrates MC with LLM-as-a-judge, improving both performance and data efficiency.
📚 Blog: qwenlm.github.io/blog/qwen2.5-math-prm/
💻 Hugging Face: huggingface.co/Qwen/Qwen2.5-Math-PRM-72B
📊 ModelScope: modelscope.cn/models/Qwen/Qwen2.5-Math-PRM-72B
 Qwen
@Alibaba_Qwen
🚀 两天前,我们宣布推出了 Qwen Chat(chat.qwenlm.ai)——您与Qwen模型互动的首选 Web 界面!🌟 我们很高兴地通知您,Qwen Chat现在支持中文了!
💬 您可以轻松地与我们的旗舰模型 Qwen2.5-Plus 进行对话,探索具备视觉语言能力的 Qwen2-VL-Max,深入研究推理模型如 QwQ 和 QVQ,还可以使用编程专家 Qwen2.5-Coder-32B-Instruct 编写代码等。
✨ 主要功能:
在一个界面上选择并比较多个模型
上传文档并根据其内容获取答案
支持HTML预览模式
上传图片以理解视觉内容
🌟 即将推出:网页搜索、图像生成、语音模式等更多功能!
🔗 准备好体验未来了吗?立即开始与 Qwen 聊天吧 💬 欢迎随时向我们发送您的反馈和建议!
Qwen
@Alibaba_Qwen
🚀 منذ يومين أعلنا عن إطلاق واجهة الدردشة الجديدة كيوون (chat.qwenlm.ai) – وجهتك المفضلة للتفاعل مع نماذج كيوون عبر الويب! 🌟 يسعدنا أن نبلغكم بأن كيوون شات تدعم اللغة العربية الآن!
💬 تواصل بسهولة مع نموذجنا الرائد كيوون2.5-بلس، واستكشف قدرات النص والصورة مع كيوون2-في-إل-ماكس، وغوص في نماذج الاستدلال مثل كيووكيو وكفيكفي، وقم بالبرمجة مع خبير البرمجة كيوون2.5-كودر-32بي-إنستركت، وغيرها.
✨ الميزات الرئيسية:
اختر وقارن بين عدة نماذج في واجهة واحدة
حمل الوثائق واحصل على إجابات بناءً عليها
وضع المعاينة مع دعم HTML
حمل الصور لفهم بصري
🌟 قريبًا: البحث عبر الويب، إنشاء الصور، وضع الصوت، والمزيد!
🔗 هل أنت مستعد لتجربة المستقبل؟ ابدأ الدردشة مع كيوون اليوم 💬 لا تتردد في إرسال ملاحظاتك واقتراحاتك!
Qwen
@Alibaba_Qwen
🚀 두 날 전에 우리는 Qwen Chat (chat.qwenlm.ai)의 출시를 발표했습니다 – 이제 Qwen 모델과 상호작용할 수 있는 새로운 웹 UI가 여러분을 찾아갑니다! 🌟 Qwen Chat이 이제 한국어를 지원하게 되어 기쁩니다!
💬 우리의 대표 모델 Qwen2.5-Plus와 채팅하고, Qwen2-VL-Max로 비전-언어 능력을 탐색하며, QwQ와 QVQ 같은 추론 모델에 몰입하고, 코딩 전문가 Qwen2.5-Coder-32B-Instruct로 코드를 작성하세요.
✨ 주요 기능:
* 하나의 인터페이스에서 여러 모델 선택 및 비교
* 문서 업로드 및 해당 내용에 기반한 답변 제공
* HTML 지원 미리보기 모드
* 이미지 업로드를 통한 시각적 이해
🌟 곧 출시 예정: 웹 검색, 이미지 생성, 음성 모드 등 더 많은 기능들이 추가될 예정입니다!
🔗 미래를 경험해 보시겠어요? 지금 Qwen과 함께 채팅을 시작하세요 💬 피드백과 제안 사항을 언제든지 보내주시기 바랍니다!
Qwen
@Alibaba_Qwen
🚀 2日前、私たちは新しいQwen Chat(chat.qwenlm.ai)のローンチを発表しました!これは、Qwenモデルと対話するための新しいWeb UIです!🌟 Qwen Chatが日本語に対応したことをお知らせいたします!
💬 当社のフラッグシップモデルであるQwen2.5-Plusでチャットを楽しんだり、Qwen2-VL-Maxで視覚言語能力を探索したり、QwQやQVQのような推論モデルに潜入したり、コーディングエキスパートであるQwen2.5-Coder-32B-Instructでコードを書いたりできます。
✨ 主な特徴:
* 1つのインターフェースで複数のモデルを選択・比較
* ドキュメントをアップロードし、それらに基づいて回答を得る
* HTMLサポート付きプレビューモード
* 画像をアップロードして視覚的理解を得る
🌟 今後追加予定:ウェブ検索、画像生成、音声モードなど!
🔗 未来を体験する準備はできていますか?今日からQwenとのチャットを始めてください 💬 フィードバックやご意見をお気軽にお寄せください!
Qwen
@Alibaba_Qwen
🚀 Due giorni fa abbiamo annunciato il lancio di Qwen Chat (chat.qwenlm.ai) – la nuova interfaccia web per interagire con i modelli Qwen! 🌟 Siamo felici di informarvi che Qwen Chat supporta ora l'italiano!
💬 Chiacchierate in modo semplice con il nostro modello principale Qwen2.5-Plus, esplorate le capacità di visione-linguaggio con Qwen2-VL-Max e immergetevi nei modelli di ragionamento come QwQ e QVQ, scrivete codice con l'esperto di coding Qwen2.5-Coder-32B-Instruct, ecc.
✨ Caratteristiche principali:
* Scegliete e confrontate più modelli in un'unica interfaccia
* Caricate documenti e ottenete risposte basate su di essi
* Modalità anteprima con supporto HTML
* Caricate immagini per una comprensione visiva
🌟 Prossimamente: ricerca web, generazione di immagini, modalità vocale e altro ancora!
🔗 Pronto a sperimentare il futuro? Inizia a chiacchierare con Qwen oggi 💬 Sentitevi liberi di inviarci i vostri feedback e suggerimenti!
Qwen
@Alibaba_Qwen
🚀 Vor zwei Tagen haben wir die Einführung von Qwen Chat ( chat.qwenlm.ai ) angekündigt – Ihre neue Web-Oberfläche zum Interagieren mit den Qwen-Modellen! 🌟 Wir freuen uns, Ihnen mitteilen zu können, dass Qwen Chat nun auch Deutsch unterstützt!
💬 Plaudern Sie mühelos mit unserem Flaggschiffmodell Qwen2.5-Plus, erkunden Sie visuelle Sprachfähigkeiten mit Qwen2-VL-Max und tauchen Sie in logische Modelle wie QwQ und QVQ ein, programmieren Sie mit dem Coding-Experten Qwen2.5-Coder-32B-Instruct usw.
✨ Hauptfunktionen:
* Wählen und vergleichen Sie mehrere Modelle in einer Oberfläche
* Laden Sie Dokumente hoch und erhalten Sie Antworten darauf
* Vorschau-Modus mit HTML-Unterstützung
* Laden Sie Bilder hoch für ein visuelles Verständnis
🌟 Kommt bald: Web-Suche, Bildgenerierung, Sprachmodus und mehr!
🔗 Bereit, die Zukunft zu erleben? Beginnen Sie noch heute, mit Qwen zu chatten 💬 Zögern Sie nicht, uns Ihr Feedback und Ihre Vorschläge zu senden!
Qwen
@Alibaba_Qwen
🚀 Il y a deux jours, nous avons annoncé le lancement de Qwen Chat (chat.qwenlm.ai) – votre nouvelle interface Web pour interagir avec les modèles Qwen ! 🌟 Nous sommes ravis de vous informer que Qwen Chat supporte maintenant le français !
💬 Discutez facilement avec notre modèle phare Qwen2.5-Plus, explorez les capacités vision-langage avec Qwen2-VL-Max, et plongez dans des modèles de raisonnement comme QwQ et QVQ, codez avec l'expert en codage Qwen2.5-Coder-32B-Instruct, etc.
✨ Fonctionnalités clés :
* Choisissez et comparez plusieurs modèles dans une seule interface
* Téléchargez des documents et obtenez des réponses basées sur ceux-ci
* Mode aperçu avec support HTML
* Téléchargez des images pour une compréhension visuelle
🌟 Prochainement : Recherche web, génération d'images, mode vocal et plus encore !
🔗 Prêt à expérimenter le futur ? Commencez à discuter avec Qwen aujourd'hui 💬 N'hésitez pas à nous envoyer vos commentaires et suggestions !
Qwen
@Alibaba_Qwen
🚀 Há dois dias, anunciamos o lançamento do Qwen Chat ( chat.qwenlm.ai ) – sua nova interface web para interagir com os modelos Qwen! 🌟 Estamos felizes em informar que o Qwen Chat agora suporta português!
💬 Converse facilmente com nosso modelo principal, o Qwen2.5-Plus, explore as capacidades de visão e linguagem com o Qwen2-VL-Max e mergulhe em modelos de raciocínio como o QwQ e QVQ. Além disso, programe com o especialista em codificação, Qwen2.5-Coder-32B-Instruct, entre outros.
✨ Principais Recursos:
* Escolha e compare múltiplos modelos em uma única interface
* Faça upload de documentos e obtenha respostas baseadas neles
* Modo de visualização com suporte a HTML
* Faça upload de imagens para compreensão visual
🌟 Em breve: busca na web, geração de imagens, modo de voz e muito mais!
🔗 Pronto para experimentar o futuro? Comece a conversar com o Qwen hoje 💬 Sinta-se à vontade para nos enviar seu feedback e sugestões!
Qwen
@Alibaba_Qwen
🚀 Hace dos días anunciamos el lanzamiento de Qwen Chat ( chat.qwenlm.ai ) – ¡tu nueva interfaz web para interactuar con los modelos Qwen! 🌟 Nos complace informarte que Qwen Chat ahora soporta el español.
💬 Chatea fácilmente con nuestro modelo insignia Qwen2.5-Plus, explora las capacidades de visión-lenguaje con Qwen2-VL-Max, y sumérgete en modelos de razonamiento como QwQ y QVQ, codifica con el experto en programación Qwen2.5-Coder-32B-Instruct, etc.
✨ Características Clave:
* Elige y compara múltiples modelos en una sola interfaz
* Sube documentos y obtén respuestas basadas en ellos
* Modo de vista previa con soporte para HTML
* Sube imágenes para comprensión visual
🌟 Próximamente: Búsqueda web, generación de imágenes, modo de voz y más!
🔗 ¿Listo para experimentar el futuro? Comienza a chatear con Qwen hoy 💬 No dudes en enviarnos tus comentarios y sugerencias.
Qwen
@Alibaba_Qwen
🚀 Exciting News! We're thrilled to announce the launch of Qwen Chat ( chat.qwenlm.ai ) – your new go-to Web UI for interacting with Qwen models! 🌟
💬 Chat effortlessly with our flagship model Qwen2.5-Plus , explore vision-language capabilities with Qwen2-VL-Max , and dive into reasoning models like QwQ and QVQ, code with coding expert Qwen2.5-Coder-32B-Instruct, etc.
✨ Key Features:
* Choose & compare multiple models in one interface
* Upload documents & get answers based on them
* Preview mode with HTML support
* Upload images for visual understanding
🌟 Coming Soon: Web search, image generation, voice mode, and more!
🔗 Ready to experience the future? Start to chat with Qwen today 💬 Feel free to send us your feedback and suggestions!
Qwen
@Alibaba_Qwen
Qwen Chat is built on Open WebUI. Huge thanks to the amazing @OpenWebUI open-source team for bringing such great contributions to the community!
Qwen
@Alibaba_Qwen
new year, new qwen
Qwen
@Alibaba_Qwen
you can just do things
Qwen
@Alibaba_Qwen
what would you like qwen to build/fix in 2025 :)
Qwen
@Alibaba_Qwen
🎄Happy holidays and we wish you enjoy this year. Before moving to 2025, Qwen has the last gift for you, which is QVQ!
🎉 This may be the first open-weight model for visual reasoning. It is called QVQ, where V stands for vision. It just reads an image and an instruction, starts thinking, reflects while it should, keeps reasoning, and finally it generates its prediction with confidence! However, it is still experimental and this preview version still suffers from a number of limitations (mentioned in our blog), which you should pay attention to while using the model. Feel free to refer to the following links for more information:
* Blog: qwenlm.github.io/blog/qvq-72b-preview
* HF: huggingface.co/collections/Qwen/qvq-676448c820912236342b9888
* ModelScope: modelscope.cn/models/Qwen/QVQ-72B-Preview
* Kaggle: www.kaggle.com/models/qwen-lm/qvq-72b-preview
🚀 It achieves impressive performance in benchmark evaluation, e.g., MMMU, MathVista, etc. But what is more interesting is that it is exciting to see the AI model behaves differently by thinking deeply and reasoning step by step instead of directly providing answers. Yet, it is still a model for preview. It is unstable, it might fall into repetition, it sometimes doesn't follow instruction, etc. We invite you to try the new interesting model and enjoy playing with it! Feel free to shoot us feedback!
 Qwen
@Alibaba_Qwen
An example for visual math problem solving.
Qwen
@Alibaba_Qwen
Demo is here!
huggingface.co/spaces/Qwen/QVQ-72B-preview
Qwen
@Alibaba_Qwen
Qwen2.5 Technical Report
hf.co/papers/2412.15115

Qwen reposted
 Subhash Peshwa
@Subhash_Peshwa
2024 State of LLMs for Text2SQL Tasks 🏆- Full Report
🥇 Overall Performance: @GoogleDeepMind Gemini-Exp-1206
🥇 Open Source Model: @Alibaba_Qwen 2.5-Coder:32b (Beats Sonnet 3.5 and on par with GPT-4o!)
Disappointing performance by GPT-4o and 3.5 Sonnet on this task. 🧵

Qwen reposted
Subhash Peshwa
@Subhash_Peshwa
That's Qwen 2.5 coder 14b!
Qwen reposted
Qwen reposted
 SambaNova
@SambaNovaAI
📣 @Alibaba_Qwen 2.5-32B-Coder now available!
✅ Access the best open-source models
✅ 5X faster than any #gpu provider
We've partnered with @continuedev to make it easier for #devs to integrate these models & experience fast #inference response times.
See how: 👇
Qwen reposted
Artificial Analysis
@ArtificialAnlys
Benchmarks of providers of Qwen2.5, a leading open-source model family 📊
@alibaba_cloud's Qwen2.5 family of models includes Qwen2.5 72B, Qwen2.5 Coder 32B and a range of smaller models including 1.5B and 0.5B models for ‘edge’ use-cases.
Qwen2.5 72B, the flagship model, is competitive in intelligence evaluations with frontier models including Llama 3.3 70B, GPT-4o and Mistral Large 2.
Despite its smaller size, Qwen 2.5 Coder 32B achieves comparable performance in coding benchmarks like HumanEval to frontier models. Its size and capabilities position it well to support developers with fast code generation and emerging use-cases such as coding agents that require multi-step inference to autonomously develop features and applications.
Amongst providers, @SambaNovaAI is the clear leader in output speed, delivering ~225 output tokens/s on Qwen2.5 72B, and 566 output tokens/s on Qwen 2.5 Coder 32B in our coding workload benchmark.
@nebiusai , @DeepInfra , @hyperbolic_labs and @togethercompute are also offering the model(s) and all at prices significantly cheaper than comparable proprietary models such as GPT-4o.
Links to our live benchmarks of Qwen2.5 on Artificial Analysis below 👇

Qwen reposted
Poe
@poe_platform
QwQ-32B-Preview is now available on Poe!
This chain-of-thought based reasoning model from Alibaba is useful for advanced math, coding, and logical reasoning, achieving top-tier scores across various problem-solving benchmarks that rival those of other reasoning models. (1/2)

Qwen reposted
 adi
@adonis_singh
running qwq 4bit on my macbook air
infinite offline intelligence
Thanks you @Alibaba_Qwen
Qwen reposted
 CAMEL-AI.org
@CamelAIOrg
🔥 Building an AI-powered Discord bot with Agentic RAG has never been easier!
Learn how 🐫 @CamelAIOrg, 🔥 @firecrawl & 👨🚀 @qdrant_engine work together to create the ultimate customer service @discord bot powered by @Alibaba_Qwen or @MistralAI.
From web scraping to qdrant's vector database - we've got your community covered with this bot!
👇 Full architecture breakdown in the figure below.
🔗 Check out the colab: colab.research.google.com/drive/1C0ew2B3gn3BGJs9PMfa79CUG…

Qwen reposted
 Abdullah Adeeb
@AbdullahAdeebx
Just tested QwQ 32B preview by @Alibaba_Qwen—an open-source AI model focused on advanced AI reasoning!
It’s a challenger to @OpenAI's o1-Preview, excelling in math and coding.
However, as a preview model, it has quirks like language mixing and reasoning loops. insights below!
Qwen reposted
Paul Couvert
@itsPaulAi
Closed AI models are no longer dominant.
You can use free and open source alternatives for all of them:
Text generation
GPT-4o → Nvidia 3.1 Nemotron
Coding
Sonnet 3.5 → Qwen 2.5 Coder
Reasoning
o1-preview → QwQ
Multimodal tasks
Gemini 1.5 Pro → Pixtral
Access them 🧵

Qwen reposted
Wolfram Ravenwolf
@WolframRvnwlf
After more than 59 runs of the MMLU-Pro CS benchmark across 25 LLMs with over 70 hours runtime, @Alibaba_Qwen's QwQ-32B-Preview is THE best local model! 🏆
Still working on the detailed analysis, but here's the main graph that accurately depicts the quality of all tested models:
 Wolfram Ravenwolf
@WolframRvnwlf
Benchmark Progress Update:
I've completed ANOTHER round to ensure accuracy - yes, I have now run ALL the benchmarks TWICE! While still compiling the results for a blog post, here's a sneak peek featuring detailed metrics and Top 10 rankings. Stay tuned for the complete analysis.
 Qwen
@Alibaba_Qwen
Qwen2.5 ❤️ Sailor2
Qian Liu
@sivil_taram
🌟 Two years after ChatGPT's release, while the AI community focuses on advanced reasoning capabilities in English with models like o1, multilingual development deserves more attention!
🚀 We proudly present Sailor2, a community-driven project delivering state-of-the-art multilingual language models in three scales - 0.8B, 8B, and 20B parameters. Released under the Apache 2.0 license, these models specialize in South-East Asian (SEA) languages, making advanced models more accessible across the region. 🌏
✈️ Building upon the foundation of Qwen2.5 @Alibaba_Qwen , Sailor2 is continually pre-trained over 500B high-quality tokens to support 15 languages, including English, Chinese, Burmese 🇲🇲, Cebuano🇵🇭, Ilocano🇵🇭, Indonesian🇮🇩, Javanese🇮🇩, Khmer🇰🇭, Lao🇱🇸, Malay🇲🇾, Sundanese🇮🇩, Tagalog🇵🇭, Thai🇹🇭, Vietnamese🇻🇳, Waray🇵🇭.
During development, we employ a range of advanced technologies to ensure top-tier performance and efficiency:
1️⃣ model expansion 📈
2️⃣ optimized data mixing strategies 🔄
3️⃣ multi-stage pre-training protocols 🔬
4️⃣ advanced multilingual post-training⚡
Despite the compact 20B parameters, our flagship 20B base model achieves performance that matches or surpasses significantly larger counterparts on different SEA languages, including Qwen2.5-32B, Gemma2-27B, Llama3.1-70B, and Aya-Expanse-32B 🎯. Our 20B chat model can achieve a 50-50 win rate with GPT-4o on most SEA languages using GPT-4o as judger!
📚Blog: sea-sailor.github.io/blog/sailor2
🤗Model: huggingface.co/collections/sail/sailor2-language-models-6…
💬Demo: huggingface.co/spaces/sail/Sailor2-20B-Chat
🌍Sailor2 Community: huggingface.co/sailor2

Qwen reposted
 Philipp Schmid
@_philschmid
Perfect for re:Invent! Want to deploy @Alibaba_Qwen QwQ-32B, the best open reasoning model that rivals @OpenAI o1 and @AnthropicAI Claude Sonnet 3.5? 🤔 Excited to share a new guide on deploying Qwen QwQ 32B on @awscloud SageMaker using the @huggingface LLM Deep Learning Container. 👀
QwQ-32B-Preview achieves 90.6% on MATH-500, matching OpenAI o1-mini and outperforming Claude 3.5 and is available under Apache 2.0. 🤯

Qwen reposted
 Shubham Saboo
@Saboo_Shubham_
Qwen QwQ-32B can reason as good as OpenAI o1 mini (in most of the cases).
Best part? You can run this locally with an UI in less than 10 lines of Python Code (100% free and without internet).
Qwen reposted
 merve
@mervenoyann
Last week we were blessed with open-source models! A recap 💝
🖼️ Multimodal
> At @huggingface we released SmolVLM, a performant and efficient smol vision language model 💗
> Show Lab released ShowUI-2B: new vision-language-action model to build GUI/web automation agents 🤖
> Rhymes AI has released the base model of Aria: Aria-Base-64K and Aria-Base-8K with their respective context length
> ViDoRe team released ColSmolVLM: A new ColPali-like retrieval model based on SmolVLM
> Dataset: Llava-CoT-o1-Instruct: new dataset labelled using Llava-CoT multimodal reasoning model📖
> Dataset: LLaVA-CoT-100k dataset used to train Llava-CoT released by creators of Llava-CoT 📕
💬 LLMs
> @Alibaba_Qwen team released QwQ-32B-Preview, state-of-the-art open-source reasoning model, broke the internet 🔥
> AliBaba has released Marco-o1, a new open-source reasoning model 💥
> @NVIDIAAI released Hymba 1.5B Base and Instruct, the new state-of-the-art SLMs with hybrid architecture (Mamba + transformer)
⏯️ Image/Video Generation
> Qwen2VL-Flux: new image generation model based on Qwen2VL image encoder, T5 and Flux for generation
> Lightricks released LTX-Video, a new DiT-based video generation model that can generate 24 FPS videos at 768x512 res
> Dataset: Image Preferences is a new image generation preference dataset made with DIBT community effort of @argilla_io
Audio
> OuteAI released OuteTTS-0.2-500M new multilingual text-to-speech model based on Qwen-2.5-0.5B trained on 5B audio prompt tokens

Qwen reposted
 Alina Lozovskaya
@ailozovskaya
🚀 QwQ model has joined the 🤗 Open LLM Leaderboard!
QwQ-32B-Preview, an experimental AI reasoning model developed by the Qwen Team, showcases promising analytical abilities but faces limitations. These include language mixing and code-switching, recursive reasoning loops, safety concerns, performance and benchmark deficiencies, and specific architectural and parameter details
✨ Highlights
• Strong average score within Qwen models (30.44 vs mean 21.61)
• Noticeable performance on BBH (53.39) and MMLU-PRO (51.98)
• Demonstrates strong MATH skills when evaluated using a chat template
🔒 License
Released under Apache 2.0, allowing both research and commercial use
What a cool experiment @Alibaba_Qwen! 👏
🏆 Open LLM Leaderboard: huggingface.co/spaces/open-llm-leaderboard/open_llm_leade…

Qwen reposted
 Caleb
@calebfahlgren
The amazing, new Qwen2.5-Coder 32B model can now write SQL for any @huggingface dataset ✨
Qwen reposted
 Vaibhav (VB) Srivastav
@reach_vb
you can just do things - ask AI to create your SQL queries and execute them right in your browser! 🔥
let your creativity guide you - powered by @Alibaba_Qwen 2.5 coder 32b ⚡
available on all 254,746 public datasets on the hub!
go check it out today! 🤗
Qwen reposted
 Aritra 🤗
@ariG23498
The @Alibaba_Qwen team is doing so much for the community by keeping research open and constructive.
They listen to the community and put efforts in building competitive models.
I was intrigued by their latest `Qwen/QwQ-32B-Preview` model and wanted to play with it.
[1/N]
Qwen reposted
 Whired
@Whi__red
MLX + QwQ in @OpenWebUI (via @LMStudioAI endpoint)
It's fast, it's good, it passes all vibe checks.
Claude is sweating.
@Alibaba_Qwen @Prince_Canuma @awnihannun @reach_vb @huybery

Qwen reposted
Wolfram Ravenwolf
@WolframRvnwlf
WTF! What sorcery is this, @Alibaba_Qwen? I kept benchmarking - and not only does the 4.25-bit version get the same score as the 8-bit (what?), using Qwen2.5-Coder-0.5B as a draft model for speculative decoding sped it up from 27 to 42 tk/s AND it scored even higher (whaaat?)! 🤯
 Wolfram Ravenwolf
@WolframRvnwlf
Finished my @Alibaba_Qwen QwQ-32B-Preview benchmark (MMLU-Pro, CS category) just now – remember this is a 32B model at 8-bit EXL2 quantization that's overtaking Llama 405B and 70B, Mistral 123B, and even ChatGPT/GPT-4o in these tests!

Qwen reposted
 clem 🤗
@ClementDelangue
QwQ is #1 trending on Hugging Face!

Qwen reposted
Wolfram Ravenwolf
@WolframRvnwlf
Finished my @Alibaba_Qwen QwQ-32B-Preview benchmark (MMLU-Pro, CS category) just now – remember this is a 32B model at 8-bit EXL2 quantization that's overtaking Llama 405B and 70B, Mistral 123B, and even ChatGPT/GPT-4o in these tests!
Qwen
@Alibaba_Qwen
🚀Now it is the time, Nov. 11 10:24! The perfect time for our best coder model ever! Qwen2.5-Coder-32B-Instruct!
Wait wait... it's more than a big coder! It is a family of coder models! Besides the 32B coder, we have coders of 0.5B / 1.5B / 3B / 7B / 14B! As usual, we not only share base and instruct models, we also provide quantized models in the format of GPTQ, AWQ, as well as the popular GGUF! 💖
👉🏻Blog: qwenlm.github.io/blog/qwen2.5-coder-family/
👉🏻Tech Report: arxiv.org/abs/2409.12186
👉🏻Hugging Face: huggingface.co/collections/Qwen/qwen25-coder-66eaa22e6f99…
👉🏻ModelScope: modelscope.cn/collections/Qwen25-Coder-9d375446e8f5814a
👉🏻Kaggle: www.kaggle.com/models/qwen-lm/qwen2.5-coder
👉🏻GitHub: github.com/QwenLM/Qwen2.5-Coder
👉🏻Demo [chat]: huggingface.co/spaces/Qwen/Qwen2.5-Coder-demo
👉🏻 Demo [Artifacts]: huggingface.co/spaces/Qwen/Qwen2.5-Coder-Artifacts
The flagship model, Qwen2.5-Coder-32B-Instruct, reaches top-tier performance, highly competitive (or even surpassing) proprietary models like GPT-4o, in a series of benchmark evaluation, including HumanEval, MBPP, LiveCodeBench, BigCodeBench, McEval, Aider, etc. It reaches 92.7 in HumanEval, 90.2 in MBPP, 31.4 in LiveCodeBench, 73.7 in Aider, 85.1 in Spider, and 68.9 in CodeArena!

 Vals AI


 jtydhr88


 Hassan
