Tonight the Postgres security team released minor version updates patching 52 CVEs in Postgres.
Neon and Databricks customers were running patched versions within 30 minutes thanks to Lakebase architecture and our Postgres engineering team.
Always-on computes will get the updates on next restart. neon.com/docs/postgresql/postgres-version-support
Reynold Xin
Reynold Xin is a computer scientist, engineer, and entrepreneur specializing in big data, distributed systems, and cloud computing. He is a co-founder and Chief Architect of Databricks. He is best known for his work on Apache Spark, a leading open-source Big Data project. He was designer and lead developer of the GraphX, Project Tungsten, and Structured Streaming components and he co-designed DataFrames, all of which are part of the core Apache Spark distribution; he also served as the release manager for Spark's 2.0 release. He was the top cited scholar in the field of databases, according to the 2021 AI 2000 records. More on Wikipedia
-
Reynold Xin reposted
Neon
@neondatabase
-
Reynold Xin reposted
Dylan Field
@zoink
🤔
Barry McCardel
@barrald
MCP for thee, but not for me…
-
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Day 0 launch of Claude Fable 5.2 on @databricks! You can just get the tokens from Unity Gateway on Databricks.
Databricks
@databricks
Claude Fable 5.2 lands on Databricks on Day 0.
Built for coding, finance and science, it sets a new high on our OfficeQA Pro v2 benchmark.
Run long-running agents on governed data, with Unity Gateway controlling calls across 70+ models.
Claude
@claudeai
Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.This media couldn't be displayed. See it on the original post. -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
I don't think we should fight. The two companies are complementary. Since you're not doing this AI stuff, I really think Snowflake should consider getting its AI tokens through Databricks. You can get both cheap OSS models as well as frontier (OAI/Ant/Gemini/Grok) models from our platform. It all goes through Unity Gateway which has Smart Routing, Budgets, and Access Control. You can even use Omnigent with any harness, including CoCo. Most of our customers used this to reduce token spend ~30% last few months while token count went up. Genie lets you then track, control, manage that spend, all your financials, marketing, etc. Quick POC?
-
Reynold Xin reposted
Hyperbolic
@hyperbolic_labs
We’ve raised an oversubscribed $30M Series A1 led by @walden_catalyst to build the Global Compute Grid.
We’re turning fragmented GPU capacity into one unified platform where AI teams can access, manage, sell, and orchestrate compute.
Our mission: make the world’s compute unified, productive and liquid.This media couldn't be displayed. See it on the original post. -
Reynold Xin
@rxin
No wonder Apple is a 5 trillion dollar company.
UPS delivery guy: "Are you waiting by the door for this?"
me: "Yes!"
him: "I never run into people when I deliver, but on iPhone release date, everybody is home waiting." -
Reynold Xin reposted
Neon
@neondatabase
Postgres 19 is late. @robertmhaas, one of the Postgres committers on our team, explains why: LLMs are finding bugs faster than they can be fixed, including in older releases, and that extra work eats into v19 review time
neon.com/blog/postgres-19-is-late-and-its-ais-fault -
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Can a single database architecture satisfy both vibe-coded and large scale enterprise apps?
The same approach makes small database ultra cheap to run and branch can also make a large one faster and easier to operate. We call this architecture Lakebase. -
Reynold Xin reposted
Sam Willis
@samwillis
Any SQL query, reactively kept up to date on front end.
And is so so simple to use, even and agent can do it!
--
Six years ago I was building an app, and thought "wouldn't it be so much easer if we could just subscribe to a query on the front end".
That started my journey through Local First, lead to joining @ElectricSQL, where we built multiple Sync Engines, PGlite and @tan_stack DB.
We finally achieved that goal with @neondatabase Realtime.
Perfect thing for a side project, give it a go!
neon.com/blog/neon-now-has-realtime -
Reynold Xin reposted
Raunak
@capsraunak
neon gives all these apart from just postgres database now
-
Reynold Xin
@rxin
Built by the Electric team (who also did pglite, i.e. Postgres on WASM), Neon Realtime is an incremental query engine to make it dramatically easier to build apps that sync data in realtime.
It leverages the Lakebase architecture's separation of storage and compute to run on a separate compute instance. This avoids overwhelming the primary write Postgres instance and pushes the write operations incrementally to all the subscribers.
Check it out. You can now build complex realtime sync apps in just a few lines of code. This is a great example of how hardcore database technologies can make the app developers' lives much simpler.
Neon
@neondatabase
Neon now has realtime, built by the team behind Electric. Turn any SQL query into a live query, joins and aggregates included. All inside Postgres, and ready for agents.
It’s in public beta and available in all Neon plans. Give it a try and tell us what you think! -
Reynold Xin
@rxin
❤️
Almog Gavra
@almoggavra
Yeah this happened. You've been listening to me tweet public love letters to object storage for a while, so it should come as no surprise that we're joining the best object-native product around: Databricks Lakebase.
Apurva Mehta
@apurva1618
I’m excited to announce that Responsive has been acquired by Databricks to accelerate the development of Lakebase and Neon!
We couldn't be more excited to join the Lakebase team. We've long admired their technical vision, and the more we got to know them, the more impressed we became by their ambition, execution, and momentum. It feels like a natural home for us.
I want to thank Responsive’s customers, investors, and especially the team. More than anything, I’m grateful for the trust you’ve placed in us through the good times and the tough times.
Onward and upward! -
Reynold Xin
@rxin
Super excited to welcome the Responsive team to @Databricks/@neondatabase to help take Lakebase Postgres to the next level. The best database is a lakebase!
Apurva Mehta
@apurva1618
I’m excited to announce that Responsive has been acquired by Databricks to accelerate the development of Lakebase and Neon!
We couldn't be more excited to join the Lakebase team. We've long admired their technical vision, and the more we got to know them, the more impressed we became by their ambition, execution, and momentum. It feels like a natural home for us.
I want to thank Responsive’s customers, investors, and especially the team. More than anything, I’m grateful for the trust you’ve placed in us through the good times and the tough times.
Onward and upward! -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Everyone has been obsessed by Jev and what it can do, and they should be! Fast typed decisions >> slow text generation. It's a complete game changer. But how do you do that with all the data you have?
We just dropped 𝚊𝚒_𝚍𝚎𝚌𝚒𝚍𝚎(), which runs decision models natively on all your data in @databricks . Now you can run system one decisions on all your big data, see screenshot.
www.databricks.com/blog/introducing-aidecide-make-fast-de… -
Reynold Xin
@rxin
Excited to announce our new partnership with @DecagonAI to bring richer enterprise data intelligence directly into customer conversations.
AI agents are only as useful as the context they can access.
Enterprises already have an incredibly rich record of their customers in Databricks. Orders, payments, product usage, preferences, and countless other signals all help explain who a customer is and what they need.
Through this partnership, Decagon agents can access governed data from the Databricks when they need it, while insights from those conversations can flow back into Databricks and become useful across the rest of the business.
We’re excited to work with the Decagon team to make enterprise customer agents more context aware while keeping data governance at the center.
decagon.ai/blog/decagon-and-databricks -
Reynold Xin reposted
Yuchen Jin
@Yuchenj_UW
We’re bringing Databricks Unity Gateway to developers on Neon (@neondatabase), and it’s the fastest AI Gateway for Kimi K3!
Databricks inference is moving super fast! -
Reynold Xin reposted
ComputeSDK
@computesdk
The results for AI Gateway Latency benchmarks are in. Here is one for @kimi_moonshot.
🥇@neondatabase
🥈@blazerail_ai
🥉@ngrokhq -
Reynold Xin reposted
Neon
@neondatabase
The Neon backend is GA. A complete set of primitives for apps and agents built around the database, with open standards, no lock-in, and branching-first by design.
Starting with: Lakebase Postgres, Object Storage, Functions, Managed Better Auth, and AI Gateway. More to come.This media couldn't be displayed. See it on the original post. -
Reynold Xin reposted
Rishi Raj Jain
@rishi_raj_jain_
Built a full-text search over all of Hacker News (~49M stories, comments, jobs & polls, syncing live per hour) to be 𝐬𝐮𝐫𝐩𝐫𝐢𝐬𝐢𝐧𝐠𝐥𝐲 𝐟𝐚𝐬𝐭 with no Next.js level cache and all magic at the Neon Postgres layer: hnfaster.vercel.app 🎉
• Every keystroke is a live query against @neondatabase Postgres
• BM25 (powered by Lakebase Search) ranking runs inside the Postgres
• No connection pool, just SQL-over-HTTP round trips
• pg_prewarm loads the table + every index into cache
• partial BM25 index per type, predicate matching the WHERE clause
• Deployed on @vercel
Just Postgres doing Postgres things, close to the compute 🐘This media couldn't be displayed. See it on the original post. -
Reynold Xin
@rxin
The best database for agents and recommended by agents is Lakebase Postgres on neon.com
Theo Otz
@Totzenberger
#1 in Claude Code, Codex and Cursor. Still first for GPT-6 Astra and Fable 5.1
@neondatabase ripped our leaderboard of which database agents choose.
Agents cite easy setup, branching and lower compute bills through scale-to-zero.
Every run open 👇
armature.tech/leaderboards -
Reynold Xin
@rxin
Pretty good summary!
Debasish (দেবাশিস্) Ghosh 🇮🇳
@debasishg
Sunday morning reading - a @VLDBconf 2026 paper on Lakebase from Databricks .. a very nice overview of the architecture that belongs to the same family as any system that treats object storage as the durable backplane and puts a low-latency cache/log in front of it.
Here are some points on how Lakebase handles durability and failure handling, things that differ so subtly across similar platforms like Aurora ..
• Commit point. Lakebase does not fsync WAL on the Postgres compute node. COMMIT returns when a quorum of safekeepers - typically two of three, in different AZs - has flushed that WAL record to local disk. Pageservers and object storage are not in that handshake.
• What each layer is allowed to lose. Compute can vanish at any time, it holds no durable state. A pageserver is a cache, so losing its NVMe does not drop committed transactions. Durability of recent writes sits on safekeeper disks until those segments are uploaded to object storage.
• The tail window. After SUCCESS, new WAL exists only on the safekeeper quorum. S3 catches up later, tracked by backup LSN. If a quorum of those flushed SK copies is destroyed before that upload, acknowledged writes are gone. That is the window, it is not closed at commit time.
• Compute and pageserver failure. Compute crash, scale-to-zero, and failover are 0 data loss because a new compute attaches to the same log. Pageserver NVMe loss does not drop committed transactions, another pageserver can reconstruct pages from WAL and from layers already in object storage.
• Object storage as the long-term copy, not the commit copy. Once backup LSN has passed a segment, Safekeeper-local WAL can be dropped and history lives in the lake. Branching and Point in time recovery use that LSN-addressable history. They do not move the commit rule: SUCCESS still means quorum disk flush, not an S3 PUT. -
Reynold Xin reposted
こば -Koba as a DB engineer-
@tzkb
Lakebaseの論文がVLDBで公開されている!AuroraやAlloyDBは第2世代で、オブジェクトストレージ上にオープンな形式でデータを保存するLakebaseは第3世代ということらしいよ。
www.vldb.org/pvldb/vol19/p4385-pandis.pdf -
Reynold Xin reposted
Databricks
@databricks
#vldb2026 is underway, and Databricks is here as a Gold Sponsor.
We’re sharing what we’re building for the future of agent-native data infrastructure, including:
• a keynote from Databricks co-founder @rxin on why the agentic future demands Lakebase Postgres
• AutoLiquid and Ultron query optimization
• Lakehouse//RT, Lakebase, and LTAP
• conversations with the database community on the ground
Still ahead: sessions and demos on Lakebase, @ApacheSpark Structured Streaming, and Enzyme.
If you’re at VLDB, come find the team 👋 -
Reynold Xin reposted
Neon
@neondatabase
Postgres on S3 is the right design, but even more interesting is making WAL the source of truth. This is how our storage works - we wrote a deep dive, summary on thread: neon.com/blog/wal-s3-lakebase-storage-for-the-era-of-agents
-
Reynold Xin reposted
Ali Ghodsi
@alighodsi
This is true. It wasn't actually possible before 2010 because datacenter networks would bottleneck. We used to design coupled storage/compute where you brought compute close to "big data". But research on "full bisection bandwidth" networks made it possible to essentially just talk from any machine to the storage system at full speed. The disaggregation started then! Databricks and Snowflake started soon after many others followed. Now "Put it on the object store" is the way to go.
Nikita | Scaling Lakebase Postgres
@nikitabase
"Put it on the object store" remains undefeated.
- OLAP: Lakehouse
- OLTP: Lakebase
- Kafka: Warpstream
- Vector Search: Turbopuffer
- Git: Cursor Origin -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Today, we announced that we crossed $7B in revenue run-rate, growing over 80% year over year in Q2.
We also shared:
🚀 $100M+ revenue run-rate for Lakebase
🚀 $1.5B+ revenue run-rate for Lakehouse, growing over 100% year over year
🚀 Continued positive adjusted free cash flow
And we raised $5B in our latest fundraise.
We’ll use this capital to invest in:
1️⃣ Lakebase, our serverless Postgres database built for AI agents
2️⃣ Genie, our AI coworkers that actually understand your business data
3️⃣ Unity AI Gateway, our multi-AI governance solution that helps control costs
@iamVictorDey shares more in @Forbes:
www.forbes.com/sites/victordey/2026/08/13/databricks-hits… -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Excited to share that we've acquired ElectricSQL, the team behind PGlite. Agents need super fast Postgres and this team built an amazing WASM (WebAssembly) implementation of postgres that runs in your browser, but can sync back with Postgres instances asynchronously. Exactly what blazing fast AI agents today need. Excited to supercharge our 𝐋𝐚𝐤𝐞𝐛𝐚𝐬𝐞 𝐏𝐨𝐬𝐭𝐠𝐫𝐞𝐬 offering with these capabilities.
www.databricks.com/blog/electric-joins-databricks-bring-w… -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
@databricks has the fastest and lowest latency on Kimi K3 (max)! Great job by Databricks AI team!
artificialanalysis.ai/models/kimi-k3/providers -
Reynold Xin reposted
Aaron Levie
@levie
Here’s another awesome use-case for what we can now do with our unstructured data because of AI agents.
Box now works with Databricks so you can take structured data from enterprise content (like contracts, financial document, supply chain data) and connect that data into Databricks.
This means that I can now query large document datasets without moving or reprocessing that content. And you can connect the data with any other system, like your ERP data, CRM, or product analytics. This opens up a ton of new use-cases for enterprise content.
All possible because of headless software and agents.
Box
@Box
The Box MCP server is now available in the @databricks Marketplace.
Data analysts and data scientists can now pull unstructured content from Box directly into their Databricks workflows through Genie. Structured vendor metrics and contract terms in one place. No platform switching. No data duplication.This media couldn't be displayed. See it on the original post. -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Gartner’s Magic Quadrant for Analytics and Business Intelligence (BI) is out, and Databricks was named a Visionary in our first appearance, the highest debut for any vendor in this MQ’s 20+ year history.
BI has already changed. Anyone can drill from a signal down to the truth behind it and agentic loops make sure every answer has the full story. That’s where we're ahead with Genie and AI/BI. I use it every day to see the key signals, understand what changed and why, and decide what to do about it.
Huge congratulations to the teams, and thank you to our customers. -
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
We benchmarked coding agents on our own internal tasks at Databricks and learned a lot!
There are many surprising opportunities to lower cost and increase quality, and many models including open source ones are truly competitive now. 🧵 -
Reynold Xin reposted
Neon
@neondatabase
Happy 30th birthday Postgres! 🎉
What an accomplishment, almost nothing in tech has stayed relevant for 30 years.
From humble beginnings as a Berkeley research project to becoming the default for everything from side projects to massive production systems.
30 years later, the database and the community have more momentum than ever. It's why we built Neon on Postgres, serverless, but 100% the Postgres you love. 🐘 -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
My co-founder @rxin personally wrote this really good paper that explains the main idea behind postgres Lakebase as well as LTAP. It almost serves as a primer on how transactional databases are built and how Lakebase and LTAP work. Maybe more importantly, what are the tradeoffs, and what are you giving up by adopting this new approach. Highly recommended reading:
www.databricks.com/blog/lakebase-ltap-rethinking-database… -
Reynold Xin
@rxin
I find the Lakebase design for serverless Postgres very elegant, so I spent some time explaining how it works in this blog.
The blog starts by explaining how databases really persist data (with a write-ahead-log and data files that are updated async), and how Lakebase separates storage and compute by externalizing those two components. It ends with how the Lakebase architecture naturally leads to LTAP, enabling OLTP and analytical workloads against a single governed copy of data.
My goal was to make it readable by anyone curious about how these systems work, not just database and storage experts. That turned out to be a lot more challenging than I first thought. Database storage is one of the most complex areas in computer science (the ARIES paper cited in blog was the hardest paper I personally ever had to read). The first draft had too little detail and I couldn't land the ideas. The second had too much and I'd lost anyone who isn't already a storage expert. This is the third draft, and I'd love feedback on whether the depth feels right.
www.databricks.com/blog/lakebase-ltap-rethinking-database… -
Reynold Xin reposted
Yuchen Jin
@Yuchenj_UW
You may have heard that GLM-5.2 at 328 token/s is cool,
How about 392?
Databricks is now #1 in inference speed for GLM-5.2 on Artificial Analysis. It's a great model, and we did a lot of optimizations. -
Reynold Xin reposted
Databricks
@databricks
We're proud to be named a Leader in the 2026 Gartner® Magic Quadrant™: AI Platforms for Data Science and Machine Learning!
Databricks is positioned highest in Ability to Execute and furthest in Completeness of Vision for the second year in a row. If you're evaluating AI platforms, this is the report to start with.
Get the report: www.databricks.com/resources/analyst-research/gartner-mq-… -
Reynold Xin reposted
Jamin Ball
@jaminball
I liked how @databricks laid out the 5 fiefdoms of the "Data Realm"
1. OLTP Databases
2. Data Engineering
3. Data Science
4. Data Warehouse
5. Real Time Analytics
Technically there was a 6 "catch all" bucket called niche databases -
Reynold Xin reposted
Tasso Argyros
@tasso
current vibe #dataaisummit
-
Reynold Xin reposted
Tasso Argyros
@tasso
After months of intense building, I am super excited to launch CustomerLake today!
CustomerLake is Databricks' answer to how Customer Data & Marketing will evolve in the agentic world.
AdWeek sat down with @alighodsi and msyelf to dig into the details. Check it out below! -
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Really excited to open source a new project: Omnigent, a meta-harness for AI agents.
It lets you build multi-agent coding and custom agents, sitting above Claude Code, Codex, Pi, and agent SDKs to let you compose them. It also adds live collaboration and rich control policies. -
Reynold Xin reposted
Neon
@neondatabase
Big news: Neon is expanding to offer a more complete set of backend primitives for running apps and agents:
✅ Database ✅ Authentication 🔜 Storage 🔜 Compute 🔜 AI Gateway -
Reynold Xin reposted
-
Reynold Xin
@rxin
The future of databases is being built directly on top of object stores. We call this the Lakebase architecture.
For a long time, the industry treated data lakes strictly as analytical or offline storage. But the Lakebase architecture is changing that by enabling true operational databases directly on top of the lake.
I believe this is the future of data infrastructure. It is how every database, whether it's an OLTP system or a vector database, should be built moving forward.
Of course, delivering the stringent performance requirements for operational databases on top of object stores require some creative engineering. Really excited to see more real-world examples of this architecture emerging. The team at Zilliz just shared a piece on why they rebuilt their vector database using this exact approach, and it perfectly captures where the industry is heading.
Check it out here: zilliz.com/blog/why-we-built-vector-lakebase -
Reynold Xin
@rxin
Oracle has spent the last two weeks writing articles comparing Oracle (and PDB) to Lakebase, and it highlights a massive philosophical divide in how we view databases in the agentic era.
They are trying to retrofit heavy, traditional architectures for AI. We believe Lakebase are the future because agents need something entirely different:
⚡️ Super simple APIs: so agents don't have to read a giant manual and hallucinate a query.
⚡️ Sub-second provisioning & auto-scaling: so you aren't paying legacy-level prices for idle time.
⚡️ Branching: Git-style branching to create isolated, safe environments for agents on the fly.
⚡️ Automatic backup & restore: so you don't sweat it when an autonomous agent inevitably drops a table.
The numbers speak for themselves. Lakebase is our fastest growing product. In the last few months alone, we've seen database start rate 30X, and now we are starting tens of millions of databases EVERY DAY. Some of these databases have 500 level deep branches and lifetime of just seconds due to how fast agents move.
Go try it yourself in a few seconds on neon.com!
The team has been cooking hard to push this gap even further. Come to Data and AI Summit next month to hear about some major new breakthrough capabilities. 🚀
(Links next so you can read their take) -
Reynold Xin reposted
Yuchen Jin
@Yuchenj_UW
Life update: I joined Databricks this week!
I thought I’d do another startup after Hyperbolic, but I was surprised by how startup-y Databricks AI is.
@alighodsi, @pwendell, @matei_zaharia are in full founder mode. They’re the best founders I’ve met. I like working with people who aren’t “normal” and they definitely aren’t. For example, they invited me to an all-hands before I joined.
I’m also impressed by how many former founders are here. @akhilgupta and @hanlintang are incredible leaders.
A big bonus: I finally have unlimited Claude Code & Codex tokens!
AI adoption on the Databricks AI team is insanely high. Every engineer I’ve met uses AI heavily and shares their own ways to drive agents. Many talented people here.
I’m super pumped for this new journey! -
Reynold Xin reposted
Amjad Masad
@amasad
Replit now deploys directly to Databricks.
Your apps run inside your Databricks environment while inheriting its security, governance, and data access.
Beta is live. Enterprises are already building with it and seeing massive acceleration in BI and internal tools. -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
@JeffDean says it best, the problem in this new agentic era is "tools designed for human speed interaction". That's why we think agents love 𝗟𝗮𝗸𝗲𝗯𝗮𝘀𝗲 𝗣𝗼𝘀𝘁𝗴𝗿𝗲𝘀, it can branch, snapshot, scale up and down in a second, orders of magnitude faster than other databases.
www.youtube.com/watch?v=joTYgvRHST0&t=1824s
Read about this architectural shift from Database to Lakebase:
www.databricks.com/blog/what-is-a-lakebase -
Reynold Xin reposted
Deirdre Bosa
@dee_bosa
the bigger story may be what comes next.
Ghodi said it out loud: "With the sort of SaaS disruption that we’re seeing, Databricks will definitely partake in that disruption"
He has the data, the AI... and now he's building the apps. Its the AWS playbook for the AI age.
Deirdre Bosa
@dee_bosa
Databricks enters cybersecurity... with Anthropic's models inside.
The company that stores data now wants to secure it too. The incumbents prepared for AI entering the market.... less clear they're prepared for the data vendor thats already inside the building
Sitting down w Databricks CEO @alighodsi today around 10:30a PT -
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Collaboration should be the default, not a paid feature. GitHub did it for coding, Neon does it for databases.
Neon
@neondatabase
Big news: You can now add unlimited team members and create multiple organizations on the free plan. 🚀
This helps you isolate your projects, collaborate with ease, and never worry about "per-seat" pricing.
Check out what’s new in the console! 👇This media couldn't be displayed. See it on the original post. -
Reynold Xin reposted
Max Brodeur-Urbas
@MaxBrodeurUrbas
gumloop raised a $50m series b led by benchmark
here's a video we had fun making about the journey
back to work.This media couldn't be displayed. See it on the original post. -
Reynold Xin reposted
Jamin Ball
@jaminball
Awesome job by the @databricks team
My summary:
They trained a model called KARL that beats Claude 4.6 and GPT 5.2 on enterprise knowledge tasks (searching docs, cross-referencing info, answering questions over internal data), at ~33% lower cost and ~47% lower latency.
The key insight: instead of throwing expensive frontier models at enterprise search, you can use reinforcement learning on synthetic data to train a smaller model that's faster, cheaper, AND better at the specific task.
RL went beyond making the model more accurate. I t learned to search more efficiently (fewer wasted queries, better knowing when to stop searching and commit to an answer).
They're opening this RL pipeline to Databricks customers so they can build their own custom RL-optimized agents for high-volume workloads.
I think we'll continue to see data platforms become agent platforms. Databricks' KARL paper is really an agent platform play. The pitch: you already store your enterprise data in the Lakehouse, now Databricks will train a custom RL agent that searches and reasons over it, tuned specifically for your highest-volume workloads (workloads = apps = agents). The business move is closing the loop: data storage → retrieval → custom agent training → serving, all on Databricks. They're turning "your data lives here" into "your agents live here too."
Kudos @alighodsi @matei_zaharia @rxin
Databricks AI Research
@DbrxMosaicAI
Meet KARL: a faster agent for enterprise knowledge, powered by custom reinforcement learning (now in preview).
Enterprise knowledge work isn’t just Q&A. Agents need to search for documents, find facts, cross-reference information, and reason over dozens or hundreds of steps.
KARL (Knowledge Agent via Reinforcement Learning) was built to handle this full spectrum of grounded reasoning tasks. The result: frontier-level performance on complex knowledge workloads at a fraction of the cost and latency of leading proprietary models.
These advances are already making their way into Agent Bricks, improving how knowledge agents reason over enterprise data.
And Databricks customers can apply the same reinforcement learning techniques used to train KARL to build custom agents for their own enterprise use cases.
Read the research → www.databricks.com/sites/default/files/2026-03/karl.pdf
Blog: www.databricks.com/blog/meet-karl-faster-agent-enterprise… -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Exactly 10 years ago (Jan 2016), I stepped in as CEO. We had just closed out Q4 with a total of $600k in revenue (screenshot from board deck).
Fast forward a decade.
Q4 audited GAAP Revenue: $1,290M and over $5.4B revenue run-rate ending January.
I’ve never tweeted our exact quarterly financials before, but seeing that $1.29B number cross my desk on my 10-year anniversary hit differently. To the team that built this: thank you. If you're following the data space, you know exactly what this milestone means. 🏗️ -
Reynold Xin
@rxin
Instead of configuring the Cursor agent from scratch, you can now install the Databricks plugin once and use it to build custom applications that query production data.
Cursor
@cursor_ai
Extend Cursor with plugins, now available in our marketplace.
-
Reynold Xin reposted
Ali Ghodsi
@alighodsi
I now constantly get questions about the SAAS meltdown, role of AI, system of records etc. I don't have an answer to all these.
But I do know that we saw an acceleration in our business in Q2, Q3, and now finished the year with accelerating Q4.
The question is, why?
Short answer: AI. But the underlying reason is subtle. We are growing fast because we are finally removing the biggest bottleneck in data: the technical barrier to entry.
For years, if you didn’t know SQL, Python, you were locked out of the value chain. That has changed fundamentally with the 𝐆𝐞𝐧𝐢𝐞 𝐟𝐚𝐦𝐢𝐥𝐲, and it is the "secret sauce" behind our recent momentum:
• 𝐆𝐞𝐧𝐢𝐞: Analysts can query data without any SQL. I use this every day myself.
• 𝐃𝐚𝐭𝐚 𝐒𝐜𝐢𝐞𝐧𝐜𝐞 𝐆𝐞𝐧𝐢𝐞: Builds end-to-end AI models for you, similar to Cursor for ML on your data.
• 𝐃𝐚𝐭𝐚 𝐄𝐧𝐠𝐢𝐧𝐞𝐞𝐫 𝐆𝐞𝐧𝐢𝐞: Write Spark pipelines, does plumbing, troubleshooting.
We've been talking about DATA + AI democratization, but generative AI finally enabled it in a way that wasn't possible before. That's why we're seeing a market response.
Take 𝐋𝐚𝐤𝐞𝐛𝐚𝐬𝐞 𝐏𝐨𝐬𝐭𝐠𝐫𝐞𝐬. We launched this serverless engine for agents and apps recently. At 8 months into its journey, its revenue is already 2x what our Data Warehouse product was at the same stage.
All this taken together, we ended up with the following stats for Q4:
🚀 $5.4B Revenue Run-Rate, growing >65% YoY
🚀 $1.4B AI Revenue Run-Rate
🚀 FCF Positive for the year
🚀 NRR >>140%
www.databricks.com/company/newsroom/press-releases/databr… -
Reynold Xin reposted
Databricks
@databricks
Today we announced Databricks Q4 results:
* Surpassing $5.4B revenue run-rate, growing >65% year-over-year
* Delivering positive free cash flow over the last 12 months
* Crossing $1.4 billion revenue run-rate for our AI products
Databricks is also completing investments in the company in excess of $7 billion, including ~$5B of equity financing at a $134 billion valuation and ~$2B of additional debt capacity.
“We’re seeing overwhelming investor interest in our next chapter as we go after two new markets,” said @alighodsi, co-founder and CEO of Databricks.
“With this new capital, we’ll double down on Lakebase so developers can create operational databases built for AI agents. At the same time, we’re investing in Genie to let every employee chat with their data, driving accurate and actionable insights.”
www.databricks.com/company/newsroom/press-releases/databr… -
Reynold Xin reposted
Databricks
@databricks
AI agents are no longer just writing code. They’re building the data layer itself.
New data shows agents now create 80% of enterprise databases and 97% of dev and test environments. This is evidence of a broader shift in data infrastructure - it needs to evolve to support building intelligent apps at machine-speed iteration.
@nikitabase, VP at Databricks and co-founder of @neondatabase, explains what is driving the move to a new kind of database: “The database is the system of record for AI applications. It’s no longer just a place to store rows; it’s the persistent memory and coordination layer for multi-agent systems.”
More from @Forbes writer @iamVictorDey: www.forbes.com/sites/victordey/2026/02/04/databricks-says… -
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Lakebase is GA! We think this is going to make it radically simpler and more reliable to work with online databases. You can instantly branch your DB, take snapshots, roll back to a point in time, or create a copy for offline analysis, whether it's humans or AI doing the work.
Databricks
@databricks
Operational databases have long relied on tightly coupled compute and storage. This architecture creates resource contention and pushes teams to manage infrastructure rather than build. As applications become more real time and automated, the transactional layer needs to adapt.
Databricks Lakebase is built for that evolution:
• Familiar Postgres semantics for app developers
• Compute separated from durable state
• Operational data running directly on the lakehouse
• Serverless autoscaling (including scale to zero), branching, and recovery to match agent-driven workload
Now generally available: www.databricks.com/blog/databricks-lakebase-generally-ava… -
Reynold Xin reposted
Databricks
@databricks
Operational databases have long relied on tightly coupled compute and storage. This architecture creates resource contention and pushes teams to manage infrastructure rather than build. As applications become more real time and automated, the transactional layer needs to adapt.
Databricks Lakebase is built for that evolution:
• Familiar Postgres semantics for app developers
• Compute separated from durable state
• Operational data running directly on the lakehouse
• Serverless autoscaling (including scale to zero), branching, and recovery to match agent-driven workload
Now generally available: www.databricks.com/blog/databricks-lakebase-generally-ava… -
Reynold Xin reposted
Sean Kerner @TechJournalist
From data lake to lakehouse to lakebase
@databricks ' Lakebase operational database cuts app delivery 92% for enterprises building AI agent infrastructure
"Really for the vibe coding trend to take off, you need the developers to believe they can actually create new apps very quickly, but you also need the central IT team, or DBAs to be comfortable with the tsunami of apps and database," @rxin told @VentureBeat
venturebeat.com/data/databricks-serverless-database-slash… via @VentureBeat -
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Yes!
DB-Engines
@DBEngines
DB-Engines Ranking climbers of the month:
1. @PostgreSQL
2. @databricks
3. @Redisinc
db-engines.com/en/ranking -
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
If you’re a recently active Neon user I just sent you a note asking for feedback on what we should prioritize in 2026. So many great replies already. We are going through all of them. Your feedback is a gift. We are going to ship some epic work this year!
-
Reynold Xin
@rxin
Yesterday we talked about how we got to $1B revenue run rate for our data warehousing business with Lakehouse. Today, we are excited to announce a whole suite of improvements for Lakebase:
⚡ Autoscaling that dynamically adjusts compute based on load
🕛 Scale to zero, allowing compute to shut down when idle and resume automatically in hundreds of milliseconds
⏫ Instant provisioning to create new database instances in seconds
🎋 Instant database branching, enabling git-like workflows with isolated, copy-on-write environments for development, testing, and staging
💾 Automated backups and point-in-time recovery for fast restore and safer operations
🆕 Postgres 17, alongside continued Postgres 16 support
📦 Increased storage capacity up to 8TB for larger production workloads
🎉 A new Lakebase UI that simplifies common workflows
Many of these are made possible by the unique Lakebase architecture that separates storage (in object stores) from compute.
Read more at www.databricks.com/blog/lakebase-holiday-update
Happy holidays! -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Yes, owning your own lakehouse is #12 on the rejuvenation program. It's right after collagen peptides and right before gene therapy. Reverses portfolio aging instantly.
-
Reynold Xin
@rxin
We disclosed today as part of our Series L that our 4-yr old data warehousing business is now >$1B revenue run rate. This is to the best of my knowledge the fastest to $1B DW product in the industry. How did we do it, and what’s next?
The conventional wisdom is that it would take 5+ years to build a new database (just to release one).
Four years ago, the linked blog announced that Databricks had won the official TPC-DS 100TB benchmark with DBSQL, which was in preview back then. It had the best perf and the best price/perf, and notably beating Snowflake by 12x in price/perf in that benchmark. (Note: we are still the top place on the official TPC-DS benchmark today.)
That blog post launched a contentious "benchmarking war" with a lot of back and forth between vendors, but more importantly it marked the very beginning of our data warehousing business.
To build this business, we assembled the best engineering team and established a new infrastructure product category called Lakehouse that inherits the flexibility and openness of data lakes and performance of data warehouses. Lakehouse is now the standard for data infrastructure, and organizations are migrating from legacy data warehouses to the Lakehouse.
The result so far is a testament to the team and their execution. We have a lot of ideas on how to take performance and usability to the next level, and the team is working hard to make that happen. Expect some big announcements next year. We want to lay the foundation for growing the data warehousing product to a $10B business.
Databricks had operated largely in the “analytics” side of data in the past, and we believe the “operational” side of data (aka “OLTP”) is also ready for a “Lakehouse” style disruption. A huge chunk of the founding team’s time is now focusing on “Lakebase”, a new category of OLTP databases that separates storage (in the lake) from compute. That architecture enables features that have been virtually impossible for databases in the past: instant provisioning, elastic scaling (down to zero), branching, high throughput scan directly from Spark, …
I won’t go into too much detail about Lakebase here, but we expect a similar trend to happen in the next few years: Lakebase will transform the industry and other OLTP systems will re-architect or position towards it.
The best data warehouse is a lakehouse, and the best database is a lakebase!
www.databricks.com/blog/2021/11/02/databricks-sets-offici… -
Reynold Xin reposted
Databricks
@databricks
We are excited to share our strong Q3 results:
- Growing >55% year over year, surpassing $4.8 billion revenue run-rate
- Exceeding $1 billion revenue run-rate for our Data Warehousing business
- Exceeding $1 billion revenue run-rate for our AI products
- Positive free cash flow over the last 12 months
We are also raising an >$4B Series L investment, valuing the company at $134 billion.
With this investment, we’ll help customers accelerate the development of Data Intelligent apps.
Congratulations to our employees, customers, partners and investors! www.databricks.com/company/newsroom/press-releases/databr… -
Reynold Xin reposted
Alex Kotenko
@alexykot
I tried several databases before coming back to the light (Postgres), and because of that, I ended up with currently having two different databases in parallel: Postgres hosted on @neondatabase and @MongoDB with Mongo Atlas.
Because of a over-eager clean-up routine that cleaned up too much, I need to restore a backup.
Neon took a second to restore, and I didn't have to worry about restoring the wrong thing because it clearly said that the pre-restore latest version is also saved, and I could switch back if I need to.
With @MongoDB , I'm writing this as I'm waiting for it to complete the restoration process. To be clear, my database is like kilobytes of data.
The Mongo part of it is miniscule, and yet I'm still waiting.
And yeah, they needed me to sign in blood that I agree that the cluster thing will be down during this whole process.
@MongoDB is a liability, I need to finish my move back to good old @postgres. -
Reynold Xin
@rxin
Zerobus will make it super easy to push data into Databricks. This is just the beginning. We will release far more capabilities in the coming months!
Databricks
@databricks
Announcing Public Preview of Zerobus Ingest, part of Lakeflow Connect: Push event data directly into your lakehouse—no message bus required!
Simplified ingestion. Reduced latency. Built for scale.
- Up to 100 MB/sec per connection
- Latency as low as 5 seconds
- Native Delta + Unity Catalog integration
With Zerobus Ingest, teams can easily build secure, real-time data pipelines for IoT, clickstream, and telemetry data, without the complexity of managing external infrastructure. Learn more: www.databricks.com/blog/announcing-public-preview-zerobus… -
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Super excited to welcome @mooncakelabs to Databricks.
Lakebase + Mooncake = one foundation for apps, analytics, and AI agents — Postgres, the Lakehouse + Agent Bricks, all on the same fresh data.
Databricks
@databricks
We’re excited to announce that Databricks has acquired @mooncakelabs to accelerate the vision of Lakebase, a new category of OLTP database built on Postgres and optimized for AI agents!
AI agents are transforming application development, and Lakebase gives developers a single foundation for applications, analytics, and AI – fully integrated with the Lakehouse and Agent Bricks.
Together, we will build on this innovation, ensuring Postgres data is immediately ready across workloads, without the overhead of ETL pipelines. Please join us in welcoming the team to Databricks! dbricks.co/3IOMj6m -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Databricks just signed a Series K term sheet at >$100B valuation to scale two flagship products:
🔥 Lakebase — serverless Postgres with true compute/storage separation
🧠 Agent Bricks — agentic framework with built-in reasoning guardrails for enterprise data
www.wsj.com/tech/ai/databricks-raising-funds-at-100-billi… -
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Separation of storage and compute doesn't sacrifice database performance. You can have both elasticity AND performance:
neon.com/blog/separation-of-storage-and-compute-perf -
Reynold Xin reposted
Databricks
@databricks
“We're at the dawn of the AI software revolution, and every engineer is becoming an AI engineer.”
Modern AI apps demand more than legacy databases can offer. At #dataaisummit, @neondatabase CEO and co-founder @nikitabase shared how Databricks and Neon are reshaping database architecture for the AI era with Lakebase.
This fully managed, serverless Postgres database is built to unify operational and analytical data on the lake house. Watch the full keynote conversation to learn more about fast, developer-first Postgres for intelligent applications: www.databricks.com/blog/announcing-lakebase-public-preview -
Reynold Xin
@rxin
This is a pretty good article on how we are rethinking OLTP databases with Lakebase!
The New Stack
@thenewstack
Are OLTP databases due for a radical rethink? @AlexWilliams reports from the @Databricks Data + AI Summit, where @rxin made the case for decoupling compute and storage in Postgres — treating data more like code.
thenewstack.io/new-oltp-postgres-with-separate-compute-an… -
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Amazing growth of the @Replit platform. Not surprised as Replit is incredibly useful and very very broad.
You can use it to prototype, up level your skills, build apps without knowing how to code, build interval apps to replace SaaS tools.
All in one, super high quality and improving daily!
Amjad Masad
@amasad
Earlier this month, we crossed $100M in ARR, up from $10M at the end of ’24.
But that’s just fraction of the value we’re creating: from enterprise teams like @zillow and @HubSpot shipping faster, to solo builders like @yoheinakajima and @GerrardL_ building and running their businesses on Replit.
We still have over half our funding in the bank. Our last round was in ‘23 at a $1.1B valuation, and we haven’t needed to raise since. We’re growing the team, and now’s a great time to join. The upside ahead is massive. -
Reynold Xin reposted
Andy Konwinski
@andykonwinski
Today, I’m launching a deeply personal project. I’m betting $100M that we can help computer scientists create more upside impact for humanity.
Built for and by researchers, including @JeffDean & @jpineau1 on the board, @LaudeInstitute catalyzes research with real-world impact. -
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
You can fight the trend of vibe coding saying it's not for "real engineers" or not for "production workloads".
No one will remember this in a few year as the industry fully transitions to the new way of doing things. -
Reynold Xin reposted
Databricks
@databricks
Databricks Co-founder and Chief Architect @rxin shares how Lakebase, a new category of databases, meets the current needs of agentic workloads and developers. “Current databases are disconnected from modern workloads—this changes that."
-
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Category creation in action. Powered by @neondatabase
www.databricks.com/blog/announcing-lakebase-public-preview -
Reynold Xin reposted
Prashanth Chandrasekar
@pchandrasekar
We are excited to announce that @StackOverflow Knowledge Solutions is joining the @databricks Marketplace! Trusted and accurate data is the foundation of AI, and through our new integration, customers will have access to Stack Overflow's 16 years of curated knowledge to power their data and AI ecosystems.
@alighodsi
Learn more about our latest partnership here: stackoverflow.co/company/press/archive/stack-overflow-dat… -
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
neon.com is live
-
Reynold Xin reposted
Andy Konwinski
@andykonwinski
If you had 15min to tell thousands of Berkeley CS/Data/Stats grads what to do with their lives, what would you say? Last Thursday I told them to RUN AT FAILURE.
Afterwards, while we were shaking hands & taking selfies, hundreds of them told me that they are excited to go fail. I don't think they’ve been given permission to do that before.This media couldn't be displayed. See it on the original post. -
Reynold Xin reposted
Glenn Solomon
@glennsolomon
1/ Big congrats to @nikitabase and the entire @neondatabase team on their acquisition by @databricks! A huge milestone for a world-class team building foundational infrastructure for the future of apps and AI.
-
Reynold Xin reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
I’m excited to share a major milestone: Neon is joining forces with @databricks.
neon.tech/blog/neon-and-databricks
Together, we will build the best Postgres experience in the world and one of the most important pieces of the modern AI-native stack.
Day 1 again for @neondatabase -
Reynold Xin reposted
Gumloop
@gumloop
today we're excited to announce guMCP
open-source MCP servers for every app, hosted for free
new integrations coming daily to democratize how LLMs get access to data -
Reynold Xin reposted
Daniel Lurie 丹尼爾·羅偉
@DanielLurie
Databricks signed a downtown lease and committed to hosting Data + AI Summit in SF through 2030, investing over $1B in the city. After considering Vegas, they’ve chosen to keep the conference here. We will keep working with business to drive our comeback!
www.sfchronicle.com/sf/article/databricks-investment-ai-c… -
Reynold Xin reposted
SAP
@SAP
We're bringing in a new era of enterprise data management and agentic AI with SAP Business Data Cloud with @Databricks.
✅ Unifies your SAP and non-SAP data
✅ Natively embeds Databricks technology
✅ AI agents streamline workflows
Learn more: sap.to/6011IgafW -
Reynold Xin reposted
Databricks
@databricks
We're excited to announce a new partnership with @SAP that will provide the Databricks Data Intelligence Platform natively within SAP’s newly launched SAP Business Data Cloud.
SAP Databricks will allow customers to use the AI, data warehousing, data engineering and data governance capabilities of Databricks on mission-critical data from SAP.
dbricks.co/4jTRXC1 -
Reynold Xin reposted
StreamNative
@streamnativeio
StreamNative's Ursa Engine now integrates with @databricks Unity Catalog, bringing real-time streaming to the Lakehouse!
✅ Stream to Iceberg & Delta Lake
✅ Better data governance & AI workflows
✅ Faster, cost-effective real-time analytics
streamnative.io/blog/seamless-streaming-to-lakehouse-unve…
#realtimedata #databricks #lakehouse #ai #streaming -
Reynold Xin reposted
Max Brodeur-Urbas
@MaxBrodeurUrbas
Gumloop will be a 10-person $1b company
We have 6 spots left
Gumloop
@gumloop
We're excited to announce Gumloop's $17m series A led by @NexusVP with participation from @firstround, @ycombinator and angels like @max, @ShaanVP, @bryantchou, @rxin to name a few
The future of AI automation is bright and we're thrilled to help shape it
blog.gumloop.com/gumloops-17m-series-a/ -
Reynold Xin reposted
Hyperbolic
@hyperbolic_labs
We're thrilled to announce that Hyperbolic has secured $20M in total funding with our Series A, led by Variant and Polychain Capital, to advance our mission of building verifiable, high-performance AI through an open, accessible ecosystem—making AI tools and services like compute and inference more affordable than ever.
In this “AI Rainforest,” the future of AI is open, accessible, and thriving.
Take your ideas Hyperbolic🌪️ at hyperbolic.xyzThis media couldn't be displayed. See it on the original post. -
Reynold Xin reposted
Andy Konwinski
@andykonwinski
I'll give $1M to the first open source AI that gets 90% on this sweet new contamination-free version of SWE-bench - kprize.ai
-
Reynold Xin reposted
Databricks
@databricks
We’re thrilled to partner with @ServiceNow to deliver Zero Copy, bi-directional integration with the Databricks Data Intelligence Platform, powered by Delta Sharing!
This integration will help our customers turn data into instant, AI-powered action.
ServiceNow News
@ServiceNowNews
✅ A Zero Copy partnership with @Databricks: supercharges machine learning and AI capabilities
Databricks’ Delta Sharing will enable ServiceNow to offer Zero Copy, high-bandwidth, bi-directional, and secure integration with the Databricks Data Intelligence Platform so customers can turn data and insights into instant, AI-powered action.
Learn more: www.servicenow.com/company/media/press-room/databricks-co… -
Reynold Xin reposted
Chris Lattner
@clattner_llvm
This speaks to me: it’s the essence of building hard things that take time to have impact, but then matter in a big way - you have to love the process, not just the outcome!
Ash Lamb
@ash_lmb
Do what feels like play to you but looks like work to others.
-
Reynold Xin reposted
Lester Mackey
@LesterMackey
I just want to return my package to Whole Foods 😭
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
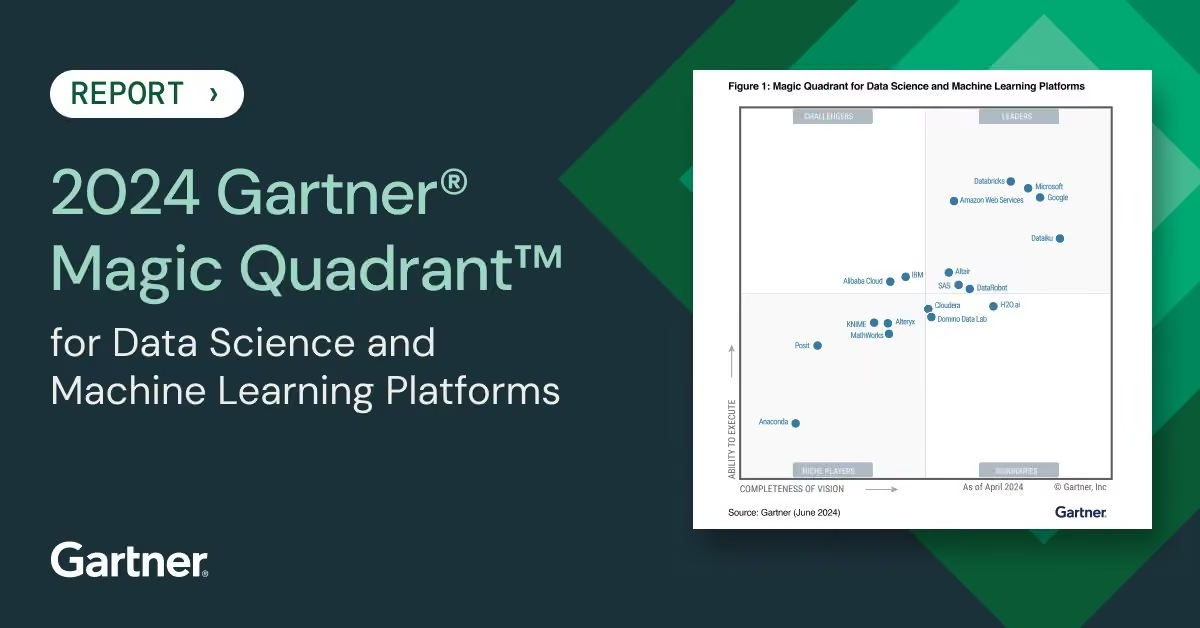
Really proud of our team for being named a leader in the Gartner MQ on Data Science and Machine Learning again, and ranked highest in Ability to Execute! By integrating ML deeply with data platform tools, we're simplifying it in ways that other AI/ML platforms can't.
Databricks
@databricks
Databricks named a Leader in the 2024 Gartner® Magic Quadrant™ for Data Science and ML Platforms & positioned highest in Ability to Execute out of all evaluated vendors!
We believe this recognition validates our focus on GenAI & traditional data science dbricks.co/3VLPvU9 -
Reynold Xin
@rxin
The best data warehouse is a lakehouse! Databricks SQL (our data warehousing product on top of the Lakehouse) became GA 2.5 yrs ago, and just crossed $400m ARR. One of the fastest growing enterprise software product ever.
Tomasz Tunguz
@ttunguz
Databricks revealed some sensational growth this week, as they did last year. Exiting this quarter to $2.4 billion annual run rate, the company’s revenue growth is accelerated year-over-year by 10 percentage points.
Net dollar retention is a major driver of growth at 140%, which is top decile. The table above shows the other data points that we’ve collected through their press releases in the last two years.
The fastest growing product category mentioned is the data warehouse revenue : 100% growth, now at $400m annually, nearing 20% of revenue.
With these modest data points, we can build a basic linear regression model for what the company is worth. This model is rough with an R^2 of approximately 0.45.
Assuming Databricks continues to grow at roughly 50%, that implies the company in the public markets would be worth approximately $54b. However, the company will likely trade at a premium to this. It is one of the few companies that provides significant exposure to AI software in the public markets.
Compared to Snowflake, Databricks is growing nearly twice as quickly. Without additional data, it’s difficult to comment on the relative sales efficiency or profitability.
Databricks’ growth rate is yet another example of the rapid demand for AI infrastructure & the systems needed to power it.
tomtunguz.com/databricks-growth-2024/ -
Reynold Xin reposted
Arvind Jain
@jainarvind
Exciting news today with our friends at @databricks.
This integration of Databricks AI/BI Genie with Glean will allow users to chat with the breadth of their enterprise data, uniting structured and unstructured data like never before while maintaining permissions and security.
Glean
@glean
Glean 🤝 @Databricks Genie
Our partnership with @Databricks enables you to query and analyze complex data directly within Glean, leveraging Genie's powerful capabilities to process structured data. www.glean.com/blog/glean-databricks-genie-announce -
Reynold Xin reposted
Databricks
@databricks
Databricks AI/BI is a new type of BI product that understands your data’s semantics & democratizes insights:
- AI/BI Dashboards: AI powered, low-code dashboarding
- Genie: learns underlying data, flexibly answers questions
Built on a compound AI system. dbricks.co/3VnMeJc -
Reynold Xin reposted
Databricks
@databricks
“The best data warehouse is a lakehouse.” @rxin live from the #dataaisummit
-
Reynold Xin reposted
Jonathan Frankle
@jefrankle
I guess I should probably include some images, since this is an image generation model. I'm so proud of @CoryMosaicML, @landanjs, Austin Jacobson, @jazco, and our extraordinary collaborators at @Shutterstock.
Jonathan Frankle
@jefrankle
Collaborating with @Shutterstock has been a highlight of my research career. The model we made together is proof that you can build great AI on trusted data in partnership with artists and creators. The path to a bright AI future is through collaboration. www.fastcompany.com/91139544/databricks-shutterstock-ai-i…
-
Reynold Xin reposted
Jonathan Frankle
@jefrankle
Collaborating with @Shutterstock has been a highlight of my research career. The model we made together is proof that you can build great AI on trusted data in partnership with artists and creators. The path to a bright AI future is through collaboration. www.fastcompany.com/91139544/databricks-shutterstock-ai-i…
-
Reynold Xin reposted
Databricks
@databricks
Databricks to acquire @Tabulario, a data platform from the original creators of Apache Iceberg. Together, we will bring format compatibility to the lakehouse for @DeltaLakeOSS and @ApacheIceberg dbricks.co/458s3n4
-
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Databricks to acquire @tabulario, a data platform from the original creators of Apache Iceberg. Together, we will bring format compatibility to the lakehouse for @DeltaLakeOSS and @ApacheIceberg
www.databricks.com/blog/databricks-tabular -
Reynold Xin reposted
Julia Neagu
@juliaaneagu
@DbrxMosaicAI DBRX outperforms @OpenAI GPT-4 on realistic, domain-specific benchmark datasets. For example, on a customer support summarization use-case👇👇👇
Still neck and neck but it shows that open models can be the no-brainer choice for actual enterprise applications. -
Reynold Xin reposted
Nathan Lambert
@natolambert
Okay @databricks what're you cooking behind this space its so fast lmao
-
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Today we released an open source model, DBRX, that beats all previous open source models on the standard benchmarks. The model itself is a Mixture of Experts (MoE), that's roughly twice the brains (132B) but half the cost (36B) of Llama2-70B. Making it both smart and cheap. Since only 36B expert parameters are used live, it's close to twice the speed (tokens/seconds) of Llama2-70B. We're excited to build custom versions of this for organizations that have proprietary data! Check it out!
www.databricks.com/blog/announcing-dbrx-new-standard-effi… -
Reynold Xin reposted
Mihir Patel
@mvpatel2000
🚨 Announcing DBRX-Medium 🧱, a new SoTA open weights 36b active 132T total parameter MoE trained on 12T tokens (~3e24 flops). Dbrx achieves 150 tok/sec while clearing a wide variety of benchmarks. Deep dive below! 1/N
-
Reynold Xin reposted
Databricks
@databricks
Databricks Ventures is excited to share its latest investment — @Glean! 🎉
We’re thrilled to accelerate their momentum as the industry’s leading AI-powered work assistant, & bring the secure deployment of #ai & knowledge building to all enterprises👇www.glean.com/blog/glean-series-d -
Reynold Xin reposted
Metronome
@getmetronome
🎉We’re excited to announce our $43M Series B funding led by @NEA, with continued support from @a16z and @generalcatalyst.
metronome.com/blog/series-b -
Reynold Xin reposted
Ram Parameswaran
@_ram_
A good listen about the foundational product (spark) of a foundational software company (databricks). well done @rxin and great interview @chakrabartis
sudipchakrabarti.substack.com/p/from-spark-to-databricks-… -
Reynold Xin reposted
Erebus
@IdemErebus
DONDA is the new FAANG
Deepmind
Open AI
Nvidia
Databricks
Anthropic -
Reynold Xin
@rxin
This is the first time that I talked extensively about Apache Spark's history, design philosophies, and the evolutions. Over the years, there have been a lot of misconceptions (why it came into existence, memory vs disk). This should explain all of them.
sudipchakrabarti.substack.com/p/from-spark-to-databricks-… -
Reynold Xin reposted
Databricks
@databricks
Databricks Vector Search is in public preview!
Augment your #llm apps and synchronize source data, eliminating the need to write and maintain separate data pipelines.
Find out why our customers already love it and how you can easily get started 👇 dbricks.co/3R9m2A1 -
Reynold Xin
@rxin
Today, more than 80% of the table metadata updates on Databricks are AI-assisted. It took 2 engineers, 1 month, and less than $1000 in compute cost to develop the custom LLM for this task. www.databricks.com/blog/creating-bespoke-llm-ai-generated…
-
Reynold Xin reposted
Ali Ghodsi
@alighodsi
The founders of Databricks put together this strategy blog on where we think data platforms are headed in the future. We're moving Databricks quickly in this direction. This is very exciting and is the outcome of the MosaicML acquisition we did earlier this year!
-
Reynold Xin reposted
Adi Polak
@AdiPolak
“ Solid understanding of Spark and ability to write, debug, and optimize Spark code. “
I was today years old when I discovered that openAI relies heavily on Spark. -
Reynold Xin reposted
Madhav Singhal
@madhavsinghal_
At Replit, we extensively use Spark on Databricks for all our training data work.
We run highly customized transformations on code like parsing, deduping, PII redaction, code filtering, tokenization, and more, written with low-level Spark primitives.
High quality data is key.
Adi Polak
@AdiPolak
“ Solid understanding of Spark and ability to write, debug, and optimize Spark code. “
I was today years old when I discovered that openAI relies heavily on Spark. -
Reynold Xin reposted
Databricks
@databricks
The trade-offs of Query Optimization is a *perfect* problem for #ai. Chief Architect @rxin walking us through new prediction optimizations in Databricks!
#lakehouseai #dataaisummit -
Reynold Xin reposted
Databricks
@databricks
We’re over the moon to announce we’ve agreed to acquire @MosaicML, a leading generative AI platform. Together, we’ll make generative AI accessible for every organization, so you can build, own & secure models with your data. www.databricks.com/mosaic-news
-
Reynold Xin reposted
Databricks
@databricks
🚨SOLD OUT 🚨
We’ve sold out in-person tickets for #dataaisummit! But you can still catch all the keynotes, select technical sessions, and live-streamed community events when you join us virtually! And it’s entirely free. Hurry & register: www.databricks.com/dataaisummit -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Big news: we've agreed to acquire @MosaicML, a leading generative AI platform. I couldn’t be more excited to join forces once the deal closes. www.databricks.com/mosaic-news
-
Reynold Xin reposted
Jonathan Frankle
@jefrankle
MPT-30B is here! Same MPT architecture, 30B parameters, > 1T tokens, 8k context window, trained on H100s, great perf (esp on coding), single-GPU inference, commercially usable, and massively upgraded instruct and chat datasets. Take it for a spin! huggingface.co/spaces/mosaicml/mpt-30b-chat
-
Reynold Xin reposted
Kent Marten
@datakmart
Learn about Mosaic, a Databricks Labs project, for geospatial processing. Tuesday, June 28 @ 4:45pm. databricks.com/dataaisummit/session/mosaic-framework-geos…
-
Reynold Xin
@rxin
English is the new programming language. Generative AI is the new compiler. Python is the new byte code.
-
Reynold Xin reposted
Databricks
@databricks
Rubicon is joining Databricks!
As companies leverage #ai + #llms, there’s a growing need for storage solutions that can process diverse data types and integrate the online + offline stack. We look forward to bringing Rubicon’s vision to the Lakehouse! www.databricks.com/blog/welcome-rubicon-databricks-future… -
Reynold Xin reposted
Databricks
@databricks
Spotted in @WSJ today!
#generationai is open to all. Every company is a data + #ai company. What will set you apart? -
Reynold Xin
@rxin
The upcoming Data and AI Summit keynote lineup looks insane: Eric Schmidt, Satya Nadella, Marc Andreessen, Nat Friedman (Github CEO introduced copilot), LangChain creator, PyTorch co-creator, DuckDB creator, and a few top researchers in AI and robotics www.databricks.com/dataaisummit/
-
Reynold Xin reposted
Mike Conover
@vagabondjack
With the Dolly 2.0 release yesterday we heard a lot of people saying they wanted smaller models that can fit on consumer grade GPU’s.
Here you go! Checkpoints from 2.8B and 6.9B now on the Databricks Hugging Face page! 🐑🚀
huggingface.co/databricks/dolly-v2-2-8b -
Reynold Xin reposted
Rachel Woods
@rachel_l_woods
@Databricks just released the first commercially usable, instruction-tuned open-source LLM
Might be a bigger step forward for open-source than LLaMA, Alpaca, et al
I'm sitting here reading the story of how they got there and it's just incredible: -
Reynold Xin
@rxin
Free Dolly! Introducing the first *commercially viable*, open source, instruction-following LLM. We are open-sourcing the entirety of Dolly 2.0, including the training code, the dataset, and the model weights, all suitable for commercial use.
www.databricks.com/blog/2023/04/12/dolly-first-open-comme… -
Reynold Xin
@rxin
If you can’t attend #dataaisummit in-person, don’t miss this free virtual option! You can still watch all keynotes and luminaries (we’ll be announcing some great ones soon) and watch tons of technical sessions from our community of experts. Join us! dbricks.co/3ZU6t2s
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
#dataaisummit Call for Presentations ends Jan 13! Submit your case studies, research or best practices around #lakehouse, MLOps, streaming, and data. Last year's event included 60,000 data experts. dbricks.co/3Wh1Mx6
-
Reynold Xin
@rxin
#dataaisummit Call for Presentations is open until Jan 13!
We want to hear from practitioners solving data, analytics and AI challenges using Apache Spark, @DeltaLakeOSS, @MLflow and more. Submit your idea! dbricks.co/3Wh1Mx6 -
Reynold Xin reposted
Andy Konwinski
@andykonwinski
The model isn’t just writing SQL, it’s also writing Pandas and Plotly code in Python. Then the webapp runs the Python (which runs the SQL) and returns the resulting plot. Almost like there’s a data scientist behind the scenes doing the hard and tedious parts for me.
Perplexity
@perplexity_ai
With Perplexity, you can search over databases. But also do more!
Visualize & Summarize results as aggregate stats, plots
Everyone gets to analyze data from natural language.
No prerequisite knowledge of SQL or plotting libraries necessary.
Link: www.perplexity.ai/sql -
Reynold Xin
@rxin
This is actually pretty cool ...
Perplexity
@perplexity_ai
Introducing Bird SQL, a Twitter search interface that is powered by Perplexity’s structured search engine. It uses OpenAI Codex to translate natural language into SQL, giving everyone the ability to navigate large datasets like Twitter.
www.perplexity.ai/sql -
Reynold Xin reposted
Perplexity
@perplexity_ai
Introducing Bird SQL, a Twitter search interface that is powered by Perplexity’s structured search engine. It uses OpenAI Codex to translate natural language into SQL, giving everyone the ability to navigate large datasets like Twitter.
www.perplexity.ai/sql -
Reynold Xin reposted
Patrick Wendell
@pwendell
Unfortunately for all of us, this is a highly accurate depiction of #mlops. @Databricks is focused on making this much simpler.
From: "Machine Learning Operations (MLOps): Overview, Definition, and Architecture". Dominik Kreuzberger, et al arxiv.org/abs/2205.02302 -
Reynold Xin
@rxin
Databricks #partnerconnect is on a roll 💪 Excited to announce six new integrations – all built to help our customers seamlessly expand the capabilities in their #lakehouse. @ArcionLabs, @matillion, @JohnSnowLabs, @_hex_tech, @anomalo_hq, Lightup. sprou.tt/1yeQCoTgpyx
-
Reynold Xin
@rxin
Apache Spark has won the SIGMOD Systems Award, and Photon won the Best Industry Paper Award! This is a great testament to the adoption and impact of these two systems.
If you are at SIGMOD this wk, please come by and say hi.
databricks.com/blog/2022/06/15/apache-spark-and-photon-re… -
Reynold Xin reposted
ACM SIGMOD
@sigmod
sigmod.org/2022-sigmod-awards/
2022 ACM SIGMOD Awards
Edgar F. Codd Innovations Award goes to Dan Suciu.
Contributions Award goes to Christian S. Jensen.
Test-of-Time Award goes to “NoDB: Efficient Query Execution on Raw Data Files”.
Systems Award goes to “Apache Spark”.
Congrats! -
Reynold Xin
@rxin
Excited about the new PopSQL integration with Databricks SQL! Some of our customers really like PopSQL and with this native support it is now super trivial to setup everything up. Look forward to more collaboration.
PopSQL
@popsql
📣 Announcing our integration with @Databricks ✨
It's now easier than ever to take stock of the data that powers your business, and make collaboration between your technical and business teams a cinch 🤝
Learn more here: popsql.com/updates/databricks
#analytics #sql #data -
Reynold Xin reposted
Parviz
@pdeyhim
The Holy Grail of Data Platforms and why I rejoined Databricks link.medium.com/Oka3QDuhCnb #databricks #data
-
Reynold Xin
@rxin
Databricks SQL Python connector is here! Connect to Databricks SQL in your applications just got much easier. sprou.tt/1K9JPGe3VcH
-
Reynold Xin
@rxin
Databricks ❤️ SQL & dbt.
databricks.com/blog/2021/12/06/deploying-dbt-on-databrick… -
Reynold Xin reposted
dbt
@getdbt
Big Coalesce drop: @databricks is launching a new dedicated dbt-databricks adapter, now in public preview. What does this mean?
🛠️ Even simpler installation process
✔️ Even better use of key Databricks functionality
📈 Even better performance
Read more: www.databricks.com/blog/2021/12/06/deploying-dbt-on-datab… -
Reynold Xin
@rxin
We are starting a Seattle eng site! Launching a number of important efforts in Seattle, covering a wide spectrum of our product and infrastructure: frontend, distributed systems, infra, databases, security.
databricks.com/blog/2021/11/22/announcing-databricks-seat… -
Reynold Xin reposted
ACM Queue
@ACMQueue
ACM Case Study
It Takes a Community:
The Open-source Challenge
Other programmers don't have to think about many of the challenges faced by OS devs, because they work where "other people" deal with those things
queue.acm.org/detail.cfm?id=3501361
@rxin @alanfgates @_SecretStache_ -
Reynold Xin
@rxin
Our customers have been asking for better SQL, so here you go! This blog post covers not only the biggest one, i.e. the switch to ANSI SQL dialect, but also lots of small features for productivity and migration from data warehouses over to Lakehouse. sprou.tt/13WFrzpQUK0
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Our bigger point is simply that that #lakehouse systems based on open data formats (Delta Lake) are now competitive with the best data warehouses, so there's no need to lock away part of your data just to do DW workloads. Even Snowflake's results on their cheapest tier show this.
-
Reynold Xin
@rxin
"We stand by our blog post and the results: Databricks SQL provides superior performance and price performance over Snowflake, even on data warehousing workloads (TPC-DS)."
databricks.com/blog/2021/11/15/snowflake-claims-similar-p… -
Reynold Xin
@rxin
Many of the best engineers at Databricks joined us straight out of school. To give back and grow the next generation, we are introducing the Databricks Engineering Fellowship.
$100k sign-on and mentorship by a world-class sr engineer.
databricks.com/blog/2021/11/10/announcing-databricks-engi… -
Reynold Xin reposted
Zaheera Valani
@zaheerav
1 month since I became a #brickster Time sure flies! Thanks @databricks for the 🔥 swag for the 🏠 office 🙏 #tgif 🧱
-
Reynold Xin reposted
Viorica Marian
@VioricaMarian1
I once taught an 8 am college class. So many grandparents died that semester. I then moved my class to 3 pm. No more deaths. And that, my friends, is how I save lives.
-
Reynold Xin reposted
Nadim Hossain
@NadimHossain
So cofounders @rxin @matei_zaharia want to spread the word that #data & #ai is not just about backend eng. It’s powered by high-performance visual analytics capabilities.
Please lend a hand by liking or tagging your favorite #frontend engineer! :)
databricks.com/blog/2021/10/21/simplifying-data-ai-one-li… -
Reynold Xin reposted
Andy Pavlo (@andypavlo.bsky.social)
@andy_pavlo
More props to @rxin for dropping the DeWitt Clause from their @databricks licensing agreement. It's 2021. There is no reason for these anymore. databricks.com/blog/2021/11/08/eliminating-the-dewitt-cla…
-
Reynold Xin
@rxin
The DeWitt clause is anti-competitive and we should foster competition and progress. At @databricks, we are removing the DeWitt Clause from our service terms to encourage open benchmarks and research, and calling upon the rest of the industry to follow.
databricks.com/blog/2021/11/08/eliminating-the-dewitt-cla… -
Reynold Xin reposted
Ben Lorica 罗瑞卡
@bigdata
FAQ: Can an open architecture built on a lakehouse provide the performance, speed, & cost advantages of data warehouses?
A: @Databricks SQL proves beyond any doubt that the lakehouse architecture is capable of achieving this. [@rxin @mostafamokhtar7]
databricks.com/blog/2021/11/02/databricks-sets-official-d… -
Reynold Xin reposted
Kanit Ham Wong
@kanitw
We’re growing our data visualization and front-end engineering teams at Databricks.
If you’re curious why Databricks is an exciting place to build the next generation of visualization tools, this blog might give you some answers.
databricks.com/blog/2021/11/03/building-the-next-generati… -
Reynold Xin reposted
VentureBeat
@VentureBeat
Databricks surpasses world record for data warehouse performance venturebeat-com.go-vip.co?p=2734862 by @theofficial_ksa
-
Reynold Xin
@rxin
Today, Databricks is known for our backend. What’s not as obvious is the focus on crafting user experiences that make data more accessible and usable. So we wrote this: databricks.com/blog/2021/10/21/simplifying-data-ai-one-li…
We are hiring 100+ engineers to craft the next-gen UI/UX to simplify data and AI! -
Reynold Xin
@rxin
I’m excited to announce that @databricks has acquired 8080 Labs! This is a great addition for customers who want to leverage low-code/no-code in their data and AI initiatives. Can’t wait to see this integration come to life! dbricks.co/3a9wiTQ
-
Reynold Xin reposted
Li Haoyi
@li_haoyi
Published a new blog post!
Reflecting on Four Years at Databricks
www.lihaoyi.com/post/ReflectingonFourYearsatDatabricks.html -
Reynold Xin reposted
Kanit Ham Wong
@kanitw
Some personal news: Today is my last day at @Apple. I'd like to thank all of my colleagues for their support and wonderful collaboration. It's been amazing for the past few years.
For my next step, I'm excited to join @databricks to help them grow visualization efforts. -
Reynold Xin
@rxin
So Amazon's Prime Day strategy: raise price by 15%, and then give you 15% discount?
-
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Why do you have to pick between diversity and merit? Make your work env. inclusive, decrease bias in hiring, as a leader don't make statements that alienate large groups. That'll give you a competitive advantage to a talent pool that won't join unwelcoming companies.
-
Reynold Xin reposted
Databricks
@databricks
Today, we’re introducing the world to the Databricks Feature Store, the first of its kind that is co-designed with a data & #mlops platform. Why are we obsessed? It helps #datateams accelerate ML efforts with simplified feature sharing & discovery. dbricks.co/2RSsFMv
-
Reynold Xin reposted
Databricks
@databricks
#automl can help Citizen Data Scientists build ML models quickly. Operationalizing them at scale...not so easy.
Meet Databricks AutoML, a “glass box” approach w/ a Citizen Data Science UI for the full ML lifecycle & generated code for experts to customize dbricks.co/3wCKvls -
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Nice updates on @Databricks SQL performance and our new #photon engine in @rxin's keynote today. We already ran faster/cheaper than cloud DWs for large datasets, but we now do great on small and concurrent queries, tables with small files, and BI fetches. www.youtube.com/watch?v=oz7XNx0YUw8
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
.@Data_AI_Summit @rxin suggests @Python is eating the world as more people are using #python #dataaisummit
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Two years ago, we introduced the world to #koalas, which was a game-changer for many customers & data scientists. We're thrilled to announce that @databricks is donating #koalas to #apachespark, which means better scalability & performance. @rxin explains at #dataaisummit
-
Reynold Xin reposted
Andy Slavitt Archived
@aslavitt46
For the first time since March of 2020, the 7 day average number of deaths from COVID-19 have fallen below 500.
And are dropping.
Keep getting vaccinated. -
Reynold Xin reposted
Andy Pavlo (@andypavlo.bsky.social)
@andy_pavlo
After 7yrs of research, @danavanaken + I are announcing that the commercial version of OtterTune is now available. This is a new easy-to-use SaaS for automatically optimizing @PostgreSQL + @MySQL configurations. See our inaugural blog post for more info: ottertune.com/blog/lets-do-this
-
Reynold Xin reposted
Databricks
@databricks
The walls between public clouds are vanishing.
A new open multi-cloud order has risen
from the structures of siloed clouds,
and customers will not rest until
all data teams can thrive together
in an open, unified platform. -
Reynold Xin
@rxin
Boba guys without boba.
www.sfchronicle.com/food/restaurants/amp/Boba-shortage-Ba… -
Reynold Xin
@rxin
*Free* registration for #dataaisummit is now open! We’ve got 200+ technical sessions on data + AI in-store and incredible keynotes from @Malala and Michael Lewis – with more to come. Join us! dbricks.co/329JzI4
-
Reynold Xin reposted
Databricks
@databricks
You asked for it. We made it happen. Dark Theme for Databricks notebook is here!
It’s been the most requested feature in Databricks history (🤯), so we can’t wait for you to try it out! Let us know what you think 👇
dbricks.co/2Odmcde -
Reynold Xin
@rxin
Biggest innovation we've ever done: Delta Time Travel for Future Data Sets. This temporal feature simplifies your pipeline by making it easy to audit, forecast schema changes and run experiments before that data even exists or is suspected of existing. databricks.com/blog/2021/04/01/introducing-delta-time-tra…
-
Reynold Xin
@rxin
Google Translate has a gender bias problem. I read this article in Greek today about @ailamaki and it was translated as "From an early age HE loved Mathematics" and "When HE finished high school".
www.kathimerini.gr/pages/k-igetides/561310444/oi-gynaikes… -
Reynold Xin
@rxin
#dataaisummit call for presentations ends Feb 26th!
If you’re interested in sharing your ideas and innovations with the world’s leading data, AI and #apachespark professionals, be sure to submit your proposal! dbricks.co/2YRpfcw -
Reynold Xin
@rxin
It's time for #lakehouse, data management platform that enables going from BI to AI, faster. See how ⬇️ sprou.tt/1ssaMGW1U6e
-
Reynold Xin reposted
Ben Lorica 罗瑞卡
@bigdata
🎙 Call for Presentations for the @Databricks #dataaisummit 2021 closes Feb 26th 🔜
databricks.com/dataaisummit/north-america-2021/call-for-p… -
Reynold Xin
@rxin
The future is multi-cloud. Today, jointly with Google, we are launching Databricks on Google Cloud.
databricks.com/blog/2021/02/17/announcing-the-launch-of-d… -
Reynold Xin reposted
Trustin Lee
@trustin
Paths Crossed Again: How I ended up joining Databricks databricks.com/blog/2021/02/16/paths-crossed-again.html
-
Reynold Xin
@rxin
😍😅😍
Databricks
@databricks
Today, we want to highlight our one true love: data 💕 #happyvalentinesday
-
Reynold Xin reposted
jay
@jay_drainjr
Consumer vs Enterprise:
Clubhouse raises at $1bn val and the world can’t stop talking about it
Databricks raises at a $28bn val and 90% of us don’t know what lakehouse architecture is -
Reynold Xin reposted
Databricks
@databricks
┻┳|
┳┻| *us when we hear someone
┻┳| talking about data*
┳┻| _
┻┳| •.•)
┳┻|⊂ノ
┻┳|
┳┻|
┻┳| -
Reynold Xin
@rxin
At @databricks, we don't all speak the same language or work in the same office. But it's all about the way we come together to work as one. 🌎 We shot a video to illustrate that point. Solving the world's toughest problems with data!
sprou.tt/1y526NgGAXU -
Reynold Xin reposted
Yatharth
@y99
Azure Databricks is now generally available in China ! azure.microsoft.com/en-us/updates/azure-databricks-now-ge…
-
Reynold Xin reposted
Seth Rosen
@sethrosen
She’s a data engineer. He’s a data analyst. Together they’re responsible for analytics at the country’s top fashion brand. Pipelines break, tempers flare, and sparks fly. Data Models premieres this fall on Fridays at 8pm on CBS.
-
Reynold Xin
@rxin
I wonder who’s genius idea it is to put a covid testing site in the ferry building farmers market, probably the highest density pedestrian traffic area in SF. It’s almost if somebody wants to maximize the likelihood of accidents transmission.
-
Reynold Xin reposted
ryan boyd
@ryguyrg
I wrote up my thoughts on what @Databricks and the Data + AI community accomplished during 2020-- most importantly around the open Lakehouse technology space.
I'm very proud of my peers for these achievements, especially in such a turbulent world.
databricks.com/blog/2021/01/08/lakehouse-architecture-rea… -
Reynold Xin reposted
Lee Edwards
@ledwards
If you’re a programmer exactly 34-38 years old, you went to college during a short-lived, unique period of time where the mainstream view was
1) Internet business is a bubble
2) all programming will be outsourced to India
And like me, you probably forget that all the time. -
Reynold Xin reposted
Ali Ghodsi
@alighodsi
Excited that our #lakehouse paper got published at #cidr21: it shares our vision of the Lakehouse: a new type of data platforms that are completely open, have full support for #machinelearning, while supporting all traditional #datawarehouse workloads.
cidrdb.org/cidr2021/papers/cidr2021_paper17.pdf -
Reynold Xin reposted
megan | מיה 🌈
@kehillahjewess
It seems like a customary Jewish tradition to eat Chinese food on Christmas, but have you ever wondered where that time-honored practice came from?🧵
-
Reynold Xin reposted
Mike Cornell
@TXMikeC
Did you see the new file browser in Azure Databricks? Now you can easily browse files and folders in DBFS and/or your mounted Azure Data Lake Store directly from the Azure Databricks Workspace UI. docs.microsoft.com/en-us/azure/databricks/data/databricks…
-
Reynold Xin reposted
Yuri Sagalov
@yuris
🚨New experiment!🚨
Hacking on a project right now? If you have a question on product / marketing / sales, email advice@wayfinder.com.
Behind that email are a few founders - @billclerico, @nolimits, @solomonstre, @rxin, myself - who will answer questions within 48 hours. -
Reynold Xin
@rxin
If you are interested in hearing more about the Lakehouse architecture, join our webinar next week: Lakehouse Architecture: From Vision to Reality databricks.com/p/webinar/lakehouse-architecture-from-visi…
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
@ApacheSpark 3.0 is a milestone community effort. Project Zen is a noble & novel effort to make #pyspark Pythonic cc @rxin #python #apachespark @Data_AI_Summit
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Arik Fraimovich of @getredash and Jesse Whitehouse of @databricks are sharing a comprehensive demo on how to use Redash for SQL Analytics on Databricks: www.databricks.com/dataaisummit
-
Reynold Xin
@rxin
I love the new query history view too. More to come!
Simon Whiteley
@MrSiWhiteley
Some awesome features inside #databricks #sqlanalytics - I love the query history, showing you what ran on the endpoint and where the performance problems are. This is a HUGE improvement for SQL admins rather than digging through the Spark UI! #dataaisummit
-
Reynold Xin reposted
Simon Späti 🏔️
@sspaeti
Nice to see @databricks shrinking #pyspark error messages from 8 pages to one, and keep optimizing!! Also adding #typehints which sess errors before running and adding #autocompletion in #notebooks and #ide's
#python #dataaisummit #dataengineering #programming #python -
Reynold Xin reposted
Li Haoyi
@li_haoyi
People who say coding interviews are unrealistic due to time pressure have obviously never had their database decide "TODAY IS THE DAY I DO BILLION ROW TABLE SCANS" at half past midnight, just as you are going to bed, & just as all your users are waking up and starting to use it
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Pretty sure I've seen people driving with only 19 neurons too!
MIT CSAIL
@MIT_CSAIL
This autonomous car can drive itself using only 19 control neurons.
Video: www.youtube.com/watch?v=8KBOf7NJh4Y
More: www.csail.mit.edu/news/new-deep-learning-models-require-f…
(work w/@ISTAustria @tuvienna)
#selfdrivingcars #autonomy #ml #dl #machinelearning -
Reynold Xin
@rxin
"You won the Nobel Prize. And so, they try to reach you, but they cannot. They don't seem to have a number for you. We gave them your cell phone number."
www.youtube.com/watch?v=co-WM5kOdaU -
Reynold Xin reposted
UC Berkeley
@UCBerkeley
The moment you realize you finally get a parking spot @UCBerkeley. 🌟
Congratulations Professor Doudna! @NobelPrize #crispr #gobears! news.berkeley.edu/2020/10/07/jennifer-doudna-wins-2020-no… -
Reynold Xin reposted
Hon. Marco Mendicino
@marcomendicino
Starting in late October, international students attending a designated learning institution that has been identified by their provincial or territorial government as having a COVID‑19 readiness plan will also be able to enter Canada.
-
Reynold Xin reposted
MIT CSAIL
@MIT_CSAIL
Stay at 127.0.0.1
Wear a 255.0.0.0 -
Reynold Xin reposted
NYSE 🏛
@NYSE
Nearly 40% of Fortune 500 companies are using @Databricks’ platform to collaborate and solve some of today’s toughest challenges
We talk with CEO Ali Ghodsi #nysefloortalkThis media couldn't be displayed. See it on the original post. -
Reynold Xin
@rxin
Welcome to Databricks, Trustin!
Trustin Lee
@trustin
Cleaned up the shelf in my home office before starting at @databricks
-
Reynold Xin reposted
Shahir Daya
@ShahirDaya
I've been working in this space recently. I have been keeping up with the Lakehouse pattern and Delta Lake. This should be a good session: www.kdnuggets.com/em/2020/databricks-0908.html. I plan to attend. This Delta Lake paper was a great read: databricks.com/wp-content/uploads/2020/08/p975-armbrust.pdf @rxin @databricks @matei_zaharia
-
Reynold Xin reposted
Antoine Nivard
@antoinenivard
Looking forward to doing this with @fnthawar @anutthara and @rxin next week to talk building remote-first teams, join the conversation! 👇
Inovia Capital
@inovia
Next up in our Inovia Sessions: Building geo-distributed and remote teams from Seed to IPO. Join us Sept 10 as Inovia @antoinenivard hosts a discussion with @Atlassian's @anutthara, @Databricks's @rxin and @Shopify's @fnthawar.
Register here: inoviasessions-distributedteams.splashthat.com -
Reynold Xin reposted
XKCD Comic
@xkcdComic
Dependency xkcd.com/2347/ m.xkcd.com/2347/
-
Reynold Xin reposted
Kayla Chan
@kayylachan
Summer in San Francisco🥰 #lightning #sundaymorning #bayarea
-
Reynold Xin reposted
CockroachDB
@CockroachDB
📚 #readinggroup "The 5 Minute Rule Ten Years Later, & Other Computer Storage Rules of Thumb." github.com/rxin/db-readings/blob/master/papers/5_min_rule…
✏️ Jim Gray & Goetz Graefe
Found this paper from the very well curated reading list from @rxin.
#paperreading -
Reynold Xin reposted
Mark⚡️Heckler 👨🏻💻🛩️
@mkheck
-
Reynold Xin
@rxin
After Delta Lake last year, we are now donating MLflow to the Linux Foundation, to provide a vendor-neutral home that will further broaden adoption and contributions to the #mlflow project. The project has 2.6 million downloads per month. A crazy number!
sprou.tt/1wef1mFHEcY -
Reynold Xin
@rxin
With our next gen data science workspace, we move one step closer to giving you the full power and flexibility of your local environment, with the benefits of the cloud (security, governance, elasticity, scalability, processing power).
sprou.tt/1XDv968zAkC -
Reynold Xin reposted
Redash
@getredash
We're excited to announce that Redash is joining @databricks! Learn more blog.redash.io/redash-joins-databricks/
#sparkaisummit #datateams -
Reynold Xin reposted
Mike Cornell
@TXMikeC
I love that @databricks doesn't just announce new shiny tools, engines, or features... they give you the history, the "why" it was needed, how it was built, and the phenomenal outcomes and value. Technical Proof in Spark 3.0, Delta Engine, and Photon! #sparkaisummit #datateams
-
Reynold Xin
@rxin
Join us at Spark Summit. Learn about data and AI, and help those in needs.
Databricks
@databricks
We’re sponsoring @NAACP_LDF and @PolicingEquity at this year’s #sparkaisummit. Join us in supporting these organizations and Databricks will match all donations up to $100,000. Let’s show what’s possible when #datateams stand together. dbricks.co/SAISSF20Donation
-
Reynold Xin
@rxin
Really excited about this. Been working with the Redash team past few weeks. Genuinely impressed. 1 + 1 > 2. We have ambitious plans and together we will make data drastically easier to query, explore, visualize, share, consume. databricks.com/blog/2020/06/24/welcoming-redash-to-databr…
-
Reynold Xin reposted
TechCrunch
@TechCrunch
Databricks acquires Redash, a visualizations service for data scientists tcrn.ch/3dvPPNe by @fredericl
-
Reynold Xin reposted
Jeffrey G. Reid
@jgreid
I'm so proud of the @Regeneron Genetics Center team for what we've accomplished in collaboration with @databricks but today is really special as we're announcing GloWGR, a distributed implementation of the exciting new Regenie package... 1/2
glow.readthedocs.io/en/latest/blogs/glowgr-blog/glowgr-bl… -
Reynold Xin reposted
Chris Moriates, MD
@ChrisMoriates
If you’ve ever visited the Texas medical center area in Houston, it is enormous - biggest in the world. Hard to imagine running out of beds there.
Just heard adults now being admitted to Texas Children’s Hospital due to overflow.
Texas, we are facing a rapidly worsening crisis -
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
Get into the relaxed mindset with morning @MLflow Yoga, followed by keynotes, @DeltaLakeOSS AMA tomorrow, and full day of technical sessions across may tracks @SparkAISummit #datateams #sparkaisummit #apachespark #deltalake #mlflow
-
Reynold Xin
@rxin
Databricks has 4 immigrant founders. We moved to the US for the opportunity to work with the best minds in the world. Our projects power all sectors of the US economy. We employ 1400 people & growing, most in the US. None of these would've happened if we were to start in 2020.
-
Reynold Xin reposted
Eric Topol
@EricTopol
“Slow the testing down”
OMFG -
Reynold Xin reposted
Li Haoyi
@li_haoyi
PSA: @databricks is still hiring software engineers in a wide variety of roles, even others are freezing hires or doing layoffs
If anyone wants to work with us on a large #scala codebase, or with me specifically on cutting edge developer tools, drop me an email with your resume! -
Reynold Xin reposted
Gavin Newsom
@GavinNewsom
They were not simply names on a list.
They were us.
💔 -
Reynold Xin reposted
kardiolabsAI
@aortaAI
The dream companies at different times for a software engineer:
1990 : @IBM
1995 : @Microsoft
2000: @Yahoo
2003: @Google
2008: @Facebook
2010: @Uber
2013: @Airbnb
2015: @Netflix
2017: @databricks
This is just a survey done on limited engineers #100daysofcode #javascript -
Reynold Xin reposted
Gavin Newsom
@GavinNewsom
LA received 170 broken ventilators from the national stockpile. Rather than complaining, we put them on a truck, drove them up overnight, and had @Bloom_Energy get to work fixing them.
Monday they‘ll back in LA--fixed.
That’s the spirit of CA. -
Reynold Xin reposted
Joe Hellerstein
@joe_hellerstein
Considering grad school at #ucberkeley? The research opportunities are first rate of course. And also, this week the wisteria started blooming as usual in Feb. And yes that’s the bay and the bridges in the background and yes it’s really like this.
-
Reynold Xin reposted
Ryan Donahue
@rydonahue
So happy to be a part of @databricks !
Databricks
@databricks
We’re excited to have @rydonahue join Databricks as our VP of Product Design!
Check out his blog post on why he joined Databricks and the potential that design has to play a huge role in making #ai and #bigdata tools more accessible.
dbricks.co/wp200227a
#lifeatdatabricks -
Reynold Xin
@rxin
#sparkaisummit has grown into one of the largest data and machine learning conferences in the world. Join over 7,500 data scientists, engineers and analysts in San Francisco, June 22-25, as we collaborate on the future of data and ML. dbricks.co/SAISSF20RegLI
-
Reynold Xin reposted
Fivetran
@fivetran
We're proud to announce that we've added @databricks as a destination! Learn how to ingest data into #deltalake to create reliable data lakes at scale. Join this webinar from @databricks to see how @fivetran makes this easy databricks.com/p/webinar/databricks-ingest-delta-lake
-
Reynold Xin reposted
Databricks
@databricks
It’s not often that someone pens a love letter about your company, but that’s exactly what @AiimiLtd's Senior Data Scientist just did.
We’ll let him tell you how Databricks stole his heart. 💘 dbricks.co/ex200213a
#valentinesday -
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Just in time for my lecture on data quality at Stanford.
-
Reynold Xin reposted
Databricks
@databricks
Databricks is coming to Canada!
@rxin, our co-founder and chief architect, shares with @itworldca why we’re opening an engineering hub in #toronto. dbricks.co/ex200203a
#lifeatdatabricks #careersintech -
Reynold Xin
@rxin
This interview shares some thoughts on why we are starting a new engineering office in Toronto, in addition to our SF headquarter and European R&D center in Amsterdam.
www.itworldcanada.com/blog/databricks-opens-major-enginee… -
Reynold Xin reposted
Databricks
@databricks
In our latest blog post, we demonstrate how to train hundreds of time series forecasting models in parallel with Facebook Prophet and #apachespark. dbricks.co/wp200127a
-
Reynold Xin reposted
Databricks
@databricks
ICYMI: @NateSilver538, founder of @FiveThirtyEight and author of The Signal and the Noise, was announced as one of the keynote speakers of #sparkaisummit.
Save your spot: dbricks.co/SAISSF20RegTW -
Reynold Xin reposted
-
Reynold Xin
@rxin
I’m proud of what we have accomplished together with data in 2019: The millions of VMs and exabytes of data per day contributed to important social issues (energy, diseases, market manipulation). Here’s a recap of 2019: databricks.com/blog/2020/01/23/2019-databricks-year-in-re…
-
Reynold Xin reposted
Databricks
@databricks
As we look back on 2019, it was a year highlighted by new developments in our open source platforms, expanding into new markets and reaching the 1,000 employee milestone.
As we welcome 2020, we're excited to see what the year has in store. dbricks.co/wp200123a
by @rxin -
Reynold Xin reposted
Kees
@KeesTalksTech
Cool. Thanks for adding us! What do you wanna know? Got a blog on it: medium.com/wehkamp-techblog/streaming-kafka-topic-to-delt… 😎
-
Reynold Xin reposted
Kelly Canuck🍁
@KellyCanuckTO
Fun Fact: All Canadian babies learn to walk by shoveling
Clarenville, NL 🇨🇦
📹 Samantha Burke-Balsom -
Reynold Xin reposted
randyhkatz
@randyhkatz
"Analytics company Databricks accepted $400 million in October after being offered $900 million from investors, said Ali Ghodsi, chief executive of the company." US Backers Rain Money On Savvy Startups - www.pymnts.com/startups/2020/us-backers-rain-money-on-sav…
-
Reynold Xin reposted
-
Reynold Xin
@rxin
#sparkaisummit is one of the largest data and machine learning conferences in the world. Submit your session idea now and join over 7,000 data scientists, engineers and analysts as we collaborate at the intersection of data and ML in San Francisco. dbricks.co/SAISSF20RegLI
-
Reynold Xin reposted
Gerhard Brueckl
@GBrueckl
Just published a new version of my Powershell module for @databricks at www.powershellgallery.com/packages/DatabricksPS
It now supports Instance Pools and also IntelliSense/AutoComplete was added to all cmdlets! -
Reynold Xin reposted
ryan boyd
@ryguyrg
Do I know any great data scientists who love to teach, learn, speak, code, and write? Reach out!
@databricks is growing 3X YoY and we're looking for great eng/ds advocates. You'll get to work with @2twitme @dennylee and the original creators of Apache Spark, DeltaLake, MLflow++ -
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
I gave a keynote at @ACMSoCC about lessons from building a large-scale cloud service at @Databricks. Did you know that Databricks runs millions of VMs/day to process exabytes of data with <200 engineers? Slides here: www.slideshare.net/matei/lessons-from-largescale-cloud-so…
-
Reynold Xin
@rxin
SFO United: you need to print your eTA.
Me: I’ve traveled dozen times with email confirmation.
Agent: No.
Me: e in eTA means electronic.
Agent: we require paper in case your phone dies.
Me: www.cic.gc.ca/english/helpcentre/answer.asp?qnum=1066&top=16
Agent: I need to check with the back. -
Reynold Xin reposted
dennylee
@dennylee
In Amsterdam and want to learn more about Koalas -pandas API on #apachespark - Tim Hunter will be presenting at the Data Council meetup #databricks Edition www.meetup.com/datacouncil-amsterdam/events/262125039/
-
Reynold Xin
@rxin
This is my personal favorite piece of our new funding round: "this one can legitimately lay claim to all the hottest enterprise software buzzwords, from open-source to machine learning to cloud." www.axios.com/databricks-series-f-valuation-venture-capit… Thanks @danprimack.
-
Reynold Xin reposted
Bloomberg Technology
@technology
Ben Horowitz says this startup chief is the best CEO he's ever worked with www.bloomberg.com/news/articles/2019-10-22/databricks-dou…
-
Reynold Xin reposted
Databricks
@databricks
We're happy to announce the appointment of David Conte as CFO. David will lead all financial and operational functions at Databricks through our next phase of global growth, bringing with him 30 years of experience in the technology industry. dbricks.co/NewCFO
-
Reynold Xin reposted
Databricks
@databricks
We're excited to announce that we've raised $400 million to continue our rapid global growth and engineering expansion, an investment that brings our valuation to $6.2 billion. Learn more: dbricks.co/SeriesFfunding
-
Reynold Xin reposted
Built with Go
@RealGophersShip
xinsnake/databricks-sdk-golang (0.1.1): This is a #golang SDK for DataBricks REST API 2.0 and Azure DataBricks REST API 2.0 mdy.io/gh/xinsnake/databricks-sdk-golang
-
Reynold Xin reposted
MLflow
@MLflow
Managed MLflow Now Available on Free Databricks Community Edition: Learn how to manage machine learning lifecycle w/ MLflow #machinelearning databricks.com/blog/2019/10/17/managed-mlflow-now-availab…
-
Reynold Xin reposted
Databricks
@databricks
Databricks' European Development Center is an engineering hub for development and innovation, and we're announcing a 100 million Euro investment in Amsterdam over the course of three years.
Learn more about this announcement: dbricks.co/EUDevCenter
#sparkaisummit -
Reynold Xin reposted
Adi Polak
@AdiPolak
Spark ecosystem is evolving. Adding @DeltaLakeOSS for ACID transactions and Koalas for Data science .
Including performance enhancments for joins operations 💫 -
Reynold Xin
@rxin
Delta Lake is now part of the Linux Foundation! EBs of data/month, in production 1000s of organizations. Can't wait to see how the community will shape its future and establish it as a standard for data lakes.
databricks.com/blog/2019/10/16/delta-lake-now-hosted-by-t… -
Reynold Xin
@rxin
We are investing 100m euro in our European R&D center in Amsterdam over the next few years: databricks.com/company/newsroom/press-releases/databricks…
-
Reynold Xin reposted
Delta Lake
@DeltaLakeOSS
Simple, Reliable Upserts and Deletes on #deltalake Tables using Python APIs (part of Delta Lake 0.4.0)
databricks.com/blog/2019/10/03/simple-reliable-upserts-an… -
Reynold Xin
@rxin
Gchat used to be my favorite messages app on desktop. Deleted hangout on my phone today. Good bye Google and the end of an era...
-
Reynold Xin reposted
Reynold Xin
@rxin
Adventures in the TCP stack: Uncovering performance regressions in the TCP SACKs vulnerability fixes
databricks.com/blog/2019/09/16/adventures-in-the-tcp-stac… -
Reynold Xin
@rxin
Adventures in the TCP stack: Uncovering performance regressions in the TCP SACKs vulnerability fixes
databricks.com/blog/2019/09/16/adventures-in-the-tcp-stac… -
Reynold Xin reposted
Databricks
@databricks
We’re excited to announce another great speaker for #sparkaisummit in Europe: @OriolVinyalsML, who led the AlphaStar team that created the first agent to beat a professional at the game of StarCraft.
Save your spot now: dbricks.co/SAISeu -
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Nice blog post from our Databricks intern Apurva, who worked on auto-logging for #mlflow (now out in MLflow 1.1): databricks.com/blog/2019/08/19/mlflow-tensorflow-open-sou…
-
Reynold Xin reposted
Delta Lake
@DeltaLakeOSS
We’re excited to announce the availability of #deltalake 0.3.0 including Scala/Java APIs for DML commands, query commit history, and vacuuming old files. github.com/delta-io/delta/releases/tag/v0.3.0
-
Reynold Xin
@rxin
We found network perf regressions in <0.2% of workloads after we applied the kernel patch. Here's more information and how you can mitigate. Make sure you secure your systems, or work with a data platform that does that for you. databricks.com/blog/2019/08/01/network-performance-regres…
-
Reynold Xin
@rxin
At Databricks we are lucky to have a team of incredibly strong engineers focusing on developer productivity. They make it possible for other engineers to run fast and create those new products that data teams around the world depend on. databricks.com/blog/2019/07/23/fast-parallel-testing-at-d…
-
Reynold Xin reposted
Li Haoyi
@li_haoyi
Wrote a new blog post: Fast Parallel Testing at Databricks with Bazel
databricks.com/blog/2019/07/23/fast-parallel-testing-at-d… -
Reynold Xin reposted
Delta Lake
@DeltaLakeOSS
.@ventanaresearch unveiled that #deltalake was named the #bigdata Winner for the 12th Annual Digital Innovation Awards! www.ventanaresearch.com/press-release/ventana-research-un…
-
Reynold Xin reposted
Bogdan Ghit
@BogdanGhit
This week Amsterdam is the main data hub of the world. Join us at Sigmod to learn about the Databricks office in Amsterdam, career opportunities, internship programs and more. @databricks @SIGMOD2019
-
Reynold Xin reposted
Takuya UESHIN
@ueshin
Koalas 0.9.0 has been released. github.com/databricks/koalas/releases/tag/v0.9.0
-
Reynold Xin reposted
Databricks
@databricks
At Databricks, we build platforms to enable data teams to solve the world’s toughest problems and we couldn’t do that without our wonderful Databricks Team. Learn more about Alexandra Cong, one of our Software Engineers, and what drew her to Databricks! (www.databricks.com/blog/2019/06/26/brickster-spotlight-me…)
-
Reynold Xin reposted
Delta Lake
@DeltaLakeOSS
Excited to announce Delta Lake release 0.2.0 is here already. Adds cloud support and improved concurrency. #analytics #dataengineering Check out release notes dbricks.co/2Iv3VCF
cc:@databricks -
Reynold Xin reposted
Nicolas Rémond
@nremond
Why are Data Lakes hard to work with? @rxin lists 3 pain points #scaladays
-
Reynold Xin reposted
Andrea Mocci 🇪🇺@🇨🇭
@andreamocci
Tracking, Projects, Models in #mlflow - pretty impressive for a 1 year old project! #scaladays
-
Reynold Xin reposted
Databricks
@databricks
Join our co-founder, @rxin at @scaladays on 6/12. He'll be presenting on "A Story of Unification from @ApacheSpark to #mlflow". Details here:
scaladays.org/schedule/a-story-of-unification-from-apache… -
Reynold Xin reposted
Takuya UESHIN
@ueshin
Koalas 0.5.0 was released. github.com/databricks/koalas/releases/tag/v0.5.0
-
Reynold Xin reposted
Scala Days
@scaladays
🎺🎺Keynote announcement: @rxin opens the 2nd day with "A Story Of Unification: From Apache Spark to MLflow" check it out 👉scaladays.org/schedule/a-story-of-unification-from-apache…
-
Reynold Xin reposted
Databricks
@databricks
We know that managing cloud infrastructure can be tough, which is why we're introducing Databricks Cloud Automation with the power of Terraform. dbricks.co/2VGySet #devops
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Registration is now open for #sparkaisummit Europe! Join us this October in Amsterdam for keynotes from @rxin @matei_zaharia @GaelVaroquaux @OriolVinyalsML - register today and save with launch pricing! databricks.com/sparkaisummit/europe
-
Reynold Xin reposted
Databricks
@databricks
Often we ask the question: was it untitled.ipynb or untitled(1).ipynb which created this training run with x% validation accuracy? Announcing the #mlflow notebook sidebar, which helps track revisions to help you reproduce successful experiments: dbricks.co/2DGMqw3
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Just attended the largest Big Data and AI lunch in the world! #sparkaisummit
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Don’t miss your chance to ‘Ask Me Anything’ featuring @matei_zaharia @rxin @xmeng Taking place today at #sparkaisummit in the Expo Theater at 6:30 pm. #deltalakeoss #mlflow #koalas #deeplearning #apachespark
-
Reynold Xin reposted
Andy Konwinski
@andykonwinski
@rxin winding up to throw stuffed pandas at the #sparkaisummit audience.
-
Reynold Xin reposted
Andy Konwinski
@andykonwinski
#sparkaisummit. I'd go to a club that looked like this, especially if the Dj was covering ML frameworks
-
Reynold Xin reposted
Andy Konwinski
@andykonwinski
Delta Lake - new open source project (Apache v2 licensed) announced. Transaction log + optimistic concurrency + performance tricks on your data lake. #sparkaisummit
-
Reynold Xin reposted
Andy Konwinski
@andykonwinski
Microsoft embraces @MLflow. They're writing open source code (e.g., windows support, contributing to tracking API) and adding MLflow to #azureml
-
Reynold Xin reposted
Python Trending 🇺🇦
@pythontrending
koalas - Koalas: Pandas API on Apache Spark github.com/databricks/koalas
-
Reynold Xin reposted
-
Reynold Xin reposted
Databricks
@databricks
[Blog] Learn how to deploy Azure Databricks clusters in your own custom VNET #cloudsecurity
dbricks.co/2IpedUT -
Reynold Xin reposted
biohub
@biohub
We require our grantees to:
💻Deposit software code to a repository such as @github
📝Submit results to preprint servers like @biorxivpreprint
🔬Make experimental protocols accessible via sites like @protocolsIO
Read about our support of open science: medium.com/@cziscience/power-to-the-protocols-388fe92001be -
Reynold Xin reposted
John Britton
@johndbritton
It's time to start my next adventure.
I've joined @databricks as VP, Developer Relations & Advocacy.
I'm excited to learn everything I can about Artificial Intelligence, Machine Learning, Data Science, and Data Engineering. -
Reynold Xin reposted
Reynold Xin
@rxin
I'm looking for an engineer in SF to build out our next-gen data processing engines. You will work with & learn from world-class engineers that have designed some of the most successful data systems (Spark, Impala, VectorWise, F1). For more details see databricks.com/company/careers?gh_jid=4249504002
-
Reynold Xin
@rxin
I'm looking for an engineer in SF to build out our next-gen data processing engines. You will work with & learn from world-class engineers that have designed some of the most successful data systems (Spark, Impala, VectorWise, F1). For more details see databricks.com/company/careers?gh_jid=4249504002
-
Reynold Xin
@rxin
Introducing Databricks AWS IAM Credential Passthrough: A guide to federate your AWS IAM with Databricks
databricks.com/blog/2019/03/26/introducing-databricks-aws… -
Reynold Xin
@rxin
Today we are excited to announce Brickchain, the next generation technology for zettabyte-scale analytics, by harnessing all the compute power on the planet. Brickchain is the most scalable, secure, and collaborative data technology ever invented. databricks.com/blog/2019/04/01/introducing-brickchain-pla…
-
Reynold Xin
@rxin
The keynote lineup for #sparkaisummit has some heavy hitters, e.g. Turing Award winners! Don’t miss insights from @databricks, @netflix, @stanford, @facebook, @google, @UCBerkeley. It’s all taking place in San Francisco April 23 - 25. Register today: dbricks.co/SAISReg
-
Reynold Xin reposted
Daniel Lemire
@lemire
All programmers should stay away from sharp knives most of the time. Most programmers should stay away from sharp knives all of the time. But we need some people to handle the scary blades or else our software stack will stagnate.
-
Reynold Xin reposted
Ken Jones
@KenJonesCA
Join us at #sparkaisummit next month for the Women in #unifiedanalytics event where women leaders from @Netflix, @LinkedIn, @Google, @Databricks, @Workday and @Stanford share experiences in data science and engineering dbricks.co/womeninua #apachespark #womeninai
-
Reynold Xin reposted
SwiftOnSecurity
@SwiftOnSecurity
Google #stadia is proof that with hundreds of computer science PhDs on staff you can get video games to run on Linux.
-
Reynold Xin reposted
Rick Schultz
@ricksschultz
Packed house to see @rxin talk about unifying data teams and Data + #machinelearning at #gartnerda #databricks #unifiedanalytics
-
Reynold Xin reposted
Databricks
@databricks
A diverse group of #ai innovators will present at #sparkaisummit next month in San Francisco. #iwd2019 Highlight: Keynoter, Timnit Gebru, a Researcher at Stanford University #balanceforbetter #womeninai #iwd2019 Discount Code - TODAY ONLY: WomensDay30
-
Reynold Xin reposted
João Pedro Martins 🇪🇺🇵🇹 🇺🇦
@lokijota
"Databricks-Connect is here! You can download here. It allows you to develop using an IDE like VSCode, PyCharm, IntelliJ etc and connect to a remote Databricks cluster to execute the task". A very welcome preview! datathirst.net/blog/2019/3/7/databricks-connect-finally?_…
-
Reynold Xin reposted
Databricks
@databricks
Catch a preview of @rxin's keynote for @SparkAISummit! Join us for the preview webinar: dbricks.co/2tReNCJ
-
Reynold Xin
@rxin
Speedy Scala Builds with Bazel at Databricks databricks.com/blog/2019/02/27/speedy-scala-builds-with-b…
-
Reynold Xin reposted
Adnan Hashmi (عدنان ھاشمی)
@adnan_hashmi
Stream processing pipeline using #azure Event Hubs, #databricks, and #cosmosdb
learn.microsoft.com/en-us/azure/architecture/reference-ar… -
Reynold Xin reposted
Roman Thompson
@romanjthompson
How to Work with Avro, Kafka, and Schema Registry in Databricks - The Databricks Blog www.databricks.com/blog/2019/02/15/how-to-work-with-avro-…
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Today is the last day to save with early bird pricing! Don't miss out on over 130 community sessions and a keynote lineup featuring @matei_zaharia @rxin @timnitGebru Caitlin Smallwood, Dave Patterson and more! Register today and save! databricks.com/sparkaisummit/north-america
-
Reynold Xin reposted
Jordan Novet
@jordannovet
in the old days, @bhorowitz said, it was scary to introduce a company to Microsoft. but he told Satya about Databricks a few years ago, and Microsoft became a great partner for Databricks. now Microsoft has invested www.cnbc.com/2019/02/04/microsoft-invests-in-databricks-f…
-
Reynold Xin reposted
João Pedro Martins 🇪🇺🇵🇹 🇺🇦
@lokijota
Probably the shortest page I've ever linked to: here's how to link Databricks to Azure DevOps for source control. Couldn't be simpler. :-) #databricks #azure docs.azuredatabricks.net/user-guide/notebooks/azure-devop…
-
Reynold Xin reposted
Business Insider
@BusinessInsider
Artificial intelligence startup Databricks is now worth $2.75 billion after raising $250 million from Andreessen Horowitz and Microsoft www.businessinsider.com/databricks-2-billion-plus-valuati…
-
Reynold Xin
@rxin
Introducing Built-in Image Data Source in Apache Spark 2.4
databricks.com/blog/2018/12/10/introducing-built-in-image… Super useful for data science and machine learning on large sets of images! -
Reynold Xin
@rxin
Longest line I have seen at SFO. And this is the pre line...
-
Reynold Xin reposted
Patrick Wendell
@pwendell
We are hiring a senior data engineer to help scale our data pipelines @databricks. Work with the creators of #apachespark, #mlflow, etc. Apply here: databricks.com/company/careers?gh_jid=4103098002
-
Reynold Xin
@rxin
Apache Spark 2.4 is now available on Databricks. Here's the blog describing the exciting new features databricks.com/blog/2018/11/08/introducing-apache-spark-2… and a notebook showing how to use higher order functions to manipulate nested data databricks-prod-cloudfront.cloud.databricks.com/public/40…
-
Reynold Xin reposted
Kristalle
@KristalleCooks
@databricks Delta + #mlflow gives ability to time travel! #sparkaisummit keynote demo by @michaelarmbrust
-
Reynold Xin reposted
Steven Uzan
@stevenuzan
Spark: how Data Exchange became much faster at @SparkAISummit #databricks
-
Reynold Xin reposted
Jacek Laskowski
@jaceklaskowski
“Please don't blame @rxin for this! He was just moving code around!” github.com/apache/spark/blob/master/sql/hive/src/main/sca… #apachespark #sparksql #happymonday
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
@databricks @rxin charts the history of @ApacheSpark @SparkAISummit keynote, and shares what’s ahead in making #deeplearning frameworks integrated w/ project hydrogen
-
Reynold Xin reposted
Kristalle
@KristalleCooks
@rxin shares the evolution of #apachespark at #sparkaisummit
-
Reynold Xin reposted
Databricks
@databricks
Simplify #marketbasketanalysis using FP-growth on #databricks databricks.com/blog/2018/09/18/simplify-market-basket-ana…
-
Reynold Xin reposted
Databricks
@databricks
Watch @rxin 's keynote at #sparkaisummit on the introduction of Project Hydrogen: State-of-the-Art Deep Learning on #apachespark databricks.com/sparkaisummit/europe
-
Reynold Xin reposted
Databricks
@databricks
Identifying Suspicious Behavior in Video with Databricks Runtime for #machinelearning databricks.com/blog/2018/09/13/identify-suspicious-behavi… #keras #tensorflow #sparkdlpipelines
-
Reynold Xin reposted
KDnuggets
@kdnuggets
Project Hydrogen, new initiative based on Apache Spark to support #ai and #datascience @rxin www.kdnuggets.com/2018/08/databricks-project-hydrogen-apa…
-
Reynold Xin reposted
Databricks
@databricks
Loan Risk Analysis with #xgboost and Databricks Runtime for Machine Learning databricks.com/blog/2018/08/09/loan-risk-analysis-with-xg… #ml #mllib
-
Reynold Xin reposted
Databricks
@databricks
Processing Petabytes of Data in Seconds with Databricks Delta #apachespark #databricksdelta #structuredstreaming #sparksql databricks.com/blog/2018/07/31/processing-petabytes-of-da…
-
Reynold Xin
@rxin
Make Your Oil and Gas Assets Smarter by Implementing Predictive Maintenance with Databricks www.databricks.com/blog/2018/07/19/make-your-oil-and-gas-… #machinelearning #sparkstreaming
-
Reynold Xin
@rxin
Early bird pricing ends on Friday for #sparkaisummit, register now to save £300! databricks.com/sparkaisummit/europe
-
Reynold Xin
@rxin
Apache Spark clusters on autopilot! databricks.com/blog/2018/07/17/apache-spark-clusters-in-a…
-
Reynold Xin reposted
Jingang
@Jingang98732471
第一次上推特,希望认识更多的折纸爱好者。
发发最近的作品吧。
shuki kato 骆驼
kamiya satoshi 寄居蟹 猛犸象
VOG2 剑鱼 -
Reynold Xin
@rxin
Yellow sky in San Francisco due to Yolo county fire.
-
Reynold Xin
@rxin
At Databricks we write thousands of jsonnet files. Here's an IntelliJ jsonnet plugin we wrote to increase developers' productivity github.com/databricks/intellij-jsonnet
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
If you missed @SparkAISummit by @databricks @rxin keynote watch @ApacheSpark journey & foray into new frontiers: open-source Project Hydrogen: all distributed machine learning frameworks on @ApacheSpark as first-class-citizens vimeo.com/274267107
-
Reynold Xin reposted
Jeffrey G. Reid
@jgreid
Interested in large-scale genomics, drug discovery, data engineering, and cat pictures???
Then you should check out my @Databricks Spark+AI 2018 keynote on the @Regeneron Genetics Center efforts to build the future of drug discovery...
vimeo.com/274274654 -
Reynold Xin reposted
Mate Gulyas
@gulyasm
Interesting start of the day: Listening to challenges in DNA sequencing at #sparksummit and how Spark and @databricks can help
-
Reynold Xin reposted
Michael Ortega
@MichaelOrtegaSF
"We've built #genomic-specific optimizations to increase the scale and lower the run time of tasks by up to 100x helping acclerate critical research" Ion Stoica cofounder of @Databricks launches the first Unified Analytics Platform for Genomics #sparkaisummit #machinelearning
-
Reynold Xin
@rxin
Check out MLflow, a new open source machine learning platform for managing the complete machine learning lifecycle: databricks.com/blog/2018/06/05/introducing-mlflow-an-open…
-
Reynold Xin reposted
Jimmy Wahl
@ygemara
Amazing to see how AI is making a real difference in people's lives #sparkaisummit
-
Reynold Xin reposted
Arsen Vladimirskiy
@ArsenVlad
Reynold Xin @rxin talks #spark history and Lester and Netflix prize in 2009 at #sparkaisummit
-
Reynold Xin reposted
Lan Jiang
@Lan_Jiang
A full wall of great sessions @databricks #sparkaisummit #apachespark
-
Reynold Xin reposted
John Ousterhout
@JohnOusterhout
I'm excited to announce that I have just published the first edition of a new book on software design. The book is based on material from a software design class I have been teaching at Stanford over the last few years:
www.amazon.com/Philosophy-Software-Design-John-Ousterhout… -
Reynold Xin reposted
Rick Schultz
@ricksschultz
Lots of great keynotes at @SparkAISummit this wk: @pmarca, @matei_zaharia @michaelijordan @dawnsongtweets @karpathy and @rxin plus #apachespark & #databricks use cases by Apple, Capital One, Bechtel, Overstock and FINRA: www.youtube.com/@Databricks/search?query=Spark+%2B+AI+Sum…
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
#sparkaisummit is almost sold out. Join experts from @amazon @LinkedIn @Indeed @Tesla @Target @Netflix @Intel @Microsoft and more. Act fast, sign up today to save your spot. databricks.com/sparkaisummit
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
Bay Area Apache Spark Meetup hits 10001 Members (this is not in binary!) Thanks to the community!
#basm #apachespark @matei_zaharia @rxin @andykonwinski @pwendell -
Reynold Xin reposted
Weihan Wang
@weihanwang
Distributed Systems: Theory vs. Reality
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
#sparkaisummit features deep dive sessions on popular software frameworks like TensorFlow, SciKit-Learn, Keras, PyTorch, DeepLearning4J, BigDL, & Deep Learning Pipelines. Don’t miss out! databricks.com/sparkaisummit
-
Reynold Xin reposted
Databricks
@databricks
Introducing Pandas UDF for PySpark: How to run your native Python code with #pyspark, fast. www.databricks.com/blog/2017/10/30/introducing-vectorized…
-
Reynold Xin reposted
Databricks
@databricks
Introducing Data Brick™: The Building Block of DataBricks' Unified Analytics Platform #databricks #apachespark dbricks.co/2GGBt0i
-
Reynold Xin reposted
Reynold Xin
@rxin
New open source project from Databricks: Click is an open-source tool that lets you quickly and easily run commands against Kubernetes resources, without copy/pasting all the time, and that easily integrates into your existing command line workflows.
databricks.com/blog/2018/03/27/introducing-click-the-comm… -
Reynold Xin reposted
Databricks
@databricks
Introducing Stream-Stream Joins in Apache Spark 2.3: Now Available on Databricks Runtime 4.0 #structuredstreaming www.databricks.com/blog/2018/03/13/introducing-stream-str…
-
Reynold Xin
@rxin
New open source project from Databricks: Click is an open-source tool that lets you quickly and easily run commands against Kubernetes resources, without copy/pasting all the time, and that easily integrates into your existing command line workflows.
databricks.com/blog/2018/03/27/introducing-click-the-comm… -
Reynold Xin
@rxin
Continuous Processing Mode in Apache Spark's Structured Streaming databricks.com/blog/2018/03/20/low-latency-continuous-pro… … millisecond low-latency - one of the most exciting changes in Spark land this year!
-
Reynold Xin reposted
Databricks
@databricks
Introducing Low-Latency Continuous Processing Mode in Structured Streaming in Apache Spark 2.3.0 #apachespark www.databricks.com/blog/introducing-real-time-mode-apache…
-
Reynold Xin
@rxin
Continuous Processing Mode in Apache Spark's Structured Streaming databricks.com/blog/2018/03/20/low-latency-continuous-pro… millisecond low-latency - one of the most exciting changes in Spark land this year!
-
Reynold Xin
@rxin
Register by Friday to save up to $400 for @SparkAISummit. Join me June 4-6 in San Francisco to hear about all the exciting updates for #apachespark and what leading companies are doing with artificial intelligence. www.databricks.com/sparkaisummit.
-
Reynold Xin
@rxin
Really bad for Canada. Top steel & aluminum exporter to the US. www.trade.gov/steel/countries/pdfs/imports-us.pdf
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
#apachespark 2.3 is out! A blog post from on some of the key features: databricks.com/blog/2018/02/28/introducing-apache-spark-2… or download it at spark.apache.org
-
Reynold Xin reposted
Databricks
@databricks
Introducing Apache Spark 2.3: Now Available on Databricks Runtime 4.0 Beta
dbricks.co/2t6usAt -
Reynold Xin
@rxin
Introducing Apache Spark 2.3
databricks.com/blog/2018/02/28/introducing-apache-spark-2… -
Reynold Xin reposted
Databricks
@databricks
ICYMI: Introducing Vectorized UDFs for PySpark dbricks.co/2DCFcYR
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
.@databricks Xiao Li shares what’s in the upcoming #apachespark 2.3 & DBR 4.0 2/2
-
Reynold Xin reposted
William Vambenepe
@vambenepe
Looks like the local cafe is trying to raise VC money.
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
I'm hosting a webinar on Jan 31st about Big Data and AI Predictions for 2018. How much is hype and what will really impact industries? Sign up at dbricks.co/2AwtvzF.
-
Reynold Xin reposted
Databricks
@databricks
Take an in-depth look at #meltdown and #spectre to learn how they can be fixed and how they impact Databricks security and performance. dbricks.co/2DFaPks
-
Reynold Xin reposted
Databricks
@databricks
Meltdown and Spectre’s Performance Impact on Big Data Workloads in the Cloud dbricks.co/2DaaeGy
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Nice post from @Databricks engineering on the impact of Meltdown and Spectre fixes on big data workloads in AWS: databricks.com/blog/2018/01/13/meltdown-and-spectre-perfo…
-
Reynold Xin
@rxin
AWS hypervisor updates in response to Meltdown & Spectre seem to have reduced performance by 3 to 5% for @ApacheSpark workloads. databricks.com/blog/2018/01/13/meltdown-and-spectre-perfo…
-
Reynold Xin reposted
Databricks
@databricks
Databricks Runtime’s New DBIO Cache Boosts #apachespark Performance: Why NVMe SSDs improve caching performance by 10x dbricks.co/2meuaAy
-
Reynold Xin
@rxin
Databricks' latest NVMe cache can improve Apache Spark workloads performance by 10X! databricks.com/blog/2018/01/09/databricks-runtimes-new-db…
-
Reynold Xin reposted
Databricks
@databricks
The Architecture of the Next @CERN Accelerator Logging Service: CERN Big Data (900 GB/day) at Scale with #apachespark dbricks.co/2jUjgQh
-
Reynold Xin reposted
Databricks
@databricks
Learn how transparent autoscaling of instance storage helps you focus on data, not resource constraints dbricks.co/2iB4LzJ
-
Reynold Xin reposted
Databricks
@databricks
Spark Summit is Becoming the Spark + AI Summit #apachespark #ai @SparkAISummit dbricks.co/2zUJ7NW
-
Reynold Xin reposted
Databricks
@databricks
Women in Big Data, Apache Spark and AI: Bay Area Spark Meetup @databricks Summary: With presentation slides and videos #womenintech #100women
dbricks.co/2zJA1Yx -
Reynold Xin reposted
Azure SQL DW
@AzureSQLDW
Microsoft and @databricks announcing Spark as a service in @Azure, natively optimized and integrated with #azuredw SQL, Azure Storage, Azure Cosmos DB, Azure Active Directory and Power BI, #msconnect
-
Reynold Xin reposted
Maxime Rouiller
@MaximRouiller
Wow. Azure @Databricks is currently blowing my mind. 😮😮 #msftconnect
-
Reynold Xin reposted
Databricks
@databricks
Watch the Microsoft Azure Databricks demo video and see how easily your data scientists, data engineers and business users can collaborate dbricks.co/2zGoEiU
-
Reynold Xin reposted
Databricks
@databricks
Announcing Microsoft Azure Databricks! A fast, easy and collaborative Apache® Spark™ based analytics platform optimized for Azure. dbricks.co/2A0HQbU #analytics #azure
-
Reynold Xin reposted
Adriaan Moors
@adriaanm
Recent Scala 2.12 compiler does 3300 line/s on an i7-6700. Benchmark that compiles 120 KLoC (std lib + compiler) takes 35s. Only applies to hot compiler; another good reason to stay in sbt shell! scala-ci.typesafe.com/grafana/dashboard/db/scala-benchmar…
-
Reynold Xin reposted
Databricks
@databricks
Introducing Vectorized UDFs for #pyspark #apachespark dbricks.co/2yalEYd
-
Reynold Xin reposted
Paul Pearce
@paul_pearce
Looks like we all have 280 now. Sweet!
-Paul
This tweet is solely for the confidential use of the recipient. This message contains confidential and proprietary information that may not be read, searched, distributed or otherwise used by anyone other than the intended recipient. -
Reynold Xin reposted
Databricks
@databricks
Introducing Command Line Interface for Databricks Developers: Work easily with Databricks File System and Workspace dbricks.co/2hdJ9Zv
-
Reynold Xin reposted
Databricks
@databricks
Introducing Vectorized UDFs for #pyspark: How to run your native Python code with PySpark, fast. #python dbricks.co/2z2PLEl
-
Reynold Xin reposted
Sundar Pichai
@sundarpichai
Will drop everything else we are doing and address on Monday:) if folks can agree on the correct way to do this!
Thomas Baekdal
@baekdal
I think we need to have a discussion about how Google's burger emoji is placing the cheese underneath the burger, while Apple puts it on top
-
Reynold Xin reposted
Rick Schultz
@ricksschultz
.@CERN ran its own Big Data benchmark #sparksummit
-
Reynold Xin reposted
Bharath Gowda
@bgowda
@Nielsen is scaling data science with @databricks unified analytics platform #sparksummit
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Excited to announce Databricks Delta: a storage system that combines the best of data lakes, warehouses & streaming: www.databricks.com/blog/2017/10/25/databricks-delta-a-uni…
-
Reynold Xin
@rxin
#sparksummit EU begins in a week. Join us in Dublin to hear the latest advancements on #apachespark. spark-summit.org/eu-2017.
-
Reynold Xin reposted
Databricks
@databricks
Data scientists: Get a free exclusive preview of select chapters from the upcoming definitive guide for #apachespark
dbricks.co/2fJLYAQ -
Reynold Xin
@rxin
Accelerating R Workflows on Databricks databricks.com/blog/2017/10/06/accelerating-r-workflows-o…
-
Reynold Xin reposted
Databricks
@databricks
Building Complex Data Pipelines with Unified Analytics Platform #databricks #apachespark dbricks.co/2y3EGT1
-
Reynold Xin reposted
Databricks
@databricks
Learn about #apachespark’s Memory Model and Spark’s State in the Cloud @Spark_Summit dbricks.co/2wwAPOV
-
Reynold Xin reposted
Databricks
@databricks
Get an exclusive preview of the upcoming definitive guide for #apachespark for free dbricks.co/2j0vTv4
-
Reynold Xin reposted
Databricks
@databricks
Get an exclusive preview of the upcoming definitive guide for #apachespark for free dbricks.co/2vK8UIY
-
Reynold Xin reposted
Herman van Hovell
@Westerflyer
Early bird pricing for @Spark_Summit ends on Aug 25, register now and save €200! spark-summit.org/eu-2017
-
Reynold Xin reposted
Beau Cronin
@beaucronin
I know I'm not the first to say it, but man has twitter helped a lot of folks become good, punchy writers
-
Reynold Xin
@rxin
Early bird pricing for @Spark_Summit ends on Aug 25, register now and save €200! spark-summit.org/eu-2017
-
Reynold Xin reposted
Databricks
@databricks
Watch today’s @BloombergTV interview regarding the future of #ai and Databricks dbricks.co/2wlzRUv
-
Reynold Xin reposted
Databricks
@databricks
Databricks Cited As A Strong Performer by @Forrester in Insight PaaS Category #forresterwave dbricks.co/2vBi0sl
-
Reynold Xin reposted
Ben Lorica 罗瑞卡
@bigdata
.@CSIROnews @databricks: Breaking the “curse of dimensionality” in Genomics using “wide” Random Forests @ApacheSpark goo.gl/6EiwuQ
-
Reynold Xin reposted
Herman van Hovell
@Westerflyer
Matei kicking off the Amsterdam Spark meetup @databricks @matei_zaharia
-
Reynold Xin reposted
Databricks
@databricks
“AI has a 1% problem” says @databricks CEO Ali Ghodsi "There are only about 5 cos who are truly conducting AI today” dbricks.co/2vMLgtx
-
Reynold Xin reposted
Databricks
@databricks
Learn how to easily set up #apacheairflow and trigger #databricks workloads
dbricks.co/2vjkN6L -
Reynold Xin reposted
Databricks
@databricks
Benchmarking Big Data SQL Platforms in the Cloud #apachespark #databricksruntime dbricks.co/2tenGDh by @databricks
-
Reynold Xin reposted
Databricks
@databricks
Introducing Apache Spark 2.2: Now available on Databricks Runtime 3.0 #apachespark
dbricks.co/2t1DLRD -
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
A tutorial on 4 #sql High-Order & Lambda Functions to Examine Structured Data in #databricks
databricks.com/blog/2017/06/27/4-sql-high-order-lambda-fu… -
Reynold Xin reposted
Databricks
@databricks
On-Demand Webinar and FAQ: #apachespark MLlib 2.x: How to Productionize your Machine Learning Models
dbricks.co/2tYjbOc -
Reynold Xin reposted
Databricks
@databricks
Declarative Infrastructure with #jsonnet Templating Language: How #databricks Provisions Infrastructure #kubernetes
dbricks.co/2sTHxcw -
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Only 2 more days to submit a talk to Spark Summit EU! ssum.it/2tiisXB
-
Reynold Xin reposted
Reynold Xin
@rxin
Apache Spark: The Definitive Guide by @databricks ready for FREE preview: databricks.com/blog/2017/06/05/sharing-knowledge-communit… just in time for @spark_summit
-
Reynold Xin reposted
Dave Nielsen
@davenielsen
"When you can do things 10, 20, 30x cheaper, you discover you can do new things" via @edd #sparksummit
-
Reynold Xin reposted
Emerson Castaneda S
@emecas
NP Complexity - People Problem, Process Problem & Platform Problem solves by @databricks with its Unified Analytics Platform #sparksummit
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Our keynote on deep learning and low-latency streaming in #apachespark is now up: www.youtube.com/watch?v=qAZ5XUz32yM #sparksummit
-
Reynold Xin reposted
Michael Armbrust
@michaelarmbrust
In case you missed today's demo on #structuredstreaming performance at #sparksummit, here is the video! #endofmicrobatch
Databricks
@databricks
Watch today's demo by @michaelarmbrust on new developments in #structuredstreaming from Databricks #sparksummit dbricks.co/2sAKv5f
-
Reynold Xin reposted
Databricks
@databricks
A Vision for Making #deeplearning Simple: From machine learning practitioners to business analysts dbricks.co/2s0vZqb
-
Reynold Xin reposted
Databricks
@databricks
Making #apachespark the Fastest Open Source Streaming Engine dbricks.co/2scZ69J
-
Reynold Xin reposted
Bhasker Allene
@bhaskerallene
During demo, when latency drops from 1 second to less than 10 milliseconds ... audience clap! This is opera for geeks #sparksummit
-
Reynold Xin reposted
Eyeview
@EyeviewDigital
New Continuous Streaming engine low latency is "fast enough to catch James Bond" - @michaelarmbrust #sparksummit
-
Reynold Xin reposted
Jay Mitra
@jaymitra
My kind of demo...classifying James Bond 007 cars using @databricks new deep learning pipeline here at #sparksummit 2017 by Tim Hunter.
-
Reynold Xin reposted
Taro L. Saito
@taroleo
Databrics’s UI is getting better and better every year for this kind of demos #sparksummit
-
Reynold Xin reposted
Fabian Schreiber
@Fabschreiber
#sparksummit: < 1ms latency in future Spark release. #realtime
-
Reynold Xin reposted
Daniel San
@danielx
#sparksummit the easiest streaming processing framework is now the fastest @michaelarmbrust
-
Reynold Xin reposted
Conor
@ConorBMurphy
Streaming at 65m records/sec with structure steaming #sparksummit
-
Reynold Xin reposted
Taro L. Saito
@taroleo
-
Reynold Xin reposted
Edd Wilder-James
@edd
Integrating deep learning models as UDFs in SQL is pretty cool #sparksummit
-
Reynold Xin reposted
GigaSpaces Technologies
@GigaSpaces
Hello #sparksummit2017 :) Kicking it off with @rxin... Here we go! #sparksummit #apachespark
-
Reynold Xin reposted
Bhasker Allene
@bhaskerallene
Wow! Spark can be used to track James Bond using image clarification.. MI16 doesn't like this. #sparksummit
-
Reynold Xin reposted
Michael Greene
@greene1of5
Back stage getting ready for my #sparksummit keynote in few min ... spark-summit.org/2017/speakers/michael-greene/
-
Reynold Xin reposted
Alexis Roos
@alexisroos
@matei_zaharia introducing Deep Learning pipelines @spark_summit
-
Reynold Xin reposted
Fer Otero【🆉🄴🅾🅂】
@fotero
Pip install pyspark ❤️ #sparksummit
-
Reynold Xin reposted
Jean-Georges Perrin
@jgperrin
#deeplearning announced as #opensource initiative from @databricks on #apachespark @ #sparksummit
-
Reynold Xin reposted
((( matt hunt )))
@instantmatthew
watching the opening of the tenth Spark Summit. tenth!
Tempus fugit. sustained effort is how ideas become real.
#sparksummit -
Reynold Xin reposted
Simeon Simeonov
@simeons
@rxin kicks off #sparksummit
-
Reynold Xin reposted
Conor
@ConorBMurphy
The creator himself @matei_zaharia at #sparksummit
-
Reynold Xin
@rxin
Apache Spark: The Definitive Guide by @databricks ready for FREE preview: databricks.com/blog/2017/06/05/sharing-knowledge-communit… just in time for @spark_summit
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
#sparksummit 2017 kicks off tomorrow in SF. See you there! #apachespark
-
Reynold Xin reposted
Databricks
@databricks
ICYMI: Statistical and Mathematical Functions with DataFrames in Apache Spark dbricks.co/2rbhS19
-
Reynold Xin reposted
Databricks
@databricks
Benefit from what Databricks has learned while helping hundreds of customers use #apachespark: dbricks.co/2rFwHJw #sparksummit
-
Reynold Xin reposted
Julian Hyde
@julianhyde
Lambdas in Spark SQL databricks.com/blog/2017/05/24/working-with-nested-data-u…
-
Reynold Xin
@rxin
Top 5 Reasons for Choosing S3 over HDFS databricks.com/blog/2017/05/31/top-5-reasons-for-choosing…
-
Reynold Xin
@rxin
Entropy-based Log Redaction for Apache Spark on Databricks databricks.com/blog/2017/05/30/entropy-based-log-redactio…
-
Reynold Xin reposted
Databricks
@databricks
sparklyr now available in Databricks. Try it now dbricks.co/2rZbgPy
-
Reynold Xin
@rxin
Super useful feature when working with nested (array) data in SQL: databricks.com/blog/2017/05/24/working-with-nested-data-u…
-
Reynold Xin
@rxin
Databricks Runtime 3.0 Beta Delivers Cloud Optimized Apache Spark databricks.com/blog/2017/05/24/databricks-runtime-3-0-bet…
-
Reynold Xin reposted
Databricks
@databricks
Running Streaming Jobs Once a Day for 10x Cost Savings: Part 6 of Scalable Data @ Databricks dbricks.co/2qcisGN
-
Reynold Xin reposted
Peter Bailis
@pbailis
2017 Jim Gray Award Talk: Coordination Avoidance in Distributed Databases speakerdeck.com/futuredata/2017-jim-gray-award-talk-coord… (deck) www.youtube.com/watch?v=HDeoOhLqUqk&t=7m49s (audio)
-
Reynold Xin reposted
Databricks
@databricks
Join 3,000 #apachespark enthusiasts, June 5-7 in San Francisco, to celebrate the 10th edition of #sparksummit: dbricks.co/2pDWiBH
-
Reynold Xin reposted
Databricks
@databricks
New Databricks feature: Persistent Clusters to simplify cluster management for analytics. Read the blog: dbricks.co/2pSS1e6
-
Reynold Xin reposted
Databricks
@databricks
Taking #apachespark’s #structuredstreaming to Production: Part 5 of scalable data at #databricks dbricks.co/2riGlkL
-
Reynold Xin reposted
Tech At Bloomberg
@TechAtBloomberg
WATCH: @EmilyChangTV chats w/ Jian-Yang about his "Not Hotdog" app.
Download it today (really): seefoodtechnologies.com #siliconvalleyhboThis media couldn't be displayed. See it on the original post. -
Reynold Xin reposted
Philipp Haller
@philippkhaller
Very excited that Reynold Xin (@rxin) is going to give a keynote at the #scala Symposium! #scala17 #splash17 /cc @scala_symposium
-
Reynold Xin
@rxin
Someone Is Spreading a Massive Google Doc Phishing Email Right Now
motherboard.vice.com/en_us/article/massive-gmail-google-d… -
Reynold Xin
@rxin
"You are not going to believe what I'm about to tell you" theoatmeal.com/comics/believe
-
Reynold Xin reposted
Amazon Web Services
@awscloud
Driving #bigdata Innovation on AWS: ISV Highlights on APN Blog feat. @databricks @alteryx @SnapLogic @TreasureData ! oak.ctx.ly/r/5m6u5
-
Reynold Xin reposted
Reynold Xin
@rxin
We are hiring a site manager to grow our engineering office and build the strongest team in Amsterdam! www.linkedin.com/jobs/view/276322554
-
Reynold Xin reposted
Databricks
@databricks
ICYMI: Working with Complex Data Formats with #structuredstreaming on #apachespark 2.1 dbricks.co/2pPPVuX
-
Reynold Xin
@rxin
We are hiring a site manager to grow our engineering office and build the strongest team in Amsterdam! www.linkedin.com/jobs/view/276322554
-
Reynold Xin reposted
Databricks
@databricks
Join us for a webinar on workflows and best practices for #deeplearning, #tensorflow, and #apachespark dbricks.co/2paQBrL
-
Reynold Xin reposted
Databricks
@databricks
Get best practices for deploying @ApacheSpark at scale during #sparksummit 2017’s Enterprise Day: dbricks.co/2paRGj2 #apachespark
-
Reynold Xin reposted
Databricks
@databricks
Learn how to terminate your runaway Spark SQL queries using Query Watchdog: dbricks.co/2omDVfc
-
Reynold Xin reposted
Databricks
@databricks
Processing Data in #apachekafka with Structured Streaming in #apachespark 2.2 dbricks.co/2piFxbV
-
Reynold Xin reposted
Databricks
@databricks
Improve your #apachespark skills. Take our new 2-day Data Engineering training course at #sparksummit 2017: dbricks.co/2oLpJB6
-
Reynold Xin reposted
Jason O. Gilbert
@gilbertjasono
Huh, never noticed these options on the United website until this morning
-
Reynold Xin reposted
Databricks
@databricks
#sparksummit 2017 is < 2 months away! Register now to secure your spot at the world's largest #apachespark event. dbricks.co/2oNHI9R
-
Reynold Xin reposted
Databricks
@databricks
Learn how to build a real-time end-to-end integration with #apachekafka in #apachespark’s Structured Streaming dbricks.co/2nApZxS
-
Reynold Xin reposted
Databricks
@databricks
Apache Spark ranks #8 on the BOSS index #oss dbricks.co/2pmBWsq
-
Reynold Xin
@rxin
Next Generation Physical Planning in Apache Spark databricks.com/blog/2017/04/01/next-generation-physical-p…
-
Reynold Xin reposted
Databricks
@databricks
Community Voice: Analyse One Year of Radio Station Songs Aired with Apache Spark, Spark SQL, Spotify, and Databricks dbricks.co/2o2ea87
-
Reynold Xin reposted
Edd Wilder-James
@edd
Exciting news! I'm co-chairing Spark Summit 2017 in San Francisco, joining @rxin svds.com/spark-summit-ignition-enterprise/
-
Reynold Xin reposted
Werner Vogels
@Werner
Summary of the Amazon S3 Service Disruption in the Northern Virginia (US-EAST-1) Region aws.amazon.com/message/41926/
-
Reynold Xin reposted
Databricks
@databricks
Voice from @Facebook: Using #apachespark for Large-Scale Language Model Training dbricks.co/2lkpabl
-
Reynold Xin
@rxin
Working with complex / nested data in Structured Streaming in @ApacheSpark and @databricks databricks.com/blog/2017/02/23/working-complex-data-forma…
-
Reynold Xin
@rxin
Processing a billion rows a sec isn't cool anymore. You know what's cool? Processing a trillion rows a sec. databricks.com/blog/2017/02/16/processing-trillion-rows-p…
-
Reynold Xin
@rxin
My answer to Is it possible to build a framework like Apache Spark in Kotlin? www.quora.com/Is-it-possible-to-build-a-framework-like-Ap…
-
Reynold Xin reposted
Databricks
@databricks
Working with Complex Data Formats with #structuredstreaming in #apachespark 2.1 dbricks.co/2mgH4gW
-
Reynold Xin reposted
Reynold Xin
@rxin
A look under the hood at Apache Spark's API and engine evolutions - my Amsterdam meetup talk slides online www.slideshare.net/databricks/a-look-under-the-hood-at-ap…
-
Reynold Xin reposted
Databricks
@databricks
Processing trillion rows per second on a single machine: how can nested loop joins be this fast? #apachespark dbricks.co/2kX8bib
-
Reynold Xin reposted
Databricks
@databricks
Enable #healthit innovation with #apachespark #machinelearning: How to Anonymize Datasets on Databricks dbricks.co/2kpiUyt
-
Reynold Xin reposted
Databricks
@databricks
Another record-setting Spark Summit in Boston: A recap of Databricks keynotes and sessions dbricks.co/2k9zC4Z #sparksummit #apachespark
-
Reynold Xin
@rxin
A look under the hood at Apache Spark's API and engine evolutions - my Amsterdam meetup talk slides online www.slideshare.net/databricks/a-look-under-the-hood-at-ap…
-
Reynold Xin reposted
Dmitriy Ryaboy 🇺🇸🇮🇱
@squarecog
Twitter's biggest contribution to CS will be the thousands of "sentiment detection on Twitter" projects that undergrads keep churning out.
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
My talk from #sparksummit is online: go.databricks.com/videos/spark-summit-east-2017/what-to-e… (video), www.slideshare.net/databricks/spark-summit-east-2017-mate… (slides). Thanks to our super fast event team!
-
Reynold Xin reposted
Amsterdam Data Science
@ams_ds
Tomorrow 18:00 @GoDataDriven: @rxin will present on history & evolution of data processing software #apachespark @databricks
Reynold Xin
@rxin
Next Wed, we will give two meetup talks on Spark to celebrate the opening of Databricks Amsterdam R&D center www.meetup.com/Amsterdam-Spark/events/237396696/
-
Reynold Xin reposted
Databricks
@databricks
Join @rxin and @Westerflyer for tech-talks at the Amsterdam #apachespark Meetup on Feb 8: dbricks.co/2kwUtCT
-
Reynold Xin reposted
TrumpDBA
@TrumpDBA
I've just signed an executive order eliminating foreign keys from databases forever. Use AMERICAN KEYS instead! ACTION!
-
Reynold Xin
@rxin
Next Wed, we will give two meetup talks on Spark to celebrate the opening of Databricks Amsterdam R&D center www.meetup.com/Amsterdam-Spark/events/237396696/
-
Reynold Xin
@rxin
Next Wed, we will give two meetup talks on Spark to celebrate the opening of Databricks Amsterdam R&D center www.meetup.com/Amsterdam-Spark/events/233817214/
-
Reynold Xin reposted
Databricks
@databricks
Integrating Your Central Hive Metastore with #apachespark on Databricks dbricks.co/2jKQWQE
-
Reynold Xin reposted
Databricks
@databricks
InfoWorld names Databricks a "Technology of the Year" for 2017 dbricks.co/2kItIIG
-
Reynold Xin
@rxin
Professor Stoica on the next AMPLab: RISELab enabling intelligent real-time decisions at @spark_summit spark-summit.org/east-2017/events/riselab-enabling-intell…
-
Reynold Xin
@rxin
Comedy Central, Nickelodeon and MTV using @databricks and Spark to monitor and improve video quality in realtime www.forbes.com/sites/bernardmarr/2017/01/26/how-mtv-and-n…
-
Reynold Xin reposted
Databricks
@databricks
Learn how @Viacom uses Databricks for real-time analytics to improve customer experience @Forbes #apachespark dbricks.co/2kxMfHI
-
Reynold Xin
@rxin
Submit your innovative data system demo to VLDB 2017 www.vldb.org/2017/cfp_demos.php
Deadline March 1st. -
Reynold Xin reposted
Databricks
@databricks
Real-time Streaming ETL with Structured Streaming in #apachespark 2.1 dbricks.co/2jL76up
-
Reynold Xin reposted
Databricks
@databricks
Real-time Streaming ETL with Structured Streaming in #apachespark 2.1: Part 1 of Scalable data @ Databricks dbricks.co/2iX3Cnd
-
Reynold Xin reposted
Databricks
@databricks
We are expanding internationally to embrace the growing demand for Apache Spark. Learn more here: dbricks.co/2iCVi8w
-
Reynold Xin reposted
Databricks
@databricks
Here are five reasons why you should attend #sparksummit East in Boston next month: dbricks.co/2jf9RRt
-
Reynold Xin reposted
Databricks
@databricks
5 talks to attend at @Spark_Summit featuring #apachespark innovators from @Databricks, @Salesforce, and @MHEducation dbricks.co/2iW3xyn
-
Reynold Xin reposted
Mike Gualtieri
@mgualtieri
Hey everyone - @spark_summit is in my hometown - Boston - Feb 7-9. I want to meet you! Come hear my keynote on #ai spark-summit.org/east-2017/speakers/mike-gualtieri/
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
The Call for Presentations is now open for Spark Summit 2017 in San Francisco, June 5-7: ssum.it/2jgBTiL #apachespark
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Discover new directions in #pyspark for time series analysis from @twosigma engineer David Palaitis: ssum.it/2iNOh98
-
Reynold Xin
@rxin
Spark 2016 review: SQL2003, whole-stage codegen, structured streaming, CloudSort record for most efficient engine... databricks.com/blog/2017/01/04/databricks-and-apache-spar…
-
Reynold Xin reposted
Databricks
@databricks
Databricks and Apache Spark Year in Review dbricks.co/2j4qQ88
-
Reynold Xin
@rxin
Top 10 Apache Spark Blog Posts from 2016 databricks.com/blog/2016/12/30/top-10-apache-spark-blog-p…
-
Reynold Xin
@rxin
Introducing Apache Spark 2.1: structured streaming, SQL and core APIs, and R machine learning improvements: databricks.com/blog/2016/12/29/introducing-apache-spark-2…
-
Reynold Xin reposted
Databricks
@databricks
ICYMI: $1.44 per terabyte: setting a new world record with #apachespark dbricks.co/2gMRnVR
-
Reynold Xin
@rxin
Submit to VLDB 2017 demo track to demonstrate your awesome, innovative data systems and applications www.vldb.org/2017/cfp_demos.php
-
Reynold Xin reposted
Databricks
@databricks
Tutorial on integrating popular #deeplearning frameworks with #apachespark using #gpus on Databricks dbricks.co/2i0SumV
-
Reynold Xin reposted
VideoAmp
@Video_Amp
Michael Allman describes his Spark 2.1 involvement with @Databricks in this new blog post www.databricks.com/blog/2016/12/15/scalable-partition-han…
-
Reynold Xin reposted
Daniel Lemire
@lemire
Clock of Aging May Be Reversible (New York Times) mobile.nytimes.com/2016/12/15/science/scientists-say-they…
-
Reynold Xin reposted
Databricks
@databricks
Learn how scalable partitioning in #apachespark 2.1 improves initial query latency in cloud-native architecture dbricks.co/2hpkfrq
-
Reynold Xin reposted
Databricks
@databricks
We’ve raised another round of funding to advance #datascience and #dataengineering at Scale with #apachespark dbricks.co/2hp5ODL
-
Reynold Xin reposted
Databricks
@databricks
Make developing #apachespark #scala libraries easier with Databricks: dbricks.co/2hweyIY
-
Reynold Xin reposted
Databricks
@databricks
We've updated our website with a new layout and more content - see the latest on Databricks and #apachespark dbricks.co/2gbiaQr
-
Reynold Xin reposted
Databricks
@databricks
How to build #apachespark #etl pipelines with Databricks and #apacheairflow dbricks.co/2gg7Iap
-
Reynold Xin reposted
Databricks
@databricks
We are currently looking for a rockstar Technology Evangelist to join our growing team. Apply today! dbricks.co/2gELTNc
-
Reynold Xin reposted
Databricks
@databricks
Databricks now offers a #hipaa compliant #apachespark platform in #aws: dbricks.co/2gGkuuq #healthit #medtec
-
Reynold Xin reposted
Databricks
@databricks
How To Make Your Mark As A Woman In Big Data dbricks.co/2fhQ8SX by @kmariappan
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
The agenda for #sparksummit East is ready! Take a look and join us in Boston! ssum.it/2eHOMR8
-
Reynold Xin reposted
Dino Lamela
@dinolamela
I'm looking to hire 2 contract recruiters, one sales focused and the other technical. Please send me your referrals.…www.databricks.com/company/careers

-
Reynold Xin
@rxin
Did Google just disable the ability to "revert to old chat"? That made hangout unusable for me ...
-
Reynold Xin reposted
Karthik
@karthikz
@rxin from @databricks talking about Hadoop and Spark in CS186 class @UCBerkeley
-
Reynold Xin
@rxin
$1.44/terabyte: setting a new world record with Apache Spark databricks.com/blog/2016/11/14/setting-new-world-record-a… joint effort by Alibaba, Nanjing U, and @databricks
-
Reynold Xin
@rxin
Apache Spark 2.0.2 is released. Update if you are on any 2.0.x version. spark.apache.org/downloads.html
-
Reynold Xin reposted
Dr. Ganapathi Pulipaka 🇺🇸
@gp_pulipaka
Music #recsys with the Spotify #api, #apachespark and #databricks. #bigdata #machinelearning #datascience #ai
medium.com/@polomarcus/music-recommendation-service-with-… -
Reynold Xin reposted
Dirk Van den Poel
@dirkvandenpoel
Today, we started using the @databricks platform for #bigdata #spark exercises w/ 100+ stud. www.databricks.com #apachespark #analytics
-
Reynold Xin reposted
Databricks
@databricks
We’ve launched a comprehensive guide for the Databricks Platform and #apachespark users. Check it out: dbricks.co/2fFIzok
-
Reynold Xin
@rxin
Apache Spark 1.6.3 released! spark.apache.org/downloads.html
Upgrade to 1.6.3 if you are still on the 1.6.x line. Even better, upgrade to 2.0.x! -
Reynold Xin reposted
Amazing Maps
@Amazing_Maps
China's population split in half
- -
Reynold Xin
@rxin
Scaling Spark in the real world: performance and usability - with @adriancolyer commentary in his morning paper blog.acolyer.org/2016/11/04/scaling-spark-in-the-real-wor…
-
Reynold Xin reposted
Tony Baer
@TonyBaer
Databricks announces 10x performance benchmarks on the new GPU option for its Spark cloud service hpcwire.com/bigdatawire/2016/10/27/spark-ml-runs-faster-g…
-
Reynold Xin reposted
Michael Armbrust
@michaelarmbrust
Appearing in CACM - Apache Spark: A Unified Engine for Big Data Processing
cacm.acm.org/magazines/2016/11/209116-apache-spark/fulltext -
Reynold Xin reposted
Spark Barcelona
@SparkBarcelona
.@rxin from @databricks reviewing the past, present and future of data processing engines! #spark thanks to @Trovit @la_UPC @BSC_CNS
-
Reynold Xin reposted
Databricks
@databricks
Join @timjhunter for a tech-talk at the Paris #apachespark Meetup! dbricks.co/2elDgqJ
-
Reynold Xin reposted
Databricks
@databricks
Databricks Voices From #sparksummit EU 2016: A summary of Day 2 dbricks.co/2fjkwMd
-
Reynold Xin reposted
Databricks
@databricks
GPU Acceleration in Databricks: Speeding Up #deeplearning on #apachespark dbricks.co/2dNlv1Z
-
Reynold Xin reposted
Kaarthik
@kaarthikss
Learn how Microsoft used @ApacheSpark, @apachekafka to build stream processing pipeline for Bing events #sparksummit spark-summit.org/eu-2016/events/spark-streaming-at-bing-s…
-
Reynold Xin reposted
Miel Hostens
@MielHostens
If only #spark was able to predict the exact date of birth!!! Thanks @databricks for the great opportunity to talk at #sparksummit
-
Reynold Xin reposted
Databricks
@databricks
Watch #apachespark Continuous Applications in action on Databricks - Demo from the #sparksummit in Brussels dbricks.co/2eFBi7w
-
Reynold Xin reposted
Kavitha Mariappan
@kmariappan
.@databricks exec chairman Ion Stoica introduces RiseLAB at UC Berkeley for real-time intelligent data analytics #sparksummit EU 2016
-
Reynold Xin reposted
Christian Alis
@ianalis
Analysing Brexit tweets using the new Spark APIs #sparksummit
-
Reynold Xin reposted
Tom Lous | @tomlous@mastodon.xyz
@tomlous
Real time #scala #spark coding during a keynote by Greg Owen , only @spark_summit #sparksummit #awesome
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
#sparksummit Europe kicks off tomorrow; if you can't make it in person, there will be a free stream: ssum.it/2ev3VkM
-
Reynold Xin reposted
Cheng Lian
@liancheng
Well, I thought it might be another awesome @ApacheSpark application, turned out to be a totally irrelevant thing...
Hacker News Bot
@newsycombinator
How to prevent drone crashes using SPARK (2015) blog.adacore.com/how-to-prevent-drone-crashes-using-spark
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
Stage Set: See you all at the @spark_summit next week! Don't forget to attend the Meetup in Brussels www.meetup.com/Spark-Belgium/events/234234256/ #sparksummit
-
Reynold Xin reposted
Dino Lamela
@dinolamela
#databricks is building out a Solutions Architect team www.databricks.com/company/careers
-
Reynold Xin reposted
Databricks
@databricks
Deep Dive into Catalyst Optimizer and Hands-on Lab with Databricks’ @Westerflyer at #sparksummit EU dbricks.co/2etjIDY
-
Reynold Xin reposted
Databricks
@databricks
Don’t miss Databricks Chief Technologist & #apachespark creator @matei_zaharia’s keynote at #sparksummit EU dbricks.co/2etjVHf
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Tweet your favorite @ApacheSpark use case & win a free ticket to #sparksummit in Brussels! #sparksummitcontest ssum.it/2ejphWU
-
Reynold Xin reposted
Databricks
@databricks
7 tips to help you debug #apachespark code faster on Databricks dbricks.co/2dYUFX6
-
Reynold Xin reposted
Databricks
@databricks
How to use #apachespark with #awslambda to automate ETL and serve #machinelearning models on Databricks dbricks.co/2e4hqqT
-
Reynold Xin reposted
Databricks
@databricks
ICYMI: Voice from @CERN: #apachespark 2.0 Performance Improvements Investigated With Flame Graphs dbricks.co/2d2J6eu
-
Reynold Xin reposted
Spark Barcelona
@SparkBarcelona
"A behind the scenes look into Spark's API and engine evolutions" by @rxin at Casa Convalescència thanks to @Trovit goo.gl/f5gtBb
-
Reynold Xin reposted
Databricks
@databricks
Databricks Bi-Weekly #apachespark Digest - 10/4/16: What’s happened in the last two weeks dbricks.co/2dFLkRQ
-
Reynold Xin
@rxin
Spark 2.0.1 is released. Upgrade to it today! spark.apache.org/news/spark-2-0-1-released.html
Also available in @databricks for all customers. -
Reynold Xin reposted
Databricks
@databricks
Voice From @CERN: #apachespark 2.0 Performance Improvements Investigated with Flame Graphs dbricks.co/2dV9ig0
-
Reynold Xin reposted
Databricks
@databricks
Spark Streaming & Machine Learning see a significant growth in production, our #apachespark survey results indicate dbricks.co/2dujQi4
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
Sudarshan explains @Bloomberg #apachespark Server arch 4 online analytics of varied data #basparkmeetup
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Looking to up your @apachespark game? Don’t miss #sparksummit Europe 2016 in just a few short weeks in Brussels. ssum.it/2cSvWkP
-
Reynold Xin reposted
Kay Ousterhout
@kayousterhout
Flame graphs are an awesome visual tool for debugging @ApacheSpark performance. Learn how to make them here: gist.github.com/kayousterhout/7008a8ebf2babeedc7ce6f8723f…
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
.@databricks' @rxin @JavaOneConf #apachespark is the Pokemon GO of #bigdata jaxenter.com/javaone-2016-java-keynote-live-129183.html
-
Reynold Xin reposted
Burr Sutter
@burrsutter
Big data on the big stage Keynote @rxin @ApacheSpark #javaone
-
Reynold Xin reposted
-
Reynold Xin reposted
Databricks
@databricks
Databricks Bi-Weekly Digest - 8/31/16: What’s happened in the last two weeks dbricks.co/2bBHJaU
-
Reynold Xin reposted
Databricks
@databricks
Find out how @Facebook uses #apachespark at scale: A 60 TB+ production use case dbricks.co/2bDlDDt
-
Reynold Xin reposted
Databricks
@databricks
Learn how to use SparkSession in #apachespark 2.0 dbricks.co/2aUqWuL
-
Reynold Xin reposted
Databricks
@databricks
Databricks powered #machinelearning platform minimized #brexit fallout for investors dbricks.co/2bl7fBK
-
Reynold Xin reposted
Assaf Araki
@BigData_ML
Thanks to Ben, Pradeep, Mike, Reynold and Reza on a great Distributed Analytics panel at #intelanalytics Summit
-
Reynold Xin reposted
Databricks
@databricks
Continuous Applications: Evolving Streaming in Apache Spark 2.0 dbricks.co/2akcNY1 by @databricks
-
Reynold Xin reposted
Databricks
@databricks
Structured Streaming in Apache Spark 2.0: A new high-level API for writing continuous applications dbricks.co/2akduAz
-
Reynold Xin reposted
Databricks
@databricks
Apache Spark 2.0 now Generally Available on Databricks dbricks.co/2agegl6
-
Reynold Xin
@rxin
Introducing Apache Spark 2.0. databricks.com/blog/2016/07/26/introducing-apache-spark-2… Very interesting how version dist changes over last year.
-
Reynold Xin reposted
Carole McDonald
@caroljmcdonald
Sameer Farooqui explains it so well ! Spark Analyze San Francisco's Open Data youtu.be/K14plpZgy_c via @YouTube
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
.@databricks celebrates its 3-years: great journey, great product, great team! Go #apachespark!
-
Reynold Xin
@rxin
The @MongoDB connector for #apachespark is here databricks.com/blog/2016/07/21/the-new-mongodb-connector-…
-
Reynold Xin
@rxin
New perk (in add to Asha bubble tea) at @databricks: many poke stops w/ lure. We're hiring! databricks.com/company/careers
-
Reynold Xin reposted
Databricks
@databricks
Databricks Bi-Weekly Digest - 7/18/2016: What’s happened in the last two weeks dbricks.co/2a5zpQI
-
Reynold Xin reposted
Stanford NLP Group
@stanfordnlp
And here’s a handy example notebook for Stanford CoreNLP use in @ApacheSpark: databricks-prod-cloudfront.cloud.databricks.com/public/40…
-
Reynold Xin reposted
Stanford NLP Group
@stanfordnlp
🆕 Stanford CoreNLP in @ApacheSpark, wrapped as DataFrame functions by @xmeng 🌲+ ⭐→🎉🎊 spark-packages.org/package/databricks/spark-corenlp github.com/databricks/spark-corenlp #nlproc
-
Reynold Xin reposted
Databricks
@databricks
Give us your feeback in our #apachespark Survey dbricks.co/293MusX
-
Reynold Xin reposted
Databricks
@databricks
.@edmunds deployed #apachespark with Databricks to improve data integrity and customer satisfaction: dbricks.co/29hfNUC
-
Reynold Xin reposted
Databricks
@databricks
Get started with #apachespark on Databricks with our new step-by-step guide with usage scenarios dbricks.co/29gn9wB
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Ready to take the stage at Spark Summit EU? We are accepting talk abstracts until July 1st! Submit today! ssum.it/2960UsY
-
Reynold Xin reposted
Databricks
@databricks
How Databricks is revolutionizing #adtech with #apachespark: dbricks.co/1UBlHne
-
Reynold Xin reposted
Databricks
@databricks
Share your thoughts in our 2016 Apache Spark Survey. We value your feedback! dbricks.co/28MhZEA
-
Reynold Xin reposted
Databricks
@databricks
Get familiar with #apachespark’s key terms and concepts dbricks.co/28Peu3u
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Missed one of the talks at Spark Summit? The videos and slides are now available at ssum.it/28NoTNz
-
Reynold Xin reposted
Patrick Wendell
@pwendell
.@rxin on cloud storage: 9 9's of durability, ~10X cheaper than HDFS... maybe this cloud thing is for real! www.quora.com/How-would-you-compare-HDFS-and-S3-in-terms-…
-
Reynold Xin
@rxin
My answer to How would you compare HDFS and S3 in terms of cost and performance for cloud-based Spark analytics? www.quora.com/How-would-you-compare-HDFS-and-S3-in-terms-…
-
Reynold Xin reposted
Reynold Xin
@rxin
Submit a talk to Spark Summit Brussels (Oct 25 - 27, 2017) to share your stories, experiences, libraries, or apps. spark-summit.org/eu-2016/
-
Reynold Xin reposted
Databricks
@databricks
Databricks brings its fully managed #apachespark platform to #aws #govcloud dbricks.co/28Jc9mG
-
Reynold Xin reposted
Databricks
@databricks
#sql Subqueries in #apachespark 2.0: Hands-on examples of scalar and predicate type of subqueries dbricks.co/1tu8dzi
-
Reynold Xin
@rxin
Submit a talk to Spark Summit Brussels (Oct 25 - 27, 2017) to share your stories, experiences, libraries, or apps. spark-summit.org/eu-2016/
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Please spread the word: We're accepting submissions to speak at the next #sparksummit in Europe: ssum.it/1YoXLEW
-
Reynold Xin reposted
Databricks
@databricks
Want an easier way to write an #apachespark application? Check out this introductory tutorial: dbricks.co/1U99Tou
-
Reynold Xin
@rxin
This Parody Of Every TED Talk Ever Is Absolutely Perfect - "How to be a thought leader?" digg.com/video/ted-talk-parody
-
Reynold Xin reposted
IBTimes UK
@IBTimesUK
WikiLeaks founder Julian Assange claims Google involved in Hilary Clinton campaign www.ibtimes.co.uk/wikileaks-founder-julian-assange-claims…
-
Reynold Xin reposted
Databricks
@databricks
Databricks in the news: This is where the real action in artificial intelligence takes place dbricks.co/1tlfYYO
-
Reynold Xin reposted
Svetlana Sicular
@Sve_Sic
►►►First time #dataengineering recognized as equal to #datascience at the big event
#sparksummit -
Reynold Xin reposted
Databricks
@databricks
Want a summary of the best of #sparksummit? Read our wrap-up blog to get the scoop: dbricks.co/1swC1es
-
Reynold Xin reposted
Michael Hunger 🇪🇺 🇺🇦 @mesirii@chaos.social
@mesirii
Are you using @ApacheSpark or @Neo4j ?
Combine them for more graph power
neo4j.com/blog/neo4j-3-0-apache-spark-connector
Please help test my neo4j-spark-connector -
Reynold Xin reposted
Michael Hunger 🇪🇺 🇺🇦 @mesirii@chaos.social
@mesirii
Published the @Neo4j to @ApacheSpark connector
to spark-packages
spark-packages.org/package/neo4j-contrib/neo4j-spark-conn…
Would love some feedback
Next release fun w/ scala -
Reynold Xin reposted
LinkedIn Engineering
@LinkedInEng
Why we built an #apachespark machine learning lib. & added Spark support to other #opensource projects: engineering.linkedin.com/blog/2016/06/open-sourcing-photo… #sparksummit
-
Reynold Xin reposted
Girish Mohandass
@girishmohandass
Baidu's Deep Learning Infrastructure #sparksummit #deeplearning
-
Reynold Xin reposted
Databricks
@databricks
Deep learning on #apachespark. Learn how @Yahoo enables distributed deep learning on Spark: dbricks.co/1TY33r6
-
Reynold Xin
@rxin
We are looking for engineer to take Python/Spark to the next level. databricks.com/company/careers Craft beautiful APIs and and efficient engines.
-
Reynold Xin reposted
Pastel GBETOHO
@pastelgpc
Genome Sequencing in a Nutshell #apachespark @databricks snip.ly/mb6gk
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Jason from Jenalia Lab shows how #datascience is used to map neurons in a fish brain #sparksummit
-
Reynold Xin
@rxin
Uber built a debugging tool for Spark using Spark DataFrames to mine Spark's own logs. @spark_summit
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Wenbo explains what is temporal join works. In time series data #sparksummit data science track
-
Reynold Xin reposted
Databricks
@databricks
DataFrames, Datasets, and SQL share the same optimization / execution pipeline via @michaelarmbrust #sparksummit
-
Reynold Xin reposted
Patrick Wendell
@pwendell
Enjoying #sparksummit? Join us at @databricks to help us work on our cloud data platform. Ping me if interested!
-
Reynold Xin
@rxin
.@AndrewYNg at @spark_summit: Spark + AI = superpowers. AI is the new electricity.
-
Reynold Xin reposted
Toru Shimogaki
@shimtoru
Spark at Baidu, tens of thousands of servers... #sparksummit
-
Reynold Xin reposted
Evan Powell (🛡️, ☮️)
@epowell101
Why is deep learning taking off now? #sparksummit @AndrewYNg
-
Reynold Xin reposted
George Chow
@ftgfop1
Andrew Ng: "AI is the new electricity." from #sparksummit (survey andrewng.org/poll1)
-
Reynold Xin reposted
Toru Shimogaki
@shimtoru
Autonomous driving by Baidu Research #sparksummit
-
Reynold Xin reposted
Databricks
@databricks
Databricks Community Edition now Generally Available to Learn and Explore #apachespark dbricks.co/1rbJzC3
-
Reynold Xin reposted
Toru Shimogaki
@shimtoru
Growing Use of Deep Learning at Google #sparksummit
-
Reynold Xin reposted
Adrian Colyer
@adriancolyer
BIgDebug - a much more efficient way to figure out why your Spark programs aren't quite doing what you want! blog.acolyer.org/2016/06/07/bigdebug-debugging-primitives…
-
Reynold Xin reposted
Toru Shimogaki
@shimtoru
Apache Spark Philosiphy #sparksummit
-
Reynold Xin reposted
Michael Armbrust
@michaelarmbrust
Analyzing tweets of the election at #sparksummit using #databricks CE - docs.cloud.databricks.com/docs/latest/featured_notebooks/…
-
Reynold Xin reposted
Databricks
@databricks
#apachespark 2.0 optimizations == faster streaming - #sparksummit demo
-
Reynold Xin reposted
(Susan) Xinh Huynh
@xinh_huynh
Use TensorFrames to run TensorFlow on #spark DataFrames - sfspark meetup #sparksummit
-
Reynold Xin reposted
{Jules Damji}=💻📚📝
@2twitme
Things #deepdreams algorithms can do. @timjhunter demo of #tensorframes on #tensorflow @spark_summit #spark meetup.
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Using @ApacheSpark for #datascience? Spark Summit 2016 has an entire track just for you. Check out the schedule: ssum.it/1UgEN0a
-
Reynold Xin reposted
-
Reynold Xin reposted
Databricks
@databricks
Preview #apachespark 2.0 With an Anthology of Technical Assets dbricks.co/22xQ5kd
-
Reynold Xin reposted
Databricks
@databricks
A free #apachespark online learning course is about to start, learn how you can sign-up: dbricks.co/25yu86i
-
Reynold Xin reposted
Databricks
@databricks
Apache Spark 2.0 Preview: Machine Learning Model Persistence dbricks.co/1PfUbeE
-
Reynold Xin reposted
Ben Hamner
@benhamner
"All scientific articles in Europe must be freely accessible as of 2020. [Also want] optimal reuse of research data" english.eu2016.nl/latest/news/2016/05/27/all-european-sci…
-
Reynold Xin reposted
((( matt hunt )))
@instantmatthew
Wow. @AndrewNg_ and Jeff dean at Sark summit. Giants of our age. Kudos, @rxin @alighodsi @databricks .
Every year you amaze and delight. -
Reynold Xin reposted
Databricks
@databricks
New from Ovum: How enterprises can tackle advanced analytics with #apachespark - dbricks.co/1Tswj5X
-
Reynold Xin reposted
Databricks
@databricks
Genome Variant Analysis using K-Means, ADAM, and #apachespark with Databricks dbricks.co/20vOslo
-
Reynold Xin
@rxin
My 1000th commit to Spark was ... [SPARK-15459][SQL] Make Range logical and physical explain consistent github.com/apache/spark/commit/845e447fa03bf0a53ed79fa7e2…
-
Reynold Xin reposted
Erik Meijer
@headinthebox
Someone should do this for LINQ expression trees databricks.com/blog/2016/05/23/apache-spark-as-a-compiler…
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Using #apachespark on #mesos? Check out this session by @deanwampler @tnachen at next month's Spark Summit: ssum.it/1qCRbNN
-
Reynold Xin reposted
MongoDB
@MongoDB
MongoDB connector for @ApacheSpark: Announcing early access program & new Spark course www.mongodb.com/products/integrations/spark-connector?jmp…
-
Reynold Xin reposted
Databricks
@databricks
Try Approximate Algorithms in Apache Spark: HyperLogLog and Quantiles dbricks.co/20aQ4Rs
-
Reynold Xin
@rxin
Attend @spark_summit to get the latest on @ApacheSpark. Take 20% off on me use personal code, "reynold16" spark-summit.org/2016/ !
-
Reynold Xin reposted
Databricks
@databricks
6 Reasons to Attend #sparksummit in San Francisco dbricks.co/1OInbeD
-
Reynold Xin reposted
Tomas Petricek (find me on BlueSky)
@tomaspetricek
Making silly #latex jokes is much more fun than doing final tweaks in my thesis on #coeffects...
-
Reynold Xin reposted
Nick Swanson-Hysell
@polarwander
.@UCBerkeley's Nobel laureate parking now includes bike parking!
-
Reynold Xin reposted
Richard Garris
@rlgarris
@databricks demo of Spark on Redis #redisconf x.com/ndunham/status/730450088107991040
-
Reynold Xin reposted
Manish Gupta
@mgupta_sv
@rxin keynote #redisconf about #redis and #spark @RedisLabs
-
Reynold Xin reposted
Databricks
@databricks
#apachespark 2.0 Technical Preview Now Available on Databricks Community Edition. dbricks.co/1TA9zOM
-
Reynold Xin
@rxin
Super excited about this. Tech preview of Spark 2.0: faster, easier, and smarter databricks.com/blog/2016/05/11/spark-2-0-technical-previe…
-
Reynold Xin reposted
GitHub
@github
Unlimited private repositories. Unlimited possibilities: github.com/blog/2164-introducing-unlimited-private-reposi…
-
Reynold Xin reposted
Joe Hellerstein
@joe_hellerstein
Seen in Berkeley. Identify yourself, Mr SQL!
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Learn about Low Latency Execution for #apachespark from @apanda and Shivaram Venkataraman of @AmpLab: ssum.it/23G1cqq #sparksummit
-
Reynold Xin reposted
Chad Aldeman
@ChadAldeman
For those born in 1900, the modal year for death was before age 1.
For those born in 2010, it will be age 90. -
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Better understand memory management in #apachespark. Attend this upcoming talk at #sparksummit 2016: ssum.it/24yB5aA
-
Reynold Xin reposted
Data Con LA
@DataConLA
We're totally looking forward to the keynote speech by Reynold Xin @rxin at #bigdatadayla! Register at www.eventbrite.com/e/big-data-day-la-2016-registration-24…!
-
Reynold Xin reposted
Rodrigo Agundez
@rragundez
Reynold benchmarking Tungsten in Spark 2.0 vs 1.6, a sum and join of a billion numbers, from 12 and 90 sec to 0.77 and 0.67 sec wow! #spark
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Baidu Chief Scientist @AndrewYNg on Intersection of Supercomputing, Machine Learning ssum.it/1QLvmRz See him speak at #sparksummit!
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Amazing photo by @gags9999 of #sanfrancisco, where the next Spark Summit is taking place in June!
-
Reynold Xin reposted
Databricks
@databricks
Don't miss this @Spark_Summit Keynote by the head of #deeplearning
research at @google. dbricks.co/1VSQaiB -
Reynold Xin reposted
Databricks
@databricks
Meet the creators and drivers of @ApacheSpark at #sparklive in Los Angeles. Spots are limited so RSVP today! dbricks.co/1rl0h2o
-
Reynold Xin
@rxin
We are doing Spark tutorials for researchers at SIGMOD and KDD. sigmod2016.org/sigmod_tutorial8.shtml and www.kdd.org/kdd2016/tutorials
-
Reynold Xin reposted
Mobius API for Spark
@MobiusForSpark
Pleased to announce the release of Mobius v1.6.100 github.com/Microsoft/Mobius/releases/tag/v1.6.100 Enjoy building #apachespark jobs in #csharp using #mobiusforspark
-
Reynold Xin reposted
Databricks
@databricks
New eBook from @Databricks to help you with @ApacheSpark #machinelearning: dbricks.co/1TwZlBa
-
Reynold Xin
@rxin
The Michael Jordan of Computer Science is .... Michael Jordan! www.sciencemag.org/news/2016/04/who-s-michael-jordan-comp…
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
With keynotes from Andrew Ng, Marvin Theimer and Jeff Dean, @Spark_Summit 2016 will be awesome! See the schedule at spark-summit.org/2016/schedule/.
-
Reynold Xin
@rxin
A conference call in real-life. This is hilarious and sadly true. www.youtube.com/watch?list=RDMhllo1xQer8&v=DYu_bGbZiiQ
-
Reynold Xin reposted
Databricks
@databricks
In case you missed it - New content in Community Edition: Machine Learning with Spark #mooc and two new notebooks. dbricks.co/1Q9ROUa
-
Reynold Xin reposted
Databricks
@databricks
Today, join Joseph Bradley for GraphFrames: DataFrame-based graphs for Apache Spark dbricks.co/1WM0XI9
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
BIG news: Andrew Ng, Jeff Dean and Marvin Theimer will be Keynote Speakers at #sparksummit! ssum.it/1W0jJNi
-
Reynold Xin
@rxin
The page for book "Site Reliability Engineering" currently shows an error: "We’re doing some maintenance from ..."
-
Reynold Xin reposted
Databricks
@databricks
Learn how @Databricks is helping @DNVGL with #iot and energy data analytics: dbricks.co/1S4UlGK
-
Reynold Xin reposted
Databricks
@databricks
Learn how @MetacogInc built a continuous integration system for @ApacheSpark applications with @Databricks: dbricks.co/1UWf2pf
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
Need #apachespark training? Learn from the best. Come to Spark Summit 2016, June 6-8: ssum.it/1N1OF8N
-
Reynold Xin reposted
Databricks
@databricks
How @Metacoginc implemented Agile @ApacheSpark application development with @databricks: dbricks.co/25zJ70P
-
Reynold Xin reposted
Databricks
@databricks
The Unreasonable Effectiveness of Deep Learning on Spark dbricks.co/1RClZoZ by @databricks
-
Reynold Xin reposted
Nezih Yigitbasi
@istanbul_techie
I and my colleague will be giving a talk at @spark_summit in San Francisco this June about how we use Spark for ETL @netflix, stay tuned!
-
Reynold Xin reposted
Ben Lorica 罗瑞卡
@bigdata
I penned my #stratahadoop tweets using DeepSpark → three 15-layer CNN on a 12000-node cluster using 1.2 PB of memory goo.gl/ur3yHY
-
Reynold Xin reposted
The Wall Street Journal
@WSJ
Tesla’s Musk: Model 3 orders surpassed 115,000 within 24 hours
www.wsj.com/articles/teslas-musk-model-3-orders-surpassed… -
Reynold Xin
@rxin
The Unreasonable Effectiveness of Deep Learning on Spark databricks.com/blog/2016/04/01/unreasonable-effectiveness… This is super exciting - next major chapter in big data.
-
Reynold Xin reposted
Databricks
@databricks
Get a collection of the best @ApacheSpark content from the @databricks blog in new e-book: dbricks.co/1Utzo8x
-
Reynold Xin reposted
Databricks
@databricks
Visit @Databricks at #stratahadoop booth 1237. Schedule a personalized demo: dbricks.co/1XSUifl
-
Reynold Xin
@rxin
Schedule for Spark Summit San Francisco (June 2016) has been posted: spark-summit.org/2016/schedule/ lots of great talks. Look forward to it.
-
Reynold Xin reposted
Daniel Whitenack
@dwhitena
I knew it, to be trendy I must integrate @apachespark with @reactjs. databricks.com/blog/2016/03/22/spark-trending-in-the-stac… @databricks #maybenot
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
The biggest surprise with #leftpad is that it was quadratic-time.. hope the new maintainers fix that.
-
Reynold Xin
@rxin
Spark is the 2nd most trending and top paying tech in @StackOverflow survey. We want to help developers learn it. databricks.com/blog/2016/03/22/spark-trending-in-the-stac…
-
Reynold Xin reposted
Databricks
@databricks
#devsurvey2016 shows need for @ApacheSpark talent, @Databricks can help: dbricks.co/1LEfox7 by @databricks
-
Reynold Xin reposted
Pastel GBETOHO
@pastelgpc
Auto-scaling #scikitlearn with #spark | @databricks snip.ly/4bdvs
-
Reynold Xin reposted
Dino Lamela
@dinolamela
We're looking to hire our first Technical Recruiter #databricks- www.databricks.com/company/careers
-
Reynold Xin reposted
BART
@SFBART
@shakatron BART was built to transport far fewer people, and much of our system has reached the end of its useful life. This is our reality.
-
Reynold Xin
@rxin
Analyzing flight on-time performance using the latest open source lib GraphFrames on Spark databricks.com/blog/2016/03/16/on-time-flight-performance…
-
Reynold Xin reposted
GitHub
@github
Faster, more flexible code review tools: github.com/blog/2123-more-code-review-tools
-
Reynold Xin reposted
Mustafa Suleyman
@mustafasuleyman
Huge milestone in AI! AlphaGo beats the world champion Lee Sedol! We made history! What an incredible moment! :-)
-
Reynold Xin reposted
Julie Bort
@Julie188
The CEO of one of the hottest, most important startups wants to help you get a higher paying tech job read.bi/1Yp229Z
-
Reynold Xin reposted
Michael Koziarski
@nzkoz
Code comments
-
Reynold Xin
@rxin
Looks like the rain followed me from Vancouver to San Francisco.
-
Reynold Xin
@rxin
Do people in non-English-speaking countries code in English? programmers.stackexchange.com/questions/1483/do-people-in…
-
Reynold Xin
@rxin
Good move on our friends at @hortonworks to deliver Spark faster than Hadoop to their customers hortonworks.com/blog/announcing-the-general-availability-…
-
Reynold Xin reposted
Jay Kreps
@jaykreps
Microservices are about scaling the number of engineers not the number of requests m.signalvnoise.com/the-majestic-monolith-29166d022228
-
Reynold Xin reposted
Seth Sandler 🙌
@SethSandler
Shipped into production without early customer feedback x.com/GIFs/status/618887257764696064/photo/1
-
Reynold Xin reposted
BigDATAWire
@BigDATAwireNews
Secret to #realtime streaming? Don't think about realtime streaming, says @Databricks co-founder @rxin hpcwire.com/bigdatawire/2016/02/25/spark-2-0-to-introduce… @ApacheSpark
-
Reynold Xin
@rxin
Haskell meets large scale distributed analytics: Haskell API for @ApacheSpark www.tweag.io/blog/haskell-meets-large-scale-distributed-a…
-
Reynold Xin reposted
Mateusz
@parzonka
Finally got my hands on the @databricks community edition. Mind is blown.
-
Reynold Xin
@rxin
If you are working on or with Spark, submit a talk proposal to Spark Summit (in San Francisco June 6 - 8) spark-summit.org/2016/call-for-presentations/
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
The CFP for San Francisco closes in 1 week! Submit today to join us on stage in June!
#sparksummit -
Reynold Xin
@rxin
Typesafe is now named @lightbend www.lightbend.com/blog/typesafe-changes-name-to-lightbend Maybe we can get some type unsafety from Scala? :)
-
Reynold Xin reposted
Asha Tea House
@AshaTeaHouse
For those of you who haven't already heard... Asha's Blood Orange Oolong is back in season! This… www.instagram.com/p/BBVgP_jRGIp/
-
Reynold Xin reposted
TechCrunch
@TechCrunch
Databricks launches free Community Edition as companion to Spark MOOCs tcrn.ch/1Q1xc51
-
Reynold Xin reposted
April Reeve
@Datagrrl
Very end of #sparksummit - Andrew Ray of Silicon Valley Data Science - pivoting datasets in #spark. Still 250 people at 5:30 pm. Geeks r us
-
Reynold Xin reposted
Databricks
@databricks
Thanks for making #sparksummit a huge success! Read the highlights here: dbricks.co/21bXfKy
-
Reynold Xin
@rxin
Future of Real-Time in Spark: simplest way to perform streaming analytics is not having to *reason* about streaming.
www.slideshare.net/rxin/the-future-of-realtime-in-spark -
Reynold Xin reposted
dennylee
@dennylee
"The simplest way to perform streaming analytics is not having to *reason* about streaming" @rxin #sparksummit
-
Reynold Xin reposted
dennylee
@dennylee
Challenges of building continuous applications at today's #sparksummit keynote with @rxin
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
My slides on Spark 2.0 at #sparksummit: www.slideshare.net/databricks/2016-spark-summit-east-keyn…
-
Reynold Xin
@rxin
Tim Cook letter about encryption/backdoor. IIUC, Apple can't decrypt data, and this is more about setting precedent? www.apple.com/customer-letter/
-
Reynold Xin reposted
Databricks
@databricks
An easier way to use @ApacheSpark: Dashboards in @Databricks announced dbricks.co/1Syn31S
-
Reynold Xin reposted
Michael Armbrust
@michaelarmbrust
Check out the demo from #sparksummit #communityedition docs.cloud.databricks.com/docs/latest/featured_notebooks/…
-
Reynold Xin reposted
Kavitha Mariappan
@kmariappan
Introducing Databricks Community Edition: Apache Spark for All @databricks #sparksummit databricks.com/blog/2016/02/17/introducing-databricks-com…
-
Reynold Xin reposted
Tony Baer
@TonyBaer
Spark meetups eating the world #sparksummit
-
Reynold Xin reposted
Dave Vellante
@dvellante
Summary slide at #sparksummit of how Spark has achieved its performance gains
-
Reynold Xin reposted
Mudit
@muppal_
Apache Spark meetup! NYC spark summit committer night! #spark #sparksummit
-
Reynold Xin reposted
((( matt hunt )))
@instantmatthew
550 people signed up for the spark meetup tonight in the Hilton. no pressure, @rxin ;-) #sparksummit
-
Reynold Xin reposted
Akka
@akka_io_
CFP is open for @spark_summit #sfo. Warm up your brain parts! spark-summit.org/2016/ #spark
-
Reynold Xin reposted
Databricks
@databricks
How to quickly pivot data with a #dataframe in @ApacheSpark 1.6: dbricks.co/1TQgreR
-
Post not available here, view on X
Reynold Xin
@rxin
See openjdk.java.net/jeps/260 "The critical internal APIs proposed to remain accessible in JDK 9 are: sun.misc.Unsafe" @sugarlife
-
Reynold Xin reposted
x1
@iyunoriue
祝!Spark Conference! #hcj2016
-
Reynold Xin reposted
x1
@iyunoriue
Sparkコミュニティの発展のところで、Tokyo Meetupが紹介された!
www.meetup.com/ja-JP/Tokyo-Spark-Meetup/ #hcj2016 -
Reynold Xin reposted
-
Reynold Xin reposted
Databricks
@databricks
.@Miklos_C will talk about Operational Tips for Deploying @ApacheSpark at @spark_summit. Register to join him there! dbricks.co/1mghFSV
-
Reynold Xin reposted
Databricks
@databricks
.@databricks February newsletter: Upcoming @spark_summit, new customer case study, and more. dbricks.co/1SGkKbL
-
Reynold Xin
@rxin
2月8日、日本で初開催となる Spark Conference Japan で Spark 2.0 と Project Tungsten の次のフェーズについてお話します www.eventbrite.com/e/hadoop-spark-conference-japan-2016-t…
-
Reynold Xin
@rxin
I will be talking about Spark 2.0 and next phase of Project Tungsten at inaugural Spark Conference Japan on Feb 8 www.eventbrite.com/e/hadoop-spark-conference-japan-2016-t…
-
Reynold Xin reposted
Databricks
@databricks
Join @nongli at @spark_summit to learn about #project Tungsten and how it will improve @ApacheSpark performance dbricks.co/1P3WUUT
-
Reynold Xin
@rxin
Love Spark? Want to work with the team that created it? Join us as an evangelist databricks.com/company/careers
-
Reynold Xin reposted
Databricks
@databricks
Deep Learning with @ApacheSpark and @TensorFlo dbricks.co/1ZYQ4Io by @timjhunter
-
Reynold Xin
@rxin
When we put all the buzz words in a single blog post: Spark, Deep Learning, TensorFlow, neural networks databricks.com/blog/2016/01/25/deep-learning-with-spark-a…
-
Reynold Xin
@rxin
Deep learning (handwritten digit recognition and image labeling) with Spark and TensorFlow: databricks.com/blog/2016/01/25/deep-learning-with-spark-a…
-
Reynold Xin reposted
Databricks
@databricks
MLlib Highlights in @ApacheSpark 1.6 by Joseph Bradley and xmeng dbricks.co/1Qo60hw
-
Reynold Xin reposted
KDnuggets
@kdnuggets
#spark 2015 Year In Review @databricks www.databricks.com/blog/2016/01/05/apache-spark-2015-year…
-
Reynold Xin reposted
Mobius API for Spark
@MobiusForSpark
Pleased to announce the release of #sparkclr v1.5.200 for @ApacheSpark v1.5.2. Download and try it out from github.com/Microsoft/SparkCLR/releases/tag/v1.5.200
-
Reynold Xin
@rxin
The most interesting thing in Spark 2015 Year in Review post is the version dist over time. databricks.com/blog/2016/01/05/spark-2015-year-in-review.…
-
Reynold Xin
@rxin
A hot topic at Spark Summit this time will be Spark 2.0. spark-summit.org/east-2016/schedule/ (Feb 16 - 18 in NYC)
-
Reynold Xin reposted
Databricks
@databricks
Announcing @ApacheSpark Essentials for the Public Sector workshop dbricks.co/1JIckyQ
-
Reynold Xin reposted
The New Stack
@thenewstack
Spark 1.6: Strong Typing, Faster Throughput tnstack.io/WUtEJ cc @rxin @databricks #jvm #algorithm
-
Reynold Xin reposted
#DataAISummit
@Data_AI_Summit
The agenda for Spark Summit East has been posted, check it out spark-summit.org/east-2016/schedule/ and register today!
-
Reynold Xin reposted
Tony Baer
@TonyBaer
Looking forward to presenting Spark&the Enterprise #sparksummit East 2/17 NYC spark-summit.org/east-2016/events/spark-and-enterprise/ register here www.prevalentdesignevents.com/sparksummit2016/east/regist…
-
Reynold Xin reposted
Arlene
@acapsimalis
53 startups that will be huge in 2016, according to VCs read.bi/1mDp5R7 via @bi_enterprise @zoomdata @tamr @databricks @confluent
-
Reynold Xin reposted
Databricks
@databricks
Databricks 2015 Year In Review: Democratizing Access to Data dbricks.co/1O35G4Z cc @databricks @ApacheSpark
-
Reynold Xin
@rxin
It's that time of the year again: Spark 2015 Year In Review. 1000 code contributors, majority are on Spark 1.5. databricks.com/blog/2016/01/05/spark-2015-year-in-review.…
-
Reynold Xin reposted
Christophe Bourguignat
@chris_bour
Data engineers should often be hired before data scientists at startups www.dataquest.io/learner-stories/
-
Reynold Xin reposted
Christophe Bourguignat
@chris_bour
Spark 1.4 : Dataframes
Spark 1.6 : Datasets
Spark 2.0 : Unification of Dataframes with Datasets databricks.com/blog/2016/01/04/introducing-spark-datasets… -
Reynold Xin reposted
Databricks
@databricks
Announcing @ApacheSpark 1.6 dbricks.co/1RbLguO
-
Reynold Xin reposted
Databricks
@databricks
Introducing @ApacheSpark Datasets dbricks.co/1RbLxOg
-
Reynold Xin
@rxin
Our most popular Spark posts in the @databricks blog in 2015: DataFrames, Tungsten, SparkR, Spark 1.4, MongoDB: dbricks.co/1U2LFgr
-
Reynold Xin reposted
Databricks
@databricks
Starting in an hour, Making #bigdata Processing Simple with @ApacheSpark with @matei_zaharia and @rxin dbricks.co/1UAL2vn
-
Reynold Xin reposted
Databricks
@databricks
Join @matei_zaharia and @rxin for the ACM Learning Webinar Making #bigdata Processing Simple with @ApacheSpark dbricks.co/1UAKYfa
-
Reynold Xin reposted
SF Bay Area ACM
@SF_BayArea_ACM
Spark for Data Science, Big and Small
Joseph K. Bradley @databricks
www.youtube.com/watch?v=Y2kARsBiCEw&list=PL87GtQd0bfJx73i…
@ApacheSpark #mlib #bigdata #dscamp #datascience -
Reynold Xin reposted
Databricks
@databricks
東京で @ApacheSpark をテーマにしたリクルートテクノロジーズオープンラボ#2 で Xiangrui Meng と石川有が登壇 dbricks.co/1NQYNAy
-
Reynold Xin reposted
Databricks
@databricks
We've achieved #bigdata Competency Status from @awscloud and won a new customer in FinTech: dbricks.co/1maN0ag @databricks @LendUpLoans
-
Reynold Xin
@rxin
Hello Beijing.
-
Reynold Xin reposted
Setu Chokshi
@setuc
#stratahadoop it takes a special skill and knowledge to simplify hard topics and math @rxin
-
Reynold Xin reposted
Databricks
@databricks
Upcoming webinar: How @CeltraMobile Optimizes its Advertising Platform with @Databricks dbricks.co/211axug
-
Reynold Xin reposted
Kate Ting
@kate_ting
2015 was a great yr for @ApacheSpark: ~4k SparkSummit attendees, 1k contributors & 50k meetup attendees - @rxin (@databricks) #stratahadoop
-
Reynold Xin reposted
Ben Lorica 罗瑞卡
@bigdata
the @ApacheSpark ecosystem: @rxin keynoting at #stratahadoop Singapore
-
Reynold Xin reposted
ginablaber
@ginablaber
Two days ago, @ApacheSpark reached 1000 contributors. @rxin at #stratahadoop
-
Reynold Xin reposted
Jennifer Marsman
@jennifermarsman
Spark has 3 difference resource managers: standalone mode (48%), YARN (40%), and Mesos (11%) - @rxin #stratahadoop
-
Reynold Xin reposted
Toru Shimogaki
@shimtoru
.@rxin から Spark 2.0 という単語が出てきましたね #stratahadoop
-
Reynold Xin reposted
Ben Lorica 罗瑞卡
@bigdata
The largest @ApacheSpark production deployments are in China: @rxin #stratahadoop Singapore goo.gl/srn2Q8
-
Reynold Xin
@rxin
300km/hr train across China. How come it would take California so long to build the SF-LA rail?
-
Reynold Xin reposted
Philip Kendall
@jorallan
Last month, @controlf1 sent me to #sparksummiteu. Here's what I thought of it controlf1.wordpress.com/2015/11/26/a-sparkling-view-from-… @helenaedelson @VincentSaulys @rxin
-
Reynold Xin reposted
Databricks
@databricks
Try a preview of @ApacheSpark 1.6 in @databricks today: new Dataset API and much more. dbricks.co/1kKOGXx
-
Reynold Xin reposted
Ben Lorica 罗瑞卡
@bigdata
I'll be going back to Tian Tian Hainanese Chicken Rice, come #stratahadoop Singapore goo.gl/QjCE0m 🍽🍽🍽
-
Reynold Xin reposted
henridf
@henridf
@rxin @michaelarmbrust @daviesliu was surprised not to find a dataframe-only word count, "gap" filled: medium.com/@henridf/say-word-count-one-more-time-9bf7e58f…
-
Reynold Xin reposted
OPNFV
@opnfv
Via @rxin "There's a whole shift to more open platforms across the whole stack from the bottom up" #opnfvsummit
-
Reynold Xin reposted
Bill Chambers
@bllchmbrs
Excellent keynote by @rxin on future of #apachespark. clear explanation of dataset API motivations, upcoming changes www.youtube.com/watch?v=TynknhKavxI
-
Reynold Xin reposted
Databricks
@databricks
More @apachespark use cases in digital media - how Elsevier uses @databricks to process digitized content in XML: dbricks.co/1ROkiWs
-
Reynold Xin reposted
Scala
@scala_lang
IntelliJ 15 has improved Scala support: macros, test framework integration, debugging lambdas, postfix completion... blog.jetbrains.com/scala/tag/minerva/
-
Reynold Xin reposted
Databricks
@databricks
Learn more about @ApacheSpark TFOCS Optimization Package at @rockthecodeIO
dbricks.co/1ljmP0t -
Reynold Xin reposted
Internet of Shit
@internetofshit
Can't wait for robotic arms to come to the kitchen
-
Reynold Xin reposted
Prabeesh K.
@prabeesh_k
A Look Ahead at @ApacheSpark 's Development - @rxin (@databricks ) youtu.be/TynknhKavxI #dataframe #tungsten
-
Reynold Xin reposted
Databricks
@databricks
Learn how @yesware used @databricks and @ApacheSpark to build a new feature: dbricks.co/1NfDZCF
-
Reynold Xin reposted
Databricks
@databricks
Tonight, join Pat McDonough for A Sneak Peek into @ApacheSpark 1.6 at Washington DC Area Apache Spark Interactive dbricks.co/1NO0TUG
-
Reynold Xin reposted
Databricks
@databricks
.@ApacheSpark Meetup Wednesday in Prague, Chicago, Geneva, and Washington DC
dbricks.co/1iwpQIQ -
Reynold Xin reposted
dennylee
@dennylee
Excited about @ApacheSpark , technical evangelism, and want an awesome challenge, come join us at @Databricks www.databricks.com/company/careers
-
Reynold Xin reposted
Databricks
@databricks
Join @SSKapci and @mhfalaki for Spark Day in Istanbul dbricks.co/1MsjUZb @ApacheSpark #sparkr
-
Reynold Xin reposted
Databricks
@databricks
A new optimization package - TFOCS - is available for @ApacheSpark! dbricks.co/1kmDgIG @databricks
-
Reynold Xin
@rxin
Want to write your Spark job in C#? Microsoft just published Spark .NET CLR language binding spark-packages.org/package/skaarthik/SparkCLR
-
Reynold Xin reposted
Databricks
@databricks
.@rxin's #sparksummiteu keynote: a look ahead at @ApacheSpark development dbricks.co/1Wkz2xs @databricks
-
Reynold Xin reposted
Patrick Wendell
@pwendell
Excited to be hiring a PM/Community Manager for @ApacheSpark. Ping me if you know a good fit! jobs.lever.co/databricks/b1c9b8d3-6bd5-401d-a41c-ccb5d904…
-
Reynold Xin
@rxin
Berlin folks - @michaelarmbrust is giving a meetup talk next Monday (Nov 2) on Spark SQL and DataFrames: www.meetup.com/Berlin-Apache-Spark-Meetup/events/225564945/
-
Reynold Xin
@rxin
People are real polite here in Amsterdam. Every question started with "thank you for your talk" or "great talk". #sparksummiteu
-
Reynold Xin reposted
((( matt hunt )))
@instantmatthew
Thought #sparksummiteu would be small but _huge_ crowd.Great energetic intro by @andykonwinski!
-
Reynold Xin reposted
Databricks
@databricks
New in @databricks - visualizing @ApacheSpark ML models! dbricks.co/1H6X87M x.com/databricks/status/658992930573676544/photo/1
-
Reynold Xin reposted
Databricks
@databricks
Introducing More @Databricks Notebooks Sharing Options in HTML dbricks.co/1M8SzkY @ApacheSpark
-
Reynold Xin reposted
Stéphane Heckel
@hsteph
#spark meetup @GoogleFrance Mon 26th. Talk 2 with @rxin @databricks about Project Tungsten follow @hugfrance #hugfr
www.meetup.com/fr-fr/paris-spark-meetup/events/226170066/ -
Reynold Xin reposted
Ben Lorica 罗瑞卡
@bigdata
Ask @rxin Anything about @ApacheSpark: One of Spark's architects is attending & speaking at #stratahadoop Singapore goo.gl/YfxiZi
-
Reynold Xin
@rxin
Spark redshift package: an important data source package for organizations with data in the cloud databricks.com/blog/2015/10/19/introducing-the-spark-reds…
-
Post not available here, view on X
Reynold Xin
@rxin
.@matei_zaharia is a great writer. cc @jaceklaskowski @ApacheSpark
-
Reynold Xin
@rxin
The call for proposals for @spark_summit in New York Feb 2016 is now open: spark-summit.org/east-2016/
-
Reynold Xin reposted
Databricks
@databricks
Interactive Audience Analytics With @ApacheSpark and HyperLogLog by @ezhulenev dbricks.co/1Ozha0R
-
Reynold Xin reposted
Databricks
@databricks
Meet @Databricks and chat about @ApacheSpark at Booth 837 at @awsreinvent in Las Vegas
-
Reynold Xin
@rxin
Generalized Linear Models in SparkR and R Formula Support in MLlib databricks.com/blog/2015/10/05/generalized-linear-models-…
-
Reynold Xin reposted
Robbert Vervuurt
@Rvervuurt
If @OReillyMedia made books about animals.
-
Reynold Xin
@rxin
This is pretty scary.
CNN Breaking News
@cnnbrk
15 million T-Mobile customers hacked. cnnmon.ie/1KY7KGO
-
Reynold Xin reposted
Databricks
@databricks
.@rxin discusses @ApacheSpark 1.5.1 and what do version numbers mean? dbricks.co/1VrDizT
-
Reynold Xin reposted
Joe Hellerstein
@joe_hellerstein
Hiring Assistant Professor: Human-Centered Data Science | UC Berkeley School of Information www.ischool.berkeley.edu/about/ischooljobs/human-centered…
-
Reynold Xin
@rxin
If you are using Spark 1.5.0, you should update to 1.5.1. databricks.com/blog/2015/10/01/spark-1-5-1-and-what-do-ve…
Databricks
@databricks
.@rxin discusses @ApacheSpark 1.5.1 and what do version numbers mean? dbricks.co/1VrDkrA
-
Reynold Xin reposted
Databricks
@databricks
Join @dennylee at the #datapopupseattle on Using @ApacheSpark in Healthcare Predictive Analytics in the OR dbricks.co/1FoOKVJ
-
Reynold Xin
@rxin
My Strata hardcore data science talk on Sketching Big Data with Spark: randomized algorithms for data analytics www.slideshare.net/databricks/sketching-big-data-with-spa…
-
Reynold Xin reposted
Hugo Gävert - hgavert.bsky.social
@hgavert
@rxin on what #apachespark is... Now I know what I tell my boss :D #stratahadoop
-
Reynold Xin reposted
Matei Zaharia
@matei_zaharia
Caffe on Spark for deep learning from Yahoo!: yahoohadoop.tumblr.com/post/129872361846/large-scale-dist…
-
Reynold Xin reposted
Databricks
@databricks
Improved Frequent Pattern Mining in @ApacheSpark 1.5: Association Rules and Sequential Patterns [updated] dbricks.co/1Lh0tbz
-
Reynold Xin
@rxin
This is a new high. Spark is the Taylor Swift of big data software. fortune.com/2015/09/25/apache-spark-survey/ @databricks @derrickharris
-
Reynold Xin
@rxin
SF has been destroyed many times recently. Planet of Apes, Terminator Genisys, Pacific Rim, San Andreas, Godzilla. SF is the new NY?
-
Reynold Xin
@rxin
Coolest Spark debugging features with integrated UI: databricks.com/blog/2015/09/23/easier-spark-code-debuggin… Real-Time Progress Bar and Spark UI Integration in Databricks
-
Reynold Xin reposted
Databricks
@databricks
Want to simplify @ApacheSpark debugging? Real-time monitoring in @databricks notebooks helps: dbricks.co/1LO1mTi x.com/databricks/status/646717368799002624/photo/1
-
Reynold Xin reposted
Databricks
@databricks
Read about LDA topic modeling improvements in @ApacheSpark: dbricks.co/1YzLAou @databricks
-
Reynold Xin
@rxin
Our @databricks slackbot now digs @AshaTeaHouse. "Boba is life, liberty, and the pursuit of happiness."
-
Reynold Xin reposted
Databricks
@databricks
Join @rxin @tathadas and @pwendell Committer night: @ApacheSpark 1.5 and beyond at #stratanyc dbricks.co/1irrXOy
-
Reynold Xin reposted
Evan Chan
@Evanfchan
Introducing FiloDB, a new #bigdata #analytics database to accelerate #spark on @cassandra. velvia.github.io/Introducing-FiloDB/ #scala #akka
-
Reynold Xin
@rxin
Sifting ... is slow, which is why Databricks’ Zaharia developed Spark, a sort of spreadsheet for big piles of data www.economist.com/news/business/21665070-flock-startups-m…
-
Reynold Xin reposted
Databricks
@databricks
Don't miss the Spark 1.5 DataFrame API Highlights: Date/Time/String Handling, Time Intervals, and UDAFs blog dbricks.co/1OZcQ9y