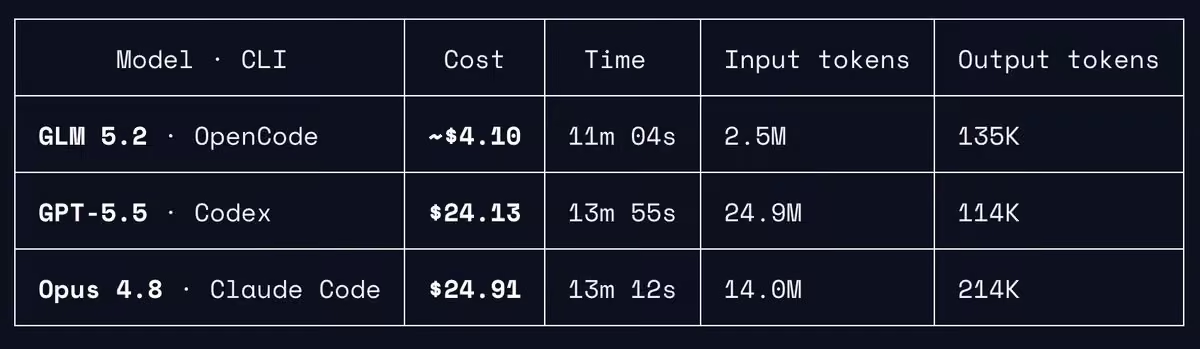
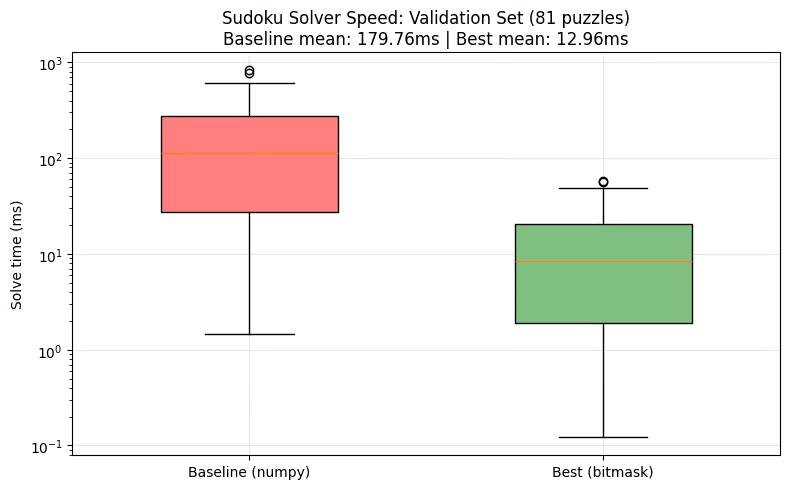
We've made it even easier to reduce coding agent costs with Unity Gateway! The new Unity Gateway Insights automatically finds cost saving opportunities once you pass your LLM traffic through Unity Gateway, including misconfigured tools/MCPs, off-topic use of coding agents, and opportunities for routing work to smaller models. It works with Claude Code, Codex, GitHub Copilot and any existing agent, on your existing LLM capacity. Just pass the traffic through Unity Gateway and hit analyze to get a report.
We're continually updating this product with new cost saving opportunities we find internally at Databricks (e.g. wasteful Claude settings) and in our work with customers.
www.databricks.com/blog/introducing-unity-gateway-insightโฆ
Matei Zaharia
Matei Zaharia (born 1984 or 1985) is a Romanian-Canadian computer scientist, educator businessman. He is the creator of Apache Spark and the chief technology officer, one of the founders of Databricks and has developed open-source projects like Delta Lake, MLflow and Omnigent. More on Wikipedia
-
Matei Zaharia
@matei_zaharia
-
Matei Zaharia
@matei_zaharia
Ali demoes how he uses Genie to run Databricks in the video here. I couldn't find many AI CEOs directly using their AI to manage such a wide swath of their company, which is really the point here, you want the layer that connects it to data, policies and decisions.
The All-In Podcast
@theallinpod
All-In Interview : Co-Founder & CEO of Databricks, Ali Ghodsi
Thanks to our partner @airwallex
-- Intelligence Isnโt the Bottleneck Anymore
-- Why Enterprise AI Is Stuck
-- Early Bets on Cloud and Open Source
-- Token Spend vs. Real Productivity
-- Will Databricks Ever IPO?
++ much more!
(0:00) @alighodsi joins the show: Databricksโ early bets on cloud, AI, and open source
(8:50) Is AGI Already Here? Why Enterprise AI Is Falling Behind
(22:04) Live Demo: How Databricks Uses Agentic AI For Efficiency
(38:25) Databricks IPO: The Case for Staying Private
(44:02) RSI, Cyber Risk & the Doom Debate
-----------------------------------------
Thanks to our partner for making this possible!
Airwallex is a leading global payments and financial platform for modern businesses, offering trusted solutions to manage everything from business accounts, payments, treasury, and spend management to embedded finance. Learn more at airwallex.com/allinThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Databricks
@databricks
LTAP isn't just a better CDC pipeline. It eliminates the need for one.
In Lakebase Postgres, the lake is the database's storage, not a replica.
We're debunking four common misconceptions about how LTAP actually works:
โ ๐๐'๐ ๐ท๐๐๐ ๐ฟ๐ฒ๐ฝ๐น๐ถ๐ฐ๐ฎ๐๐ถ๐ผ๐ป. LTAP maintains one logical table, not two databases that need to stay in sync.
โ ๐ข๐ป๐ฒ ๐ฐ๐ผ๐ฝ๐ ๐บ๐ฒ๐ฎ๐ป๐ ๐๐น๐ผ๐๐ฒ๐ฟ ๐พ๐๐ฒ๐ฟ๐ถ๐ฒ๐. Postgres uses heap pages for fast lookups, while analytics scans Parquet.
โ ๐๐ป๐ฎ๐น๐๐๐ถ๐ฐ๐ ๐บ๐๐๐ ๐ฏ๐ฒ ๐๐๐ฎ๐น๐ฒ. Queries see consistent snapshots, including recent commits not yet materialized in the lake.
โ ๐๐ผ๐ด๐ถ๐ฐ๐ฎ๐น ๐ฟ๐ฒ๐ฝ๐น๐ถ๐ฐ๐ฎ๐๐ถ๐ผ๐ป ๐ถ๐ ๐ฒ๐ป๐ผ๐๐ด๐ต. CDC requires a separate pipeline to process changes and maintain a second copy. LTAP doesn't.
Read the deep dive: www.databricks.com/blog/dispelling-ltap-myths -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Really enjoyed this chat on @theallinpod! @Jason got me to demo how I actually use AI to run @databricks, HR, Eng, Sales, etc!
The All-In Podcast
@theallinpod
All-In Interview : Co-Founder & CEO of Databricks, Ali Ghodsi
Thanks to our partner @airwallex
-- Intelligence Isnโt the Bottleneck Anymore
-- Why Enterprise AI Is Stuck
-- Early Bets on Cloud and Open Source
-- Token Spend vs. Real Productivity
-- Will Databricks Ever IPO?
++ much more!
(0:00) @alighodsi joins the show: Databricksโ early bets on cloud, AI, and open source
(8:50) Is AGI Already Here? Why Enterprise AI Is Falling Behind
(22:04) Live Demo: How Databricks Uses Agentic AI For Efficiency
(38:25) Databricks IPO: The Case for Staying Private
(44:02) RSI, Cyber Risk & the Doom Debate
-----------------------------------------
Thanks to our partner for making this possible!
Airwallex is a leading global payments and financial platform for modern businesses, offering trusted solutions to manage everything from business accounts, payments, treasury, and spend management to embedded finance. Learn more at airwallex.com/allinThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
The All-In Podcast
@theallinpod
All-In Interview : Co-Founder & CEO of Databricks, Ali Ghodsi
Thanks to our partner @airwallex
-- Intelligence Isnโt the Bottleneck Anymore
-- Why Enterprise AI Is Stuck
-- Early Bets on Cloud and Open Source
-- Token Spend vs. Real Productivity
-- Will Databricks Ever IPO?
++ much more!
(0:00) @alighodsi joins the show: Databricksโ early bets on cloud, AI, and open source
(8:50) Is AGI Already Here? Why Enterprise AI Is Falling Behind
(22:04) Live Demo: How Databricks Uses Agentic AI For Efficiency
(38:25) Databricks IPO: The Case for Staying Private
(44:02) RSI, Cyber Risk & the Doom Debate
-----------------------------------------
Thanks to our partner for making this possible!
Airwallex is a leading global payments and financial platform for modern businesses, offering trusted solutions to manage everything from business accounts, payments, treasury, and spend management to embedded finance. Learn more at airwallex.com/allinThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Yichuan Wang
@YichuanM
Beyond Score Centering: what else can we fix in async RL? ๐งต
Score centering (SC) is the hot new trick for off-policy LLM RL. We stress-tested it under real async staleness (every batch up to 127 steps old) and found what it fixes, what it doesn't, and two cheap wins on top
๐ What SC actually fixes
โข Without SC, a trajectory's gradient norm grows ~linearly with its age: at age 64 it's 3.2ร an on-policy one. With SC: 1.5ร
โข The culprit is a hidden drift term, an uncontrolled โAยทKL(ฮผโฯ) baked into the policy gradient. SC removes it
โ ๏ธ What SC + IS gets wrong
โข SC then IS โ adds a new drift
โข IS then SC โ a no-op without truncation; with truncation it centers on a distribution with no guarantee of being closer to ฯ
โข So "IS and SC are orthogonal" (from the SC paper) doesn't hold
Two wins on top of SC
1๏ธโฃ State-level KL mask: drop states where KL(ฮผโฯ) > ฯ, instead of masking by token-level ratios. It depends only on the state, so SC's baseline property survives. At age 127: 3/3 seeds climb steadily, while TIS+SC and MIS+SC spike and crash
2๏ธโฃ Random buffer sampling, a free lunch from the system: same buffer, sample at random instead of FIFO. Mean age 127 โ 52, better for every method at equal wall-clock
Recipe = SC + KL penalty + KL mask. At lr 4e-2 (w/ SGD), MIS+SC and DPPO collapse and TIS+SC swings, while every recipe seed trains and learns faster early
๐ค So far, weโve only tested on Countdown with Qwen3-0.6B (wants to scale it up!). When staleness is low, all the fixes perform similarly, but the differences become clearer as staleness increases. We also havenโt compared against sequence-level masking (which might already be enough!) or isolated kernel mismatch from async lag. Both are worth looking into next.
#llm #rl #asyncrl #reinforcementlearning -
Matei Zaharia reposted
Row Zero
@GetRowZero
You can now update tables in your data warehouse directly from your spreadsheets. Import a table using Row Zeroโs query builder, make your cell updates, and write your changes with a single click.
Learn more here: rowzero.com/docs/data-export?hss_channel=tw-1763181848614โฆ -
Matei Zaharia reposted
Databricks
@databricks
Genie Migrate for Lakehouse is now generally available!
Migrating to the lakehouse no longer has to mean manually rewriting SQL file by file. Built on Genie Code, Genie Migrate uses AI to convert proprietary warehouse SQL into open ANSI SQL on Databricks, automatically checking and refining its work.
Over 90% of files converted correctly in benchmarks across all seven sources.
Learn more: www.databricks.com/blog/genie-migrate-for-lakehouse-generโฆ -
Matei Zaharia reposted
Databricks
@databricks
We benchmarked Genie, powered by Genie Ontology, against two frontier agents on enterprise data tasks. Here's what we found.
In collaboration with @turingcom, we developed a benchmark that tests more than table queries. Agents had to use business knowledge spread across notebooks, dashboards, and saved SQL queries in a live Databricks workspace, running each agent five times per task.
Genie passed 91% of runs, compared with 45% and 58% for the other agents, while using less than half the tokens and finishing 3โ4ร faster.
The key difference is business context. A valid SQL query can still produce the wrong answer if it uses the wrong definitions or calculation rules.
Genie Ontology retrieves and prioritizes business knowledge, helping agents find and apply the right context instead of relying on table schemas alone.
Explore the benchmark and methodology: www.databricks.com/blog/genie-genie-ontology-delivers-16-โฆ -
Matei Zaharia
@matei_zaharia
Stats on how 10,000+ companies are using AI via Unity Gateway!
Patrick Wendell
@pwendell
1/ Today weโre publishing the Databricks AI Index, showing trends from enterprises who manage AI with our Unity Gateway. Data covers >10,000 companies with broad representation (Digital Natives, Fortune 500, Global 2000, etc...). Enterprise AI consumption is changing quite a bit:
-
Matei Zaharia reposted
Patrick Wendell
@pwendell
1/ Today weโre publishing the Databricks AI Index, showing trends from enterprises who manage AI with our Unity Gateway. Data covers >10,000 companies with broad representation (Digital Natives, Fortune 500, Global 2000, etc...). Enterprise AI consumption is changing quite a bit:
-
Matei Zaharia reposted
Databricks
@databricks
AI is moving beyond answering questions. It's writing code, analyzing data, and taking on entire business processes.
But powerful models alone aren't enough. They need access to the right company data, business context, and governance.
That's what our partnership with @OpenAI brings together:
โข Accelerating work for business users with ChatGPT + Genie
โข Coding with enterprise-level governance through Codex and Unity Gateway
โข Transforming business processes with GPT models and Databricks Apps
Three ways to bring frontier AI into the enterprise, built around the data and controls businesses already rely on.
See how it all works together: www.databricks.com/blog/openai-and-databricks-enterprise-โฆ -
Matei Zaharia reposted
Julia Neagu
@juliaaneagu
I am hiring a Researcher for my team at @databricks AI Research.
If you have a deep instinct for measuring complex systems and want to build self-improving agents at the frontier, I'd love to talk.
Link below ๐ -
Matei Zaharia
@matei_zaharia
Check out Automations in the new Omnigent release! They make it easy to create software factories where agents automatically handle bug reports, pull requests, etc using any mix of coding agents you want (Codex, Claude Code, etc).
Omnigent
@omnigent_ai
Omnigent 0.22.0 is now available. ๐
โก Automations can run on a schedule or start from Jira, Slack, GitHub, Linear, or PagerDuty events.
๐ The PR Changes tab adds file filters, diff search, viewed-file tracking, and per-commit diffs.
๐ฌ Tag sessions, sub-agents, and files in the composer.
๐๏ธ Agents spawned through the Omnigent MCP or created on the same managed sandbox now nest in the sidebar.
๐ฆ New AWS Lambda MicroVMs sandbox provider.
Full release notes โคต๏ธ
omnigent.ai/releases/0.22.0 -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
I saw @jack's BuilderLab talk on Buzz earlier this week in person. Awesome to see the future architecture of companies emerging with AI. We're excited to be a small part of Buzz at @databricks
www.databricks.com/blog/how-block-powers-collaborative-aiโฆ -
Matei Zaharia reposted
Ankit Mathur
@ankit_math
Really cool to see @bradleyaxen's team at @blocks ship their multi-agent collaboration factory Buzz using Unity Gateway! Software factories are the future.
www.databricks.com/blog/how-block-powers-collaborative-aiโฆ
Check it out here: app.builderlab.xyz/signup -
Matei Zaharia reposted
Databricks
@databricks
Gemini 4 Hydrogen is available on Databricks on Day 0.
Pair it with Carbon: Carbon plans and coordinates, Hydrogen executes and verifies sub-agent tasks. Google reports 2.5x faster task completion than Gemini 3.8 Flash.
Govern both through Unity Gateway ๐ซก
Google DeepMind
@GoogleDeepMind
Meet Gemini 4 Hydrogen: built for rapid coding, multimodal synthesis, and everyday workflows.
It finishes tasks 2.5x faster than 3.8 Flash and surpasses Argon on the @ArtificialAnlys Intelligence Index. -
Matei Zaharia reposted
Databricks
@databricks
Genie Agents can now analyze thousands of documents alongside governed data and take action inside your tools.
A table might show margins declining, but the explanation could be buried in analyst reports.
With unstructured data analysis now in public preview, Genie Agents can connect those findings in one conversation, with page-level citations.
The next step is action. Native MCP connectors are now generally available, letting agents take those insights further by creating tickets, updating records, and posting messages across enterprise tools.
www.databricks.com/blog/enterprise-context-action-genie-aโฆ -
Matei Zaharia reposted
Matt Kixmoeller
@mattkix
I've done a few launch events in my career, but this one was unique to just see @alighodsi turn around his laptop and show us how the new Genie makes him a 10X better @databricks CEO!
Join @alighodsi, @gdb, and crew at 9AM PST today or hit the replay:
www.youtube.com/live/BsVfRCNI8IY -
Matei Zaharia reposted
Rishabh Singh
@rishabhs
Enterprise context is key to making knowledge agents perform well in the real world.
Existing data and knowledge agent benchmarks primarily focus on tabular data, whereas actual enterprise tasks often require leveraging business context present in multiple sources such as dashboards, notebooks, historical queries, documents, and metric views.
We partnered with @turingcom to create a new benchmark that reflects this real-world enterprise complexity. We observed that Genie (powered by Genie Ontology) significantly outperforms frontier agents:
โข 1.6x accuracy
โข 4x faster
โข 50% fewer tokens
More details: www.databricks.com/blog/genie-genie-ontology-delivers-16-โฆ -
Matei Zaharia reposted
Databricks
@databricks
Introducing Databricks Genie plugins for ChatGPT, Claude, Microsoft Copilot Cowork and Grok Bot!
More data doesn't automatically mean better answers. An AI agent may find the right data but still use the wrong context.
Now, your agents can tap into Genie to access governed business context, investigate questions across data and documents, and return answers with citations, all within their existing workflow.
Build your Ontology once. Bring it to the AI tools your teams already use.
www.databricks.com/blog/bring-your-business-context-chatgโฆ -
Matei Zaharia reposted
Databricks
@databricks
๐ก๐ฒ๐ ๐ถ๐ป ๐๐ฒ๐ป๐ถ๐ฒ ๐ข๐ป๐ฒ: dynamic dashboards and slides, more ways to search, org directories, shareable skills, tracing, and more!
Work rarely stays in one application. Genie One brings search, finished work, and actions across connected tools into one home for AI cowork, grounded in Genie Ontology.
Through Unity Gateway, admins can trace sources and actions, control tool access and approvals, and manage usage and costs, helping teams scale AI cowork confidently.
www.databricks.com/blog/genie-one-ai-cowork-home-everyone -
Matei Zaharia
@matei_zaharia
Genie has transformed how I work as CTO at Databricks, even more than coding agents. It connects across production data, GitHub, Drive, Slack and the web, and automatically learns from this data (Genie Ontology), so I can ask it to do stuff like:
- Tell me how competitors position vs each of our products and which critiques are valid
- Find when and why a design decision was made
- Find bugs based on production events + code changes
- Prototype code changes that would speed up our slowest services in production
Really, it can do so much stuff that I would never even bother to ask a person that it totally changes how you work and the size of tasks you can take on directly. Learn more about our latest release of Genie: www.databricks.com/blog/new-genie-autonomous-ai-complex-eโฆ -
Matei Zaharia reposted
TechCrunch
@TechCrunch
At 12,000 employees, AI Ghodsi is the first to admit that he can't know everyone and that they are unlikely to confess the things that go wrong to him. But he doesn't need them to. He uses Databricks' newly revised Genie agent for that.
techcrunch.com/2026/11/11/databricks-new-ai-agent-tells-cโฆ -
Matei Zaharia reposted
Databricks
@databricks
๐๐ป๐๐ฟ๐ผ๐ฑ๐๐ฐ๐ถ๐ป๐ด ๐๐ต๐ฒ ๐ป๐ฒ๐ ๐๐ฒ๐ป๐ถ๐ฒ: an always-on, autonomous AI coworker that proactively handles long-running work within your organization's guardrails.
AI assistants can answer questions and run analyses. But most enterprise work is complex and continuous, requiring teams to track changes, follow up, and take action.
Genie Ontology is now generally available, providing the shared business context behind it. The agentic ontology now includes new knowledge sources and new ways to curate and govern that context.
New capabilities across Genie Agents and plugins extend that same context to more workflows and AI tools.
Here's what's new: www.databricks.com/blog/new-genie-autonomous-ai-complex-eโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
A year ago, I ran @databricks totally differently from today. Getting stuff done at Databricks involved calling ppl, scheduling meetings, and lots of back and forth.
Today, I just wake up and use Genie, which works for me in the background. I often just use the phone app to queue up work in the background.
Three examples from just this week:
โ Org charts. How do we flatten the org? It literally found me the hotspots where many projects had gotten stuck. Turns out the data was already in the ontology graph.
โ New internal project everyone raves about (Keanu). Genie monitored the slack channel, got all the insights, correlated them with the source code, and gave me a dashboard of what I needed.
โ New culture survey. Used ontology to figure out from the org chart, work output, and survey scores, which leaders are AI pilled. Why certain scores (e.g. work-life balance) are so low.
These are things that used to take me hours and many meetings, often waiting for the data science team. This is possible because Genie has access to an Agentic Ontology, so it proactively does all the work in the background for me.
Learn more about our next-generation release of Genie:
databricks.com/blog/new-genie-autonomous-ai-complex-enterโฆ -
Matei Zaharia reposted
Josue Bogran
@joshbogran
With all the talk about @AnthropicAI's entry into spreadsheets, here is an early preview of my interview + demo with former @GetRowZero CEO, recently acquired by @databricks. It seeks to bring spreadsheet, straight to where your data lives!
-
Matei Zaharia reposted
Databricks
@databricks
Gemini 4 Carbon. Day 0 on Databricks.
Google's strongest model for complex coding, scientific reasoning, and long-running agent workflows is available on Databricks the same day it opened to developers.
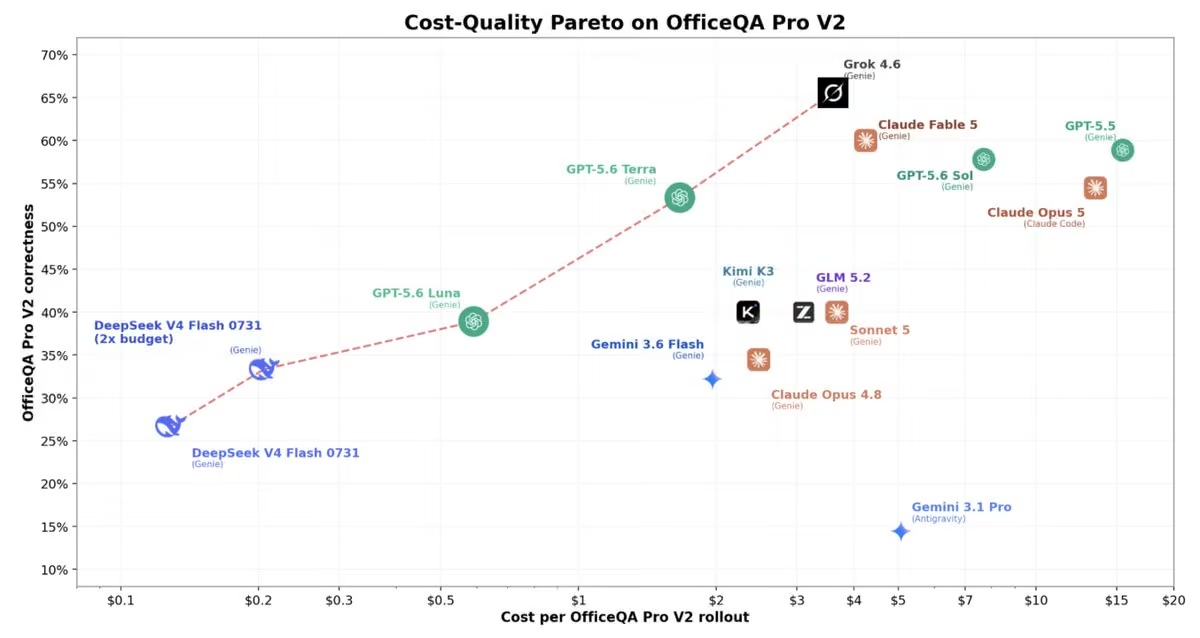
In our enterprise-document testing, Carbon scored 66.7% on OfficeQA Pro v2, compared with 57.8% for Gemini 4 Argon, our previous best Gemini result.
Now put it to work on your own data. Unity Gateway handles access, usage limits, and spend tracking across Carbon and every other model your teams use. -
Matei Zaharia reposted
Isaac Miller ๐งฉ
@isaacbmiller1
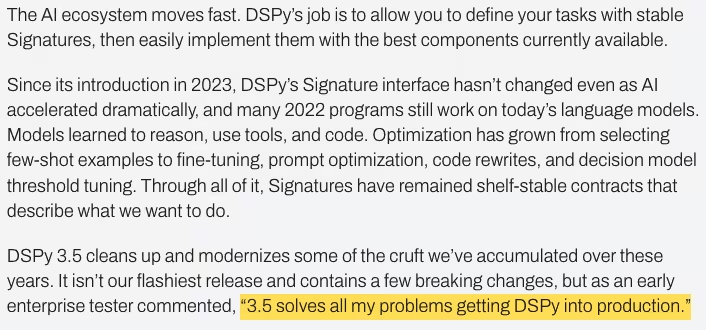
DSPy is now 85% smaller!
We just released DSPy 3.5 which makes DSPy lighter, faster, and a more reliable experience out of the box. -
Matei Zaharia reposted
Databricks
@databricks
Your app data is already in Postgres. Why move it somewhere else just to search it?
Lakebase Search brings vector, BM25 full-text, and hybrid search into the same database as your operational data. You can combine search with live data using SQL, without a separate search engine or ETL pipeline to maintain.
Now generally available on AWS and Azure. www.databricks.com/blog/lakebase-search-state-art-full-teโฆ -
Matei Zaharia reposted
Databricks
@databricks
Something's loading...
Tomorrow, join Databricks Co-founder and CEO @alighodsi, @OpenAI Co-founder and President @gdb, and other special guests for DATA + AI LIVE and a first look at the next generation of Genie, the data smart AI coworker.
Context is just the beginning.
9 AM PT. Save your spot:
www.linkedin.com/events/data-ailive-contextisjustthebeg75โฆ -
Matei Zaharia reposted
AI.Engineer ๐ CODE
@aiDotEngineer
From review comments to tested fixes.
Build a PR review and repair workflow with @omnigent_ai, led by Elise Gonzales and @bradfordc of @databricks.
Agent roles, permissions, repairs and validation. You leave with a runnable workflow.
Nov 10 at AIE CODE, San Francisco.
Workshop add-on required.
Apply: ai.engineer/code -
Matei Zaharia reposted
Databricks
@databricks
Claude Fable 5.2 lands on Databricks on Day 0.
Built for coding, finance and science, it sets a new high on our OfficeQA Pro v2 benchmark.
Run long-running agents on governed data, with Unity Gateway controlling calls across 70+ models.
Claude
@claudeai
Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
Theyโre capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Omnigent
@omnigent_ai
At QCon San Francisco, @ev_hur and @dennylee will present Multi-Agent Coding with Omnigent.
In this talk, they will cover how Omnigent works under the hood, how they use it to automate their own workflows, and what building it in the open has taught them.
๐๏ธ Wednesday, November 18
๐ Session details: qconsf.com/presentation/nov2026/multi-agent-coding-omnigent
#omnigent #opensource -
Matei Zaharia reposted
Databricks
@databricks
Join Databricks Co-founder and CEO @alighodsi and @OpenAI co-founder and President @gdb, and other special guests at DATA + AI LIVE to hear exciting announcements about the next generation of Genie, the data smart AI coworker.
Get a first look on Nov 11 at 9 AM PT. Save your spot: www.linkedin.com/events/7516902543436939264 -
Matei Zaharia reposted
Simons Institute for the Theory of Computing
@SimonsInstitute
Join us!
simons.berkeley.edu/events/accelerating-research-engineerโฆ -
Matei Zaharia reposted
Kasey Uhlenhuth
@kuhlenhuth
See how @Ubisoft managed their tokenomics for coding agents with @databricks #unitygateway. Their devs get frontier & open models in native terminals/UI (!!!) while their platform team tracks consumption and uses alerts to monitor rising costs. www.databricks.com/customers/ubisoft/unity-gateway
-
Matei Zaharia reposted
Databricks
@databricks
Agents can build software. But what about the databases behind it?
Databricks VP of Engineering and @neondatabase co-founder @nikitabase joined @MTSlive to talk about database branching, serverless architecture, and building for both AI agents and enterprise workloads. -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
This is an awesome video on how Lakeflow Designer works! If you use Alteryx, then this is a must see video!
Josue Bogran
@joshbogran
As a long time fan of making @databricks accessible to everyone, I love how it is easier and easier for business users with limited technical background to use many of Databricks' capabilities. Check out Lakeflow Designer: youtu.be/IkgV9KWGksA
-
Matei Zaharia reposted
Josue Bogran
@joshbogran
As a long time fan of making @databricks accessible to everyone, I love how it is easier and easier for business users with limited technical background to use many of Databricks' capabilities. Check out Lakeflow Designer: youtu.be/IkgV9KWGksA
-
Matei Zaharia reposted
Databricks
@databricks
Introducing Apache Sparkยฎ 4.3, now available in Databricks Runtime 19!
The release brings major new capabilities across real-time processing, history-preserving pipelines, small-data performance, Spark Connect, and SQL.
Whatโs new:
- Bring state to Real-Time Mode with streaming aggregation and transformWithState
- Preserve history with SCD Type 2 Auto CDC
- Iterate faster on small data with Project Feather
- Reach Spark from more applications with expanded Spark Connect capabilities
It also begins a new quarterly feature-release cadence, bringing completed improvements to users sooner.
Get started: www.databricks.com/blog/introducing-apache-spark-43-now-aโฆ -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
crazy - the real bitter lesson: ~no emergent behaviors, only emergent data industries
Idan Mann
@mann_idan
weโre buying traces of engineers modifying weights like this plus related engineering tasks!
comment a description of your data, and Iโll dm you if weโre interested.This post is unavailable. See it on X. -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
We're launching Kimi K3.1 Pro on Databricks on Day 0!
It's the best oss model to date. Our team has already started using it for internal coding.
Excited to be a launch partner with Moonshot AI!
Kimi.ai
@Kimi_Moonshot
Releasing the model weights of Kimi K3.1 Pro: huggingface.co/moonshotai/Kimi-K3.1-Pro
We'll keep advancing open intelligence. -
Matei Zaharia reposted
Sam Willis
@samwillis
Absolutely incredible showcase of what can be built with @neondatabase Realtime! ๐๐
It's not just cursors that sync, the full state of the document is a set of live queries straight from Postgres - that's all it take to keep all users in sync!
OrcDev
@orcdev
Introducing orcanva.app
A fully open source and 100% free multiplayer Canva alternative.
I make all my thumbnails here. It's simple and easy to use.
You can jump into public designs with other people, no signup needed. Perfect for making memes live. -
Matei Zaharia reposted
Ivan Zhou
@ivanzhouyq
Weโve been cooking up smart routing at Databricks. It is cutting our internal coding costs, and many engineers didnโt even notice it was on.
The new one will come soon to Databricks Unity Gateway. DM me if youโd like to try it first.
Yuchen Jin
@Yuchenj_UW
AI bills are exploding everywhere.
Since joining Databricks, I've seen brilliant engineers across the industry (Distinguished Engineers, Berkeley/MIT/Stanford PhDs) spend months figuring out where to buy AI tokens.
Let me save you some time.
Choose Databricks AI Gateway:
- Fast open-source and proprietary models, available on Day 0.
- Smart Routing cut our internal coding costs by 35%.
- Easily track spending and set budgets across teams.
Spend less time managing AI tokens. Spend more time building. -
Matei Zaharia reposted
Shiyi Cao
@shiyi_c98
1/n
Introducing our NeurIPSโ26 work ๐Evolving Agent Teams (EAT) ๐, where a supervisor diagnoses why an agent team stalls and restructures it to escape local optima, for long-running optimization tasks.
EAT shows superior performance across domains:
๐ Open Kernel Challenge, decode layer on H200: 2.449ร over SGLang, #4 of 1,180 (as of Nov 1, 2026)
โก๏ธ NVIDIA kernels: KDA prefill on B200, 3.44ร over FlashKDA (previous best: 2.96ร)
๐ฅ AMD kernels: KDA prefill on MI350X, 3.01ร over vLLM
๐ป MoE serving on Mac: Qwen3.8-Flash-Next (Unsloth UD-IQ4_XS GGUF) on M5 Pro, ~3.3ร faster prefill (930 tok/s) and 1.22ร faster decode (43.7 tok/s) than Strata at the same memory
๐ฆพ RoboDojo: 62.1 on held-out seeds (the best leaderboard entry as of Oct 26, 2026 is 55.3)
- Paper: arxiv.org/abs/2610.36848
- Code: github.com/caoshiyi/EAT
๐งต๐ -
Matei Zaharia reposted
AI.Engineer ๐ CODE
@aiDotEngineer
Cheap tokens can still mean an expensive coding task.
Hear @ankit_math of @databricks at AIE CODE.
Thank you to Databricks, a Platinum Sponsor.
November 10 to 12, San Francisco.
Apply: ai.engineer/code -
Matei Zaharia reposted
Databricks
@databricks
AI research is changing as agents take on more of the experimentation loop.
Instead of manually running every trial, our researchers increasingly use agents to propose changes, launch parallel experiments, evaluate results, and decide what to try next.
Across our AI Functions research workloads, training jobs have grown 8x.
At that scale, launch latency and GPU reliability become critical. Here's how we're using AI Runtime to keep up with the pace of agent-driven research.
www.databricks.com/blog/how-our-ai-research-team-uses-ai-โฆ -
Matei Zaharia reposted
Databricks
@databricks
Stripe Data Pipeline now supports real-time sync to Lakebase Postgres!
With updates arriving within seconds, apps can use SQL to manage feature access, display billing details, and deliver personalized offers.
www.databricks.com/blog/stripe-data-pipeline-now-syncs-reโฆ -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
It's important to understand what this unlocks. We are calling it "playable" environments.
Where agents can instantly load up many exact copies of production. What else is playable? Chess, Go, Starcraft, Math (Lean). All of cloud software is next.
Evis Drenova
@evisdrenova
the next version of cloud infrastructure will need to be able to branch infrastructure top to bottom in milliseconds
Not just sandboxes, but also databases, networking, VPCs, IAM etc.
simulations environments are the next test environments -
Matei Zaharia reposted
Databricks
@databricks
Agents shouldn't have to relearn the same facts every session.
Agent Memory on Agent Bricks combines session history with distilled long-term memories. A background pipeline extracts durable facts, removes duplicates, and replaces information contradicted by newer conversations. Lakebase provides low-latency access.
In our internal benchmarks of enterprise data tasks, this memory architecture tripled agent pass rates while using 31% fewer tokens compared to agents without memory.
www.databricks.com/blog/introducing-agent-memory-databricks -
Matei Zaharia reposted
James Arthur
@thruflo
Starts in an hour -- 6pm CET / 10am PT.
Francesco Ciulla
@FrancescoCiull4
Neon just shipped Realtime: any SQL query becomes a live query, no polling, all inside Postgres.
Trying it live Thursday at 6PM CET, building a real-time Q&A board with @neondatabase from scratch.
Set your reminder:
www.youtube.com/watch?v=nXB2B1nSfng -
Matei Zaharia reposted
Sam Willis
@samwillis
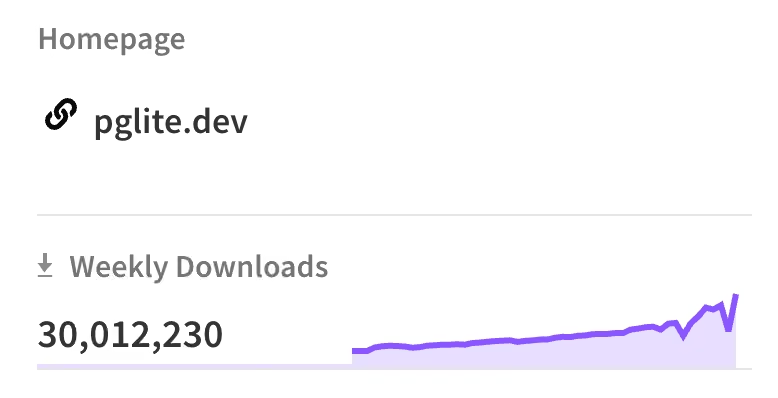
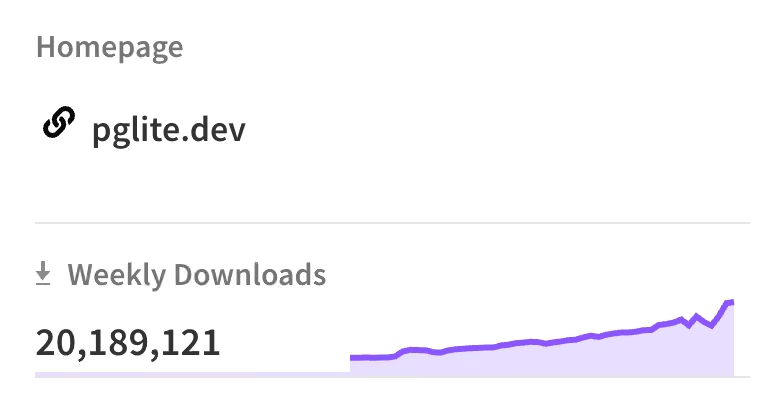
Well... PGlite just crossed 30 MILLION downloads / week ๐คฏ
-
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent v0.20.0 is now available! ๐
๐ Merge, edit, label, and review PRs in the Pull Requests tab, including auto-merge off, reviewers, and comments
โ๏ธ Databricks Sandboxes can run as managed hosts as you, with no SSH and no shared credential inside the Sandbox
๐งฉ Type /mcp in the composer to see a session's MCP servers and whether each is connected
omnigent.ai/releases/0.20.0
#omnigent #opensource -
Matei Zaharia
@matei_zaharia
Great writeup on what Databricks is and how our tech fits into the broader changing nature of work and companies!
-
Matei Zaharia reposted
a16z
@a16z
Every company can rent the same frontier models, so the edge comes from what a company's agents learn about its own business. Databricks' answer is a system of record built for agents.
Before an agent can be trusted with real work, that record has to tell it:
1. What's true: the company's own data
2. What it means: how the business defines things (grounding agents in it raised accuracy from about 50% to 84.5% in Databricks' testing)
3. What it's allowed to do: an identity, a budget, and guardrails
4. Whether it worked: grading against the company's own definition of good
Feed every correction back into the record, and the company keeps what it learns even when the model changes.
"If you replace the AI model at your company and the new one inherits your definitions, permissions, evaluated cases, customer history, and hard-won exceptions, that is a foundation for a sustainable competitive advantage."
From the latest Profiles of the Future by @bhorowitz and @mikemcg0 on Databricks & the Future of the Firm: www.a16z.news/p/databricks-and-the-future-of-the -
Matei Zaharia reposted
a16z
@a16z
About a decade ago, Databricks got an acquisition offer at roughly six times its valuation at the time. CEO Ali Ghodsi tells the story of the conversation with Ben Horowitz that made him turn it down:
Ben: "You just don't get this good of a market opportunity with this good of an entrepreneur. That's the rarest of rare things."
"We see great entrepreneurs, but their market opportunity is limited, and then we see companies that have a great market opportunity, but the entrepreneur is not big enough to fulfill that... But this was a case where we had both."
Ali: "The acquisition offer was on the table... I had made the mistake of telling my co-founders, and they were like, 'Take your hands off the keyboard. Nobody work anymore. We're done here. Let's count my money.'"
"And I was like, 'Maybe they're right. Maybe we should just sell.' And I remember having that conversation with Ben."
"He said, 'If you sell for this number, it's really great for me. I'll pay the investors back many times over... But if you're like me, you're gonna look back the rest of your life thinking, I missed that one shot. I should have taken it all the way. And now I'll never know how far I could have taken it. So do you wanna live with that, or do you wanna just have the money?'"
"And I was like, 'Okay, thanks.' Hung up the phone. 'We're never doing this. This is not happening.'"
@alighodsi @bhorowitz
Read the latest Profiles of the Future by @bhorowitz and @mikemcg0 on Databricks & the Future of the Firm: www.a16z.news/p/databricks-and-the-future-of-theThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
-
Matei Zaharia reposted
Neon
@neondatabase
We shipped a new search experience for the Neon docs, built entirely on Neon primitives.
Neon docs search now uses our Lakebase Search extensions, is served by a Neon Function, and uses Neon AI Gateway for embeddings and reranking!
Read more here: neon.com/blog/neon-docs-search-lakebase-search?v3 -
Matei Zaharia reposted
Pieter Abbeel
@pabbeel
We 'll be hiring very actively at Berkeley!
Assistant/ Associate/ Full Professor โ Electrical Engineering & Computer Sciences (Deadline: Dec. 7, 2026 at 11:59 pm Pacific Time). Apply here: aprecruit.berkeley.edu/JPF05591
Assistant Professor โ AI for Biology โ Electrical Engineering & Computer Sciences and Center for Computational Biology (Deadline: Nov. 9, 2026 at 11:59 pm Pacific Time) Apply here: aprecruit.berkeley.edu/JPF05560
Assistant Professor โ Intersection of Statistics and CS โ Departments of Electrical Engineering & Computer Sciences and Statistics (Deadline: Nov. 10, 2026 at 11:59 pm Pacific Time). Apply here: aprecruit.berkeley.edu/JPF0556
Assistant/ Associate/ Full Professor โ Computational Biomedicine - Center for Computational Biology (Deadline: Nov. 18 2026 at 11:59 pm Pacific Time). Apply here: aprecruit.berkeley.edu/JPF05568
Assistant / Associate Professor โ Electronic, Functional, and Quantum Materials โ Electrical Engineering & Computer Sciences and Materials Science & Engineering (Deadline: Dec. 7, 2026 at 11:59 pm Pacific Time). Apply here: aprecruit.berkeley.edu/JPF05584
Coming Soon! Assistant/ Associate/ Full Professor - AI and the Physical Sciences -Bakar Institute of Digital Materials for the Planet (BIDMaP) and home department(s) to be determined. (Deadline: Dec. 7, 2026 at 11:59 pm Pacific Time) Apply here: aprecruit.berkeley.edu/JPF05619
Coming Soon! Assistant/ Associate/ Full Professor-in-Residence - Gladstone Institute of Data Science and Biotechnology and home department(s) to be (Deadline: TBD at 11:59 pm Pacific Time) Apply here: aprecruit.berkeley.edu/JPF05621 -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
AWS is sold out. Meanwhile, how much capacity is sitting in idle, over-provisioned RDS instances?
Lakebase architecture is the future: compute scales based on load and it's never wasted on idle databases
a16z
@a16z
Five years into his run as CEO, Andy Jassy has nearly tripled the size of AWS, grown Amazon's revenue by about 80%, and expects to spend $220 billion this year to win AI. Amazon's AI business hit a $25 billion run rate in three years, growing several hundred times faster than early AWS.
Jassy joins a16z's Ben Horowitz and Erik Torenberg to discuss the decisions behind that run, from rebuilding Amazon's fulfillment network after the pandemic to the AWS origin story.
They also cover why data centers became a political fight, Amazon's custom chips, its stakes in Anthropic and OpenAI, why inference needs to get 10x cheaper, AI's most underrated risk, and why every company will have to reinvent its products from scratch, plus Jassy's advice for anyone who's 18 today.
0:47 How Amazon has changed since 2021
1:51 How the pandemic reshaped retail
3:30 Why AI supercharged AWS's growth
5:20 When leadership principles clash
9:36 $60M vs. $25B: early AWS vs. early AI
13:20 How the AI CapEx cash cycle works
15:44 Why the US must build data centers
20:55 The labs-to-enterprise AI barbell
23:12 Demand vs. longtime AWS customers
28:11 Annapurna, Graviton, and Trainium
33:55 Backing Anthropic and OpenAI
37:15 Why AI means smaller teams
42:13 AI's underrated risk: security
46:29 Why Amazon rewired Alexa's brain
53:07 What Jassy tells his kids about AI
56:36 Betting on AI, robotics, and space
YouTube: youtu.be/-YMMRQ1qscI
@ajassy @Amazon @bhorowitz @eriktorenbergThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
1/ ๐ฐMulti-vector retrieval shouldnโt charge you by the token!
๐ Excited to share FLINT (Fixed-budget Late INTeraction), a late-interaction retriever designed for long, complex queries with up to 89% reduction in index and 23-170ร faster retrieval latency.โก
๐๏ธ FLINT gives a vector-budget knob to balance storage, latency, and quality.
๐ Paper: arxiv.org/abs/2610.27273
How does it work? ๐งต
ColBERT stores and compares one vector per token. FLINT pools every query and every document into a fixed number of vectors, so thereโs far less to store and far fewer comparisons at search time. -
Matei Zaharia reposted
Shicheng Liu
@ShichengGLiu
(1/n) Before trusting AI to make scientific discoveries, can it reproduce existing research - and go one step further to test whether conclusions survive reasonable alternative analytical choices?
Sharing work from this summer with @DbrxMosaicAI, @StanfordNLP, and @StanfordOVAL on using AI agents to reproduce published medical findings and autonomously investigate analytical choices that could change their conclusions. -
Matei Zaharia reposted
OrcDev
@orcdev
My first ship at Neon is live ๐ข
The official @neondatabase AI Gateway adapter for @tan_stack AI.
Huge thanks to @AlemTuzlak for an awesome collaboration on this one. TanStack team is amazing!
tanstack.com/ai/latest/docs/adapters/neon
OrcDev
@orcdev
I joined @neondatabase ๐
I'll be doing DX and leading open source at Neon. Also I guess I'm their mascot now. ๐
Orcs are green. Neon is green. It was meant to be. ๐ข
I love Neon, and I love the team even more. This move just made sense.
The channel stays OrcDev. Same orc. Same Horde.
Follow along. Things are about to get interesting ๐ -
Matei Zaharia reposted
Brendan (can/do)
@BrendanFoody
Weโve automated a very low percentage of enterprise tasks with AI.
Thatโs @jefrankleโs estimate, and he thinks the models are already smart enough to do significantly more.
Jonathan is the Chief AI Scientist at Databricks, co-founder of MosaicML, and my latest guest on The Frontier.
We talked about why evals are the biggest bottleneck to enterprise AI adoption. The intelligence is increasingly there, but enterprises need to figure out how to define what they want agents to do and measure whether theyโre doing it well.
Full episode below ๐This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
jacqueline
@jacquelineli_
Jev 1.14 is out on @databricks
Built for fast decisions and complex tasks, weโre excited to partner with @typesafeai to bring Jev to all our customers!
Enable it for your account and try it out today ๐
docs.databricks.com/aws/en/machine-learning/foundation-moโฆ -
Matei Zaharia
@matei_zaharia
Databricks AI Runtime (AIR) is now GA, offering an easy and super-fast way to launch GPU workloads. Unlike provisioning your own GPU servers, you get GPUs with your code in seconds, with easy access to all your data. This is especially relevant now that agents can automate much of AI training, and want to scale up/down experiments quickly. Read how companies like Robinhood, Superhuman, Factset and Merck have been using AIR to accelerate AI training: www.databricks.com/blog/ai-runtime-generally-available
-
Matei Zaharia reposted
Liana
@lianapatel_
very cool to see TokenGate already trending on @askalphaxiv โ and only a few hours since our release ๐
๐super excited for this work. check it out and share your questions!
(links in comments)
Liana
@lianapatel_
Introducing โจToken-Gated Language Modelsโจ for up to 11x faster prefill by learning to skim context, conditionally forwarding only tokens that matter.
Akin to the shift from dense models to MoEs, the next frontier of efficient LLMs is conditional computation over a new scaling axis: context tokens๐งต๐ -
Matei Zaharia
@matei_zaharia
Great work on fast long-context prefill. TokenGate is a trainable module that works with existing models to make long-context inference much more efficient.
Liana
@lianapatel_
Introducing โจToken-Gated Language Modelsโจ for up to 11x faster prefill by learning to skim context, conditionally forwarding only tokens that matter.
Akin to the shift from dense models to MoEs, the next frontier of efficient LLMs is conditional computation over a new scaling axis: context tokens๐งต๐ -
Matei Zaharia reposted
Liana
@lianapatel_
Introducing โจToken-Gated Language Modelsโจ for up to 11x faster prefill by learning to skim context, conditionally forwarding only tokens that matter.
Akin to the shift from dense models to MoEs, the next frontier of efficient LLMs is conditional computation over a new scaling axis: context tokens๐งต๐ -
Matei Zaharia
@matei_zaharia
Hereโs how weโre building memory in Genie and the new Agent Bricks Memory service you can use in your own agents. MemCurrent automatically synthesizes new memories from traces to produce better results than alternatives.
Databricks
@databricks
Introducing MemCurrent, a persistent memory architecture designed to help production agents stop starting from zero.
MemCurrent combines episodic memory with derived memory across three access patterns:
โข Plugins to log and load context automatically
โข Tools the agent calls on demand
โข An offline โdreamingโ pipeline that consolidates memory in the background
Agents carry forward user preferences, prior corrections, metric definitions and successful workflows instead of rediscovering them every session.
On our internal benchmark built from real enterprise data, MemCurrent triples the agent's pass rate while using 31% fewer tokens and running 26% faster. It's built into Agent Bricks' Memory offering and already powers memory in Genie.
Read the research: www.databricks.com/blog/memcurrent-designing-persistent-mโฆ -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent v0.19.0 is now available! ๐
๐ MCP registry and gateway: connect managed accounts in Settings, pick tools for local hosts or sandboxes through a server gateway with shared policy checks
๐ Sandboxed agents use approved Git repos over SSH without receiving the key
๐๏ธ Set reasoning effort for Claude SDK and Codex SDK agents from the web composer
Release notes: omnigent.ai/releases/0.19.0
#omnigent #opensource -
Matei Zaharia reposted
Databricks
@databricks
Introducing MemCurrent, a persistent memory architecture designed to help production agents stop starting from zero.
MemCurrent combines episodic memory with derived memory across three access patterns:
โข Plugins to log and load context automatically
โข Tools the agent calls on demand
โข An offline โdreamingโ pipeline that consolidates memory in the background
Agents carry forward user preferences, prior corrections, metric definitions and successful workflows instead of rediscovering them every session.
On our internal benchmark built from real enterprise data, MemCurrent triples the agent's pass rate while using 31% fewer tokens and running 26% faster. It's built into Agent Bricks' Memory offering and already powers memory in Genie.
Read the research: www.databricks.com/blog/memcurrent-designing-persistent-mโฆ -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Using agents raises two practical questions: what are they allowed to do, and how much are they spending?
Julia Fรธrde and Zoรซ Van Noppen cover both questions in part two of their Omnigent series: stateful policies, session and user-period budgets, cost views, smart routing, and Unity Gateway for traffic that goes through it.
๐ Read the full post:ย databricksdecoded.substack.com/p/omnigent-part-2-control-โฆ
#omnigent #aiagents #opensource -
Matei Zaharia reposted
Ivan Zhou
@ivanzhouyq
Over the course of the past year, my research team at @databricks has completely shifted from manually running every experiment to having a swarm of agents run experiments for us. As a result, the training workloads of my research team have skyrocketed and continue to rise.
Fortunately, we have a very scalable GPU infra named AIR. Through AIR, our agents can easily provision GPU endpoints for training models of various sizes (<1B to 1T+) and monitor their status.
The agent swarm + AIR give us an infinite amount of execution power, so our focus has shifted towards defining crystal-clear goals and reviewing the outcomes. Our models come out more quickly, the quality goes up, the speed increases, and new products also get launched more quicklyโฆ
AIR is now available for all @databricks customers to use. We dogfood our own product first ;) Now you should be able to unleash your AI research team with infinite execution power as well. -
Matei Zaharia reposted
Neon
@neondatabase
Getting Stripe data into your app just got a lot easier. @stripe Data Pipeline now syncs subscriptions, customers, and invoices straight into Neon, in real time
-
Matei Zaharia reposted
Databricks
@databricks
Decide faster. TypeSafe's Jev-1.14 is now available on Databricks.
Jev isn't a text generator. It's a structured decision model. It classifies, scores, and returns calibrated probabilities, resolving each decision in roughly 70 to 500 milliseconds, 20 to 200 times faster and up to 400 times lower cost than standard LLMs. For Databricks customers, that means real-time decisioning across millions of records at a fraction of the cost.
With our frictionless access, you can get started testing Jev right away. Put Jev to work directly on the data in your Lakehouse through ai_classify and ai_decide. Tag documents, route records, and score decisions across millions of rows, with every call governed, monitored, and secured by Unity Gateway.
Try Jev โ dbricks.co/3TQncpg -
Matei Zaharia
@matei_zaharia
All Neon databases now support live queries with Neon Realtime! This was much easier to build with the disaggregated architecture of lakebase, and enables so many new user experiences.
Anthony Giuliano
@ant_giuliano
As a longtime @neondatabase user, there is one feature that I have always wanted.
Well...This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Reynold Xin
@rxin
Built by the Electric team (who also did pglite, i.e. Postgres on WASM), Neon Realtime is an incremental query engine to make it dramatically easier to build apps that sync data in realtime.
It leverages the Lakebase architecture's separation of storage and compute to run on a separate compute instance. This avoids overwhelming the primary write Postgres instance and pushes the write operations incrementally to all the subscribers.
Check it out. You can now build complex realtime sync apps in just a few lines of code. This is a great example of how hardcore database technologies can make the app developers' lives much simpler.
Neon
@neondatabase
Neon now has realtime, built by the team behind Electric. Turn any SQL query into a live query, joins and aggregates included. All inside Postgres, and ready for agents.
Itโs in public beta and available in all Neon plans. Give it a try and tell us what you think! -
Matei Zaharia
@matei_zaharia
Cool results making auto-research / AI-based optimization better by having agents forget! Turns out that just running an agent for a long time can lock it into small steps in the same direction.
Shangyin Tan
@ShangyinT
Autoresearch with coding agents can now run for days on a single problem, but we've seen an increasing number of cases where they stop improving early. We address this issue with a simple idea: forgetting.
Introducing our new paper: "Scaling Discovery Requires Forgetting" -
Matei Zaharia reposted
Shangyin Tan
@ShangyinT
Autoresearch with coding agents can now run for days on a single problem, but we've seen an increasing number of cases where they stop improving early. We address this issue with a simple idea: forgetting.
Introducing our new paper: "Scaling Discovery Requires Forgetting" -
Matei Zaharia reposted
Sam Willis
@samwillis
Iโm so very excited that Neon Realtime is out! ๐๐
Live reactive SQL queries, straight from Postgres
Subscribe to ANY query from the front end, and it will been updated in realtime.
To do this we built a brand new sync/query engine, running inside Postgres.
For anyone whoโs worked on a sync engine, being inside Postgres is a bit like being in a sweet shop, itโs all we ever wanted! Everything we could possible need is just there and ready to use.
Weโre going to be writing more about how we built it in the coming weeks, but want to say Iโm indelibly proud of what the team have achieved, itโs very VERY cool.
Iโm looking forward to seeing how our users get on with it!
If you have any questions, give me a shout!
Neon
@neondatabase
Neon now has realtime, built by the team behind Electric. Turn any SQL query into a live query, joins and aggregates included. All inside Postgres, and ready for agents.
Itโs in public beta and available in all Neon plans. Give it a try and tell us what you think! -
Matei Zaharia reposted
Databricks
@databricks
Gemini 4 Argon is available on Databricks today, day 0๏ธโฃ.
We had early access and ran it through our internal benchmarks. It's the strongest @Google Gemini model we've tested, with the best results on our internal coding tasks and OfficeQA Pro V2, our flagship enterprise agentic benchmark.
Point it at the data already in your Lakehouse. Unity Gateway handles governance, monitoring, and security for every call.
Try Gemini 4 Argon โ docs.databricks.com/aws/en/release-notes/product/2026/octโฆ -
Matei Zaharia
@matei_zaharia
Welcome to the Lakebase team, Responsive! There's really exciting stuff brewing in the database space.
Apurva Mehta
@apurva1618
Iโm excited to announce that Responsive has been acquired by Databricks to accelerate the development of Lakebase and Neon!
We couldn't be more excited to join the Lakebase team. We've long admired their technical vision, and the more we got to know them, the more impressed we became by their ambition, execution, and momentum. It feels like a natural home for us.
I want to thank Responsiveโs customers, investors, and especially the team. More than anything, Iโm grateful for the trust youโve placed in us through the good times and the tough times.
Onward and upward! -
Matei Zaharia reposted
Reynold Xin
@rxin
Super excited to welcome the Responsive team to @Databricks/@neondatabase to help take Lakebase Postgres to the next level. The best database is a lakebase!
Apurva Mehta
@apurva1618
Iโm excited to announce that Responsive has been acquired by Databricks to accelerate the development of Lakebase and Neon!
We couldn't be more excited to join the Lakebase team. We've long admired their technical vision, and the more we got to know them, the more impressed we became by their ambition, execution, and momentum. It feels like a natural home for us.
I want to thank Responsiveโs customers, investors, and especially the team. More than anything, Iโm grateful for the trust youโve placed in us through the good times and the tough times.
Onward and upward! -
Matei Zaharia reposted
Apurva Mehta
@apurva1618
Iโm excited to announce that Responsive has been acquired by Databricks to accelerate the development of Lakebase and Neon!
We couldn't be more excited to join the Lakebase team. We've long admired their technical vision, and the more we got to know them, the more impressed we became by their ambition, execution, and momentum. It feels like a natural home for us.
I want to thank Responsiveโs customers, investors, and especially the team. More than anything, Iโm grateful for the trust youโve placed in us through the good times and the tough times.
Onward and upward! -
Matei Zaharia reposted
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
Today at #colm2026 I will present DeepScholar-Bench and how we can evaluate AI-generated research synthesis!
๐ Imperial Ballroom, Poster #72
๐ Today, 11 AMโ1 PM
Come stop by! Would love to chat!
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
I'll be BARTing over to #colm2026 this week ๐๐
Around all week and happy to chat about search agents & deep research systems!
๐ Thu: DeepScholar-Bench
arxiv.org/abs/2508.20033
๐ Fri: Multi-Agent Transactive Memory @ Lifelong Agents Workshop
arxiv.org/abs/2606.19911 -
Matei Zaharia reposted
Databricks
@databricks
Anthropic's latest model, Claude Haiku 5.5, is now being made available, as a Day 0 launch, on Databricks!
It is the cheapest, fastest, and most capable small model Anthropic has ever released. On Databricks' OfficeQA Pro V1 benchmark, Claude Haiku 5.5 delivers ~15% higher quality than Haiku 4.5 at a fraction of the cost.
Run Haiku 5.5 & 60+ other models on the data that already sits in Databricks and power your agentic apps and agents. Unity Gateway takes care of governing, monitoring, and securing every call as you scale.
Try Claude Haiku 5.5 โ dbricks.co/3TQncpg -
Matei Zaharia reposted
Omnigent
@omnigent_ai
A debugging session or a multi-agent run can rack up a big LLM bill before anyone notices.
This blog by @TerryTangYuan covers how Omnigent handles that. Smart routing keeps trivial tasks off expensive models. Progressive budgets warn before they block expensive models. The Usage page shows spend by model, harness, and session.
Read the full post ๐ omnigent.ai/blog/stop-surprise-llm-bills
#omnigent #aiagents #opensource #llmops -
Matei Zaharia reposted
Databricks
@databricks
Databricks is bringing databases up to AI speed.
โLakebase, a ground-up rearchitecture of databases, can spin them up and shut them down at AI speeds, facilitating the multitude of small, fast workloads of AI-driven development.โ
Excited to see Lakebase in @FastCompany's Next Big Things in Tech issue. dbricks.co/4zfhoov -
Matei Zaharia reposted
Sam Willis
@samwillis
PGlite has hit **20 Million Downloads / Week!**
Absolutely mind blowing the growth we are seeing ๐คฏ๐
We have a bunch of stuff planned, including Postgres v19 support soon after it's release later this month. -
Matei Zaharia reposted
Neon
@neondatabase
Major update to the Free Plan: you now get 0ฬถ.ฬถ5ฬถ ฬถGฬถBฬถ 1 GB of Postgres storage per project, 100 projects still included.
This is made possible by efficiencies of scale as we grow. We're creating new projects at a rate of more than one per second!
Go build. -
Matei Zaharia reposted
Tasso Argyros
@tasso
Not every marketer is familiar with Databricks today, but that's about to change!
Marketing agents simply do not work without real-time customer+business context. Databricks' CustomerLake is quickly becoming the cornerstone of the marketing stack of the future, providing just that.
It was great discussing all of that on stage at Braze's Forge conference. Thank you for having me, @jon_hyman! -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Everyone has been obsessed by Jev and what it can do, and they should be! Fast typed decisions >> slow text generation. It's a complete game changer. But how do you do that with all the data you have?
We just dropped ๐๐_๐๐๐๐๐๐(), which runs decision models natively on all your data in @databricks . Now you can run system one decisions on all your big data, see screenshot.
www.databricks.com/blog/introducing-aidecide-make-fast-deโฆ -
Matei Zaharia reposted
Databricks
@databricks
How much of your AI workload is really just making a decision?
ai_decide is a new Databricks AI Function built for fast, structured decisions over governed data. It classifies, scores and chooses what happens next in a fraction of a second, with lower latency and cost than an LLM on similar tasks.
Use it for model routing, document processing, agent evaluations and real-time app logic ๐ www.databricks.com/blog/introducing-aidecide-make-fast-deโฆ -
Matei Zaharia reposted
Neon
@neondatabase
Build Personal Agents Hack ยท Sun, Oct 4 ยท San Francisco
Total prize pool: $279,500
+ $1,625 in credits for every hacker
RSVP: luma.com/build-agentsThis media couldn't be displayed. See it on the original post.
Neon
@neondatabase
Oct 4, San Francisco
luma.com/build-agentsThis media couldn't be displayed. See it on the original post. -
Matei Zaharia
@matei_zaharia
Run decision models at scale in your SQL and Spark queries!
Jane Zhang
@jjanezhang
๐ Introducing Databricks AI Decide: make fast decisions on your governed data
Following the TypeSafe AI Jev launch, weโve seen increasing demand for a fast, low-cost API that turns raw text into structured decisions. However, many of our enterprise customers are unable to use Jev due to data privacy and access concerns.
AI Decide is our enterprise-grade function for fast decisions on customerโs governed data. It is supported for batch use cases like processing millions of documents with SQL and for realtime applications like model routing through our REST API. Starting early next week, customers will also be able to govern permissions on the ai_decide function through Databricks Unity Gateway.
A big shoutout to @mattydtweetz @ivanzhouyq @nihit_desai @hanlintang for getting this new function launched in less than a week! -
Matei Zaharia reposted
Jane Zhang
@jjanezhang
๐ Introducing Databricks AI Decide: make fast decisions on your governed data
Following the TypeSafe AI Jev launch, weโve seen increasing demand for a fast, low-cost API that turns raw text into structured decisions. However, many of our enterprise customers are unable to use Jev due to data privacy and access concerns.
AI Decide is our enterprise-grade function for fast decisions on customerโs governed data. It is supported for batch use cases like processing millions of documents with SQL and for realtime applications like model routing through our REST API. Starting early next week, customers will also be able to govern permissions on the ai_decide function through Databricks Unity Gateway.
A big shoutout to @mattydtweetz @ivanzhouyq @nihit_desai @hanlintang for getting this new function launched in less than a week! -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent v0.16.0 is now available! ๐
This release updates desktop onboarding, the workspace browser, sandbox controls, and agent configuration.
๐งญ Redesigned desktop onboarding
๐๏ธ Unified workspace browser
๐ฆ Sandbox copy-on-write and clones
๐ Admin sharing and Slack defaults
๐งฉ Pi prompt controls, plus native images for supported harnesses
Full release notes ๐ omnigent.ai/releases/0.16.0
#omnigent #aiagents #opensource -
Matei Zaharia reposted
Phillip Isola
@phillip_isola
Students sometimes ask me if it still makes sense, in this accelerating age, to pursue a PhD in AI.
Perhaps counterintuitively, I think it's a great time to do so.
I wrote up some thoughts on this here: web.mit.edu/phillipi/www/writing/PhD-in-age-of-AI.html -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
We just tested the latest AI models on 2,400 engineers. The cost/quality frontier just shifted massively.
The TL;DR:
โข Opus 5.5: Our new daily default - higher quality and 20% cheaper than prior baselines.
โข GPT-6 Luna: Shockingly capable and 20x cheaper than Opus 5.5 for high-volume routing.
Must-read for anyone managing production AI workloads ๐
Patrick Wendell
@pwendell
Crazy few weeks for model releases! Our findings @Databricks show several new models meaningfully advance the pareto frontier. Results below (online workload analysis of N=2,400 engineers, plus offline evals):
1. Two of the three models released last week clearly expand the cost/quality frontier: Opus 5.5 and GPT-6 Luna.
2. Opus 5.5 is now the highest quality mid-tier model. It is better than all prior Opus models, better than GPT-6 Sol, and better than GPT-5.6 Sol.
3. Opus 5.5 reduces same-task costs consistently by 20% in both offline and online analysis. This is against a baseline of Opus 4.8, the prior least-cost Opus model (Opus 5.0 was a bit of a dud with high costs and barely noticeable quality improvements).
4. Due to best-in-class quality and lower costs, Opus 5.5 is a strong candidate as an โevery day defaultโ model for coding, and we are now encouraging it for this purpose at Databricks.
5. GPT-6 Luna is very, very, very cheap. It was at least 20 times cheaper per-task than Opus 5.5 in every offline benchmark we tested and in observed online use.
6. GPT-6 Luna is surprisingly capable given how cheap it is. On one of our most difficult evaluation suites it roughly matches Opus 4.6 performance, while being 99.3% cheaper per-task than Opus 4.6 was at that time. That's a 100X cost reduction in ~9 months! This finding is preliminary and we are still evaluating Luna quality on a broader set of offline and online tests.
Our production setup: Unity Gateway to route workloads across models and trace agentic interactions. A mix of end-user harnesses including: Omingent (meta-harness), Claude Code, Codex, and Cursor. -
Matei Zaharia
@matei_zaharia
Really cool results with autoresearch that are going into our model serving stack!
Yuchen Jin
@Yuchenj_UW
We @databricks now rank #1 on NVIDIAโs SOL-ExecBench kernel leaderboard, across all 4 tracks.
We put GPT-6 Astra and Opus 5 in a self-hillclimbing loop, and the agents beat the top GPU kernel engineers.
Total toten spend: ~$70K, far less than what kernel engineers get paid.
One learning: GPT-6 Astra and Opus 5 are still much better than OSS models at writing GPU kernels. -
Matei Zaharia reposted
Patrick Wendell
@pwendell
Crazy few weeks for model releases! Our findings @Databricks show several new models meaningfully advance the pareto frontier. Results below (online workload analysis of N=2,400 engineers, plus offline evals):
1. Two of the three models released last week clearly expand the cost/quality frontier: Opus 5.5 and GPT-6 Luna.
2. Opus 5.5 is now the highest quality mid-tier model. It is better than all prior Opus models, better than GPT-6 Sol, and better than GPT-5.6 Sol.
3. Opus 5.5 reduces same-task costs consistently by 20% in both offline and online analysis. This is against a baseline of Opus 4.8, the prior least-cost Opus model (Opus 5.0 was a bit of a dud with high costs and barely noticeable quality improvements).
4. Due to best-in-class quality and lower costs, Opus 5.5 is a strong candidate as an โevery day defaultโ model for coding, and we are now encouraging it for this purpose at Databricks.
5. GPT-6 Luna is very, very, very cheap. It was at least 20 times cheaper per-task than Opus 5.5 in every offline benchmark we tested and in observed online use.
6. GPT-6 Luna is surprisingly capable given how cheap it is. On one of our most difficult evaluation suites it roughly matches Opus 4.6 performance, while being 99.3% cheaper per-task than Opus 4.6 was at that time. That's a 100X cost reduction in ~9 months! This finding is preliminary and we are still evaluating Luna quality on a broader set of offline and online tests.
Our production setup: Unity Gateway to route workloads across models and trace agentic interactions. A mix of end-user harnesses including: Omingent (meta-harness), Claude Code, Codex, and Cursor. -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
Had a great time giving a talk at @aiDotEngineer World's Fair on Self-improving Agents with Reflective Optimization covering GEPA, optimize_anything, gskill and Fast-Slow Training.
The recording is now up at:
www.youtube.com/watch?v=OA-Mc60Rboo -
Matei Zaharia
@matei_zaharia
Really cool research on automatically generating state of the art robot controllers!
KD
@Reveur_7
What happens if you run @gepa_ai style evolutionary search on @NVIDIAAI's Graph-as-Policies? Do the robot policies actually get any better?
My latest blogpost explores this: kael.tech.blog/2026/09/26/robotics-harness-optimization-oโฆ -
Matei Zaharia reposted
DSPy
@DSPyOSS
DSPy 3.4.0 out, with:
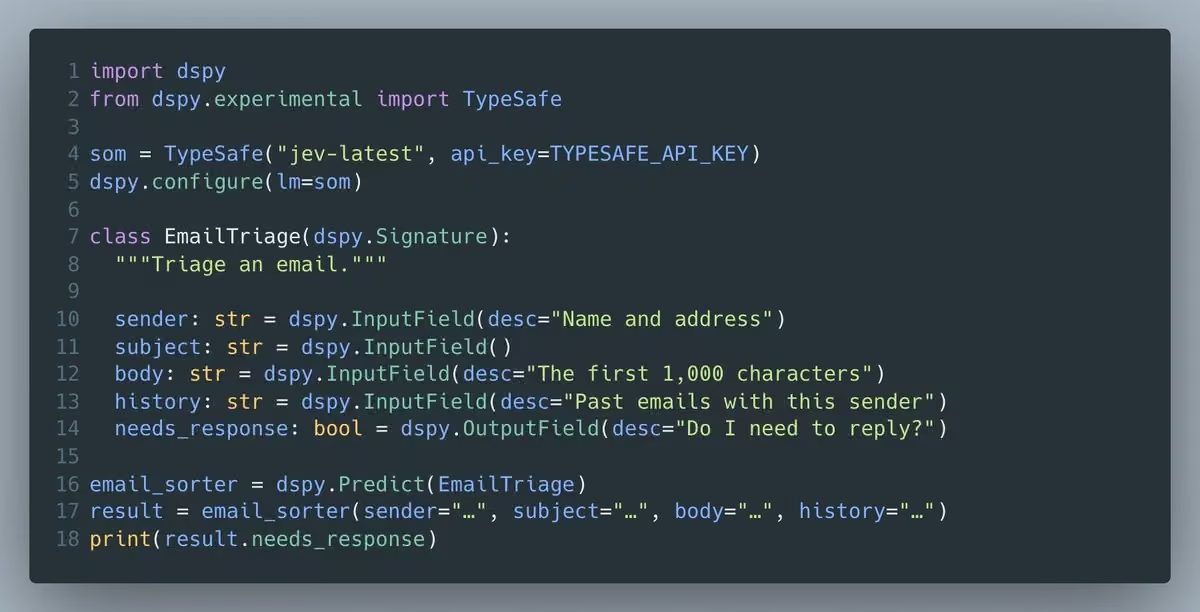
(1) native support for Jev and System One models - in the timeless DSPy syntax.
(2) a brand new optimizer, ReAnchor, specifically for calibrating outputs with confidence.
(3) lightning-fast import speeds for the LLM abstraction, via sibling library LM15)
Isaac Miller ๐งฉ
@isaacbmiller1
DSPy 3.4.0 was just released!
This release includes native support for Jev and System one models inside of DSPy! Use it with compatible signatures. This release also includes a brand new optimizer, ReAnchor, specifically for calibrating outputs with confidence. -
Matei Zaharia reposted
Databricks
@databricks
A new model comes out roughly every five days. The best model for a coding task today may not be the best or most cost-effective choice a few months from now.
The new Unity Gateway CLI helps organizations keep up with that pace.
Developers can keep working in Claude Code, Codex, OpenCode and other coding agents, while admins centrally manage models, tools, policies and budgets in Unity Gateway. When a better option emerges, teams update the configuration once and the CLI rolls it out across supported agents.
Now with the Unity Gateway CLI, teams can:
โข Set default models, MCP servers, skills, Smart Routing and spending policies centrally
โข Launch approved coding agents with one command and automatically apply organization settings
โข Track spend and capture traces across supported coding agents
www.databricks.com/blog/deploy-and-manage-coding-agents-sโฆ -
Matei Zaharia reposted
Andre Landgraf
@andrelandgraf
Iโm very excited about this. Coming next to the Neon backend: realtime.
Sync is incredibly hard to get right - especially if the goal is to make it great to work with, support as many database query use cases as possible, and scale well.
Sync coming to Neon was probably obvious to many after our announcement that the Electric team is joining Databricks but we can finally announce it officially today!
The Electric team is building sync for Neon. I asked @thruflo about joining Databricks and their first few weeks at the company: neon.com/blog/electrifying-neon-building-the-realtime-bacโฆ -
Matei Zaharia reposted
Shu Lynn Liu
@shulynnliu
Formal verification ร agents ๐
Our IDS paper was accepted as a NeurIPS oral! We study how agents can co-evolve code + proofs, achieving 3x the success rate of Claude Code on distributed systems specs.
IDS Paper: arxiv.org/abs/2605.23109
Code: github.com/skydiscover-ai/skydiscover
And also check out our recent work on the next challenge: ensuring the spec itself captures human intent. ๐
x.com/istoica05/status/2100950168333906251
Boris Cherny
@bcherny
I used Opus 5.5 to formally verify the Claude Agent SDK using Lean. A couple short prompts = 16 PRs fixing various bugs and race conditions. Video attached.
TLA+ also works well. I sometimes combine Lean and TLA+ to look for issues around data flow, concurrency, and state mgmt.
I don't know either language well, but Claude is excellent at both. This approach is super useful for formally modeling your code and finding bugs that a human probably wouldn't have spotted.
Is formal verification the future of coding (or at least, bug finding)?This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
All seven Databricks co-founders began our journey together at UC Berkeley. We started the company in a room in Soda Hall, moved to a small office on Addison Street, and spent our first few years in Berkeley before eventually heading to SF. Two of our co-founders are still on the faculty.
Today we announced Databricks Field at California Memorial Stadium, our first collegiate athletics sponsorship.
Berkeley shaped everything about how this company thinks, and this is our way of investing in the next generation of students and builders who'll do their best work on that campus.
Go Bears!
www.databricks.com/company/newsroom/press-releases/soda-hโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
At the beginning of this year, big portions of @databricks started running on Genie. When finance started doing all their work with Genie, we noticed that they were combining Genie with a Live Cloud Spreadsheet called Row Zero. This combination is really powerful. We met the Row Zero team and were blown away. Today, we're excited to announce that we've agreed to acquire Row Zero. Stay tuned for an awesome experience of Genie + Row Zero:
www.databricks.com/company/newsroom/press-releases/databrโฆ -
Matei Zaharia reposted
Liana
@lianapatel_
jev for semantic operators is a great example of how LLM data processing at scale requires rethinking across the stack, model architecture and learning algs included
new work and many more thoughts on this coming soon ๐
in the meantime, check out lotus, star and stay tuned (link below)
Eric Mao
@ericmao
I borrowed a ton of concepts from the lotus paper. The idea was well ahead of its time. Credit to the core contributors: @lianapatel_ @sid_jha1 @pgasawa @melissapan Harshit Gupta
-
Matei Zaharia reposted
Databricks
@databricks
Exciting day for Databricks customers! Weโre launching three new frontier models on Databricks today.
โณ @OpenAI's GPT-6 Sol and GPT-6 Luna, with strong performance at lower cost and a higher Pareto frontier on the OfficeQA Pro benchmark
โณ @AnthropicAI's Claude Opus 5.5, with substantial improvements in cost efficiency and strong performance on enterprise document parsing tasks
The industryโs best models are shipping faster than ever. Putting them into production and scaling your AI footprint means governing every model call, controlling costs, monitoring performance, and using the right model for the right task.
Unity Gateway gives you one governance layer across every model, so you can govern and audit requests, set budgets, track costs, and choose the best model for each job.
docs.databricks.com/aws/en/release-notes/product/2026/sepโฆ -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Neon now has cron jobs!
Neon
@neondatabase
We just shipped Function Triggers, branch-scoped definitions that tell Neon when to invoke a deployed function.
First type is cron schedules compatible with scale to zero: neon.com/blog/your-neon-functions-can-now-run-on-a-schedule -
Matei Zaharia
@matei_zaharia
Very cool that GEPA works on Jev!
Praneeth Paikray
@Paiky16
TypeSafe AI's Jev kept coming up, so I decided to test it on a task using public medical literature.
Jev lets you describe a decision in natural language and get structured answers with probabilities. I used it to identify sentences reporting suspected adverse drug effects.
It found most relevant sentences, but also flagged many negatives and sometimes gave incorrect answers complete confidence.
I then connected Jev to GEPA, a prompt optimizer, to see whether clearer instructions would help. An assistant proposed revisions based on training errors, and GEPA evaluated the candidates.
The selected prompt clarified the evidence needed in each sentence: a drug, a harmful effect, and a relationship between them.
On the same 300 fresh test sentences:
โ F1 increased from 69.1% to 79.7%.
โ False positives fell from 47 to 22.
โ Probability error, measured by Brier score, fell by about 45%.
๐praneeth16.github.io/blog/adapting-jev-with-gepa -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Super impressive how @Superhuman scales their AI infra:
blog.superhuman.com/scaling-gec-inference/ -
Matei Zaharia reposted
Sarah Wang
@sarahdingwang
Ali Ghodsi explains how Databricksโ Ontology digitizes everything that happens in an organization to give AI maximum context:
โOntology just means in an organization, the relationship between all the abstract concepts of all the goals and all the departments and all the people and all the projects that are going on.โ
โOf all of our customers, we have the largest Ontologyโฆ Itโs millions and millions of nodes in the graph.โ
โYou have a tree structure organization, and information flows up and down the tree structure. If you canโt make a decision, you escalate to your boss. Maybe they can tie break, it escalates up. They need to get up to speed on whatโs happening, and they need to get all the context, and then they make decisions.โ
โOnce decisions get made, you have to percolate them down in the organization. A lot of this can now be done by AI if you have an Ontology.โ
โItโs a game changer for us.โ
@alighodsiThis media couldn't be displayed. See it on the original post.
a16z
@a16z
Databricks' @alighodsi on AI risk and adoption:
Ali isn't losing sleep over the existential risk debate.
He says a number of conditions would all have to be true simultaneously to enable an actual runaway takeoff scenario, and currently several opposite conditions exist.
Each frontier training run requires significantly more resources. Power, GPUs, engineers - and some attempts fail, burning up huge piles of money with them. Until that reverses, he doesn't see the self-improving loop happening.
Cyber is what he's watching most closely and where he anticipates real impact. Most orgs are not equipped for the coming change in agentic capabilities. The time between a vulnerability being published and being weaponized has collapsed from years to hours.
On adoption, he believes most companies don't need a smarter model. The models are already smart enough. The gap is context they don't absorb - the things an employee who's worked at a company for five years learned by osmosis.
If the frontier stopped advancing today, he thinks it wouldn't meaningfully change the value most are extracting from AI anyway.
In conversation with a16z's Martin Casado and Sarah Wang:
00:00 Intro
00:48 Why Ali places the AI risk near zero
05:05 The word "pacing" was a mistake
10:50 What 10k agents and $100m can do
12:20 What would change his mind on AI risk
14:20 More GPUs, more ways to fail
18:05 US export controls on PlayStations
20:10 The damage everyone expected by now
24:30 Public vulnerabilities weaponized in hours
30:15 Why labs can't grade each other
37:15 Why most of RSI isn't actually RSI
40:05 Why nobody really needs a smarter model
41:50 The AI use cases nobody argues about
47:30 Google Search solved this 25 years ago
50:55 Nobody has privileged knowledge now
55:10 Same model, new harness, 2x cost
58:15 Open source: 5% of spend, 60% of tokens
1:05:30 90% of new databases are created by agents
YouTube: youtu.be/GzEtpAKYRvE
@databricks @martin_casado @sarahdingwangThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
a16z
@a16z
Databricks' @alighodsi on the clock that's forcing cyber and data into the same market:
"It used to be like, okay, we have data and AI... you have a bunch of data and you run AI and machine learning, and that just lives separately."
"And then you have the cyber world. Cyber world is, you know, we want to detect if bad people are trying to hack us."
"But now on the data and AI side, we have agents running internally in the company. And the agents are also doing things with other people's agents, and they're producing a lot of data. Logs, trails, fingerprints that are being left."
"All the data that's being produced needs to be analyzed. And the scale at which you need to do that is many, many orders of magnitude more than just one or two years ago."
"2018, 2019, the time it would take from a CVE, a vulnerability being published, until you see it actually weaponized in the industry would be like two, three years."
"That went down in 2022 significantly, but it was still like eight, nine months. So that's kind of fine, you have eight, nine months."
"Now if you look at this curve from 2022 until now, it's down to basically hours, basically no time. Things get immediately weaponized."
@alighodsiThis media couldn't be displayed. See it on the original post.
a16z
@a16z
Databricks' @alighodsi on AI risk and adoption:
Ali isn't losing sleep over the existential risk debate.
He says a number of conditions would all have to be true simultaneously to enable an actual runaway takeoff scenario, and currently several opposite conditions exist.
Each frontier training run requires significantly more resources. Power, GPUs, engineers - and some attempts fail, burning up huge piles of money with them. Until that reverses, he doesn't see the self-improving loop happening.
Cyber is what he's watching most closely and where he anticipates real impact. Most orgs are not equipped for the coming change in agentic capabilities. The time between a vulnerability being published and being weaponized has collapsed from years to hours.
On adoption, he believes most companies don't need a smarter model. The models are already smart enough. The gap is context they don't absorb - the things an employee who's worked at a company for five years learned by osmosis.
If the frontier stopped advancing today, he thinks it wouldn't meaningfully change the value most are extracting from AI anyway.
In conversation with a16z's Martin Casado and Sarah Wang:
00:00 Intro
00:48 Why Ali places the AI risk near zero
05:05 The word "pacing" was a mistake
10:50 What 10k agents and $100m can do
12:20 What would change his mind on AI risk
14:20 More GPUs, more ways to fail
18:05 US export controls on PlayStations
20:10 The damage everyone expected by now
24:30 Public vulnerabilities weaponized in hours
30:15 Why labs can't grade each other
37:15 Why most of RSI isn't actually RSI
40:05 Why nobody really needs a smarter model
41:50 The AI use cases nobody argues about
47:30 Google Search solved this 25 years ago
50:55 Nobody has privileged knowledge now
55:10 Same model, new harness, 2x cost
58:15 Open source: 5% of spend, 60% of tokens
1:05:30 90% of new databases are created by agents
YouTube: youtu.be/GzEtpAKYRvE
@databricks @martin_casado @sarahdingwangThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
a16z
@a16z
Databricks' @alighodsi on AI risk and adoption:
Ali isn't losing sleep over the existential risk debate.
He says a number of conditions would all have to be true simultaneously to enable an actual runaway takeoff scenario, and currently several opposite conditions exist.
Each frontier training run requires significantly more resources. Power, GPUs, engineers - and some attempts fail, burning up huge piles of money with them. Until that reverses, he doesn't see the self-improving loop happening.
Cyber is what he's watching most closely and where he anticipates real impact. Most orgs are not equipped for the coming change in agentic capabilities. The time between a vulnerability being published and being weaponized has collapsed from years to hours.
On adoption, he believes most companies don't need a smarter model. The models are already smart enough. The gap is context they don't absorb - the things an employee who's worked at a company for five years learned by osmosis.
If the frontier stopped advancing today, he thinks it wouldn't meaningfully change the value most are extracting from AI anyway.
In conversation with a16z's Martin Casado and Sarah Wang:
00:00 Intro
00:48 Why Ali places the AI risk near zero
05:05 The word "pacing" was a mistake
10:50 What 10k agents and $100m can do
12:20 What would change his mind on AI risk
14:20 More GPUs, more ways to fail
18:05 US export controls on PlayStations
20:10 The damage everyone expected by now
24:30 Public vulnerabilities weaponized in hours
30:15 Why labs can't grade each other
37:15 Why most of RSI isn't actually RSI
40:05 Why nobody really needs a smarter model
41:50 The AI use cases nobody argues about
47:30 Google Search solved this 25 years ago
50:55 Nobody has privileged knowledge now
55:10 Same model, new harness, 2x cost
58:15 Open source: 5% of spend, 60% of tokens
1:05:30 90% of new databases are created by agents
YouTube: youtu.be/GzEtpAKYRvE
@databricks @martin_casado @sarahdingwangThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Ion Stoica
@istoica05
-
Matei Zaharia reposted
Neon
@neondatabase
The Neon backend is GA. A complete set of primitives for apps and agents built around the database, with open standards, no lock-in, and branching-first by design.
Starting with: Lakebase Postgres, Object Storage, Functions, Managed Better Auth, and AI Gateway. More to come.This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Databricks
@databricks
Databricks CEO and co-founder @alighodsi joined @EdLudlow on Bloomberg Tech to discuss the AI pacing debate and why he believes the existential risk to humanity today is close to zero.
On where companies should focus their efforts today, Ghodsi shares, โAI models are great at breaking in, and they have all these targets to go through. We have to make huge investments in cybersecurity and protect our software systems."
Lakewatch is purpose-built to help defend against those risks.
Watch the full segment: www.youtube.com/watch?v=onrApadm2RU -
Matei Zaharia reposted
Brian Halligan
@bhalligan
Ali Ghodsi never wanted to be CEO. In 2015, he was interviewing for a professor job at Berkeley when the @Databricks board handed him the interim title. Revenue that year was $1.5M.
This episode with @alighodsi will go down as one of my favorites. 10 things I took away:
1. Focus the entire company, orders of magnitude of attention, on its single biggest bottleneck. Like a laser, almost to an extreme. The cycle is 1-3 years, not weeks. If your focus changes weekly, then youโre just in firefighting mode.
2. There is nothing worse than a conflict-averse CEO. They are wonderful people, but they are in the wrong job. Conflict is the gym for a CEO: nobody likes it, but everyone has to go.
3. Study your enemy carefully, understand their weaknesses and apply your strengths to those weaknesses. Snowflake had 2x his revenue. He didnโt copy them. He found three weaknesses (proprietary, no AI, expensive) and hammered them account by account for four years. Watch the competition, never follow it.
4. The concept of a Lakehouse was ridiculed internally and online. No one wanted to market with this new term. So he made the whole company religious about it anyway, killed the ads that converted better without the word, and put it in the sales comp plan. It worked. All hands on deck, no exceptions.
5. Be willing to take a step back for a much bigger vision, even when the company is already succeeding. At multiple hundreds of millions in ARR, he was unhappy, because the vision he pitched investors wasnโt the company he was running. So he took one step back to go ten forward.
6. On the flat org, player-coach model that a lot of people have talked about this year: โitโs BS.โ Separate how the company thinks (AI, ontology) from how the humans get managed (they are after all, still humans). His staff meets 3x a week. I asked if it could just be coordinated in a Google doc. His answer: do you meet your wife and kids, or coordinate that in a Google doc?
7. His test for a sales leader: can they build the car, or just drive it? Ron Gabrisko, the Databricks CRO, had seen $0โ50M and $50โ100M+, and hadnโt changed jobs in 10 years prior to joining. Now he has been the CRO for over a decade. He built and drove the car the whole way. That almost never happens.
8. Hire execs ahead of the curve because by the time you need them, itโs too late. A real search takes 6-12 months. The extra time helps you increase false negatives and decrease false positives. Do an insane number of backdoor references because 80% of โfront doorโ references are bs.
9. The best salespeople are not super technical, so stop trying to force them to be. Square peg, round hole. The best win with professional aggression, high EQ, and mapping the real power base (how decisions get made high up in an organization), not technical depth.
10. Yes, your best AEs will annoy people. One of the first at Databricks got a meeting nobody could get, but got banned from the customerโs building for it. He told Ali, โwhat are you complaining about? I got the meeting.โ Professionally aggressive is the bar.
One bottleneck, zero wussing out. He reminds me of @elonmusk that way.
Chapters
0:00 โ Introduction
1:22 โ The secret CEO search and why the board bet on a founder
4:11 โ Professor or CEO? Always taking the harder option
8:18 โ Pour everything into one bottleneck
12:16 โ Killing PLG and learning what great enterprise sellers actually have
19:09 โ Hiring ahead of the curve: sales leaders, execs, and back-door references
27:02 โ The Snowflake rivalry: study your enemy, never copy them
33:22 โ Lakehouse: conviction, ridicule, and the case for second acts
41:02 โ The killer instinct and why conflict-averse CEOs fail
44:10 โ Dunbar's number and rethinking the org chart around AI
48:00 โ AGI is already here โ enterprises just use it as a chatbot
52:55 โ Does he still code? Two days for a connector vs. three quarters
57:18 โ A day in the life, and why the Monday meeting isn't theater
1:04:53 โ Why Databricks will go public, just not yet
1:08:09 โ Get over conflict aversion, or don't be CEO
1:11:07 โ Brian's takeaways
Link to more in the comments.This media couldn't be displayed. See it on the original post. -
Matei Zaharia
@matei_zaharia
Some concrete measurements on Astra from Databricks engineering!
Patrick Wendell
@pwendell
Today we rolled out Astra to every engineer at Databricks (N=~3500). Some notes that may be helpful to others:
1. Astra unambiguously out performs our previous highest-end models (Opus 5, Sol 5.6) on highly complex tasks, especially those related to high level system design or long range horizontal tasks.
2. Engineers given Astra increased overall coding spend by around 60% compared to baseline.
3. It is not clear Astra meaningfully improves on medium/low complexity coding tasks compared to earlier models. We suspect those tasks are mostly saturated (i.e. perfectly executed) by existing models.
4. We learned above by piloting Astra with around 200 users to gain signal on both quality and cost. We use Unity Gateway to do cohort-based experiments for all new models.
5. We give engineers a sub-budget specific to Astra to encourage them to use Astra selectively on complex tasks while preferring lower cost models for everyday tasks. Our engineers are able to mix-and-match tools and models within their overall budget envelope (we also allow for increased budgets through various mechanisms). These budgets are defined in Unity Gateway and regularly revisited.
Note: We do not have robust comparisons of Astra-vs-Fable because we have net yet rolled out Fable widely due to data retention policies. -
Matei Zaharia reposted
Patrick Wendell
@pwendell
Today we rolled out Astra to every engineer at Databricks (N=~3500). Some notes that may be helpful to others:
1. Astra unambiguously out performs our previous highest-end models (Opus 5, Sol 5.6) on highly complex tasks, especially those related to high level system design or long range horizontal tasks.
2. Engineers given Astra increased overall coding spend by around 60% compared to baseline.
3. It is not clear Astra meaningfully improves on medium/low complexity coding tasks compared to earlier models. We suspect those tasks are mostly saturated (i.e. perfectly executed) by existing models.
4. We learned above by piloting Astra with around 200 users to gain signal on both quality and cost. We use Unity Gateway to do cohort-based experiments for all new models.
5. We give engineers a sub-budget specific to Astra to encourage them to use Astra selectively on complex tasks while preferring lower cost models for everyday tasks. Our engineers are able to mix-and-match tools and models within their overall budget envelope (we also allow for increased budgets through various mechanisms). These budgets are defined in Unity Gateway and regularly revisited.
Note: We do not have robust comparisons of Astra-vs-Fable because we have net yet rolled out Fable widely due to data retention policies. -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent v0.14.0 is now available! ๐
This release makes it easier to work across GitHub repositories, configure sessions, and keep track of ongoing work.
๐ Multi-repo GitHub PRs and sandboxes
๐๏ธ Redesigned composer
๐ช Claude SDK /compact
๐๏ธ Gensee, Kubernetes, CockroachDB
๐ Approvals that survive restarts
Learn more ๐ omnigent.ai/releases/0.14.0
#omnigent #aiagents #opensource -
Matei Zaharia
@matei_zaharia
Agent harnesses seem to make a lot of difference, at least for cost, even on open source coding benchmarks. Melissaโs research project digs into why.
Melissa Pan
@melissapan
Does your Claude model really need Claude Codeโฆ? ๐ค
We evaluate 7 models on Claude Code, Codex, and Pi. Three surprising findings emerge:
1๏ธโฃHarness choice has little effect on task success rate, but can significantly affect the cost
2๏ธโฃA simple harness can be competitive
3๏ธโฃThe native harness isnโt always the best.
Millions of people are using coding agents, but the impact of harness choice remains unclear.
(1/n) More details in the thread. ๐งต -
Matei Zaharia reposted
Melissa Pan
@melissapan
Does your Claude model really need Claude Codeโฆ? ๐ค
We evaluate 7 models on Claude Code, Codex, and Pi. Three surprising findings emerge:
1๏ธโฃHarness choice has little effect on task success rate, but can significantly affect the cost
2๏ธโฃA simple harness can be competitive
3๏ธโฃThe native harness isnโt always the best.
Millions of people are using coding agents, but the impact of harness choice remains unclear.
(1/n) More details in the thread. ๐งต -
Matei Zaharia reposted
Rishi Raj Jain
@rishi_raj_jain_
Built a full-text search over all of Hacker News (~49M stories, comments, jobs & polls, syncing live per hour) to be ๐ฌ๐ฎ๐ซ๐ฉ๐ซ๐ข๐ฌ๐ข๐ง๐ ๐ฅ๐ฒ ๐๐๐ฌ๐ญ with no Next.js level cache and all magic at the Neon Postgres layer: hnfaster.vercel.app ๐
โข Every keystroke is a live query against @neondatabase Postgres
โข BM25 (powered by Lakebase Search) ranking runs inside the Postgres
โข No connection pool, just SQL-over-HTTP round trips
โข pg_prewarm loads the table + every index into cache
โข partial BM25 index per type, predicate matching the WHERE clause
โข Deployed on @vercel
Just Postgres doing Postgres things, close to the compute ๐This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Leon van Zyl
@leonvz
I made Claude Code and Codex debate a plan, then let a third agent build it.
All in Omnigent, Databricks' new open-source layer for running coding agents together. Setup, session forking, security policies, full build.
youtu.be/gYtQ1LKSgXY -
Matei Zaharia reposted
Neon
@neondatabase
Agents can now get a Neon database without signup, and a human can claim it later. Your agent wonโt stop because it needs you to create an account first.
Weโre calling this flow Claimable Neon. It implements the @WorkOS auth.md spec: neon.com/claimable-neon -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
5 months at Databricks. I do not say this lightly.
Our AI inference is getting too fast. We are extremely close to the model answering before you finish typing the prompt.
We are not asking for a ban. We are asking for a pause. -
Matei Zaharia
@matei_zaharia
If you're building production agents and want to contribute to research, take our survey! We'll release aggregate stats like we did in last year's MAP paper.
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
1/๐คAgents in production are changing fast.
Following our #icml2026 oral work, weโre running the study again this year to understand whatโs changing in how agents are built, deployed and evaluated in real systems.
๐ If youโre working on agents in production, weโd love your input. The survey is short, but it can help us build a much clearer picture of what is actually working in practice.
๐ Survey: berkeley.qualtrics.com/jfe/form/SV_3q1WIz3UAGgw0wC
๐๏ธ Weโre also interviewing practitioners! Reach out if youโd like to share your experience in more depth.
๐ And if youโre curious about what we learned last year, check out our previous study in the thread below -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent v0.13.0 is now available! ๐
This release is focused on tightening the loop between your agents, your code, and the infrastructure they run on.
๐ GitHub PR panel in the session workspace
๐ผ๏ธ Built-in Canvas board of live session cards
๐ฆ New managed sandboxes: libkrun microVMs and self-reclaiming Kubernetes
โก Instant session switching
๐ Jcode as a first-class ACP harness
Full release notes ๐ github.com/omnigent-ai/omnigent/releases/tag/v0.13.0
#omnigent #aiagents #opensource -
Matei Zaharia reposted
Databricks
@databricks
Effective enterprise data agents require search that is both accurate and fast.
Thatโs why weโre introducing ๐๐ฑ๐ฎ๐ฝ๐๐ถ๐๐ฒ ๐๐ป๐๐๐ฟ๐๐ฐ๐๐ฒ๐ฑ-๐ฅ๐ฒ๐๐ฟ๐ถ๐ฒ๐๐ฒ๐ฟ, which combines the speed of parallel retrieval with the performance of sequential search while maintaining strict cost and latency guarantees.
The goal is simple: spend additional search steps only when they are useful. -
Matei Zaharia reposted
Daya
@dskhudia
www.databricks.com/blog/achieving-extreme-efficiency-throโฆ
We recently published a blog on work on Proteus, a system for generating specialized GPU kernels.
Why should models from 1B to 1T parameters rely on the same generic kernels? By specializing for the exact shapes encountered at runtime, we can unlock extreme efficiency.
Using Proteus, we generated individual kernels for Qwen 3.5 122B that were 1.8โ5.2ร faster than the best implementations available in vLLM. But finding a fast kernel is only the beginning. The harder problem is knowing whether its results can be trusted.
Generation is often the cheap step in terms of token cost. In our initial harness, knowledge and context management, not candidate generation, consumed most of the token budget. Verification introduces another cost: candidates must run on real GPUs, in isolation, often more than once.
Verification must be airtight. A kernel must be functionally correct, but its performance claims also need rigorous validation: fair comparisons, multiple timers, clean state, hidden tests, and repeated measurements. Otherwise, we generate impressive numbers and not production-ready kernels.
Agentic kernel generation makes extreme specialization possible. Building a reliable, production-ready system around it remains a hard frontier.
At @Databricks, weโre tackling these challenges at the intersection of AI and systems to make inference faster, more efficient, and autonomously improving.
@leshenj15
Previous AA results from Databricks posted by @Yuchenj_UW :
Yuchen Jin
@Yuchenj_UW
GLM-5.3 at 310 tok/s!
Databricks inference is #1 in both speed and latency, again.
On our internal Databricks coding benchmark, GLM-5.3 is the strongest OSS model for coding, competitive with Fable 5 and Opus 4.8. -
Matei Zaharia reposted
Databricks
@databricks
AI needs context to understand how your business actually runs.
Join our upcoming webinar to learn how Genie Ontology helps bring that context together so AI can deliver trusted answers, act autonomously, and give teams back time.
Youโll learn how to:
โ Build a living context graph across business terms, entities, and KPIs
โ Deliver trusted answers based on each userโs access
โTurn insights into autonomous actions, agents, and apps
โ Bring context-aware AI into Slack, Teams, mobile, and MCP-based experiences
Hear directly from Databricks experts and see Genie Ontology in action. RSVP: www.databricks.com/resources/webinar/closing-the-ai-conteโฆ -
Matei Zaharia reposted
Liana
@lianapatel_
As better models rapidly eat the stack, what system research problems will remain to enable the next frontier of data agents?
We studied the evolution of data agent capabilities the past 2 years, finding general coding agents beat hand-designed data agents by up to 37 points, with 4ร fewer turns.
So what's actually left for system researchers to solve?
More than you might think...
๐ Paper: arxiv.org/abs/2609.03141
๐งต๐ -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
If you want to understand how fast AI is improving, look at intelligence per dollar.
1.5 years ago:
o1 Pro: $150 / $600 per M tokens
Today:
GLM-5.3 Flash: $0.15 / $0.50
Thatโs a ~1000x collapse in price in under 1.5 years, while GLM-5.3 Flash is more intelligent than o1 Pro. -
Matei Zaharia reposted
Daniel Liden
@danjliden
Excellent post on controlling Agent spend with @omnigent_ai by @TerryTangYuan. The post covers smart routing, progressive budgets, and cost visibility for AI agents, with a guide to rolling them out for yourself and your team.
omnigent.ai/blog/stop-surprise-llm-bills -
Matei Zaharia
@matei_zaharia
Stronger open models + new inference systems also means super powerful local AI is coming! Cool work by Shuo from UC Berkeley Sky Lab.
Shuo Yang
@Andy_ShuoYang
Qwen3.8-Flash-Next now runs on a single RTX 5090 at 68.3 tok/s โ no extreme quantization, no speculative decoding.
ยท Production-level checkpoint: GB300-validated NVFP4 checkpoint from RadixArk
ยท 63GB host RAM โ less than what 1-bit quants of this model need
ยท The 51GB n-gram table? It lives on your NVMe, at ~0.5% throughput cost
In the video: one prompt โ a playable minecraft-style world, then FreeToken on my 5090 desktop fixing a real FreeToken bug in 10.5 minutes.
Meet FreeToken ๐งตThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Josue Bogran
@joshbogran
Just crossed 1,500 subscribers on Youtube & am 100 "watch hours" away from an important milestone there as well. Here is a collection of recent @databricks
interviews, deep-dives, and more!
Omnigent deep-dive with Matei Zaharia: youtu.be/K99zQ3h0TK4
Lakebase branching with Kevin Hartman: youtu.be/R1Lwng6lfxo
Discover & Domains with Stef Bran-Melรฉndez: youtu.be/SXyG-TKISX8
SDP-Meta for pipelines at scale with Ravi Gawai: youtu.be/Z0CYboIzp9M
Sales culture with Ron Gabrisko: youtu.be/UsX7cY7UgvA
Telecom monetization with Nevash Pillay: youtu.be/1zuLESVHEuc
AI context with Jonathan Frankle: youtu.be/8YxBTlCwu7k
Why Lakebase with Reynold Xin: youtu.be/F9exV_HAHyU
Zerobus with Scott Haines: youtu.be/UNxJor_w8yE
OpenSharing Overview with Akram Chetibi:
youtu.be/0mfuNybtmdE
Bonus
SAP connection with Akram: youtu.be/j_utw66Wr94
OpenSharing Global Distribution with Akram: youtu.be/8E3RYwn1Mns
OpenSharing SecureConnect with Akram: youtu.be/lcoQrmhBfEI
Capital markets & data moats with Andrea DeSosa: youtu.be/EHi22OtTnTw
And many more!
Thank you to everyone that has interviewed with me, watched, and/or reshared my content. I truly love what I get to do, because of you. -
Matei Zaharia reposted
Databricks
@databricks
GPT-6 Astra, @OpenAI's most powerful model, has landed as a day-zero release on Databricks!
This is OpenAI's biggest leap in agentic reasoning and your teams can put it to work on production data today.
โ In our internal evaluations, Astra achieves state-of-the-art quality at great efficiency on Databricks' OfficeQA Pro, OfficeQA Pro V2, and Document Processing benchmarks.
โ Every call to GPT-6 Astra flows through Unity Gateway:
โณ same governance
โณ same audit trail
โณ same cost controls you already know and trust across Claude, Gemini, Grok and every other model on Databricks.
Try GPT-6 Astra - see documentation: docs.databricks.com/aws/en/release-notes/product/2026/sepโฆ -
Matei Zaharia
@matei_zaharia
Check out the Lakebase VLDB paper for tons of detail on why and how Neon and Lakebase are built! We think this type of highly elastic architecture over commodity lake storage (S3) is going to be used for more and more infra as software development speeds up and agents do more of it.
Nikita | Scaling Lakebase Postgres
@nikitabase
www.vldb.org/pvldb/vol19/p4385-pandis.pdf
This is the foundation of Lakebase architecture pioneered by @neondatabase
We just presented it at @VLDBconf - the main database scientific conference and also covered it on the @VLDBconf keynote by a @databricks cofounder @rxin -
Matei Zaharia reposted
Ivan Zhou
@ivanzhouyq
We evaluated GPT 6 Astra at @databricks and it claims the new SOTA on our OfficeQA Pro & Pro V2 benchmarks, using our Genie harness. It also improves significantly from gpt 5.6 sol on the $ per task. Throughout our benchmarks, it shows a clear step up on data reasoning and document understanding for enterprises.
It also has become my daily driver on @omnigent_ai. It is a great model to collaborate with and get things done reliably.
Congrats to @OpenAI. The model will come to our Unity Gateway and smart routing soon! -
Matei Zaharia
@matei_zaharia
Really cool example of using tracing data to get insights into AI workloads with Unity AI Gateway. We think this will be a new form of operational data analysis that all companies do, a lot like finance and security.
Databricks
@databricks
We found and eliminated an estimated $1.2M a year in wasted AI spend and lost productivity in one hour.
Here's how ๐
Using Unity Gateway tracing and Genie One, we identified seven small MCP-server bugs that were quietly driving:
โข ~$499K/year in wasted tokens
โข ~12,000 engineering hours/year in agent wait time
โข 1,409 tool errors in a single 24-hour window
Genie One turned the trace data into a ranked list of what to fix, and a coding agent helped close the loop in an hour. www.databricks.com/blog/how-we-eliminated-1-million-year-โฆ -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
www.vldb.org/pvldb/vol19/p4385-pandis.pdf
This is the foundation of Lakebase architecture pioneered by @neondatabase
We just presented it at @VLDBconf - the main database scientific conference and also covered it on the @VLDBconf keynote by a @databricks cofounder @rxin -
Matei Zaharia reposted
Databricks
@databricks
#vldb2026 is underway, and Databricks is here as a Gold Sponsor.
Weโre sharing what weโre building for the future of agent-native data infrastructure, including:
โข a keynote from Databricks co-founder @rxin on why the agentic future demands Lakebase Postgres
โข AutoLiquid and Ultron query optimization
โข Lakehouse//RT, Lakebase, and LTAP
โข conversations with the database community on the ground
Still ahead: sessions and demos on Lakebase, @ApacheSpark Structured Streaming, and Enzyme.
If youโre at VLDB, come find the team ๐ -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent v0.12.0 is now available! ๐
This release is focused on meeting your existing tools and workflows where they already live.
๐ฅ Import Claude Code, Codex, and other CLI sessions into the web UI
๐ Projects now drive new sessions
๐ฑ Refreshed mobile and wide-screen UI
๐ Antigravity, plus Devin and Grok Build in the New Chat picker
๐ฅ๏ธ Run your host as a service on macOS and Linux
Full release notes ๐ omnigent.ai/releases/0.12.0
#omnigent #aiagents #opensource -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
GLM-5.3 at 310 tok/s!
Databricks inference is #1 in both speed and latency, again.
On our internal Databricks coding benchmark, GLM-5.3 is the strongest OSS model for coding, competitive with Fable 5 and Opus 4.8. -
Matei Zaharia reposted
Alex Dimakis
@AlexGDimakis
4000 GB200s just arrived in Texas for the Horizon TACC cluster. I'm informed this is the largest academic supercomputer. Very excited to start training some open models with this bad-ass machine.
(photo courtesy of Adam Klivans, director of NSF IFML) -
Matei Zaharia reposted
Databricks
@databricks
What if documents, images, audio, and video could behave like any other column in your lakehouse?
FILE type makes unstructured data native to your tables, so teams can query and process multimodal data while applying the same fine-grained access controls and security policies used for standard tables.
And because FILE is being built in the open, weโre working with the community to bring support directly to Parquet, Delta Lake, Apache Iceberg, and Apache Sparkโข.
Learn more: www.databricks.com/blog/introducing-file-type-native-coluโฆ -
Matei Zaharia reposted
Liana
@lianapatel_
Looking forward to VLDB in Boston this week! Iโll be on the job market this year for CS faculty positions. Iโm also co-organizing the NOVAS workshop tomorrow, featuring research at the intersection of data systems and AI, including semantic operator optimization and agentic data systems.
Please reach out if youโre attendingโIโd love to meet and chat! -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
GLM-5.3-Flash at 270 tok/s!
Databricks inference team is on fire. So proud of the team!
On our OfficeQA Pro v2 benchmark, GLM-5.3-Flash delivers 10% higher quality than GLM-5.2 at just 1/10 the cost.
Fast, cheap, and good. -
Matei Zaharia reposted
amrutha srivatsav
@amruthaaa___
Charts contain important information in enterprise documents, but agents often struggle to retrieve and reason over them accurately. Chart images can be misread, while captions often omit the precise values and labels needed for retrieval.
Thatโs why our team at @DbrxMosaicAI developed structured chart extraction for ai_parse_document, converting chart content into JSON that can be indexed and used by Genie and other RAG systems.
Across two chart-heavy benchmarks, our approach, which uses a lightweight 300M-parameter text embedding model, outperformed multimodal embedding baselines which were up to 10ร larger. -
Matei Zaharia reposted
Databricks
@databricks
.@SpaceXAI's latest model, Grok 4.6, is now available on Databricks!
Grok 4.6 sets a new state-of-the-art performance standard with Genie harness on Databricks' OfficeQA Pro v2 benchmark, our flagship benchmark for complex data reasoning tasks on enterprise documents.
Run Grok 4.6 where your data already lives - governed, secure, and ready for custom AI apps and agents built with the data in your Lakehouse. Govern every call, monitor performance, and scale securely across your AI apps with Unity Gateway.
docs.databricks.com/aws/en/release-notes/product/2026/august -
Matei Zaharia
@matei_zaharia
This is unfortunate, but this is why we're making cloud storage, databases, etc all branchable and recoverable at @neondatabase and @databricks! Agentic development will need a new kind of cloud infra.
Sebastien Guillemot
@SebastienGllmt
Bad news: Fable nuked my entire dev machine
Claude decided to test a sandbox it was building by running `rm -rf` on my home directory
The sandbox didn't work.
It's all gone -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
Allow me to say that retrieval is the only ML problem in which we still cling to the assumption that an inert scoring function (a meager dot product!), which couples your โsearch-time computeโ with the dimensionality of the representation, can be sensible.
Who would have guessed this forces you to have exponentially larger embeddings just to do basic things. Instead, if this makes it sound more modern, you need โinference scaling for retrievalโ, also known as late interaction from 2019/2020:
Sumit
@_reachsumit
Retrieval Needs Multivectors: An Exponential Separation
Microsoft formally proves that multi-vector embeddings can be exponentially more compact than single-vector ones for ranking documents.
๐ arxiv.org/abs/2608.21494 -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
GLM-5.3-Flash (Ox Alpha) is a big deal!
320B-A18B, less than half the size of GLM-5.2, yet it beats GLM-5.2 across every benchmark.
Amazing to see @Zai_org keep pushing frontier intelligence with increasingly efficient models. Appreciate the MIT license.
Databricks will bring GLM-5.3-Flash to our customers asap, and make it run super fast.
Z.ai
@Zai_org
Introducing GLM-5.3-Flash
- Leading capabilities at a highly competitive price
- Natively multimodal with a 1M-token context window
- A 320B-A18B model released under the MIT License
- Previously previewed as Ox Alpha, running entirely on Chinese AI chips
Blog: z.ai/blog/glm-5.3-flash
Available now across all official platforms:
Weights: huggingface.co/zai-org/GLM-5.3-Flash
API: docs.z.ai/guides/llm/glm-5.3-flash
Coding Plan: z.ai/subscribe
ZCode: zcode.z.ai/en
Chat: chat.z.ai
AutoClaw: autoclaw.z.ai -
Matei Zaharia reposted
Andy Hattemer
@andyhattemer
What idiot called it S3 and not WALmart
Neon
@neondatabase
Postgres on S3 is the right design, but even more interesting is making WAL the source of truth. This is how our storage works - we wrote a deep dive, summary on thread: neon.com/blog/wal-s3-lakebase-storage-for-the-era-of-agents
-
Matei Zaharia reposted
Neon
@neondatabase
Postgres on S3 is the right design, but even more interesting is making WAL the source of truth. This is how our storage works - we wrote a deep dive, summary on thread: neon.com/blog/wal-s3-lakebase-storage-for-the-era-of-agents
-
Matei Zaharia reposted
Andy Konwinski
@andykonwinski
Introducing Headlong, an open source microharness for persistent agents: self-guided agents that think continuously.
Most agent harnesses are reactive: you send a task, the agent completes it, and then it sits frozen until the next request. Cron jobs and heartbeats wake it up to run a checklist and put it back to sleep.
A Headlong agent is never asleep. It keeps generating thoughts about whatever it decides is interesting, in a self-guided loop inspired by human inner monologue. Your message doesn't start a session. It's one more observation that lands in the agent's thought stream, and the agent decides if and when to reply.
Headlong is built on the idea of persistent agency: continuous inner thought generation between external interactions. The agent sets its own interests and priorities, comes up with its own projects, and sometimes pings you unprompted with progress.
To keep our prototype as simple and small as possible, we implemented Headlong as a microharness: a complete agent harness in under 10K lines of Bash, organized as a handful of small executables. It includes a loop that generates the next thought, shellm (a recursive language model written in Bash), a trajectory stored as a DAG of jsonl files, and context as a projection of that trajectory.
We've been running one Headlong agent internally at Laude for several weeks. The whole team talks to it over Slack and Telegram, and every conversation lands in its single stream of thought. It works in its own fork of Headlong and we've pulled over 50 of its commits into main.
One night, with nobody talking to it, it went back to check whether a recall process it had built was actually wired into its mind, found that it wasn't, diagnosed and fixed the bug, and verified the fix end to end. 48 minutes, no human asked for the fix or was in the loop at any point. Every step is a timestamped line in its log.
Things broke too, and we wrote those up. Background thinking costs us $1 to $2 an hour, our agent stopped its own service three times by accident, and self-delegation died on day one. Details in the post.
One line installs everything and starts an agent. Use a dedicated sandbox and spend-capped API key; it runs real shell commands and thinks around the clock.
Headlong is research software, be careful!
curl -fsSL headlong.ai/install.sh | bash
Launch post: www.laude.org/updates/headlong-a-microharness-for-persistโฆ
Repo: github.com/laude-institute/headlong
Headlong is a @LaudeInstitute / MIT collaboration. -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
2024: A gaming PC with a RTX 4090 ran Llama 3 70B at ~2 tok/s in 4-bit.
2026: A gaming PC with a RTX 5090 runs DeepSeek-V4-Flash 284B at ~24 tok/s with native mxfp4.
Prediction: by the end of 2027, a gaming PC will run Fable 5-class intelligence locally at decent speed. -
Matei Zaharia reposted
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
Last year, Measuring Agents in Production (MAP) uncovered a ton of under-explored research opportunities around how agents are actually being built and deployed.
Check out our ICML 2026 oral presentation: icml.cc/virtual/2026/oral/71172
Weโre doing it again! ๐ค๐
And now MAP 2026 is live! If youโre building or deploying agents in production, weโd love to hear from you. Take our survey and help contribute to open science ๐
berkeley.qualtrics.com/jfe/form/SV_3q1WIz3UAGgw0wC
Melissa Pan
@melissapan
ICML oral videos are outโ๏ธCheck out our talk on Measuring Agents in Production if you want to learn about under-explored research opportunities ๐ค
link: icml.cc/virtual/2026/oral/71172
#icml #icml2026 -
Matei Zaharia reposted
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
So excited to see Tยณ accepted to the #emnlp2026 Main Track! ๐
arxiv.org/abs/2605.03344
Itโs been incredibly fun exploring the idea that RAG can actually improve reasoning when we retrieve from the right kind of corpus.
Huge thanks to my incredible co-authors @wenjie_ma @sewon__min @matei_zaharia ! ๐
See you in Budapest!๐ญ๐บ
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
1/ Thrilled to introduce Tยณ: a corpus for RAG over reasoning tasks, built from thinking traces.
We show that surprisingly RAG can improve reasoningโ with the right corpus.
Rag with Transformed Thinking Traces Tยณ gain by up to 43.9% on AIME 2025-2026.
๐ arxiv.org/abs/2605.03344 ๐งต -
Matei Zaharia
@matei_zaharia
Really cool results from Sky Labโs @Andy_ShuoYang to run massive LLMs on local GPUs!
Shuo Yang
@Andy_ShuoYang
Your gaming PC can now serve frontier models at interactive speed using official checkpoints without extreme quantization!
Qwen3.6 35B โ 8GB RTX 4060 laptop @ 39 tok/s
DeepSeek-V4-Flash 284B โ RTX 5090 desktop @ 22-25 tok/s
GLM-5.2 753B โ RTX PRO 6000 workstation @ 15 tok/s
Run your claude code or codex now with frontier model for $0
Meet FreeToken ๐งต -
Matei Zaharia reposted
Databricks
@databricks
Your AI is smart enough. The missing piece is context.
Join Databricks on September 23 to see how Genie Ontology helps AI understand how your business actually works.
Youโll learn how to:
โข Build a living context graph across business terms, entities, and KPIs
โข Deliver trusted answers based on each userโs access
โข Turn insights into autonomous actions, agents, and apps
โข Bring context-aware AI into Slack, Teams, mobile, and MCP-based experiences
Save your seat: www.databricks.com/resources/webinar/closing-the-ai-conteโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
This is true. It wasn't actually possible before 2010 because datacenter networks would bottleneck. We used to design coupled storage/compute where you brought compute close to "big data". But research on "full bisection bandwidth" networks made it possible to essentially just talk from any machine to the storage system at full speed. The disaggregation started then! Databricks and Snowflake started soon after many others followed. Now "Put it on the object store" is the way to go.
Nikita | Scaling Lakebase Postgres
@nikitabase
"Put it on the object store" remains undefeated.
- OLAP: Lakehouse
- OLTP: Lakebase
- Kafka: Warpstream
- Vector Search: Turbopuffer
- Git: Cursor Origin -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
"Put it on the object store" remains undefeated.
- OLAP: Lakehouse
- OLTP: Lakebase
- Kafka: Warpstream
- Vector Search: Turbopuffer
- Git: Cursor Origin -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Full house at the Omnigent & Multi-Agent Coding Meetup in NYC tonight! ๐ฝ๐ฅ
@dennylee is kicking things off with an overview of Omnigent.
๐@databricks NYC office
#omnigent #opensource #agentsThis media couldn't be displayed. See it on the original post. -
Matei Zaharia
@matei_zaharia
Some continued great results with our custom trained models at Databricks!
Ivan Zhou
@ivanzhouyq
We are excited to share @databricks 's new AI Extract achieves the new frontier at complex document processing tasks! It addresses a few key customers' pain points:
- Process documents with 500+ pages that exceeds 1M tokens
- Large, nested schema with 1k+ of objects
- Complex schema that requires frontier reasoning
Here is how we achieved it:
- In-house custom model for document extraction that is trained for complex real-world examples and optimized for serving large volume of workloads
- Custom agent harness that is designed for long document extraction. It decomposes large extraction jobs, executes smaller tasks in parallel, and reconciles them into one final structured output.
This is the methodology behind many of our work: identify key large workloads of enterprise customers, build in-house models + harness to address it, and ship to the customers through a close collaboration between the research + product! -
Matei Zaharia reposted
Ivan Zhou
@ivanzhouyq
We are excited to share @databricks 's new AI Extract achieves the new frontier at complex document processing tasks! It addresses a few key customers' pain points:
- Process documents with 500+ pages that exceeds 1M tokens
- Large, nested schema with 1k+ of objects
- Complex schema that requires frontier reasoning
Here is how we achieved it:
- In-house custom model for document extraction that is trained for complex real-world examples and optimized for serving large volume of workloads
- Custom agent harness that is designed for long document extraction. It decomposes large extraction jobs, executes smaller tasks in parallel, and reconciles them into one final structured output.
This is the methodology behind many of our work: identify key large workloads of enterprise customers, build in-house models + harness to address it, and ship to the customers through a close collaboration between the research + product! -
Matei Zaharia reposted
Shicheng Liu
@ShichengGLiu
Take a look at this great write-up on how we (@harshitj__ , @PriyankShethia , and @JiudingSun) won this incredible @databricks competition!
In short, lessons I learnt from building knowledge agents in summer 2026:
(1) Parsing is still not a 100% solved problem;
(2) Try to build on top of coding agents, as opposed to building complete alternatives; and
(3) Custom verification pipelines are still very important in high-stakes situations (example at 7:10 in the video!)
Matei Zaharia
@matei_zaharia
This was a super cool event at Data + AI Summit, probably the first live competition for AI researchers and agents! Check out the video and congrats to the winning teams from Stanford, UMass Amherst and Yale! m.youtube.com/watch?v=MNkmRtXIp04
Blog on winning ideas: www.databricks.com/blog/evaluating-ai-agents-live-groundeโฆ -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent 0.10.0 is now available! ๐
๐ป Run several sandbox providers at once
๐ค Devin harness and Copilot subscription support
๐ฐ New usage page to track session costs, daily spend, and breakdowns by harness and model
๐จ Manage sessions from the web UI
โก๏ธ Switching conversations and terminals is now instant
๐ Full details, bug fixes, and upgrade notes:
github.com/omnigent-ai/omnigent/releases/tag/v0.10.0
#omnigent #aiagents -
Matei Zaharia reposted
Bhavya Chopra @ UIST 2026
@BhavyaChopra1
Spent hours digging into GEPA logs finding ways to fix your run? ๐
We have reimagined GEPA to be human-steerable. We built deep observability tools allowing agents to monitor, proactively surface, and fix issues in your run. We provide multiple levers for users to intervene and meaningfully affect the optimization trajectory!
Early access signup in ๐งต๐๐ฝ -
Matei Zaharia
@matei_zaharia
This was a super cool event at Data + AI Summit, probably the first live competition for AI researchers and agents! Check out the video and congrats to the winning teams from Stanford, UMass Amherst and Yale! m.youtube.com/watch?v=MNkmRtXIp04
Blog on winning ideas: www.databricks.com/blog/evaluating-ai-agents-live-groundeโฆ -
Matei Zaharia reposted
Databricks
@databricks
The next generation of databases may be built as much for agents as for developers.
Databricks VP of Engineering @nikitabase joins Itโs About Data to unpack the idea behind @neondatabase that now powers Lakebase: separating compute and storage for Postgres OLTP.
The conversation explores how object storage can make operational data available to downstream systems, why developer-first database architecture matters, and what changes when agents start provisioning databases, creating branches, and managing application state themselves.
Tune in to the full episode: www.youtube.com/watch?v=zpqM-YWrXB4 -
Matei Zaharia reposted
Databricks
@databricks
โWith coding agents, youโre putting this jetpack on and going 10,000 miles an hour, doing things you were never able to do before.โ
In this conversation, @OpenAIโs @steipete and @thsottiaux join Databricks Co-founder @pwendell to unpack what comes next as agents move beyond code authoring into observability, operational work, and long-running responsibilities across software and data systems.
Watch the full conversation: www.databricks.com/resources/webinar/agents-work-shippingโฆThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Connor Shorten
@CShorten30
Retrieve more, rerank, get better results. That's what most of us expect from search, but it turns out to be wrong! ๐คฏ
I'm SUPER EXCITED to publish the 141st episode of the Weaviate Podcast with Mathew Jacob (@mat_jacob1002)! Mathew led the work behind "Drowning in Documents" during his time at Databricks and is now a Ph.D. student at the University of Washington working on ML systems!
This episode dives deep into "Drowning in Documents". This has been one of the most influential papers for us @weaviate_io as we are exploring scaling reranked retrieval. I think it is a must read for those working in Search and Information Retrieval. ๐
We begin with an overview of the paper, and then dive into full scoring with cross encoders and phantom hits. We then cover Listwise Rerankers, what next generation cross encoders might look like, and ranking cascades.
On the topic of ranking cascades, I loved learning about Mathewโs work with Melissa Pan (@melissapan), Negar Arabzadeh (@NegarEmpr) and collaborators on โNatural Language Query to Configuration for Retrieval Agentsโ. Per-query โeffortโ prediction is certainly going to be a huge component on the future of these search systems! (Congratulations to OpenRouter ๐)
We then dove into Mathewโs work on TraceLab, a super exciting effort to understand coding agents such as Claude Code and Codex. โจ๏ธ
This was a super fun conversation, and I really hope you find it useful!
YouTube: youtu.be/fWuavBcoTzk
Spotify: open.spotify.com/episode/2A81hDgbUpr14Jh2h9gfVl -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
This is how Smart Routing working on our AI Gateway, super simple idea, lowers cost about 30% without giving up on quality!
Databricks
@databricks
Introducing Smart Routing in Unity AI Gateway.
Stop overpaying for AI. Smart Routing matches each coding task to the right model and harness based on what the task needs, so higher-cost models can differentiate on intelligence while lower-cost models differentiate on cost and performance.
Match frontier quality and cut task costs by 30%+.
www.databricks.com/blog/smart-routing-unity-ai-gateway-maโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
I got this question so many times today. "How can you grow 80% at $7B?"
The true answer is that we're finally seeing a breakthrough with AI agents starting to work in the enterprise.
The AIs have been super smart for a while, but have lacked basic context that's in people's heads, or in some SaaS system-or-record. A lot of organizations are deploying FDEs to capture this context, or Ontology, and feed it to the AI. This is labor intensive and expensive. We just automated that with Genie Ontology.
Once you have that enterprise context graph, an AI agent like Genie becomes magical. I find myself no longer waiting for answers from my CRO, CFO, CMO, CHRO etc, I just keep queuing up questions on the phone while sitting in meetings. It'd frankly addictive.
Our customers are starting to do the same, over 70% of all queries on the platform are now generated by Genie agents. This fuels more questions to the platform, which drives consumption, which drives revenue. That's the simple answer. -
Matei Zaharia reposted
Ivan Zhou
@ivanzhouyq
We are in a Cambrian explosion of frontier models. Even as a researcher who spends a lot of time evaluating models, I find it hard to keep up. New models are arriving constantly, and the mental overhead of choosing the right setup for each task keeps growing.
That motivated us to build Smart Routing: an intelligent layer that automatically matches each task to the right model based on its complexity and the capabilities it needs. Our early results are promising: frontier level quality with 30%+ lower cost, and more than 50% savings on public benchmarks. -
Matei Zaharia reposted
Sarah Wang
@sarahdingwang
The fact that Databricks is growing nearly the same rate at $7b revenue as it was when the growth fund invested at ~$200m revenue 6 years ago never ceases to blow my mind. Today no one is better positioned to help the enterprise get true ROI out of AI.
Congrats @alighodsi @rxin and the entire @databricks team! Honored to be your partners.
Ali Ghodsi
@alighodsi
Today, we announced that we crossed $7B in revenue run-rate, growing over 80% year over year in Q2.
We also shared:
๐ $100M+ revenue run-rate for Lakebase
๐ $1.5B+ revenue run-rate for Lakehouse, growing over 100% year over year
๐ Continued positive adjusted free cash flow
And we raised $5B in our latest fundraise.
Weโll use this capital to invest in:
1๏ธโฃ Lakebase, our serverless Postgres database built for AI agents
2๏ธโฃ Genie, our AI coworkers that actually understand your business data
3๏ธโฃ Unity AI Gateway, our multi-AI governance solution that helps control costs
@iamVictorDey shares more in @Forbes:
www.forbes.com/sites/victordey/2026/08/13/databricks-hitsโฆ -
Matei Zaharia
@matei_zaharia
Smart Routing is now available in Unity AI Gateway on @databricks to improve coding agent quality and cost! Read how we built it to make it task-aware and preserve good cache hit rates. With so many frontier models coming out every week, this can really improve both cost and quality.
Databricks
@databricks
Introducing Smart Routing in Unity AI Gateway.
Stop overpaying for AI. Smart Routing matches each coding task to the right model and harness based on what the task needs, so higher-cost models can differentiate on intelligence while lower-cost models differentiate on cost and performance.
Match frontier quality and cut task costs by 30%+.
www.databricks.com/blog/smart-routing-unity-ai-gateway-maโฆ -
Matei Zaharia reposted
Databricks
@databricks
Introducing Smart Routing in Unity AI Gateway.
Stop overpaying for AI. Smart Routing matches each coding task to the right model and harness based on what the task needs, so higher-cost models can differentiate on intelligence while lower-cost models differentiate on cost and performance.
Match frontier quality and cut task costs by 30%+.
www.databricks.com/blog/smart-routing-unity-ai-gateway-maโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Today, we announced that we crossed $7B in revenue run-rate, growing over 80% year over year in Q2.
We also shared:
๐ $100M+ revenue run-rate for Lakebase
๐ $1.5B+ revenue run-rate for Lakehouse, growing over 100% year over year
๐ Continued positive adjusted free cash flow
And we raised $5B in our latest fundraise.
Weโll use this capital to invest in:
1๏ธโฃ Lakebase, our serverless Postgres database built for AI agents
2๏ธโฃ Genie, our AI coworkers that actually understand your business data
3๏ธโฃ Unity AI Gateway, our multi-AI governance solution that helps control costs
@iamVictorDey shares more in @Forbes:
www.forbes.com/sites/victordey/2026/08/13/databricks-hitsโฆ -
Matei Zaharia reposted
Ivan Zhou
@ivanzhouyq
We worked with @SpaceXAI to evaluate Grok 4.6 on the latest OfficeQA Pro V2 from @DbrxMosaicAI. It achieves the SOTA performance with @databricks's Genie harness!
The model is strongest on our document understanding and data reasoning tasks, and it is a very efficient driver! -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
3 frontier models in one day!
- Grok 4.6: Fable 5-level, but 85% cheaper.
- Qwen3.8-Max: 2.4T params, 95B active. Weights are out.
- DeepSeek-V4-Pro-0813: weights could drop any time. Heard itโs good, not just benchmaxxing.
Competition is great for consumers and businesses. -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent v0.9.0 is now available! ๐
๐งญ Smart routing (@databricks AI Gateway + OSS)
๐จ Refreshed web UI
๐งฐ More sandbox and deployment control
๐ค Grok Build harness + example agents
๐ nimble_extract and nimble_research builtins
๐ Full details, bug fixes, and upgrade notes:
github.com/omnigent-ai/omnigent/releases/tag/v0.9.0
#omnigent #aiagents -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Did you know you can run Omnigent sessions straight from Slack? ๐
Mention the bot to start work, then approve tool calls and answer multiple-choice prompts inline in the thread.
Learn more: omnigent.ai/docs/interact/slack
#agents #omnigent -
Matei Zaharia reposted
Neon
@neondatabase
PGlite + real-time sync have emerged as key primitives in an era where millions of apps are deployed by agents.
Weโre excited to announce @ElectricSQL is joining team Neon at Databricks to build the world's most advanced Postgres backend platform.
neon.com/blog/electric-joins-neon -
Matei Zaharia
@matei_zaharia
Welcome to Databricks and @neondatabase, @ElectricSQL!
Ali Ghodsi
@alighodsi
Excited to share that we've acquired ElectricSQL, the team behind PGlite. Agents need super fast Postgres and this team built an amazing WASM (WebAssembly) implementation of postgres that runs in your browser, but can sync back with Postgres instances asynchronously. Exactly what blazing fast AI agents today need. Excited to supercharge our ๐๐๐ค๐๐๐๐ฌ๐ ๐๐จ๐ฌ๐ญ๐ ๐ซ๐๐ฌ offering with these capabilities.
www.databricks.com/blog/electric-joins-databricks-bring-wโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Excited to share that we've acquired ElectricSQL, the team behind PGlite. Agents need super fast Postgres and this team built an amazing WASM (WebAssembly) implementation of postgres that runs in your browser, but can sync back with Postgres instances asynchronously. Exactly what blazing fast AI agents today need. Excited to supercharge our ๐๐๐ค๐๐๐๐ฌ๐ ๐๐จ๐ฌ๐ญ๐ ๐ซ๐๐ฌ offering with these capabilities.
www.databricks.com/blog/electric-joins-databricks-bring-wโฆ -
Matei Zaharia
@matei_zaharia
AI tokens are another resource to optimize in software engineering now. My cofounder @pwendell wrote about how we and other tech companies are starting to manage this resource now, by routing everything through an AI Gateway. This enables centralized analysis (e.g. we found settings we can change on Claude Code and Codex to lower cost a lot), smart routing, and โpushing downโ control to our engineers so they can set budgets on individual tasks and prevent surprises.
Patrick Wendell
@pwendell
Today @databricks we're publishing a detailed analysis of techniques we used to drastically reduce our internal AI spend while aggressively growing adoption. Savings come from layering in several techniques, which combine to drive unit costs down as much as 90% in some scenarios. Tl;dr, the wins come from:
1. Shifting defaults to more efficient models, including OSS models such as GLM. Maximum intelligence models simply aren't needed for many coding tasks, and "good enough" models are quickly becoming very cheap. We shift traffic between models using Unity AI Gateway. Approximate savings: 50% or more.
2. Using smart routing to automate model selection. Routing can further squeeze efficiency by dynamically selecting the model or harness that can most efficiently execute a particular task. Our task-level routing leverages @omnigent_ai. Approximate savings: 30%.
3. Providing user visibility and adaptive budgeting. Every user can see how much they spend, and users receive hints on how to contain spend. Heavy spenders encounter progressive friction as they ratchet spend above certain levels. Approximate savings: 10%.
4. Managing context bloat by pruning tool call results and tuning harness settings. Extraneous context costs $$ and delivers no value. Tuning cache settings also help lower average token costs. Approximate savings: 10%. -
Matei Zaharia reposted
Patrick Wendell
@pwendell
Today @databricks we're publishing a detailed analysis of techniques we used to drastically reduce our internal AI spend while aggressively growing adoption. Savings come from layering in several techniques, which combine to drive unit costs down as much as 90% in some scenarios. Tl;dr, the wins come from:
1. Shifting defaults to more efficient models, including OSS models such as GLM. Maximum intelligence models simply aren't needed for many coding tasks, and "good enough" models are quickly becoming very cheap. We shift traffic between models using Unity AI Gateway. Approximate savings: 50% or more.
2. Using smart routing to automate model selection. Routing can further squeeze efficiency by dynamically selecting the model or harness that can most efficiently execute a particular task. Our task-level routing leverages @omnigent_ai. Approximate savings: 30%.
3. Providing user visibility and adaptive budgeting. Every user can see how much they spend, and users receive hints on how to contain spend. Heavy spenders encounter progressive friction as they ratchet spend above certain levels. Approximate savings: 10%.
4. Managing context bloat by pruning tool call results and tuning harness settings. Extraneous context costs $$ and delivers no value. Tuning cache settings also help lower average token costs. Approximate savings: 10%. -
Matei Zaharia reposted
Neon
@neondatabase
You can now branch your database AND your files without duplicating storage
Neon Object Storage gives you S3-compatible buckets that branch just like your Neon Postgres does -
Matei Zaharia reposted
Christopher Potts
@ChrisGPotts
I would like to not-at-all-humbly state that we were right all along (or at least since early 2024), not about anything neurosymbolic, but rather about how important it is to think in terms of AI systems, not just models: bair.berkeley.edu/blog/2024/02/18/compound-ai-systems/
-
Matei Zaharia reposted
Krista Opsahl-Ong
@kristahopsalong
๐ฃ Excited to introduce OfficeQA Pro V2, the next generation of OfficeQA Pro!
It's built on a new corpus of 120,000 PDFs provided by the U.S. Treasury.
Frontier AI agents average 26% accuracy. More info below ๐
www.databricks.com/blog/introducing-officeqa-pro-v2-new-bโฆ -
Matei Zaharia reposted
Jialin Zhang
@benzhang04
1/ We just made GEPAโs optimization loop much faster, along with improved generalization!
Instead of proposing and evaluating one candidate at a time, each GEPA step now proposes a batch of candidates and evaluates them all concurrently. Parallel proposals significantly cut wall-clock time (3โ4ร faster) while, surprisingly, also generalizing better (up to +11 pts). ๐งต -
Matei Zaharia reposted
Databricks
@databricks
Today, we're announcing General Availability of Unity AI Gateway, giving enterprises the cost, control, and choice they need to manage AI spend and enforce security across every AI agent and asset.
Thousands of customers are already running it. Over a quadrillion tokens have passed through the gateway in the past year.
Enterprise AI governance has changed. You're no longer managing a handful of models โ you're governing a sprawling estate of agents and apps that can access data, call tools, and take action on their own.
Unity AI Gateway serves as the central hub for any AI asset, including external agents, MCPs, skills, and coding assistants, and delivers end-to-end observability and granular cost attribution across models, providers, teams, and applications. www.databricks.com/blog/unity-ai-gateway-generally-available -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
Kimi K3 at 239 tokens/s!
Databricks is now #1 for Kimi K3 inference speed and latency on Artificial Analysis.
A huge 2.8T parameters model, itโs the largest oss model weโve ever served. We make sure the GPUs go brrr at Databricks. -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
@databricks has the fastest and lowest latency on Kimi K3 (max)! Great job by Databricks AI team!
artificialanalysis.ai/models/kimi-k3/providers -
Matei Zaharia reposted
Melissa Pan
@melissapan
Agents are becoming increasingly difficult to verify as they take on open-ended, real-world problems.
That is why weโre organizing the ๐ Who Verifies Agents? ๐ฆ Workshop at #neurips2026.
Weโre excited to bring together researchers working on robust verification, environment-grounded evaluation, process-level signals, simulators, agent safety, and real-world agent systems.
Check out our website for more details, and follow our official account for future updates!
Veri Agents
@veri_agents
Announcing the ๐Who Verifies Agents๐ฆ workshop at #neurips2026
As AI agents become more capable and are deployed more widely, how can we ensure they behave reliably and as intended?
๐๏ธ Workshop day: Dec 11โ12, 2026
๐ Sydney
Follow us for more details!
๐งต 1/n -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Join us in SF for the Agentic + AI Observability Meetup! ๐
An evening on agentic architectures, AI observability, and real-world Omnigent deployment.
๐น Corey Zumar (@databricks): Meta Harnesses for multi-agent coding
๐น Wesley Pasfield (@OpenAI): Governing production agents with Omnigent and Codex
๐น Mingling with bites and dessert
๐๏ธ August 12 | 5โ8 PM PT | Databricks SF office
๐ Register: luma.com/Agentic_AI_8-12
#omnigent #aiagents #aiobservability -
Matei Zaharia reposted
Databricks
@databricks
For forty years, transactional and analytical databases were treated as separate systems, connected by pipelines that moved data between them. As AI agents generate more database activity, that architecture is being reconsidered around speed, scale, and a single copy of governed data.
Databricks Co-Founder and Chief Architect @rxin joined @DataCampโs DataFramed podcast to discuss LTAP, Lakebase, real-time analytics, governance for AI agents, self-service analytics with Genie, and more.
Watch the full conversation: www.youtube.com/watch?v=US6Z_buKizkThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Databricks
@databricks
AI spend is climbing faster than the value it creates.
Join Databricks Co-founder and CTO @matei_zaharia and Product Director @kuhlenhuth to learn how Unity AI Gateway helps organizations move from token maxing to value maxing. See how it already governs more than 1 quadrillion tokens annually, with Omnigent providing open, multi-harness flexibility for developers.
Live on August 13. Register now: www.databricks.com/resources/webinar/govern-ai-spend-scalโฆ -
Matei Zaharia reposted
Jensen Huang
@JensenHuang
Attackers have frontier AI. Defenders need a frontier AI ecosystemโthe best open and closed models, force-multiplied by a global community.
During the Hugging Face incident, closed AI blocked essential forensics. An open-weight frontier model helped contain the intrusion.
Thatโs why we created the Open Secure AI Alliance.
NVIDIA
@nvidia
AI security advances when the industry builds in the open, together.
We're introducing the Open Secure AI Alliance with industry leaders to develop new techniques and tools to safeguard software and agents.
By sharing models, tooling and research in the open, we can broaden the community of defenders.
Learn more about the founding membersโ contributions: nvda.ws/4pD8Fc5 -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent 0.6.0 brings updates across file viewing, chat imports, Slack, and desktop support. ๐
๐ Richer file viewing: Preview PDFs with review comments, use find-in-file, view rendered previews for markdown and notebooks, and wrap long lines in diffs.
๐ฅ Chat imports: Import up to 50 Claude Code and Codex conversations with omni import.
๐ฌ Slack integration: Start and drive sessions, approve tool calls, and answer agent questions from Slack.
๐ป Desktop support: Use the native app on Windows and Linux, alongside macOS.
Read the full release notes: omnigent.ai/releases/0.6.0
#omnigent #opensource #aiagents #codingagents -
Matei Zaharia reposted
Julia Neagu
@juliaaneagu
We found that improving data agent quality also improves efficiency. Sometimes more is less: agents that take long, exploratory random walks are often less likely to arrive at the right answer.
We put Genie Code head-to-head against three leading general-purpose coding agents on 400+ real user data tasks.
Result below ๐ -
Matei Zaharia reposted
Databricks
@databricks
.@AnthropicAI's Claude Opus 5 is now available where your data already lives - governed, secure, and ready for custom AI applications and agents built with the data in your Lakehouse.
On Databricks' internal coding bench, Opus 5 achieved SOTA performance. It delivers major gains in agentic coding, professional knowledge work, and long-horizon reasoning, with stronger performance per token across effort levels. Teams can build agents that handle complex workflows with fewer iterations and meaningfully lower cost, all governed by Unity AI Gateway
Put Claude Opus 5 to work on your most important data, securely and at production scale. docs.databricks.com/aws/en/release-notes/product/2026/july -
Matei Zaharia
@matei_zaharia
AI-based research and engineering is one of the main topics we're researching in the STAR Lab at Berkeley, and something I'm seeing used in industry more and more too. This is nice work from my grad students packaging multiple AI-based "autoresearch" algorithms into one API in the GEPA package so you can mix-and-match them to get the best results. These can be used for anything from writing prompts to designing agents to optimizing code.
Shangyin Tan
@ShangyinT
Many LLM-based optimization algorithms have been proposed recently. We find that GEPA, AutoResearch, and Meta-Harness each win on different tasks and no single LLM optimizer wins everywhere.
How do we leverage the complementary performance profiles of these optimization algorithms?
Today, we release optimize_anything omni: a meta-optimizer that leverages the best of each optimizer. At a matched budget, omni beats every standalone optimizer. (thread) -
Matei Zaharia reposted
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
So excited to share that I received the SIGIR Early Career Research Award! ๐ฅน
I still remember attending my first SIGIR, watching someone receive this award, and thinking, โThereโs no way that could ever be me.โ And now, here I am!๐ต
This truly means so much to me. Thank you to the @ACMSIGIR community for recognizing my contributions. #sigir2026
P.S. Get yourself a PhD supervisor who matches your award-celebration energy ๐ So cool to celebrate this moment together! @claclarke -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
The GEPA team is excited to announce the release of optimize_anything omni, a meta-optimizer pipeline that lets you get the best of all optimizers, including GEPA, AutoResearch, Meta-Harness and others! We find that different optimizers have complementary performance profiles, and propose a simple pipeline, compatible with existing optimize_anything, to get the best of all optimizers for a given task!
Shangyin Tan
@ShangyinT
Many LLM-based optimization algorithms have been proposed recently. We find that GEPA, AutoResearch, and Meta-Harness each win on different tasks and no single LLM optimizer wins everywhere.
How do we leverage the complementary performance profiles of these optimization algorithms?
Today, we release optimize_anything omni: a meta-optimizer that leverages the best of each optimizer. At a matched budget, omni beats every standalone optimizer. (thread) -
Matei Zaharia reposted
Shangyin Tan
@ShangyinT
Many LLM-based optimization algorithms have been proposed recently. We find that GEPA, AutoResearch, and Meta-Harness each win on different tasks and no single LLM optimizer wins everywhere.
How do we leverage the complementary performance profiles of these optimization algorithms?
Today, we release optimize_anything omni: a meta-optimizer that leverages the best of each optimizer. At a matched budget, omni beats every standalone optimizer. (thread) -
Matei Zaharia reposted
Melissa Pan
@melissapan
It is very clear that cost and inefficiency is one of the biggest problem in agent systems now.
Cursor released router that choose models for either cost or performance. Omnigent from Databricks orchestrates between different harnesses. Fugu from Sakana etc.. And many other companies in the agent ecosystem is releasing features somewhat to reduce agent cost.
In BRANE, we work towards reducing cost in agents while preserving quality. Glad to see the community picking up the problem and the idea ๐
Diam
@diamai_
One agent benchmark cost Melissa Pan's team about $11,000 to profile.
Her 30-minute talk shows why choosing the model is only one part of the route. The system may also need to choose retrieval, document count, summarization, and whether an agent loop runs at all.
03:48 The cheapest and most expensive configurations differed in cost by roughly 1,000x. Exhaustive search is too expensive to repeat for every workload.
09:12 Two nearly identical questions need different pipelines. GLM-5 can answer who Matei Zaharia is from its weights. The same model invents an answer about Melissa until web search is enabled.
20:10 Pan explains BRANE, her system for routing each query to a full agent configuration. It gives every candidate configuration its own classical predictor, then selects the cheapest one likely to meet the accuracy target.
29:05 Across three benchmarks, BRANE was the only tested method that met the 100% static accuracy target on all three while reducing cost. The maximum reduction was 89%.
BRANE uses roughly 150 to 600 profiled queries per configuration. Most teams need a manual router before they have that history.
The article below starts there, with a fixed task card, proof, retry cap, and permission ceiling. Each comparable run adds a row to the ledger.
That ledger is the training data for the router you may automate later.This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent 0.6.0 is released! ๐
๐ Richer file viewing: inline PDF preview + review comments, find-in-file, markdown & notebook previews
๐จ Custom themes: guided editor + new Nord palette
๐ฅ Import your Claude Code & Codex chats
๐งญ Transcript navigation bar
๐ฌ Slack integration: run & approve sessions inline
๐ช Desktop app now available on Windows & Linux
Read more about it โก๏ธ omnigent.ai/releases/0.6.0
#omnigent #opensource -
Matei Zaharia reposted
Jane Zhang
@jjanezhang
๐ AI Classify + vector search beats frontier models on accuracy and cost!
At Databricks, we see customers with large taxonomy classification problems like vendor name normalization and biomedical entity linking. Typically they reach for regex, trained classifiers, or direct LLM calls, but these methods struggle on cost, maintenance, and context limits.
To address this, we experiment with 3 classification methods:
1. Vector search
2. AI Classify Workflow: shortlist label candidates with vector search, then classify with the Databricks AI Classify function
3. Direct frontier model calls (GPT-5.4 mini, GPT-5.6 Luna, Sonnet 5, Gemini 3.5 Flash) with prompt caching.
We find that the AI Classify workflow yields the best overall accuracy at ~100x cheaper than the next best direct frontier model.
Shoutout to my teammates @arnav_thebigman @ivanzhouyq @nihit_desai ! -
Matei Zaharia reposted
Neon
@neondatabase
We recently made Lakebase Search available on Neon: hybrid vector and full-text search built for agents.
One half of that is lakebase_text. Here's why we built it, and why Postgres' default BM25 solution isn't enough ๐งต -
Matei Zaharia
@matei_zaharia
I spent so long trying to explain @omnigent_ai well, but today I just asked it and it came up with the perfect description.
-
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Highly recommended interview with @matei_zaharia about open source @omnigent_ai . Meta-harnesses are the future!
Jamin Ball
@jaminball
Next up on @AltimeterCap First Pass: A conversation with @matei_zaharia from @databricks on Omnigent
Agents are in their infancy, and so are the ways we develop and build them. Omnigent is a meta-harness aimed at solving many of the gaps in agent development todayThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Melissa Pan
@melissapan
Building agents? We'd love to hear from you ๐ค
Take our survey to better understand how your agent's design compares with others in the community๐งญ and help shape the future of agent research ๐
By participating, you'll contribute to open science and help uncover common design choices, emerging shifts, and underexplored research opportunities ๐ฑAs we did with MAP v1, we'll share the findings openly with the entire community๐ค
๐งต Link in the thread! -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
We're raising funding at $188 billion valuation to double down on our AI strategy focused on three priorities:
1๏ธโฃ Unity AI Gateway - our multi-AI governance solution that helps control costs.
2๏ธโฃ Genie - our AI coworkers that actually understand your business data.
3๏ธโฃ Lakebase - our serverless Postgres database specifically for AI agents.
www.databricks.com/company/newsroom/press-releases/databrโฆ -
Matei Zaharia reposted
Wenjie Ma
@wenjie_ma
Turns out ARCโAGIโ3 may be saturable after all -- with the right harness. [schema] turns experience into a program world model, verifies it against the full history, then searches it for solutions without further real-world trial and error. See interesting interactive demos + analysis at schema-harness.github.io.
Haven Feng
@HavenFeng
Today, weโre introducing [schema]: a harness reaching 99% RHAE with Opus 4.8 + Fable 5 and 95.35% with GPT-5.6 Sol on ARC-AGI-3 Public set.
[schema] makes an LLM think like a physicist. ๐งตThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
Enterprises are seeking ways to manage AI cost, like rightsizing models, using open source, and doing RL. But, as we frequently remind each other at Databricks, 90% of that journey is data. Building evals to measure the tradeoffs of reducing agent cost. Marshalling realistic environments to make RL possible. Training is the final 10%. If you want to go on the journey to manage AI cost, getting your data, environment, and evals in order is the preparation for and measure of success. If data is 90% of the journey, consider your effort and your budget accordingly. This is the advice we constantly give to our customers and repeat to ourselves.
-
Matei Zaharia
@matei_zaharia
Lots of new goodies in Apache Spark 4.2: Metric Views, GEOGRAPHY and GEOMETRY types, AutoCDC in Spark Declarative Pipelines, and more, from 1900 total commits. Available today on Databricks: www.databricks.com/blog/introducing-apache-spark-42
-
Matei Zaharia
@matei_zaharia
Neon is evolving with three new backend functions now in beta, all branchable like the database! Object Storage, Functions and AI Gateway all ready for agents to safely work with to build the next generation of apps.
This is what the next wave of cloud infra for agentic development will look like.
Neon
@neondatabase
Today we're opening up the beta of our first 3 new products: Object Storage, Functions, and AI Gateway
Together with our database and Managed Better Auth (our auth service), they form the first version of our backend platform -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Excited to expand the offering! And everything branches for the benefit of agentic workflows!
Neon
@neondatabase
Today we're opening up the beta of our first 3 new products: Object Storage, Functions, and AI Gateway
Together with our database and Managed Better Auth (our auth service), they form the first version of our backend platform -
Matei Zaharia reposted
Databricks
@databricks
.@thinkymachines' first open-weights model, Inkling, is now available on Databricks through Unity AI Gateway.
As a day zero launch partner, Databricks gives enterprise teams access to a model that excels at coding and agentic reasoning and supports multimodal inputs.
Teams can customize Inkling for their business, govern it with centralized security, permissions, cost controls, and observability, and connect it to coding agents including Cursor and OpenCode.
Start building with Inkling on Databricks โ www.databricks.com/blog/inkling-thinking-machines-lab-nowโฆ -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Slow-burn attacks hide data theft inside steps that each look normal on their own.
This blog walks through the attack on a vendor-review agent in Omnigent. Without a contextual policy, the outbound email goes through. With session risk tracking, it gets blocked, and the agent cannot turn the policy off.
๐ www.databricks.com/blog/blocking-slow-burn-attacks-contexโฆ
#omnigent #aisecurity #opensource -
Matei Zaharia reposted
Sabhya Chhabria
@sabhyac267
Check out @omnigent_ai -- it's an OSS framework that lets you run any model x harness on any platform (phone, laptop, cloud, etc)!
-
Matei Zaharia
@matei_zaharia
Very interesting, this is why you really need to benchmark agents, especially with reasoning models that use variable # of tokens. This is similar to what we saw in some applications with Sonnet (www.databricks.com/blog/benchmarking-coding-agents-databrโฆ) and to arxiv.org/abs/2603.23971. It will surely depend by task though!
Artificial Analysis
@ArtificialAnlys
GPT-5.6 Sol and Luna are ahead of Terra at every point on the Intelligence vs Cost per Task chart. GPT-5.6 Luna stands out as a particularly cost efficient model
Charting the Artificial Analysis Intelligence Index shows the trade-off between intelligence and Cost per Intelligence Index Task. Across reasoning efforts, each GPT-5.6 model pushes past GPT-5.5 on the Pareto frontier (excluding non-reasoning).
However, Luna and Sol are always ahead of Terra. This means for any Terra effort level, there is a Luna or Sol effort level that is more intelligent at no extra cost, or as intelligent at lower cost. -
Matei Zaharia reposted
Alex Dimakis
@AlexGDimakis
Best Paper Award to our ICML Workshop paper 'Fantastic Adaptive Taxonomies and How to Use Them'.
Let me summarize briefly what the paper is about: Failure taxonomies are becoming increasingly important.
We show that failure taxonomies can be used in multiple ways: 1. As a test-time scaling tool for best-of-N judges, 2) as a mutation feedback mechanism in optimization loops and 3) as runtime feedback for coding agents.
Previously people used MAST and other hand-made fixed failure taxonomies. In this paper we show how to create the failure taxonomy adaptively and dynamically: We observe agent rollouts and create an adaptive failure taxonomy, bespoke to the agent weaknesses and task challenges. These adaptive taxonomies give a massive boost: On Terminal Bench 2 we get 89.9% with Opus 4.6 / Forgecode harness and the adaptive taxonomy used with a Best-of-N Judge, outperforming fixed taxonomies by 15%. (1/n) -
Matei Zaharia reposted
Liana
@lianapatel_
Excited to share that DeepScholar-Bench has been accepted to COLM 2026!
Huge thanks to my co-authors @NegarEmpr @harshitgupta412 @AnkitaSundar @istoica05 @guestrin @matei_zaharia
Liana
@lianapatel_
Interested in building and benchmarking deep research systems?
Excited to introduce DeepScholar-Bench, a live benchmark for generative research synthesis, from our team at Stanford and Berkeley!
๐Live Leaderboard guestrin-lab.github.io/deepscholar-leaderboard/leaderboarโฆ
๐ Paper: arxiv.org/abs/2508.20033
๐ ๏ธ Code: github.com/guestrin-lab/deepscholar-bench
๐งต๐ -
Matei Zaharia
@matei_zaharia
Omnigent 0.5 is out including a native iOS app thatโs more convenient for coding on mobile! You can connect it to your own Omnigent server and reach the same agents.
Omnigent
@omnigent_ai
Omnigent 0.5.0 is Released!
Highlights in this release:
๐ฑ Omnigent for iOS apps.apple.com/us/app/omnigent/id6783102694
๐งฉ Generic ACP harness
๐ Command palette & richer search
๐จ More appearance & customization setting
๐ฌ Message steering & queuing
โธ๏ธ Kubernetes deployment
๐ Embedded browser
Enjoy!
Read more about this release: omnigent.ai/releases/0.5.0 -
Matei Zaharia reposted
Databricks
@databricks
OpenAI GPT-5.6 Sol, GPT-5.6 Terra, and GPT-5.6 Luna are now available as Databricks-hosted models through Model Serving.
Built for complex problem-solving, coding, and budget-friendly workloads, the GPT-5.6 series uses fewer tokens to complete tasks, making the models highly efficient and cost-effective.
Access all three through Foundation Model APIs on a pay-per-token basis. docs.databricks.com/aws/en/release-notes/product/2026/july -
Matei Zaharia reposted
Omnigent
@omnigent_ai
Using multiple coding agents every day? The harder question is how they work together.
Join us on July 22 from 5 to 8pm PT at the @databricks SF office for a meetup on multi-agent coding workflows. โฌ๏ธ
๐ค Omnigent talk: Claude Code, Codex, Cursor, OpenCode, Pi + more
๐ค Panel with engineering leaders from @DoorDash & other AI-forward teams on orchestration, supervision, sandboxing, governance
๐ Bites + dessert
Register: luma.com/omnigent_multi-agent_coding
#omnigent #aiagents #genai -
Matei Zaharia
@matei_zaharia
Great example of building a difficult domain-specific benchmark and learning from it! Every company seriously pursuing agents needs to build evals like this.
Maithra Raghu
@maithra_raghu
Excited to be releasing FrontierFinance, the largest and most challenging open benchmark for evaluating AI agents across the full investment workflow!
FrontierFinance is substantially harder than current finance benchmarks: Existing benchmarks like FinanceBench and Finance Agent focus almost entirely on data extraction.
FrontierFinance spans diverse use cases across the full investment process: Screening & Discovery, Company Research, Sector/Industry/Macro, Earnings & Events, and Coverage & Catalyst Monitoring.
Created for ambiguous, long-horizon agents: 220 examples paired with 11,543 expert-crafted rubrics, following Samaya's Criteria Eval methodology. The rubrics are what let us evaluate the reasoning and steps behind a true expert-level output, not just a plausible-looking one.
Evaluations: We evaluated Claude Fable 5, Claude Opus 4.8, GPT 5.5, Gemini, open-source models including GLM and DeepSeek, and others. We used the same public rubric and a standard harness for financial tasks. Samaya's AI system reached state-of-the-art accuracy at 50.8%, at 4x lower inference cost than Fable 5. Next best was Fable 5 (49.2%), then Opus 4.8 (45%) and GPT 5.5 (43.5%).
We're releasing the benchmark, methodology, and full evaluation results - see link in comments.
Future releases: FrontierFinance was curated from Samaya's larger internal set of ~5,000 examples, and we plan to release subsequent, harder benchmarks as well as a more detailed technical report! -
Matei Zaharia reposted
Melissa Pan
@melissapan
Check out our โจOral Talkโจ today 4:15pm at Hall B2
if you want to learn about research opportunities in agents ๐
#icml #icml2026
Melissa Pan
@melissapan
Come to Hall A #4211 between 10:30-12:30 today if you want to learn about โจagent research opportunitiesโจ and where should agent research be heading to! #icml #icml2026
-
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
At Databricks, we built an internal coding benchmark on our multi-million-line codebase.
Biggest takeaways:
1. Open-source coding models are no longer toys. GLM-5.2 is strong and cheaper.
2. OpenAI, Anthropic, and GLM-5.2 are all on the Pareto frontier. The real unlock is an intelligent router that picks the right model for the task (weโre building this!).
3. Stop comparing models by $/token. Start comparing them by $/task.
Matei Zaharia
@matei_zaharia
We benchmarked coding agents on our own internal tasks at Databricks and learned a lot!
There are many surprising opportunities to lower cost and increase quality, and many models including open source ones are truly competitive now. ๐งต -
Matei Zaharia
@matei_zaharia
One reason we built custom coding and data agent benchmarks internally at Databricks (e.g. www.databricks.com/blog/benchmarking-coding-agents-databrโฆ). Academic benchmarks are great and people will build better ones, but you also care about YOUR tasks, which are often different. Each company needs its own "loop".
OpenAI
@OpenAI
We audited SWE-Bench Pro, one of the most widely used AI coding benchmarks, and found it no longer reliably measures frontier coding capability.
We find 30% of SWE-Bench Pro tasks to be broken, and are retracting our previous recommendation that the research community use it as a leading coding eval.
openai.com/index/separating-signal-from-noise-coding-evalโฆ -
Matei Zaharia
@matei_zaharia
We benchmarked coding agents on our own internal tasks at Databricks and learned a lot!
There are many surprising opportunities to lower cost and increase quality, and many models including open source ones are truly competitive now. ๐งต
Matei Zaharia
@matei_zaharia
Why did we build an internal coding benchmark? Public benchmarks like SWE-Bench are often over-tuned for, so we took real tasks our engineers did and curated test suites for them to see which agents can solve them end-to-end. www.databricks.com/blog/benchmarking-coding-agents-databrโฆ
Post not available here, view on X
Matei Zaharia
@matei_zaharia
3) Harnesses make a huge difference in cost-performance. The very simple Pi harness (@badlogicgames) got the same success rate as harnesses from the LLM vendors with Opus and GPT 5.5, but at 2x less cost! Seems to be mainly due to smaller inputs to the LLM.
Matei Zaharia
@matei_zaharia
4) Cheaper per-token does not imply cheaper per-task. For example, Sonnet 5 costs less per token than Opus 4.8 but used more tokens, resulting in higher cost and lower quality. Interestingly my ex-student @ChenLingjiao had also found this on other tasks: arxiv.org/abs/2603.23971
Matei Zaharia
@matei_zaharia
Read more in the blog how we built the benchmark and what we're doing with the findings. This is partly why we built @omnigent_ai as a "meta-harness" to let developers switch and compose agents, and Unity AI Gateway to analyze and gate LLM usage centrally. www.databricks.com/blog/benchmarking-coding-agents-databrโฆ
-
Matei Zaharia
@matei_zaharia
Amazing that @PostgreSQL has been around for 30 years and is still growing and getting better! This is the awesome thing about open source.
Neon
@neondatabase
Happy 30th birthday Postgres! ๐
What an accomplishment, almost nothing in tech has stayed relevant for 30 years.
From humble beginnings as a Berkeley research project to becoming the default for everything from side projects to massive production systems.
30 years later, the database and the community have more momentum than ever. It's why we built Neon on Postgres, serverless, but 100% the Postgres you love. ๐ -
Matei Zaharia reposted
Neon
@neondatabase
Happy 30th birthday Postgres! ๐
What an accomplishment, almost nothing in tech has stayed relevant for 30 years.
From humble beginnings as a Berkeley research project to becoming the default for everything from side projects to massive production systems.
30 years later, the database and the community have more momentum than ever. It's why we built Neon on Postgres, serverless, but 100% the Postgres you love. ๐ -
Matei Zaharia reposted
Matei Zaharia
@matei_zaharia
Yes, the name of the game is more usable / expressive security policies. The same is used for human actions. Should you have to 2FA each time you check your email? Maybe not in the office, but if you suddenly teleport to another country, maybe yes.
-
Post not available here, view on XPost not available here, view on X
Matei Zaharia
@matei_zaharia
Yes, the name of the game is more usable / expressive security policies. The same is used for human actions. Should you have to 2FA each time you check your email? Maybe not in the office, but if you suddenly teleport to another country, maybe yes.
-
Matei Zaharia
@matei_zaharia
Most coding agents have very limited features for controlling security: just a list of actions to allow, deny, or ask users on. In @omnigent_ai, we introduced Contextual Policies, which can track *state* about a session to manage both security and cost in a far more flexible way.
Matei Zaharia
@matei_zaharia
As a meta-harness, Omnigent lets you add these over any existing coding agents (Claude Code, Codex, OpenCode, Pi, etc) or custom agents. More in our blog: www.databricks.com/blog/contextual-policies-omnigent-usinโฆ
Matei Zaharia
@matei_zaharia
Tracking state makes policies way more powerful. Some examples:
- Track whether an agent has read a confidential doc, and if so, require approval for it to send emails.
- Track the total cost of each agent session as it runs and ask the user to continue after each $10 spent.Post not available here, view on X
Matei Zaharia
@matei_zaharia
Omnigent ships with many useful built-in policies in the open source repo and lets you write your own. Read more about contextual policies at www.databricks.com/blog/contextual-policies-omnigent-usinโฆ
Matei Zaharia
@matei_zaharia
In general, good security needs to be usable, and contextual policies help a ton. For example, they also enable "intent based" security: set permissions based on the user's first prompt. If I ask an agent to send a tweet, it should not be pushing to Git. This is super easy to do.
-
Matei Zaharia reposted
Omnigent
@omnigent_ai
Omnigent v0.4.0 is live ๐
๐Harness plugin SDK (bring your own agent)
๐ง Model router picks harness + model per turn
๐คน Polly fans work to Cursor, Hermes, OpenCode
๐ชข Native-harness parity + cost/polish fixes
uv tool install --force "omnigent==0.4.0"
github.com/omnigent-ai/omnigent/releases/tag/v0.4.0
#omnigent #opensource -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
My co-founder @rxin personally wrote this really good paper that explains the main idea behind postgres Lakebase as well as LTAP. It almost serves as a primer on how transactional databases are built and how Lakebase and LTAP work. Maybe more importantly, what are the tradeoffs, and what are you giving up by adopting this new approach. Highly recommended reading:
www.databricks.com/blog/lakebase-ltap-rethinking-databaseโฆ -
Matei Zaharia
@matei_zaharia
It was great being on this panel with @vgcerf, @fchollet, Dave Patterson and @JohnOusterhout on building things that last at OpenFrontier yesterday! Probably the only time Iโll be on a panel with two Turing Award winners. Great conference overall and all the panels were recorded.
Laude Institute
@LaudeInstitute
"Father of the Internet" Vint Cerf @vgcerf joins Dave Patterson, @fchollet and @JohnOusterhout to talk about lessons from building the internet and how they apply to building an open commons in AI.
www.youtube.com/live/-41kYH6JgvU -
Matei Zaharia reposted
Liana
@lianapatel_
Agentic map-reduce is an incredibly powerful pattern. It's also just one pattern of a whole family of declarative LLM operators (e.g., filters, joins, sorting etc) that allow for better LLM-based bulk processing over large datasets. Check out LOTUS' open-source agentic map-reduce, and many more semantic operators that serve and optimize a very broad variety of tasks that require parallel LLMs over your data github.com/lotus-data/lotus
Cognition
@cognition
Introducing Devin Security Swarm
A more cost effective and accurate way to find security vulnerabilities in complex codebases, based on a new architecture: Agentic MapReduce.This media couldn't be displayed. See it on the original post. -
Matei Zaharia
@matei_zaharia
Similar to what I've done for a lot of development. I also frequently have them cross-review plans or search for bugs in parallel. I can easily get different agents that see each other's state in one Omnigent session.
Mitchell Hashimoto
@mitchellh
I'm having a lot success using Fable xhigh as a planner/architect, using GPT 5.5 xhigh (subscription) as a coder, then Fable xhigh again as a judge. At API pricing, planning+judge costs are in the ~few dollar range compared to typical $50+ full round trips.
I've seen some others using dumber/cheaper coders, but GPT 5.5 even at xhigh compared to Fable 5 is very cheap and very fast. And GPT 5.5 is just... really good.
Still been less than 24hrs since the re-release so the longevity of this approach is unclear, but its been working really well. -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
I predicted this months ago:
The highest-paying jobs today may be first in line for AI disruption.
GPU kernel engineers used to get million-dollar offers. Now AI agents can self hill climb, write better kernels, and top the leaderboard.
(We didnโt even use Fable or GPT-5.6)
Yuchen Jin
@Yuchenj_UW
Databricks ranks #1 on NVIDIAโs SOL-ExecBench kernel leaderboard, in the L1 single operation track, powered by KDA (Kernel Design Agents) ๐
Whatโs crazy is: we 100% leveraged AI agents to beat the competition.
This is a sneak peek at recursive self-improvement. The core frameworks we used were KDA, Humanize, and Omnigent: Claude writes code, Codex reviews. Together, they enabled agents to run autonomously for as long as possible. The key is setting up the right framework to let the agents cook.
This work was driven by @leshenj15 at Databricks, in collaboration with NVIDIA and MIT HAN Labโs @LigengZhu and @DongyunZou03 .
Databricks AI is like a neolab. Join us if youโre cracked! -
Matei Zaharia reposted
Databricks
@databricks
Full-text search indexes are now available in Beta on Databricks Runtime 18.2.
Create a search index with a single SQL statement to accelerate substring and keyword queries, with no query hints or application changes required.
Teams are already seeing 100x+ faster substring search queries against petabyte-scale tables.
Learn how it works:
www.databricks.com/blog/accelerate-search-queries-full-teโฆ -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
2 key lessons we learned:
- agents are very good at reward hacking. We spent a lot of time preventing them from cheating the benchmark.
- multi-model, multi-agent collaboration is the future. @databricks Omnigent + AI Gateway are built for exactly this.
Kernel leaderboard: research.nvidia.com/benchmarks/sol-execbench/leaderboard/โฆ
KDA: github.com/mit-han-lab/kernel-design-agents
Humanize: github.com/PolyArch/humanize
Omnigent: omnigent.ai -
Matei Zaharia
@matei_zaharia
This is really cool, using multiple models to auto-optimize GPU kernels better than the state of the art. Why limit your agents to models from just one company?
Yuchen Jin
@Yuchenj_UW
Databricks ranks #1 on NVIDIAโs SOL-ExecBench kernel leaderboard, in the L1 single operation track, powered by KDA (Kernel Design Agents) ๐
Whatโs crazy is: we 100% leveraged AI agents to beat the competition.
This is a sneak peek at recursive self-improvement. The core frameworks we used were KDA, Humanize, and Omnigent: Claude writes code, Codex reviews. Together, they enabled agents to run autonomously for as long as possible. The key is setting up the right framework to let the agents cook.
This work was driven by @leshenj15 at Databricks, in collaboration with NVIDIA and MIT HAN Labโs @LigengZhu and @DongyunZou03 .
Databricks AI is like a neolab. Join us if youโre cracked! -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
Databricks ranks #1 on NVIDIAโs SOL-ExecBench kernel leaderboard, in the L1 single operation track, powered by KDA (Kernel Design Agents) ๐
Whatโs crazy is: we 100% leveraged AI agents to beat the competition.
This is a sneak peek at recursive self-improvement. The core frameworks we used were KDA, Humanize, and Omnigent: Claude writes code, Codex reviews. Together, they enabled agents to run autonomously for as long as possible. The key is setting up the right framework to let the agents cook.
This work was driven by @leshenj15 at Databricks, in collaboration with NVIDIA and MIT HAN Labโs @LigengZhu and @DongyunZou03 .
Databricks AI is like a neolab. Join us if youโre cracked! -
Matei Zaharia reposted
Reynold Xin
@rxin
I find the Lakebase design for serverless Postgres very elegant, so I spent some time explaining how it works in this blog.
The blog starts by explaining how databases really persist data (with a write-ahead-log and data files that are updated async), and how Lakebase separates storage and compute by externalizing those two components. It ends with how the Lakebase architecture naturally leads to LTAP, enabling OLTP and analytical workloads against a single governed copy of data.
My goal was to make it readable by anyone curious about how these systems work, not just database and storage experts. That turned out to be a lot more challenging than I first thought. Database storage is one of the most complex areas in computer science (the ARIES paper cited in blog was the hardest paper I personally ever had to read). The first draft had too little detail and I couldn't land the ideas. The second had too much and I'd lost anyone who isn't already a storage expert. This is the third draft, and I'd love feedback on whether the depth feels right.
www.databricks.com/blog/lakebase-ltap-rethinking-databaseโฆ -
Matei Zaharia reposted
Laude Institute
@LaudeInstitute
The researchers and scientists are headed to their breakout sessions to dig in to the real work of ensuring AI stays in the open. Tune back in at 3:30 p.m. PT for our next livestreamed discussions from Open Frontier:
Building Things That Last: Lessons from Computing's Long Arc with Dave Patterson, @fchollet, @vgcerf, @JohnOusterhout, and @matei_zaharia
Then: From Open Research to World-Scale Infrastructure with @alighodsi and @Thom_Wolf
www.youtube.com/live/-41kYH6JgvU -
Matei Zaharia reposted
Laude Institute
@LaudeInstitute
Open Frontier is live in SF - catch the first panel discussion, featuring @percyliang @natolambert @istoica05 @ctnzr
youtube.com/live/-41kYH6JgvU -
Matei Zaharia reposted
Sabhya Chhabria
@sabhyac267
This is a similar core thesis we had when we @omnigent_ai's multi-agent multi-harness orchestrator Polly:
1. We were going crazy talking to 10-15++ agent threads at a time. In an ideal world I only talk to one agent and tell it what I need to get done and it dispatches as many sub agents to do the needful.
2. Human attention is the most scarce resource in agentic engineering. It's very easy for me to spin up a 100 different threads, but jumping between thread's continuously fragments my attention and makes me less productive.
3. Because @omnigent_ai AI is multi-harness, it naturally lends itself to loops / workflows like: Claude build, Codex review, and then have them go back and forth
4. Instead of having one agent per /loop, we're trying to push and see if we can have an Polly (our orchestrator) reliably run several /loops & /goals all at once and only bring in the human when absolutely necessary
So many interesting problems still to solve: context management across several disjoint threads, sub agent life cycle architectures, reliably getting agents with different harnesses to work well together, improving speed + throughput of completed tasks while preserving & protecting human attention. If any of this sounds interesting to would love to chat more!
Boris Cherny
@bcherny
In the next version of Claude Code: subagents run in the background by default, so you can keep talking to Claude while your subagents work
If you want your agent to run in the foreground, just tell Claude -
Matei Zaharia
@matei_zaharia
Good lessons on managing AI spend. We support a lot of this natively on Databricks with Unity AI Gateway, which makes it easy to analyze and control usage in one place, and itโs also easy to set these up as policies with the open source omnigent.ai framework.
Brian Armstrong
@brian_armstrong
How to keep AI spend flat while token usage grows exponentially: Not with friction and spend alerts. With better defaults, routing, and caching.
Better Defaults (not Usage Caps) โ Engineers can choose any model they want, but defaults matter. Weโre experimenting with defaulting to open weight models like GLM 5.2 and Kimi 2.7 through our LLM gateway, while still encouraging engineers to choose the right model for the task. 91% of our employees were never hitting their usage caps, so instead of lowering caps and driving up alerts, we're moving to cheaper defaults. Note that code reviews use a diversity of models, so they can check each other's work.
Better Routing โ In our custom harnesses, we preprocess prompts and route to the best model for the job, considering cache hits and model pricing. For instance, you may want a frontier model for planning, but not for execution where they can be overkill. Ultimately, humans shouldn't be choosing models - AI can automate this task.
Better Caching โ Cache misses are the easiest way to drive your cost up. All of our requests are cache aware, so weโre reusing a warm cache wherever possible. For example, our cache hit rate went from 5% โ 60% in LibreChat once properly implemented.
Keep Context Lean โ Start fresh sessions when switching tasks. Scope file context narrowly. Disconnect unused tools. Don't just compact. The goal isn't fewer tokens used, it's fewer tokens wasted.
Better Visibility โ Our engineers can use as many tokens as they want, from whatever model they want, but weโve made usage visible โ and the more you spend on AI, the more impact we expect.
The goal isn't to suppress usage. It's to build the infrastructure that makes exponential growth sustainable.
Putting this into practice has cut our AI spend nearly in half, while our token usage continues to grow. -
Matei Zaharia reposted
Omnigent
@omnigent_ai
We are happy to announce #omnigent v0.3.0!
Major new features
๐ค Seven new agent harnesses: #hermes (SDK + native TUI), #github #copilot (SDK), #opencode, #goose, #qwencode, #kiro, and #kimicode; plus #antigravity promoted to a full SDK + native #agy CLI harness
๐ชข Native-harness parity across the fleet: compaction, cost/token tracking, resume, true fork with history, in-session model switching, and tool-approval / AskQuestion web cards, for #cursor, #codex, #qwen, #pi, #hermes, #goose, and #opencode
๐ฅ๏ธ Omnigent Desktop: now manages the server + runner automatically
๐๏ธ Projects workspace:vgroup sessions into Projects and drag between them, plus a Settings surface and per-harness run-mode memory
๐งญ Intelligent model router to pick the right model per turn
๐ฆ More deploy & sandbox targets: host on #databricks Apps + #lakebase #postgres, #aws #bedrock provider, on-demand #kubernetes runner #pod sandbox, and a #boxlite managed host
๐ช Native #windows support
๐ต๏ธ Custom #agent Creation UI
๐ In-app #mcp management from Agent Info, sys_session_share agent-facing session sharing, and web UX polish โ shortcuts overlay, pinned-session hotkeys, image lightbox
Read details about this release: github.com/omnigent-ai/omnigent/releases/tag/v0.3.0 -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Highly recommended if you want to understand how why Omnigent and LTAP are important!
Latent.Space
@latentspacepod
Why the Frontier Ecosystem must be Open โ Matei Zaharia and Reynold Xin, Databricks www.latent.space/p/databricks
@databricks cofounders @matei_zaharia and @rxin explain why Databricks is moving into the infrastructure layer for enterprise agents, how Omnigent creates a shared harness for coding agents and custom agents, why LTAP and Lakebase rethink the split between operational and analytical databases, why agent security needs contextual policies and spend controls, and why the future of software may be as simple as getting the right data in place and putting agents on top.This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Oh you're right! Key point being that open source GLM is over 300 tokens per second. This matters for agents (we all hate waiting 10 minutes for responses). Proprietary frontier models are at best at 100 tokens per second. So 3x speedup really matters for agentic workloads.
-
Matei Zaharia
@matei_zaharia
The Databricks inference team is ๐ฅ
Yuchen Jin
@Yuchenj_UW
You may have heard that GLM-5.2 at 328 token/s is cool,
How about 392?
Databricks is now #1 in inference speed for GLM-5.2 on Artificial Analysis. It's a great model, and we did a lot of optimizations. -
Matei Zaharia reposted
Parth Asawa
@pgasawa
Always fun to chat with @andykonwinski, see 41:33 for some of my brief takes on evaluating continual learning and academia / open science.
Laude Institute
@LaudeInstitute
At @CAISconf last month, @andykonwinski sat down with researchers on the conference floor -- @matei_zaharia @istoica05 @lateinteraction @dawnsongtweets @gneubig @pgasawa @JonSaadFalcon @heathercmiller @ryan_marten @alexgshaw @profjoeyg @swyx and Ioannis Ioannidis -- to talk open vs. closed, agent evals, compound AI systems, and where the frontier is headed ๐
www.youtube.com/watch?v=PbymvxpbWHg -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
You may have heard that GLM-5.2 at 328 token/s is cool,
How about 392?
Databricks is now #1 in inference speed for GLM-5.2 on Artificial Analysis. It's a great model, and we did a lot of optimizations. -
Matei Zaharia reposted
swyx
@swyx
LOTS of alpha in this pod:
- Why Databricks beat Snowflake (! a straight answer!)
- Why everyone is building a metaharness now
- Why the @neondatabase made so much sense (so much @nikitabase glazing its not even funny)
- How LTAP solves the HTAP dream I discussed with @ankrgyl in our @braintrust pod
- What happened to @MosaicML + DBRX
- How to maintain research/startup culture in a $175B megacorp
- What's more important knowledge/experience in the race to the agent cloud: databases, operating systems, or.... networking!
very honored to be invited to @Data_AI_Summit to interview two of the top people in our industry and somehow be able to jam on everything from the @bennstancil modern data stack theme to @alighodsi's amazing keynote aura
Latent.Space
@latentspacepod
Why the Frontier Ecosystem must be Open โ Matei Zaharia and Reynold Xin, Databricks www.latent.space/p/databricks
@databricks cofounders @matei_zaharia and @rxin explain why Databricks is moving into the infrastructure layer for enterprise agents, how Omnigent creates a shared harness for coding agents and custom agents, why LTAP and Lakebase rethink the split between operational and analytical databases, why agent security needs contextual policies and spend controls, and why the future of software may be as simple as getting the right data in place and putting agents on top.This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Latent.Space
@latentspacepod
Why the Frontier Ecosystem must be Open โ Matei Zaharia and Reynold Xin, Databricks www.latent.space/p/databricks
@databricks cofounders @matei_zaharia and @rxin explain why Databricks is moving into the infrastructure layer for enterprise agents, how Omnigent creates a shared harness for coding agents and custom agents, why LTAP and Lakebase rethink the split between operational and analytical databases, why agent security needs contextual policies and spend controls, and why the future of software may be as simple as getting the right data in place and putting agents on top.This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Laude Institute
@LaudeInstitute
At @CAISconf last month, @andykonwinski sat down with researchers on the conference floor -- @matei_zaharia @istoica05 @lateinteraction @dawnsongtweets @gneubig @pgasawa @JonSaadFalcon @heathercmiller @ryan_marten @alexgshaw @profjoeyg @swyx and Ioannis Ioannidis -- to talk open vs. closed, agent evals, compound AI systems, and where the frontier is headed ๐
www.youtube.com/watch?v=PbymvxpbWHg -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Join @databricks startup program and get @neondatabase for free
Databricks
@databricks
We're launching a new Databricks Startup Program!
Qualifying venture-backed startups can now receive up to $200K in credits across Databricks and @neondatabase, giving founders access to the app backend, data, and AI stack they need to go from idea to product-market fit.
The program also includes:
โข One application to access the full Databricks platform
โข Hands-on technical guidance to help teams architect and ship faster
โข Go-to-market support, partner access, and founder community connections
Wondering if you qualify? Learn more about the program and apply today: www.databricks.com/blog/announcing-new-databricks-startupโฆ -
Matei Zaharia reposted
Y Combinator
@ycombinator
When electric motors were invented, factories didn't become dramatically more productive overnight. The biggest gains came years later, after people redesigned factories around the new technology.
@databricks co-founder and Chief Architect Reynold Xin (@rxin) believes AI is creating a similar shift in software.
In this fireside with YC's @sdianahu, Reynold explains how AI agents are reshaping engineering organizations, why startups have an advantage in building AI-native products, and why the next generation of infrastructure needs to be lightweight, scalable, and built for agentic workloads from day one.This media couldn't be displayed. See it on the original post. -
Matei Zaharia
@matei_zaharia
Check this out if you're looking for a database, AI or analytics platform for your startup!
Databricks
@databricks
We're launching a new Databricks Startup Program!
Qualifying venture-backed startups can now receive up to $200K in credits across Databricks and @neondatabase, giving founders access to the app backend, data, and AI stack they need to go from idea to product-market fit.
The program also includes:
โข One application to access the full Databricks platform
โข Hands-on technical guidance to help teams architect and ship faster
โข Go-to-market support, partner access, and founder community connections
Wondering if you qualify? Learn more about the program and apply today: www.databricks.com/blog/announcing-new-databricks-startupโฆ -
Matei Zaharia reposted
Natalie Fratto
@NatalieFratto
5 million people watched my latest @chartsncrafts video explaining Databricks ๐ฑ so I decided to one-up myself in a p2 trying to explain the entire AI stackโฆ
Models! Harnesses! A fancy new open source meta-harness!
Thrilled to partner with @databricks on this one to help unveil Omnigent which I believe is going to entirely change the AI landscape.
Hope you find it helpfulThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Databricks
@databricks
Missed the #dataaisummit 2026 keynotes? Weโve got you covered.
Full keynote replays and select breakout sessions are now available on-demand to help you catch up on the biggest moments from the week.
Start watching: www.databricks.com/dataaisummit -
Matei Zaharia reposted
Dawn Song
@dawnsongtweets
๐จ The full program for Agentic AI Summit 2026 is now live.
๐ Aug 1โ2 @ UC Berkeley
๐ฅ The largest Agentic AI event ever held
Last year: 2,000+ in person, 40,000+ online
This year: 5,000+ in person, hundreds of thousands on livestream
Want to understand where Agentic AI is headed next?
Join us to get the most comprehensive view of the frontier of Agentic AI, from cutting-edge research to production deployments, covering every layer of the stack:
โก Infrastructure
โก Foundation models & capabilities
โก Agent frameworks & platforms
โก Evaluation & benchmarks
โก Enterprise & consumer applications; agentic AI for Science, Math, Finance, Legal, Healthcare
โก Safety, security & governance
๐ฃ Also excited to announce the Startup Spotlight:
Building something exciting in Agentic AI? Apply to pitch directly to 5,000+ decision-makers, investors, practitioners in the room and hundreds of thousands watching worldwide.
Application form in thread๐งต
Deadline: July 6, 11:59pm PT
The future of AI won't just be discussed hereโit will be built here.
#agenticai #aiagents #artificialintelligence -
Matei Zaharia reposted
Rishabh Tiwari
@rish2k1
-
Matei Zaharia
@matei_zaharia
Nice summary of learnings on self-distillation in the run-up to our Learning Fast & Slow paper!
Rishabh Tiwari
@rish2k1
-
Matei Zaharia reposted
Sabhya Chhabria
@sabhyac267
GLM 5.2 initial test to review an Omnigent PR!
I asekd GPT 5.5 (in Codex), Opus 4.8 (in Claude Code), and GLM 5.2 (in OpenCode) to "launch a swarm of agents to review PR #102 for me"
GLM price assumes no cache. Crazy that we have on par quality w fewer tokens and ~1/6 cost ๐คฏ -
Matei Zaharia
@matei_zaharia
Nice overview and tutorial on Omnigent: www.youtube.com/watch?v=oGE_Dwz-rMk
-
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
After using GLM-5.2 for a day, Iโm surprised by how often it feels close to Opus 4.8/GPT-5.5 level.
I compared it side by side with Opus 4.8, and sometimes I even preferred GLM-5.2โs results.
OSS LLMs are impressive, especially given how many fewer GPUs they were trained on. -
Matei Zaharia
@matei_zaharia
We just released Omnigent 0.2 with a ton of improvements from the past 5 days! Here's what's new according to Omnigent. Major additions are @cursor_ai CLI and @antigravity harnesses, lots of new sandbox providers, and secret-free sandboxing via API proxy. github.com/omnigent-ai/omnigent/releases/tag/v0.2.0
-
Matei Zaharia reposted
Shicheng Liu
@ShichengGLiu
Still canโt believe this journey: we went from 2nd place to 1st literally in the LAST 1 MINUTE. It felt like I was playing the โAgent World Cupโ myself, proudly representing @StanfordOVAL and @stanfordnlp.
Huge shoutout to my amazing teammates @harshitj__ @SunJiuding @PriyankShethia - couldnโt have asked for a better team. Big thanks as well to our mentor Lucas from @AnthropicAI for guiding us along the way.
And huge thanks to the @databricks team and the OfficeQA team - including amazing people like @kristahopsalong, @arnav_thebigman, @bemikelive, and @matei_zaharia - for putting together such an incredible competition. What an unforgettable experience! ๐
More lessons learned from building our agent coming soon. Stay tuned.
Databricks
@databricks
Stanford University is the 2026 Databricks Grounded Reasoning Cup champion! ๐
The inaugural Grounded Reasoning Cup at #dataaisummit 2026 is in the books, with Stanford taking 1st, UMass Amherst earning 2nd, and Yale University securing 3rd after six high-intensity rounds of live AI agent competition over 200+ years of U.S. Treasury data.
Teams mentored by @AnthropicAI, @OpenAI, and @GoogleDeepMind built agents that tackled messy historical PDFs, multimodal chart interpretation, and web-augmented reasoning on real government data.
Thank you to @USAFacts, the U.S. Treasury, our student teams from 11 universities, and everyone who joined live. -
Matei Zaharia
@matei_zaharia
Congrats to the Stanford team! This was super fun, perhaps the only *live* AI competition with humans and agents working together to attempt the next gen OfficeQA benchmark. So many cool approaches and lessons from these teams.
Databricks
@databricks
Stanford University is the 2026 Databricks Grounded Reasoning Cup champion! ๐
The inaugural Grounded Reasoning Cup at #dataaisummit 2026 is in the books, with Stanford taking 1st, UMass Amherst earning 2nd, and Yale University securing 3rd after six high-intensity rounds of live AI agent competition over 200+ years of U.S. Treasury data.
Teams mentored by @AnthropicAI, @OpenAI, and @GoogleDeepMind built agents that tackled messy historical PDFs, multimodal chart interpretation, and web-augmented reasoning on real government data.
Thank you to @USAFacts, the U.S. Treasury, our student teams from 11 universities, and everyone who joined live.
Matei Zaharia
@matei_zaharia
Specifically the team was @ShichengGLiu, @harshitj__ @SunJiuding and @PriyankShethia from @StanfordOVAL and @stanfordnlp! Congrats!
-
Matei Zaharia reposted
Databricks
@databricks
Announcing OpenSharing SecureConnect to simplify networking configuration for data sharing
OpenSharing introduces a Databricks-managed proxy for storage access. Providers configure storage access once, making it easier to onboard new recipients without the firewall changes and network coordination that often slow down data sharing.
Optionally, data providers can use NCC for SecureConnect to access provider storage over private connectivity.
Now in Public Preview. www.databricks.com/blog/introducing-opensharing-secureconโฆ -
Matei Zaharia reposted
-
Matei Zaharia reposted
Gary Marcus
@GaryMarcus
yet another win for neurosymbolic systems!
Matei Zaharia
@matei_zaharia
Really cool research using AI-driven search (a GEPA-like method) to beat the state of the art in robotics. I think these type of neurosymbolic systems where AI generates an AI + code hybrid will be very effective. Seeing this in other applications too.
KD
@Reveur_7
What if a robot policy weren't a neural net or a test-time chat loop, but a multi-file code repo selected from a Pareto frontier of genetically evolved candidates? RHO moves all its LLM exploration to training time, then runs that repo on scenes it was never trained on. ๐งต๐๐ฝ
-
Matei Zaharia reposted
Databricks
@databricks
"Ali Ghodsi wants to rebuild the stack itself," writes @iamVictorDey for @Forbes.
For 40 years, every data stack has carried the same split: one set of systems to run the business, another to analyze it. The real bottleneck for agentic AI isn't model intelligence. It's that divide.
At #dataaisummit, we introduced LTAP (Lake Transactional/Analytical Processing): both transactional and analytical engines running on a single copy of data, in an open format. One data, zero compromises, zero copies.
It's built on Lakebase, our serverless Postgres database. Across the platform, agents now create roughly 80% of databases.
"Our primary user is already the agent," says Databricks co-founder and CEO @alighodsi.
Read the full story: www.forbes.com/sites/victordey/2026/06/16/databricks-ceo-โฆ -
Matei Zaharia reposted
Databricks
@databricks
.@rxin, Databricks Co-founder and Chief Architect and Jack Naglieri, Founder and CEO of @runpanther took the stage at #dataaisummit to discuss security built for the agentic era.
Panther delivers what legacy SIEMs can't: AI SOC agents that triage and investigate every alert, and broad data source coverage that captures the full spectrum of security telemetry. -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Announcing industry first cross cloud DR. Recovery branches are unique to @neondatabase architecture to preserve data history at failover.
-
Matei Zaharia
@matei_zaharia
Really cool research using AI-driven search (a GEPA-like method) to beat the state of the art in robotics. I think these type of neurosymbolic systems where AI generates an AI + code hybrid will be very effective. Seeing this in other applications too.
KD
@Reveur_7
What if a robot policy weren't a neural net or a test-time chat loop, but a multi-file code repo selected from a Pareto frontier of genetically evolved candidates? RHO moves all its LLM exploration to training time, then runs that repo on scenes it was never trained on. ๐งต๐๐ฝ
-
Matei Zaharia reposted
KD
@Reveur_7
What if a robot policy weren't a neural net or a test-time chat loop, but a multi-file code repo selected from a Pareto frontier of genetically evolved candidates? RHO moves all its LLM exploration to training time, then runs that repo on scenes it was never trained on. ๐งต๐๐ฝ
-
Matei Zaharia
@matei_zaharia
Flashy agent frameworks are cool, but control is one of the main things holding AI back today. This is the other big AI product I've been working on, with contextual security and cost governance and across agents, data and tools. Super excited to have these great launch partners!
Databricks
@databricks
As AI moves from experiments to production, governance has to cover more than models. Teams need to see how AI is used, control what agents can access, and guard against new threats.
At Data + AI Summit 2026, we're introducing the Unity AI Gateway partner ecosystem.
We're proud to welcome some of the most trusted names in AI security, identity, and observability: @alice_dot_io, @CrowdStrike, HiddenLayer, @Netskope, @openlayerco, @PaloAltoNtwks, @Zscaler, @Okta, @pingidentity, @saviynt, @NomaSecurity, @cyera_io and @ObsidianAudits.
Together, these partners help you govern AI consistently across providers and frameworks. www.databricks.com/blog/building-open-ecosystem-ai-governโฆ -
Matei Zaharia reposted
Databricks
@databricks
As AI moves from experiments to production, governance has to cover more than models. Teams need to see how AI is used, control what agents can access, and guard against new threats.
At Data + AI Summit 2026, we're introducing the Unity AI Gateway partner ecosystem.
We're proud to welcome some of the most trusted names in AI security, identity, and observability: @alice_dot_io, @CrowdStrike, HiddenLayer, @Netskope, @openlayerco, @PaloAltoNtwks, @Zscaler, @Okta, @pingidentity, @saviynt, @NomaSecurity, @cyera_io and @ObsidianAudits.
Together, these partners help you govern AI consistently across providers and frameworks. www.databricks.com/blog/building-open-ecosystem-ai-governโฆ -
Matei Zaharia reposted
Databricks
@databricks
We are excited to announce the next evolution of Agent Bricks as our agent platform.
Agent Bricks has expanded into a comprehensive platform for building agents with any model and any harness, accessing data anywhere, and confidently deploying and controlling agents in production.
Agent Bricks provides the building blocks developers need to build impactful agents, including secure sandboxes, agent memory, token capacity, and managed infrastructure.
The platform is open by design, supporting any model, any harness, and any data source. We also offer a managed version of Omnigent, our open source meta-harness, to orchestrate different harnesses.
We believe the future of agents requires data and AI on a single platform, making it easier to build and operate agents in production.
We can't wait to see what you build! www.databricks.com/blog/agent-bricks-dais-2026 -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
The future of coding is not one agent. It's a whole AI team.
Omnigent lets you run a team of agents in one live session: Claude Code, Codex, Cursor, Pi, and your own agents.
It is a meta-harness for AI agents, built from our internal Databricks dev tools, and now open-sourced for everyone.
Built by the legendary @matei_zaharia and the Databricks AI team. And yes, Matei still writes a lot of code, even the frontend code for Omnigent and our products. -
Matei Zaharia
@matei_zaharia
My Omnigent demo for @Data_AI_Summit literally writes itself.. get two agents to debate and hilarity ensues. Tune into the stream tomorrow morning!
-
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
First time delivering a keynote to 25000 people. Wild.
We delivered some incredible stuff:
- available on every cloud
- cross cloud disaster recovery
- LTAP. Query lakebase data directly from lake with new low latency analytical query engine
Best team Iโve ever worked with
Databricks
@databricks
โWe made a virtual C-suite. It serves small business owners by creating a suite of agents to help them manage cash flow, investments and more. Standardizing on Lakebase has been critical.โ
Fed Cohen Freue, EVP of AI & Data Operations at Mastercard, on how a unified infrastructure has helped accelerate solutions.
โWe are uncompromising in our approach to how to manage and govern our AI and data. Lakabase built that foundation from the start.โ -
Matei Zaharia
@matei_zaharia
You can now query your lakehouse data in real time at <10ms latency! Any table, just faster, at 12,000+ QPS, on the existing open data formats. Powered by what @rxin's team affectionally called Reynold's Dream Engine (Reyden).
Databricks
@databricks
Introducing Lakehouse//RT, a real-time data warehouse that delivers millisecond responses at massive scale without data movement.
Support real-time workloads while using the same open formats, governance, and data architecture already powering your analytics and AI. -
Matei Zaharia reposted
Databricks
@databricks
โHow do we truly unify transactional and analytical data?โ
@rxin announces LTAP - lake transactional-analytics process - a new data processing architecture that unifies OLAP and OLTP on a single copy of data in the lake, eliminating ETL, replicas, and pipelines by design. -
Matei Zaharia reposted
Databricks
@databricks
Weโre excited to announce that we have agreed to acquire @runpanther, a next-generation AI SOC platform. Panther delivers what legacy SIEMs can't: AI SOC agents that triage and investigate every alert, and broad data source coverage across the full spectrum of security telemetry. Panther accelerates our vision for agentic security operations.
Trusted by leading security teams โ including Anthropic โ Panther has proven it can defend the most demanding, AI-native environments.
Panther marks our third security acquisition as we double down to help organizations defend against increasingly sophisticated AI-driven attackers.
Together, weโll deliver agentic detection and response workflows on an open security lakehouse. This is security built for the agentic era. www.databricks.com/company/newsroom/press-releases/databrโฆ -
Matei Zaharia reposted
#DataAISummit
@Data_AI_Summit
Databricks Co-founder and Chief Architect @rxin at #dataaisummit, announcing Reyden: a breakthrough new engine for real-time workloads that require immediate responsiveness at high concurrency.
โThis is the single largest innovation weโve built since the introduction of Lakehouse.โ
www.databricks.com/dataaisummit/watch -
Matei Zaharia reposted
Tasso Argyros
@tasso
After months of intense building, I am super excited to launch CustomerLake today!
CustomerLake is Databricks' answer to how Customer Data & Marketing will evolve in the agentic world.
AdWeek sat down with @alighodsi and msyelf to dig into the details. Check it out below! -
Matei Zaharia reposted
Sabhya Chhabria
@sabhyac267
@antigravity coming asap as well!!
Matei Zaharia
@matei_zaharia
Omnigent getting @cursor_ai agent support soon. That was fast!
Sabhya Chhabria
@sabhyac267
@Mikeapedia1 -- we were able to add cursor-sdk as first party agent harness in Omnigent (github.com/omnigent-ai/omnigent/commit/88de81a4594500586dโฆ)
I'm trying to see how we can get cursor cli in as well! -
Matei Zaharia
@matei_zaharia
Omnigent getting @cursor_ai agent support soon. That was fast!
Sabhya Chhabria
@sabhyac267
@Mikeapedia1 -- we were able to add cursor-sdk as first party agent harness in Omnigent (github.com/omnigent-ai/omnigent/commit/88de81a4594500586dโฆ)
I'm trying to see how we can get cursor cli in as well! -
Matei Zaharia
@matei_zaharia
The #dataaisummit keynotes start tomorrow and this year is packed with very exciting launches in both AI and data. Check it out in person or online!
My own keynote on omnigent.ai will be Wednesday.
Databricks
@databricks
#dataaisummit 2026 is officially underway!
This week, thousands of data and AI leaders, engineers, analysts, architects, and builders are coming together in San Francisco to explore the future of apps and agents through keynotes, technical sessions, training, and hands-on experiences.
We'll be sharing announcements, highlights, and moments from across the event all week long.
Not in San Francisco? Join the virtual experience here: www.databricks.com/dataaisummit -
Matei Zaharia reposted
Parth Asawa
@pgasawa
The AI community seems to increasingly be heading towards a polarized world when discussing safety and consolidated power. I see this discourse as a false dichotomy, so @profjoeyg and I wrote an essay on how we need to change the conversation (link below).
-
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
-
Matei Zaharia reposted
Neon
@neondatabase
Onboarding begins now: Compute, Storage, AI Gateway. Access at ๐ neon.com/backend
- Compute: Long-running functions
- Storage: object storage that branches with your database
- AI Gateway: One API for all frontier and open-source models -
Matei Zaharia reposted
Neon
@neondatabase
Introducing ๐๐๐๐.๐๐ - infrastructure as code for Neon
โ Declare Neon services and provision them via CLI
โ Type-safe env vars
โ Program what new branches get: TTL, autoscaling, scale to zero -
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
This is super exciting - Iโve been using Omnigent at Databricks for a while, and today we open-sourced it.
Omnigent is a meta-agent for orchestrating a swarm of agents.
Why do we need this? The best results no longer come from a single model running in a single harness.
I used to run the same task with Codex and Claude Code, then pick the better one. But the obvious thing is to let them collaborate, debate, and converge on something better. Omnigent makes this smooth.
The other feature I love is real-time collaboration. You can invite people into an Omnigent session to watch, steer, and send commands.
Multi-agent, multi-human collaboration is the future.
Omnigent was built by @matei_zaharia and a very lean team in just 6 weeks, working every day out of a Databricks war room, truly amazing.
Databricks AI really feels like a startup.
Matei Zaharia
@matei_zaharia
Really excited to open source a new project: Omnigent, a meta-harness for AI agents.
It lets you build multi-agent coding and custom agents, sitting above Claude Code, Codex, Pi, and agent SDKs to let you compose them. It also adds live collaboration and rich control policies. -
Matei Zaharia
@matei_zaharia
Really excited to open source a new project: Omnigent, a meta-harness for AI agents.
It lets you build multi-agent coding and custom agents, sitting above Claude Code, Codex, Pi, and agent SDKs to let you compose them. It also adds live collaboration and rich control policies.Post not available here, view on X
Matei Zaharia
@matei_zaharia
Omnigent focuses on three problems above the level of a single harness: composition, collaboration and control. www.databricks.com/blog/introducing-omnigent-meta-harnessโฆ
For composition, it lets you create multi-agent teams with different harnesses or swap harness and model mid-session and mid-loop.
Matei Zaharia
@matei_zaharia
For collaboration, Omnigent adds a common UI above any agents, with native app, web and mobile UIs and live collaboration with teammates. No more copy-pasting text and screenshots between agents, Slack, and Docs all the time! You can even review code with the agent that wrote it.
Post not available here, view on X
Matei Zaharia
@matei_zaharia
Omnigent can be run on your laptop or deployed to @Docker, @Railway and @flydotio, and can run agents in the cloud on @modal and @daytonaio. It works with any LLM provider too (coding agents' subscriptions, @OpenRouter, @databricks, etc).
Matei Zaharia
@matei_zaharia
There's a lot more coming, e.g. meta-optimization with @gepa_ai and programmatic tool calling as in RLM and MemEx. Read more in our blog: www.databricks.com/blog/introducing-omnigent-meta-harnessโฆ or get started at omnigent.ai
-
Matei Zaharia reposted
Replit โ
@Replit
Replit and @databricks integration just leveled up.
Build apps where every user sees only what they should. Your HR analyst can build a full org view for the CEO without ever accessing the underlying data.
Public preview is open for sign up! Read more โ -
Matei Zaharia reposted
Liana
@lianapatel_
๐ Beyond excited to share we're releasing LOTUSPlan, a new API & optimizer for higher performance LLM-powered data processing, from our team at Berkeley & Stanford.
LOTUS now lets you write your LLM-based queries and optimize them for up to 2.4ร lower cost and 4.6ร higher accuracy for tasks like, agent trace analysis, LLM-judge evals, RAG, document extraction and deep research.
โจCheckout our our new blog: liana313.github.io/blog/lotusplan.html
๐งต -
Matei Zaharia reposted
Yichuan Wang
@YichuanM
The web was never meant to be flattened into text.
Yet most web RAG systems start by parsing HTML --- a complex and lossy process.
๐ฅ Introducing PixelRAG: the first RAG system that retrieves and reads 30M+ web pages as pixels.
Instead of extracting text, PixelRAG retrieves screenshots and lets a VLM read them directly.
PixelRAG not only preserves visual information, but also outperforms text-based RAG on text-only QA benchmarks by +18.1%.
Why?
(1) HTML-to-text conversion often discards layout, structure, tables, and other useful signals.
(2) We continued pretraining a VLM on web page screenshots and turned it into a surprisingly strong visual retriever.
(3) Recent VLMs are remarkably good at understanding web pages, often with better accuracy and token efficiency than text-only pipelines.
Takeaway: HTML parsing may be one of the biggest self-inflicted bottlenecks in web RAG.
Demo below ๐
Code: github.com/StarTrail-org/PixelRAG
Paper: github.com/StarTrail-org/PixelRAG/blob/main/assets/pixelrโฆ
Playground: pixelrag.ai -
Matei Zaharia
@matei_zaharia
Delta Sharing became one of the most popular ways to exchange data thanks to its open cross-platform nature. Weโve now expanded it to also support any Iceberg client and to share AI assets like agent skills and unstructured data. It needed a new name, so welcome OpenSharing!
Matei Zaharia
@matei_zaharia
OpenSharing is now becoming a top level project at the Linux foundation instead of a subproject of Delta Lake too. Read more about it here: www.databricks.com/company/newsroom/press-releases/databrโฆ
Matei Zaharia
@matei_zaharia
And get started at opensharing.io
-
Matei Zaharia reposted
Databricks
@databricks
.@AnthropicAI's Claude Fable 5 is now available on Databricks, governed by Unity AI Gateway, across AWS, Azure, and GCP!
Fable 5 sets a new state of the art on OfficeQA Pro at 57.9% and is designed for work that was previously too complex or too long-running to hand to an AI.
Databricks customers can build domain-specific agents on Fable 5 and deploy them as Databricks Apps with Lakebase-powered memory, enabling agents to maintain context across sessions.
Build your first long-running agent with Agent Bricks: www.databricks.com/blog/claude-fable-5-now-available-dataโฆ -
Matei Zaharia reposted
Parth Asawa
@pgasawa
Awesome to see folks using tasks from Continual Learning Bench to evaluate what aspects of continual learning can look like with models like Mythos/Fable!! I'm eager to push the frontier of training methods and evals here -- reach out if you want to chat about all things CL :')
Lance Martin
@RLanceMartin
-
Matei Zaharia
@matei_zaharia
Stay tuned!
Patrick Collison
@patrickc
I want some kind of LLM workflow tool.
โข Ability to manage a set of input files (Markdown or similar), plus other general-purpose context.
โข With real-time collaboration. (And maybe some concept of snapshots or VCS integration.)
โข And the ability to create/manage a inference workflows and a stored set of prompts.
โข Access to general-purpose coding agents (and not just chat models).
โขย Some concept of compiled outputs/inference results (which ideally can be shared externally).
Many projects have this feeling: "there is all this stuff, which I want to process/compute over in this iterated way, with some build artifacts being important/worth saving." GNU Autotools x Notion or something. Is anyone building this? -
Matei Zaharia
@matei_zaharia
Thereโs a ton of interest in custom model tuning as agents reach production and scale up. Here is how we made Databricks Knowledge Assistant 3x faster using our new Instructed Retriever model trained end-to-end to do parallel test-time compute. Itโs rolling out to customers now!
Databricks AI Research
@DbrxMosaicAI
Most agentic search systems get better by thinking longer: more tool calls, more reason-act loops, each step waiting on the last. Quality goes up, but so does latency.
Instructed-Retriever-1 takes a different route. Instead of scaling test-time compute sequentially, it scales it in parallel. One retrieval-specialized model fans the work out: it generates multiple query and filter formulations to widen recall, then reranks the merged evidence with a multi-pivot reranker to sharpen precision. Both stages run at once, so searching more broadly no longer means searching more slowly.
The result inside Knowledge Assistant: search time drops more than 3x and answer time 2x, with time to first token around two seconds, and no drop in quality (it matches Claude Sonnet 4.5 retrieval quality on KARLBench). For the people using it, that means far less waiting between question and answer, the freedom to ask more follow-ups, and more of the knowledge base actually surfaced. Rolling out to all customers now, with no reconfiguration.
Read how we did it: www.databricks.com/blog/3x-faster-search-parallel-test-tiโฆ -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
Most agentic search systems get better by thinking longer: more tool calls, more reason-act loops, each step waiting on the last. Quality goes up, but so does latency.
Instructed-Retriever-1 takes a different route. Instead of scaling test-time compute sequentially, it scales it in parallel. One retrieval-specialized model fans the work out: it generates multiple query and filter formulations to widen recall, then reranks the merged evidence with a multi-pivot reranker to sharpen precision. Both stages run at once, so searching more broadly no longer means searching more slowly.
The result inside Knowledge Assistant: search time drops more than 3x and answer time 2x, with time to first token around two seconds, and no drop in quality (it matches Claude Sonnet 4.5 retrieval quality on KARLBench). For the people using it, that means far less waiting between question and answer, the freedom to ask more follow-ups, and more of the knowledge base actually surfaced. Rolling out to all customers now, with no reconfiguration.
Read how we did it: www.databricks.com/blog/3x-faster-search-parallel-test-tiโฆ -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
Super excited to share that 2 of our papers got the Industry Spotlight at the ACM CAIS Conference!
optimize_anything: A Universal API for Optimizing any Text Parameter
Composing Policy Gradients and Prompt Optimization (mmGRPO)
Thanks to @CAISconf and @aiDotEngineer! -
Matei Zaharia
@matei_zaharia
This is going to be awesome, human plus AI teams competing in real time at @Data_AI_Summit to answer challenging questions. I think this is the first competition of this kind for LLM researchers.
Databricks
@databricks
Introducing the lab sponsors for the Databricks Grounded Reasoning Cup at #dataaisummit 2026: @AnthropicAI, @OpenAI, and @GoogleDeepMind.
Each lab is partnering with leading academic teams to build agents that tackle grounded reasoning over complex government data using the latest models and tooling.
Meet the teams, see the agents theyโre bringing to the competition, and join us as they push the boundaries of enterprise AI reasoning live on stage! ๐ -
Matei Zaharia reposted
Databricks
@databricks
๐ Weโve been busy shipping new features, and Nick Karpov and Holly Smith are here to break down the highlights in the latest episode of Over Architected.
Covered in this episode:
โข Multi-table transactions
โข Lakeflow Designer
โข AI functions for RAG workflows
โข Vector search improvements
โข AI governance updates
โข New agent capabilities across the platform
Watch the full walkthrough of whatโs new โ
www.youtube.com/watch?v=rPephv4WDlk -
Matei Zaharia reposted
Neon
@neondatabase
Big news: Neon is expanding to offer a more complete set of backend primitives for running apps and agents:
โ Database โ Authentication ๐ Storage ๐ Compute ๐ AI Gateway -
Matei Zaharia reposted
Databricks
@databricks
.@AnthropicAI's Claude Opus 4.8 is now available where your data already livesโgoverned, secure, and ready for custom AI applications and agents built on your lakehouse data.
In Genie, Opus 4.8 enables deeper multi-step reasoning across structured data and unstructured content in a single response. Teams can build agents that handle complex workflows with fewer iterations and lower cost, all governed through Unity Catalog.
Put Claude Opus 4.8 to work on your most important data securely and at production scale. docs.databricks.com/aws/en/release-notes/product/2026/may -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
How we build in a world where cloud limits are hit daily:
1. HA on both Compute and Storage
2. Hold control plane to same standards as data plane
3. Dependency minimalism
4. Control blast radius
5. Failure simulation
6. Measure everything
7. Build a world-class team with deep operating/scaling experience -
Matei Zaharia reposted
Alex Krentsel
@AlexKrentsel
Very excited about our workshop on AI Agents for Discovery in the Wild ๐พ๐ฆ๐ , happening *tomorrow*, Tuesday, May 26th 9am-5pm, as part of CAIS '26 in San Jose.
We were blown away by all of the excellent submissions we gotโฆ(1/n) -
Matei Zaharia reposted
Melissa Pan
@melissapan
Excited to share that MAP has been selected for โจICML Oralโจ
We look forward to sharing the insights in the paper with the community
And much much appreciations to everyone who participated in our study โค๏ธ MAP wonโt be possible without your contribution to open science
Melissa Pan
@melissapan
Excited to share: MAP has been accepted as ๐ ICML Spotlight ๐
We hope MAP can provide data-driven insights that help the communities to work on various under-explored research directions around agent systems!
Huge thanks & congrats to my amazing co-authors. See you all at Seoul! ๐ซก -
Matei Zaharia reposted
Databricks
@databricks
For decades, operational and analytical databases lived as separate systems because they had to.
This walkthrough explores what happens when Backstage, @Spotifyโs internal developer portal, runs on Databricks Lakebase instead of Postgres, testing how database branching changes the development cycle.
What changed:
โข Production database branches created in about 1 second
โข Point-in-time recovery completed in under 4 seconds
โข Developers testing schema changes against real data instead of mocks
www.databricks.com/blog/backstage-lakebase -
Matei Zaharia reposted
Apache Spark
@ApacheSpark
Apache Spark 4.1 is out today. ๐
AI data agents are now common in data engineering. They're also a real risk in production: tool sprawl and the glue code required to run real pipelines create a huge surface area for silent errors. The cost is wasted time and wasted compute on jobs you only notice are broken three hours into a four-hour run.
Three architectural changes in 4.1 shrink that surface area.
1๏ธโฃ Spark Declarative Pipelines (SDP)
2๏ธโฃ Real-Time Mode
3๏ธโฃ Spark Connect + Project Feather
Three architectural changes. One platform shape. Fewer surfaces for the agent to drift on. Less technical debt as you ship.
๐ Get started: spark.apache.org/downloads
#apachespark #dataengineering #oss #aiagents -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
Our paper on optimize_anything has been accepted to CAIS 2026, and is out on Arxiv with expanded experiments and details!
A unified API to optimize agents (with architecture), CUDA kernels, cloud scheduling policies, or even graphics!
Lakshya A Agrawal
@LakshyAAAgrawal
Excited to release @gepa_ai's optimize_anything: a universal API for optimizing any text parameter.
It consistently matches or outperforms domain-specific tools optimizing code, prompts, agent harnesses, cloud policies, even visuals!
If you can measure it, you can optimize it. -
Matei Zaharia reposted
Ashutosh Baheti
@abaheti95
In 1945, Vannevar Bush imagined a machine to extend a scientist's memory. He called it the MemEx.
80 years later, we built one for LLM agents.
Tool outputs become Python objects; only print statements reach the model's context.
๐งต www.databricks.com/blog/memex-programmable-scratchpad-llmโฆ -
Matei Zaharia reposted
Databricks
@databricks
Unity AI Gateway is expanding runtime AI governance with new Beta capabilities for AI agents and MCPs.
New in Beta
โข LLM guardrails to enforce customizable safety and compliance policies
โข Payload logging and service policies for MCPs to improve observability and control agent actions
โข Cost controls with per-user alerts and budget limits across models and providers
Organizations can now govern every model call and agent action with consistent policies, full observability, and enforceable cost controls in one unified layer.
Learn more: www.databricks.com/blog/whats-new-unity-ai-gateway-servicโฆ -
Matei Zaharia reposted
Databricks
@databricks
Google's Gemini 3.5 Flash is now available on Databricks!
@Google just released Gemini 3.5 Flash, and Databricks is among the first outside the Gemini Enterprise Agent Platform to offer it. Build and scale agentic AI applications on your enterprise data with the governance and operational tooling your teams need for production.
Congrats to the Google Gemini team on this release. We can't wait to see what you build with it! docs.databricks.com/aws/en/release-notes/product/2026/may -
Matei Zaharia reposted
Yichuan Wang
@YichuanM
LEANN just won the Best Paper Award at #mlsys26 ๐ฅน
still processing this.
paper: arxiv.org/abs/2506.08276
repo: github.com/yichuan-w/LEANN
huge thanks to all the amazing collaborators, advisors, and open-source contributors who made this possible โค๏ธ -
Matei Zaharia reposted
Freddie Vargus
@freddiev4
infinite token budget if you join our team at Databricks
Julia Neagu
@juliaaneagu
Iโm not making any promises but we can backstop the corporate card with @freddiev4โs personal one
-
Matei Zaharia
@matei_zaharia
This is a fantastic team. Check it out if you want to help build agents and models that reliably answer the most challenging analytical questions in biotech, finance, etc for our customers.
Julia Neagu
@juliaaneagu
I'm building a new team at @databricks AI Research and we're hiring.
We're focused on one of the hardest open problems in AI right now: how do you measure and continuously improve agents that operate on enterprise data at scale. We're looking for founding engineers to build the flywheel that turns evaluation results directly into better agents โ from development and training all the way to production.
If you want to work on problems that actually matter at the frontier of AI research, I'd love to talk.
Link in comments ๐ -
Matei Zaharia
@matei_zaharia
Really excited about this work that combines GEPA with RL! You get some of the advantages of both, with reflection on rich feedback leading to better weight updates.
Kusha Sareen
@KushaSareen
Can LLMs adapt continually without losing base skills?
Fast-Slow Training (FST) pairs "slow" weights with "fast" context.
FST vs. RL:
โข 3x more sample-efficient
โข Higher performance ceiling
โข Less KL drift (better plasticity)
โข Continual learning: succeeds where RL stalls -
Matei Zaharia reposted
Kusha Sareen
@KushaSareen
Can LLMs adapt continually without losing base skills?
Fast-Slow Training (FST) pairs "slow" weights with "fast" context.
FST vs. RL:
โข 3x more sample-efficient
โข Higher performance ceiling
โข Less KL drift (better plasticity)
โข Continual learning: succeeds where RL stalls -
Matei Zaharia reposted
ACM Conference on AI and Agentic Systems
@CAISconf
๐ค Keynote announcement:
@percyliang (Percy Liang), Professor of Computer Science at @Stanford, founding director of the Center for Research on Foundation Models, and co-founder of @togethercompute, is keynoting #cais2026.
Percy's HELM framework set the standard for holistic evaluation of language models, and his Foundation Model Transparency Index (now in its third year) put every major AI lab on notice for what they do and don't disclose. His current work on Marin takes this further: an open lab where every experiment, successful or not, is public from day one.
This one's going to be good.
San Jose ยท May 26โ29 caisconf.org -
Matei Zaharia reposted
Databricks
@databricks
.@gdb, President and Co-Founder of @OpenAI, will take the keynote stage with Databricks CEO @alighodsi to discuss the state of AI, whatโs next for agentic systems, and the OpenAI x Databricks partnership.
Attend Data + AI Summit in San Francisco to see it live: -
Matei Zaharia reposted
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
1/ Thrilled to introduce Tยณ: a corpus for RAG over reasoning tasks, built from thinking traces.
We show that surprisingly RAG can improve reasoningโ with the right corpus.
Rag with Transformed Thinking Traces Tยณ gain by up to 43.9% on AIME 2025-2026.
๐ arxiv.org/abs/2605.03344 ๐งต -
Matei Zaharia
@matei_zaharia
Cool work from the Databricks Model Serving team and Superhuman, to scale their custom LLM serving to 200K QPS with sub-second P99 latency! Here's how our teams got a +60% throughput gain vs the previous engine to serve over 40 million daily users. sprou.tt/1U9Jjq9glQl
-
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
There is a new era of data tech that is effectively "__ on object storage":
Turbopuffer is "vector search on object storage"
Warpstream is "kafka on object storage"
Neon is "Postgres on Object Storage" or โPostgres on S3โ.
It doesnโt mean that every read and write goes directly to S3. That would be incredibly slow. Iโm saying that a Postgres database in the "Postgres on object storage" category can be faster than one in the "Postgres on a cluster of servers with NVMe disks" category.
No one is claiming that S3 is faster than NVMe but Postgres on S3 (with low latency storage in between) can be faster than Postgres running on NVMe with HA on. HA is important here, without HA you donโt do durable writes so it would be an unfair comparison.
While neon runs on s3, calls into s3 are almost never on the transaction reads or writes. Writes are sent into a consensus service and streamed into s3 asynchronously. So the claim can be expanded to Postgres running on a disaggregated storage which implements low latency tier on top of s3 is faster then Postgres with HA running on NVMe.
We are not the only ones making this claim. For example AWS Aurora says "Aurora has 5x the throughput of MySQL and 3x of PostgreSQL with full PostgreSQL and MySQL compatibility."
So why does disaggregating compute allow for higher throughput on Postgres and potentially lower latency as well? The reason is that we can offload a number of CPU and IO operations down to storage. We just published a blog post on how we can turn off full page writes which dramatically reduces WAL volume and saves on CPU cycles on the Postgres node.
In many scenarios this may be a wash because for many workloads you might not be write throughout bound and therefore Postgres checkpoints and full page writes donโt impact overall throughput. However this is general purpose enough to impact a large swath of workloads. Itโs also important to mention that scaling write throughput is more important since Postgres is a single write system and you canโt scale writes with read replicas.
So is Postgres on S3 faster than Postgres on NVMe? We believe it can and will be. Postgres with disaggregated storage and several kernel performance optimizations has higher throughput than stock Postgres on NVMe with HA implemented via sync replication.
We'll share more including latency impact as we gather insights after rollout. Lots of things to learn here if saving CPU on full page writes can have a material impact on latency under high throughput. The idea is that if CPU is all used up, freeing up some CPU will impact both latency and throughput - but we'll see!
The statement is indeed provocative, but far from โshock value marketingโ as some of the responses claim. -
Matei Zaharia
@matei_zaharia
Genie has transformed how Databricks users work with data, with 3x the accuracy of generic agents. We're sharing some of the research behind it and what makes building data agents challenging. Super proud of our research team's impact with this! www.databricks.com/blog/pushing-frontier-data-agents-genie
-
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
There are some amazing performance database kernel folks at @databricks on the @neondatabase team
www.databricks.com/blog/how-lakebase-architecture-deliverโฆ -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Postgres on S3 is faster than Postgres on NVMe
-
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
An OpenAI friend told me he burns 300M GPT-5.5 tokens/day.
The top one in his team burns billions of tokens/day. Codex coding for them every night.
Databricks also gives engineers unlimited tokens.
We're looking for cracked inference engineers to join us at Databricks AI to produce trillions of tokens, insanely fast. DM me if you have:
- Contributed to open-source ML systems like SGLang/vLLM/PyTorch
- Experience serving LLMs at large scale
Databricks AI runs like a startup. Lots of exciting things to build! -
Matei Zaharia reposted
ACM Conference on AI and Agentic Systems
@CAISconf
๐ขKeynote announcement:
@andykonwinski (Andy Konwinski), co-founder of Databricks and Perplexity AI, founder of @LaudeInstitute, is keynoting #cais2026.
Laude's "Ship Your Research" mission funds open-source AI research through its Moonshots, Slingshots, and Open Frontier programs. Case in point: Terminal-Bench, a Laude-backed agent benchmark, reached Anthropic's Claude 4 model card 126 days after inception and has since become the industry-wide standard for measuring command line performance.
We're thrilled to have him.
San Jose ยท May 26โ29
caisconf.org -
Matei Zaharia reposted
Kasey Uhlenhuth
@kuhlenhuth
๐I'm back to building developer tools! Please help me better understand your siiick dev setups with coding agents or your frictions/pains by completing this 3-5min survey: forms.gle/gdn6vNCRpWfwFfSL9.
-
Matei Zaharia reposted
Omar Khattab
@lateinteraction
Wow, it's already May 5th. Don't miss the early-bird registration TODAY for the first ACM conference on AI systems @CAISconf.
CAIS will have a packed program of really exciting keynotes, paper presentations, workshops, and demos.
See you in San Jose in late May! -
Matei Zaharia reposted
Parth Asawa
@pgasawa
Today, weโre releasing Continual Learning Bench 1.0: the first, realistic benchmark for measuring how AI systems can improve in online settings.
Benchmarks today assume models are stateless. Each example is independent, and once a system finishes a task, it moves on as if nothing happened.
But deployed AI systems should learn from experience. We tested 10+ frontier systems against novel, expert-validated tasks and find thereโs still plenty of headroom for learning. (1/n) -
Matei Zaharia reposted
ACM Conference on AI and Agentic Systems
@CAISconf
๐ค Keynote announcement:
@trq212 (Thariq Shihipar), Member of Technical Staff on Claude Code at @AnthropicAI, is keynoting #cais2026.
Thariq's "Lessons from Building Claude Code" series on Skills, prompt caching, tool design, and "unhobbling" is required reading for anyone building agentic systems.
We're thrilled to have him.
๐ San Jose ยท May 26โ29
๐ caisconf.org -
Matei Zaharia reposted
KD
@Reveur_7
What if one person could run a unicorn company?
Today we're open-sourcing OMAR โ a TUI that lets a single engineer orchestrate hundreds of AI coding agents in deep, recursive hierarchies.
Built at Berkeley. Powered by tmux.
github.com/lsk567/omar ๐งต -
Matei Zaharia reposted
Databricks
@databricks
Big news: @stripe payments data is now available on Databricks Marketplace.
Activate the Stripe Data Pipeline in minutes, then query live payment data in Databricks to power models, agents and Genie workspaces
โข Deploy an agent that monitors transactions continuously
โข Combine transaction history with behavioral signals to score customers
โข Ask questions like "Show me MRR by geography" and get instant answers
No heavy ETL. Just governed, real-time access to the data that drives your business, and a feedback loop between payments and decision-making. www.databricks.com/blog/stripe-data-now-available-databriโฆ -
Matei Zaharia reposted
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
1/ "Can QPP Choose the Right Query Variant?" has been accepted at #sigir2026!๐ฆ๐บ
You can easily over-generate multiple query variants at low cost, but running RAG for all of them is expensive!
Can we pick the winner query before paying the generation cost?
arxiv.org/abs/2604.22661 -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
๐๐๐ง๐ข๐ is now the most important way to do data analysis in Databricks. What's unique about it is its ability to extract semantics from your entire Lakehouse, enabling it to answer complex data questions that cripple agents without a deep data understanding. We've now added a Mobile version, added Unstructured data processing, as well as enabled it to operate on all your dashboards and notebooks. Check it out:
www.databricks.com/blog/next-generation-databricks-genie -
Matei Zaharia
@matei_zaharia
GPT 5.5 and Codex are now available and manageable on Databricks! Both support Unity AI Gateway so you can manage access and costs, add guardrails, secure access to MCPs centrally, and audit usage. www.databricks.com/blog/openai-gpt-55-now-available-databโฆ
-
Matei Zaharia reposted
Databricks
@databricks
Databricks is excited to partner with @OpenAI on GPT-5.5, their latest frontier model. GPT-5.5 will be available in Unity AI Gateway on launch. You can use it with coding tools such as Codex, or to power your enterprise agents.
GPT-5.5 is state-of-the-art on many benchmarks including OfficeQA Pro, our benchmark for evaluating grounded reasoning on enterprise tasks.
We are partnering with OpenAI to co-launch on Databricks. Hear more from our co-founder @pwendell and OpenAI CRO @dhdresser on GPT-5.5 in Databricks. www.databricks.com/blog/databricks-partners-openai-gpt-55 -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
Thrilled to present GEPA as an Oral Talk and Poster at ICLR 2026 this Friday in Rio! ๐ง๐ท
Apr 24
Oral Session 3A (Agents), 10:30 AM BRT, Amphitheater
Poster Session 4, 3:15 PM, Pavilion 3
x.com/LakshyAAAgrawal/status/1949867947867984322
Let's recap what's happened since we released GEPA last year ๐งต
Lakshya A Agrawal
@LakshyAAAgrawal
How does prompt optimization compare to RL algos like GRPO?
GRPO needs 1000s of rollouts, but humans can learn from a few trialsโby reflecting on what worked & what didn't.
Meet GEPA: a reflective prompt optimizer that can outperform GRPO by up to 20% with 35x fewer rollouts!๐งต -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
What will the future of Spark and data engineering look like? How can you radically simplify it with AI? How do you ensure that the AI doesn't screw things up? How do you productionize all this so you can track reliability over time? This is exactly the problem that ๐๐๐ค๐๐๐ฅ๐จ๐ฐ ๐๐๐ฌ๐ข๐ ๐ง๐๐ซ solves, this is the future for data engineering! This is now available for all our customers (public preview)!
You tell the AI what transformations you want your data pipeline! (e.g. "join product data with the pricing table"). It shows you a GRAPH of the transformations which you can verify and approve yourself. Everything is behind the scenes represented by CODE which can be version controlled, productionized, in CI/CD. If you want to, you can review the code as well. Behind the scenes, the pipeline code is just open source ๐๐ฉ๐๐๐ก๐ ๐๐ฉ๐๐ซ๐ค ๐๐๐๐ฅ๐๐ซ๐๐ญ๐ข๐ฏ๐ ๐๐ข๐ฉ๐๐ฅ๐ข๐ง๐๐ฌ (๐๐๐)! Check it out.
www.databricks.com/blog/announcing-public-preview-lakefloโฆ -
Matei Zaharia reposted
ACM Conference on AI and Agentic Systems
@CAISconf
๐๐๐
www.caisconf.org/program/2026/papers/
CAIS's 2026 accepted papers!
61 accepted papers, from 110+ organizations globally
Papers come equally from industry and academia -
Matei Zaharia reposted
Sanjay Adhikesaven
@sadhikesaven
Imagine you fully post-trained "YourModel v1". Then, you've got better data โ math, code, tool use, safety โ and you want to improve it.
Today, that usually means retraining the whole model.
But what if new data could be added modularly, with a fixed cost each time? -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Just got this internal email on Genie Code progress! For the first time, we have MORE code written by Genie Code than by humans on the platform.
-
Matei Zaharia reposted
Yuchen Jin
@Yuchenj_UW
Life update: I joined Databricks this week!
I thought Iโd do another startup after Hyperbolic, but I was surprised by how startup-y Databricks AI is.
@alighodsi, @pwendell, @matei_zaharia are in full founder mode. Theyโre the best founders Iโve met. I like working with people who arenโt โnormalโ and they definitely arenโt. For example, they invited me to an all-hands before I joined.
Iโm also impressed by how many former founders are here. @akhilgupta and @hanlintang are incredible leaders.
A big bonus: I finally have unlimited Claude Code & Codex tokens!
AI adoption on the Databricks AI team is insanely high. Every engineer Iโve met uses AI heavily and shares their own ways to drive agents. Many talented people here.
Iโm super pumped for this new journey! -
Matei Zaharia
@matei_zaharia
Welcome Yuchen, super excited about what our AI team is building!
Yuchen Jin
@Yuchenj_UW
Life update: I joined Databricks this week!
I thought Iโd do another startup after Hyperbolic, but I was surprised by how startup-y Databricks AI is.
@alighodsi, @pwendell, @matei_zaharia are in full founder mode. Theyโre the best founders Iโve met. I like working with people who arenโt โnormalโ and they definitely arenโt. For example, they invited me to an all-hands before I joined.
Iโm also impressed by how many former founders are here. @akhilgupta and @hanlintang are incredible leaders.
A big bonus: I finally have unlimited Claude Code & Codex tokens!
AI adoption on the Databricks AI team is insanely high. Every engineer Iโve met uses AI heavily and shares their own ways to drive agents. Many talented people here.
Iโm super pumped for this new journey! -
Matei Zaharia
@matei_zaharia
Super excited to have Neon in the Codex marketplace for a great Postgres hosting experience!
Neon
@neondatabase
Codex just released a big update! Codex for almost everything - including for Neon!
This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Databricks
@databricks
Introducing Databricks Document Intelligence: a research-specialized layer that turns raw enterprise documents into structured data your agents can actually reason over.
Across our benchmarks, Document Intelligence delivered the highest end-to-end parsing and extraction quality at 6-8x lower cost, with a 16% average performance gain across every agent framework tested, just from better parsing.
How to get started: www.databricks.com/blog/why-frontier-agents-cant-read-docโฆ -
Matei Zaharia
@matei_zaharia
Securing agents is one of the main bottlenecks to adoption. With Unity AI Gateway, we're making it easy to secure your agents, tools and data they access in one place. It's super easy to plug into existing agents as just an MCP and LLM proxy.
Databricks
@databricks
AI Gateway in Databricks now extends Unity Catalog governance to agentic AI.
As agents call LLMs, pull data through MCP servers, and invoke external APIs, every step touches sensitive data and audit requirements. With the latest updates to AI Gateway, you can now bring all of that into one governance model:
โข Set access policies once across every LLM and tool
โข Trace the full agent call chain end-to-end
โข Centralize logging for FinOps, engineering, and security
www.databricks.com/blog/ai-gateway-governance-layer-agentโฆ -
Matei Zaharia reposted
MLflow
@MLflow
Reviewing logs one by one doesn't scale. MLflow 3.11.1 introduces ๐๐๐๐ผ๐บ๐ฎ๐๐ถ๐ฐ ๐๐๐๐๐ฒ ๐๐ฒ๐๐ฒ๐ฐ๐๐ถ๐ผ๐ป, turning hours of manual triage into just three clicks. ๐
This feature moves teams from reactive debugging to proactive quality identification by analyzing existing traces to find conversations where users got frustrated or agents returned misleading answers.
The ๐๐๐๐๐ฅ๐ฆ Framework: MLflow organizes detection across six quality dimensions:
๐น Correctness: Accuracy of the output.
๐น Latency: Performance bottlenecks.
๐น Execution: Technical failures or tool calling errors.
๐น Adherence: Following system instructions.
๐น Relevance: Alignment with user intent.
๐น Safety: Guardrail violations and risk detection.
Read the full technical breakdown ๐ mlflow.org/blog/issue-detection
#mlflow #llmops #generativeai #issuedetection -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
Most enterprise questions don't live in one dataset. They span structured systems and unstructured sources like documents, reviews, and reports.
In our latest research, we show how Agent Bricks Supervisor Agent handles this by decomposing queries across structured and unstructured tools, then synthesizing results over multiple reasoning steps.
The results across STaRK and KARLBench: 20%+ improvement over SoTA baselines, with the biggest gains on tasks requiring tight integration of structured and unstructured data.
All built declaratively โ no custom code, just precise instructions and the right tools. www.databricks.com/blog/agentic-reasoning-practice-makingโฆ -
Matei Zaharia reposted
Alex Dimakis
@AlexGDimakis
Check our new cool workshop for Agents, Discovery and Optimization: CAIS AI Agents for Discovery in the Wild. We have a pretty good speaker lineup. Submit your papers by: May 1st. (1/2)
-
Matei Zaharia reposted
Databricks
@databricks
Making Data and AI @Lovable.
Lovable now integrates with Databricks, providing a natural language interface that allows anyoneโregardless of technical skillsโto build live data apps can read and write data stored in Databricks.
Bridge the gap between complex data engineering and beautiful, functional front-ends. www.databricks.com/blog/lovable-databricks-build-data-driโฆ -
Matei Zaharia reposted
Amjad Masad
@amasad
Replit now deploys directly to Databricks.
Your apps run inside your Databricks environment while inheriting its security, governance, and data access.
Beta is live. Enterprises are already building with it and seeing massive acceleration in BI and internal tools. -
Matei Zaharia
@matei_zaharia
Registration is open for the CAIS conference! We have some awesome workshops and papers in the program.
ACM Conference on AI and Agentic Systems
@CAISconf
Registration for ACM CAIS 2026 is open.
May 26โ29 ยท San Jose, CA
Four days on AI and agentic systems, with a full workshop day on the 26th.
Early-bird pricing runs through May 5. Lock it in:
www.caisconf.org/pages/registration/ -
Matei Zaharia
@matei_zaharia
As AI reasoning gets good enough, we think memory will be the next bottleneck for agents. Can your agent improve with more experience?
We call this Memory Scaling, and it's related but different from continual learning. A few examples and challenges:
www.databricks.com/blog/memory-scaling-ai-agents
Matei Zaharia
@matei_zaharia
One cool finding: an agent that could retrieve memories from uncurated usage logs beat hand-crafted domain instructions after just 62 records. Memory scaling can help your agent learn for the true target task instead of relying on manual tuning or training on OOD data.
-
Matei Zaharia
@matei_zaharia
Definitely a surprise! It wouldn't have been possible without my awesome collaborators and students.
Databricks
@databricks
We're incredibly proud to congratulate our co-founder and CTO, @matei_zaharia, on receiving the ACM Prize in Computing for his development of distributed data systems that have enabled large-scale machine learning, analytics, and AI.
Matei's open-source contributions have fundamentally changed how organizations work with data and AI โ including Apache Sparkโข, Delta Lake, and MLflow. Researchers, nonprofits, startups, and enterprises across every industry have built on the foundation he helped create.
Now he's pushing the frontier further, focusing on building and scaling reliable AI agents through open-source research like DSPy and GEPA.
Matei, this recognition is so well deserved. We're honored to build alongside you every day. awards.acm.org/about/2025-acm-prize -
Matei Zaharia reposted
TechCrunch
@TechCrunch
Databricks co-founder wins prestigious ACM award, says โAGI is here alreadyโ techcrunch.com/2026/04/08/databricks-matei-zaharia-wins-aโฆ
-
Matei Zaharia reposted
Tiernan Ray
@TiernanRayTech
I had a fascinating conversion this week with a computing pioneer, Matei Zaharia, the CTO of Databricks, who is the recipient of this yearโs ACM Prize in Computing, a kind of genius award, in part because of his development of the Spark open-source software. Out chat confirmed my sense that there is a lot of fundamental R&D to be done to make โagenticโ AI work, but also that Zaharia has some very promising ideas on how to fix things.
Databricksโs resident genius sees AI agents living โGroundhog Dayโ
Matei Zaharia, co-founder and CTO of database giant Databricks, says todayโs agentic AI technology is in a kind of โGroundhog Dayโ scenario, where it must constantly relearn. Solving that problem could make Databricks one of the most important companies in AI.
โDid the agent double-check all the things that might be wrong? Did it make assumptions, and, inasmuch as you could even say that it's making an assumption, did it get confused somehow?โ
www.thetechnologyletter.com
@databricks
@matei_zaharia -
Matei Zaharia reposted
Shu Lynn Liu
@shulynnliu
๐ข Excited to announce the Call for Papers for our ACM CAIS 2026 workshop: AI Agents for Discovery in the Wild
๐ We want to bring together researchers and practitioners building autonomous AI systems that search, optimize, and discover, and tackle the hard problems of moving from benchmarks to the real world!
๐ ai-discovery-in-the-wild.github.io
๐งต๐ -
Matei Zaharia reposted
AI-Driven Research for Systems
@ai4research_ucb
๐ฏ One Year of AI-Driven Research at Berkeley
[ADRS Blog #20] For the past year at Berkeley, we have been working on automating discovery with AI. In our blog post this week, we provide an overview of these efforts: the key problems weโre tackling, the frameworks and solutions weโve built so far, and how these efforts fit into a broader vision for AI-driven scientific discovery.
โ๏ธ Read the blog: ucbskyadrs.github.io/blog/berkeley-ai-driven-research/
๐ ADRS Blog Series: ucbskyadrs.github.io -
Matei Zaharia
@matei_zaharia
We're running an AI research competition with $100K in prizes at Data+AI Summit! University teams can work with frontier models to solve questions in an unreleased OfficeQA-like dataset, covering reasoning over complex documents. It will be a live event with an audience! ๐
Databricks AI Research
@DbrxMosaicAI
Applications are officially open for the Grounded Reasoning Cup at Data + AI Summit 2026! ๐
Weโre looking for students who want to:
- Tackle highโimpact enterprise challenges
- Showcase work to top researchers/engineers (with recruiters in the room)
- Compete for $100k in model credit prizes
Apply here: forms.gle/ijdHDbAJFZpFLi1b7
Competition overview: docs.google.com/document/d/19owtX7-ELUoMRMN_HlgLq2B9Rbx0Cโฆ
Matei Zaharia
@matei_zaharia
The competition details are available at docs.google.com/document/d/19owtX7-ELUoMRMN_HlgLq2B9Rbx0Cโฆ. Sign up at docs.google.com/forms/d/e/1FAIpQLSdbwc5eN68SsuU80TlNfHxkJโฆ
-
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Agentic coding changes infrastructure requirements. This what is means for databases.
Every service will have these capabilities over time.
www.databricks.com/blog/how-agentic-software-development-โฆ -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
Applications are officially open for the Grounded Reasoning Cup at Data + AI Summit 2026! ๐
Weโre looking for students who want to:
- Tackle highโimpact enterprise challenges
- Showcase work to top researchers/engineers (with recruiters in the room)
- Compete for $100k in model credit prizes
Apply here: forms.gle/ijdHDbAJFZpFLi1b7
Competition overview: docs.google.com/document/d/19owtX7-ELUoMRMN_HlgLq2B9Rbx0Cโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
@JeffDean says it best, the problem in this new agentic era is "tools designed for human speed interaction". That's why we think agents love ๐๐ฎ๐ธ๐ฒ๐ฏ๐ฎ๐๐ฒ ๐ฃ๐ผ๐๐๐ด๐ฟ๐ฒ๐, it can branch, snapshot, scale up and down in a second, orders of magnitude faster than other databases.
www.youtube.com/watch?v=joTYgvRHST0&t=1824s
Read about this architectural shift from Database to Lakebase:
www.databricks.com/blog/what-is-a-lakebase -
Matei Zaharia reposted
Databricks
@databricks
Planned maintenance causes more database disruption than actual hardware failures.
Most databases get patched far more often than they experience outages, but every patch means a maintenance window, severed connections, and a cold cache that tanks performance for minutes after restart.
Weโre changing that. This is Part 1 of our series on eliminating the impact of planned maintenance entirely, rolling out automatically over the next few weeks. www.databricks.com/blog/zero-downtime-patching-lakebase-pโฆ -
Matei Zaharia reposted
lingjiao chen
@ChenLingjiao
๐จ Are lower-priced AI models really cheaper? Beware of the "Price Reversal" phenomenon in Reasoning Language Models (RLMs)! ๐ธ
We evaluated frontier RLMs and found sth shocking: a model with lower API pricing can actually cost more! ๐งต๐ -
Matei Zaharia
@matei_zaharia
We've lots of time building agents at Databricks, and developed this coSTAR pattern for it. It works even better with better models and keeps your agent hill-climbing on the hardest tasks from users without regressing. And it's super easy in @MLflowOSS. www.databricks.com/blog/costar-how-we-ship-ai-agents-dataโฆ
-
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
We believe security needs to be open and agent-centric. ๐๐๐ค๐๐ฐ๐๐ญ๐๐ก is built directly on the open data lakehouse pattern. By bringing agentic automation directly to where your open data already lives, we're automating the heavy lifting in the Security Operations Center. As a result, you keep ownership of your data, your agents can operate on absolutely everything, and you get it done in a architecturally cost efficient way.
www.databricks.com/blog/databricks-announces-lakewatch-neโฆ -
Matei Zaharia reposted
Databricks
@databricks
Today weโre announcing Lakewatch โ a new open, agentic SIEM.
Security has changed. Attackers now use agents, operating 24/7 at machine scale, while legacy security tools were built for human-speed threats. We need tools where agents work alongside humans to keep up.
Lakewatch brings a new architecture for this agentic era:
โข Ingest and store all enterprise data, including multimodal sources
โข Analyze it alongside business data with full governance
โข Use AI agents to automate detection, investigation, and response
Security requires a fundamental platform shift. This is how teams can fight agents with agents.
www.databricks.com/blog/databricks-announces-lakewatch-neโฆ -
Matei Zaharia reposted
Databricks
@databricks
Today at #nvidiagtc, weโre introducing AI Runtime, with serverless NVIDIA A10 and H100 GPUs now available on Databricks for training and fine-tuning.
GPU infrastructure has been one of the biggest blockers for teams building advanced AI, from long procurement cycles to complex distributed setups and data bottlenecks. AI Runtime removes that friction:
- On-demand GPUs with no cluster management
- Optimized distributed training with key frameworks pre-installed
- Native integration with Lakeflow, MLflow, and Unity Catalog
With AI Runtime, teams can focus on building and shipping models, not managing infrastructure. www.databricks.com/blog/introducing-ai-runtime-scalable-sโฆ -
Matei Zaharia
@matei_zaharia
Customers are getting some amazing performance with Apache Spark Real-Time Mode! Try it out, just turn a SQL or DataFrame query to a streaming job! This was our-term vision for streaming of Spark since we first designed the API over Spark SQL, and itโs great to see it in action.
Databricks
@databricks
Real-Time Mode for Apache Spark Structured Streaming on Databricks is now generally available.
For ultra-low latency workloads, teams have historically needed to run separate, specialized engines like Apache Flink alongside Spark, duplicating codebases, governance, and operational overhead. RTM eliminates that by bringing millisecond-level latency to the Spark APIs you already use.
Industry-leading companies are already seeing results:
- @coinbase cut end-to-end latency by 80%+ while computing 250+ ML features on a unified Spark engine
- @DraftKings rebuilt fraud detection pipelines for live sports betting with latencies that weren't previously possible
- @makemytrip hit sub-50ms P50 latencies and saw a 7% lift in click-through rates
If you're already on Structured Streaming, a single config update is all it takes to get started. www.databricks.com/blog/announcing-general-availability-rโฆ -
Matei Zaharia reposted
Databricks
@databricks
GPT-5.4 Mini and GPT-5.4 Nano are available on Databricks today.
Both models run on your enterprise data with the governance and operational tooling teams need for production. GPT-5.4 Mini brings meaningful gains over GPT-5 Mini in coding, reasoning, multimodal understanding, and tool use, at more than 2x the speed.
GPT-5.4 Nano is the smallest and most cost-efficient option in the GPT-5.4 family, built for classification, data extraction, ranking, and simpler coding subagents.
Congrats to the @OpenAI team. Looking forward to seeing what our customers build! docs.databricks.com/aws/en/release-notes/product/2026/march -
Matei Zaharia
@matei_zaharia
Cool use case of DSPy! This is well supported in @MLflow and @databricks too using the DSPy and human evaluation interfaces.
-
Matei Zaharia reposted
Koushik Sen
@koushik77
Embrace the future that is coming for systems research. We are doing "meta-metalevel research" ...
Shu Lynn Liu
@shulynnliu
Researchers spend hours and hours hand-crafting the strategies behind LLM-driven optimization systems like AlphaEvolve: deciding which ideas to reuse, when to explore vs exploit, and what mutations to try.
๐คBut what if AI could evolve its own evolution process?
We introduce EvoX, a meta-evolution pipeline that lets AI evolve the strategy guiding the optimization. It achieves high-quality solutions for <$5, while existing open systems and even Claude Code often cost 3-5ร more on some tasks.
Across ~200 optimization problems, EvoX delivers the strongest overall results: often outperforming AlphaEvolve, OpenEvolve, GEPA, and ShinkaEvolve on math and systems tasks, exceeding human SOTA, and improving median performance by up to 61% on 172 competitive programming problems. ๐ -
Matei Zaharia reposted
Shu Lynn Liu
@shulynnliu
Researchers spend hours and hours hand-crafting the strategies behind LLM-driven optimization systems like AlphaEvolve: deciding which ideas to reuse, when to explore vs exploit, and what mutations to try.
๐คBut what if AI could evolve its own evolution process?
We introduce EvoX, a meta-evolution pipeline that lets AI evolve the strategy guiding the optimization. It achieves high-quality solutions for <$5, while existing open systems and even Claude Code often cost 3-5ร more on some tasks.
Across ~200 optimization problems, EvoX delivers the strongest overall results: often outperforming AlphaEvolve, OpenEvolve, GEPA, and ShinkaEvolve on math and systems tasks, exceeding human SOTA, and improving median performance by up to 61% on 172 competitive programming problems. ๐ -
Matei Zaharia reposted
MLflow
@MLflow
Starting in ๐ ๐๐ณ๐น๐ผ๐ ๐ฏ.๐ญ๐ฌ.๐ฌ, you can now use Guardrails AI validators as native, deterministic GenAI scorers! ๐
The TL;DR:
โ ๐๐ฒ๐๐ฒ๐ฟ๐บ๐ถ๐ป๐ถ๐๐๐ถ๐ฐ & ๐ฅ๐ฒ๐ฝ๐ฒ๐ฎ๐๐ฎ๐ฏ๐น๐ฒ: No more non-deterministic "judges" for PII or Secrets.
โ ๐ก๐ฎ๐๐ถ๐๐ฒ ๐ช๐ผ๐ฟ๐ธ๐ณ๐น๐ผ๐: Use ๐๐๐๐๐๐ .๐๐๐๐๐.๐๐๐๐๐๐๐๐() with the new ๐๐๐๐๐๐๐๐๐๐ scorer provider.
โ ๐๐/๐๐ ๐ฅ๐ฒ๐ฎ๐ฑ๐: Automated pass/fail gates for your LLM outputs.
Read the full technical breakdown here โก๏ธ guardrailsai.com/blog/guardrails-mlflow
#llmops #genai #mlflow #guardrailsai #llm -
Matei Zaharia reposted
Databricks
@databricks
Push 10+ GB/sec to your lakehouse in under 5 seconds.
With Zerobus Ingest, stream data directly into your lakehouse โ no message bus required.
Less infrastructure to manage, lower costs, and faster access to real-time data.
Key capabilities:
โข Sub-5-second latency for thousands of concurrent connections
โข Supports over 10 GB/sec aggregate throughput to a single table
โข Includes gRPC and REST APIs, plus SDKs for Python, Java, Rust, Go, and Typescript
โข Built-in governance with Unity Catalog
Now generally available:
www.databricks.com/blog/announcing-general-availability-zโฆ -
Matei Zaharia reposted
Haocheng Xi
@HaochengXiUCB
๐-๐บ๐ฒ๐ฎ๐ป๐ ๐ถ๐ ๐๐ถ๐บ๐ฝ๐น๐ฒ. ๐ ๐ฎ๐ธ๐ถ๐ป๐ด ๐ถ๐ ๐ณ๐ฎ๐๐ ๐ผ๐ป ๐๐ฃ๐จ๐ ๐ถ๐๐ปโ๐.
Thatโs why we built Flash-KMeans โ an IO-aware implementation of exact k-means that rethinks the algorithm around modern GPU bottlenecks.
By attacking the memory bottlenecks directly, Flash-KMeans achieves 30x speedup over cuML and 200x speedup over FAISS โ with the same exact algorithm, just engineered for todayโs hardware. At the million-scale, Flash-KMeans can complete a k-means iteration in milliseconds.
A classic algorithm โ redesigned for modern GPUs.
Paper: arxiv.org/abs/2603.09229
Code: github.com/svg-project/flash-kmeans -
Matei Zaharia reposted
Databricks
@databricks
Most critical enterprise data doesn't live in organized column and rows. It's unstructured โ PDFs, reports, and diagrams. Extracting insights historically meant rules-heavy OCR pipelines that break the changes.
@Alex_TheAnalyst walks through how document processing in Databricks replaces all of that with AI-powered extraction that's flexible, accurate, and easy to maintain.
Watch the full walkthrough: youtu.be/ItzSyfNEptk -
Matei Zaharia reposted
Databricks
@databricks
Data + AI Summit is where data, dev and AI teams go to level up.
Whether you're building AI agents, scaling real-time pipelines, or trying to get more projects out of pilot and into production, the 2026 agenda is built for the practitioners doing the actual work.
800+ hands-on sessions and deep technical dives across:
- App Development
- AI/ML & Agents
- Analytics & BI
- Data Engineering & Streaming
- Data Sharing & Collaboration
- Data Warehousing
- Governance & Security
Register today to take advantage of early-bird pricing: www.databricks.com/dataaisummit -
Matei Zaharia reposted
Databricks
@databricks
Databricks CEO and co-founder @alighodsi joined @technology to discuss the launch of Genie Code, an autonomous AI agent built specifically for data teams.
"Just six months ago, we were talking about autocompleting code โ now agents automate the code. The new question is: how do we take the code thatโs been written into production and make sure we're monitoring it?"
Watch the full conversationThis media couldn't be displayed. See it on the original post. -
Matei Zaharia
@matei_zaharia
Iโm super excited about the launch of Genie Code! It extends the power of AI coding to agentic data work, answering questions 2-3x more accurately than coding agents and automatically engineering and monitoring high quality pipelines. Itโs transformed my own work at Databricks!
Databricks
@databricks
Today we're announcing Genie Code, your autonomous AI partner for data.
Genie Code is a state-of-the-art agent that lets data teams move from prompting a copilot to delegating real work: building pipelines, machine learning models, debugging failures, and shipping dashboards.
This isn't a smarter autocomplete. It's a different kind of AI partner entirely.
Unlike general coding agents that stop once the code is built, Genie Code plans, executes, and iterates across the full data and AI lifecycle inside Databricks. It's purpose-built for data engineering, data science, and BI:
โข More than doubles the success rate of leading coding agents on real-world data science tasks
โข Proactively monitors your pipelines and AI models in the background, triaging failures and fixing issues before a human intervenes
โข Works with your data wherever it lives, across Databricks and external platforms, with full governance and MCP support
This is what the future of data work looks like. www.databricks.com/blog/introducing-genie-code
Matei Zaharia
@matei_zaharia
Basically, with Genie Code, I can find out about datasets I didnโt even know existed for a business question, do anything from simple questions to multi-page what-if forecasts, and productionize or turn it into a regular monitored task.
-
Matei Zaharia reposted
Databricks
@databricks
Databricks is acquiring Quotient AI to strengthen the agent evaluation and reinforcement learning capabilities in Genie, Genie Code, and Agent Bricks so customers get more reliable AI agents in production.
Databricks already provides powerful tools for evaluating and improving AI agents. With Quotient, we're strengthening these capabilities across our platform with a continuous evaluation and improvement layer that monitors agent behavior in production, catches issues like hallucinations and broken reasoning before users do, and uses those signals to continuously improve performance over time.
We're excited to welcome the Quotient AI team to Databricks as we continue building the most reliable platform for developing, deploying, and improving agentic systems at scale! www.databricks.com/blog/databricks-acquires-quotient-ai-pโฆ -
Matei Zaharia reposted
Michael Bendersky
@bemikelive
We just published OfficeQA Pro - a set of 133 challenging questions from the original OfficeQA benchmark. Even the best frontier agents still struggle on OfficeQA Pro with common issues stemming from errors in parsing, retrieval, and visual reasoning.
-
Matei Zaharia reposted
Krista Opsahl-Ong
@kristahopsalong
Most AI benchmarks test reasoning in isolation.
Real enterprise tasks require grounded reasoning:
1๏ธโฃ Find the right documents
2๏ธโฃ Extract the right values
3๏ธโฃ Perform analyses
OfficeQA Pro evaluates this end-to-end. Frontier agents still score <50%.
๐งตPaper & details below! -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
. @gepa_ai + @DSPyOSS used for agent self-evolution and skill optimization by @NousResearch @Teknium to get +39.5% gains!
Check out the full report to see how to build self-optimizing agents using GEPA. -
Matei Zaharia
@matei_zaharia
This is really cool: design your agent so that running out of context isnโt possible, and it can keep going indefinitely.
-
Matei Zaharia
@matei_zaharia
This is a great pattern to build your own specialized AI, described in our report.
- Generate synthetic data with current version of model
- Apply efficient large-batch off-policy RL (OAPL)
- Generate harder data with updated model
- Produce efficient, generalizable small model
Databricks AI Research
@DbrxMosaicAI
Meet KARL: a faster agent for enterprise knowledge, powered by custom reinforcement learning (now in preview).
Enterprise knowledge work isnโt just Q&A. Agents need to search for documents, find facts, cross-reference information, and reason over dozens or hundreds of steps.
KARL (Knowledge Agent via Reinforcement Learning) was built to handle this full spectrum of grounded reasoning tasks. The result: frontier-level performance on complex knowledge workloads at a fraction of the cost and latency of leading proprietary models.
These advances are already making their way into Agent Bricks, improving how knowledge agents reason over enterprise data.
And Databricks customers can apply the same reinforcement learning techniques used to train KARL to build custom agents for their own enterprise use cases.
Read the research โ www.databricks.com/sites/default/files/2026-03/karl.pdf
Blog: www.databricks.com/blog/meet-karl-faster-agent-enterpriseโฆ
Matei Zaharia
@matei_zaharia
Check out our tech report www.databricks.com/sites/default/files/2026-03/karl.pdf for how we produced a super efficient yet SOTA model for document search. We're making the pipeline available to customers on Serverless GPU Compute so it's easy to run.
-
Matei Zaharia reposted
Databricks
@databricks
Day-one access to @OpenAI GPT-5.4 is now available on Databricks!
Use GPT-5.4 on Databricks to build and scale GenAI applications on your enterprise data, end to end, with the governance and operational tooling teams need for production.
GPT-5.4 achieved significant accuracy improvements on OfficeQA, a benchmark for grounded reasoning over real-world enterprise documents, driven by stronger tool use and multi-step reasoning. It's also roughly 2x faster than comparable frontier-level agent systems, translating directly to better performance in production document workflows.
Congrats to the OpenAI team on this release. We canโt wait to see what our customers build!
docs.databricks.com/aws/en/release-notes/product/2026/march -
Matei Zaharia reposted
Wen Sun
@WenSun1
Going to do a more technical deep dive on our enterprise knowledge agents and how we train them with RL.
Overall we found that simple, yet principled off-policy RL works at scale for complex agentic tasks with hundreds of steps of tool use and context management. Here are the key takeaways from our 80 page technical report.
(1) RL does not just sharpen base model's distribution.
We see test-time scaling improves consistently over the iterations of the RL training. Skills learned during RL transfers to unseen prompts and agent learns to solve prompts where base model has zero accuracy under pass@16.
(2) Multi-task RL generalizes really well
Simple mixing of training data from multiple tasks works well and allows multi-task RL scale beyond your in-distribution training tasks. We found that multi-task RL just works better than multi-expert distillation.
(3) End-to-end RL for tools and context management works best.
We skipped mid-training, and directly trained everything end-to-end using RL at scale (2m tokens per gradient computation). Models learned to use vector database tools and context compression at the same time.
Jonathan Frankle
@jefrankle
Meet KARL, an RL'd model for document-centric tasks at frontier quality and open source cost/speed. Great for @databricks customers and scientists (77-page tech report!) As usual, this isn't just one model - it's an RL assembly line to churn out models for us and our customers ๐งต
-
Matei Zaharia reposted
VentureBeat
@VentureBeat
Most enterprise RAG agents are optimized for one search task and fail on the others. Databricks built KARL to fix that โ a single agent trained across six search behaviors using reinforcement learning.
venturebeat.com/ai/databricks-built-a-rag-agent-it-says-cโฆ -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
Meet KARL, an RL'd model for document-centric tasks at frontier quality and open source cost/speed. Great for @databricks customers and scientists (77-page tech report!) As usual, this isn't just one model - it's an RL assembly line to churn out models for us and our customers ๐งต
-
Matei Zaharia reposted
Databricks
@databricks
For years, developers have had to bridge the gap between operational databases and analytics with brittle ETL pipelines. That data tax โ duplicated storage, persistent lag, fragmented governance โ ends today.
Azure Databricks Lakebase is now generally available.
Lakebase is a managed, serverless Postgres built natively into the Databricks Platform on @Azure, sharing the same storage layer as your lakehouse. Instant branching and zero-copy clones accelerate development without compromising governance.
No pipelines to maintain, no data out of sync, one governance model across your entire data estate. www.databricks.com/blog/azure-databricks-lakebase-generalโฆ -
Matei Zaharia reposted
ACM Conference on AI and Agentic Systems
@CAISconf
The CAIS 2026 demo track is open.
Show us the agent that coordinates across tools in ways we haven't seen. The serving infrastructure that makes compound AI practical at scale. The debugging tool that finally makes production AI observable.
Submissions close March 13. -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
Thrilled to see @CraigGGMyles achieve SOTA on the MEDEC medical error notes detection benchmark using @gepa_ai!
It's incredible to see automated prompt engineering approach doctor-level clinical reasoning.
Accuracy gains:
GPT-5: 66.9% -> 78.5%
Qwen3-32B: 57.8% -> 69.0% -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
New research from Databricks AI Research: FlashOptim cuts training memory by over 50% with no measurable loss in model quality.
Training a model with AdamW typically requires 16 bytes per parameter just for weights, gradients, and optimizer state. FlashOptim brings that down to 7 bytes, or 5 with gradient release. For Llama-3.1-8B finetuning, peak GPU memory drops from 175 GiB to 113 GiB.
Two techniques drive this: improved master weight splitting using tighter ULP-normalized error correction, and companded optimizer state quantization that reduces quantization error and improves convergence.
FlashOptim works as a drop-in replacement for SGD, AdamW, and Lion, supports distributed training with DDP and FSDP2, and is open source.
Paper: arxiv.org/html/2602.23349v1
Source code: github.com/databricks/flashoptim -
Matei Zaharia reposted
Databricks
@databricks
Still maintaining two engines for streaming? It's time to simplify.
Now you can get millisecond-level latency using the same Apache Spark APIs you already know.
Using Real-Time Mode (RTM) in Spark Structured Streaming, you get the best of both worlds:
โข Ultra-low latency (millisecond-level p99s) on Spark
โข A unified codebase using the familiar Spark APIs for all your streaming use cases
โข Lower ops overhead by eliminating second-engine complexity
Whether it's fraud detection, instant personalization, or generating real-time context for your AI agents, using RTM to keep your stack unified is the ultimate productivity hack for data teams. www.databricks.com/blog/real-time-mode-ultra-low-latency-โฆ -
Matei Zaharia reposted
Wen Sun
@WenSun1
Many recent works try to force GRPO to be on-policy by adding things like extra importance weighting, clipping, masking, data deletion, inference engine edits, router replayโฆ
But are these actually needed?
We push the other direction: make it maximally off-policy and keep it simple!
Turns out that nothing is wrong with off-policy. It works well, avoids entropy collapse, and improves test-time scaling (RL doesn't just sharpen base model's distribution).
While we only presented dense models in this report for math and coding tasks, similar recipe works for large-scale MoEs in agentic settings. Will share more results very soon!
Kiantรฉ Brantley
@xkianteb
Does LLM RL post-training need to be on-policy?
-
Matei Zaharia
@matei_zaharia
Really cool work from Databricks Research in collaboration with Harvard and Cornell! It turns out off-policy RL can match and even outperform on-policy, making post training a lot more efficient and flexible. Try it on your tasks on Databricks!
Kiantรฉ Brantley
@xkianteb
Does LLM RL post-training need to be on-policy?
Matei Zaharia
@matei_zaharia
Full paper here: arxiv.org/pdf/2602.19362
-
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
New research from @databricks: LLMs Can Learn to Reason via Off-Policy RL
Optimal Advantage-based Policy Optimization with Lagged Inference policy (OAPL) shows you donโt need strict on-policy training to improve reasoning.
It matches or beats Group Relative Policy Optimization (GRPO), stays stable with large policy lag, and uses ~3ร fewer training generations.
For Databricks customers, itโs a simpler, practical, and equally powerful approach to RL that Databricks is pioneering internally โ and bringing directly to Databricks customers, so enterprises can improve agents using the same methods we use for our in-house agents, without complex infrastructure changes.
arxiv.org/pdf/2602.19362 -
Matei Zaharia reposted
ACM Conference on AI and Agentic Systems
@CAISconf
Thinking about organizing a workshop or tutorial at CAIS 2026 but have questions? Reach out โ we're happy to talk through ideas before you submit.
Workshop proposal deadline: March 9 AoE -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
It's not often the co-founders and I author blog posts together, but we thought this one is important so we took time to write this together with the Neon team. In this blog we outline why we think a new type of database will slowly take over and replace all existing databases, we call it the Lakebase. We cover the WHY and the WHAT here:
๐ ๐๐๐ฐ ๐๐ซ๐ ๐จ๐ ๐๐๐ญ๐๐๐๐ฌ๐๐ฌ: ๐๐๐ค๐๐๐๐ฌ๐
www.databricks.com/blog/what-is-a-lakebase -
Matei Zaharia
@matei_zaharia
Why we're excited about Lakebase GA: most database services are based on outdated assumptions leading to poor operability, scalability and devex.
Databricks
@databricks
App development has completely transformed with agents, but the underlying databases have been largely unchanged since the 1980s.
Meet: Lakebase.
Lakebases are enabled by a fundamentally new design. The core breakthrough is separate storage and compute. Data sits directly in low-cost cloud storage in open formats, while the compute layer runs independently on top. And fully managed, serverless Postgres scales up instantly with demand and down when idle.
Learn about this new era of databases: www.databricks.com/blog/what-is-a-lakebase -
Matei Zaharia reposted
ACM Conference on AI and Agentic Systems
@CAISconf
Paper submissions close Friday, February 27 (AoE).
If you're working on compound AI systems, agentic architectures, or AI infrastructure: this is your venue.
Submit your paper at: caisconf.org/pages/cfp/
Contact us: contact@caisconf.org -
Matei Zaharia reposted
Databricks
@databricks
Push 10+ GB/sec to your lakehouse in under 5 seconds.
Zerobus Ingest is now Generally Available, streaming data directly into your lakehouse โ no message bus required.
This means less infrastructure to manage, lower costs, and faster access to real-time data.
Key capabilities:
โข Sub-5-second latency for thousands of concurrent connections
โข Supports over 10 GB/sec aggregate throughput to a single table
โข gRPC API and REST API (Beta) with production-ready SDKs, plus SDKs for Python, Java, Rust, Go, and Typescript
โข Built-in governance with Unity Catalog
www.databricks.com/blog/announcing-general-availability-zโฆ -
Matei Zaharia reposted
Databricks
@databricks
Google's Gemini 3.1 Pro models are now available on Databricks.
Use Googleโs Gemini 3.1 Pro on Databricks to build and scale GenAI applications on your enterprise data โ end to end, with the governance and operational tooling teams need for production.
Gemini 3.1 Pro delivers top results on OfficeQA, a Databricks benchmark for real-world document Q&A, for grounded Q&A with PDFs. Customers can now extract clear answers, summaries, and key takeaways from enterprise documents like policies, contracts, reports, and manuals.
Databricks is the only platform with Gemini, Claude, and OpenAI. We canโt wait to see what customers build! docs.databricks.com/aws/en/release-notes/product/2026/febโฆ -
Matei Zaharia reposted
Marius Vach
@rasmus1610
Took the new `optimize_anything` for a spin to optimize a Sudoku solver I wrote a couple of months ago.
14x speedup for $0.27
Very very cool. This is the future.
(notebook in the next tweet)
h/t @LakshyAAAgrawal @lateinteraction
Lakshya A Agrawal
@LakshyAAAgrawal
Excited to release @gepa_ai's optimize_anything: a universal API for optimizing any text parameter.
It consistently matches or outperforms domain-specific tools optimizing code, prompts, agent harnesses, cloud policies, even visuals!
If you can measure it, you can optimize it. -
Matei Zaharia reposted
Shangyin Tan
@ShangyinT
GEPA for skills is here!
Introducing gskill, an automated pipeline to learn agent skills with @gepa_ai. With learned skills, we boost Claude Codeโs repository task resolution rate to near-perfect levels, while making it 47% faster.
Here's how we did it: -
Matei Zaharia reposted
Alex Dimakis
@AlexGDimakis
How to specialize a coding agent for your codebase?
GEPA for Skills makes it easy to create a skills file for a repository:
1. Run Swe-Smith to create tasks on your repo.
2. Use GEPA optimize_anything to develop skills for your repo.
3. Done.
Shangyin Tan
@ShangyinT
GEPA for skills is here!
Introducing gskill, an automated pipeline to learn agent skills with @gepa_ai. With learned skills, we boost Claude Codeโs repository task resolution rate to near-perfect levels, while making it 47% faster.
Here's how we did it: -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
We tested across 8 diverse domains. optimize_anything can:
Learn Coding agent skills โ Boost Claude Code to near-perfect accuracy and make it 47% faster
Discover Cloud scheduling Policies โ 40% cost savings, beating expert heuristics
Discover bespoke Agent Harnesses โ Nearly triple Gemini Flash's ARC-AGI accuracy (32.5% โ 89.5%)
Perform GEPA's state-of-the-art Prompt Optimization โ Boost GPT's accuracy on math reasoning
Optimize Code Execution โ Generate fast CUDA kernels
AND...
Model a 3D Unicorn! -
Matei Zaharia
@matei_zaharia
Really excited for this new line of work from GEPA! We found that you can auto-generate anything from coding agent skills to 3D images with a LLM-guided optimization algorithm, and outperform past methods.
Lakshya A Agrawal
@LakshyAAAgrawal
Excited to release @gepa_ai's optimize_anything: a universal API for optimizing any text parameter.
It consistently matches or outperforms domain-specific tools optimizing code, prompts, agent harnesses, cloud policies, even visuals!
If you can measure it, you can optimize it. -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
Excited to release @gepa_ai's optimize_anything: a universal API for optimizing any text parameter.
It consistently matches or outperforms domain-specific tools optimizing code, prompts, agent harnesses, cloud policies, even visuals!
If you can measure it, you can optimize it. -
Matei Zaharia reposted
lingjiao chen
@ChenLingjiao
๐ข The CAIS workshop & tutorial proposal site is officially open! If you have timely, engaging topics to explore with the agentic AI community, please submit proposals!
๐๏ธ Deadline: March 9th, 2026
๐ Guidelines: www.caisconf.org/pages/workshops/
๐ฅ Submission: cais26workshops.hotcrp.com -
Matei Zaharia reposted
Replit โ
@Replit
Your data is only as valuable as what you build on top of it.
We now integrate with @Databricks to let enterprise teams vibe code living applications and deploy them directly into Databricks Apps: with governance, security, and observability built in.
๐ท๐ผโโ๏ธ More builders.
๐ ๏ธ Better tools.
๐ฎ No compromises on control. -
Matei Zaharia reposted
Apache Spark
@ApacheSpark
We've been using declarative tools like Kubernetes and Terraform for years to manage infrastructure. Spark SQL even brought that same "specify the what, not the how" logic to individual queries. But why stop there?
But why stop there?
SDP takes that logic and applies it to the entire data pipeline. By building an end-to-end dependency graph before execution, you gain a holistic understanding of your data flow.
As Sandy Ryza breaks down, this means:
โ Instant feedback on whether your pipeline can run successfully
โ Upstream and downstream schema matching
โ Significant savings in time and compute costs
๐บ Watch the full webinar: youtu.be/WNPYEZ7SMSM
#apachespark #dataengineering #datapipelines #sdpThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Yixin Dong
@yi_xin_dong
๐ FlashInfer-Bench accepted to MLSys 2026!
FlashInfer-Bench is also the platform for MLSys 2026 AI Kernel Challenge. Tomorrow is the last registration day! If you're into agents and CUDA kernels, be sure to join! ๐ mlsys26.flashinfer.ai
So proud of the team for this milestone. Over the past two months, we've witnessed rapid progress in AI Agents for GPU optimization. We have been upgrading our benchmark system and dataset to keep up this pace: better model coverage, stronger safety guardrails.
Check out our OSS project: ๐ github.com/flashinfer-ai/flashinfer-bench
See you on the leaderboard, and see you at MLSys! ๐ -
Matei Zaharia reposted
ACM Digital Library
@ACMDL
Build the future of Agentic & AI systems at the inaugural ACM CAIS!
Held May 26-29 in San Jose, California, the conference is dedicated to the design, evaluation, and engineering of compound and agentic AI systems.
For more details: www.caisconf.org
Submit your research by Feb 27, 2026! -
Matei Zaharia reposted
Google Students
@googlestudents
If you're a fan of optimization puzzles or coding, be sure to check out the MLSys 2026 Graph Scheduling Competition! ๐งฉ
The challenge: You have a complex AI workload and a tiny high-speed memory scratchpad. Your goal is to design a schedule (just a JSON file) that moves data in and out efficiently to minimize latency. Itโs like a high-stakes game of inventory management.
Open to students, researchers, hobbyists and puzzle-solvers worldwide.
Register now and start coding โ goo.gle/4ktgyyb
#mlsys2026 #codingchallenge -
Matei Zaharia reposted
Tyler Griggs
@tyler_griggs_
SkyRL now implements the Tinker API.
Now, training scripts written for Tinker can run on your own GPUs with zero code changes using SkyRL's FSDP2, Megatron, and vLLM backends.
Blog: novasky-ai.notion.site/skyrl-tinker
๐งต -
Matei Zaharia reposted
Databricks
@databricks
Databricks Delta Sharing now has first-class support for Apache Iceberg.
As the most widely adopted open protocol for data and AI sharing, Delta Sharing now lets data providers securely share live Iceberg data from Databricks to any Iceberg-compatible client.
Companies like Navitaire, an Amadeus company, use this capability to deliver governed data products to airlines, giving customers direct access to trusted insights without copying data.
Learn more about this release: www.databricks.com/blog/announcing-first-class-support-icโฆ -
Matei Zaharia
@matei_zaharia
Very excited about this opportunity for CAIS paper authors to also present at @aiDotEngineer World's Fair!
swyx
@swyx
Excited to share that this yearโs @aiDotEngineer Worldโs Fair will be the first to offer industry spotlight awards for peer reviewed papers, and we are setting aside poster sessions to feature the best industry-impacting research of 2026.
Please submit and we very much look forward to having the first paper awards at AIE become a longstanding tradition.
maybeโฆ maybe we go back to San Diego this Dec since the other research confs are going to korea and australia?
Heather Miller
@heathercmiller
๐
@CAISconf and @swyx's @aiDotEngineer AI Engineer World's Fair are partnering up!
Accepted CAIS papers on real-world systems and industry applications will be invited to present at both venues; the ACM CAIS conference in San Jose (May 27โ29) and at the AIE World's Fair.
Idea behind this:
Researchers get peer review and an academic venue (@ACMDL!โค๏ธ). They also get a stage in front of the practitioner community actually building with these systems. Industry gets work that's been through rigorous peer review ๐ค
Paper submissions due February 27! -
Matei Zaharia reposted
Heather Miller
@heathercmiller
๐
@CAISconf and @swyx's @aiDotEngineer AI Engineer World's Fair are partnering up!
Accepted CAIS papers on real-world systems and industry applications will be invited to present at both venues; the ACM CAIS conference in San Jose (May 27โ29) and at the AIE World's Fair.
Idea behind this:
Researchers get peer review and an academic venue (@ACMDL!โค๏ธ). They also get a stage in front of the practitioner community actually building with these systems. Industry gets work that's been through rigorous peer review ๐ค
Paper submissions due February 27! -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
I now constantly get questions about the SAAS meltdown, role of AI, system of records etc. I don't have an answer to all these.
But I do know that we saw an acceleration in our business in Q2, Q3, and now finished the year with accelerating Q4.
The question is, why?
Short answer: AI. But the underlying reason is subtle. We are growing fast because we are finally removing the biggest bottleneck in data: the technical barrier to entry.
For years, if you didnโt know SQL, Python, you were locked out of the value chain. That has changed fundamentally with the ๐๐๐ง๐ข๐ ๐๐๐ฆ๐ข๐ฅ๐ฒ, and it is the "secret sauce" behind our recent momentum:
โข ๐๐๐ง๐ข๐: Analysts can query data without any SQL. I use this every day myself.
โข ๐๐๐ญ๐ ๐๐๐ข๐๐ง๐๐ ๐๐๐ง๐ข๐: Builds end-to-end AI models for you, similar to Cursor for ML on your data.
โข ๐๐๐ญ๐ ๐๐ง๐ ๐ข๐ง๐๐๐ซ ๐๐๐ง๐ข๐: Write Spark pipelines, does plumbing, troubleshooting.
We've been talking about DATA + AI democratization, but generative AI finally enabled it in a way that wasn't possible before. That's why we're seeing a market response.
Take ๐๐๐ค๐๐๐๐ฌ๐ ๐๐จ๐ฌ๐ญ๐ ๐ซ๐๐ฌ. We launched this serverless engine for agents and apps recently. At 8 months into its journey, its revenue is already 2x what our Data Warehouse product was at the same stage.
All this taken together, we ended up with the following stats for Q4:
๐ $5.4B Revenue Run-Rate, growing >65% YoY
๐ $1.4B AI Revenue Run-Rate
๐ FCF Positive for the year
๐ NRR >>140%
www.databricks.com/company/newsroom/press-releases/databrโฆ -
Matei Zaharia reposted
Databricks
@databricks
We just launched our new R&D and Engineering hub in New York City! ๐ฝ
We're building on our existing AI teams to create a world-class engineering site in one of the world's top centers for technical talent. NYC represents a major expansion of our engineering capacity as we continue to build the future of data and AI. -
Matei Zaharia reposted
Ishaq Aden-Ali
@AdenIshaq
1/7 Excited about our new paper with @axliu42 @GolowichNoah @AShettyV @nhaghtal and Ankur on how data selection can have wild effects!
-
Matei Zaharia
@matei_zaharia
ACM CAIS is a the first research conference focused on agentic and AI systems, and will run in San Jose this year. The deadline is coming up Feb 27th โ submit your papers here: www.caisconf.org
-
Matei Zaharia reposted
Parth Asawa
@pgasawa
Continual learning from natural language is data-hungry. Can we make it sample-efficient? SIEVE distills natural language context (instructions, feedback, rules, etc.) into model weights using as few as 3 examples only of queriesโoutperforming prior methods and even in-context learning baselines. (1/n)
-
Matei Zaharia
@matei_zaharia
Agentic Data Quality Monitoring is now in public preview on @Databricks, powered by Unity Catalog! This next generation of monitoring looks at how your data is used to automatically flag the most important issues without needing manual rules & thresholds. www.databricks.com/blog/data-quality-monitoring-scale-ageโฆ
-
Matei Zaharia reposted
Databricks
@databricks
AI agents are no longer just writing code. Theyโre building the data layer itself.
New data shows agents now create 80% of enterprise databases and 97% of dev and test environments. This is evidence of a broader shift in data infrastructure - it needs to evolve to support building intelligent apps at machine-speed iteration.
@nikitabase, VP at Databricks and co-founder of @neondatabase, explains what is driving the move to a new kind of database: โThe database is the system of record for AI applications. Itโs no longer just a place to store rows; itโs the persistent memory and coordination layer for multi-agent systems.โ
More from @Forbes writer @iamVictorDey: www.forbes.com/sites/victordey/2026/02/04/databricks-saysโฆ -
Matei Zaharia reposted
Apache Spark
@ApacheSpark
Stop micromanaging your pipelines! ๐โ
Apache Spark 4.1 introduces ๐ฆ๐ฝ๐ฎ๐ฟ๐ธ ๐๐ฒ๐ฐ๐น๐ฎ๐ฟ๐ฎ๐๐ถ๐๐ฒ ๐ฃ๐ถ๐ฝ๐ฒ๐น๐ถ๐ป๐ฒ๐ (๐ฆ๐๐ฃ), and itโs a total shift in how we build data workflows. ๐
๐ง๐ต๐ฒ ๐ผ๐น๐ฑ ๐๐ฎ๐: Manual sequencing, retry logic, and dependency chaos. ๐ซ
๐ง๐ต๐ฒ ๐ฆ๐๐ฃ ๐๐ฎ๐: Declare your tables, define your flow, and let Spark do the heavy lifting. โ
Check out our latest video with a core SDP engineer, Sandy Ryza, to see how this feature automates:
โ๏ธ Parallelism
โ๏ธ Checkpointing
โ๏ธ Pipeline Sequencing
๐ฅ Watch the full talk: youtu.be/WNPYEZ7SMSM
#apachespark #datapipelines #sdp #dataengineering #opensource -
Matei Zaharia
@matei_zaharia
Agent memory is a simple and powerful way to do continual learning! With the new MemAlign method from Databricks Research, we can build better LLM judges from examples of human ratings, and they scale with more data. Now in Databricks and @MLflow. www.databricks.com/blog/memalign-building-better-llm-judgโฆ
-
Matei Zaharia reposted
Sean Kerner @TechJournalist
From data lake to lakehouse to lakebase
@databricks ' Lakebase operational database cuts app delivery 92% for enterprises building AI agent infrastructure
"Really for the vibe coding trend to take off, you need the developers to believe they can actually create new apps very quickly, but you also need the central IT team, or DBAs to be comfortable with the tsunami of apps and database," @rxin told @VentureBeat
venturebeat.com/data/databricks-serverless-database-slashโฆ via @VentureBeat -
Matei Zaharia
@matei_zaharia
Lakebase is GA! We think this is going to make it radically simpler and more reliable to work with online databases. You can instantly branch your DB, take snapshots, roll back to a point in time, or create a copy for offline analysis, whether it's humans or AI doing the work.
Databricks
@databricks
Operational databases have long relied on tightly coupled compute and storage. This architecture creates resource contention and pushes teams to manage infrastructure rather than build. As applications become more real time and automated, the transactional layer needs to adapt.
Databricks Lakebase is built for that evolution:
โข Familiar Postgres semantics for app developers
โข Compute separated from durable state
โข Operational data running directly on the lakehouse
โข Serverless autoscaling (including scale to zero), branching, and recovery to match agent-driven workload
Now generally available: www.databricks.com/blog/databricks-lakebase-generally-avaโฆ
Matei Zaharia
@matei_zaharia
And Lakebase automatically scales up as you use it and scales to zero for minimal cost when not in use, greatly lowering TCO over all other cloud managed Postgres. All while keeping the standard Postgres interface and extensions.
-
Matei Zaharia reposted
Databricks
@databricks
Agent Bricks Knowledge Assistant is now Generally Available!
You can now deploy a fully managed AI agent grounded in your own documents in minutes and get accurate, cited answers you can trust.
Powered by Databricks AI Research, Knowledge Assistant delivers higher-quality results than traditional RAG, with continuous upgrades, built-in evaluation, and a scalable inference API that improves answer quality over time without requiring teams to rebuild or redeploy their agent.
www.databricks.com/blog/agent-bricks-knowledge-assistant-โฆ -
Matei Zaharia reposted
Liana
@lianapatel_
We've just released code for DeepScholar-base, our deep research reference pipeline, capable of synthesizing 100s of sources and achieving competitive perf with OpenAI's DR while running 2x faster
Deepscholar-base works by using semantic operators, data-processing primitives in LOTUS that go beyond search( ) and LM( ) calls to serve a richer set of semantic transformations over large datasets. I'll write a more detailed thread on this soon
In the meantime, here's the official repo for DeepScholar-base. try it out and give us a star :)
github.com/guestrin-lab/deepscholar -
Matei Zaharia reposted
Databricks
@databricks
Open data sharing should not depend on table format or platform.
That's why weโre announcing first-class support for Apache Icebergโข in Databricks Delta Sharing, so data providers can securely share live data to any Iceberg-compatible client and reach customers wherever they are.
Delta Sharing also enables providers to share Iceberg tables that live in external catalogs, extending governed access across the Databricks ecosystem.
See how this makes it easier to collaborate across open data ecosystems. www.databricks.com/blog/announcing-first-class-support-icโฆ -
Matei Zaharia reposted
Josue Bogran
@joshbogran
I sat down with @databricks CTO and Cofounder @matei_zaharia to cut through the noise in AI, looking at whatโs working, whatโs not, and what business leaders should be thinking about next. For full interview: www.youtube.com/watch?v=nGu7ylYpycY
-
Matei Zaharia
@matei_zaharia
Super excited that weโre open sourcing the Dicer autosharder! Itโs become a critical piece of infrastructure in Databricks thatโs made many of our systems more scalable and reliable, and itโs powered by really cool systems work. www.databricks.com/blog/open-sourcing-dicer-databricks-auโฆ
Matei Zaharia
@matei_zaharia
Dicer is a statue of the art reliable autosharder that can power a wide range of stateful services. You can find it on GitHub at github.com/databricks/dicer
-
Matei Zaharia reposted
MLflow
@MLflow
Happy New Year, MLflow community! ๐
As we kick off 2026,ย MLflowย is looking for your honest feedback to guide our roadmap. Whether youโre scaling production agents or just starting with LLM observability, your insights will directly influence the tools we build this year.
๐ Share your thoughts:ย docs.google.com/forms/d/e/1FAIpQLSdGgNFQTVhg_jlLDDeIV1ouaโฆ
Why take 5 minutes to join the survey?
โ ๐๐บ๐ฝ๐ฎ๐ฐ๐:ย Directly shape the features you use for GenAI ops and evaluations.
โ ๐๐ผ๐ป๐ณ๐ถ๐ฑ๐ฒ๐ป๐๐ถ๐ฎ๐น:ย Your responses and personal info are 100% private.
โ ๐ง๐ต๐ฒ ๐๐๐๐๐ฟ๐ฒ:ย Help us define the standard for high-quality agent development in 2026.
Donโt waitโthe survey closes onย ๐๐ฎ๐ป๐๐ฎ๐ฟ๐ ๐ญ๐ณ, ๐ฎ๐ฌ๐ฎ๐ฒ.
#oss #mlflow #genai #llm #opensource -
Matei Zaharia reposted
Michael Bendersky
@bemikelive
Really excited to share our latest research on the Instructed Retriever - a novel retrieval architecture that reimagines search for the agentic era.
www.databricks.com/blog/instructed-retriever-unlocking-syโฆ
Amazing work by @cindyxinyiwang and @mrdrozdov who co-led this effort! -
Matei Zaharia reposted
Databricks
@databricks
โWhen AI agents fail, it's not because the agent is not able to reason about data, but because the agent is not getting the right data in the first place.โ
Databricks Research Director @bemikelive explains the core challenge behind getting enterprise agents to produce high-quality output and why a newly announced architecture for retrieval-augmented AI agents called Instructed Retriever solves most of the shortcomings of RAG.
Read the full article from @FortuneMagazine to see benchmark test results: fortune.com/2026/01/06/want-ai-agents-to-work-better-imprโฆ -
Matei Zaharia reposted
Databricks
@databricks
Reliable enterprise agents require system-level reasoning when retrieving across heterogeneous knowledge sources. Traditional RAG often fails to consistently follow instructions, schemas, and constraints end to end.
Thatโs why weโre presenting Instructed Retriever, a new retrieval architecture that propagates complete system specifications through every stage of the search pipeline. The approach delivers:
- 35โ50% gains in retrieval recall on instruction-following benchmarks
- 70% improvements in end-to-end answer quality over simplistic RAG, and ~15% over reranking-based approaches
- Strong instruction adherence with small, efficient models suitable for real-world deployment
Together, these results show how system-wide instruction awareness translates directly into more accurate and efficient enterprise agents. www.databricks.com/blog/instructed-retriever-unlocking-syโฆ -
Matei Zaharia reposted
Databricks
@databricks
If youโre building with data and AI, nowโs the time to tell the story.
Call for Presentations for Data + AI Summit 2026 is open, and weโre looking for real-world solutions, lessons learned, and bold ideas from data engineers, AI pioneers, data scientists, analysts and researchers.
Lightning talk or breakout, share what youโve built and the impact itโs made! Submit your proposal by February 13, 2026 ๐๏ธ
www.databricks.com/dataaisummit/call-for-presentations -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
If youโre a recently active Neon user I just sent you a note asking for feedback on what we should prioritize in 2026. So many great replies already. We are going through all of them. Your feedback is a gift. We are going to ship some epic work this year!
-
Matei Zaharia reposted
Association for Computing Machinery
@TheOfficialACM
Happy New Year! As of January 1, 2026, all ACM publications and related artifacts in the ACM Digital Library are now open access, making computing research more accessible, discoverable, and reusable worldwide.
โThis is a truly monumental milestone,โ said ACM President Yannis Ioannidis, marking a new era for the global computing community.
Explore ACMโs open access journey:
๐ www.acm.org/publications/openaccess
#openaccess #acm #openscience #computingresearch -
Matei Zaharia reposted
Databricks
@databricks
Databricks CEO @alighodsi shared what we'll see in 2026 at the @FortuneMagazine Brainstorm AI event.
Real value for enterprises will come from reasoning over proprietary data. The challenge isnโt access to AI, but applying it securely and effectively inside the enterprise.
Watch the full conversation: www.youtube.com/live/O6OpIMWgddE -
Matei Zaharia reposted
Bg2 Pod
@BG2Pod
BG2 Guest Interview. AI Enterprise - Databricks & Glean ๐ฅWhy AIs Fail and Where Real Value Emerges @bg2pod @apoorv03 @alighodsi @jainarvind
---
(00:00) Intro
(01:00) Consumer AI vs. Enterprise Reality
(02:15) Why 95% of AI Projects Fail
(04:15) RBC, Merck, and 7-Eleven Use Cases
(06:45) What Actually Makes AI Work
(07:00) LLMs Are CommoditiesโData Is the Moat
(08:45) Failed AI Bets at Databricks & Glean
(11:00) RPA vs. Generative AI
(14:15) Advice for CIOs Planning AI Budgets
(16:00) AI CapEx and the Revenue Math
(18:00) The Three Camps of AI
(21:00) Making AI Useful Inside Enterprises
(24:30) Why Apps Capture the Value
(30:00) The Future of UI, Voice, and Data Entry
(37:30) Rapid Fire: Winners, Bubbles, Long/ShortThis media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Databricks
@databricks
Serverless Snapshot Restoration removes a common interruption in serverless notebooks: idle disconnect.
With this new functionality, Databricks captures and restores your full interactive environment, including both Python and Apache Sparkโข state โ in seconds!
This makes Databricks the first platform to support complete environment restoration for serverless notebooks, enabling seamless continuity between sessions.
www.databricks.com/blog/seamlessly-resume-sessions-serverโฆ -
Matei Zaharia
@matei_zaharia
I'm thrilled to be co-organizing a new ACM research Conference on Agentic & AI Systems (CAIS) this spring! It's the first conference focused solely on this field.
๐caisconf.org
๐San Jose, May 26-29, 2026
๐๏ธPaper deadline Feb 27th
Follow @CAISconf for updates!
Matei Zaharia
@matei_zaharia
CAIS is organized by a great steering and organizing committee, including @heathercmiller @jaredq_ @deeptir18 @ChenLingjiao @JeffDean @lmthang @gneubig @pirroh @dawnsongtweets @istoica05 @lateinteraction @MonicaSLam @ChrisGPotts @NaveenGRao. Submit your papers & workshops in Feb!
-
Matei Zaharia reposted
Heather Miller
@heathercmiller
ANNOUNCING ๐ฅ๐ฅ๐ฅ:
the inaugural ACM Conference on AI and Agentic Systems! ๐
(ACM CAIS 2026)
Agents are now everywhere, compound AI systems have become the norm. The hard problems now are things like how to compose agents, how to optimize pipelines you can't differentiate through, how to evaluate and debug systems that are inherently probabilistic. These are fundamentally systems and engineering problems. Last year some of us wrote a BAIR blog article making that argument. It's held up.
There hasn't really been a home for this work. The big ML conferences focus on models. MLSys covers infrastructure. But agents, compound systems, AI engineering? It's been scattered.
A few of us have been working with @TheOfficialACM leadership to build a home for this work. And it's happening!:
CAIS 2026, ACM's first AI conference ๐
๐ San Jose, May 26-29, 2026
๐ Paper deadline Feb 27
caisconf.org
follow @CAISconf for updates!
Steering/organizing co: @matei_zaharia @jaredq_ @deeptir18 @ChenLingjiao @JeffDean @gneubig @pirroh @dawnsongtweets @istoica05 @lateinteraction @MonicaSLam @lmthang @ChrisGPotts @NaveenGRao -
Matei Zaharia reposted
MLflow
@MLflow
Weโre excited to announce the release of ๐ ๐๐ณ๐น๐ผ๐ ๐ฏ.๐ด, which brings advanced capabilities for evaluating LLM-based applications, particularly for evaluation and observation. ๐
Whatโs New in MLflow 3.8.0?
โ๏ธ ๐ฃ๐ฟ๐ผ๐บ๐ฝ๐ ๐ ๐ผ๐ฑ๐ฒ๐น ๐๐ผ๐ป๐ณ๐ถ๐ด๐๐ฟ๐ฎ๐๐ถ๐ผ๐ป: Prompts can now include model configuration, allowing you to associate specific model settings with prompt templates for more reproducible LLM workflows.
โณ ๐๐ป-๐ฃ๐ฟ๐ผ๐ด๐ฟ๐ฒ๐๐ ๐ง๐ฟ๐ฎ๐ฐ๐ฒ ๐๐ถ๐๐ฝ๐น๐ฎ๐: The Traces UI now supports displaying spans from in-progress traces with auto-polling, enabling real-time debugging and monitoring of long-running LLM applications.
โ๏ธ ๐๐ฒ๐ฒ๐ฝ๐๐๐ฎ๐น ๐ฎ๐ป๐ฑ ๐ฅ๐๐๐๐ฆ ๐๐๐ฑ๐ด๐ฒ๐ ๐๐ป๐๐ฒ๐ด๐ฟ๐ฎ๐๐ถ๐ผ๐ป: New get_judge API enables using DeepEval's evaluation metrics as MLflow scorers, providing access to 20+ evaluation metrics including answer relevancy, faithfulness, and hallucination detection.
๐ก๏ธ ๐๐ผ๐ป๐๐ฒ๐ฟ๐๐ฎ๐๐ถ๐ผ๐ป๐ฎ๐น ๐ฆ๐ฎ๐ณ๐ฒ๐๐ ๐ฆ๐ฐ๐ผ๐ฟ๐ฒ๐ฟ: New built-in scorer for evaluating safety of multi-turn conversations, analyzing entire conversation histories for hate speech, harassment, violence, and other safety concerns.
โก ๐๐ผ๐ป๐๐ฒ๐ฟ๐๐ฎ๐๐ถ๐ผ๐ป๐ฎ๐น ๐ง๐ผ๐ผ๐น ๐๐ฎ๐น๐น ๐๐ณ๐ณ๐ถ๐ฐ๐ถ๐ฒ๐ป๐ฐ๐ ๐ฆ๐ฐ๐ผ๐ฟ๐ฒ๐ฟ: New built-in scorer for evaluating tool call efficiency in multi-turn agent interactions, detecting redundant calls, missing batching opportunities, and poor tool selections.
Check out the full release notes: github.com/mlflow/mlflow/releases/tag/v3.8.0
A big thanks for all of the contributions from the community and MLflow maintainers. ๐ฅณ Happy holidays to all! โ๏ธ
#opensource #mlflow #oss #llm #genai -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
I'm hiring interns for next summer at @databricks! Specifically on (1) empirical RL at scale on non-verifiable tasks and (2) enabling real people specify the behaviors they want out of AI (e.g., through evals) on highly complex tasks. ๐งต
-
Matei Zaharia reposted
AI-Driven Research for Systems
@ai4research_ucb
๐ Excited to share our updated paper on AI-Driven Research for Systems (ADRS)!
We evaluate 3 open-source frameworks across 10 real-world systems performance problems, showing that AI can generate solutions that outperform human experts, including aย 13x speedupย in load balancing andย 35% cost savingsย in cloud scheduling.
๐งต๐ Check it out! -
Matei Zaharia reposted
SkyLight
@skylight_org
Weโve been assuming that extreme attention sparsity must destroy model quality.
That assumption is now false.
New SkyLight Release: vAttention โก๏ธ
We added vAttention to the Tier1A leaderboard. The data is striking:
๐ #1 Practical Method: Surpasses the previous lead (PQCache), closing the gap to dense models within 1% at up to 10x sparsity..
๐ Saturates Benchmarks: Dominates the sparsityโquality frontier (w/ oracle top-k).
๐ก Introducing Verified-X: A new paradigm for reliable inference-time sparsity.
In this weekโs blog, we share an in-depth look at the algorithm and how to run it via SkyLight ๐ -
Matei Zaharia reposted
Databricks
@databricks
Data collaboration is the backbone of modern AI innovation, especially as organizations work with external partners to unlock new insights.
Databricks Clean Rooms enable privacy-centric collaboration by letting partners run shared analysis on sensitive data without exposing raw records or intellectual property. Teams approve the logic together and control what outputs leave the clean room.
Weโve answered the top 10 questions about what Clean Rooms are, how they protect data, and how to get started. www.databricks.com/blog/top-10-questions-you-asked-about-โฆ -
Matei Zaharia reposted
Reynold Xin
@rxin
Yesterday we talked about how we got to $1B revenue run rate for our data warehousing business with Lakehouse. Today, we are excited to announce a whole suite of improvements for Lakebase:
โก Autoscalingย that dynamically adjusts compute based on load
๐ Scale to zero, allowing compute to shut down when idle and resume automatically in hundreds of milliseconds
โซ Instant provisioningย to create new database instances in seconds
๐ Instant database branching, enabling git-like workflows with isolated, copy-on-write environments for development, testing, and staging
๐พ Automated backups and point-in-time recoveryย for fast restore and safer operations
๐ Postgres 17, alongside continued Postgres 16 support
๐ฆ Increased storage capacity up to 8TBย for larger production workloads
๐ A new Lakebase UIย that simplifies common workflows
Many of these are made possible by the unique Lakebase architecture that separates storage (in object stores) from compute.
Read more at www.databricks.com/blog/lakebase-holiday-update
Happy holidays! -
Matei Zaharia
@matei_zaharia
People often ask me why we think Databricks can succeed in new areas we expand to. This is the recipe why: we build stellar teams in areas where we think we can greatly improve on the status quo. Lakehouse was one, Lakebase is next, but there's more coming, especially in AI.
Reynold Xin
@rxin
We disclosed today as part of our Series L that our 4-yr old data warehousing business is now >$1B revenue run rate. This is to the best of my knowledge the fastest to $1B DW product in the industry. How did we do it, and whatโs next?
The conventional wisdom is that it would take 5+ years to build a new database (just to release one).
Four years ago, the linked blog announced that Databricks had won the official TPC-DS 100TB benchmark with DBSQL, which was in preview back then. It had the best perf and the best price/perf, and notably beating Snowflake by 12x in price/perf in that benchmark. (Note: we are still the top place on the official TPC-DS benchmark today.)
That blog post launched a contentious "benchmarking war" with a lot of back and forth between vendors, but more importantly it marked the very beginning of our data warehousing business.
To build this business, we assembled the best engineering team and established a new infrastructure product category called Lakehouse that inherits the flexibility and openness of data lakes and performance of data warehouses. Lakehouse is now the standard for data infrastructure, and organizations are migrating from legacy data warehouses to the Lakehouse.
The result so far is a testament to the team and their execution. We have a lot of ideas on how to take performance and usability to the next level, and the team is working hard to make that happen. Expect some big announcements next year. We want to lay the foundation for growing the data warehousing product to a $10B business.
Databricks had operated largely in the โanalyticsโ side of data in the past, and we believe the โoperationalโ side of data (aka โOLTPโ) is also ready for a โLakehouseโ style disruption. A huge chunk of the founding teamโs time is now focusing on โLakebaseโ, a new category of OLTP databases that separates storage (in the lake) from compute. That architecture enables features that have been virtually impossible for databases in the past: instant provisioning, elastic scaling (down to zero), branching, high throughput scan directly from Spark, โฆ
I wonโt go into too much detail about Lakebase here, but we expect a similar trend to happen in the next few years: Lakebase will transform the industry and other OLTP systems will re-architect or position towards it.
The best data warehouse is a lakehouse, and the best database is a lakebase!
www.databricks.com/blog/2021/11/02/databricks-sets-officiโฆ -
Matei Zaharia reposted
Reynold Xin
@rxin
We disclosed today as part of our Series L that our 4-yr old data warehousing business is now >$1B revenue run rate. This is to the best of my knowledge the fastest to $1B DW product in the industry. How did we do it, and whatโs next?
The conventional wisdom is that it would take 5+ years to build a new database (just to release one).
Four years ago, the linked blog announced that Databricks had won the official TPC-DS 100TB benchmark with DBSQL, which was in preview back then. It had the best perf and the best price/perf, and notably beating Snowflake by 12x in price/perf in that benchmark. (Note: we are still the top place on the official TPC-DS benchmark today.)
That blog post launched a contentious "benchmarking war" with a lot of back and forth between vendors, but more importantly it marked the very beginning of our data warehousing business.
To build this business, we assembled the best engineering team and established a new infrastructure product category called Lakehouse that inherits the flexibility and openness of data lakes and performance of data warehouses. Lakehouse is now the standard for data infrastructure, and organizations are migrating from legacy data warehouses to the Lakehouse.
The result so far is a testament to the team and their execution. We have a lot of ideas on how to take performance and usability to the next level, and the team is working hard to make that happen. Expect some big announcements next year. We want to lay the foundation for growing the data warehousing product to a $10B business.
Databricks had operated largely in the โanalyticsโ side of data in the past, and we believe the โoperationalโ side of data (aka โOLTPโ) is also ready for a โLakehouseโ style disruption. A huge chunk of the founding teamโs time is now focusing on โLakebaseโ, a new category of OLTP databases that separates storage (in the lake) from compute. That architecture enables features that have been virtually impossible for databases in the past: instant provisioning, elastic scaling (down to zero), branching, high throughput scan directly from Spark, โฆ
I wonโt go into too much detail about Lakebase here, but we expect a similar trend to happen in the next few years: Lakebase will transform the industry and other OLTP systems will re-architect or position towards it.
The best data warehouse is a lakehouse, and the best database is a lakebase!
www.databricks.com/blog/2021/11/02/databricks-sets-officiโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Excited to raise $4B+ in our latest fundraise! We shared that we will primarily be using the capital to invest in:
1๏ธโฃ Lakebase Postgres - serverless database for Agents
2๏ธโฃ Agent Bricks - high quality agents that can reason on enterprise data
3๏ธโฃ Databricks Apps - Data Intelligence Apps built on Lakebase and Agent Bricks
As part of this we also disclosed:
๐ Crossed $4.8B revenue run-rate, over 55% YoY growth
๐ Crossed $1B of revenue run-rate for our Data Warehousing product
๐ Crossed $1B of revenue run-rate for our AI products
๐ Continued to be cash flow positive in the last 12 months
Big thanks to Insight Partners, Fidelity Investments, and J.P. Morgan who led the round.
www.databricks.com/company/newsroom/press-releases/databrโฆ -
Matei Zaharia reposted
Liana
@lianapatel_
๐Excited to share we've re-launched DeepScholar, with a set of updates and fixes to support the volume of requests we've gotten since launching our research preview two weeks ago
DeepsScholar is still openly-accessible, fast, and capable of efficiently processing 100s are articles from the web for research synthesis
... and hopefully its just in time to help you catch up on your post-neurips reading list
Let us know what you're using DeepScholar for, and what features you'd like to see next
Links below ๐ -
Matei Zaharia
@matei_zaharia
Great to see GPT-5.2 come out today! We also found it to do better than past frontier models on OfficeQA, though there is still a lot of headroom for AI to do well on this benchmark.
Databricks
@databricks
Weโre excited to share that our customers have day-one access to OpenAI GPT-5.2 on Databricks!
GPT-5.2 delivers strong gains on OfficeQA, our benchmark for grounded enterprise reasoning, and is now available on our platform with native Response API support. Paired with Agent Bricks, teams get a unified way to build governed, trusted, data-aware agents with minimal integration work.
Congrats to the @OpenAI team on this release. We canโt wait to see what our customers build! www.databricks.com/blog/openai-gpt-52-and-responses-api-dโฆ -
Matei Zaharia reposted
Databricks
@databricks
Databricks CEO @alighodsi joined @FortuneMagazine Brainstorm AI 2025 to discuss the future of the AI market, and how Agent Bricks is transforming organizations across industries.
โItโs a commodity now to have AI that has general knowledge, but itโs very elusive to get AI that really understands the proprietary data thatโs inside the enterprise โ thatโs what weโre helping enterprises do with Agent Bricks.โ
fortune.com/2025/12/09/databticks-ceo-1-trillion-valuatioโฆ -
Matei Zaharia reposted
SuperAnnotate
@superannotate
๐Congratulations to our partner @databricks on the launch of the OfficeQA Benchmark.
Enterprises can use the OfficeQA Benchmark to measure whether AI systems can handle the messy, high-precision tasks found in real business workflows. Teams can now more easily identify gaps, compare models, and make informed decisions about when AI is ready for deployment.
The benchmark was developed using a large dataset: nearly 89,000 pages of historical U.S. Treasury Bulletins (documents spanning decades, with scanned pages, PDFs, complex tables, charts, figures, and mixed unstructured + structured data).
๐ฃSuperAnnotate is proud to have powered the dataset and annotation rubrics behind this benchmark and to collaborate with the incredible Databricks team - Arnav Singhvi, Krista Opsahl-Ong, Jasmine Collins, @ivanzhouyq, @cindyxinyiwang, Ashutosh Baheti, Jacob Portes, Sam Havens, Erich Elsen, Michael Bendersky, @matei_zaharia, Xing Chen.
Databricks
@databricks
Today weโre introducing OfficeQA, a new benchmark grounded in ~89,000 pages of U.S. Treasury Bulletins that reflects the complex, document-heavy tasks enterprises actually face.
Unlike existing benchmarks, OfficeQA measures economically valuable, real-world reasoning: parsing dense tables, navigating scanned PDFs, and retrieving facts across decades of documents.
Even strong agents reach only ~45% accuracy, showing how far the field has to go. The benchmark is now open to the community, and the Databricks Grounded Reasoning Cup in Spring 2026 will challenge teams to push these capabilities forward. www.databricks.com/blog/introducing-officeqa-benchmark-enโฆ -
Matei Zaharia
@matei_zaharia
LLMs are claimed to reach PhD intelligence, but still fail mundane tasks. To understand this challenge, Databricks launched OfficeQA, a benchmark of useful tasks that require reliability&diligence, not specialized knowledge. We're also doing a competition! www.databricks.com/blog/introducing-officeqa-benchmark-enโฆ
Matei Zaharia
@matei_zaharia
OfficeQA stands in contrast to "superintelligence" benchmarks that test esoteric or abstract knowledge but do not necessarily translate into better performance on real work. One way to view it is "can ASI make it through one day at the office?"
Matei Zaharia
@matei_zaharia
OfficeQA is neat because we believe any new grad can do the tasks reliably, but it highlights the challenges enterprises have with AI. Elaborate agents with our latest document AI tools do a bit better, but there is still plenty of headroom. We hope researchers find this useful!
-
Matei Zaharia reposted
Michael Bendersky
@bemikelive
We released OfficeQA today -- a hard benchmark for evaluating agents on grounded reasoning tasks. More details in our blog www.databricks.com/blog/introducing-officeqa-benchmark-enโฆ and the thread below
-
Matei Zaharia reposted
MLflow
@MLflow
MLflow 3.7.0 is here and it brings major features and improvements for GenAI Observability, Evaluation, and Prompt Management! ๐๐ฅณ
๐ View the release notes: github.com/mlflow/mlflow/releases/tag/v3.7.0
๐ผ๐๐๐๐ ๐ต๐๐๐๐๐๐๐
โ๏ธ ๐๐ ๐ฝ๐ฒ๐ฟ๐ถ๐บ๐ฒ๐ป๐ ๐ฃ๐ฟ๐ผ๐บ๐ฝ๐๐ ๐จ๐: Manage and search prompts (including version search in traces) directly within the experiment UI.
๐ฌ ๐ ๐๐น๐๐ถ-๐๐๐ฟ๐ป ๐๐๐ฎ๐น๐๐ฎ๐๐ถ๐ผ๐ป: Enhanced mlflow.genai.evaluate now supports assessing conversational AI applications with multi-turn inputs.
โ๏ธ ๐ง๐ฟ๐ฎ๐ฐ๐ฒ ๐๐ผ๐บ๐ฝ๐ฎ๐ฟ๐ถ๐๐ผ๐ป: New side-by-side view in the Traces UI to analyze and debug LLM behavior across runs.
โ ๐๐ฒ๐บ๐ถ๐ป๐ถ ๐ง๐๐ฝ๐ฒ๐ฆ๐ฐ๐ฟ๐ถ๐ฝ๐ ๐ฆ๐๐: Added auto-tracing support for Googleโs Gemini in TypeScript.
๐ฏ ๐ฆ๐๐ฟ๐๐ฐ๐๐๐ฟ๐ฒ๐ฑ ๐ข๐๐๐ฝ๐๐๐ ๐ถ๐ป ๐๐๐ฑ๐ด๐ฒ๐: The make_judge API now supports precise, programmatically consumable structured evaluation results.
๐ฃ ๐ฉ๐ผ๐น๐๐๐ด๐ฒ๐ป๐ ๐ง๐ฟ๐ฎ๐ฐ๐ถ๐ป๐ด: Added auto-tracing support for the @voltagent_dev framework.
Thanks to all the contributions from the community! ๐
Try it out: pip install mlflow==3.7.0
#opensource #oss #mlflow #llm -
Matei Zaharia reposted
Andy Konwinski
@andykonwinski
The open frontier only moves forward if we work together. Weโre bringing the leaders of open research in AI into one room. I'll meet you there. openfrontier.ai
Laude Institute
@LaudeInstitute
The open frontier of AI has never had a home to call its own. So weโre giving it one. ๐
One day, one place, one hundred of the leading scientists and researchers working at the leading edge. Livestreamed to the world.
openfrontier.ai -
Matei Zaharia reposted
Melissa Pan
@melissapan
Thrilled to release our new paper MAP: Measuring Agents in Production โ๏ธ๐
2025 is the year of agentsโฆ but do they actually work in the real world? Is it just hype?
A group of 25 researchers from Berkeley, Stanford, UIUC, IBM, and Intesa Sanpaolo investigated what makes agents deployable in the wild. Soโฆ
๐ Why agents? Productivity gains
โ How to build production agents? Simple & controllable methods
๐งโ๐ป How to evaluate agents? Heavy human oversight
๐ Top challenge now? Reliability remains unsolved
We surveyed 306 agent builders and ran 20 in-depth interviews across 26 agent application domains to understand the current landscape of production agents.
Check out our latest paper: MAP - more in the thread ๐
(1/N) -
Matei Zaharia
@matei_zaharia
This was a great collaboration between @BerkeleySky, @IBMResearch, @intesasanpaolo and others: we surveyed hundreds of agent developers to see what patterns work for *production* agents. Check out what we learned:
Melissa Pan
@melissapan
Thrilled to release our new paper MAP: Measuring Agents in Production โ๏ธ๐
2025 is the year of agentsโฆ but do they actually work in the real world? Is it just hype?
A group of 25 researchers from Berkeley, Stanford, UIUC, IBM, and Intesa Sanpaolo investigated what makes agents deployable in the wild. Soโฆ
๐ Why agents? Productivity gains
โ How to build production agents? Simple & controllable methods
๐งโ๐ป How to evaluate agents? Heavy human oversight
๐ Top challenge now? Reliability remains unsolved
We surveyed 306 agent builders and ran 20 in-depth interviews across 26 agent application domains to understand the current landscape of production agents.
Check out our latest paper: MAP - more in the thread ๐
(1/N) -
Matei Zaharia reposted
Databricks
@databricks
โGenAI makes it so easy to create a great demo. But the challenge is not the demo โ itโs getting to production.โ
From the show floor at #awsreinvent, Craig Wiley, Sr. Director of Product for AI/ML at Databricks, explains how the Databricks + AWS partnership helps enterprises move past POCs and into real, governed, high-stakes deployments.
Agent Bricks gives teams the evaluation, governance, and cost optimization needed to ship agents responsibly and at scale on @awscloud. Watch the full conversation: youtu.be/Q6jRdpF6yXE -
Matei Zaharia
@matei_zaharia
If you're at #neurips, check out Erich Elsen's talk at 5:15 today on a new AI benchmark competition we created at @Databricks for economically valuable tasks, where frontier model still struggle significantly. neurips.cc/virtual/2025/loc/san-diego/talk/127768
-
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
Weโre headed to #neurips2025 as a Platinum sponsor! Catch us at booth 1619 to talk research, demos, and opportunities. All the details: www.databricks.com/blog/databricks-neurips-2025
-
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
I'm missing NeurIPS BUT my extraordinary @databricks colleagues will be there:
๐งฑ Erich Elsen (multimodal)
๐งฑ @abaheti95, @gupta__abhay, @jjgort (RL at scale)
๐งฑ @JacobianNeuro (search)
๐งฑ @VeronicaLyu (feedback)
Hang out with them, and you won't miss me at all ๐ -
Matei Zaharia reposted
Abhay Gupta
@gupta__abhay
Iโll be at #neurips2025 from 2nd-6th Dec. DM if you want to chat about MoEs, scaling training and inference, making GPUs go brrr and other fun stuff !!
Jonathan Frankle
@jefrankle
I'm missing NeurIPS BUT my extraordinary @databricks colleagues will be there:
๐งฑ Erich Elsen (multimodal)
๐งฑ @abaheti95, @gupta__abhay, @jjgort (RL at scale)
๐งฑ @JacobianNeuro (search)
๐งฑ @VeronicaLyu (feedback)
Hang out with them, and you won't miss me at all ๐ -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
As someone who worked on db engines my whole life Iโm still in awe how much is possible when you run a database on an object store.
-
Matei Zaharia reposted
MLflow
@MLflow
๐ Help shape the future and frontier of open source MLflow!
Weโre running a short survey to learn how you use MLflow for GenAI Ops, agent evals, and observability.
๐ง Every response helps us raise the bar for agent quality and open innovation.
๐ A random 25% of participants will receive exclusive MLflow swag!
๐๏ธ Closes Jan 17, 2026
๐ docs.google.com/forms/d/e/1FAIpQLSdGgNFQTVhg_jlLDDeIV1ouaโฆ
Your feedback = better agents, better MLflow.
๐ #mlflow #opensource #genai -
Matei Zaharia reposted
SkyLight
@skylight_org
Sparse attention offers a viable path to solving the computational and memory issues of long-context LLM serving. However, we observe a surprising gap between the rapid pace of academic research and the reality of open-source adoption.
We identify the core barrier as fragmentation where new methods are published rapidly, but with missing comparative grounding.
Today weโre excited to share SkyLight, where we are building a unified framework designed to bridge this gap. SkyLight standardizes the implementation and evaluation of sparse attention to enable rigorous, controlled benchmarking.
Our first major effort is to understand the frontier of inference time sparse-decoding in LLMs.
1/N ๐งต -
Matei Zaharia reposted
Liana
@lianapatel_
๐ Thrilled to launch DeepScholar, an openly-accessible DeepResearch system we've been building at Berkeley & Stanford.
DeepScholar efficiently processes 100s of articles, demonstrating strong long-form research synthesis capabilities, competitive with OpenAI's DR, while running up to 2x faster!
Try it out: deep-scholar.vercel.app -
Matei Zaharia
@matei_zaharia
Congrats to all the database product teams at Databricks for this great recognition!
Databricks
@databricks
Weโre proud to share that Databricks has been named a Leader in the 2025 @Gartner_inc Magic Quadrantโข for Cloud Database Management Systems for the fifth year in a row!
The Databricks Platform enables everyone in your organization to use data and AI. New innovations like Agent Bricks and Lakebase empower teams to create production-ready AI agents that operate securely on real-time, governed data, all on an open platform.
Download the report to see why we continue to be named a Leader in cloud data management. www.databricks.com/resources/analyst-paper/databricks-namโฆ -
Matei Zaharia reposted
Jelani Nelson
@minilek
Awesome getting to listen to Bill Joy today at Berkeley, co-hosted by @LaudeInstitute and @berkeley_csge
Lots of OGs in the audience. I spotted Randy Katz, Dave Patterson, Eric Schmidt, John Gage, John Doerr, Tom Lyon. Iโm sure Iโm missing several โฆ -
Matei Zaharia reposted
Databricks
@databricks
.@Google's Gemini 3 models are now available on Databricks!
Gemini 3 brings faster reasoning, stronger factual accuracy, and richer multimodal capabilities, from image and video understanding to ultra-long-context RAG, summarization, and classification for both batch and real-time workloads.
With AI Gateway and Agent Bricks, teams can ground Gemini in governed enterprise data and build agents that act on real business context. Gemini CLI support is coming soon to make this even easier.
Databricks is now the only platform with Gemini, Claude, and OpenAI. We canโt wait to see what customers build! www.databricks.com/blog/launching-gemini-3-pro-databricks -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Six months ago we joined Databricks. Today, Lakebase is powering production-grade AI products for multi-billion-dollar enterprises. The pace here is unreal, itโs only possible because the team ships world-class engineering at world-class speed.
-
Matei Zaharia
@matei_zaharia
Great new capability in Databricks powered by our AI research team! We trained a document parsing system that delivers leading quality at 3-5x lower cost and outperforms leading VLMs like GPT-5 and Claude. This is critical to connect AI to so many kinds of data.
Databricks
@databricks
80% of enterprise data is unstructured, locked in PDFs, reports, and diagrams that traditional tools canโt parse or govern.
Introducing ai_parse_document, state-of-the-art document intelligence on Databricks.
With a single SQL command, teams can now turn any document into structured, queryable data, unlocking context that agents can finally reason over โ at up to 5ร lower cost.
โข Capture every element โ tables, figures, and diagrams โ with AI-generated descriptions and precise bounding boxes
โข Process at scale with Lakeflow and govern everything in Unity Catalog
โข Use parsed data seamlessly across Agent Bricks, Vector Search, and AI/BI
Now in Public Preview! www.databricks.com/blog/pdfs-production-announcing-state-โฆ
Matei Zaharia
@matei_zaharia
Enterprise documents are very complex, with tables, headings, figures, etc, and the new ai_parse_document identifies these components reliably and returns them in a JSON form for downstream apps/agents. Customers have been putting it to the test on some very tough datasets!
Matei Zaharia
@matei_zaharia
We also made it super easy to use from SQL or Apache Spark. Just call ai_parse_document and we automatically handle batch execution at scale. Docs here: docs.databricks.com/aws/en/sql/language-manual/functions/โฆ
-
Matei Zaharia reposted
MLflow
@MLflow
MLflow 3.6.0 just landed. Thanks to MLflow maintainers and the community.
๐ Check it out: mlflow.org/releases
Big rocks include:
๐ Full OpenTelemetry Support in MLflow Tracking Server
๐ Session-level View in Trace UI
๐ New Supported Frameworks in TypeScript Tracing SDK
๐ Tracking Judge Cost and Traces
๐ New experiment tab bar
Try it out: pip install mlflow. Let us know! -
Matei Zaharia reposted
Databricks
@databricks
Submissions are now open for the Databricks Free Edition Hackathon!
Build something incredible with Free Edition and show whatโs possible with data and AI. Whether itโs an AI agent, a machine learning model, or a powerful visualization, this is your opportunity to share your project with the global data + AI community.
Projects will be judged by Databricks leaders @rxin, Franco Patano, Holly Smith, and William Valori. Submit your project by November 14: www.databricks.com/resources/free-edition-hackathon -
Matei Zaharia reposted
Tyler Griggs
@tyler_griggs_
Huge thanks to the Laude team for supporting SkyRL with the Slingshots program!
Andy and the team at @LaudeInstitute have already been a big help to the project and OSS research in general
Laude Institute
@LaudeInstitute
Meet Slingshots // One.
This inaugural batch includes leading-edge researchers advancing the science and practice of AI - with benchmarks, frameworks, and agents that ship real impact into the world.
We're honored to support research from:
@alexgshaw @Mike_A_Merrill @lschmidt3 @andykonwinski @lateinteraction @a1zhang @GregKamradt @mikeknoop @fchollet @jyangballin @KLieret @Diyi_Yang @tyler_griggs_ @profjoeyg @istoica05 @DachengLi177 @shiyi_c98 @matei_zaharia @sijun_tan @ralucaadapopa @ying11231 @lm_zheng @Tim_Dettmers @Muennighoff @AndrewYNg @YejinChoinka @atharva_sehgal @yisongyue @ChengleiSi @tatsu_hashimoto @KexinHuang5 @lisabdunlap @JacobSteinhardt @LakshyAAAgrawal
This first batch sets a VERY high bar, and weโre proud to call these researchers part of the Laude community.
More details here: www.laude.org/updates/slingshots-one -
Matei Zaharia reposted
Databricks
@databricks
Enterprises can now securely connect AI agents to external tools and data with the new MCP Catalog and Agent Bricks!
โข MCP Catalog lets teams find and manage MCP servers in one place with Unity Catalog governance.
โข MCP in Databricks Marketplace expands your ecosystem with trusted partners like @SPGlobal, @moodysratings, @DunBradstreet and @FactSet.
โข Agent Bricks Multi-Agent Supervisor combines and creates powerful agents that reason over data and take action using servers from your MCP Catalog
Together, they turn disconnected tools into secure, production-ready AI systems: www.databricks.com/blog/accelerate-ai-development-databriโฆ -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
We reduced compute prices by 25%.
Generally itโs impossible to deliver better price performance than @neondatabase without separation of storage and compute. Here is why: -
Matei Zaharia reposted
Databricks
@databricks
AI agents are shaking up every industry. The stakes are high when deploying agents into production, and the reality is that many projects stall in the pilot phase.
The barrier to production: trust.
This week, weโre announcing new Agent Bricks capabilities that make it easier to build agents that are accurate, governed, and production-ready. Agents you can trust.
Hereโs a look at whatโs new ๐
www.databricks.com/blog/building-trusted-ai-agents-new-caโฆ -
Matei Zaharia reposted
MLflow
@MLflow
Only a few days left until the ๐ง๐ฒ๐ฟ๐บ๐ถ๐ป๐ฎ๐น ๐๐ฒ๐ป๐ฐ๐ต ๐ ๐ฒ๐ฒ๐๐๐ฝ atย @databricks HQ! ๐
๐ฃ Join theย #mlflowย community this Thursday for an evening of demos, discussions, and new announcements from Terminal Bench 2.0.
Hear fromย Danny Chiaoย on building high-quality agents faster with MLflowโplus, enjoy good food, drinks, and great company.
๐ Thursday, Nov 6
๐ 6:00โ8:00 PM PST
๐ Databricks, San Francisco
Seats are filling up fastโgrab yours now ๐ luma.com/h9kb99vd
#terminalbench #aiagents #opensource #oss #sanfrancisco -
Matei Zaharia reposted
Databricks
@databricks
How our engineers built versionless Apache Sparkโข โ a new way of running Spark that delivers automatic upgrades, zero code changes, and unmatched stability.
A stable client API + AI-powered release management keeps workloads reliable while still delivering the latest features and fixes. With this innovation, over 2 billion workloads have been upgraded with a 99.99% success rate: www.databricks.com/blog/examining-versionless-apache-sparโฆ -
Matei Zaharia
@matei_zaharia
This is a big deal -- ingest data into any lakehouse table with no infra setup, just calling a REST API. Simple, efficient and powerful.
Databricks
@databricks
Announcing Public Preview of Zerobus Ingest, part of Lakeflow Connect: Push event data directly into your lakehouseโno message bus required!
Simplified ingestion. Reduced latency. Built for scale.
- Up to 100 MB/sec per connection
- Latency as low as 5 seconds
- Native Delta + Unity Catalog integration
With Zerobus Ingest, teams can easily build secure, real-time data pipelines for IoT, clickstream, and telemetry data, without the complexity of managing external infrastructure. Learn more: www.databricks.com/blog/announcing-public-preview-zerobusโฆ -
Matei Zaharia reposted
AI-Driven Research for Systems
@ai4research_ucb
๐ฏ AI found algorithm beat * NSDI'24 Best Paper * ๐คฏ
[ADRS Blog #2] We use AI to find new spot-instance scheduling algorithms. It beats the original paper algorithm by cutting cloud costs up to 48% (average 27%), while still meeting the job deadlines!
โ๏ธย Read the blog: adrs-ucb.notion.site/spot-instance-scheduling
๐ย ADRS Blog Series: ucbskyadrs.github.io
๐ย Full paper: arxiv.org/abs/2510.06189
๐ฉโ๐ปย Code: github.com/UCB-ADRS/ADRS -
Matei Zaharia reposted
MLflow
@MLflow
Have you heard of GEPA? ๐ฅ
GEPA has quickly become one of the most popular prompt optimization techniques in AIโand through our collaboration with @DSPyOSS, #mlflow now makes it easier than ever to apply GEPA to your agents.
MLflow brings GEPA to where your traces and eval datasets already liveโno code change needed.
We tested it on @OpenAI Agents with the HotpotQA dataset and saw a 14% accuracy boost in just 30 minutes! ๐
๐ Read the full guide: mlflow.org/blog/mlflow-prompt-optimization
#opensource #oss #ai #gepa #dspy #promptoptimization -
Matei Zaharia reposted
Audrey Cheng
@audreyccheng
Thanks @ThomasClaburn and @TheRegister for featuring our ADRS research! Excited to continue our work in this area!
The Register
@TheRegister
Berkeley boffins build better load balancing algo with AI www.theregister.com/software/2025/10/25/openevolve-ai-codโฆ
-
Matei Zaharia reposted
Michael Bendersky
@bemikelive
We are hiring interns in all areas of AI at Databricks Research! In particular, my team is looking for exceptional candidates with background in combining large language models and large-scale retrieval systems.
Matei Zaharia
@matei_zaharia
My team is hiring AI research interns for summer 2026 at Databricks! Join us to learn about AI use cases at thousands of companies, and contribute to making it easier for anyone to build specialized AI agents and models for difficult tasks.
-
Matei Zaharia
@matei_zaharia
Fine-tuned (PEFT/LoRA) models can greatly improve quality, but serving them can be challenging due to both numerical and performance issues. Our team has done amazing work to get up to 2x higher throughput and 2-3% better quality than open source engines: www.databricks.com/blog/fast-peft-serving-scale
-
Matei Zaharia reposted
UC Berkeley EECS
@Berkeley_EECS
Amazing! 10 @BerkeleyEECS @SkyCompLab grad students are Amazon AI PhD Fellows! Congrats! Learn more about our fellows here: eecs.berkeley.edu/news/eecs-students-drive-ai-innovation-โฆ
#amazonaifellowship
@BerkeleySky
Amazon Science
@AmazonScience
๐ Amazon launches AI PhD Fellowship program, providing $68 million over two years to fund PhD students at 9 universities pursuing research in machine learning, computer vision, and natural-language processing. #amazonaifellowship www.amazon.science/news/amazon-launches-68-million-ai-phdโฆ
-
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
We managed 99.97% of database operations successfully on US-East-1 throughout the outage.
Mostly because we depend on a relatively short list of AWS services. We buy big metal instances from AWS relatively infrequently, and then handle all the tenant provisioning ourselves.
Neon
@neondatabase
Neon runs warm pools of compute and storage so new database creates are fast and generally don't require resource changes on AWS.
This architecture meant we could still run 99.9%+ of database operations throughout the incident. -
Matei Zaharia reposted
Databricks
@databricks
Kubernetes handles most workloads with ease โ but managing millions of persistent gRPC connections at Databricks scale pushes the limits of default load balancing.
Thatโs why we built a client-side system with a lightweight control plane and xDS to make routing faster, more balanced, and resilient: www.databricks.com/blog/intelligent-kubernetes-load-balanโฆ -
Matei Zaharia reposted
UC Berkeley EECS
@Berkeley_EECS
UC Berkeley EECS is hiring! We're seeking exceptional faculty candidates at all ranks for our "Engineering + AI" search and up to 7 tenure-track Asst. Professors in EECS.
EECS Focused Searches Include:
Quantum Computing โ๏ธ
AI, Inequality, & Society โ๏ธ
eecs.berkeley.edu/connect/faculty-jobs/ -
Matei Zaharia
@matei_zaharia
My team is hiring AI research interns for summer 2026 at Databricks! Join us to learn about AI use cases at thousands of companies, and contribute to making it easier for anyone to build specialized AI agents and models for difficult tasks.
Matei Zaharia
@matei_zaharia
Specific focus areas include scalable RL training, multimodal models, information retrieval, evaluation, and coding and data science agents. Apply here: www.databricks.com/company/careers/university-recruiting/โฆ
-
Matei Zaharia reposted
Melissa Pan
@melissapan
Checkout our blog for โbarbarians at the gate: how AI is upending systems researchโ in the ACM SIGOPS blog series ๐
ACM SIGOPS
@ACMSIGOPS
Barbarians at The Gate: How AI is Upending Systems Research by @audreyccheng, @LynnLiu41887950, @melissapan, @istoica05, and the @ai4research_ucb team,
sigops.org/2025/barbarians-at-the-gate-how-ai-is-upendingโฆ
This's first article of the The Next Horizon of System Intelligence blog series. -
Matei Zaharia reposted
Wenjie Ma
@wenjie_ma
LLMs solving math benchmarks with verifiable answers like AIME? โ
LLMs solving math proofs? โ Still an open problem.
RL works great for final-answer problems, but proofs are different:
- Often no single checkable answer
- Correct answers can hide flawed reasoning
The key bottleneck: reliable proof evaluation. Without a good evaluator, we can't automatically evaluate or train better "provers."
Our new work tackles this challenge step by step. ๐งต
๐ Paper: arxiv.org/pdf/2510.13888 -
Matei Zaharia reposted
Matei Zaharia
@matei_zaharia
If you're running agents in production, consider taking this short survey from my research group!
We're collaborating with IBM, Stanford, UIUC, Intesa Sanpaolo and others to better understand the challenges in building agents. It only takes 5 minutes: agents-survey.github.io/AI-Agent-Survey/participate/ -
Matei Zaharia
@matei_zaharia
We've been getting some great results with AI for systems optimization at Berkeley! This is a way of using AI that I think is under-explored: use LLMs as a prior to search for a solution given a verifiable metric. It could probably be applied to more industry problems.
AI-Driven Research for Systems
@ai4research_ucb
๐ Excited to release our new paper: โBarbarians at the Gate: How AI is Upending Systems Researchโ
We show how AI-Driven Research for Systems (ADRS) can rediscover or outperform human-designed algorithms across cloud scheduling, MoE expert load balancing, LLM-SQL optimization, transaction scheduling, and more โ all within hours โก๏ธ and under $20 ๐ฐ.
๐งต๐ Check it out!
Matei Zaharia
@matei_zaharia
The same kind of search was used in AI for chip design, AlphaEvolve/OpenEvolve, and GEPA for finding prompts, but not enough organizations are setting up their problems this way.
Matei Zaharia
@matei_zaharia
Paper: arxiv.org/abs/2510.06189v2
-
Matei Zaharia
@matei_zaharia
Congratulations Omar! I feel super lucky to have collaborated with Omar's group at Berkeley, if only in a small way so far!
UC Berkeley
@UCBerkeley
Congratulations to UC Berkeleyโs Omar Yaghi, who shares the 2025 @NobelPrize in #chemistry for helping create a field called reticular chemistry. news.berkeley.edu/2025/10/08/uc-berkeleys-omar-yaghi-sharโฆ
-
Matei Zaharia
@matei_zaharia
We've invested a lot in agent evaluation in MLflow and made it super easy to get high quality judges. Our new make_judge judges can take declarative instructions, analyze entire traces from any agent framework, and align their ratings with human feedback. mlflow.org/blog/custom-llm-judges-make-judge
-
Matei Zaharia reposted
MLflow
@MLflow
MLflow 3.4 introduces make_judge, a declarative API for building domain-specific LLM judges that automatically align with expert preferences.
This approach removes complex prompt engineering, enables agentic scorers with built-in trace introspection, and delivers meaningful reductions in evaluation errors based on task and feedback quality.
Automate building domain-specific evaluators with MLflow ๐ Dive in: mlflow.org/blog/custom-llm-judges-make-judge
#opensource #genai #oss #llm #judges -
Matei Zaharia reposted
Parth Asawa
@pgasawa
Training our advisors was too hard, so we tried to train black-box models like GPT-5 instead. Check out our work: Advisor Models, a training framework that adapts frontier models behind an API to your specific environment, users, or tasks using a smaller, advisor model (1/n)!
-
Matei Zaharia reposted
Databricks
@databricks
Big news: @SAP Business Data Cloud Connect is GA!
Now you can connect SAP Business Data Cloud with Databricks for zero-copy, bidirectional, live data sharing via Delta Sharing.
Together, these capabilities drive faster insights, smarter decisions, and enterprise-wide innovation: www.databricks.com/blog/announcing-general-availability-sโฆ -
Matei Zaharia reposted
Databricks
@databricks
How Databricks Engineers developed a high performance rate limiting system.
The team rebuilt the system with in-memory sharding and client-driven batch reporting to achieve low-latency, high-throughput enforcement. With this approach, they cut tail latency by up to 10x.
See how they did it: www.databricks.com/blog/high-performance-ratelimiting-datโฆ -
Matei Zaharia reposted
Delta Lake
@DeltaLakeOSS
๐ Open Lakehouse + AI events are dedicated to advancing open lakehouse and AI through adoption, collaboration, and sharing real-world use cases.
Explore whatโs coming up to learn, connect, and collaborate with a global community passionate about shaping the future of data and AI.
๐น ๐ข๐ฐ๐๐ผ๐ฏ๐ฒ๐ฟ ๐ณ: Webinar | From Functions to AI Agents: Reimagining the Lakehouse for an Agentic Future
๐น ๐ก๐ผ๐๐ฒ๐บ๐ฏ๐ฒ๐ฟ ๐ญ๐ฏ: Mini Summit | Mountain View
๐น ๐ก๐ผ๐๐ฒ๐บ๐ฏ๐ฒ๐ฟ ๐ฎ๐ฐ: Meetup | Paris
๐ RSVP & learn more at luma.com/open-lakehouse
#opensource #lakehouse #openlakehouse #ai #deltalake #oss -
Matei Zaharia reposted
Databricks
@databricks
Weโre excited to announce that Databricks has acquired @mooncakelabs to accelerate the vision of Lakebase, a new category of OLTP database built on Postgres and optimized for AI agents!
AI agents are transforming application development, and Lakebase gives developers a single foundation for applications, analytics, and AI โ fully integrated with the Lakehouse and Agent Bricks.
Together, we will build on this innovation, ensuring Postgres data is immediately ready across workloads, without the overhead of ETL pipelines. Please join us in welcoming the team to Databricks! dbricks.co/3IOMj6m -
Matei Zaharia reposted
Dipendra Misra
@DipendraMisra
Our paper showing that with a general-purpose RLVR recipe, we can get SOTA on the BIRD benchmark is out:
www.arxiv.org/pdf/2509.21459
Our hybrid approach performs offline RL and online RL to fine-tune a 32B model. This, along with self-consistency, was sufficient to get us to SOTA. -
Matei Zaharia reposted
Neon
@neondatabase
Postgres 18 is now available on Neon: neon.com/blog/postgres-18
Hereโs a shortlist of whatโs new ๐งต -
Matei Zaharia reposted
Databricks
@databricks
Big news: Databricks and @OpenAI are partnering to deliver powerful AI to the enterprise. OpenAI frontier models will now be available natively in Databricks.
This means you can build, evaluate and scale production-grade AI apps and agents on your governed enterprise data, leveraging the latest OpenAI models like GPT-5.
Weโre excited to expand our relationship with OpenAI; Databricks was one of the first to host gpt-oss open models, they use Databricks products and now weโre offering OpenAI models natively on Databricks: www.databricks.com/blog/run-openai-models-directly-databrโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
-
Matei Zaharia
@matei_zaharia
Prompt optimization is becoming a powerful technique for improving AI that can even beat SFT! Here are some of our research results with GEPA at Databricks, in difficult Agent Bricks info extraction tasks. We can match the best models at 90x lower cost, or improve them by ~6%.
Matei Zaharia
@matei_zaharia
Details and analysis in our research blog: www.databricks.com/blog/building-state-art-enterprise-ageโฆ
Matei Zaharia
@matei_zaharia
Most interestingly perhaps, reflective prompt optimization can beat SFT on the same data, or can stack with it as observed in Better Together (arxiv.org/abs/2407.10930). In practice it also requires fewer labels and can take in richer user feedback (ALHF: www.databricks.com/blog/agent-learning-human-feedback-alhโฆ).
-
Matei Zaharia reposted
Ivan Zhou
@ivanzhouyq
Automated prompt optimization (GEPA) can push open-source models beyond frontier performance on enterprise tasks โ at a fraction of the cost!
๐ Key results from our research @DbrxMosaicAI:
1โฃ gpt-oss-120b + GEPA beats Claude Opus 4.1 on Information Extraction (+2.2 points) โ while being 90ร cheaper to serve.
2โฃ The same technique also lifts frontier models (Claude Sonnet 4, Opus 4.1), pushing them to new SOTA benchmarks.
3โฃVersus Supervised Fine-Tuning (SFT): GEPA delivers equal or better performance at 20% lower serving cost. Even better โ GEPA + SFT together gives the highest gains.
4โฃLifetime cost analysis shows GEPA + gpt-oss is orders of magnitude cheaper overall. At scale, the one-time optimization overhead fades away โ making optimized agents highly practical for real-world deployment.
#dspy #gepa #promptoptimization #airesearch -
Matei Zaharia reposted
Databricks
@databricks
KPMG is using Delta Sharing on Databricks to transform audits. By securely accessing cross cloud data directly in Databricks, @KPMG eliminated data copies and cut query times by 80%.
"Using Delta Sharing has made a noticeable difference to our audit process ... so our audit teams always work from the latest, single source of the truth."
Learn more: www.databricks.com/blog/how-kpmg-uses-delta-sharing-accesโฆ -
Matei Zaharia reposted
Neon
@neondatabase
One of the top features in @Replit and @v0 is the ability to roll back to previous versions and keep iterating.
If youโre building your own agent, we just shipped the Neon snapshots API - the easiest way to add checkpointing + versioning to your platform:This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Melissa Pan
@melissapan
Excited to share: MAST has been accepted as ๐ NeurIPS D&B Spotlight๐
Updates for the community:
- NEW: We open-source 1,000+ multi-agent traces (link in ๐งต).
- lots of exciting use cases are emerging, weโll be releasing blogs & tutorials to help you get started
- And โฆ more surprises are on the way
Huge thanks & congrats to my amazing co-authors. See you all at SD! ๐ซก -
Matei Zaharia reposted
Databricks
@databricks
Weโre looking forward to helping scale the next generation of AI startups.
โWith the new accelerator, Databricks wants to go beyond standard venture capital, offering companies mentorship from its executives, and helping them grow, in some cases, even before the startup has a product out.โ
Read more about our new AI Accelerator Program in @Forbes www.forbes.com/sites/richardnieva/2025/09/17/databricks-sโฆ -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
GEPA is now available in TypeScript through ax (DSPy in TypeScript). Amazing work by @dosco!
spacy
@dosco
latest ax release has the new dspy optimizer gepa, mcp with oauth, and other fixes. github.com/ax-llm/ax/releases/tag/14.0.21
-
Matei Zaharia reposted
Databricks
@databricks
Databricks CEO @alighodsi joined @CNBC to talk about AI adoption, hitting key milestones, data governance, and how new products are powering the next wave of AI innovation.
โWeโre seeing lots of momentum around our AI products, including Agent Bricks, a product that helps you build AI agents in the workplace to automate everyday tasks,โ says Ghodsi. โWeโre seeing a huge uptick in this โ and some of these AI use cases really taking off.โ www.cnbc.com/video/2025/09/08/concerns-around-corporate-dโฆ -
Matei Zaharia
@matei_zaharia
I gave a keynote at @VLDBconf about why we think it's time to rethink OLTP databases with Lakebase, which combines the cloud-native Postgres design of @neondatabase with Lakehouse. Reasons include the cloud, changing demands on DWs to be more real-time, and AI agents. Slides โฌ๏ธ
Matei Zaharia
@matei_zaharia
My presentation: vldb.org/2025/files/keynote/vldb25-keynote3.pdf
-
Matei Zaharia reposted
Databricks
@databricks
The future of data science is autonomous, collaborative, and faster than ever.
That's why we're excited to introduce the Data Science Agent for Databricks Assistant, an autonomous partner that plans, executes, and self-corrects entire workflows in your Notebooks and SQL Editor.
Get:
-End-to-end lifecycle support โ from EDA to feature engineering, model training, and evaluation
-Autonomous multi-step execution with full transparency and control
-Deep Unity Catalog integration for governed, production-ready results
-Native to Databricks Notebooks and SQL Editor for a seamless experience
www.databricks.com/blog/introducing-databricks-assistant-โฆ -
Matei Zaharia reposted
tobi lutke
@tobi
Both DSPy and (especially) GEPA are currently severely under hyped in the AI context engineering world
-
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
We removed all upfront fees for SOC 2, Private Networking, and now HIPAA. It's all on the new Scale plan.
You can build HIPAA-compliant from day zero for 100x less. Start at $5.99 not $599! -
Matei Zaharia reposted
Databricks
@databricks
Now GA: Share Materialized Views and Streaming Tables with Delta Sharing!
GA introduces new capabilities:
- Providers can now share views created from MV/STs
- Recipients can create views on top of shared MV/STs
- Recipients can easily build their own data pipelines on top of shared MV/STs
Learn how customers like @Reltio are using this to eliminate redundant pipelines and deliver trusted, insight-ready data instantly: www.databricks.com/blog/now-ga-share-materialized-views-aโฆ -
Matei Zaharia reposted
Aditya Parameswaran
@adityagp
New research agenda we're kickstarting at Berkeley: redesigning data systems to serve the dominant workload of the future: agents!
Agentic speculation is massive, heterogeneous, steerable, and redundant: properties data systems can better support and take advantage of.
Take a look: arxiv.org/abs/2509.00997 -
Matei Zaharia reposted
Shiyi Cao
@shiyi_c98
An amazing collaboration with the Biomni team! We introduce Biomni-R0, a reasoning-enabled multi-task multi-tool biomedical research agent, trained through end-to-end RL. The results are impressive -- 2x stronger than the base model and >10% better than GPT 5 and Claude 4 Sonnet!
The biomedical environment is far more complicated than our previous SWE/Text-to-SQL training, consisting of a large set of tools and diverse tasks, and we've observed interesting challenges such as tool retrieval, context management, and coordinating complex reasoning across tasks and tools.
Thrilled to see how end-to-end RL continues to push performance, and stay tuned for more results!
Kudos to @RyanLi0802 @KexinHuang5 @shiyi_c98 @YuanhaoQ @jure!
Kexin Huang
@KexinHuang5
๐ Thrilled to share a preview of Biomni-R0 โ we trained the first RL agent end-to-end for biomedical research.
โก๏ธ nearly 2ร stronger than its open-source base
โก๏ธ >10% better than frontier closed-source models
โก๏ธ Scalable path to hill climb to expert-level performance
๐ Technical report: biomni.stanford.edu/blog/biomni-r0-technical-report
Collab between @ProjectBiomni and SkyRL @NovaSkyAI, with the amazing @RyanLi0802 @shiyi_c98 @YuanhaoQ @jure.
Open-sourcing soon! -
Matei Zaharia reposted
Tyler Griggs
@tyler_griggs_
Very cool to see SkyRL powering research in biomedicine! Unsurprisingly, one of key implementation challenges was env scaling, a common theme
Kudos to the Biomni team and @shiyi_c98
Kexin Huang
@KexinHuang5
๐ Thrilled to share a preview of Biomni-R0 โ we trained the first RL agent end-to-end for biomedical research.
โก๏ธ nearly 2ร stronger than its open-source base
โก๏ธ >10% better than frontier closed-source models
โก๏ธ Scalable path to hill climb to expert-level performance
๐ Technical report: biomni.stanford.edu/blog/biomni-r0-technical-report
Collab between @ProjectBiomni and SkyRL @NovaSkyAI, with the amazing @RyanLi0802 @shiyi_c98 @YuanhaoQ @jure.
Open-sourcing soon! -
Matei Zaharia reposted
Databricks
@databricks
We're excited to share that Delta Sharing: An Open Protocol for Cross-Platform Data Sharing was named Best Paper Industry Runner-Up at #vldb2025! www.vldb.org/pvldb/vol18/p5197-puttaswamy.pdf
Catch @matei_zaharia's keynote Thurs (9:15โ10:15 BST) and visit our booth or Careers Site for more information on our open roles across databases and distributed systems: www.databricks.com/company/careers/open-positions?departmโฆ -
Matei Zaharia
@matei_zaharia
Lakebase makes it easy to build stateful operational apps over your data with the full power of Postgres and @neondatabase! It's super easy to get started and directly integrates with your data security controls.
Databricks
@databricks
Building apps on Databricks just got a lot easier! ๐๏ธ Learn how Lakebase can serve as the transactional data layer for Databricks Apps.
- Unified stack: Build apps on top of data in your lakehouse with Databricks Apps + Lakebase
- Secure & serverless: Native auth, governance, and access controls included
- Practical guide: Walkthrough the setup of building an App
www.databricks.com/blog/how-use-lakebase-transactional-daโฆ -
Matei Zaharia reposted
Liana
@lianapatel_
Interested in building and benchmarking deep research systems?
Excited to introduce DeepScholar-Bench, a live benchmark for generative research synthesis, from our team at Stanford and Berkeley!
๐Live Leaderboard guestrin-lab.github.io/deepscholar-leaderboard/leaderboarโฆ
๐ Paper: arxiv.org/abs/2508.20033
๐ ๏ธ Code: github.com/guestrin-lab/deepscholar-bench
๐งต๐ -
Matei Zaharia reposted
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
๐ฅณ๐คฉExcited to share the outcome of my first project as a postdoc at Sky Lab, a Stanford + Berkeley collaboration!
Weโre introducing DeepScholar-Bench, a live benchmark for generative research synthesis.
๐Paper: arxiv.org/abs/2508.20033
๐ ๏ธ Code: github.com/guestrin-lab/deepscholar-bench
Liana
@lianapatel_
Interested in building and benchmarking deep research systems?
Excited to introduce DeepScholar-Bench, a live benchmark for generative research synthesis, from our team at Stanford and Berkeley!
๐Live Leaderboard guestrin-lab.github.io/deepscholar-leaderboard/leaderboarโฆ
๐ Paper: arxiv.org/abs/2508.20033
๐ ๏ธ Code: github.com/guestrin-lab/deepscholar-bench
๐งต๐ -
Matei Zaharia reposted
Jared Quincy Davis
@jaredq_
If you're running agents in production, consider taking this brief survey.
In a collaboration spanning researchers from @UCBerkeley, @IBMResearch , @StanfordAILab, @UofIllinois , @intesasanpaolo, and moreโwith participants from leading banks, telecoms, agent startups, and frontier labsโwe're working to understand the challenges of building and deploying agents.
The survey takes ~5 minutes! Link in the next tweet. We look forward to sharing the results. -
Matei Zaharia
@matei_zaharia
If you're running agents in production, consider taking this short survey from my research group!
We're collaborating with IBM, Stanford, UIUC, Intesa Sanpaolo and others to better understand the challenges in building agents. It only takes 5 minutes: agents-survey.github.io/AI-Agent-Survey/participate/ -
Matei Zaharia
@matei_zaharia
Really cool -- looks like system design and prompts can have more impact than foundation model weight training past some point.
Lin Yang
@lyang36
Our IMO gold medal-winning AI pipeline is now model-agnostic. ๐ฅ
What worked for Gemini 2.5 Pro now gets the same 5/6 score with GPT-5 & Grok4. This confirms the power of our verification-and-refinement pipeline to improve base model capabilities.
The new code & results are live on GitHub[github.com/lyang36/IMO25]! Paper update coming soon.
Huge thanks to @xai for the Grok4 API credits! #ai #llm #imo #matholympiad #opensourceโ -
Matei Zaharia reposted
Databricks
@databricks
We're excited to share that @TectonAI will soon join Databricks, providing enterprises with fast, reliable, real-time data for deploying AI agents.
Tectonโs technology helps enterprises leverage their mission-critical data to power AI agents for critical use cases.
Bringing Tecton into Databricks will unite the best in online data serving with Databricksโ Agent Bricks, empowering customers to build, deploy and scale AI agents faster and more confidently than ever before.
We're excited to see what you build. www.databricks.com/blog/tecton-joining-databricks-power-rโฆ -
Matei Zaharia reposted
Databricks
@databricks
Databricks DevConnect brings together data practitioners, AI innovators, and developers for technical deep dives, real-world insights, and community connection ๐ค
Join us for live demos, thought-provoking discussions on data engineering and AI, and pushing the boundaries of whatโs possible with Databricks. lu.ma/DevConnectDBX?k=c -
Matei Zaharia
@matei_zaharia
Lakebase makes it super easy to serve your data in operational apps by automating Reverse ETL. Just create a synched table from your lakehouse, no need to write or babysit any infra. This is all available today on Databricks; try it out! www.databricks.com/blog/reverse-etl-lakebase-activate-youโฆ
-
Matei Zaharia
@matei_zaharia
Real-time mode for Apache Spark streaming is now in public preview on Databricks, and it's so simple to use! Just change a config and get super low latency with the same API. www.databricks.com/blog/introducing-real-time-mode-apacheโฆ
-
Matei Zaharia reposted
Databricks
@databricks
Our co-founder and CEO @alighodsi joined @CNBC's Power Lunch to discuss our Series K funding round, and how weโre powering agentic AI innovation.
โOur focus is helping organizations build agents that are actually useful and solve the day-to-day tasks organizations are facing,โ said Ghodsi. Watch the full interview: www.cnbc.com/video/2025/08/19/databricks-ceo-on-ai-vcs-arโฆ -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Databricks just signed a Series K term sheet at >$100B valuation to scale two flagship products:
๐ฅ Lakebase โ serverless Postgres with true compute/storage separation
๐ง Agent Bricks โ agentic framework with built-in reasoning guardrails for enterprise data
www.wsj.com/tech/ai/databricks-raising-funds-at-100-billiโฆ -
Matei Zaharia reposted
Andrew Drozdov
@mrdrozdov
We built a thing! The Databricks Reranker is now in Public Preview. It's as easy as changing the arguments to your vector search call, and doesn't require any additional setup.
Read more: www.databricks.com/blog/reranking-mosaic-ai-vector-searchโฆ -
Matei Zaharia reposted
VentureBeat
@VentureBeat
GEPA optimizes LLMs without costly reinforcement learning venturebeat.com/ai/gepa-optimizes-llms-without-costly-reiโฆ
-
Matei Zaharia
@matei_zaharia
Try out GEPA! Excited to see how it does on people's problems.
Lakshya A Agrawal
@LakshyAAAgrawal
Very excited to share that GEPA is now live on @DSPyOSS as dspy.GEPA!
This is an early code release. Weโre looking forward to community feedback, especially about any practical challenges in switching optimizers. -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
Very excited to share that GEPA is now live on @DSPyOSS as dspy.GEPA!
This is an early code release. Weโre looking forward to community feedback, especially about any practical challenges in switching optimizers. -
Matei Zaharia reposted
Josue Bogran
@joshbogran
My interview with @databricks CTO, @matei_zaharia, at the Databricks Data + AI Summit.
Topic? What AI capabilities are proving to work right now for businesses.
Link: youtu.be/OLv-Kk4xoI4 -
Matei Zaharia reposted
MLflow
@MLflow
MLflow 3.3 introduces an assessment-first approach to GenAI evaluation workflows. Assessmentsโquality evaluations and trace annotationsโare now integrated directly into the tracing UI, making it easier to create, view, and manage them throughout the application lifecycle.
New features include:
๐น A redesigned trace viewer with CRUD operations for assessments, accessible in the detail view.
๐น The Traces tab updated to display assessment metrics and visual indicators for status/quality scores.
๐น Filtering and sorting by assessment values and other attributes to help monitor and diagnose app performance.
Dive into our latest blog for more! โก๏ธ mlflow.org/blog/mlflow-assessment-ui
#opensource #oss #mlflow #genai -
Matei Zaharia reposted
Alex Dimakis
@AlexGDimakis
Imagine you're trying to teach a human how to do a task, say install Windows XP in a virtual machine. The human walks into a room and sees a document (prompt) that you have written, that describes exactly what they are supposed to do. There is also a computer ready for their keyboard inputs.
Then, they try for a while, and suppose they fail. Then, you write some detailed notes and new additional instructions in the prompt document, based on how they failed trying to teach them how to do the task.
But then, A NEW PERSON walks in and tries to solve the task. Every day, it's a fresh new employee and you can only update the document.
This Memento-like experience is how most companies are currently trying to train agents, by writing prompts (Multi-agent systems usually means multiple prompts) and is not going to lead to AGI.
But no wait, you should say, there is Reinforcement Learning post-training, this is the path to AGI, nicely summarized in the recent paper "The Era of Experience" by Silver and Sutton. With RL, the agent will try to solve the task and we will update their brain weights to increase the probability of good rollouts (successful attempts to install Windows) and decrease the probability of failed rollouts. This is good, but imagine trying to teach a human how to install Windows with this tormenting process: leaving them alone in a room, letting them bang their head into a wall and only when they manage to install Windows, update their brain weights a tiny bit. If they keep messing up, there will be no reward, no gradient and no learning. That is why agents must be post-trained with SFT first (basically observe other people solving the task end-to-end) and only after they can solve task 1 out of 10 times, RL can be deployed. You cannot talk to them during the process, you cannot give them verbal feedback on what error they made, they cannot think why they failed etc. One good signal that this process is sub-optimal is that RL trained agents keep getting GRPO gradients after re-solving the same math problem thousands of times, which shows that GRPO is extremely sample inefficient, compared to how humans learn.
Dwarkesh has a recent video "Why I don't think AGI is right around the corner".
He says that this lack of continual learning is showing that we lack a fundamental idea to reach human-level performance. He describes an example similar to mine but with teaching a kid to play the saxophone, while I set an arguably lower bar(?) of installing Windows.
Dwarkesh says "The reason humans are so useful is not mainly their raw intellect, its their ability to build up context, interrogate their own failures and to pick up small improvements as they practice a task."
I would summarize the challenge as follows: Right now, there is no established RL algorithm to give a model verbal feedback and have it update it's weights. There is also no established algorithm for a model to reflect on a previous failed execution and update it's own weights.
There are several methods (e.g. TextGrad, Reflexion, ALHF from Databricks and the now well-known GEPA) that update PROMPTS or create 'lessons learned' or memory summaries which are inserted into the prompt context, but this is still like a fresh new student walks in every day and things that cannot be explicitly verbalized cannot be learned.
On updating weights from feedback and reflection, there is significant on-going research e.g. I recently saw "Natural Language Reinforcement Learning (NLRL)" by Feng et al. and I'd love to get more pointers. I think that indeed we are entering the era of experience and we will need to find new algorithmic ideas before agents can learn as efficiently as humans. -
Matei Zaharia reposted
Neon
@neondatabase
app.build, our open-source reference architecture for agent building, now supports open weights LLMs via @ollama , @lmstudio , and @openrouter
Run it locally: neon.com/blog/app-build-supports-open-source-models-locally -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
Well, in the most lowkey way possible, and on a random Tue afternoon, @DSPyOSS 3.0 is out of beta.
pip install -U dspy
So many amazing people contributed to this. Thank you all!
(Release notes below. Stay tuned for a ton of stuff over the next few weeks!!) -
Matei Zaharia reposted
Alex Trott
@alexrtrott
Ever wonder what it'd look like if an LLM Judge and a Reward Model had a baby? So did we, which is why we created PGRM -- the Prompt-Guided Reward Model.
TLDR: You get the instructability of an LLM judge + the calibration of an RM in a single speedy package (1/n) -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
Not that I have a favorite recent project, but... ๐งต LLM judges are the popular way to evaluate generative models. But they have drawbacks. They're:
* Generative, so slow and expensive.
* Nondeterministic.
* Uncalibrated. They don't know how uncertain they are.
Meet PGRM!
Alex Trott
@alexrtrott
Ever wonder what it'd look like if an LLM Judge and a Reward Model had a baby? So did we, which is why we created PGRM -- the Prompt-Guided Reward Model.
TLDR: You get the instructability of an LLM judge + the calibration of an RM in a single speedy package (1/n) -
Matei Zaharia reposted
MLflow
@MLflow
At Agents in Production 2025, Yuki Watanabe presented ๐๐ท๐ข๐ญ๐ถ๐ข๐ต๐ช๐ฐ๐ฏ-๐๐ณ๐ช๐ท๐ฆ๐ฏ ๐๐ฆ๐ท๐ฆ๐ญ๐ฐ๐ฑ๐ฎ๐ฆ๐ฏ๐ต ๐ธ๐ช๐ต๐ฉ ๐๐๐ง๐ญ๐ฐ๐ธ 3.0 โ a process that uses evaluation as the foundation for building high-quality, reliable Agentic systems.
The talk showed how #mlflow 3.0 supports this approach with:
๐ธ One-line observability
๐ธ Automatic evaluation
๐ธ Human-in-the-loop feedback loops
๐ธ Monitoring for ongoing reliability
๐ฅ Watch the full presentation: www.youtube.com/watch?v=7Q2Z9CYvdRc
#opensource #oss #aiagents #agentic #llm #mlops -
Matei Zaharia reposted
Yichuan Wang
@YichuanM
1/N ๐ Launching LEANN โ the tiniest vector index on Earth!
Fast, accurate, and 100% private RAG on your MacBook.
0% internet. 97% smaller. Semantic search on everything.
Your personal Jarvis, ready to dive into your emails, chats, and more.
๐ Code: github.com/yichuan-w/LEANN
๐ Paper: arxiv.org/abs/2506.08276
๐ Thread on why it matters: -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
Even if AI progress suddenly halted today (it hasn't and won't), we will still see a decade of extraordinary technological progress as we figure out how to build reliable, useful software out of this incredible new material. The future is bright.
-
Matei Zaharia reposted
Databricks
@databricks
You can get started with @OpenAI's GPT-5 model today on Databricks with AI Gateway! GPT-5 unlocks new frontiers in reasoning, multimodal understanding, and task execution โ we canโt wait to see what our customers build.
Weโre thrilled to support this incredible week of innovation from OpenAI. www.databricks.com/blog/build-gpt-5-databricks-ai-gateway -
Matei Zaharia reposted
Dilara Soylu
@dilarafsoylu
Should you RL your compound AI system or optimize its prompts? We think both! ๐คฏ
A short preview of work co-led with @NoahZiems and @LakshyAAAgrawal!๐ -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
This was a really fun collab during my time at @databricks !! Itโs basically a product answer to the fact that:
(1) People want to optimize their agents and to specialize them for downstream preferences (no free lunch!)
(2) People donโt have upfront training setsโor even upfront specs! No one is motivated enough to label good data.
(3) Downstream users viscerally and immediately know what bothered them when they see a bad response.
So, you meet the users where they areโhaving them tell you what upset them about agent responses, and have the agent learn from that over time. They learn fast too.
Matei Zaharia
@matei_zaharia
Really excited about ALHF, new work from our research team that lets users give natural language feedback to agents and optimizes them for it. It sort of upends the traditional supervision paradigm where you get a scalar reward, and it makes AI more customizable for non-experts.
-
Matei Zaharia
@matei_zaharia
Really excited about ALHF, new work from our research team that lets users give natural language feedback to agents and optimizes them for it. It sort of upends the traditional supervision paradigm where you get a scalar reward, and it makes AI more customizable for non-experts.
Matei Zaharia
@matei_zaharia
With ALHF, subject matter experts (not ML experts) can review conversations after the fact and give text feedback. We then incorporate it into the agent using retrieval, summarization or other methods. This reliably increases quality on future conversations.
Matei Zaharia
@matei_zaharia
As models get smarter at following instructions, this becomes a natural paradigm for tuning AI systems. Read more about our experience with it in our blog: www.databricks.com/blog/agent-learning-human-feedback-alhโฆ
-
Matei Zaharia reposted
Michael Bendersky
@bemikelive
Since joining @databricks, our research team has been hard at work on Agent Bricks, a new product that helps enterprises develop state-of-the-art domain-specific agents. We are now releasing a research blog about Agent Learning from Human Feedback (ALHF) www.databricks.com/blog/agent-learning-human-feedback-alhโฆ
-
Matei Zaharia reposted
Databricks
@databricks
Weโre excited to partner with @OpenAI to launch their new open source models natively on Databricks!
gpt-oss sets a new standard of quality for open language models, supporting advanced reasoning with the transparency, flexibility and control enterprises need. Running on Databricks, the gpt-oss models connect securely to your data and scale with built-in governance, and expand what you can build and do with GenAI.
Try both the 20B and 120B today in the Mosaic AI Playground. www.databricks.com/blog/introducing-openais-new-open-modeโฆ -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
RLVR and test-time compute are a powerful combo for enterprises, so much so that @databricks now leads overall BIRD single-model leaderboard. This isn't about BIRD, though. It's an example of what our customers are accomplishing in their domains with our RL recipe in Agent Bricks
Jonathan Frankle
@jefrankle
RLVR isn't just for math and coding! At @databricks, it's impacting products and users across domains. One example: SQL Q&A. We hit the top of the BIRD single-model single-generation leaderboard with our standard TAO+RLVR recipe - the one rolling out in our Agent Bricks product.
-
Matei Zaharia
@matei_zaharia
RT @MLflow: MLflow 3.2 is here! ๐
Key updates include:
๐น ๐ง๐๐ฝ๐ฒ๐ฆ๐ฐ๐ฟ๐ถ๐ฝ๐ ๐ฆ๐๐ ๐ณ๐ผ๐ฟ ๐ง๐ฟ๐ฎ๐ฐ๐ถ๐ป๐ด: Add MLflow tracing to TypeScript GenAI apps and captโฆ -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
If you build a new agentic codegen system and in need of a backend this repo had a full reference architecture for it.
Neon
@neondatabase
app.build has a brand new web UI ๐
We built app.build as a reference architecture for agentic codegen. 100% open source, supports React, Laravel, FastAPI tech stacks.
GitHub below -
Matei Zaharia reposted
Dawn Song
@dawnsongtweets
Really excited for the Agentic AI Summit 2025 at @UCBerkeleyโ2K+ in-person attendees and ~10K online! Building on our 25K+ LLM Agents MOOC community, this is the premier global forum for advancing #agenticai.
๐ Livestream starts at 9:15 AM PT on August 2โtune in! -
Matei Zaharia reposted
MLflow
@MLflow
Today, we're thrilled to introduce theย MLflow TypeScript SDK, bringing the industry-leading observability capabilities of MLflow directly to your TypeScript and JavaScript applications!ย ๐
The SDK enables:
โ Automatic tracing of #llm and AI API calls
โ Manual instrumentation for custom code and workflows
โ OpenTelemetry-based standards for exporting and integrating trace data
โ Integration with any MLflow Tracking Server (local or cloud-managed)
โ Human feedback collection and evaluation tools
You can find hands-on guides, code snippets, and setup tips in the full blog post. ๐
๐ Dive in:ย mlflow.org/blog/mlflow-typescript
#opensource #oss #mlflow #typescript -
Matei Zaharia reposted
DSPy
@DSPyOSS
Our latest optimizer GEPA writes beautiful prompts, even with a โminiโ model. Stay tuned for a lot more these coming days.
Lakshya A Agrawal
@LakshyAAAgrawal
We implemented GEPA as a new @DSPyOSS optimizer (release soon!). This means that it works for even sophisticated agents or compound systems you've already implemented.
GEPA outperforms the MIPROv2 optimizer by as much as 11% across 4 tasks for Qwen3 and GPT-4.1-mini.
Of course: Weight updates remain necessary to teach the models completely new tasks and still excel at general-purpose (massively multi-task!) post-training!
However, we show that for specialization to downstream systems, reflective prompt optimization can go really far with tiny data sizes and rollout budgets!
(2/n) -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
RLVR isn't just for math and coding! At @databricks, it's impacting products and users across domains. One example: SQL Q&A. We hit the top of the BIRD single-model single-generation leaderboard with our standard TAO+RLVR recipe - the one rolling out in our Agent Bricks product.
-
Matei Zaharia reposted
Omar Khattab
@lateinteraction
New paper: Reflective Prompt Evolution Can Outperform GRPO.
It's becoming clear that learning via natural-language reflection (aka prompt optimization) will long be a central learning paradigm for building AI systems.
Great work by @LakshyAAAgrawal and team on GEPA and SIMBA.
Lakshya A Agrawal
@LakshyAAAgrawal
How does prompt optimization compare to RL algos like GRPO?
GRPO needs 1000s of rollouts, but humans can learn from a few trialsโby reflecting on what worked & what didn't.
Meet GEPA: a reflective prompt optimizer that can outperform GRPO by up to 20% with 35x fewer rollouts!๐งต -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
How does prompt optimization compare to RL algos like GRPO?
GRPO needs 1000s of rollouts, but humans can learn from a few trialsโby reflecting on what worked & what didn't.
Meet GEPA: a reflective prompt optimizer that can outperform GRPO by up to 20% with 35x fewer rollouts!๐งต -
Matei Zaharia
@matei_zaharia
AI progress is hardest in tasks where feedback is slow, so I'm super excited about this work to learn faster using reflective prompt updates!
In just 1 rollout, a reflective optimizer can make a natural language update to a prompt that greatly boosts perf, unlike RL on weights.
Lakshya A Agrawal
@LakshyAAAgrawal
How does prompt optimization compare to RL algos like GRPO?
GRPO needs 1000s of rollouts, but humans can learn from a few trialsโby reflecting on what worked & what didn't.
Meet GEPA: a reflective prompt optimizer that can outperform GRPO by up to 20% with 35x fewer rollouts!๐งต -
Matei Zaharia reposted
Liana
@lianapatel_
Curious to understand system prompts from sota LLM systems, like the one that allowed Gemini 2.5 Pro to solve IMO 2025 problems?
@AnkitaSundar analyzed ~100 leaked system prompts systematically using LLM-powered data analysis with LOTUS.
๐ Check out her awesome collab demo colab.research.google.com/drive/1NSVQYOMp2GCre5ZRgvgs6BPGโฆ
A lot of cool insights, and a great walkthrough of getting started with LOTUS for llm-powered data analysis over your own text / document datasets. -
Matei Zaharia reposted
Michael Bendersky
@bemikelive
This is a good opportunity to announce that I recently joined the research team at @databricks where I will be working alongside @jefrankle @rishabhs @matei_zaharia Erich Elsen, and many others on the hardest problems at the intersection of information retrieval and AI.
Jonathan Frankle
@jefrankle
I'm at ICML ๐จ๐ฆ and I'm hiring at @databricks. Visit our booth if you're interested. My scientific focus: It's 1972 in AI, there's an AI crisis, Dijkstra isn't here to save us, and maybe RL can. Why Databricks? The long road to AGI is being paved here and we have the real evals ๐งต
-
Matei Zaharia reposted
NovaSky
@NovaSkyAI
The SkyRL roadmap is live!
Our focus is on building the easiest-to-use high-performance RL framework for agents.
We'd love your ideas, feedback, or code to guide the project: github.com/NovaSky-AI/SkyRL/issues/83 -
Matei Zaharia reposted
Wen Sun
@WenSun1
Does RL actually learn positively under random rewards when optimizing Qwen on MATH? Is Qwen really that magical such that even RLing on random rewards can make it reason better?
Following prior work on spurious rewards on RL, we ablated algorithms. It turns out that if you deploy algorithms like Reinforce and REBEL (a generalization of Natural Policy Gradient), RL does not learn under random rewards. These two simple algorithms simply behave as we would expect in this case.
GRPO and PPO indeed can behave strangely. They can learn positively or negatively, depending on different random seeds. The clipping heuristic introduces certain bias in the objective function, which causes such unexpected behaviors (this even happens in bandit which has nothing to do w/ LLM or reasoning). Perhaps it is time to abandon the clipping heuristic...
Gokul Swamy
@g_k_swamy
Recent work has seemed somewhat magical: how can RL with *random* rewards make LLMs reason? We pull back the curtain on these claims and find out this unexpected behavior hinges on the inclusion of certain *heuristics* in the RL algorithm. Our blog post: fuchsia-arch-d8e.notion.site/Heuristics-Considered-Harmfuโฆ
-
Matei Zaharia
@matei_zaharia
We're finding that what's needed in RL for enterprise tasks is pretty different than in foundation model training on math, code, etc. Catch @jefrankle and our team at ICML to talk about these problems!
Jonathan Frankle
@jefrankle
Properties of our problems:
* Semi-verifiability. Can LLM judges productively augment RLVR? How clean must they be?
* Intermediate rewards. Signals we can exploit to make harder tasks tractable.
* Real traces. Tons of human traces for imitation learning or environment building. -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
I'm at ICML ๐จ๐ฆ and I'm hiring at @databricks. Visit our booth if you're interested. My scientific focus: It's 1972 in AI, there's an AI crisis, Dijkstra isn't here to save us, and maybe RL can. Why Databricks? The long road to AGI is being paved here and we have the real evals ๐งต
-
Matei Zaharia reposted
Omar Khattab
@lateinteraction
The #sigir2025 Best Paper just awarded to the WARP engine for fast late interaction!
Congrats to Luca Scheerer๐ WARP was his @ETH_en MS thesis, completed while visiting us at @StanfordNLP.
Incidentally, it's the fifth Paper Award for a ColBERT paper since 2020!*
Luca did an incredible job leading and executing this. See the thread below for some relevant links.
*Though it's notable that this is actually the first among these awards with ColBERT(v1/v2) authors๐ ๐
Omar Khattab
@lateinteraction
๐ข If youโre at #sigir2025 this week, make sure to be at Luca Scheererโs paper talk:
โWARP: An Efficient Engine for Multi-Vector Retrievalโ (Wednesday 11am)
WARP makes PLAID, the famous ludicrously fast ColBERT engine, another 3x faster on CPUs.
With the usual ColBERT quality! -
Matei Zaharia reposted
Negar Arabzadeh โ๏ธ EMNLP2026
@NegarEmpr
Come find me at the poster session now at #sigir2025! Letโs chat about LLM-based relevance judgments! @SIGIRConf
-
Matei Zaharia reposted
DSPy
@DSPyOSS
Yes, this is a description of how the dspy.SIMBA optimizer works.
> a review/reflect stage along the lines of "what went well? what didn't go so well? what should I try next time?" etc. and the lessons from this stage feel explicit, like a new string to be added to the system prompt for the future, optionally to be distilled into weights (/intuition) later a bit like sleep.
Distilling through the weights is the dspy.BetterTogether strategy.
Andrej Karpathy
@karpathy
Scaling up RL is all the rage right now, I had a chat with a friend about it yesterday. I'm fairly certain RL will continue to yield more intermediate gains, but I also don't expect it to be the full story. RL is basically "hey this happened to go well (/poorly), let me slightly increase (/decrease) the probability of every action I took for the future". You get a lot more leverage from verifier functions than explicit supervision, this is great. But first, it looks suspicious asymptotically - once the tasks grow to be minutes/hours of interaction long, you're really going to do all that work just to learn a single scalar outcome at the very end, to directly weight the gradient? Beyond asymptotics and second, this doesn't feel like the human mechanism of improvement for majority of intelligence tasks. There's significantly more bits of supervision we extract per rollout via a review/reflect stage along the lines of "what went well? what didn't go so well? what should I try next time?" etc. and the lessons from this stage feel explicit, like a new string to be added to the system prompt for the future, optionally to be distilled into weights (/intuition) later a bit like sleep. In English, we say something becomes "second nature" via this process, and we're missing learning paradigms like this. The new Memory feature is maybe a primordial version of this in ChatGPT, though it is only used for customization not problem solving. Notice that there is no equivalent of this for e.g. Atari RL because there are no LLMs and no in-context learning in those domains.
Example algorithm: given a task, do a few rollouts, stuff them all into one context window (along with the reward in each case), use a meta-prompt to review/reflect on what went well or not to obtain string "lesson", to be added to system prompt (or more generally modify the current lessons database). Many blanks to fill in, many tweaks possible, not obvious.
Example of lesson: we know LLMs can't super easily see letters due to tokenization and can't super easily count inside the residual stream, hence 'r' in 'strawberry' being famously difficult. Claude system prompt had a "quick fix" patch - a string was added along the lines of "If the user asks you to count letters, first separate them by commas and increment an explicit counter each time and do the task like that". This string is the "lesson", explicitly instructing the model how to complete the counting task, except the question is how this might fall out from agentic practice, instead of it being hard-coded by an engineer, how can this be generalized, and how lessons can be distilled over time to not bloat context windows indefinitely.
TLDR: RL will lead to more gains because when done well, it is a lot more leveraged, bitter-lesson-pilled, and superior to SFT. It doesn't feel like the full story, especially as rollout lengths continue to expand. There are more S curves to find beyond, possibly specific to LLMs and without analogues in game/robotics-like environments, which is exciting. -
Matei Zaharia reposted
Liana
@lianapatel_
Awesome read on Lucene's implementation of ACORN-1๐ฅ๐ฅ
Filtered vector search is everywhere! Efficient, general-purpose (predicate-agnostic) indices that can support those use cases are super, super powerful!!
Try it out & check out our original paper dl.acm.org/doi/10.1145/3654923
Doug Turnbull
@softwaredoug
Elasticsearch / Lucene adopts ACORN-1, which expands the exploration of nodes to ensure enough candidates that meet the filter By @benwtrent
www.elastic.co/search-labs/blog/filtered-hnsw-knn-search -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Separation of storage and compute doesn't sacrifice database performance. You can have both elasticity AND performance:
neon.com/blog/separation-of-storage-and-compute-perf -
Matei Zaharia reposted
NovaSky
@NovaSkyAI
๐ SkyRL + Search-R1
Training a multi-turn search agent doesnโt have to be complicated.
With SkyRL, reproducing the SearchR1 recipe at high training throughput is quick and easy! We wrote up a detailed guide to show you how:
novasky-ai.notion.site/skyrl-searchr1
1/N ๐งต -
Matei Zaharia reposted
Pratiksha Thaker
@prthaker_
I'm very excited to share some new work arxiv.org/abs/2506.06488. This work started out in conversations with @thorn where we realized that shadow model MIAs couldn't be used to audit models for harmful content of children. See ๐งต for why, and our progress on solving this...
-
Matei Zaharia reposted
Daniel Kang
@ddkang
As AI agents near real-world use, how do we know what they can actually do? Reliable benchmarks are critical but agentic benchmarks are broken!
Example: WebArena marks "45+8 minutes" on a duration calculation task as correct (real answer: "63 minutes"). Other benchmarks misestimate agent competence by 1.6-100%.
Why are the evaluation foundations for agentic systems fragile? See below for thread and links
1/8 -
Matei Zaharia reposted
Ivan Zhou
@ivanzhouyq
I will be atย #icml next week! It'll be great to catch up with friends, old and new.
Happy to chat about our work onย Data + AI atย @DbrxMosaicAI. We're growing our team and have openings forย researchers and engineers in areas such as document intelligence, knowledge assistant, data reasoning, reinforcement learning, and training/inference efficiency, etc. Feel free to reach out if you'd like to connect! -
Matei Zaharia reposted
Nikhil Thorat
@nsthorat
We just published a Databricks App template that shows how to:
- Deploy a LangGraph agent asa Databricks app with a chat UI
- Automatically monitor MLflow 3.0 traces on Databricks (including syncing to delta tables, with Unity Catalog governance of traces)
I've also embedded my favorite OSS stack in this repo, uv, bun, shadcn, etc. Poke around :)
Now this is June 2025 so this repo has an opinionated Claude memory file where I have some of my favorite tricks:
3 self-verificatication loops:
1) running the devserver in the background to see python logs
2) opening playwright so that claude can take screenshots of the UI as you develop
3) deploying the app to databricks and then checking the service logs for any installation issues.
The verification loops are the most important way to get claude to turn that automation slider up. -
Matei Zaharia reposted
Neon
@neondatabase
If you are:
- An early-stage startup
- Have raised up to $5M in venture funding
- And are using Postgres,
Apply to our Startup Program and get up to $100k in credits: neon.com/startups -
Matei Zaharia reposted
NovaSky
@NovaSkyAI
โจRelease: We upgraded SkyRL into a highly-modular, performant RL framework for training LLMs. We prioritized modularityโeasily prototype new algorithms, environments, and training logic with minimal overhead.
๐งต๐
Blog: novasky-ai.notion.site/skyrl-v01
Code: github.com/NovaSky-AI/SkyRL -
Matei Zaharia reposted
uccl_project
@uccl_proj
1/N ๐ข Introducing UCCL (Ultra & Unified CCL), an efficient collective communication library for ML training and inference, outperforming NCCL by up to 2.5x ๐
Code: github.com/uccl-project/uccl
Blog: uccl-project.github.io/posts/about-uccl
Results: AllReduce on 6 HGX across 2 racks over RoCE RDMA -
Matei Zaharia reposted
tobi lutke
@tobi
DSPy is my context engineering tool of choice
-
Matei Zaharia reposted
Reynold Xin
@rxin
This is a pretty good article on how we are rethinking OLTP databases with Lakebase!
The New Stack
@thenewstack
Are OLTP databases due for a radical rethink? @AlexWilliams reports from the @Databricks Data + AI Summit, where @rxin made the case for decoupling compute and storage in Postgres โ treating data more like code.
thenewstack.io/new-oltp-postgres-with-separate-compute-anโฆ -
Matei Zaharia
@matei_zaharia
Unified governance is increasingly a requirement for data and AI platforms, but how do you design a system for it that covers diverse asset types and scales? Our team is presenting Unity Catalog at #sigmod2025 this week, discussing 4+ years of experience at 1000s of customers.
Matei Zaharia
@matei_zaharia
Drop by to meet our team at SIGMOD, or check out the full paper: dl.acm.org/doi/abs/10.1145/3722212.3724459
-
Matei Zaharia reposted
Andy Konwinski
@andykonwinski
Today, Iโm launching a deeply personal project. Iโm betting $100M that we can help computer scientists create more upside impact for humanity.
Built for and by researchers, including @JeffDean & @jpineau1 on the board, @LaudeInstitute catalyzes research with real-world impact. -
Matei Zaharia reposted
Lionel Montrieux
@LionelMontrieux
SIGMOD is happening (almost) in my back garden this year so I'll be there next week. We have a paper presenting our work on @databricks Lakeguard, come say hi! And if you're a talented engineer... we're hiring ๐
-
Matei Zaharia reposted
Omar Khattab
@lateinteraction
Calling learning natural-language rules โnot real learningโ is so backwards.
Interacting with an environment to generate abstract hypotheses and turn them into actionable natural-language rules is as โlearningโ as the wordโs natural connotations get.
Though gradient-based learning is obviously deeply fundamental and essential, itโs undeniable that calling fitting a differentiable function to data โlearningโ actually involves moreโnot lessโdeviation from the raw connotations of the term.
And in the long run, both are absolutely essential. Theyโre just learning at vastly different levels of abstraction.
Xin Eric Wang
@xwang_lk
A few years ago, people dismissed fine-tuning: โYouโre just tweaking a trained modelโthatโs incremental.โ Now they say the same about prompt learning. Before that, they dismissed model training itself. Funny how every learning paradigm shift starts as โnot real research.โ
-
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Scaled up (not scale out) Postgres can power most high traffic websites today.
Neon
@neondatabase
dev.to runs on Neon.
3M+ registered users.
500k daily pageviews.
500+ new dev posts a day.
A global community for anyone learning to code, now powered by serverless Postgres - built to scale with the developers it serves. -
Matei Zaharia reposted
Databricks
@databricks
Clean Rooms now support multi-party collaborations across all clouds!
The latest advancements in Databricks Clean Rooms help users unlock richer insights. Take a look at what's new:
- Databricks Clean Rooms now GA in GCP, enabling seamless cross-collaborations
- Multi-party collaborations are now GA with advanced privacy approvals
- Leading identity partners using Clean Rooms for privacy-centric Identity Resolution
Learn more: www.databricks.com/blog/whats-new-databricks-clean-rooms -
Matei Zaharia reposted
Dipendra Misra
@DipendraMisra
AI for data science is going to be a big productivity boost across the industry. It is an important area for us, and we are hiring strong researchers and engineers in this space.
Matei Zaharia
@matei_zaharia
Lakeflow Designer and our new Genie Deep Research really begin to show the power of AI for data science, which I think will be even more impactful than AI for coding. I'm proud that Databricks is leading the charge here.
We're hiring researchers in this area, so reach out!
Databricks
@databricks
You can now build scalable pipelines and perform data analysis without writing a single line of code.
Announcing Lakeflow Designer, a visual, no-code pipeline builder that lets business analysts create ETL pipelines using drag-and-drop and natural language. Coming soon to Public Preview. www.databricks.com/blog/announcing-lakeflow-designer-no-cโฆ -
Matei Zaharia reposted
Databricks
@databricks
.@michaelarmbrust, Distinguished Software Engineer at Databricks, talked to @VentureBeat Apache Sparkโข Declarative Pipelines: a proven declarative API for building robust data pipelines with a fraction of the work.
โYou declare a series of datasets and data flows, and Apache Spark figures out the right execution plan."
venturebeat.com/data-infrastructure/databricks-open-sourcโฆ -
Matei Zaharia reposted
Andre Landgraf
@andrelandgraf
Need a Postgres DB for a quick demo, experiment, or random thingy?
Free Postgres - no signup, no credit card, nothing. Spins up in milliseconds, claim it later :)
๐ neon.new -
Matei Zaharia
@matei_zaharia
Gemini is a fantastic set of models with unique reasoning and long context capabilities. Excited to bring them at scale to our customers on Databricks!
Databricks
@databricks
We're excited to announce a strategic AI partnership with Google Cloud to bring Gemini Models natively to the Data Intelligence Platform.
The latest Gemini models will be available as native products within Databricks, empowering organizations to build, deploy and scale AI agents using Google Geminiโs advanced capabilities directly on their enterprise data โ securely and with unified governance โ within their Databricks environment.
www.databricks.com/company/newsroom/press-releases/databrโฆ -
Matei Zaharia reposted
Databricks
@databricks
Databricks AI/BI Genie is now GA! Over 4,000 organizations have already adopted AI/BI Genie in Preview โ including HP Inc., 7-Eleven and SEGA Europe โ to democratize data and to empower their non-technical users.
Building on these innovations, weโre excited to announce the preview of Genie Deep Research โ a new mode designed to address more complex, multi-step โwhyโ questions. -
Matei Zaharia
@matei_zaharia
Lakeflow Designer and our new Genie Deep Research really begin to show the power of AI for data science, which I think will be even more impactful than AI for coding. I'm proud that Databricks is leading the charge here.
We're hiring researchers in this area, so reach out!
Databricks
@databricks
You can now build scalable pipelines and perform data analysis without writing a single line of code.
Announcing Lakeflow Designer, a visual, no-code pipeline builder that lets business analysts create ETL pipelines using drag-and-drop and natural language. Coming soon to Public Preview. www.databricks.com/blog/announcing-lakeflow-designer-no-cโฆ -
Matei Zaharia reposted
Databricks
@databricks
Announcing Databricks One: a new, streamlined experience that gives business users fast and secure access to data and AI insights.
Databricks One is designed to get powerful tools like AI/BI Dashboards, Genie and Databricks Apps into the hands of business users. A single, intuitive entry point to interact with your data โ without needing to understand clusters, queries, models, or notebooks. www.databricks.com/blog/introducing-databricks-one -
Matei Zaharia
@matei_zaharia
Favorite part of @alighodsi's keynote: we're announcing a new data warehouse that's 29% faster but 35% more expensive -- NO, WAIT, that was the other conference last week! We're just making DBSQL 25% faster.
Matei Zaharia
@matei_zaharia
We still offer the best TCO for cloud data warehouses even vs their internal data formats, and significantly better on open formats like Apache Iceberg & Delta. Check out how our engineers are accelerating DBSQL: www.databricks.com/blog/databricks-sql-accelerates-customโฆ
-
Matei Zaharia reposted
Databricks
@databricks
.@ThomasOrTK, CEO of @googlecloud, and Databricks CEO and Co-founder @alighodsi discuss a new strategic partnership, the latest Gemini models, and how organizations can build and scale AI agents tailored to their specific domains and data.
โOur partnership is another critical step in helping every enterprise transform their businesses with generative AI,โ said Thomas Kurian. -
Matei Zaharia
@matei_zaharia
I gave our update on Unity Catalog at #dataaisummit, covering two big launches:
1. Full support for @ApacheIceberg, making UC the best catalog for Iceberg.
2. Business concepts like metrics, certification and curation in Unity Catalog, for unified governance.
Matei Zaharia
@matei_zaharia
Why are these a big deal? First, while many vendors are adding some support for Iceberg, none of them offer fully governed read & write access from any engine. With Unity, we provide this, letting you truly have a single catalog for Iceberg data, and add other powerful features.
Matei Zaharia
@matei_zaharia
We also integrated technology from @tabulario and @databricks for table optimization to auto-optimize Iceberg tables and deliver significantly better performance on them than data warehouses that support Iceberg.
Matei Zaharia
@matei_zaharia
And Iceberg tables can now be shared to any clients in the growing Delta Sharing ecosystem for secure cross-organization collaboration.
Matei Zaharia
@matei_zaharia
We also announced GA of Unity Catalog Metrics, a unified semantic layer that works the same way across data engineering, ML and BI instead of being stuck in the BI layer, and new Discover features including certification, domains and rich metadata.
Matei Zaharia
@matei_zaharia
These features provide unified governance and intelligence across the data lifecycle, making it much easier to work with data for humans as well as our AI assistants. There's a lot more new in UC -- more details in our blog: www.databricks.com/blog/whats-new-databricks-unity-cataloโฆ
-
Matei Zaharia
@matei_zaharia
We're open sourcing everything we learned about reliable pipelines in Delta Live Tables as @ApacheSpark Declarative Pipelines! This API makes reliable, incremental and repairable data processing significantly easier and can now be used anywhere with Spark.
Databricks
@databricks
Declarative Pipelines is going open source!
Weโre excited to bring a proven standard for building reliable, scalable data pipelines with Apache Sparkโข to the community.
Built with openness and composability in mind, Declarative Pipelines allows developers to define what their pipeline should do โ and let Spark determine the how.
Thank you to everyone who contributed - we're thrilled to continue our commitment to open source. www.databricks.com/blog/bringing-declarative-pipelines-apโฆ -
Matei Zaharia reposted
Databricks
@databricks
Today, at #dataaisummit @matei_zaharia introduced major innovations that expand Unity Catalog to business users!
- Unity Catalog Metrics: A single source of truth for business metrics across data engineering, ML and BI
- Unity Catalog Discover: New curated internal marketplace with certifications and metadata
See what's new: www.databricks.com/blog/whats-new-databricks-unity-cataloโฆ -
Matei Zaharia reposted
Naveen Rao
@NaveenGRao
Agents, agents, agents. You hear it all the time. But getting generic tools to work on YOUR problem and YOUR data remains elusive. Thatโs why we at @databricks and @DbrxMosaicAI rethought how to make agents actually work by focusing on specific types of tasks and building a loop for continuous improvement! Slope beats y-intercept in the end ;)
Introducing Agent Bricks!!
Matei Zaharia
@matei_zaharia
Excited to launch Agent Bricks, a new way to build auto-optimized agents on your tasks. Agent Bricks uniquely takes a *declarative* approach to agent development: you tell us what you want, and we auto-generate evals and optimize the agent.
www.databricks.com/blog/introducing-agent-bricks -
Matei Zaharia reposted
Databricks
@databricks
โAgents are now creating databases. This agentic era is going to disrupt the whole database industry.โ
Databricks CEO @alighodsi sat down with @dee_bosa today at #dataaisummit to discuss the database market, the Lakebase launch, and the overall AI landscape โ including bottlenecks of AI adoption, the talent war, and more.
Watch the full @CNBC segment here: youtu.be/UKFYmu0gQBw -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
OK folks. I'm finally heading up to SF for DAIS, after finishing up some stuff ๐
Come to my DSPy 3.0 breakout at 5:20pm to learn what the team has been up to for the last few months and what's on the short-term roadmap.
And let me know if we should find time to meet! -
Matei Zaharia reposted
Nikhil Thorat
@nsthorat
Excited to finally announce what we've been working on for a year - MLflow 3.0: Unified AI Experimentation, Observability, and Governance ๐
MLflow 3.0 enables continuous improvement of your AI systems through data, allowing you to trace, evaluation, and monitor your AI systems.
We've built MLflow 3.0 with enterprise in mind:
- human collaboration with subject matter experts
- data governance & security
- integration with the rest of the data ecosystem at Databricks
We brought the ideas and tools we built in Lilac to the world of GenAI observability, with a LOT more to come this year.
You try MLflow on Databricks for free today too! Link to blog & signup in the threads.
Thread of the new features in MLflow 3.0 for GenAI ๐งต
Databricks
@databricks
Hanlin Tang, our CTO of Neural Networks, on stage talking about new GenAI capabilities in MLflow 3.0! #dataaisummit
-
Matei Zaharia
@matei_zaharia
We've been learning a lot about GenAI and ML development with our customers, and have streamlined MLflow 3.0 on Databricks to be great at both. A data and evaluation-centric workflow and new integrations with 20+ GenAI frameworks make it easier than ever to build quality AI apps.
Matei Zaharia
@matei_zaharia
More details in our blog: www.databricks.com/blog/mlflow-30-unified-ai-experimentatโฆ
-
Matei Zaharia
@matei_zaharia
Also launching today, MLflow 3.0 has been redesigned for agent observability and development, with some great updates for classical structured ML as well.
MLflow
@MLflow
๐ฃ After months of collaboration across the open source community, weโre thrilled to announce the release of ๐ ๐๐ณ๐น๐ผ๐ ๐ฏ.๐ฌ! ๐
๐๐ฉ๐บ ๐ต๐ฉ๐ช๐ด ๐ฎ๐ข๐ต๐ต๐ฆ๐ณ๐ด:
GenAI has changed the game, introducing complex execution flows, subjective output quality, and new challenges for observability and evaluation. MLflow 3.0 meets these challenges head-on, expanding the platform trusted by millions for ML operations into a unified solution for all AI workloads.
Key highlights of MLflow 3.0:
๐ ๐๐ฒ๐ฒ๐ฝ ๐ข๐ฏ๐๐ฒ๐ฟ๐๐ฎ๐ฏ๐ถ๐น๐ถ๐๐ ๐๐ถ๐๐ต ๐ง๐ฟ๐ฎ๐ฐ๐ถ๐ป๐ด
Instantly capture complex GenAI execution flowsโincluding every LLM call, vector retrieval, document ranking, and prompt orchestration. MLflow Tracing provides a complete, hierarchical timeline for debugging and monitoring, all with a single line of code.
๐ ๐ฆ๐๐๐๐ฒ๐บ๐ฎ๐๐ถ๐ฐ ๐ค๐๐ฎ๐น๐ถ๐๐ ๐๐๐ฎ๐น๐๐ฎ๐๐ถ๐ผ๐ป
Evaluate GenAI quality at scale using the new evaluation framework. Assess outputs with built-in and custom LLM judges, human feedback, and automated scoringโdirectly on tracesโso you can compare and improve application versions with confidence.
๐ ๐จ๐ป๐ถ๐ณ๐ถ๐ฒ๐ฑ ๐๐ฝ๐ฝ๐น๐ถ๐ฐ๐ฎ๐๐ถ๐ผ๐ป ๐๐ถ๐ณ๐ฒ๐ฐ๐๐ฐ๐น๐ฒ ๐ ๐ฎ๐ป๐ฎ๐ด๐ฒ๐บ๐ฒ๐ป๐
Treat GenAI applications as first-class, versioned artifacts. Package, register, and deploy your complete appโincluding models, prompts, retrieval logic, and dependenciesโatomically, ensuring what you test is exactly what you deploy.
๐ ๐๐ป๐ต๐ฎ๐ป๐ฐ๐ฒ๐ฑ ๐ ๐ผ๐ฑ๐ฒ๐น ๐ฅ๐ฒ๐ด๐ถ๐๐๐ฟ๐ & ๐๐ฒ๐ฝ๐น๐ผ๐๐บ๐ฒ๐ป๐
The new LoggedModel abstraction tracks the full lifecycle of both GenAI and traditional ML models, linking metrics, parameters, and traces across training, evaluation, and deployment. Deployment Jobs orchestrate evaluation, approval, and deployment with automated quality gates, all governed by Unity Catalog.
๐ ๐๐บ๐ฝ๐ฟ๐ผ๐๐ฒ๐บ๐ฒ๐ป๐๐ ๐ณ๐ผ๐ฟ ๐ง๐ฟ๐ฎ๐ฑ๐ถ๐๐ถ๐ผ๐ป๐ฎ๐น ๐ ๐ & ๐๐ฒ๐ฒ๐ฝ ๐๐ฒ๐ฎ๐ฟ๐ป๐ถ๐ป๐ด
Enhanced experiment tracking, unified evaluation, and better checkpoint management benefit all model typesโfrom scikit-learn classifiers to multi-modal foundation models.
Ready to get started? Upgrade withย ๐๐๐ ๐๐๐๐๐๐๐ -๐ ๐๐๐๐๐๐ ย and experience the next era of unified, observable, and reliable AI development.
๐ Learn more:ย mlflow.org/blog/mlflow-3-launch
๐ View the release notes:ย mlflow.org/releases
P.S. Our BRAND NEW mlflow.org website is now LIVE! Check it out today. ๐
#opensource #mlflow #ml #oss #linuxfoundation -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
๐
Databricks
@databricks
Announcing Agent Bricks: auto-optimize agents for your domain tasks.
Provide a high-level description of the agentโs task, and connect your enterprise data โ Agent Bricks handles the rest.
Agent Bricks builds out an agent system that automatically optimizes against your goals and generates domain-specific synthetic datasets, accelerating agent development without relying on manual labeling or external sources. www.databricks.com/blog/introducing-agent-bricks -
Matei Zaharia
@matei_zaharia
Excited to launch Agent Bricks, a new way to build auto-optimized agents on your tasks. Agent Bricks uniquely takes a *declarative* approach to agent development: you tell us what you want, and we auto-generate evals and optimize the agent.
www.databricks.com/blog/introducing-agent-bricksPost not available here, view on X
Matei Zaharia
@matei_zaharia
Agent Bricks automatically searches and combines the latest AI development techniques to give you a high-quality. It gets really great results quickly compared to DIY agents, e.g. state of the art performance on information extraction and question answering out of the box.
Matei Zaharia
@matei_zaharia
This is a joint effort across our engineering and @DbrxMosaicAI research teams, based on new tuning methods we developed like TAO and ALHF. I think this type of declarative development is the future of AI -- help users build evals and auto-optimize based on those. Try it today!
-
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Category creation in action. Powered by @neondatabase
www.databricks.com/blog/announcing-lakebase-public-preview -
Matei Zaharia reposted
Databricks
@databricks
In just 6 months, customers have created 20,000+ apps across over 2,500 organizations with Databricks Apps.
Today, weโre excited to announce the General Availability of Databricks Apps, enabling all customers to securely build, deploy, and scale interactive data and AI-powered applications natively on the Databricks Data Intelligence Platform. We canโt wait to see what you build! www.databricks.com/blog/announcing-general-availability-dโฆ -
Matei Zaharia reposted
Databricks
@databricks
At #dataaisummit, @nikitabase, Co-founder and CEO of @Neondatabase, and @rxin, Co-founder and Chief Architect of Databricks, discussed the shift to AI agents โ and how weโre building the most developer and AI agent-friendly database platform.
-
Matei Zaharia
@matei_zaharia
Lakebase is in public preview!
Databricks
@databricks
Introducing Lakebase, the first fully-managed Postgres database integrated with the lakehouse and built for AI.
Lakebase combines the familiarity of Postgres with the scalability of the lakehouse and the agility of @neondatabaseโs database branching technology. Hundreds of customers are already using Lakebase for a variety of use cases. www.databricks.com/blog/announcing-lakebase-public-preview -
Matei Zaharia
@matei_zaharia
Weโve released a free edition of Databricks and opened up a lot of our training materials to help developers learn data engineering, data science and AI! Check it out to rapidly get started with the latest tools and with challenging use cases.
Databricks
@databricks
Databricks launches Free Edition! Explore and learn the latest data and AI technologies for free.
Users can experiment with the full range of use cases โ from building AI agents and applications to analyzing data with SQL โ on the same platform used by millions of professionals.
Weโre proud to help todayโs students and enthusiasts build real skills on real tools in today's competitive AI and ML job market. -
Matei Zaharia reposted
Delta Lake
@DeltaLakeOSS
๐ฃ Announcing Delta Lake 4.0.0!
We are excited to announce the release of Delta Lake 4.0! ๐ This major release is packed with powerful new features and improvements designed to make your lakehouse experience even better.
๐ Release Highlights
๐ ๐ฃ๐ฟ๐ฒ๐๐ถ๐ฒ๐: ๐๐ฎ๐๐ฎ๐น๐ผ๐ด-๐ ๐ฎ๐ป๐ฎ๐ด๐ฒ๐ฑ ๐ง๐ฎ๐ฏ๐น๐ฒ๐
Native support for catalog-integrated lakehouse tablesโlaying the foundation for unified governance and discoverability.
๐ ๐๐ฒ๐น๐๐ฎ ๐๐ผ๐ป๐ป๐ฒ๐ฐ๐ ๐ณ๐ผ๐ฟ ๐ฆ๐ฝ๐ฎ๐ฟ๐ธ ๐๐ผ๐ป๐ป๐ฒ๐ฐ๐
Delta Connectย is an extension forย Spark Connectย which enables the usage of Delta over Spark Connect, allowing Delta to be used with the decoupled client-server architecture of Spark Connect.
๐ ๐ฉ๐ฎ๐ฟ๐ถ๐ฎ๐ป๐ ๐๐ฎ๐๐ฎ ๐ง๐๐ฝ๐ฒ
Support for theย Variant data typeย to enable semi-structured storage and data processing, for flexibility and performance.
๐ ๐๐ป๐๐๐ฎ๐ป๐ ๐๐ฅ๐ข๐ฃ ๐๐๐๐ง๐จ๐ฅ๐
Remove table features without truncating your tableโs history or requiring downtime.
Delta Lake 4.0 is a major leap forward for the open lakehouse community, offering advanced management, greater flexibility, and modern architecture.
๐ Check out theย official release notes: github.com/delta-io/delta/releases/tag/v4.0.0
#opensource #oss #deltalake #linuxfoundation -
Matei Zaharia reposted
Databricks
@databricks
Tomorrow at #dataaisummit, the keynote stage lights up with leading experts, researchers, open source contributors and special guests. Be among the first to witness the latest breakthroughs from Databricks, and share the success of innovative data and AI companies.
Join us live or virtually at 8AM PT: www.databricks.com/dataaisummit -
Matei Zaharia reposted
Databricks
@databricks
#dataaisummit starts NOW.
Thousands of data engineers, data scientists and data experts are gathered in San Francisco this week to explore the convergence of data and AI. We'll be sharing highlights here.
Couldn't join us in person? Register for a virtual pass ๐: -
Matei Zaharia reposted
Stack Overflow
@StackOverflow
Stack Overflow is joining the @databricks Marketplace! Through our new integration, customers will have access to Stack Overflow Knowledge Solutions to power their data and AI ecosystems.
Learn more: stackoverflow.co/company/press/archive/stack-overflow-datโฆ -
Matei Zaharia reposted
#DataAISummit
@Data_AI_Summit
#devconnect Meetup tonight at 5:30 pm! @matei_zaharia @jefrankle and many other AI experts will share insights + best practices on GenAI quality, fine-tuning, observability and more.
Didn't register in time? Stop by and join the standby list.
www.databricks.com/dataaisummit/session/devconnect-meetup -
Matei Zaharia
@matei_zaharia
Super excited for some great launches at our largest Summit yet!
Databricks
@databricks
#dataaisummit starts tomorrow! 20,000 attendees, 700+ sessions, keynotes, meetups, and trainingโall at the worldโs largest data, analytics, and AI conference
Itโs not too late to join us. Register to attend in San Francisco or virtually: www.databricks.com/dataaisummit -
Matei Zaharia reposted
Databricks
@databricks
Apache Icebergโข v3 brings advanced new features designed for modern data workloads โ and marks a major step toward format unification!
Updates include:
โ Improved read performance with deletion vectors
โ Easier incremental processing via row lineage
โ Native support for semi-structured and geospatial data
โ Seamless interoperability across Delta Lake, Apache Parquet and Apache Sparkโข
www.databricks.com/blog/apache-icebergtm-v3-moving-ecosysโฆ
Catch Ryan Blue and Daniel Weeks at #dataaisummit as they share how weโre bringing Iceberg v3 features into our managed tables. Join us! -
Matei Zaharia reposted
Andrew Ng
@AndrewYNg
New short course: DSPy: Build and Optimize Agentic Apps
DSPy is a powerful open-source framework for automatically tuning prompts for GenAI applications. In this course, you'll learn to use DSPy, together with MLflow. This is built in partnership with @databricks and taught by @ChenMoneyQ, co-lead of the DSPy framework.
Many AI builders spend hours hand-tuning prompts. When given a set of evals, DSPy automates this process. Itโs especially useful for optimizing prompts, including few-shot prompts, in complex agentic AI workflows. Further, if you switch an application to a newer LLM, performance can degrade if your prompts were optimized to the previous model. DSPy automatically optimizes the entire system for the new LLM as well, using just a few evaluation examples.
This course teaches DSPy works, and best practices for using it. Youโll write programs using DSPyโs signature-based programming model, debug them with MLflow tracing -- to gain visibility into how different parts of a pipeline, as well as how the overall system, are performing -- and automatically improve their accuracy with DSPy Optimizer.
Please sign up here: www.deeplearning.ai/short-courses/dspy-build-optimize-ageโฆThis media couldn't be displayed. See it on the original post. -
Matei Zaharia
@matei_zaharia
Really proud of the Databricks AI and Data Science platform teams for getting the top-right position in the Gartner Magic Quadrant! We've been delivering the best integrated data and AI platform for a while and it's great to see this recognition.
Databricks
@databricks
Weโre proud to be named a Leader in the 2025 @Gartner_incยฎ Magic Quadrantโข for Data Science and Machine Learning Platforms for the fourth time!
Databricks is positioned highest in Ability to Execute and furthest in Completeness of Vision. We believe this reinforces our reputation as a trusted platform with proven success in Data Science, ML and AI.
๐ Get the report: www.databricks.com/resources/analyst-research/gartner-mq-โฆ -
Matei Zaharia reposted
Quentin Lhoest ๐ค
@lhoestq
Exciting ! We cooked with @DataBricks for the new Spark 4 !
We brought all of @huggingface Datasets into Spark:
โจAccess to 400k+ community datasets: C4, FineWeb, @nvidia reasoning datasets etc
๐คPublish datasets on HF for your team or publicly
๐ชVersioning, filters etc
1/n ๐งต -
Matei Zaharia reposted
Matei Zaharia
@matei_zaharia
Apache Spark 4.0 is out with some huge improvements across the board. SQLโs much more powerful, Spark Connect makes it easier to run apps, new languages and more. Itโs amazing to see the community still growing fast and releasing over 5000 patches in 4.0. www.databricks.com/blog/introducing-apache-spark-40
-
Matei Zaharia
@matei_zaharia
Promoting Qwen was most of what you needed? This is why it should be standard practice to run a prompt optimizer like @DSPyOSS when evaluating a LLM on most benchmarks.
Shashwat Goel
@ShashwatGoel7
Confused about recent LLM RL results where models improve without any ground-truth signal? We were too. Until we looked at the reported numbers of the Pre-RL models and realized they were serverely underreported across papers. We compiled discrepancies in a blog below๐งต๐
-
Matei Zaharia reposted
Andy Konwinski
@andykonwinski
If you had 15min to tell thousands of Berkeley CS/Data/Stats grads what to do with their lives, what would you say? Last Thursday I told them to RUN AT FAILURE.
Afterwards, while we were shaking hands & taking selfies, hundreds of them told me that they are excited to go fail. I don't think theyโve been given permission to do that before.This media couldn't be displayed. See it on the original post. -
Matei Zaharia
@matei_zaharia
Apache Spark 4.0 is out with some huge improvements across the board. SQLโs much more powerful, Spark Connect makes it easier to run apps, new languages and more. Itโs amazing to see the community still growing fast and releasing over 5000 patches in 4.0. www.databricks.com/blog/introducing-apache-spark-40
-
Matei Zaharia reposted
Apache Spark
@ApacheSpark
[ANNOUNCEMENT] The Apache Spark 4.0.0โข release is here! ๐
Congrats to the #apachespark community! This milestone is a testament to tremendous collaboration, resolving over 5100 tickets with contributions from more than 390 individuals.
Try it out! โก๏ธ spark.apache.org/releases/spark-release-4-0-0.html -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
If you're in SF in 2 weeks, see you at the @Databricks Data + AI Summit, where we have a long list of sessions on @DSPyOSS, including:
โ DSPy 3.0 by @kristahopsalong & me (Jun 11)
โ DSPy <> MLflow by @ChenMoneyQ (Jun 11)
โ Opinionated intro to DSPy by @dbreunig (Jun 10) -
Matei Zaharia reposted
#DataAISummit
@Data_AI_Summit
Weโre super excited for the AI Agents Hackathon at #dataaisummit. Teams will use Databricks agent authoring and evaluation tools to build, test, and refine intelligent agent systems. We canโt wait to see what you build! #ai #enterpriseai #databricks
www.databricks.com/dataaisummit/session/ai-agents-hackathon -
Matei Zaharia reposted
Ali Ghodsi
@alighodsi
Databricks announced the full agenda and lineup of featured speakers for this year'sย Data + AI Summit.
Join data + AI practitioners, leaders, and visionaries to discuss the latest in generative AI, machine learning, analytics and data governance.ย sprou.tt/1U1APefbxyr -
Matei Zaharia reposted
NovaSky
@NovaSkyAI
1/N Introducing SkyRL-SQL, a simple, data-efficient RL pipeline for Text-to-SQL that trains LLMs to interactively probe, refine, and verify SQL queries with a real database.
๐ Early Result: trained on just ~600 samples, SkyRL-SQL-7B outperforms GPT-4o, o4-mini, and SFT model trained with 2.5M samples across multiple Text-to-SQL benchmarks!
๐งต๐
Code: github.com/NovaSky-AI/SkyRL
Blog: novasky-ai.notion.site/skyrl-sql
Model and Data: huggingface.co/collections/NovaSky-AI/skyrl-sql-682c2ae19โฆ -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
Weโre proud to be a platinum sponsor of #mlsys2025 alongside our co-founder & CTO @matei_zaharia serving as general chair.
Stop by our booth to check out the latest projects from the Databricks team and RSVP for our networking event here: lu.ma/09ugowur.
See you there! ๐ -
Matei Zaharia
@matei_zaharia
Super excited about our agreement to acquire @neondatabase, bringing state-of-the-art, serverless elastic Postgres to Databricks! Building end-to-end data and AI apps is about to get much easier.
Ali Ghodsi
@alighodsi
I am super excited to announce that we have agreed to acquire Neon, a developer-centric serverless Postgres company. The Neon team engineered a new database architecture that offers speed, elastic scaling, and branching and forking. The capabilities that make Neon great for developers are also great for AI agents.
Together, we'll deliver an open, serverless database foundation for developers and AI agents.
www.databricks.com/company/newsroom/press-releases/databrโฆ -
Matei Zaharia reposted
Nikita | Scaling Lakebase Postgres
@nikitabase
Iโm excited to share a major milestone: Neon is joining forces with @databricks.
neon.tech/blog/neon-and-databricks
Together, we will build the best Postgres experience in the world and one of the most important pieces of the modern AI-native stack.
Day 1 again for @neondatabase -
Matei Zaharia reposted
Tianqi Chen
@tqchenml
If you are around in the Bay Area, make sure to attend the #mlsys2025 keynote tomorrow by @soumithchintala at the Santa Clara Convention Center. Checkout the full program at mlsys.org
Soumith Chintala
@soumithchintala
writing out my Keynote at @MLSysConf this year and I'm pretty excited!
"Extreme PyTorch: Inside the Most Demanding ML Workloadsโand the Open Challenges in Building AI Agents to Democratize Them" -
Matei Zaharia reposted
Dan Fu
@realDanFu
See everyone at MLSys 2025 in Santa Clara next week!
Super excited to organize the Young Professional Symposium program on day one (May 12) and our invited speakers @soumithchintala (keynote), @Tim_Dettmers, @infwinston, @simran_s_arora, @BeidiChen! -
Matei Zaharia reposted
Databricks
@databricks
We're excited to introduce a collaboration with @Atlassian that unlocks new data sharing capabilities from Atlassian Analytics!
Powered by Delta Sharingโs open protocol, Atlassian customers can securely access and analyze their data from the Atlassian Data Lake with the tools of their choice. This new data share feature opens up practical use cases: BI integration, custom data workflows, cross-team collaboration and more.
www.databricks.com/blog/atlassian-databricks-unlocking-daโฆ -
Matei Zaharia reposted
NovaSky
@NovaSkyAI
1/N Introducing SkyRL-v0, our RL training pipeline enabling efficient RL training for long-horizon, real-environment tasks like SWE-Bench. We also open-source a series of our early trained models to showcase the potential of end-to-end online RL training on long-horizon (20-50 turns) agentic tasks.
- SkyRL-Agent-7B-v0: 11.0% โ 14.6%
- SkyRL-Agent-8B-v0: 3.6% โ 9.4%
- SkyRL-Agent-14B-v0: 18.0% โ 21.6%
Code: github.com/NovaSky-AI/SkyRL
Blog: novasky-ai.notion.site/skyrl-v0
Models: huggingface.co/collections/NovaSky-AI/skyrl-agent-v0-681bโฆ. -
Matei Zaharia reposted
Databricks
@databricks
Attend #dataaisummit in San Francisco to hear from experts across industries on how theyโre applying the latest data and AI technologies in the real world.
Register for access to:
โ๏ธ Keynotes from expert leaders on the latest advancements and technology trends
โ๏ธ 700+ technical sessions on data intelligence, GenAI, data warehousing and more
โ๏ธ Hands-on training and certifications
โ๏ธ Technical Meetups and networking events
dbricks.co/42BHcgW -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
So many things in the run-up to DSPy 3. Here's a first, EXPERIMENTAL one:
๐จWe're releasing dspy.GRPO, an online RL optimizer for DSPy programs
Your DSPy code as-is can be dspy.GRPO'ed. Yes, even compound multi-module programs.
Led by @NoahZiems @LakshyAAAgrawal @dilarafsoylu. -
Matei Zaharia
@matei_zaharia
#mlsys 2025 is next week! You can still register at mlsys.org.
-
Matei Zaharia reposted
Soumith Chintala
@soumithchintala
writing out my Keynote at @MLSysConf this year and I'm pretty excited!
"Extreme PyTorch: Inside the Most Demanding ML Workloadsโand the Open Challenges in Building AI Agents to Democratize Them" -
Matei Zaharia reposted
Databricks
@databricks
Itโs official: @SAP Databricks is now GA!
SAP customers can now unlock data intelligence across their SAP data and external sourcesโenabling improved governance, advanced analytics, and AI use cases. Learn more: dbricks.co/4d1tmrY -
Matei Zaharia reposted
DSPy
@DSPyOSS
Oh, we just learned that at LlamaCon, Meta announced llama-prompt-ops, a Python package that "transforms prompts that work well with other LLMs into prompts optimized for Llama models".
They demonstrated neat gains across tasks. Built in DSPy and via our MIPROv2 optimizer.
Ben Ankiel
@benankiel
HUGE performance gains with the new llama-prompt-ops tool to optimize prompts from other models for llama
this is crazy -
Matei Zaharia
@matei_zaharia
#mlsys 2025 is starting May 12th! You can still register at mlsys.org. Come see 61 great accepted papers and keynotes by @AnimaAnandkumar, @soumithchintala, Ling Liu and @istoica05!
-
Matei Zaharia reposted
Melissa Pan
@melissapan
๐จ Why Do Multi-Agent LLM Systems Fail? โ๏ธ
๐ฅ Introducing MAST: The first multi-agent failure taxonomy - consists of 14 failure modes and 3 categories, generalizes for diverse multi-agent systems and tasks!
Paper: arxiv.org/pdf/2503.13657
Code: github.com/multi-agent-systems-failure-taxonomy/MAST
๐งต1/n -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
We've been working quietly for a few months on a half-dozen core directions for better AI software.
Now, DSPy 3.0 is approaching and presenting them togetherโand honestly, it's daunting to figure out how to sequence all the releases from the DSPy OSS team.
Follow @DSPyOSS.
DSPy
@DSPyOSS
Hello world!
-
Matei Zaharia reposted
Databricks
@databricks
Thereโs still time to join tomorrowโs webinar with Databricks CEO @AliGhodsi, @AnthropicAI CEO @DarioAmodei, and other industry leaders โ and learn how enterprises can build AI apps they can trust.
Explore real-life examples of customers using AI agents to accomplish domain-specific solutions โ and gain best practices for optimizing workflows that provide high-quality results for their specific domain, understand organizational data, and adhere to security and governance protocols.
Donโt miss it โ register now: dbricks.co/4iwJnZ2 -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
This was super cool work from Tomu Hirata and the rest of the DSPy and MLflow OSS teams at @databricks.
Understanding the experiments being launched by DSPy optimizers like MIPRO, the score progression over time, and the resulting prompts is quite a bit easier via @MLflow now.
MLflow
@MLflow
MLflow now supports tracking for DSPy (Community) optimization workflows โ just like it does for @PyTorch training! ๐
DSPy (Community) makes it easy to automatically optimize your #llm prompts using powerful optimizers. And now, MLflow is the first and only framework that brings visibility and observability into that optimization process.
Whether youโre tuning a prompt or training a model, MLflow helps you understand whatโs happening under the hood โ so you can iterate faster and build better. โ
๐ Check out this blog to get started today! โก๏ธ medium.com/@AI-on-Databricks/boosting-dspy-optimizer-obseโฆ
MLflow documentation โก๏ธ mlflow.org/docs/latest/llms/dspy/optimizer
#mlflow #dspy #opensource #oss -
Matei Zaharia reposted
Tianqi Chen
@tqchenml
Less than a month to go before #mlsys2025. We have a great line of keynote speakers @soumithchintala @istoica05 @AnimaAnandkumar , Lin Liu. See the full schedule mlsys.org/virtual/2025/calendar and don't forget to book your hotel room while you still can shorturl.at/1CKn3
-
Matei Zaharia reposted
Nandan Thakur
@beirmug
Existing IR/RAG benchmarks are unrealistic: theyโre often derived from easily retrievable topics, rather than grounded in solving real user problems.
๐งตIntroducing ๐ ๐ซ๐๐ฌ๐ก๐๐ญ๐๐๐ค, a challenging RAG benchmark on niche, recent topics.
Work done during intern @databricks ๐งฑ -
Matei Zaharia reposted
Databricks
@databricks
Thrilled to welcome the Fennel team to Databricks!
Fennel improves the efficiency and data freshness of feature engineering pipelines for batch, streaming and real-time data. Their innovative approach tackles some of the biggest challenges of feature engineering while optimizing costs.
Integrating Fennelโs capabilities into the Databricks Data Intelligence Platform will help customers quickly iterate on features, deploy #ml models with reliable, real-time data and improve model accuracy. Learn more: dbricks.co/4lzNSDL -
Matei Zaharia reposted
MLflow
@MLflow
Join us for the next MLflow Community Meetup โ Wednesday, April 23 at 4PM PT! ๐๏ธ
๐ REGISTER: lu.ma/mlflow423
Weโre bringing two exciting presentations to the community:
๐นMLflow + #dspy Integration
Discover new features that integrate MLflow with DSPy โ including compilation tracking, tracing enhancements, and a preview of expanded capabilities on the way.
๐น @CleanlabAI + MLflow
Learn how Cleanlab can enhance your MLflow workflows by adding automation and trust to every data point and prediction โ especially in AI and RAG pipelines.
๐ฅ The event will be livestreamed on YouTube, LinkedIn, and X.
๐ฌ Bring your questions โ we'll be taking them live from the audience!
Donโt miss this opportunity to connect with the MLflow community and explore powerful new tooling.
#opensource #oss #mlflow #linuxfoundation -
Matei Zaharia reposted
Tianqi Chen
@tqchenml
#mlsys2025 early registration deadline is today, register at mlsys.org/Register/ to get a discounted price. Looking forward to seeing everyone at the conference!
Tianqi Chen
@tqchenml
๐#mlsys2025 program is now available at mlsys.org/virtual/2025/calendar. The early registration deadline is coming up in four days. Register at mlsys.org/Register/
-
Matei Zaharia reposted
Tianqi Chen
@tqchenml
๐#mlsys2025 program is now available at mlsys.org/virtual/2025/calendar. The early registration deadline is coming up in four days. Register at mlsys.org/Register/
-
Matei Zaharia reposted
Databricks
@databricks
Catch @alighodsi and Mark Zuckerberg at ๐ฆ #llamacon, where theyโll discuss the importance of open source AI and share advice for founders building AI-powered applications.
This is a canโt-miss event for developers who want to explore the latest in open source AI and best practices from industry leaders.
dbricks.co/4loqZDi -
Matei Zaharia reposted
Naman Jain
@StringChaos
Excited to release R2E-Gym
- ๐ฅ 8.1K executable environments using synthetic data
- ๐ง Hybrid verifiers for enhanced inference-time scaling
- ๐ 51% success-rate on the SWE-Bench Verified
- ๐ค Open Source Data + Models + Trajectories
1/ -
Matei Zaharia
@matei_zaharia
This is a really cool framework that came out of our research on inference scaling strategies (networks of networks), with the equivalent of XLA for that space. Take a look if you want to quickly experiment with these.
Jared Quincy Davis
@jaredq_
Ember: an inference-time scaling architecture framework
๐งต
(1/8) -
Matei Zaharia
@matei_zaharia
Nice results on never-ending learning for code editing. We believe that a lot of AI applications will be customizable this way (to every company's codebase, users, etc). The combined AI serving, data analytics and MLOps environment on Databricks makes these easy to build.
Dipendra Misra
@DipendraMisra
1/ In our new exciting results, we show how a small Llama 8b model, fine-tuned on user-edits from interaction data, outperforms GPT-4o on both accuracy and speed, in a real A/B test in an enterprise setting.
www.databricks.com/blog/power-fine-tuning-your-data-quickโฆ -
Matei Zaharia reposted
Ahmad Al-Dahle
@Ahmad_Al_Dahle
As of today, Llama 4 Maverick offers a best-in-class performance to cost ratio with an experimental chat version scoring ELO of 1417 on LMArena.
It's wild to think Llama was a research project a couple of years ago & amazing to see how much progress we've made in the last two years ๐ And this is just the first taste of the Llama 4 collection โ get ready for a herd like youโve never seen before.
Very proud of the GenAI team. -
Matei Zaharia
@matei_zaharia
Congrats @AIatMeta on the release of Llama 4! Weโre excited to be launch partners at Databricks and already have it available: www.databricks.com/blog/introducing-metas-llama-4-databriโฆ. This makes our mission of letting any organization build specialized AI that much easier.
-
Matei Zaharia reposted
AI at Meta
@AIatMeta
Today is the start of a new era of natively multimodal AI innovation.
Today, weโre introducing the first Llama 4 models: Llama 4 Scout and Llama 4 Maverick โ our most advanced models yet and the best in their class for multimodality.
Llama 4 Scout
โขย 17B-active-parameter model with 16 experts.
โขย Industry-leading context window of 10M tokens.
โขย Outperforms Gemma 3, Gemini 2.0 Flash-Lite and Mistral 3.1 across a broad range of widely accepted benchmarks.
Llama 4 Maverick
โขย 17B-active-parameter model with 128 experts.
โขย Best-in-class image grounding with the ability to align user prompts with relevant visual concepts and anchor model responses to regions in the image.
โข Outperforms GPT-4o and Gemini 2.0 Flash across a broad range of widely accepted benchmarks.
โข Achieves comparable results to DeepSeek v3 on reasoning and coding โ at half the active parameters.
โขย Unparalleled performance-to-cost ratio with a chat version scoring ELO of 1417 on LMArena.
These models are our best yet thanks to distillation from Llama 4 Behemoth, our most powerful model yet. Llama 4 Behemoth is still in training and is currently seeing results that outperform GPT-4.5, Claude Sonnet 3.7, and Gemini 2.0 Pro on STEM-focused benchmarks. Weโre excited to share more details about it even while itโs still in flight.
Read more about the first Llama 4 models, including training and benchmarks โก๏ธ go.fb.me/gmjohs
Download Llama 4 โก๏ธ go.fb.me/bwwhe9 -
Matei Zaharia reposted
VentureBeat
@VentureBeat
The TAO of data: How Databricks is optimizingย AI LLM fine-tuning without data labels venturebeat.com/data-infrastructure/the-tao-of-data-how-dโฆ
-
Matei Zaharia
@matei_zaharia
Super excited about our new partnership with @AnthropicAI and native availability of Claude 3.7 Sonnet in Databricks on AWS, Azure and GCP! Stay tuned for more integrations and great support across the entire agent development and MLOps stack. sprou.tt/19muXYu3ZuR
-
Matei Zaharia reposted
WIRED
@WIRED
Using several recent innovations, the company Databricks will let customers boost the IQ of their AI models even if they donโt have squeaky clean data. www.wired.com/story/databricks-has-a-trick-that-lets-ai-mโฆ
-
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
The hardest part about finetuning LLMs is that people generally don't have high-quality labeled data. Today, @databricks introduced TAO, a new finetuning method that only needs inputs, no labels necessary. Best of all, it actually beats supervised finetuning on labeled data.
-
Matei Zaharia
@matei_zaharia
Really cool result from the Databricks research team: You can tune LLMs for a task *without data labels*, using test-time compute and RL, and outperform supervised fine-tuning! Our new TAO method scales with compute to produce fast, high-quality models. www.databricks.com/blog/tao-using-test-time-compute-trainโฆ
Post not available here, view on X
Matei Zaharia
@matei_zaharia
Key to TAO is a search and scoring process that leverages test-time compute only during training, and new RL methods and models from our team. More details in our blog: www.databricks.com/blog/tao-using-test-time-compute-trainโฆ
Matei Zaharia
@matei_zaharia
TAO is now in preview for Databricks customers. You can sign up from our blog: www.databricks.com/blog/tao-using-test-time-compute-trainโฆ
-
Matei Zaharia
@matei_zaharia
We're thrilled to announce the keynote speakers for #mlsys2025: @AnimaAnandkumar, @soumithchintala, Ling Liu and @istoica05! Registration is open to attend the conference in Santa Clara.
-
Matei Zaharia
@matei_zaharia
Travel grant applications are open for #mlsys2025. Students, postdocs and early-career researchers can apply at mlsys.org/Conferences/2025/CallForTravelGrants.
-
Matei Zaharia
@matei_zaharia
The #mlsys2025 program is up and registration is open! Check out accepted papers at mlsys.org/virtual/2025/papers.html?filter=titles and sign up to attend at mlsys.org/Register.
-
Matei Zaharia reposted
Mike Cornell
@TXMikeC
๐ The ai_forecast() SQL function in Databricks allows you to execute forecasts directly on time series tables with a single line of code! /1
-
Matei Zaharia reposted
Databricks
@databricks
We're excited to introduce major updates to Lakehouse Federation!
โ Lakehouse Federation for Google BigQuery now GA
โ Public Preview of Oracle and Teradata connectors
Now, you can connect, discover, govern, and query data from these sources through Unity Catalogโwithout migration or ETL.
dbricks.co/3Fvtljp -
Matei Zaharia reposted
Haocheng Xi
@HaochengXiUCB
๐ Introducing #sparsevideogen: 2x speedup in video generation with HunyuanVideo with high pixel-level fidelity (PSNR = 29)! No training is required, no perceptible difference to the human eye!
Blog: svg-project.github.io
Paper: arxiv.org/abs/2502.01776
Code: github.com/svg-project/Sparse-VideoGen
#artificialintelligence #opensource
[1/7] -
Matei Zaharia reposted
Databricks
@databricks
Weโre wrapping up our Week of Agents with some major updates to AI Functions! Introducing Serverless Batch Inference.
Whether general-purpose or task-specific, AI functions are now fully serverless and production-grade, requiring zero configuration and delivering over 10x faster performance.
See whatโs new ๐
dbricks.co/4iJ8Iym -
Matei Zaharia reposted
Databricks
@databricks
Introducing Genie Conversation APIs: self-serve data insights from your favorite productivity tools and custom-built apps.
With this new suite of APIs, you can programmatically embed AI/BI Genie into popular apps like Slack and Teams or seamlessly integrate it with Mosaic AI Agent Frameworks.
Now in Public Preview on AWS, Azure and GCP! dbricks.co/3FnWwF6 -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
Yes there's an evals crisis, but evaluating *models* is not even the right question most of the time
LangProBe from @ShangyinT @LakshyAAAgrawal @arnav_thebigman @LaiLiheng112 @michaelryan207 et al begins to ask what complete *AI systems* we should build and under what settings
Lakshya A Agrawal
@LakshyAAAgrawal
๐งตIntroducing LangProBe: the first benchmark testing where and how composing LLMs into language programs affects cost-quality tradeoffs!
We find that, on avg across diverse tasks, smaller models within optimized programs beat calls to larger models at a fraction of the cost. -
Matei Zaharia reposted
Lakshya A Agrawal
@LakshyAAAgrawal
๐งตIntroducing LangProBe: the first benchmark testing where and how composing LLMs into language programs affects cost-quality tradeoffs!
We find that, on avg across diverse tasks, smaller models within optimized programs beat calls to larger models at a fraction of the cost. -
Matei Zaharia reposted
Hui Guan
@guanh01
๐ Join us at MLSys 2025 Young Professionals Symposium on May 12 in Santa Clara. Submit your 1-page abstract by April 7 & present your work at our poster session #mlsys2025. Check out the website for more details: mlsys.org/Conferences/2025/YPS
-
Matei Zaharia reposted
Andrew Drozdov
@mrdrozdov
We're probably a little too obsessed with zero-shot retrieval. If you have documents (you do), then you can generate synthetic data, and finetune your embedding. Blog post lead by @JacobianNeuro shows how well this works in practice. www.databricks.com/blog/improving-retrieval-and-rag-embedโฆ
-
Matei Zaharia reposted
lingjiao chen
@ChenLingjiao
Compound AI systems often make multiple LLM calls for complex tasks. But which LLM should be used for each call? We build LLMSELECTOR, a framework that automatically optimizes LLM selection for each call, with substantial perf gains (5-70%) over the best-performing fixed model!
-
Matei Zaharia reposted
Liana
@lianapatel_
Excited to share our release of LOTUS 1.1.0, which now makes it easier than ever to get started with LLM-powered data processing over a variety of custom knowledge sources.
Seamlessly connect to data from the web, your SQL databases, vector databases and more.
And process it all with the power of semantic operators.
github.com/lotus-data/lotus -
Matei Zaharia reposted
NovaSky
@NovaSkyAI
Interleaving SFT + RL unleashes the power of small models.
๐ Introducing Sky-T1-7B, a SOTA open-recipe model trained with 4-step SFT->RL->SFT->RL. We also release Sky-T1-mini, trained with RL from DeepSeek-R1-Distill-Qwen-7B model, approaching o1-mini performance on math tasks. -
Matei Zaharia reposted
Liana
@lianapatel_
Some of the most exciting AI apps require LLM reasoning over large datasets at test time.
For these types of NL questions, RAG or Text2SQL + your favorite LLM are simply not enough.
Excited to announce our new leaderboard, from the TAG team at Stanford and Berkeley, to benchmark progress on these difficult types of NL questions over data.
Make a submission & top our leaderboard: huggingface.co/spaces/TAG-Research/TAG-Leaderboard -
Matei Zaharia reposted
SAP
@SAP
We're bringing in a new era of enterprise data management and agentic AI with SAP Business Data Cloud with @Databricks.
โ Unifies your SAP and non-SAP data
โ Natively embeds Databricks technology
โ AI agents streamline workflows
Learn more: sap.to/6011IgafW -
Matei Zaharia reposted
Asim Biswal
@_asimbiswal
๐ New Leaderboard Release!
Reasoning models like Deepseek-R1 are excelling on math and science benchmarks, but how well do they handle complex questions over large-scale data?
Table Augmented Generation (TAG) is a unified paradigm that generalizes methods for natural language question answering over data. We are now excited to release the TAG-Leaderboard to evaluate these methods. We are welcoming submissions and want to see how your method does! Joint work from Berkeley and Stanford.
๐ Leaderboard: huggingface.co/spaces/TAG-Research/TAG-Leaderboard
๐ Project Homepage: tag-research.github.io/homepage/ -
Matei Zaharia reposted
Databricks
@databricks
We're excited to announce a new partnership with @SAP that will provide the Databricks Data Intelligence Platform natively within SAPโs newly launched SAP Business Data Cloud.
SAP Databricks will allow customers to use the AI, data warehousing, data engineering and data governance capabilities of Databricks on mission-critical data from SAP.
dbricks.co/4jTRXC1 -
Matei Zaharia reposted
AK
@_akhaliq
LLMs Can Easily Learn to Reason from Demonstrations Structure, not content, is what matters!
-
Matei Zaharia reposted
Databricks
@databricks
Weโre excited to announce a major expansion in the Databricks + @confluentinc partnership, enabling real-time data for AI-driven decision-making.
Many organizations struggle to make AI operational because their data is siloed into different systems that werenโt built to work together. New bidirectional integrations between Confluentโs Tableflow and Databricks Unity Catalog will provide consistent, real-time data across operational and analytical systems that is discoverable, secure, and trustworthy.
Our CEO @alighodsi and Confluent CEO @jaykreps share more about this partnership: dbricks.co/3CAPjAx -
Matei Zaharia reposted
Agentica Project
@Agentica_
โจRL magic is in the air! Introducing DeepScaleR-1.5B-Previewโa fully open-source, 1.5B-parameter model trained with RL to surpass o1-preview for general math reasoning.
๐Blog: pretty-radio-b75.notion.site/DeepScaleR-Surpassing-O1-Preโฆ
๐ปGithub: github.com/agentica-project/deepscaler -
Matei Zaharia reposted
Databricks
@databricks
Now GA on Google Cloud: Serverless Compute for notebooks, Workflows and DLT pipelines!
Serverless compute provides practitioners with the speed, scalability, and simplicity needed to address challenges across todayโs data engineering and analytics landscape: -
Matei Zaharia reposted
Databricks
@databricks
Announcing GA of Databricks Clean Rooms โ secure, privacy-centric collaboration on any cloud, region or data platform.
Leading companies like Mastercard and Intuit are already using Clean Rooms to drive privacy-centric data sharing and solve complex challenges.
Clean Rooms is now available on AWS and Azure. See how to get started:
dbricks.co/40PhuDE -
Matei Zaharia reposted
Parth Asawa
@pgasawa
Instruct-tuned models are getting better at following instructions and โreasoningโ every day, but theyโre shockingly poor at generating diverse responses. Diversity is crucial to many tasks like synthetic data generation. We tackle this with a new approach, BARE ๐ป! (1/n)
-
Matei Zaharia reposted
Naveen Rao
@NaveenGRao
Woohoo! DeepSeek R1 on @databricks ! And as always, it comes with the security and governance that our customers have come to rely on.
www.databricks.com/blog/deepseek-r1-databricks -
Matei Zaharia reposted
Naveen Rao
@NaveenGRao
We're about to see a huge number of RL innovations after Deepseek! All of those researchers in academia or small labs that couldn't work on pre-training (lack of budget) will be unleashed on all the open-source base models.
I think the afterburners just got turned on for AI progress ๐ฅโ๏ธ -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
ColBERT got ridiculously fast in 2022 with PLAID. I thought that was as fast as it could get.
But Luca Scheerer taught us that you can make it 3x faster: a single CPU core can encode the query *and* search hundreds of millions of tokens in 100ms.
WARPโworth a thread tmrw?
Sumit
@_reachsumit
WARP: An Efficient Engine for Multi-Vector Retrieval
Introduces an efficient engine that significantly reduces query latency for multi-vector retrieval systems through implicit decompression and dynamic similarity imputation.
๐arxiv.org/abs/2501.17788
๐จ๐ฝโ๐ปgithub.com/jlscheerer/xtr-warp -
Matei Zaharia reposted
Jiayi Pan
@jiayi_pirate
We reproduced DeepSeek R1-Zero in the CountDown game, and it just works
Through RL, the 3B base LM develops self-verification and search abilities all on its own
You can experience the Ahah moment yourself for < $30
Code: github.com/Jiayi-Pan/TinyZero
Here's what we learned ๐งต -
Matei Zaharia reposted
NovaSky
@NovaSkyAI
1/5 โก๏ธPresenting Sky-T1-32B-Flashโก๏ธ, our open reasoning model that tackles "overthinking" to cut generation lengths (and inference cost!) by 50% without sacrificing accuracy โ tuned with only $275!
๐Blog: novasky-ai.github.io/posts/reduce-overthinking/
๐๏ธโโ๏ธWeights: huggingface.co/NovaSky-AI/Sky-T1-32B-Flash -
Matei Zaharia reposted
Andrew Drozdov
@mrdrozdov
Using 100+ tokens to answer 2 + 3 =
-
Matei Zaharia reposted
Andrew Drozdov
@mrdrozdov
the answer to basically any "what is the bottleneck" question in AI rn
Sasha Rush
@srush_nlp
I would say diversity and complexity of tasks. Other stuff seems important but not insurmountable.
-
Matei Zaharia reposted
Dimitris Papailiopoulos
@DimitrisPapail
almost an entire community was overfitting on the words "search" and "PRM", yet there was another, simpler, cleaner path to reasoning :)
DeepSeek
@deepseek_ai
๐ DeepSeek-R1 is here!
โก Performance on par with OpenAI-o1
๐ Fully open-source model & technical report
๐ MIT licensed: Distill & commercialize freely!
๐ Website & API are live now! Try DeepThink at chat.deepseek.com today!
๐ 1/n -
Matei Zaharia reposted
Isaac Miller ๐งฉ
@isaacbmiller1
i wrote up a dspy example notebook showing off this type of functionality as a first example of multimodal dspy. (completely inspired by this tweet, I take no credit for the idea)
code linked below
Thorondor LLC
@ThorondorLLC
New project! Optimize your stable diffusion prompts via a "chain-of-thought" style iteration - built with DSPy
-
Matei Zaharia
@matei_zaharia
Sponsor registration open for #mlsys 2025. We have the most submissions ever to MLSys so it promises to be a great conference! mlsys.org/Sponsors/sponsorinfo
-
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
Interesting Friday evening code drop from @brandon_cui and @rajammanabrolu... Contributions from @wat_the_fun @j_nadan_chang @alexrtrott @mvpatel2000 as well. That's all I'm allowed to say for now ๐ github.com/databricks/compose-rl
-
Matei Zaharia reposted
James Zou
@james_y_zou
Our updated #frugalgpt paper w/ @ChenLingjiao @matei_zaharia is published! openreview.net/pdf?id=cSimKw5p6R
We show how to automatically optimize #llm cascades that outperform frontier models while saving 50-98% of inference cost.๐ฏ -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
We're kicking off 2025 with another Compound AI System Meetup with @lancedb in Mountain View on Jan 22! ๐ Join us for a deep dive into AI infrastructure and insights with Lu Qiu, Allison Wang, Holden Karau, and Dr. Sharon Zhou. ๐Save your spot: lu.ma/5ech3qaz
-
Matei Zaharia reposted
Dipendra Misra
@DipendraMisra
1/n Looking to do research in frontier models that make a real-world impact? Our team at Databricks is hiring strong researchers and engineers. Apply here:
www.databricks.com/company/careers/engineering/genai-reseโฆ -
Matei Zaharia reposted
Naman Jain
@StringChaos
๐ข Excited to share the 5th update for LiveCodeBench
We have added 167 new problems this time and collected 880 problems overall, over two-fold increase from 400 problems in v1
Leaderboard โฌ๏ธ
- ๐ฅ open and closed reasoning models (o1, Gemini-Flash, QwQ, and upcoming R1!) -
Matei Zaharia reposted
Alex Dimakis
@AlexGDimakis
I was very surprised that straightforward SFT on a few thousand examples produces a posttraining dataset that gives o1 level reasoning abilities. Congratulations to the team: they show there is absolutely no moat in reasoning and no RL is needed if you can get a few thousand CoTs
NovaSky
@NovaSkyAI
1/6 ๐
Introducing Sky-T1-32B-Preview, our fully open-source reasoning model that matches o1-preview on popular reasoning and coding benchmarks โ trained under $450!
๐Blog: novasky-ai.github.io/posts/sky-t1/
๐๏ธโโ๏ธModel weights: huggingface.co/NovaSky-AI/Sky-T1-32B-Preview -
Matei Zaharia reposted
NovaSky
@NovaSkyAI
1/6 ๐
Introducing Sky-T1-32B-Preview, our fully open-source reasoning model that matches o1-preview on popular reasoning and coding benchmarks โ trained under $450!
๐Blog: novasky-ai.github.io/posts/sky-t1/
๐๏ธโโ๏ธModel weights: huggingface.co/NovaSky-AI/Sky-T1-32B-Preview -
Matei Zaharia reposted
Prithviraj (Raj) Ammanabrolu
@rajammanabrolu
my job here is done
Jonathan Frankle
@jefrankle
Speak for yourself. I just think RL people are really fun to hang out with.
-
Matei Zaharia reposted
Omar Khattab
@lateinteraction
horrors of PHP-esque stringly typed programming all over again
Guillermo Rauch
@rauchg
โข writing style โ prompt
โข coding style โ prompt
โข color system โ prompt
โข design system โ prompt
โข brand guidelines โ prompt
โข a11y requirements โ prompt
โข compliance & legal โ prompt
โข vendor preferences โ prompt
โข product requirements โ prompt
โข customer preferences โ prompt
โข institutional knowledge โ prompt
On a long enough timeline, everything gets subsumed by the (system) prompt and integrations that populate it -
Matei Zaharia reposted
Databricks
@databricks
New goal for the #newyear โ sharing your data + AI expertise with the world.
#dataaisummit Call For Presentations is now open! Weโre looking for data engineers, ML engineers, data scientists and analysts who are pushing the limits of AI, analytics and data engineering.
Submit your proposal by February 3rd ๐ dbricks.co/3Wh1Mx6 -
Matei Zaharia reposted
Databricks
@databricks
Credential vending for #unitycatalog open APIs now in Public Preview.
Benefits include:
- Seamless interoperability across diverse compute engines
- Simplified permissions management
- A foundation for advanced governance features
Learn more๐ dbricks.co/41NaFoe -
Matei Zaharia reposted
MLflow
@MLflow
๐ MLflow community survey is LIVE!
Help us build the future of ML infrastructure in just 10 minutes. Your insights shape how thousands of data scientists and engineers work.
Take the survey, make an impact: surveys.training.databricks.com/jfe/form/SV_cA2jrfBjs6vi6SG
#mlflow #machinelearning -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
๐งฑAnnouncing v1 of the @databricks Domain Intelligence Benchmark Suite (DIBS) ๐งฑ AGI is AI that "outperforms humans at most economically valuable work." To achieve AGI, we need evals that measure economically valuable work. Our 10,000 enterprise customers are helping us do that.
Pallavi
@herengoneagn
๐งต Super proud to finally share this work I led last quarter - the @Databricks Domain Intelligence Benchmark Suite (DIBS)! TL;DR: Academic benchmarks โ real performance and domain intelligence > general capabilities for enterprise tasks. 1/3
-
Matei Zaharia
@matei_zaharia
You can now use Unity Catalog as a tool registry for AI agents, and reuse the exact same functions in data analytics workflows for full consistency.
Unity Catalog
@unitycatalog_io
Today, we released Unity Catalog AI โ an open-source toolkit designed to create and manage AI tools as functions registered in Unity Catalog! ๐
Check out the release: pypi.org/project/unitycatalog-ai/
#unitycatalog #opensource -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
New blog post on Benchmarking Domain Intelligence: www.databricks.com/blog/benchmarking-domain-intelligence
Evaluating your #ai solutions should be done with tests that match your actual use case. We observed that the tasks in many academic AI benchmarks don't match what business needs. (1/n) -
Matei Zaharia reposted
Liana
@lianapatel_
We've been building LOTUS at Stanford and Berkeley to make LLM-powered data processing fast, easy and declarative.
LOTUS is an open-source query engine that makes programming as easy as writing Pandas and optimizes your programs for up to 400x speedups.
To celebrate the holidays, we're excited to share our release of LOTUS 1.0.0 with a batch of new updates that make reasoning over your data faster, easier and better than ever!
Code: github.com/guestrin-lab/lotus
๐งต๐ -
Matei Zaharia reposted
Databricks
@databricks
Today, some of the largest companies in the world use Databricks to find and treat diseases and cancer earlier, detect financial fraud, reduce time to mental health intervention, decrease local financial inequality, and much more.
Our CEO Ali Ghodsi spoke with @WSJ about the company's beginnings, and how it became one of the fastest growing companies in tech: dbricks.co/4gjLRJ5 -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
The field converges on inference-time scaling, which is wonderful.
You also need inference-time composition (programmable inductive biases, not just compute/search) and pre-inference time scaling (what dspy calls compiling/optimization).
You need all 3 to build good AI systems. -
Matei Zaharia
@matei_zaharia
Excited about our investment and continued partnership with @twelvelabs! They're building some amazing multimodal AI models and products. www.databricks.com/blog/databricks-ventures-invests-twelvโฆ
-
Matei Zaharia reposted
Unity Catalog
@unitycatalog_io
๐ Excited to announce the release of Unity Catalog 0.2.1! ๐
This update brings:
๐ New unitycatalog-client Python library
๐ MODIFY permissions for tables
๐ Enhanced model APIs/UI
โ๏ธ Iceberg Catalog APIs updates
Read the release notes ๐ github.com/unitycatalog/unitycatalog/releases/tag/v0.2.1?โฆ
#opensource -
Matei Zaharia reposted
Databricks
@databricks
Introducing Serverless Time Series Forecasting in Mosaic AI! Unlock the predictive power of your time series data with 50% better accuracy, enhanced flexibility, and improved governance. dbricks.co/3Vv3uNK
-
Matei Zaharia reposted
Ken Goldberg
@Ken_Goldberg
New computer systems perspective on integrated (modular and hybrid) large models with good old fashioned engineering (GOFE). @UCBerkeley @Berkeley_EECS @Databricks
arxiv.org/abs/2412.05299
Ken Goldberg
@Ken_Goldberg
This is an excellent robotics survey paper contrasting deep learning โimplicitโ models (data driven) with the long history of โexplicitโ models (Good Old Fashioned Engineering) and calling for methods that integrate both: @BekrisKostas arxiv.org/abs/2410.12172
-
Matei Zaharia reposted
Jared Quincy Davis
@jaredq_
Today's AI landscape is reminiscent of the early automotive and aviation industries. Although we have seen remarkable demonstrations and early successes, the full transformative impact and proliferation of LLM systems are bottlenecked by robustness and reliability challenges.
Building on the analogy, massive leaps were needed to progress from the Wright Brothers' initial Kitty Hawk breakthrough to the contemporary aviation industry, where over 2M humans fly daily. Notably, the gap from Kitty Hawk to what is considered the dawn of commercial aviation with Jannus was ~10 years.
In this paper, Ion Stoica, along with collaborators @matei_zaharia, @joseph_gonzalez , @Ken_Goldberg, @haozhangml , @ml_angelopoulos, @shishirpatil_, @ChenLingjiao, @infwinston, and I, surveys the landscape and lays out a vision for advancing todayโs LLM systems design into a mature engineering discipline with even broader deployed impact. This paper begins to address how we can reconcile the tensions arising from the value of these systems partially being their stochasticity and โcreativityโ (hallucination) and the engineering imperative to build robust, reliable 'compound AI' systems out of these noisy components.
SPECIFICATIONS: THE MISSING LINK TO MAKING THE DEVELOPMENT OF LLM SYSTEMS AN ENGINEERING DISCIPLINE
arxiv.org/pdf/2412.05299 -
Matei Zaharia
@matei_zaharia
Lots of debate about this at the conference. My take is that whatever happens with general FLOPS scaling, *domain-specific* AI is still in its infancy and is where the action will be. That's what we're working on at @databricks Research and @DbrxMosaicAI!
Jonathan Frankle
@jefrankle
Reflections on NeurIPS: There's always a big theme people seem to be preoccupied with. This year, it was the continuation of scaling/progress. Will it continue? What will the next generation of models hold? I even got to sass @dylan522p over it. Here are my personal thoughts ๐งต
-
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
Reflections on NeurIPS: There's always a big theme people seem to be preoccupied with. This year, it was the continuation of scaling/progress. Will it continue? What will the next generation of models hold? I even got to sass @dylan522p over it. Here are my personal thoughts ๐งต
-
Matei Zaharia reposted
Naveen Rao
@NaveenGRao
Gen AI is still very much in the phase of fast price reduction/quality increase! Mosaic's Law (4x increase perf/$ yoy) in full effect.
www.databricks.com/blog/making-ai-more-accessible-80-costโฆ -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
I really enjoyed reading this. Very concrete and quite accessible. Thanks @dbreunig!
Drew Breunig
@dbreunig
Really enjoy DSPyโs workflow for LLM work. Handing off the specifics of prompt generation and engineering back to the LLM makes a lot of sense: www.dbreunig.com/2024/12/12/pipelines-prompt-optimizationโฆ
-
Matei Zaharia reposted
Naveen Rao
@NaveenGRao
If you're at NeurIPS, stop by and say hi!
Databricks AI Research
@DbrxMosaicAI
@jefrankle and the @databricks team are in our data + AI era at #neurips2024. Stop by our booth in the expo hall and #shakeitoff with us.
-
Matei Zaharia reposted
Databricks
@databricks
Introducing Hive Metastore and AWS Glue Federation in Unity Catalog. Seamlessly leverage Unity Catalog's advanced features without the overhead of migrating HMS or AWS Glue-managed tables.
Learn more ๐ dbricks.co/49H5Pek -
Matei Zaharia reposted
Andy Konwinski
@andykonwinski
I'll give $1M to the first open source AI that gets 90% on this sweet new contamination-free version of SWE-bench - kprize.ai
-
Matei Zaharia
@matei_zaharia
Congrats to these awesome startups! @vevo_ai @OrbyAI @ChipStackAI
Databricks
@databricks
Announcing the winners of the Databricks #generativeai Startup Challenge!
- Grand Prize: @vevo_ai
- Second Place: @OrbyAI
- Third Place: @ChipStackAI
- Honorable Mention: Flagler Health
Weโre thrilled to see their continued growth and impact! dbricks.co/3DbIULQ -
Matei Zaharia reposted
Nikhil Thorat
@nsthorat
We just released the @databricks synthetic evaluation SDK! ๐
Weโve found that synthesizing evals is a great way to hill climb your AI system before youโre able to get labels from domain experts.
With this SDK, and our fancy diffing UI, users are able to improve the inner loop of improving their agent pretty effectively.
Check out the blog post linked ๐
Daniel Smilkov
@dsmilkov
Our first public launch since joining @databricks!
Organizations struggle with creating high-quality evaluation datasets. Getting time with Subject Matter Experts to make diverse questions is hard.
This is why weโre excited to introduce Synthetic Data Generation API! -
Matei Zaharia reposted
VentureBeat
@VentureBeat
How Databricks is using synthetic data to simplify evaluation of AI agents venturebeat.com/data-infrastructure/databricks-makes-ai-aโฆ
-
Matei Zaharia
@matei_zaharia
This is a big launch for our AI agent platform -- making it easier to create high quality evaluations, which is often the bottleneck for improving agents. Our researchers and engineers collaborated to automatically generate high-quality questions and provide a great curation UI.
Databricks
@databricks
Introducing new synthetic data capabilities in Mosaic AI Agent Evaluation.
Now, developers can create high-quality evaluation data sets based on their proprietary data in just minutes โ without being bottlenecked by SMEs.
How to get started๐www.databricks.com/blog/streamline-ai-agent-evaluation-wiโฆ -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
See you at NeurIPS! I'll be there Tuesday to Friday. Find me at the @databricks booth at the expo.
-
Matei Zaharia
@matei_zaharia
Congrats to the Meta team on Llama 3.3. Open weight models are advancing so rapidly and the cost to get this performance is quickly going down. We're thrilled to let users serve and customize this on @databricks starting next week.
Ahmad Al-Dahle
@Ahmad_Al_Dahle
Introducing Llama 3.3 โ a new 70B model that delivers the performance of our 405B model but is easier & more cost-efficient to run. By leveraging the latest advancements in post-training techniques including online preference optimization, this model improves core performance at a significantly lower cost, making it even more accessible to the entire open source community ๐ฅ
huggingface.co/meta-llama/Llama-3.3-70B-Instruct -
Matei Zaharia reposted
Databricks
@databricks
Thrilled to partner with @AIatMeta on the new Llama 3.3 model on Databricks. Starting next week, our customers will be able to serve the updated model to build agent systems.
Together, we're making AI more accessible & cost-effective for developers & enterprises. -
Matei Zaharia reposted
MLflow
@MLflow
MLflow Tracing shows you how your AI agents think & work.
๐ See agent chains & tool usage
๐ Track all steps & decisions
โก Auto-works w/ LangChain & AutoGen
โ Preserves error data
mlflow.org/docs/latest/llms/tracing/index.html
#mlops #ai #llmops -
Matei Zaharia reposted
Jared Quincy Davis
@jaredq_
Join us for the Compound AI Systems, Inference-time Compute Meetup @ NeurIPS 2024
Meetup for practitioners and researchers working on and interested in topics related to compound AI systems, inference-time strategies and scaling laws, networks of networks, and agentic systems.
The venue has limited space for 250 people max, so please apply below to join.
lu.ma/q5r8b67t
Timing: Dec 12th from 4-6pm local time, at the Fairmont Waterfront Ballroom.
Featuring presentations and a panel with leading experts from industry and academia.
Schedule
50 min of introduction and an industry-academia panel
15 min of 1-min featured poster lightning talks
45 min of posters and networking
Poster link
If you have a poster you'd like to bring to the event to feature during the poster/networking session, request via the following link โ docs.google.com/forms/d/e/1FAIpQLSf20SnZ0SSXPV903V647O8Qhโฆ
Panelists and organizers include:
@matei_zaharia (UC Berkeley, Databricks)
@jaredq_ (Foundry, Stanford)
@BorisHanin (Princeton, Foundry)
@mcarbin (MIT, Databricks)
@YejinChoinka (NVIDIA, UW)
@Chi_Wang_ (Google DeepMind)
@james_y_zou (Stanford)
@heathercmiller (CMU)
@ChenLingjiao (Microsoft Research)
... and others
Thanks to our event sponsors, Databricks (databricks.com) and Foundry (mlfoundry.com). -
Matei Zaharia
@matei_zaharia
Submit your talks to #dataaisummit now to reach tens of thousands of practitioners and execs! The conference will be in San Francisco next June.
Databricks
@databricks
Calling all Data + AI Innovators!
dbricks.co/4fy5e08
#dataaisummit 2025 is your chance to showcase your work to 70,000+ peers! ๐
Share insights on:
โ๏ธ Real-time data streaming
โ๏ธ Deep learning & ML
โ๏ธ BI and SQL analytics
โ๏ธ & more! -
Matei Zaharia reposted
Liana
@lianapatel_
Awesome to see ACORN delivering huge speedups for filtered vector search at Weaviate! Try it out and check out our full paper here: dl.acm.org/doi/10.1145/3654923
Weaviate AI Database
@weaviate_io
25x faster filtered search queries in 1.27? ๐คฏ
With Weaviateโs new ACORN filtered search strategy in v1.27, weโre seeing filtered search queries that are way faster than they were before! It improves upon the existing strategy to better handle negatively correlated queries and high selectivity filters.
The best part is that it doesnโt require any vector reindexing, meaning you can enable this at any time for Weaviate instances in 1.27 or above.
Join us on November 27 to learn how to enable ACORN-filtered search and for an in-depth look all the new features of 1.27: us02web.zoom.us/meeting/register/tZAtfu-tqD8tHdUnzSScmBQeโฆ
๐น @_jphwang -
Matei Zaharia
@matei_zaharia
Some surprising results on current neural rerankers by @mat_jacob1002 and the Databricks research team!
Mathew Jacob
@mat_jacob1002
It's time to revisit common assumptions in IR! Embeddings have improved drastically, but mainstream IR evals have stagnated since MSMARCO and BEIR.
We ask: on private or tricky IR tasks, are current rerankers even better? Surely, reranking as many docs as you can afford is best? -
Matei Zaharia reposted
MLflow
@MLflow
MLflow 2.18 is here!
The release includes:
๐งต Thread/process-safe fluent APIs
๐ DSPy integration
๐ฅ๏ธ Enhanced trace UI
๐ New tracing integrations
โ๏ธ Expanded LLM evaluation
Read the full release notes: mlflow.org/releases
#mlflow #ai #mlops -
Matei Zaharia reposted
#DataAISummit
@Data_AI_Summit
#dataaisummit Call for presentations now open!
Showcase your best practices, solutions and research findings. Weโre looking for sessions and lightning talks on AI, data science, BI, data engineering, ML and data warehousing.
Submit your idea:dbricks.co/4fy5e08 -
Matei Zaharia reposted
Mike Cornell
@TXMikeC
Trino joins (trino.io/docs/current/release/release-462.html) Snowflake and Dremio as being able to read Unity Catalog (UC) managed Uniform tables via UC's Iceberg REST Catalog API. Lots of great movement in the ecosystem allowing UC tables to be consumed downstream by any Delta or Iceberg client. ๐ช
-
Matei Zaharia reposted
Databricks
@databricks
Struggling with unstructured text data across millions of documents? Discover how Databricks simplifies and automates LLM inference, turning vast text into actionable insights at record speed.
Learn more about batch inference on #mosaicai Model Serving: dbricks.co/4eeg1vs -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
New interview where Sam Altman at 24:12 has an inexplicable epiphany:
> Something about the way we currently talk about [AI] & think about it feels wrong. Maybe if I had to describe it, we will shift from talking about models to talking about systems. But that will take a while. -
Matei Zaharia reposted
Delta Lake
@DeltaLakeOSS
Learn about the origins of #deltalake with Dominique Brezinski, our newest TSC member! Discover how a collaboration with @databricks & a conversation with @michaelarmbrust in 2017 turned a side project into Delta Lake. ๐
Watch the full conversation ๐www.youtube.com/live/8JOV7ImOPUk?hss_channel=tw-111926575โฆThis media couldn't be displayed. See it on the original post. -
Matei Zaharia
@matei_zaharia
We had over 270 submissions to MLSys 2025 this week. Excited to see the final program next spring! mlsys.org
-
Matei Zaharia
@matei_zaharia
You can now use MLflow to log and trace OpenAI Swarm applications. This adds to our support for GenAI tracing and MLOps in LangChain, LangGraph, LlamaIndex, AutoGen and other frameworks, giving you a consistent MLOps stack across them.
-
Matei Zaharia reposted
James Zou
@james_y_zou
We derive *inference compute scaling laws* to characterize when more #llm calls help and when they *hurt* performance.
Updated #neurips2024 paper openreview.net/pdf?id=m5106RRLgx
Great job by @ChenLingjiao + awesome collaborators @jaredq_ @BorisHanin @pbailis Ion Stoica @matei_zaharia!
lingjiao chen
@ChenLingjiao
A surprising finding: a larger number of LLM calls can incur worse performance of compound AI systems! Why and what is the desired number of LLM calls? We initialize the study of scaling properties of compound AI systems both theoretically and empirically: arxiv.org/pdf/2403.02419.pdf
-
Matei Zaharia reposted
Omar Khattab
@lateinteraction
Compound AI Systems & The DSPy Framework
www.youtube.com/watch?v=JEMYuzrKLUw -
Matei Zaharia
@matei_zaharia
We've expanded our collaboration with Dun & Bradstreet to bring their industry-leading commercial data on hundreds of millions of businesses to the Databricks Marketplace! Every Databricks customer can now easily connect to this data. sprou.tt/1SN4eUIRS2h
-
Matei Zaharia reposted
Liana
@lianapatel_
This is so cool! Check out this demo from @_asimbiswal for asking questions over large tables, like election contributions๐ณ๏ธI have so many questions to ask๐
โจAnd it's powered by Text2LOTUS! NL questions are converted to LOTUS programs for optimized LLM-powered data processing!
Asim Biswal
@_asimbiswal
๐งต Excited to share a demo for our recent work on Table Augmented Generation (TAG)! Ask interesting natural language queries over structured data!
fe64014b8540250c8f.gradio.live -
Matei Zaharia reposted
Asim Biswal
@_asimbiswal
๐งต Excited to share a demo for our recent work on Table Augmented Generation (TAG)! Ask interesting natural language queries over structured data!
fe64014b8540250c8f.gradio.live -
Matei Zaharia reposted
Databricks
@databricks
Databricks Apps is the fastest way to build applications on the Databricks Data Intelligence Platform!
Now in Public Preview on AWS and Azure, developers can create applications with popular frameworks, serverless deployment, and built-in governance: dbricks.co/40jjV2z -
Matei Zaharia reposted
Databricks
@databricks
Weโre thrilled to partner with @ServiceNow to deliver Zero Copy, bi-directional integration with the Databricks Data Intelligence Platform, powered by Delta Sharing!
This integration will help our customers turn data into instant, AI-powered action.
ServiceNow News
@ServiceNowNews
โ A Zero Copy partnership with @Databricks: supercharges machine learning and AI capabilitiesโ
Databricksโ Delta Sharing will enable ServiceNow to offer Zero Copy, high-bandwidth, bi-directional, and secure integration with the Databricks Data Intelligence Platform so customers can turn data and insights into instant, AI-powered action. โ
Learn more: www.servicenow.com/company/media/press-room/databricks-coโฆ -
Matei Zaharia
@matei_zaharia
Our new batch inference offering from @databricks launched today, making it easy to get reliable, low-cost inference right from SQL. No need to export data to another system or format, just call ai_query and we'll automatically scale and mange resources. www.databricks.com/blog/introducing-simple-fast-and-scalaโฆ
-
Matei Zaharia reposted
Liana
@lianapatel_
Awesome to see 10x faster hybrid search using ACORN in production! Really exciting release from @weaviate_io
John Trengrove
@trengrj
-
Matei Zaharia reposted
MLflow
@MLflow
MLflow 2.17 enhances ChatModel, improves GenAI evaluation, and adds audio support among other updates
๐ Improved Tracing UI
๐ Callable GenAI metrics
๐ LlamaIndex & LangChain enhancements
Release notes: mlflow.org/releases -
Matei Zaharia reposted
Databricks
@databricks
Embedding for AI/BI Dashboards is now available! Seamlessly integrate Databricks AI/BI Dashboards into your internal websites and applications. LINK
Key Features:
- Integration flexibility
- Secure access
- Optimized performance
Learn more: dbricks.co/3Y22dOn -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
New blog post! @quinn_leng, @JacobianNeuro, @sam_havens, @matei_zaharia, and @mcarbin have released part 2 of our investigation into long-context RAG!
Read on for the full details: www.databricks.com/blog/long-context-rag-capabilities-opeโฆ
(1/5) -
Matei Zaharia
@matei_zaharia
Super excited by what the team has built with Apps, supporting all the major Python frameworks for deploying internal data or AI apps directly from your workspace. Check it out today!
Databricks
@databricks
Introducing Databricks Apps โ a new way to build internal data + AI applications.
Build data visualizations, AI applications and self-service analytics directly on the Databricks Data Intelligence Platform. Now in Public Preview on AWS and Azure. dbricks.co/4dLsQxa -
Matei Zaharia reposted
Kumo
@Kumo_ai_team
Kumo AI, in partnership with Databricks, is transforming predictive modeling. Our innovative use of #gnns and #llms provides highly accurate predictions across extensive datasets, eliminating complex feature engineering.
๐ Read the full blog: docs.nvidia.com/sdgm/client/kumo-relational/about-kumo-reโฆ -
Matei Zaharia reposted
Unity Catalog
@unitycatalog_io
We are very happy to announce #unitycatalog 0.2 is now published with new and updated features including:
โ #identity, #authentication, and #authorization: You can now configure the UC server to authenticate with an external identity provider
โ ML Models: You can now store #mlmodels in UC and use them with @MLflow >=2.16.1
โ Credential Vending: Expanded support for credential vending APIs
โ @ApacheSpark and @DeltaLakeOSS Integration: Support for operating on tables in UC using Spark 3.5.3 and Delta 3.2.1
โ User Interface: Support for a new UI for exploring UC including support login via Google Authentication
This release was created by 63 contributors, with 31 new contributors!
For more information, check out the release notes at github.com/unitycatalog/unitycatalog/releases/tag/v0.2.0 -
Matei Zaharia reposted
Naveen Rao
@NaveenGRao
Some really cool functionality dropped in @databricks GenAI. Our customers often struggle to understand the quality of their gen AI systems. Is the answer useful? Correct? Well-grounded? Check out auto-eval when build compound AI systems in Databricks!
www.databricks.com/blog/build-compound-ai-systems-faster-โฆ -
Matei Zaharia reposted
Databricks
@databricks
Over 7k customers use #databrickssql as their data warehouse. We recently added new features & performance improvements that make it simpler, faster & lower cost. Including:
- AI-powered performance
- AI Assistant for SQL Analysts
- AI Functions updates
dbricks.co/3XGxZSh -
Matei Zaharia reposted
AI at Meta
@AIatMeta
A few technical insights on our lightweight Llama 3.2 1B & 3B models. ๐ฆ๐งต
-
Matei Zaharia
@matei_zaharia
Super excited about the new 1B and 3B Llama models and multimodal Llama! The cost-performance of open source AI is improving dramatically, and private, device-local AI is becoming practical with these models. Proud that @databricks is a launch partner.
AI at Meta
@AIatMeta
๐ฃ Introducing Llama 3.2: Lightweight models for edge devices, vision models and more!
Whatโs new?
โขย Llama 3.2 1B & 3B models deliver state-of-the-art capabilities for their class for several on-device use cases โ with support for @Arm, @MediaTek & @Qualcomm on day one.
โขย Llama 3.2 11B & 90B vision models deliver performance competitive with leading closed models โ and can be used as drop-in replacements for Llama 3.1 8B & 70B.
โข New Llama Guard models to support multimodal use cases and edge deployments.
โขย The first official distro of Llama Stack simplifies and supercharges the way developers & enterprises can build around Llama to support agentic applications and more.
Details in the full announcement โก๏ธ go.fb.me/229ug4
Download Llama 3.2 models โก๏ธ go.fb.me/w63yfd
These models are available to download now directly from Meta and @HuggingFace โ and will be available across offerings from 25+ partners that are rolling out starting today, including @accenture, @awscloud, @AMD, @azure, @Databricks, @Dell, @Deloitte, @FireworksAI_HQ, @GoogleCloud, @GroqInc, @IBMwatsonx, @Infosys, @Intel, @kaggle, @NVIDIA, @OracleCloud, @PwC, @scale_AI, @snowflakeDB, @togethercompute and more.
With Llama 3.2 weโre making it possible to run Llama in even more places, with even more flexible capabilities. Weโve said it before and weโll say it again: open source AI is how we ensure that these innovations reflect the global community theyโre built for and benefit everyone. Weโre continuing our drive to make open source the standard with Llama 3.2. -
Matei Zaharia
@matei_zaharia
Great post on how AI can be engineered "brick-by-brick" to get the best results, including through the design of compound AI systems. The teams that figure out how to get the right data pipelines and system design are the ones getting transformational results.
Maithra Raghu
@maithra_raghu
The best AIs will be constructed not emergent.
Some predictions on the next era of AIs with @ericschmidt
We argue that the best AIs will be constructed (purpose built) rather than purely emergent.
General purpose foundation models will serve as important infrastructure (not applications) with close tie-ins to cloud and consumer applications.
AI training will be a key differentiator between the best AIs and the rest, with prompting being โflashlightโ (versatile but less powerful + precise) and training a โlaser beamโ (powerful, precisely controllable).
This is especially important as we transition to AI agents (still in the future!), which can tackle entire workflows. But in doing so we face challenges with compounding errors, which demand the most performant AI capabilities.
The real world has a combinatorial explosion of workflows, and we think it unlikely that they consolidate around a single future foundation model. We outline a โbrick by brickโ AI construction that has complex capabilities calling simpler capabilities like subroutines. We see this structure in many of the powerful AIs today, with more such to be built in the future. -
Matei Zaharia
@matei_zaharia
It was great chatting with @Ahmad_Al_Dahle about the growing Llama ecosystem at Meta's Connect conference! Llama has transformed both the industry adoption of LLMs and the AI research community.
Ahmad Al-Dahle
@Ahmad_Al_Dahle
Had an awesome time chatting with @matei_zaharia from @Databricks, @karibriski from @NVIDIA and @adamse from @AWS on the latest trends and challenges facing the AI community at a pre-Connect welcome for Llama developers. Excited to share more news tomorrow at Connect!
-
Matei Zaharia reposted
Ahmad Al-Dahle
@Ahmad_Al_Dahle
Had an awesome time chatting with @matei_zaharia from @Databricks, @karibriski from @NVIDIA and @adamse from @AWS on the latest trends and challenges facing the AI community at a pre-Connect welcome for Llama developers. Excited to share more news tomorrow at Connect!
-
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
At @databricks, we want to help customers build more #inference-friendly #llms. With MixAttention architecture, you can maintain model quality while improving inference speed and reducing memory footprint: www.databricks.com/blog/mixattention
-
Matei Zaharia reposted
Databricks
@databricks
Introducing the Databricks Generative AI Startup Challenge โ a competition for startups using #genai to build innovative products powered by the Databricks Data Intelligence Platform!
Participate for a chance to win up to $1M in venture funding & prizes: dbricks.co/3Bd9bso -
Matei Zaharia reposted
Christopher Potts
@ChrisGPotts
All LLM evaluations are system evaluations. The LLM just sits there on disk. To get it do something, you need at least a prompt and a sampling strategy. Once you choose these, you have a system. The most informative evaluations will use optimal combinations of system components.
-
Matei Zaharia
@matei_zaharia
Really cool to see OpenAI o1 launched today. It's another example of the trend towards compound AI systems, not models, getting the best AI results. I'm sure that future versions will not only scale inference, but also use tools (coding, search, etc) for better results.
Matei Zaharia
@matei_zaharia
Interesting trend in AI: the best results are increasingly obtained by compound systems, not monolithic models.
AlphaCode, ChatGPT+, Gemini are examples.
In this post, we discuss why this is and emerging research on designing & optimizing such systems.
bair.berkeley.edu/blog/2024/02/18/compound-ai-systems/
Matei Zaharia
@matei_zaharia
There are lots of ways to combine models and tools to get better results, so it will be interesting to see which ones do best for which tasks. We talked about some of them here: bair.berkeley.edu/blog/2024/02/18/compound-ai-systems/
-
Matei Zaharia reposted
Quentin Lhoest ๐ค
@lhoestq
๐คHugging Face Datasets users rejoice !
I made a few lines of code for โจPySparkโจ to read/write from/to HF Datasets. All distributed and optimized !
Code snippet / docs and JupyterLab demo below ๐งก -
Matei Zaharia
@matei_zaharia
AI Gateways are a critical pattern to use LLMs in production, allowing you to easily switch between models, log events, and implement security, rate limiting and cost control. We've just updated Databricks AI Gateway with a slew of new features that work across providers and OSS.
Databricks
@databricks
Thrilled to introduce new updates to #mosaicai Gateway! Simplified, secure & governed AI for all your GenAI models.
This release adds advanced features in usage tracking, payload logging & guardrails to help customers accelerate their AI initiatives. dbricks.co/3XClhUs -
Matei Zaharia
@matei_zaharia
Building AI judges for real-world apps is hard -- unlike academic benchmarks, many of these have long answers in complex domains. Here's how we improved Databricks Agent Eval for these use cases to perform >10% better on customer datasets: www.databricks.com/blog/databricks-announces-significant-โฆ
Matei Zaharia
@matei_zaharia
Difference in performance of our new judge and some open source ones between customer and academic datasets:
-
Matei Zaharia reposted
Omar Khattab
@lateinteraction
๐ Thoughts on Research Impact in AI.
Grad students often ask: how do I do research that makes a difference in the current, crowded AI space?
This is a blogpost that summarizes my perspective in six guidelines for making research impact via open-source artifacts. Link below. -
Matei Zaharia
@matei_zaharia
I'm thrilled to serve as general chair of #mlsys 2025. The call for papers is now out: submit your work by Oct 31st at mlsys.org. We're super fortunate to have @CelineLinatGT and Gauri Joshi as program chairs.
-
Matei Zaharia reposted
Tianqi Chen
@tqchenml
#mlsys2025 call for papers is out! The conference will be led by the general chair @matei_zaharia , PC chairs @CelineLinatGT, and Gauri Joshi. Consider submitting and bringing your latest works in AI and systemsโmore details at mlsys.org.
-
Matei Zaharia reposted
Databricks
@databricks
Hybrid search in #mosaicai Vector Search is now GA!
This powerful feature combines the strength of pre-trained embedding models with keyword search flexibility.
Explore how it works and how to use it to improve your search results: www.databricks.com/blog/announcing-hybrid-search-general-โฆ -
Matei Zaharia reposted
Liana
@lianapatel_
Want to answer NL questions over your data?
Introducing Table Augmented Generation (TAG)!
Joint work w/ the amazing @matei_zaharia @guestrin @profjoeyg @_asimbiswal @sid_jha1 @AmogKamsetty @LynnLiu41887950
๐ Paper: arxiv.org/abs/2408.14717
๐ ๏ธ Code: github.com/tag-research/tag-bench
๐งต -
Matei Zaharia reposted
Zack Ankner
@ZackAnkner
Excited to announce our new work: Critique-out-Loud (CLoud) reward models. CLoud reward models first produce a chain of thought critique of the input before predicting a scalar reward, allowing reward models to reason explicitly instead of implicitly!
arxiv.org/abs/2408.11791 -
Matei Zaharia
@matei_zaharia
DSPy has helped set state of the art results in multiple AI tasks by automatically tuning complex LLM pipelines and systems. Join us in Mountain View this Thursday for an intro to DSPy and some of the latest research around it.
Databricks AI Research
@DbrxMosaicAI
Questions about the #dspy roadmap? Meet the authors at the South Bay GenAI meetup in Mountain View this Thursday! @lateinteraction and @arnav_thebigman of @databricks, @kristahopsalong and Dilara Soylu of @stanfordnlp, will be presenting.
RSVP: www.meetup.com/gen-ai/events/302305291/ -
Matei Zaharia
@matei_zaharia
Welcome Omar, and really excited to keep working together on research along with the DSPy community.
Omar Khattab
@lateinteraction
Some personal news: I'm thrilled to have joined @Databricks @DbrxMosaicAI as a Research Scientist last month, before I start as MIT faculty in July 2025!
Expect increased investment into the open-source DSPy community, new research, & strong emphasis on production concerns ๐งต. -
Matei Zaharia reposted
Dan Biderman
@dan_biderman
In May, LLM PEFT expert @danielhanchen carefully read our paper and posted his thoughts here. We took his suggestions to heart, and Daniel now appears in the Acknowledgements section of our published paper.
Daniel Han
@danielhanchen
My new take on LoRA Learns Less & Forgets Less:
1. Authors added gate_proj, used a=2*rank from prev suggestions. Prev gap on LoRA doing worse shrinks
2. LoRA does well on diverse datasets like Tulu
3. Lots of nuggets in openreview.net/pdf?id=aloEru2qCG - great work @dan_biderman & team! -
Matei Zaharia
@matei_zaharia
A great roadmap ahead for DSPy.
Omar Khattab
@lateinteraction
๐งตWhat's next in DSPy 2.5? And DSPy 3.0?
I'm excited to share an early sketch of the DSPy Roadmap, a document we'll expand and maintain as more DSPy releases ramp up.
The goal is to communicate our objectives, milestones, & efforts and to solicit inputโand help!โfrom everyone. -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
Function calling significantly enhances the utility of LLMs in real-world applications; however, evaluating and improving this capability isn't easy โ and no one benchmark tells the whole story. Learn more about our approach in the latest blog from @databricks:
-
Matei Zaharia reposted
Dan Biderman
@dan_biderman
*LoRA Learns Less and Forgets Less* is now out in its definitive edition in TMLR๐ Checkout the latest numbers fresh from the @DbrxMosaicAI oven ๐จโ๐ณ
Certified papers at TMLR
@TmlrCert
New #featuredcertification:
LoRA Learns Less and Forgets Less
Dan Biderman, Jacob Portes, Jose Javier Gonzalez Ortiz et al.
openreview.net/forum?id=aloEru2qCG
#learns #regularization #rank -
Matei Zaharia
@matei_zaharia
Not a problem with Lakehouse.
Roshan Patel
@roshanpateI
my friend works in fashion. i set her up with one of my tech homies. this is how it went.
-
Matei Zaharia
@matei_zaharia
Super cool work. Amazing to see how far the late interaction retrieval architecture of ColBERT still gets us today, with tiny models!
Ben Claviรฉ
@bclavie
๐Happy to finally release answerai-colbert-small-v1: the small but mighty @answerdotai ColBERT.
It might not be able to count the number of "r"s in words, but it can definitely find the instructions on how to do that.
With just 33M params, it beats even `bge-base` on BEIR! -
Matei Zaharia
@matei_zaharia
Does long context solve RAG? We found that many long-context models fail in specific and weird ways as you grow context length, making the optimal system design non-obvious. Some models tend to say there's a copyright issue, some tend to summarize, etc. www.databricks.com/blog/long-context-rag-performance-llms
-
Matei Zaharia reposted
Deepti Raghavan
@deeptir18
I'm very excited to be starting at @BrownCSDept this fall!
Brown CS
@BrownCSDept
Please welcome Deepti Raghavan, joining us this fall as assistant professor! A recent graduate of @Stanford, her research interests focus on operating systems, networking, and machine learning systems: cs.brown.edu/news/2024/08/12/deepti-raghavan-joins-brown-โฆ
-
Matei Zaharia reposted
Shadaj Laddad
@ShadajL
The SF Distributed Systems Meetup (now under the SF Systems Club umbrella) is back! Join us 8/29 at @Databricks SF for an exciting evening featuring talks by Ben Hindman (co-creator of Mesos) and community members! lu.ma/x17bg5fh
-
Matei Zaharia reposted
Databricks
@databricks
Lakehouse Federation makes it simple for organizations to discover, query, and govern all your data in one place, no matter where it lives
Now in GA, see the latest capabilities in Lakehouse Federation โ and whatโs coming next.
dbricks.co/3A56EQr -
Matei Zaharia
@matei_zaharia
Databricks Clean Rooms are now in public preview, letting you do private joint computation with any API in Databricks (SQL, Python, R, Apache Spark, ML, GenAI and more) combining data from multiple organizations on different clouds and platforms. www.databricks.com/blog/databricks-clean-rooms-privacy-saโฆ
Matei Zaharia
@matei_zaharia
We think this will be a game-changer for secure collaboration in finance, media, CPG, HLS, manufacturing and other industries. Check out how partners like LiveRamp and Mastercard have been working with Clean Rooms in our blog.
-
Matei Zaharia reposted
Databricks
@databricks
Databricks Clean Rooms enables collaboration with partners in a privacy-safe manner without relinquishing control over sensitive data.
Key features:
Any language, any workload
Any cloud, no replication
Any scale, any trust level
Learn how it works ๐
dbricks.co/4fykWt0 -
Matei Zaharia reposted
Cody Blakeney
@code_star
Weโre hiring researcher engineers at @DbrxMosaicAI! Interested and think you might be a good fit? DM me!
-
Matei Zaharia reposted
Databricks
@databricks
LakeFlow Connect is now in Public Preview for SQL Server, Salesforce, & Workday!
These connectors provide a simple & efficient way to ingest data into the Data Intelligence Platform, allowing users to spend less time building complex ingestion pipelines. dbricks.co/4dk60gJ -
Matei Zaharia
@matei_zaharia
Data sharing features are often locked into one platform. We started #deltasharing as the first open protocol for data sharing and itโs taking off: 40% of our customersโ shares go outside Databricks! Read how @Atlassian, @Nasdaq, @Oracle and others use it: www.databricks.com/blog/democratizing-data-sharing-platfoโฆ
-
Matei Zaharia reposted
LlamaIndex ๐ฆ
@llama_index
MLflow is a unified platform to manage model development, deployment, and management. Now it comes in LlamaIndex flavor!
โก๏ธ Tracking lets you manage your prompts, LLMs, retrievers, tools, config and more
โก๏ธ Model packages your LlamaIndex engine and all its dependencies into a single deployable target
โก๏ธ Evaluate helps you evaluate the performance of your genAI application
โก๏ธ Tracing helps you monitor and debug your application
Check out the quick intro in our docs:
docs.llamaindex.ai/en/latest/module_guides/observability/
And full documentation in theirs:
mlflow.org/docs/latest/llms/llama-index/index.html
MLflow
@MLflow
๐ MLflow 2.15.0 is here and includes major features like native @llama_index integration for #genai apps, @OpenAI tracing, enhanced model validation, custom metrics logging, & full @Databricks SDK integration. ๐ฅณ
Check out the release notes! ๐ github.com/mlflow/mlflow/releases/tag/v2.15.0 -
Matei Zaharia reposted
MLflow
@MLflow
๐ MLflow 2.15.0 is here and includes major features like native @llama_index integration for #genai apps, @OpenAI tracing, enhanced model validation, custom metrics logging, & full @Databricks SDK integration. ๐ฅณ
Check out the release notes! ๐ github.com/mlflow/mlflow/releases/tag/v2.15.0 -
Matei Zaharia reposted
Databricks
@databricks
Serverless compute is now GA! โ
Focus on writing code while we handle the rest. Enjoy fully managed compute infrastructure with fast workload startup, high reliability, and simple operation.
Learn more about our latest updates: www.databricks.com/blog/announcing-general-availability-sโฆ -
Matei Zaharia reposted
Rohan Paul
@rohanpaul_ai
Llama 3.1 405B is at No-2 spot outranking GPT-4-Turbo, in the new ZebraLogic reasoning benchmark.
The benchmark consists of 1,000 logic grid puzzles. -
Matei Zaharia
@matei_zaharia
We're hosting the Berkeley LLM Meetup next week at Databricks, with talks by #dspy's @michaelryan207 on prompt optimization, and SWE-Agent's creator @_carlosejimenez on automating software engineering with LLMs. Sign up here:
lu.ma/berkeley-llm-meetup-july -
Matei Zaharia reposted
Boris Hanin
@BorisHanin
Fun colab with co-authors @jaredq_, @ChenLingjiao, @pbailis, Ion Stoica, and @matei_zaharia on principles for combining LLM calls.
tl;dr โ when verification of correct answers is easier than generation with classical algorithms, it seems like this is also true for LLMs!
arxiv.org/abs/2407.16831
Toy example: consider factoring a three digit integer into a product of two primes. Probability GPT-4o generates correct answer is just under 4%. But probability that GPT-4o can correctly classify whether a proposed factorization is correct is about 90%.
Consequence โ itโs a good idea to use a bunch of calls to generate answers and then to verify easy proposal. In the factorization task, doing this 10 generators gives about 36% accuracy!
This continues to hold for โrealโ tasks like MMLU as well, where we find significant gains (around 6%-8%) from this kind of many generators and then one verifier-based judge approach on sub-topics like High School Math, Abstract Algebra, Formal Logic and others. -
Matei Zaharia
@matei_zaharia
Really cool result, again achieved using a compound AI system for this domain using multiple model calls, fine-tuning, and external tools. The kind of system design and training data generation here is a hint of what we'll need for other domain-specific AI.
Google DeepMind
@GoogleDeepMind
Weโre presenting the first AI to solve International Mathematical Olympiad problems at a silver medalist level.๐ฅ
It combines AlphaProof, a new breakthrough model for formal reasoning, and AlphaGeometry 2, an improved version of our previous system. ๐งต dpmd.ai/imo-silver -
Matei Zaharia
@matei_zaharia
Cool research by @jaredq_ and team on determining how compound AI systems can scale when they involve verification. We also show that on AI benchmarks like MMLU, different tasks have different levels of verifiability by LLMs, so chaining can help more in some than others.
Jared Quincy Davis
@jaredq_
In this article, I and co-authors @BorisHanin, @ChenLingjiao, @pbailis, Ion Stoica, and @matei_zaharia explore one of the most powerful ideas we have yet discovered to inform compound AI systems design:ย verifiability.
In common situations where practitioners are willing to expend a higher budget to go beyond the capabilities frontier accessible to today's state-of-the-art (SOTA) monolithic models, they may be willing to invoke many model inference calls, composing them into โnetworks of networksโ (NoNs) of sorts.
The question then becomes: what principles should guide the composition of these NoNs? Inspired by TCS and PCP notions that often verification is easier than generation (as holds for classical problems like graph coloring), we construct โbest-of-Kโ or โjudge-basedโ Compound AI Systems, which explicitly separate โgeneratorโ modules from โverifierโ modules. We posit that these systems are particularly helpful for โreasoning-basedโ or โprocedural-knowledgeโ oriented tasks, which are often more verifiable, less so for factual or declarative-knowledge settings (and we can use these systems partly to help characterize tasks, including subjects in the MMLU, along these lines). Very neatly, it turns out we can analytically characterize when these systems can confer a gain and predict the gainโs extent.
We hope people will extend these ideas to tackle some of the reasoning-oriented application frontiers that are a bit beyond the range of todayโs SOTA models.
Arxiv: arxiv.org/pdf/2407.16831 -
Matei Zaharia
@matei_zaharia
How can you make LLM-as-judge reliable in specialized domains? Our applied AI team developed a simple but effective approach called Grading Notes that we've been using in Databricks Assistant. We think this can help anyone doing domain-specific AI! www.databricks.com/blog/enhancing-llm-as-a-judge-with-graโฆ
Matei Zaharia
@matei_zaharia
Grading Notes are very lightweight annotations on each question that help an LLM judge answers, and lead to high judge alignment with human ratings without expensive manual annotation of all answers. Kudos to Yi Liu and Ritendra Datta for creating and operationalizing this!
-
Matei Zaharia reposted
Patrick Wendell
@pwendell
Meta AI's Llama release today is really important, likely the most important open source AI announcement ever. Many people don't understand why:
1. The quality gap between the best proprietary and open models has effectively vanished. No one really knew if this gap would get bigger or smaller over time, but the answer is here now. More importantly, Meta is already working on Llama 4... they are not messing around. There's an outside chance that open models actually surpass the quality of closed models in the future. That's something no one would have thought possible 12 months ago.
2. The Llama license now allows you to use generated outputs to train your own customized models. Llama 405b is the first frontier-quality model that allows you to do this. Almost every AI product can benefit from this... distilling models into smaller footprints is a huge win for driving costs down and quality up for production AI applications.
3. Llama really doubled down on stuff enterprises need in these newer models. The new models are best in class on tool use as well as have a 128k context window which is really critical for applications that use complex chaining, which is extremely prevalent.
The big winner in all this is companies and consumers deploying AI. The Llama models will accelerate existing trends towards lower costs and broad availability of AI reasoning for the next generation of products.
@databricks is super excited to be partnering with @Meta on making this model available to our customers. www.databricks.com/blog/new-standard-open-source-ai-meta-โฆ. -
Matei Zaharia
@matei_zaharia
Awesome to see so much open science shared in the Llama 3.1 paper, including a shoutout to @code_star and @mansiege's work. There are also great details on RLHF and other aspects of Llama 3.1.
Cody Blakeney
@code_star
If you want to learn more about how the Llama3 team used annealing to assess data quality check out our paper! At ICML? go chat with @mansiege about it!
-
Matei Zaharia
@matei_zaharia
Congrats @AIatMeta on the Llama 3.1 release and super thrilled to be a launch partner! Llama 3.1 is a huge step forward for open models at all scales.
Databricks
@databricks
Thrilled to offer the @AIatMeta Llama 3.1 series of models on Databricks! These models expand context length to 128K, add multilingual capabilities + include Llama 3.1 405B โ the largest + highest-quality openly available foundation model. dbricks.co/4dcJpC3
-
Matei Zaharia reposted
AI at Meta
@AIatMeta
Starting today, open source is leading the way. Introducing Llama 3.1: Our most capable models yet.
Today weโre releasing a collection of new Llama 3.1 models including our long awaited 405B. These models deliver improved reasoning capabilities, a larger 128K token context window and improved support for 8 languages among other improvements. Llama 3.1 405B rivals leading closed source models on state-of-the-art capabilities across a range of tasks in general knowledge, steerability, math, tool use and multilingual translation.
The models are available to download now directly from Meta or @huggingface. With todayโs release the ecosystem is also ready to go with 25+ partners rolling out our latest models โ including @awscloud, @nvidia, @databricks, @groqinc, @dell, @azure and @googlecloud ready on day one.
More details in the full announcement โก๏ธ go.fb.me/tpuhb6
Download Llama 3.1 models โก๏ธ go.fb.me/vq04tr
With these releases weโre setting the stage for unprecedented new opportunities and we canโt wait to see the innovation our newest models will unlock across all levels of the AI community.This media couldn't be displayed. See it on the original post. -
Matei Zaharia reposted
Databricks AI Research
@DbrxMosaicAI
The next @berkeley_ai #llm meetup will be held at @databricks HQ in SF! July 31, 5:30-8:00 PM PDT
Come see @michaelryan207 (DSPy) and @_carlosejimenez (SWE-Agent/SWE-bench) share about their projects with the Bay Area #ai community!
RSVP here: lu.ma/berkeley-llm-meetup-july -
Matei Zaharia reposted
Naveen Rao
@NaveenGRao
Finetuning + RAG FTW! @DbrxMosaicAI/@databricks we're building products to continuously improve compound AI system quality by customizing with your data for your application. Fine-tuning in GA..check out the blog: www.databricks.com/blog/introducing-mosaic-ai-model-trainโฆ
-
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
Databricks is having an event at ICML on Wednesday! If you want the registration link, DM me. (I sadly won't be there, but many awesome members of our team will be)
-
Matei Zaharia reposted
Mihir Patel
@mvpatel2000
I'll be at ICML! Come say hi if you're interested in performance engineering, ML infra, open source, or if you just wanna hang :)
-
Matei Zaharia
@matei_zaharia
How can you analyze large text datasets with LLMs? This new research project by @lianapatel_ introduces "semantic operators" for bulk processing and optimizations for them.
Try our open source implementation with pandas-like APIs, and tell us what other analyses you'd like.
Liana
@lianapatel_
Super excited to share our work on LOTUS, a query engine for reasoning over large corpuses of data with LLMs!
Joint work w/ the amazing @sid_jha1, @matei_zaharia & @guestrin
Read the paper: www.arxiv.org/abs/2407.11418
Try out the code: github.com/stanford-futuredata/lotus
๐งต๐ -
Matei Zaharia reposted
Liana
@lianapatel_
Super excited to share our work on LOTUS, a query engine for reasoning over large corpuses of data with LLMs!
Joint work w/ the amazing @sid_jha1, @matei_zaharia & @guestrin
Read the paper: www.arxiv.org/abs/2407.11418
Try out the code: github.com/stanford-futuredata/lotus
๐งต๐ -
Matei Zaharia reposted
Databricks
@databricks
Now GA: Serverless compute for Databricks Notebooks, Workflows, and Delta Live Tables!
You write the code, and we provide a fully managed compute infrastructure with fast workload startup, high reliability and simple operation. dbricks.co/4bPEVjz -
Matei Zaharia
@matei_zaharia
Great post by @celebaltech on implementing RAFT on top of @databricks fine-tuning to out-perform RAG: celebaltech.com/blogs/enhancing-rag-systems-with-fine-tunโฆ
Incidentally the RAFT paper will be presented at @COLM_conf so check it out if you're there.
Matei Zaharia
@matei_zaharia
RAFT paper: arxiv.org/abs/2403.10131
-
Matei Zaharia
@matei_zaharia
Great to see @databricks' approach to data engineering and streaming recognized in two reports:
- 2024 IDC MarketScape: Worldwide Analytic Stream Processing
- The Forrester Waveโข: Cloud Data Pipelines, Q4'23
We're making these even better with Lakeflow. sprou.tt/1gUCxSfvh8m -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
I recently had the pleasure of joining @qAmbard and Maria Zervou to discuss DBRX and our AI work at @databricks. From fine-tuning APIs to our latest models, weโre making cutting-edge AI accessible for everyone! youtu.be/K896pnum5dE
-
Matei Zaharia reposted
Databricks
@databricks
Announcing Mosaic AI Agent Framework and Agent Evaluation! Designed to help developers build and deploy high-quality Agentic and RAG apps.
Learn more: dbricks.co/3RWt7VJ -
Matei Zaharia reposted
Daniel Liden
@danjliden
Excellent post by @MLflow ambassador Awadelrahman Ahmed on what, exactly, MLflow models are. Ensuring a model works consistently across environments takes more than just the model binaries: an MLflow model also includes code, metadata, and more.
#mlops
awadrahman.medium.com/what-exactly-is-a-model-in-mlflow-cโฆ -
Matei Zaharia
@matei_zaharia
Databricks Assistant, our in-context AI, is now GA! I'm really proud of what the team built: it's one of the most effective AI assistants in the industry according to users, thanks to integrating context like related code, data, usage patterns, etc. sprou.tt/1j98qM3klMN
-
Matei Zaharia reposted
Mihir Patel
@mvpatel2000
Fun collaboration between @DbrxMosaicAI and @PyTorch team! We've been working hard to scale MoEs and PyTorch distributed to thousands of GPUs, and this is a great summary of a lot of the cool things we've added to PyTorch.
Quick rundown (1/N)
PyTorch
@PyTorch
Training MoEs at Scale with PyTorch ๐ฅ
In our latest post, we show how we scale to over three thousand GPUs using PyTorch Distributed and MegaBlocks, an efficient open-source MoE implementation in PyTorch.
Check it out: pytorch.org/blog/training-moes/?hss_channel=tw-7765855026โฆ -
Matei Zaharia reposted
Trevor Gale
@Tgale96
Awesome work ๐๐ฅ
Great to see some of these details being communicated more widely.
PyTorch
@PyTorch
Training MoEs at Scale with PyTorch ๐ฅ
In our latest post, we show how we scale to over three thousand GPUs using PyTorch Distributed and MegaBlocks, an efficient open-source MoE implementation in PyTorch.
Check it out: pytorch.org/blog/training-moes/?hss_channel=tw-7765855026โฆ -
Matei Zaharia reposted
Connor Shorten
@CShorten30
ACORN is a breakthrough in Vector Search with Filtering!! I am BEYOND EXCITED to publish the 99th Weaviate Podcast with Liana Patel and Abdel Rodriguez! ๐๏ธ๐
This podcast dives into all things ACORN! To set the stage, Vector Search with Filtering is very slow at scale for highly selective filters, such as a filter that composes <5% of the index.
There have been a few approaches to combat this such as IVF^2, that stores the oracle partition index per filter, Window Search Tree, that has a clever strategy for continuous-valued filters, or Filtered DiskANN, that modifies the pruning heuristic based on unique filter membership.
The caveat with these approaches is that they require knowing the filters you want to search with in advance, and don't generalize well to arbitrary combinations of filters, such as `city` = "Boston" AND `num_bedrooms` < 3 OR ... -- they also typically add a significant amount of memory to the Vector Database.
ACORN instead proposes a neighbor of neighbors pruning and search heuristic that increases the connectivity of the subgraph induced by the filter! This enables super fast search with minimal indexing slow downs and added memory! ๐ง
I think this is such an exciting advancement for the field of Approximate Nearest Neighbor Search, and I can't wait to see the continued use and development of Vector Search with Filtering! Major thanks to Liana and Abdel for joining the podcast!! ๐
YouTube: youtu.be/PxJ7FpbopKY -
Matei Zaharia
@matei_zaharia
There are a lot of great new partners and features for Delta Sharing this year, and itโs been growing 300% YoY to become one of the largest secure data sharing protocols in the industry (and the main cross platform one). Hereโs whatโs new:
Databricks
@databricks
We recently announced new Delta Sharing innovations that enable Data + AI success! This includes:
- GA of volume sharing and Cloudflare R2 support
- Cross-platform view sharing
- Sharing for Lakehouse Federation
and more!๐
dbricks.co/4cfLBIP -
Matei Zaharia reposted
Andrew Brust
@andrewbrust
New in @thenewstack! 'Databricks Launches Lakehouse, AI, BI and Governance Advances at Annual Summit'
thenewstack.io/databricks-launches-lakehouse-ai-bi-and-goโฆ
#dataaisummit @databricks #lakehouse #ai #bi #bionbigdata #analytics -
Matei Zaharia reposted
#DataAISummit
@Data_AI_Summit
The #dataaisummit keynote included demos of the latest @databricks announcements, including new @DbrxMosaicAI and Databricks SQL innovations โ plus, the newly launched Databricks AI/BI.
You can catch it all on-demand! www.databricks.com/dataaisummit -
Matei Zaharia reposted
Michael Ryan
@michaelryan207
MIPROv2, our new state-of-the-art optimizer for LM programs, is live in DSPy @stanfordnlp!
It's even faster, cheaper, and more accurate than MIPRO. MIPROv2 proposes instructions, bootstraps demonstrations, and optimizes combinations.
Letโs dive into a visual ๐งตof how it works! -
Matei Zaharia reposted
Liana
@lianapatel_
It was fun presenting at #sigmod2024 last week and sharing our work on ACORN, an index that supports efficient vector search while filtering on structured attributes, which is a common setting for many vector DBs.
Many folks asked if there's code available, and there is!๐งต -
Matei Zaharia
@matei_zaharia
Really proud of our team for being named a leader in the Gartner MQ on Data Science and Machine Learning again, and ranked highest in Ability to Execute! By integrating ML deeply with data platform tools, we're simplifying it in ways that other AI/ML platforms can't.
Databricks
@databricks
Databricks named a Leader in the 2024 Gartnerยฎ Magic Quadrantโข for Data Science and ML Platforms & positioned highest in Ability to Execute out of all evaluated vendors!
We believe this recognition validates our focus on GenAI & traditional data science dbricks.co/3VLPvU9 -
Matei Zaharia reposted
trevordarrell
@trevordarrell
So much Berkeley news from CVPR today... Awards! LLARVA Vision-Action Instruction Tuning! Multimodal Chatbot Arena! (1/4)
-
Matei Zaharia reposted
Shyam Nandan Upadhyay
@ShyamUpadhyayy
"Open-source models are getting really close to the best-closed models. Meanwhile, the best-closed models havenโt gotten that much better,โ said @databricks's co-founder & CTO, @matei_zaharia
I had an incredible opportunity to speak with the CTO
Read:
analyticsindiamag.com/databricks-looks-to-dominate-enterpโฆ -
Matei Zaharia reposted
Omar Khattab
@lateinteraction
๐จAnnouncing the largest study focused on *how* to optimize the prompts within LM programs, a key DSPy challenge.
Should we use LMs toโฆ Craft instructions? Self-generate examples? Handle credit assignment? Specify a Bayesian model?
By @kristahopsalong* @michaelryan207* &team๐งต -
Matei Zaharia
@matei_zaharia
Compound AI systems for the win? Makes sense that a program search approach could do well on this.
Dwarkesh Patel
@dwarkesh_sp
I asked Buck about his thoughts on ARC-AGI to prepare for interviewing @fchollet.
He tells his coworker Ryan, and within 6 days they've beat SOTA on ARC and are on the heels of average human performance. ๐คฏ
"On a held-out subset of the train set, where humans get 85% accuracy, my solution gets 72% accuracy." -
Matei Zaharia
@matei_zaharia
It was great talking with @TheRegister about the early history of @ApacheSpark and some of its current use cases. Lots more under way in Spark 4.0!
The Register
@TheRegister
How Apache Spark lit up the tech world and outshone its big data brethren www.theregister.com/software/2024/06/14/ten-years-of-apacโฆ
-
Matei Zaharia
@matei_zaharia
Awesome to see more quality open source LLMs coming out!
Bryan Catanzaro
@ctnzr
Nemotron-4-340B is released today!
* Base, Instruct, Reward models
* Permissive license
* Great for Synthetic Data Generation
* Designed to help others build their own models
* Sized for inference on 8 NVIDIA H100 GPUs
* Competitive across many tasks -
Matei Zaharia reposted
Databricks
@databricks
A snapshot of new innovations announced at #dataaisummit. New solutions for GenAI, unified governance, data sharing, and more. These include:
- Databricks AI/BI
- Unity Catalog OSS
- New Mosaic AI capabilities
- Databricks LakeFlow
- Shutterstock ImageAI
dbricks.co/4cbHOMA -
Matei Zaharia reposted
Reynold Xin
@rxin
The best data warehouse is a lakehouse! Databricks SQL (our data warehousing product on top of the Lakehouse) became GA 2.5 yrs ago, and just crossed $400m ARR. One of the fastest growing enterprise software product ever.
Tomasz Tunguz
@ttunguz
Databricks revealed some sensational growth this week, as they did last year. Exiting this quarter to $2.4 billion annual run rate, the companyโs revenue growth is accelerated year-over-year by 10 percentage points.
Net dollar retention is a major driver of growth at 140%, which is top decile. The table above shows the other data points that weโve collected through their press releases in the last two years.
The fastest growing product category mentioned is the data warehouse revenue : 100% growth, now at $400m annually, nearing 20% of revenue.
With these modest data points, we can build a basic linear regression model for what the company is worth. This model is rough with an R^2 of approximately 0.45.
Assuming Databricks continues to grow at roughly 50%, that implies the company in the public markets would be worth approximately $54b. However, the company will likely trade at a premium to this. It is one of the few companies that provides significant exposure to AI software in the public markets.
Compared to Snowflake, Databricks is growing nearly twice as quickly. Without additional data, itโs difficult to comment on the relative sales efficiency or profitability.
Databricksโ growth rate is yet another example of the rapid demand for AI infrastructure & the systems needed to power it.
tomtunguz.com/databricks-growth-2024/ -
Matei Zaharia
@matei_zaharia
The Compound AI Workshop at DAIS is kicking off with @lmthang. Super excited about our program! Thanks to the great speakers and organizers (sites.google.com/view/compound-ai-systems-workshop/home).
-
Matei Zaharia reposted
Databricks
@databricks
Introducing Databricks LakeFlow, a new solution that simplifies all aspects of data engineering through a simple, unified & intelligent experience. Easily build production-grade data pipelines to scale to the ever-growing demand for reliable #data & #ai. dbricks.co/3VAB5Ge
-
Matei Zaharia reposted
Neil Ramaswamy
@entersudonym
Just announced at the Data + AI Summit: streaming on @databricks, powered by Structured Streaming, now has a real-time mode that is 10x-30x faster (in the p99!) than micro-batch mode!
It's been a privilege to architect and implement major parts of this. Our team is incredible! -
Matei Zaharia
@matei_zaharia
We just posted the first release of open source Unity Catalog! It supports tables, unstructured data, and AI, and we have a great set of partners across data and AI integrating with it. Read more at www.databricks.com/blog/open-sourcing-unity-catalog
Databricks
@databricks
.@matei_zaharia just open sourced Unity Catalog LIVE at #dataaisummit!
-
Matei Zaharia reposted
Dan Pechi
@danpechi
@lateinteraction sharing some of our work using DSPy at @databricks #dataaisummit !
-
Matei Zaharia reposted
Glean
@glean
Glean ๐ค @Databricks Genie
Our partnership with @Databricks enables you to query and analyze complex data directly within Glean, leveraging Genie's powerful capabilities to process structured data. www.glean.com/blog/glean-databricks-genie-announce -
Matei Zaharia reposted
Databricks
@databricks
Databricks AI/BI is a new type of BI product that understands your dataโs semantics & democratizes insights:
- AI/BI Dashboards: AI powered, low-code dashboarding
- Genie: learns underlying data, flexibly answers questions
Built on a compound AI system. dbricks.co/3VnMeJc -
Matei Zaharia reposted
Jonathan Frankle
@jefrankle
I guess I should probably include some images, since this is an image generation model. I'm so proud of @CoryMosaicML, @landanjs, Austin Jacobson, @jazco, and our extraordinary collaborators at @Shutterstock.
Jonathan Frankle
@jefrankle
Collaborating with @Shutterstock has been a highlight of my research career. The model we made together is proof that you can build great AI on trusted data in partnership with artists and creators. The path to a bright AI future is through collaboration. www.fastcompany.com/91139544/databricks-shutterstock-ai-iโฆ
-
Matei Zaharia
@matei_zaharia
This is a great example of companies turning their data into new AI products: @Shutterstock partnered with @Databricks to create this state of the art text-to-image model. Awesome partnership with the @DbrxMosaicAI research team to make this fast and high-quality.
jasmine collins
@jazco
today we're announcing our @DbrxMosaicAI x @Shutterstock partnership, and a new text-to-image diffusion model: โจImageAI!!โจ
this model is geared towards enterprise use cases and is trained exclusively on shutterstock's trusted data catalog!
www.databricks.com/company/newsroom/press-releases/introdโฆ -
Matei Zaharia
@matei_zaharia
Super excited about the new Agent Framework, Tool Catalog, Vector Search, Evaluation and Training capabilities we launched today in Mosaic AI. We see more companies building compound AI systems, and we have created an end-to-end environment to do this. www.databricks.com/blog/mosaic-ai-build-and-deploy-producโฆ
-
Matei Zaharia
@matei_zaharia
We're serious about an open, compatible foundation for all enterprise data. Very excited to work with the @tabulario team to make the open source data ecosystem even better.
Ali Ghodsi
@alighodsi
Databricks to acquire @tabulario, a data platform from the original creators of Apache Iceberg. Together, we will bring format compatibility to the lakehouse for @DeltaLakeOSS and @ApacheIceberg
www.databricks.com/blog/databricks-tabular -
Matei Zaharia
@matei_zaharia
I'm co-organizing the inaugural research workshop on Compound AI Systems on June 13th: sites.google.com/view/compound-ai-systems-workshop/home . Send in your work on designing & optimizing such systems!
Thrilled to have @RichardSocher, @MonicaSLam and @polynoamial as speakers, and host this at @Data_AI_Summit. -
Matei Zaharia
@matei_zaharia
Interesting trend in AI: the best results are increasingly obtained by compound systems, not monolithic models.
AlphaCode, ChatGPT+, Gemini are examples.
In this post, we discuss why this is and emerging research on designing & optimizing such systems.
bair.berkeley.edu/blog/2024/02/18/compound-ai-systems/ -
Matei Zaharia
@matei_zaharia
Super cool work by @haoliuhl and @wilson1yan using Ring Attention. A multimodal 7B model with 1M context length.
Aran Komatsuzaki
@arankomatsuzaki
World Model on Million-Length Video And Language With RingAttention
Open-sources 7B models capable of processing long text documents and videos of over 1M tokens
proj: largeworldmodel.github.io
abs: arxiv.org/abs/2402.08268 -
Matei Zaharia
@matei_zaharia
Lots of people are wondering whether #gpt4 and #chatgpt's performance has been changing over time, so Lingjiao Chen, @james_y_zou and I measured it. We found big changes including some large decreases in some problem-solving tasks: arxiv.org/pdf/2307.09009.pdf
-
Matei Zaharia
@matei_zaharia
MLflow just added first-class support for LLMs, including integrations with @huggingface transformers/pipelines, @OpenAI and @langchain! Open source #llmops is here. www.databricks.com/blog/2023/04/18/introducing-mlflow-23-โฆ
-
Matei Zaharia
@matei_zaharia
#dataaisummit Call for Presentations ends Jan 13! Submit your case studies, research or best practices around #lakehouse, MLOps, streaming, and data. Last year's event included 60,000 data experts. dbricks.co/3Wh1Mx6
-
Post not available here, view on XPost not available here, view on X
Matei Zaharia
@matei_zaharia
Our bigger point is simply that that #lakehouse systems based on open data formats (Delta Lake) are now competitive with the best data warehouses, so there's no need to lock away part of your data just to do DW workloads. Even Snowflake's results on their cheapest tier show this.
-
Matei Zaharia
@matei_zaharia
Congrats to my student @codyaustun (with @pbailis) on defending his PhD today! Cody did amazing work improving the resource and data efficiency of deep learning, including widely used benchmarks (DAWNBench/MLPerf), perf analysis, and new 10-1000x faster algorithms (SVP & SEALS).
-
Matei Zaharia
@matei_zaharia
Nice updates on @Databricks SQL performance and our new #photon engine in @rxin's keynote today. We already ran faster/cheaper than cloud DWs for large datasets, but we now do great on small and concurrent queries, tables with small files, and BI fetches. www.youtube.com/watch?v=oz7XNx0YUw8
-
Matei Zaharia
@matei_zaharia
Excited to co-organize an ML Systems virtual seminar at Stanford this fall (with @HazyResearch, @w4nderlus7, @realDanFu, @krandiash and Fiodar Kazhamiaka)! Tune in online starting Oct 15, where @marcotcr will talk about NLP model QA with CheckList: mlsys.stanford.edu
-
Matei Zaharia
@matei_zaharia
Pretty sure I've seen people driving with only 19 neurons too!
MIT CSAIL
@MIT_CSAIL
This autonomous car can drive itself using only 19 control neurons.
Video: www.youtube.com/watch?v=8KBOf7NJh4Y
More: www.csail.mit.edu/news/new-deep-learning-models-require-fโฆ
(work w/@ISTAustria @tuvienna)
#selfdrivingcars #autonomy #ml #dl #machinelearning -
Matei Zaharia
@matei_zaharia
DAWN researchers are involved in 5 papers at next week's #mlsys conference, as well as workshops and a keynote! Take a look at ML systems research we'll be presenting here: dawn.cs.stanford.edu/2020/02/28/mlsys/
-
Matei Zaharia
@matei_zaharia
Just in time for my lecture on data quality at Stanford.
-
Matei Zaharia
@matei_zaharia
I'm co-organizing a workshop on MLOps Systems (together with @dedutta and Ce Zhang) at #mlsys 2020. We'd love to see position papers from researchers and industry on managing production ML applications. Submit your paper here: mlops-systems.github.io
-
Matei Zaharia
@matei_zaharia
I gave a keynote at @ACMSoCC about lessons from building a large-scale cloud service at @Databricks. Did you know that Databricks runs millions of VMs/day to process exabytes of data with <200 engineers? Slides here: www.slideshare.net/matei/lessons-from-largescale-cloud-soโฆ
-
Matei Zaharia
@matei_zaharia
This is an awesome project that we built at @Databricks and contributed back to HyperOpt: scale out trials on @ApacheSpark, no need to run MongoDB or a separate cluster scheduling system: databricks.com/blog/2019/10/29/scaling-hyperopt-to-tune-mโฆ
-
Matei Zaharia
@matei_zaharia
Congrats to the whole team at Databricks for the continued ultra-fast growth! We're hiring in all roles to continue simplifying how organizations work with data through technologies such as @DeltaLakeOSS, @MLflow, @ApacheSpark and more.
Databricks
@databricks
We're excited to announce that we've raised $400 million to continue our rapid global growth and engineering expansion, an investment that brings our valuation to $6.2 billion. Learn more: dbricks.co/SeriesFfunding
-
Matei Zaharia
@matei_zaharia
Nice blog post from our Databricks intern Apurva, who worked on auto-logging for #mlflow (now out in MLflow 1.1): databricks.com/blog/2019/08/19/mlflow-tensorflow-open-souโฆ
-
Matei Zaharia
@matei_zaharia
With a stage magician as the MC and a rock band on stage, @BigDataSpain was a lot of fun! In case you missed it, my slides (an update on MLflow) are available here: www.slideshare.net/databricks/mlflow-accelerating-the-endโฆ
-
Matei Zaharia
@matei_zaharia
#apachespark 2.3 is out! A blog post from on some of the key features: databricks.com/blog/2018/02/28/introducing-apache-spark-2โฆ or download it at spark.apache.org
-
Matei Zaharia
@matei_zaharia
I'm hosting a webinar on Jan 31st about Big Data and AI Predictions for 2018. How much is hype and what will really impact industries? Sign up at dbricks.co/2AwtvzF.
-
Matei Zaharia
@matei_zaharia
Nice post from @Databricks engineering on the impact of Meltdown and Spectre fixes on big data workloads in AWS: databricks.com/blog/2018/01/13/meltdown-and-spectre-perfoโฆ
-
Matei Zaharia
@matei_zaharia
Excited to announce Databricks Delta: a storage system that combines the best of data lakes, warehouses & streaming: www.databricks.com/blog/2017/10/25/databricks-delta-a-uniโฆ
-
Matei Zaharia
@matei_zaharia
Our keynote on deep learning and low-latency streaming in #apachespark is now up: www.youtube.com/watch?v=qAZ5XUz32yM #sparksummit
-
Matei Zaharia
@matei_zaharia
#sparksummit 2017 kicks off tomorrow in SF. See you there! #apachespark
-
Matei Zaharia
@matei_zaharia
My talk from #sparksummit is online: go.databricks.com/videos/spark-summit-east-2017/what-to-eโฆ (video), www.slideshare.net/databricks/spark-summit-east-2017-mateโฆ (slides). Thanks to our super fast event team!
-
Matei Zaharia
@matei_zaharia
#sparksummit Europe kicks off tomorrow; if you can't make it in person, there will be a free stream: ssum.it/2ev3VkM
-
Matei Zaharia
@matei_zaharia
With keynotes from Andrew Ng, Marvin Theimer and Jeff Dean, @Spark_Summit 2016 will be awesome! See the schedule at spark-summit.org/2016/schedule/.
-
Matei Zaharia
@matei_zaharia
The biggest surprise with #leftpad is that it was quadratic-time.. hope the new maintainers fix that.
-
Matei Zaharia
@matei_zaharia
My slides on Spark 2.0 at #sparksummit: www.slideshare.net/databricks/2016-spark-summit-east-keynโฆ
-
Matei Zaharia
@matei_zaharia
Caffe on Spark for deep learning from Yahoo!: yahoohadoop.tumblr.com/post/129872361846/large-scale-distโฆ